This is the full developer documentation for Honeybadger.io # Honeybadger Docs > Official Honeybadger documentation. Honeybadger provides error tracking, uptime monitoring, logging, and application performance insights in one simple platform that helps developers understand and fix issues faster. ## Product guides [Section titled “Product guides”](#product-guides) [Error monitoring](/guides/errors/)Get notified when errors occur in your applications [Insights & Logging](/guides/insights/)Analyze logs, error trends, patterns, and more [Dashboards & APM](/guides/dashboards/)Customize your monitoring dashboards to spot trends [Uptime monitoring](/guides/uptime/)Get notified when your API and website are unresponsive [Check-ins](/guides/check-ins/)Tracking pings from scheduled tasks and cron jobs [Deployments](/guides/deployments/)Viewing and tracking deployments [Status pages](/guides/status-pages/)Give users insight into your system status [Reports](/guides/reports/)Viewing and understanding reports [Accounts](/guides/accounts/)Manage billing and users [Projects](/guides/projects/)Projects contain your errors, check-ins & uptime [Integrations](/guides/integrations/)Connect Honeybadger to your favorite tools [User Management](/guides/user-management/)User membership for project, teams, and accounts [User Settings](/guides/user-settings/)Your personal preferences [Heroku](/guides/heroku/)Honeybadger + Heroku <3 ## Client libraries (SDKs) [Section titled “Client libraries (SDKs)”](#client-libraries-sdks) [Ruby](/lib/ruby/) [JavaScript](/lib/javascript/) [PHP](/lib/php/) [Python](/lib/python/) [Elixir](/lib/elixir/) [Java](/lib/java/) [Go](/lib/go/) [Cocoa](/lib/cocoa/) [.NET/C#](/lib/dotnet/) [Crystal](/lib/crystal/) [Clojure](/lib/clojure/) [Other platforms](/lib/other/) # API documentation > Complete API documentation for Honeybadger's REST and reporting APIs. Honeybadger’s APIs allow you to report exceptions from your applications, monitor your scheduled tasks, and retrieve and update the data we generate from your app’s errors. ## Reporting [Section titled “Reporting”](#reporting) These endpoints are the core of Honeybadger and how you get your data into our system. [Exceptions](/api/reporting-exceptions/)`api.honeybadger.io/v1/notices` [Check-Ins](/api/reporting-check-ins/)`api.honeybadger.io/v1/check_in/:id` [Deployments](/api/reporting-deployments/)`api.honeybadger.io/v1/deploys` [Source Maps](/api/reporting-source-maps/)`api.honeybadger.io/v1/source_maps` [Events](/api/reporting-events/)`api.honeybadger.io/v1/events` ## Data API [Section titled “Data API”](#data-api) The Data API can be used to access data stored in your Honeybadger account and to make changes to your account data. [Faults](/api/faults/) [Dashboards](/api/dashboards/) [Uptime](/api/uptime/) [Check-Ins](/api/check-ins/) [Comments](/api/comments/) [Deployments](/api/deployments/) [Projects](/api/projects/) [Teams](/api/teams/) [Environments](/api/environments/) [Accounts](/api/accounts/) [Status Pages](/api/status-pages/) # Accounts API reference > API reference for managing account information and users. In Honeybadger, all resources are tied to an account. A user may belong to one or more accounts (for instance, you can have a work account and a personal account). The Accounts API allows you to programmatically fetch details about your accounts. ## Get all accounts [Section titled “Get all accounts”](#get-all-accounts) ```bash curl -u AUTH_TOKEN: https://app.honeybadger.io/v2/accounts/ ``` Returns a list of all accounts the authenticated user belongs to. ```json { "results": [ { "id": "Me3upk", "email": "homerjsimpson@gmail.com", "name": "homer", "active": true, "parked": false }, { "id": "9bYfrm", "email": "homer.j@simpsons.io", "name": "Work", "active": true, "parked": false } ], "links": { "self": "http://localhost:3000/v2/accounts" } } ``` ## Get info for one account [Section titled “Get info for one account”](#get-info-for-one-account) ```bash curl -u AUTH_TOKEN: https://app.honeybadger.io/v2/accounts/ID ``` Returns info about an account, including the quota consumption for the current month. Each of the three sets of quota info is returned as an array of arrays, with one date & count pair for each day of the month, starting at midnight UTC on the first of the month. The different types of stats are as follows: * Stored: The number of error notifications saved and available for display in the UI * Limited: The number of notifications that were discarded due to throttling (429 responses) * Ignored: Notifications discarded as a result of errors being flagged as ignored in the UI The quota\_consumed value is a percentage, so `0.75` would mean 75% of the month’s quota has been consumed. The quota resets at the first of the month. ```json { "id": "Me3upk", "email": "homerjsimpson@gmail.com", "name": "homer", "active": true, "parked": false, "quota_consumed": 0.75, "api_stats": { "stored": [ [ 1648767600, 116 ], [ 1648771200, 65 ], ... ], "limited": [], "ignored": [] } } ``` ## Get a list of account users or user details [Section titled “Get a list of account users or user details”](#get-a-list-of-account-users-or-user-details) ```bash curl -u AUTH_TOKEN: https://app.honeybadger.io/v2/accounts/ID/users curl -u AUTH_TOKEN: https://app.honeybadger.io/v2/accounts/ID/users/ID ``` Returns all the users or a single user for the given account: ```json { "results": [ { "id": 1, "role": "Owner", "name": "", "email": "westley@example.com" } ] } ``` ## Update a user [Section titled “Update a user”](#update-a-user) ```bash curl -u AUTH_TOKEN: -X PUT -H 'Content-type: application/json' -d '{"user":{"role":"Admin"}}' https://app.honeybadger.io/v2/accounts/ID/users/ID ``` The list of valid fields is as follows: | Field name | Type | Description | | ---------- | ------ | ----------------------------------------------- | | `role` | string | One of “Member”, “Billing”, “Admin”, or “Owner” | ## Remove a user from the account [Section titled “Remove a user from the account”](#remove-a-user-from-the-account) ```bash curl -u AUTH_TOKEN: -X DELETE https://app.honeybadger.io/v2/accounts/ID/users/ID ``` ## Create an invitation for a user to join an account [Section titled “Create an invitation for a user to join an account”](#create-an-invitation-for-a-user-to-join-an-account) ```bash curl -u AUTH_TOKEN: -X POST -H 'Content-type: application/json' \ -d '{"invitation":{"email":"inigo@example.com"}}' \ https://app.honeybadger.io/v2/accounts/ID/invitations ``` You can specify these fields: | Field name | Type | Description | | ---------- | ------ | --------------------------------------------------------- | | `email` | string | The invited user’s email address. | | `role` | string | One of “Member”, “Billing”, “Admin”, or “Owner” | | `team_ids` | array | Array of team ids to which the invited user will be added | Returns the created user invitation: ```json { "id": 9, "email": "inigo@example.com", "created_by": { "email": "westley@example.com", "name": "Westley" }, "accepted_by": null, "role": "Member", "accepted_at": null, "created_at": "2013-01-08T15:42:16Z", "team_ids": [] } ``` ## Update an account invitation [Section titled “Update an account invitation”](#update-an-account-invitation) ```bash curl -u AUTH_TOKEN: -X PUT -H 'Content-type: application/json' \ -d '{"invitation":{"role": "Admin"}}' \ https://app.honeybadger.io/v2/accounts/ID/invitations/ID ``` You can specify either of these fields: | Field name | Type | Description | | ---------- | ------ | --------------------------------------------------------- | | `role` | string | One of “Member”, “Billing”, “Admin”, or “Owner” | | `team_ids` | array | Array of team ids to which the invited user will be added | ## Get an account invitation list or account invitation details [Section titled “Get an account invitation list or account invitation details”](#get-an-account-invitation-list-or-account-invitation-details) ```bash curl -u AUTH_TOKEN: https://app.honeybadger.io/v2/accounts/ID/invitations curl -u AUTH_TOKEN: https://app.honeybadger.io/v2/accounts/ID/invitations/ID ``` Returns a list of account invitations or a single account invitation for the given account: ```json { "results": [ { "id": 9, "email": "inigo@example.com", "created_by": { "email": "westley@example.com", "name": "Westley" }, "accepted_by": { "email": "inigo@example.com", "name": "Inigo Montoya" }, "role": "Member", "accepted_at": "2013-01-08T15:42:41Z", "created_at": "2013-01-08T15:42:16Z", "team_ids": [] } ] } ``` ## Delete an account invitation [Section titled “Delete an account invitation”](#delete-an-account-invitation) ```bash curl -u AUTH_TOKEN: -X DELETE https://app.honeybadger.io/v2/accounts/ID/invitations/ID ``` # Alarms API reference > API reference for managing Insights alarms with endpoints to create, read, update, and delete alarms and view their trigger history. The Alarms API lets you programmatically manage [Insights alarms](/guides/insights/alarms/). All alarm endpoints are scoped to a project. Notification channels for alarms are managed in the Honeybadger UI and can’t be set via the API. ## Get an alarm list or alarm details [Section titled “Get an alarm list or alarm details”](#get-an-alarm-list-or-alarm-details) ```bash curl -u AUTH_TOKEN: https://app.honeybadger.io/v2/projects/ID/alarms curl -u AUTH_TOKEN: https://app.honeybadger.io/v2/projects/ID/alarms/ID ``` The list endpoint returns results in a `results` array. The detail endpoint returns a single alarm: ```json { "id": "8f0dc2b1-4d9e-4b6a-9c3f-2e7a51d0c8aa", "name": "High error rate", "description": "Triggers when error count exceeds 100 in 5 minutes", "state": "ok", "query": "filter event_type::str == \"notice\"", "stream_ids": ["a1b2c3d4e5f6"], "evaluation_period": "5m", "lookback_lag": "1m", "trigger_config": { "type": "alert_result_count", "config": { "operator": "gt", "value": 100 } }, "error": null, "last_checked_at": "2026-02-04T09:10:00Z", "next_check_at": "2026-02-04T09:15:00Z", "created_at": "2026-01-31T14:22:18Z", "updated_at": "2026-02-04T09:11:05Z", "url": "https://app.honeybadger.io/projects/1/insights/alarms/42", "project_id": 1 } ``` The response includes: | Field name | Type | Description | | ------------------- | ------- | ------------------------------------------------------------------------------------------------------------------------- | | `id` | string | The alarm’s UUID. Use this value in URLs for show, update, delete, and history requests. | | `name` | string | The alarm name. | | `description` | string | The alarm description. | | `state` | string | The alarm’s current state: `"ok"` (trigger condition not met), `"alarm"` (triggered), or `"initial"` (not yet evaluated). | | `query` | string | The [BadgerQL query](/guides/insights/badgerql/) the alarm evaluates. | | `stream_ids` | array | The IDs of the Insights streams the alarm queries. | | `evaluation_period` | string | How often the alarm is evaluated, as a duration string (`"5m"`, `"1h"`, `"1d"`). | | `lookback_lag` | string | The delay before each evaluation to allow data to arrive (`"1m"`, `"0s"`). | | `trigger_config` | object | The trigger condition. See [Trigger config](#trigger-config). | | `error` | string | The error message if the alarm’s query failed to execute; `null` otherwise. | | `last_checked_at` | string | ISO 8601 timestamp of the last evaluation. | | `next_check_at` | string | ISO 8601 timestamp of the next scheduled evaluation. | | `created_at` | string | ISO 8601 timestamp. | | `updated_at` | string | ISO 8601 timestamp. | | `url` | string | A link to the alarm in the Honeybadger UI. | | `project_id` | integer | The project the alarm belongs to. | ## Create an alarm [Section titled “Create an alarm”](#create-an-alarm) ```bash curl -u AUTH_TOKEN: \ -X POST \ -H 'Content-type: application/json' \ -d '{ "alarm": { "name": "High error rate", "description": "Triggers when error count exceeds 100 in 5 minutes", "query": "filter event_type::str == \"notice\"", "evaluation_period": "5m", "lookback_lag": "1m", "trigger_config": { "type": "alert_result_count", "config": { "operator": "gt", "value": 100 } } } }' \ https://app.honeybadger.io/v2/projects/ID/alarms ``` Returns `201 Created` with the alarm JSON shown above. The request body must be wrapped in a top-level `alarm` object. These fields can be provided: | Field name | Type | Description | | ------------------- | ------ | ----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | | `name` | string | Required. The alarm name. | | `query` | string | Required. A [BadgerQL query](/guides/insights/badgerql/) that returns the data to monitor. The alarm system wraps the query to count matching results per evaluation period, so a bare `filter` works — see [Query guidelines](#query-guidelines) below. | | `evaluation_period` | string | Required. How often the alarm is evaluated, as a duration string (`"5m"`, `"1h"`, `"1d"`). Minimum `1m`, maximum less than a week. | | `trigger_config` | object | Required. The condition that triggers the alarm. See [Trigger config](#trigger-config). | | `description` | string | Optional description. | | `stream_ids` | array | Optional list of [Insights stream IDs](/api/streams/) to query. If omitted, the alarm queries all streams on the project. IDs that don’t belong to the project are ignored; if that leaves the list empty, the request fails with a `422`. Note these are stream IDs, not slugs — `"default"` is a slug and is ignored. | | `lookback_lag` | string | Optional delay before each evaluation to allow data to arrive (`"1m"`, `"0s"`). | A `422 Unprocessable Entity` response with an `errors` key is returned when the alarm is invalid — for example, a missing required field, an invalid BadgerQL query, or an unknown trigger type. ### Trigger config [Section titled “Trigger config”](#trigger-config) The `trigger_config` object defines when the alarm transitions to the alarm state: | Field name | Type | Description | | ----------------- | ------- | ----------------------------------------------------------------------------------------------------------------------- | | `type` | string | The trigger type. Currently `"alert_result_count"`, which triggers based on the count of results returned by the query. | | `config.operator` | string | The comparison operator: `"gt"`, `"gte"`, `"lt"`, `"lte"`, `"eq"`, or `"neq"`. | | `config.value` | integer | The threshold to compare the result count against. Must be >= 0. | Some examples: ```json // Trigger when more than 50 events match the query { "type": "alert_result_count", "config": { "operator": "gt", "value": 50 } } // Trigger when no events match (e.g., a missing heartbeat) { "type": "alert_result_count", "config": { "operator": "eq", "value": 0 } } // Trigger when any events match { "type": "alert_result_count", "config": { "operator": "neq", "value": 0 } } ``` ### Query guidelines [Section titled “Query guidelines”](#query-guidelines) The alarm system automatically wraps the query to count results per evaluation period, so the query should filter and/or aggregate events, and the system handles the final counting: ```plaintext filter event_type::str == "notice" filter status::int >= 500 filter event_type::str == "request.handled" and duration::int > 5000 ``` Queries with `stats` also work — the system counts the result rows: ```plaintext filter event_type::str == "notice" | stats count() as count by fault_id::int ``` ## Update an alarm [Section titled “Update an alarm”](#update-an-alarm) ```bash curl -u AUTH_TOKEN: \ -X PUT \ -H 'Content-type: application/json' \ -d '{ "alarm": { "name": "High error rate", "query": "filter event_type::str == \"notice\"", "evaluation_period": "10m", "trigger_config": { "type": "alert_result_count", "config": { "operator": "gt", "value": 100 } } } }' \ https://app.honeybadger.io/v2/projects/ID/alarms/ID ``` Returns `204 No Content` on success. The request body uses the same fields as [Create an alarm](#create-an-alarm). The submitted definition replaces the existing one, so include every field — even the ones you aren’t changing. ## Delete an alarm [Section titled “Delete an alarm”](#delete-an-alarm) ```bash curl -u AUTH_TOKEN: -X DELETE https://app.honeybadger.io/v2/projects/ID/alarms/ID ``` Returns `204 No Content` on success. ## Get alarm trigger history [Section titled “Get alarm trigger history”](#get-alarm-trigger-history) ```bash curl -u AUTH_TOKEN: https://app.honeybadger.io/v2/projects/ID/alarms/ID/history ``` Returns the alarm’s past evaluations that changed its state: ```json { "triggers": [ { "id": "d4c8a2f6-3b1e-4f7a-8c5d-9e0b2a6f1c3e", "state": "alarm", "result": { "count": 127 }, "created_at": "2026-02-04T09:05:00Z" } ], "links": { "self": "...", "prev": "...", "next": "..." } } ``` Each entry in the `triggers` array includes: | Field name | Type | Description | | ------------ | ------ | ---------------------------------------------------------------- | | `id` | string | The trigger event ID. | | `state` | string | The state after the evaluation: `"ok"`, `"alarm"`, or `"error"`. | | `result` | object | The query result that caused the state change. | | `created_at` | string | ISO 8601 timestamp of the evaluation. | Use the `page` query parameter to paginate; the `links` object contains URLs for the previous and next pages. # Check-ins API reference > API reference for managing check-ins with endpoints to create, read, update, and delete scheduled task and cron monitors. ## Get a check-in list or check-in details [Section titled “Get a check-in list or check-in details”](#get-a-check-in-list-or-check-in-details) ```bash curl -u AUTH_TOKEN: https://app.honeybadger.io/v2/projects/ID/check_ins curl -u AUTH_TOKEN: https://app.honeybadger.io/v2/projects/ID/check_ins/ID ``` Returns a list of check-ins or a single check-in for a project. There are two different types of check-ins, simple or cron, and the response varies a bit between the two types. ### Simple check-in [Section titled “Simple check-in”](#simple-check-in) ```json { "state": "pending", "schedule_type": "simple", "reported_at": null, "expected_at": null, "missed_count": 0, "grace_period": "5 minutes", "id": "XXXXXX", "name": "Hourly clean up", "slug": "hourly-clean-up", "url": "https://api.honeybadger.io/v1/check_in/XXXXXX", "report_period": "1 hour" } ``` ### Cron check-in [Section titled “Cron check-in”](#cron-check-in) ```json { "state": "reporting", "schedule_type": "cron", "reported_at": "2018-01-16T12:36:11Z", "expected_at": "2018-01-17T12:36:11Z", "missed_count": 0, "grace_period": "", "id": "YYYYYY", "name": "Hourly check", "slug": "hourly-check", "url": "https://api.honeybadger.io/v1/check_in/YYYYYY", "cron_schedule": "30 * * * *", "cron_timezone": "UTC" } ``` ## Create a check-in [Section titled “Create a check-in”](#create-a-check-in) ```bash curl -u AUTH_TOKEN: -X POST -H 'Content-type: application/json' -d '{"check_in":{"name":"Daily reports", "report_period":"1 day", "schedule_type":"simple"}}' https://app.honeybadger.io/v2/projects/ID/check_ins ``` This endpoint returns either the simple or cron check-in response described above, depending on the type of check-in you create. These fields can be provided: | Field name | Type | Description | | -------------- | ------ | -------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | | name | string | | | slug | string | Optional identifier for more human-friendly check-in URL. | | schedule\_type | string | Valid values are “simple” or “cron”. If you specify “cron”, then the “cron\_schedule” field is required. | | report\_period | string | For simple check-ins, the amount of time that can elapse before the check-in is reported as missing. E.g., “1 day” would require a hit to the API daily to maintain the “reporting” status. Valid time periods are “minute”, “hour”, “day”, “week”, and “month”: “5 minutes”, “7 days”, etc. | | grace\_period | string | The amount of time to allow a job to not report before it’s reported as missing. Valid values are the same as the report\_period field. | | cron\_schedule | string | For a `schedule_type` of “cron”, the [cron-compatible string](https://en.wikipedia.org/wiki/Cron#Overview) that defines when the job should be expected to hit the API. | | cron\_timezone | string | The timezone setting for your server that is running the cron job to be monitored. The default value is “UTC”. Valid timezone values are listed [here](/api/check-ins/timezones/). | ## Update a check-in [Section titled “Update a check-in”](#update-a-check-in) ```bash curl -u AUTH_TOKEN: -X PUT -H 'Content-type: application/json' -d '{"check_in":{"name":"Updated check-in name"}}' https://app.honeybadger.io/v2/projects/ID/check_ins/ID ``` The fields listed in the previous section other than `schedule_type` can be updated. In other words, the schedule type can’t be changed. The `report_period` field is only valid for simple check-ins, and the `cron_schedule` and `cron_timezone` fields are only valid for cron check-ins. ## Update all check-ins [Section titled “Update all check-ins”](#update-all-check-ins) Caution Use this endpoint with caution, as it will delete all existing check-ins if you send an empty payload. ```bash curl -u AUTH_TOKEN: -X PUT -H 'Content-type: application/json' -d '{"check_ins":[{"name":"Updated check-in name", "slug":"my-slug"}]}' https://app.honeybadger.io/v2/projects/ID/check_ins ``` Similar to updating a single check-in, this endpoint can be used to update multiple check-ins at once. All check-ins need to be unique by slug and by name (if provided). Any check-ins that do not have a matching slug or name will be created, and any check-ins that are not present in the request will be deleted. The results will be an array of the updated check-ins and any check-ins that were created or deleted. The response will look like this: ```json { "results": [ { "operation": "update", "slug": "my-changed-slug", "success": true }, { "operation": "create", "slug": "my-changed-slug", "success": false, "errors": ["Slug is not unique"] }, { "operation": "delete", "slug": "my-deleted-slug", "success": true } ] } ``` ## Delete a check-in [Section titled “Delete a check-in”](#delete-a-check-in) ```bash curl -u AUTH_TOKEN: -X DELETE https://app.honeybadger.io/v2/projects/ID/check_ins/ID ``` # Check-in timezone values > Complete list of supported timezones for Honeybadger check-in scheduling and cron monitoring configuration. Use the friendly name (like Pacific Time (US & Canada) instead of America/Los\_Angeles) when working with the API. The other labels are provided here for search-ability. 🙂 | Value for `cron_timezone` (use this) | AKA (don’t use this) | | ------------------------------------ | ------------------------------- | | UTC | Etc/UTC | | Abu Dhabi | Asia/Muscat | | Adelaide | Australia/Adelaide | | Alaska | America/Juneau | | Almaty | Asia/Almaty | | American Samoa | Pacific/Pago\_Pago | | Amsterdam | Europe/Amsterdam | | Arizona | America/Phoenix | | Astana | Asia/Dhaka | | Athens | Europe/Athens | | Atlantic Time (Canada) | America/Halifax | | Auckland | Pacific/Auckland | | Azores | Atlantic/Azores | | Baghdad | Asia/Baghdad | | Baku | Asia/Baku | | Bangkok | Asia/Bangkok | | Beijing | Asia/Shanghai | | Belgrade | Europe/Belgrade | | Berlin | Europe/Berlin | | Bern | Europe/Zurich | | Bogota | America/Bogota | | Brasilia | America/Sao\_Paulo | | Bratislava | Europe/Bratislava | | Brisbane | Australia/Brisbane | | Brussels | Europe/Brussels | | Bucharest | Europe/Bucharest | | Budapest | Europe/Budapest | | Buenos Aires | America/Argentina/Buenos\_Aires | | Cairo | Africa/Cairo | | Canberra | Australia/Melbourne | | Cape Verde Is. | Atlantic/Cape\_Verde | | Caracas | America/Caracas | | Casablanca | Africa/Casablanca | | Central America | America/Guatemala | | Central Time (US & Canada) | America/Chicago | | Chatham Is. | Pacific/Chatham | | Chennai | Asia/Kolkata | | Chihuahua | America/Chihuahua | | Chongqing | Asia/Chongqing | | Copenhagen | Europe/Copenhagen | | Darwin | Australia/Darwin | | Dhaka | Asia/Dhaka | | Dublin | Europe/Dublin | | Eastern Time (US & Canada) | America/New\_York | | Edinburgh | Europe/London | | Ekaterinburg | Asia/Yekaterinburg | | Fiji | Pacific/Fiji | | Georgetown | America/Guyana | | Greenland | America/Godthab | | Guadalajara | America/Mexico\_City | | Guam | Pacific/Guam | | Hanoi | Asia/Bangkok | | Harare | Africa/Harare | | Hawaii | Pacific/Honolulu | | Helsinki | Europe/Helsinki | | Hobart | Australia/Hobart | | Hong Kong | Asia/Hong\_Kong | | Indiana (East) | America/Indiana/Indianapolis | | International Date Line West | Etc/GMT+12 | | Irkutsk | Asia/Irkutsk | | Islamabad | Asia/Karachi | | Istanbul | Europe/Istanbul | | Jakarta | Asia/Jakarta | | Jerusalem | Asia/Jerusalem | | Kabul | Asia/Kabul | | Kaliningrad | Europe/Kaliningrad | | Kamchatka | Asia/Kamchatka | | Karachi | Asia/Karachi | | Kathmandu | Asia/Kathmandu | | Kolkata | Asia/Kolkata | | Krasnoyarsk | Asia/Krasnoyarsk | | Kuala Lumpur | Asia/Kuala\_Lumpur | | Kuwait | Asia/Kuwait | | Kyiv | Europe/Kiev | | La Paz | America/La\_Paz | | Lima | America/Lima | | Lisbon | Europe/Lisbon | | Ljubljana | Europe/Ljubljana | | London | Europe/London | | Madrid | Europe/Madrid | | Magadan | Asia/Magadan | | Marshall Is. | Pacific/Majuro | | Mazatlan | America/Mazatlan | | Melbourne | Australia/Melbourne | | Mexico City | America/Mexico\_City | | Mid-Atlantic | Atlantic/South\_Georgia | | Midway Island | Pacific/Midway | | Minsk | Europe/Minsk | | Monrovia | Africa/Monrovia | | Monterrey | America/Monterrey | | Montevideo | America/Montevideo | | Moscow | Europe/Moscow | | Mountain Time (US & Canada) | America/Denver | | Mumbai | Asia/Kolkata | | Muscat | Asia/Muscat | | Nairobi | Africa/Nairobi | | New Caledonia | Pacific/Noumea | | New Delhi | Asia/Kolkata | | Newfoundland | America/St\_Johns | | Novosibirsk | Asia/Novosibirsk | | Nuku’alofa | Pacific/Tongatapu | | Osaka | Asia/Tokyo | | Pacific Time (US & Canada) | America/Los\_Angeles | | Paris | Europe/Paris | | Perth | Australia/Perth | | Port Moresby | Pacific/Port\_Moresby | | Prague | Europe/Prague | | Pretoria | Africa/Johannesburg | | Puerto Rico | America/Puerto\_Rico | | Quito | America/Lima | | Rangoon | Asia/Rangoon | | Riga | Europe/Riga | | Riyadh | Asia/Riyadh | | Rome | Europe/Rome | | Samara | Europe/Samara | | Samoa | Pacific/Apia | | Santiago | America/Santiago | | Sapporo | Asia/Tokyo | | Sarajevo | Europe/Sarajevo | | Saskatchewan | America/Regina | | Seoul | Asia/Seoul | | Singapore | Asia/Singapore | | Skopje | Europe/Skopje | | Sofia | Europe/Sofia | | Solomon Is. | Pacific/Guadalcanal | | Srednekolymsk | Asia/Srednekolymsk | | Sri Jayawardenepura | Asia/Colombo | | St. Petersburg | Europe/Moscow | | Stockholm | Europe/Stockholm | | Sydney | Australia/Sydney | | Taipei | Asia/Taipei | | Tallinn | Europe/Tallinn | | Tashkent | Asia/Tashkent | | Tbilisi | Asia/Tbilisi | | Tehran | Asia/Tehran | | Tijuana | America/Tijuana | | Tokelau Is. | Pacific/Fakaofo | | Tokyo | Asia/Tokyo | | Ulaanbaatar | Asia/Ulaanbaatar | | Urumqi | Asia/Urumqi | | Vienna | Europe/Vienna | | Vilnius | Europe/Vilnius | | Vladivostok | Asia/Vladivostok | | Volgograd | Europe/Volgograd | | Warsaw | Europe/Warsaw | | Wellington | Pacific/Auckland | | West Central Africa | Africa/Algiers | | Yakutsk | Asia/Yakutsk | | Yerevan | Asia/Yerevan | | Zagreb | Europe/Zagreb | | Zurich | Europe/Zurich | # Comments API reference > API reference for managing error comments with endpoints to create, read, update, and delete resources. ## Get a comment list or comment details [Section titled “Get a comment list or comment details”](#get-a-comment-list-or-comment-details) ```bash curl -u AUTH_TOKEN: https://app.honeybadger.io/v2/projects/ID/faults/ID/comments curl -u AUTH_TOKEN: https://app.honeybadger.io/v2/projects/ID/faults/ID/comments/ID ``` Returns a list of comments or a single comment for the given fault with the following format: ```json { "id": 14, "fault_id": 2, "event": null, "source": "unknown", "notices_count": 0, "created_at": "2012-08-22T15:47:26Z", "author": "Inigo", "body": "You killed my father; prepare to die" } ``` ## Create a comment [Section titled “Create a comment”](#create-a-comment) ```bash curl -u AUTH_TOKEN: -X POST -H 'Content-type: application/json' -d '{"comment":{"body":"My comment"}}' https://app.honeybadger.io/v2/projects/ID/faults/ID/comments ``` The `body` field is the only field that can be included in the payload. ## Update a comment [Section titled “Update a comment”](#update-a-comment) ```bash curl -u AUTH_TOKEN: -X PUT -H 'Content-type: application/json' -d '{"comment":{"body":"Updated comment"}}' https://app.honeybadger.io/v2/projects/ID/faults/ID/comments/ID ``` ## Delete a comment [Section titled “Delete a comment”](#delete-a-comment) ```bash curl -u AUTH_TOKEN: -X DELETE https://app.honeybadger.io/v2/projects/ID/faults/ID/comments/ID ``` # Dashboards API reference > API reference for managing Insights dashboards with endpoints to create, read, update, and delete dashboards and their widgets. The Dashboards API lets you programmatically manage [Insights dashboards](/guides/dashboards/) and their widgets. All dashboard endpoints are scoped to a project. ## Get a dashboard list or dashboard details [Section titled “Get a dashboard list or dashboard details”](#get-a-dashboard-list-or-dashboard-details) ```bash curl -u AUTH_TOKEN: https://app.honeybadger.io/v2/projects/ID/dashboards curl -u AUTH_TOKEN: https://app.honeybadger.io/v2/projects/ID/dashboards/ID ``` The list endpoint returns results in a `results` array. The detail endpoint returns a single dashboard: ```json { "id": "abc123", "title": "My Dashboard", "widgets": [ { "id": "4b2e9c1a-7f3d-4a12-9d5e-0b8f6a2c1e4d", "type": "insights_vis", "grid": { "x": 0, "y": 0, "w": 12, "h": 3 }, "presentation": { "title": "Total requests" }, "config": { "query": "filter event_type::str == \"request\" | stats count() by bin()", "vis": { "view": "line" }, "streams": ["default"] } } ], "is_default": false, "shared": true, "default_ts": "P7D", "created_at": "2026-01-31T14:22:18Z", "updated_at": "2026-02-04T09:11:05Z", "project_id": 1 } ``` The response includes: | Field name | Type | Description | | ------------ | ------- | --------------------------------------------------------------------------------------------------------------------------------- | | `id` | string | The dashboard’s hashid. Use this value in URLs for show, update, and delete requests. | | `title` | string | The dashboard title. | | `widgets` | array | The dashboard’s widgets, in source form (see below). | | `is_default` | boolean | Whether this is the project’s default dashboard. | | `shared` | boolean | Whether the dashboard is shared with other users on the account. Dashboards created via the API are shared. | | `default_ts` | string | The dashboard’s default time range, if set. See `default_ts` under [Create a dashboard](#create-a-dashboard) for accepted values. | | `created_at` | string | ISO 8601 timestamp. | | `updated_at` | string | ISO 8601 timestamp. | | `project_id` | integer | The project the dashboard belongs to. | In the response, each widget’s `config.streams` contains stream *slugs* (for example `"default"` or `"internal"`) rather than numeric stream IDs. Use the same slugs when creating or updating widgets. ## Create a dashboard [Section titled “Create a dashboard”](#create-a-dashboard) ```bash curl -u AUTH_TOKEN: \ -X POST \ -H 'Content-type: application/json' \ -d '{"dashboard":{"title":"My Dashboard","widgets":[]}}' \ https://app.honeybadger.io/v2/projects/ID/dashboards ``` Returns `201 Created` with the dashboard JSON shown above. The request body must be wrapped in a top-level `dashboard` object. These fields can be provided: | Field name | Type | Description | | ------------ | ------ | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | | `title` | string | The dashboard title. | | `widgets` | array | The dashboard’s widgets. See the widget fields below. Pass an empty array to create a dashboard with no widgets. | | `default_ts` | string | Optional default time range. Accepts an ISO 8601 duration (`P1D`, `P7D`, `PT1H`), a keyword (`today`, `yesterday`, `week`, `month`), or a date range (`2024-01-01/2024-01-31`). | ### Widget fields [Section titled “Widget fields”](#widget-fields) Each entry in the `widgets` array describes a single widget. The most common widget type is `insights_vis`, which renders a BadgerQL query as a chart or table: | Field name | Type | Description | | -------------- | ------ | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | | `type` | string | The widget type, e.g. `"insights_vis"`. Other built-in types include `"alarms"`, `"deployments"`, `"checkins"`, `"uptime"`, and `"errors"`. | | `id` | string | Optional UUID. If omitted, the server generates one. Must be unique within the dashboard. On update, include the existing widget’s `id` to preserve it; omitting it will regenerate the ID. | | `grid` | object | Position and size on the dashboard grid. Keys: `x`, `y`, `w`, `h`. Defaults to `{"x": 0, "y": 0, "w": 12, "h": 3}` if omitted. | | `presentation` | object | Display options. Keys: `title`, `subtitle`. | | `config` | object | Widget-specific configuration. See below. | For `insights_vis` widgets, `config` accepts: | Field name | Type | Description | | ---------- | ------ | ------------------------------------------------------------------------------------------------------------------------------------------ | | `query` | string | A [BadgerQL query](/guides/insights/badgerql/) to execute. | | `vis.view` | string | The visualization view. One of `"table"`, `"line"`, `"bar"`, `"area"`, `"pie"`, `"billboard"`, `"histogram"`, `"scatter"`, or `"heatmap"`. | | `streams` | array | Optional list of stream slugs to query (for example `["default"]`). Defaults to all streams on the project. | ### Example with a widget [Section titled “Example with a widget”](#example-with-a-widget) ```bash curl -u AUTH_TOKEN: \ -X POST \ -H 'Content-type: application/json' \ -d '{ "dashboard": { "title": "Traffic overview", "widgets": [ { "type": "insights_vis", "grid": { "x": 0, "y": 0, "w": 12, "h": 3 }, "presentation": { "title": "Total requests" }, "config": { "query": "filter event_type::str == \"request\" | stats count() by bin()", "vis": { "view": "line" } } } ] } }' \ https://app.honeybadger.io/v2/projects/ID/dashboards ``` The request body is validated against the dashboard schema. A `422 Unprocessable Entity` response is returned when the payload violates the schema (unknown widget `type`, unknown properties, duplicate widget IDs, a title longer than 255 characters, etc.) or when the account’s dashboard or widget limit has been reached. See the [Insights dashboards guide](/guides/dashboards/) for more on the widget catalog and schema. In the Honeybadger UI, the **Edit Source** view exposes the full YAML-equivalent of the same schema used by this API. ## Update a dashboard [Section titled “Update a dashboard”](#update-a-dashboard) ```bash curl -u AUTH_TOKEN: \ -X PUT \ -H 'Content-type: application/json' \ -d '{"dashboard":{"title":"Updated title","widgets":[]}}' \ https://app.honeybadger.io/v2/projects/ID/dashboards/ID ``` Returns `204 No Content` on success. The request body uses the same fields as [Create a dashboard](#create-a-dashboard). The submitted `widgets` array replaces the existing one, so include every widget you want to keep. ## Delete a dashboard [Section titled “Delete a dashboard”](#delete-a-dashboard) ```bash curl -u AUTH_TOKEN: -X DELETE https://app.honeybadger.io/v2/projects/ID/dashboards/ID ``` Returns `204 No Content` on success. # Deployments API reference > API reference for managing deployments with endpoints to read and delete resources. ## Get a deploy list or deploy details [Section titled “Get a deploy list or deploy details”](#get-a-deploy-list-or-deploy-details) ```bash curl -u AUTH_TOKEN: https://app.honeybadger.io/v2/projects/ID/deploys curl -u AUTH_TOKEN: https://app.honeybadger.io/v2/projects/ID/deploys/ID ``` Returns a list of deploys or a single deploy for the given project with the following format: ```json { "created_at": "2013-04-30T13:12:51Z", "environment": "production", "local_username": "deploy", "project_id": 1, "repository": "some/repo", "revision": "2013-04-29-take-2-16-g6cf7eae" } ``` The deploy list can be filtered with a number of URL parameters: | Parameter | Description | | ---------------- | --------------------------------------------------------- | | `environment` | A string with the desired environment, e.g., ‘production’ | | `local_username` | Username of the person doing the deployment | | `created_after` | A Unix timestamp (number of seconds since the epoch) | | `created_before` | A Unix timestamp (number of seconds since the epoch) | | `limit` | Number of results to return (max and default are 25) | The deploy list is always ordered by creation time descending. ## Delete a deploy [Section titled “Delete a deploy”](#delete-a-deploy) ```bash curl -u AUTH_TOKEN: -X DELETE https://app.honeybadger.io/v2/projects/ID/deploys/ID ``` # Environments API reference > API reference for managing environments with endpoints to retrieve and configure environment-specific settings. In Honeybadger, errors are grouped by the environment they occurred in. When an error is reported with a new environment, the environment is automatically stored, so you can search and filter by it in the future. You can also add, remove and manage your projects’ environments via the API. ## Get all environments [Section titled “Get all environments”](#get-all-environments) ```bash curl -u AUTH_TOKEN: https://app.honeybadger.io/v2/projects/PROJECT_ID/environments ``` Returns a list of all recorded environments in this project. ```json { "results": [ { "id": 1, "project_id": 1, "name": "production", "notifications": true, "created_at": "2021-08-10T13:56:29.513358Z", "updated_at": "2021-08-10T13:56:29.513358Z" } ], "links": { "self": "http://localhost:3000/v2/projects/1/environments" } } ``` ## Get a single environment’s details [Section titled “Get a single environment’s details”](#get-a-single-environments-details) ```bash curl -u AUTH_TOKEN: https://app.honeybadger.io/v2/projects/PROJECT_ID/environments/ID ``` ```json { "id": 1, "project_id": 1, "name": "production", "notifications": true, "created_at": "2021-08-10T13:56:29.513358Z", "updated_at": "2021-08-10T13:56:29.513358Z" } ``` ## Create an environment [Section titled “Create an environment”](#create-an-environment) ```bash curl -u AUTH_TOKEN: -X POST -H 'Content-type: application/json' \ -d '{ "environment": { "name": "Test", "notifications": true } }' https://app.honeybadger.io/v2/projects/PROJECT_ID/environments ``` You can specify these fields within the `environment` object: | Field name | Type | Description | | --------------- | ------- | ---------------------------------------------------------------------- | | `name` | string | The name of the environment | | `notifications` | boolean | (Optional) Enable notifications for this environment. Default: `true`. | Returns a 201 Created response containing the created environment’s details. ## Update an environment [Section titled “Update an environment”](#update-an-environment) ```bash curl -u AUTH_TOKEN: -X PUT -H 'Content-type: application/json' \ -d '{ "environment": { "name": "Staging", "notifications": false } }' https://app.honeybadger.io/v2/projects/PROJECT_ID/environments/ID ``` You can specify any of these fields within the `environment` object: | Field name | Type | Description | | --------------- | ------- | ----------------------------------------- | | `name` | string | The name of the environment | | `notifications` | boolean | Enable notifications for this environment | Returns an empty response (204 No Content) if successful. ## Delete an environment [Section titled “Delete an environment”](#delete-an-environment) ```bash curl -u AUTH_TOKEN: -X DELETE https://app.honeybadger.io/v2/projects/PROJECT_ID/environments/ID ``` Returns an empty response (204 No Content) if successful. # Errors API reference > API reference for managing errors (faults) with endpoints to create, read, update, and delete error data. Note A **fault** is synonymous with an **error**, in that it contains a collection of **notices** (individual error events) ## Get a fault list or fault details [Section titled “Get a fault list or fault details”](#get-a-fault-list-or-fault-details) ```bash curl -u AUTH_TOKEN: https://app.honeybadger.io/v2/projects/ID/faults curl -u AUTH_TOKEN: https://app.honeybadger.io/v2/projects/ID/faults/ID ``` Returns a list of faults or a single fault for the given project with the following format: ```json { "action": "runtime_error", "assignee": { "email": "westley@honeybadger.io", "id": 1, "name": "Westley" }, "comments_count": 0, "component": "pages", "created_at": "2013-01-22T16:33:22.704628Z", "environment": "development", "id": 2, "ignored": false, "klass": "RuntimeError", "last_notice_at": "2013-02-11T19:18:31.991903Z", "message": "This is a runtime error", "notices_count": 7, "project_id": 1, "resolve_on_deploy": false, "resolved": false, "tags": ["internal"], "url": "https://app.honeybadger.io/projects/1/faults/2" } ``` The fault list can be filtered with a number of URL parameters: | Parameter | Description | | ----------------- | ---------------------------------------------------- | | `q` | A [search string](/guides/errors/search/) | | `created_after` | A Unix timestamp (number of seconds since the epoch) | | `occurred_after` | A Unix timestamp (number of seconds since the epoch) | | `occurred_before` | A Unix timestamp (number of seconds since the epoch) | | `limit` | Number of results to return (max and default are 25) | The fault list can be ordered with the order parameter in the URL, with the following possible values: | Value | Description | | ---------- | --------------------------------------------------------------- | | `recent` | List the errors that have most recently occurred first | | `frequent` | List the errors that have received the most notifications first | The default order is by creation time. If the search query affects the amount of matched notices, the `notices_count` field may not be accurate. For those cases, we add a `notices_count_in_range` field to the payload which reflects the notice counts with the query applied. ## Get a count of faults [Section titled “Get a count of faults”](#get-a-count-of-faults) ```bash curl -u AUTH_TOKEN: https://app.honeybadger.io/v2/projects/ID/faults/summary ``` Returns a total count of all the errors for a project and counts of errors grouped by environment, resolution status, and ignored status. The counts can be filtered by these parameters: | Parameter | Description | | ----------------- | ---------------------------------------------------- | | `q` | A [search string](/guides/errors/search/) | | `created_after` | A Unix timestamp (number of seconds since the epoch) | | `occurred_after` | A Unix timestamp (number of seconds since the epoch) | | `occurred_before` | A Unix timestamp (number of seconds since the epoch) | For example, to get a count of open faults in production, you would use the `q` parameter to filter the results: ```bash curl -u AUTH_TOKEN: https://app.honeybadger.io/v2/projects/ID/faults/summary?q=environment%3Aproduction%20-is%3Aresolved%20-is%3Aignored ``` ## Update a fault [Section titled “Update a fault”](#update-a-fault) ```bash curl -u AUTH_TOKEN: -X PUT -H 'Content-type: application/json' -d '{"fault":{"resolved":true}}' https://app.honeybadger.io/v2/projects/ID/faults/ID ``` The following fields can be updated: | Field name | Type | Description | | ------------------- | ------- | ---------------------------------------------------------- | | `resolved` | boolean | | | `ignored` | boolean | | | `assignee_id` | integer | | | `resolve_on_deploy` | boolean | Mark the fault to be resolved automatically on next deploy | Setting `resolved` or `ignored` to `true` in the same request takes precedence over `resolve_on_deploy`: the fault is resolved or ignored immediately and is not left marked for deploy. The current `resolve_on_deploy` state is also returned on each fault (see the fault details above). ## Delete a fault [Section titled “Delete a fault”](#delete-a-fault) ```bash curl -u AUTH_TOKEN: -X DELETE https://app.honeybadger.io/v2/projects/ID/faults/ID ``` ## Get a count of occurrences for a fault [Section titled “Get a count of occurrences for a fault”](#get-a-count-of-occurrences-for-a-fault) ```bash curl -u AUTH_TOKEN: https://app.honeybadger.io/v2/projects/ID/faults/ID/occurrences ``` Provides the number of times errors have been encountered for a particular fault. ```json [ [ 1510963200, 1 ], [ 1511049600, 0 ], [ 1511136000, 0 ], [ 1511222400, 1 ], ... ] ``` The data can be filtered with these URL parameters: | Parameter | Description | | --------- | ------------------------------------------------------------ | | `period` | One of “hour”, “day”, “week”, or “month”. Defaults to “hour” | ## Pausing and unpausing faults [Section titled “Pausing and unpausing faults”](#pausing-and-unpausing-faults) You can pause notifications for a period of time or for the number of occurrences of a fault. This doesn’t affect the resolved/unresolved status. If a fault is resolved while paused, new occurrences will still mark it as unresolved — you just won’t be notified about it. For time-based pauses, notifications resume on the first occurrence received after the time period has elapsed. For count-based pauses, notifications resume on the occurrence that exhausts the count. In both cases, a notification will be sent even if the fault was already reopened by an earlier occurrence during the pause. ```bash curl -u AUTH_TOKEN: -X POST -H 'Content-type: application/json' -d '{"time":"day"}' https://app.honeybadger.io/v2/projects/ID/faults/ID/pause curl -u AUTH_TOKEN: -X POST -H 'Content-type: application/json' -d '{"count":100}' https://app.honeybadger.io/v2/projects/ID/faults/ID/pause ``` Valid values for `time` are “hour”, “day”, and “week”, and valid values for `count` are 10, 100, and 1000. You can clear the pause for a fault, or for all of a project’s faults: ```bash curl -u AUTH_TOKEN: -X POST https://app.honeybadger.io/v2/projects/ID/faults/ID/unpause curl -u AUTH_TOKEN: -X POST https://app.honeybadger.io/v2/projects/ID/faults/unpause ``` You don’t need to provide a request body for the unpause endpoints. The response body will be empty, and the status code will be 200. ## Bulk-resolving faults [Section titled “Bulk-resolving faults”](#bulk-resolving-faults) You can mark all faults for a project as resolved using this endpoint: ```bash curl -u AUTH_TOKEN: -X POST https://app.honeybadger.io/v2/projects/ID/faults/resolve ``` The faults to be resolved can be filtered with the URL parameter `q`, which is a [search string](/guides/errors/search/). Faults that are already resolved are skipped. On success the response body is empty. The status code tells you whether the update was completed or was queued: | Status | Meaning | | ------ | -------------------------------------------------------------------------------- | | 200 | Up to 1,000 faults matched. They were all resolved before the response was sent. | | 202 | More than 1,000 faults matched. The work was queued and runs in the background. | If the background work can’t be queued, the endpoint returns a 500 with an `errors` field, and nothing is resolved. Retry the request in that case. ## Linking faults to existing 3rd-party issues [Section titled “Linking faults to existing 3rd-party issues”](#linking-faults-to-existing-3rd-party-issues) ```bash curl -u AUTH_TOKEN: -H 'Content-type: application/json' -d '{"channel_id":123, "data":{"number":42}}' -X POST https://app.honeybadger.io/v2/projects/ID/faults/ID/link ``` This associates an existing GitHub issue, Pivotal Tracker story, etc. with a fault. Once associated, the error detail page in the UI will include a link to the associated issue. The `channel_id` portion of the payload can be obtained from the [integrations](/api/projects#get-a-list-of-integrations-for-a-project) API endpoint. The `data` portion of the payload varies depending on which type of integration is being referenced: ### GitHub [Section titled “GitHub”](#github) | Field name | type | Description | | ---------- | ------- | -------------------------------------------------------------------------------------------- | | `number` | integer | The issue number at the end of the issue URL: \*\* | ### Jira [Section titled “Jira”](#jira) | Field name | type | Description | | ---------- | ------- | -------------------------------------------------------------------------------------------------- | | `id` | integer | The issue id at the end of the issue URL: \*\* | | `key` | string | The issue label: HB-123 | | `self` | url | The issue URL: | ### Pivotal Tracker [Section titled “Pivotal Tracker”](#pivotal-tracker) | Field name | type | Description | | ------------- | ------- | -------------------------------------------------------------------------------------------------- | | `story_id` | integer | The story number at the end of the story URL: \*\* | | `project_id` | integer | The Pivotal Tracker project ID | | `pivotal_url` | url | The story URL: | ### Trello [Section titled “Trello”](#trello) | Field name | type | Description | | ---------- | ------ | ------------------------------------------------------------------ | | `id` | string | The card ID, e.g. 60ca3275a482444bcaae2a8a | | `shortUrl` | url | Shortened version of the card URL: | This endpoint is also used to update an existing link (e.g., to change the issue number for a linked GitHub issue). ## Unlinking faults [Section titled “Unlinking faults”](#unlinking-faults) ```bash curl -u AUTH_TOKEN: -H 'Content-type: application/json' -d '{"channel_id":123}' -X POST https://app.honeybadger.io/v2/projects/ID/faults/ID/unlink ``` This removes the link to an associated GitHub issue, Pivotal Tracker story, etc. The `channel_id` portion of the payload can be obtained from the [integrations](/api/projects/#get-a-list-of-integrations-for-a-project) API endpoint. ## Get a list of notices [Section titled “Get a list of notices”](#get-a-list-of-notices) ```bash curl -u AUTH_TOKEN: https://app.honeybadger.io/v2/projects/ID/faults/ID/notices ``` Returns a list of notices for the given fault with the following format: ```json { "created_at": "2013-02-11T19:18:31.123931Z", "environment": { "environment_name": "development", "hostname": "apollo.local", "project_root": { "path": "/Users/bob/code/crywolf" } }, "cookies" { ... }, "fault_id": 2, "id": "f78391e4-7789-49f0-888e-5f6c07a222f2", "url": "https://app.honeybadger.io/projects/1/faults/2/d23e5f62-747f-11e2-a65e-4f2716edc8b7" "message": "RuntimeError: This is a runtime error", "web_environment": { "CONTENT_LENGTH": "82", "CONTENT_TYPE": "application/x-www-form-urlencoded", "HTTP_USER_AGENT": "Mozilla/5.0 (Macintosh; Intel Mac OS X 10_7_4) AppleWebKit/537.4 (KHTML, like Gecko) Chrome/22.0.1229.79 Safari/537.4", ... }, "request": { "action": "runtime_error", "component": "pages", "context": { "cart_id": "8EF99AFC-B4DB-4FC5-A92A-9A6F86ABD364" }, "params": { "_method": "post", "a": "1", "action": "runtime_error", "authenticity_token": "...", "b": "2", "controller": "pages" }, "session": { "_csrf_token": "...", "session_id": "..." }, "url": "http://example.com/pages/runtime_error?a=1&b=2", "user": { "email": "foo@bar.com", "id": 1 } }, "backtrace": [ { "number": "4", "file": "/Users/westley/code/crywolf/app/controllers/pages_controller.rb", "method": "runtime_error" }, ... ], "application_trace": [] } ``` The notice list can be filtered with these URL parameters: | Parameter | Description | | ---------------- | ---------------------------------------------------- | | `created_after` | A Unix timestamp (number of seconds since the epoch) | | `created_before` | A Unix timestamp (number of seconds since the epoch) | | `limit` | Number of results to return (max and default are 25) | The notice list is always ordered by creation time descending. ## Get a list of affected users [Section titled “Get a list of affected users”](#get-a-list-of-affected-users) ```bash curl -u AUTH_TOKEN: https://app.honeybadger.io/v2/projects/ID/faults/ID/affected_users ``` Returns a list of the users who were affected by an error: ```json [ { "user": "bob@example.com", "count": 4 }, { "user": "ann@example.com", "count": 1 } ] ``` The data can be filtered with the URL parameter `q`, which is a [search string](/guides/errors/search/). # Data API > Get started with Honeybadger's REST API including authentication, rate limits, and basic usage examples. Our REST Data API can be used to access the data stored in your Honeybadger account and to make changes to your account data. To learn about reporting exception data, deployments, and other events, check out the [API](/api/) documentation. ## Glossary [Section titled “Glossary”](#glossary) The resource names used by the API may be different from those used in our web UI. Here is a glossary of the most important resource names: * **Project:** A container that holds all your data for a single app or service. * **Fault:** Called an “error” in the web UI. It has many Notices. * **Notice:** Called an “error occurrence” in the web UI. * **Site:** Called an “uptime check” in the web UI. * **CheckIn:** Manages dead-man-switch checks. * **Team:** Connects Honeybadger users to projects. * **TeamInvitation:** Invites a user to join a team. ## Authentication [Section titled “Authentication”](#authentication) Authentication to the API is performed via [HTTP Basic Auth](http://en.wikipedia.org/wiki/Basic_access_authentication). Each request should be sent with your personal authentication token (available from [your profile page](https://app.honeybadger.io/users/edit)) as the basic auth username value. You do not need to provide a password. For example, you can request your projects list with `curl` like so (the trailing colon after the token prevents curl from asking for a password): ```bash curl -u AUTH_TOKEN: https://app.honeybadger.io/v2/projects ``` ## Rate limiting [Section titled “Rate limiting”](#rate-limiting) You can make up to 360 requests per hour to our API. After you reach the limit for the hour, additional requests will receive a response with the 403 (Forbidden) status code. The following headers, returned with every API response, can provide you the information about your rate limit: | Header | Description | | ----------------------- | ----------------------------------------------------------------------------------------------------------------- | | `X-RateLimit-Limit` | The number of requests that you can make per hour | | `X-RateLimit-Remaining` | The number of requests you can make before getting an error | | `X-RateLimit-Reset` | A Unix timestamp (number of seconds since the epoch) when remaining requests counter will be reset to the maximum | ## Format [Section titled “Format”](#format) The API returns JSON by default, but you should include `Accept: application/json` in your request headers. Lists of items are always paginated, even if there is only one page of results. The general response format for a list is as follows: ```json { "links": { "self": "https://app.honeybadger.io/v2/...", "next": "https://app.honeybadger.io/v2/..." } "results": [ { ... }, { ... } ] } ``` You can get the page after the current page by loading the value found in the `next` element of the `links` hash and the page before the current page by loading the value found in the `prev` element of the links hash. Either or both of those elements may be missing from the links hash if we can determine there is no next page or previous page of results. On the other hand, there may be a next link that, when loaded, results in no records being found — in which case, the `results` top-level element will be an empty array. ## Requests and responses [Section titled “Requests and responses”](#requests-and-responses) When you create or update resources, send the request (via POST for creations or PUT for updates) with the `Content-type` header as application/json, the `Accept` header as application/json and the request body as a valid json object. No request body is required for deleting a resource via the DELETE method. A successful POST request will return a 201 status code and the JSON representation of the just-created resource as the response body. A PUT request that successfully updates an object will return a 204 status code with no response body. Responses for successful DELETE requests return a status code of 204 and an empty response body. Requests that result in errors will return a JSON response body like so: ```json { "errors": "Reason for error" } ``` The status code will be 403 if there is a permissions problem, 422 if the request was invalid, or in the 500 range if something unexpected happened. # Insights API reference > API reference for querying data with Insights. ## Query Insights data [Section titled “Query Insights data”](#query-insights-data) This endpoint executes a BadgerQL query against your project’s Insights data and returns the results. ```bash curl -u AUTH_TOKEN: -X POST -H 'Content-type: application/json' -d '{"query":"fields @ts, @preview | limit 3"}' https://app.honeybadger.io/v2/projects/ID/insights/queries ``` The following fields can be provided in the request body: | Field name | Type | Description | | ------------ | ------ | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ | | `query` | string | A [BadgerQL query string](/guides/insights/badgerql/) to execute against your Insights data | | `ts` | string | Optional timestamp range (defaults to `PT3H`). Accepts shortcuts (`today`, `week`) or ISO 8601 formats: durations (`P8D`), datetimes (`2021-12-14T22:14:08`), time intervals (`2021-12-10T00:00/2021-12-12T00:00`), or duration intervals (`P1W/P0D`). | | `timezone` | string | Optional timezone for timestamp interpretation. Must be a valid IANA timezone identifier (e.g., `America/New_York`, `UTC`, `Europe/London`). | | `stream_ids` | array | Optional list of [Insights stream IDs](/api/streams/) to query. Defaults to all streams on the project. IDs that don’t belong to the project are ignored. | Returns the query results with the following format: ```json { "results": [ { "@ts": "2025-11-18 11:40:05.802", "@preview": "{\"ctx.class\":\"UptimeWorker\",\"ctx.elapsed\":0.297,\"ctx.jid\":\"aed85cd96b60c142b8c9b835\",\"lvl\":\"INFO\",\"msg\":\"done\",\"pid\":1,\"tid\":\"1knd\"}" }, { "@ts": "2025-11-18 11:40:05.812", "@preview": "{\"ctx.class\":\"UptimeWorker\",\"ctx.elapsed\":0.198,\"ctx.jid\":\"dfb0be7609bb3d4747efb5fd\",\"lvl\":\"INFO\",\"msg\":\"done\",\"pid\":1,\"tid\":\"1kp5\"}" }, { "@ts": "2025-11-18 11:40:05.813", "@preview": "{\"ctx.class\":\"FaultMetricWorker\",\"ctx.elapsed\":0.22,\"ctx.jid\":\"f1f3b3a9b9d874ba82e97590\",\"lvl\":\"INFO\",\"msg\":\"done\",\"pid\":1,\"tid\":\"1ksp\"}" } ], "meta": { "query": "fields @ts, @preview | limit 3", "fields": [ "@ts", "@preview" ], "schema": [ { "name": "@ts", "type": "datetime" }, { "name": "@preview", "type": "json" } ], "row_count": 3, "total_count": 3, "start_at": "2025-11-18 11:11:26", "end_at": "2025-11-18 14:11:26" } } ``` The response includes: | Field name | Type | Description | | ------------------ | ------ | ------------------------------------------------- | | `results` | array | Array of objects containing the query results | | `meta.query` | string | The query that was executed | | `meta.fields` | array | List of fields included in the results | | `meta.schema` | array | Schema information for each field (name and type) | | `meta.row_count` | number | Number of rows returned in this response | | `meta.total_count` | number | Total number of rows matching the query | | `meta.start_at` | string | Start of the time range for the query | | `meta.end_at` | string | End of the time range for the query | Please see the [BadgerQL guide](/guides/insights/badgerql/) for the query syntax to use for the `query` field. # Projects API reference > API reference for managing projects with endpoints to create, retrieve, update, and delete resources, and fetch reports. ## Get a project list or project details [Section titled “Get a project list or project details”](#get-a-project-list-or-project-details) ```bash curl -u AUTH_TOKEN: https://app.honeybadger.io/v2/projects?account_id=ACCOUNT_ID curl -u AUTH_TOKEN: https://app.honeybadger.io/v2/projects/ID ``` Returns a list or a single project with the following format: ```json { "active": true, "created_at": "2012-06-09T20:33:27.798800Z", "disable_public_links": false, "earliest_notice_at": "2015-12-18T19:30:32.470689Z", "environments": ["development", "production"], "fault_count": 14, "id": 1, "last_notice_at": "2016-06-14T18:31:54.000000Z", "name": "Rails exception tracking gem", "owner": { "email": "westley@honeybadger.io", "id": 1, "name": "Westley" }, "purge_days": 30, "resolve_errors_on_deploy": true, "sites": [ { "active": true, "id": "9eed6a7e-af77-4cc6-8c55-7a5afa59a90b", "last_checked_at": "2016-06-15T12:57:29.646956Z", "name": "Main site", "state": "up", "url": "http://www.example.com" } ], "streams": [ { "id": "a1b2c3d4e5f6", "name": "Default", "slug": "default", "internal": false, "project_id": 1, "created_at": "2026-07-15T13:56:29.513358Z" }, { "id": "f6e5d4c3b2a1", "name": "Internal", "slug": "internal", "internal": true, "project_id": 1, "created_at": "2026-07-15T13:56:29.513358Z" } ], "teams": [ { "id": 1, "name": "Team Marie" } ], "token": "098sflj2", "unresolved_fault_count": 1, "users": [ { "email": "inigo@honeybadger.io", "id": 2, "name": "Inigo Montoya" }, { "email": "westley@honeybadger.io", "id": 1, "name": "Westley" } ] } ``` If the `account_id` parameter is not supplied when requesting the list of projects, all projects will be returned across all accounts to which the provided AUTH\_TOKEN has access. `purge_days` is `null` when the project has no explicit retention setting of its own, in which case data is retained for the maximum number of days available to your subscription plan. ## Create a project [Section titled “Create a project”](#create-a-project) ```bash curl -u AUTH_TOKEN: \ -X POST \ -H 'Content-type: application/json' \ -d '{"project":{"name":"My project"}}' \ https://app.honeybadger.io/v2/projects?account_id=ACCOUNT_ID ``` Here is a list of the fields that can be provided: | Field name | Type | Description | | -------------------------- | ------- | ---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | | `name` | string | | | `resolve_errors_on_deploy` | boolean | Whether all unresolved faults should be marked as resolved when a deploy is recorded | | `disable_public_links` | boolean | Whether to allow fault details to be publicly shareable via a button on the fault detail page | | `language` | string | One of “js”, “elixir”, “golang”, “java”, “node”, “php”, “python”, “ruby”, or “other” | | `user_url` | string | A URL format like `"http://example.com/admin/users/[user_id]"` that will be displayed on the fault detail page and have \[user\_id] replaced with the user\_id from the fault’s context hash. | | `source_url` | string | A URL format like `"https://gitlab.com/username/reponame/blob/[sha]/[file]#L[line]"` that is used to link lines in the backtrace to your git browser. This can be left blank if you provide the repository info in your deploy payloads or if you use the GitHub integration for your project. | | `purge_days` | integer | The number of days to retain data (up to the max number of days available to your subscription plan). | | `user_search_field` | string | A field such as “context.user\_email” that you provide in your error context. This field will be used to create the aggregated list of affected users. | If the `account_id` query parameter is not provided, the project will be associated with the first account accessible by the user associated with the AUTH\_TOKEN. ## Update a project [Section titled “Update a project”](#update-a-project) ```bash curl -u AUTH_TOKEN: -X PUT -H 'Content-type: application/json' -d '{"project":{"name":"Updated project name"}}' https://app.honeybadger.io/v2/projects/ID ``` The fields listed in the prior section are also available when updating a project. ## Delete a project [Section titled “Delete a project”](#delete-a-project) ```bash curl -u AUTH_TOKEN: -X DELETE https://app.honeybadger.io/v2/projects/ID ``` ## Get a count of occurrences for all projects or a single project [Section titled “Get a count of occurrences for all projects or a single project”](#get-a-count-of-occurrences-for-all-projects-or-a-single-project) ```bash curl -u AUTH_TOKEN: https://app.honeybadger.io/v2/projects/occurrences curl -u AUTH_TOKEN: https://app.honeybadger.io/v2/projects/ID/occurrences ``` Provides the number of times errors have been encountered in your project or across all your projects. ```json [ [ 1510963200, 1440 ], [ 1511049600, 1441 ], [ 1511136000, 1441 ], [ 1511222400, 1441 ], ... ] ``` The data is returned as an array of epoch seconds/count pairs, and it can be filtered with these URL parameters: | Parameter | Description | | ------------- | ------------------------------------------------------------ | | `period` | One of “hour”, “day”, “week”, or “month”. Defaults to “hour” | | `environment` | Limit results to this environment | When the period is “hour” (the default), the data returned is the most recent 60 one-minute buckets. When it is “day”, the data comes from the most recent 24 one-hour buckets, and when it is “week” or “month”, the data is grouped into one-day buckets. All times and bucket boundaries are UTC. ## Get a list of integrations for a project [Section titled “Get a list of integrations for a project”](#get-a-list-of-integrations-for-a-project) ```bash curl -u AUTH_TOKEN: https://app.honeybadger.io/v2/projects/ID/integrations ``` Returns a list of integrations (a.k.a. channels) for a project: ```json [ { "id": 9693, "active": false, "events": ["occurred", "assigned"], "site_ids": ["605e7c8e-e6c8-4102-a8f8-37a9431ee78be"], "options": { "url": "http://requestb.in/7d87eae" }, "excluded_environments": [], "filters": [], "type": "WebHook" } ] ``` The `options` element varies depending on the type of integration. ## Get report data [Section titled “Get report data”](#get-report-data) The following endpoints provide the data that is displayed on the Reports tab for a project. These URL parameters can be used to filter the data returned by each of the report endpoints: | Parameter | Description | | ------------- | ---------------------------------------------------------------------- | | `start` | Date/time in ISO 8601 format for the beginning of the reporting period | | `stop` | Date/time in ISO 8601 format for the end of the reporting period | | `environment` | Limit results to this environment | ### Notices by class [Section titled “Notices by class”](#notices-by-class) ```bash curl -u AUTH_TOKEN: https://app.honeybadger.io/v2/projects/ID/reports/notices_by_class ``` Returns a count of error notifications processed, grouped by class. ```json [ ["RuntimeError", 8347], ["SocketError", 4651] ] ``` ### Notices by location [Section titled “Notices by location”](#notices-by-location) ```bash curl -u AUTH_TOKEN: https://app.honeybadger.io/v2/projects/ID/reports/notices_by_location ``` Returns a count of error notifications processed, grouped by location. The location is framework-dependent; e.g., for Rails applications it’s a combination of the controller and the action. ```json [ ["inquiries#create", 2904], ["members#details", 862] ] ``` ### Notices by user [Section titled “Notices by user”](#notices-by-user) ```bash curl -u AUTH_TOKEN: https://app.honeybadger.io/v2/projects/ID/reports/notices_by_user ``` Returns a count of error notifications processed, grouped by user (assuming you are providing user\_id and/or user\_email in the context). ```json [ ["julia@example.com", 579], ["marie@example.com", 289] ] ``` ### Notices by day [Section titled “Notices by day”](#notices-by-day) ```bash curl -u AUTH_TOKEN: https://app.honeybadger.io/v2/projects/ID/reports/notices_per_day ``` Returns a count of error notifications processed, grouped by day (with days starting at midnight UTC). ```json [ ["2023-01-24T00:00:00.000000+00:00", 3161], ["2023-01-25T00:00:00.000000+00:00", 2620], ["2023-01-26T00:00:00.000000+00:00", 2852], ["2023-01-27T00:00:00.000000+00:00", 2502], ["2023-01-28T00:00:00.000000+00:00", 1759], ["2023-01-29T00:00:00.000000+00:00", 1420], ["2023-01-30T00:00:00.000000+00:00", 3027], ["2023-01-31T00:00:00.000000+00:00", 1624] ] ``` # Reporting check-ins > API reference for reporting check-ins to Honeybadger to monitor scheduled tasks and cron jobs. To report a check-in, simply send a GET request to the endpoint URL you received when creating the check-in: ```bash curl https://api.honeybadger.io/v1/check_in/XyZZy ``` You can also send an email (no subject or body required) to `XyZZy@report.hbchk.in`, where `XyZZy` is the same (case-sensitive) ID from the endpoint URL. If you specify a [slug](/guides/check-ins/#slugs) for a check-in, you can use that slug and the project’s API key in the URL rather than the ID: ```bash curl https://api.honeybadger.io/v1/check_in/PROJECT_API_KEY/my_identifier ``` ## Check-in payloads [Section titled “Check-in payloads”](#check-in-payloads) Business-tier accounts can send additional check-in details via POST. The payload is optional and must be under 20KB. ```bash curl -X POST https://api.honeybadger.io/v1/check_in/XyZZy \ -H "Content-Type: application/json" \ -d '{ "check_in": { "status": "success", "duration": 1234, "stdout": "backup completed", "stderr": "", "exit_code": 0 } }' ``` The `check_in` object supports: * `status` (string): `success` or `error` * `duration` (integer): milliseconds * `stdout` (string): captured standard output * `stderr` (string): captured standard error * `exit_code` (integer): process exit code The data sent with the `check_in` object will be sent to [Insights](/guides/insights/) as part of the check-in event. You can find more information on using check-ins [here](/guides/check-ins/). # Reporting deployments > API reference for reporting deployments to Honeybadger. Use this endpoint to notify Honeybadger when a deploy occurs. For an overview of all reporting methods, see the [Deployments guide](/guides/deployments/#reporting-deployments). ## POST /v1/deploys [Section titled “POST /v1/deploys”](#post-v1deploys) Make a POST request to `https://api.honeybadger.io/v1/deploys` with the following parameters: | Parameter | Required | Description | | ------------------------ | -------- | --------------------------------------------------------------------------------------------------------------------------- | | api\_key | Required | Your project’s API key | | deploy\[environment] | Optional | The environment name. Example: `production` | | deploy\[revision] | Optional | The VCS revision being deployed. Could be a git hash, or a tag name. Example: `7cd4bac1bd7e2ddf858d10ee86e362c8d8e2f912` | | deploy\[repository] | Optional | The base URL of the VCS repository. It should be HTTPS-style. Example: `https://github.com/honeybadger-io/honeybadger-ruby` | | deploy\[local\_username] | Optional | The name of the user who is deploying. Example: `Jane` | Example `curl` command: ```sh HONEYBADGER_ENV="production" \ HONEYBADGER_REVISION="$(git rev-parse HEAD)" \ HONEYBADGER_REPOSITORY="$(git config --get remote.origin.url)" \ HONEYBADGER_API_KEY="Your project API key" \ && curl -g "https://api.honeybadger.io/v1/deploys?deploy[environment]=$HONEYBADGER_ENV&deploy[local_username]=$USER&deploy[revision]=$HONEYBADGER_REVISION&deploy[repository]=$HONEYBADGER_REPOSITORY&api_key=$HONEYBADGER_API_KEY" ``` You can also send a JSON payload with `Content-Type: application/json`: ```bash curl https://api.honeybadger.io/v1/deploys \ -H 'X-API-Key: Your project API key' \ -H 'Content-Type: application/json' \ -H 'Accept: application/json' \ -d '{ "deploy": { "environment": "production", "local_username": "sam", "revision": "7cd4bac1bd7e2ddf858d10ee86e362c8d8e2f912", "repository": "https://github.com/someuser/somerepo" } }' ``` A successful response returns `{"status":"OK"}`. # Reporting events > API reference for sending events to Honeybadger Insights for monitoring and analysis. Events you send to this API will appear in [Honeybadger Insights](/guides/insights), where you can query and visualize the events. Your [newline-delimited JSON](https://en.wikipedia.org/wiki/JSON_streaming#Newline-Delimited_JSON) payload should be submitted as the body of a POST request to with the following headers: * X-API-Key: The API key from your project settings page * Accept: application/json * User-Agent: ”{{ Client name }} {{ client version }}; {{ language version }}; {{ platform }}” Regarding the format of the User-Agent header, you can see an example of how that’s generated in our Ruby implementation [here](https://github.com/honeybadger-io/honeybadger-ruby/blob/991d7cb85ea3f224d6cf0943a87f690de9f9b051/lib/honeybadger/util/http.rb#L21), which generates a string like this: `HB-Ruby 2.1.1; 2.2.7; x86_64-linux-gnu`. If you don’t have all this information available to send, that’s OK, but the more the merrier. :) If all went well with your POST, you’ll get a response with the status code 201 and information about the just-logged error as a JSON hash. If all *didn’t* go well, you could get a response with one of these status codes: | Status Code | Description | | ----------- | ------------------------------------------------------------------------------------------------------------------------------------------------ | | `403` | Either the API key is incorrect or the account has been deactivated | | `413` | The payload size was too large. The maximum acceptable size is 102,400 bytes | | `422` | The payload couldn’t be processed. | | `429` | The API key was valid, but the payload was not accepted because you hit a rate limit (i.e., we have received too much traffic for this API key). | | `500` | Our bad! :) | ## Sample payloads [Section titled “Sample payloads”](#sample-payloads) Each line of the payload must be a single JSON object. The structure of the events you send to this endpoint is up to you, based on your use case. For example, if you wanted to send lines from an unstructured log, you could send a payload like this: ```json {"ts": "2023-08-31T09:19:30Z", "message": "This is a log line"} {"ts": "2023-08-31T09:19:30Z", "message": "This is another log line"} ``` We strongly recommend you send structured logs to make querying a better experience: ```json { "ts": "2023-08-31T16:17:57Z", "level": "info", "action": "health", "controller": "PagesController", "method": "GET", "path": "/health", "status": 200, "duration": 322 } ``` Sending events in this way would make it easy to do analytical queries like average request duration, counts by request path, etc. Of course, you aren’t limited to logs — you can track any kind of event that makes sense for your application: ```json {"ts": "2023-08-31T14:31:05Z", "event": "user.signup", "user": {"id": 42, "source": "Daring Fireball Ad"}} {"ts": "2023-08-31T14:33:05Z", "event": "company.created", "project": {"id": 54, "name": "Spacely Space Sprockets", "shared": true}} ``` You do not need to include a `ts` element in each JSON object, but if you do, it must be an [RFC3339](https://www.rfc-editor.org/rfc/rfc3339)-formatted timestamp. If `ts` is omitted, or if it can’t be parsed as a timestamp, it will be added or replaced with the value of the current time as of the payload being processed. ## Setting default fields with a query parameter [Section titled “Setting default fields with a query parameter”](#setting-default-fields-with-a-query-parameter) You can pass a `defaults` query parameter containing a URL-encoded JSON object, and its fields will be merged into every event in the batch: ```plaintext POST https://api.honeybadger.io/v1/events?defaults={"environment":"production","region":"us-east-1"} ``` With that parameter, this payload: ```json {"message": "This is a log line"} {"message": "This is another log line", "environment": "staging"} ``` …is stored as: ```json {"message": "This is a log line", "environment": "production", "region": "us-east-1"} {"message": "This is another log line", "environment": "staging", "region": "us-east-1"} ``` Fields already present in an event always win — a default never overwrites data you send in the payload. The `defaults` parameter has a few restrictions: * It must be a flat JSON object; values must be strings, numbers, or booleans. * The keys `event_type` and `ts` are reserved and will be ignored. * It’s limited to 16 keys and 2kB (URL-decoded). * The 100kB per-event size limit applies to events after defaults are merged. An invalid `defaults` parameter never causes the request to fail: entries that break the rules above are dropped (an unparseable or oversized parameter is ignored entirely), and the events are ingested as sent. ## Sending events from log files and other sources [Section titled “Sending events from log files and other sources”](#sending-events-from-log-files-and-other-sources) Check out our instructions on how to add data from other sources, like your log files, Heroku apps, etc., in our [Insights Guide](/guides/insights#adding-data-from-other-sources). ## Limits [Section titled “Limits”](#limits) Nested JSON structures are supported, but limiting the nesting to 2 or 3 levels is best. Each event must be less than 100kB, and the total request size must be less than 5MB. Information about the quotas for this endpoint can be found [here](/resources/quotas/#insights). # Reporting errors > API reference for reporting exceptions to Honeybadger with request formats, parameters, and response structures. Your JSON payload should be submitted as the body of a POST request to , with the following headers: * X-API-Key: The API key from your project settings page * Content-Type: application/json * Accept: application/json * User-Agent: ”{{ Client name }} {{ client version }}; {{ language version }}; {{ platform }}” Regarding the format of the User-Agent header, you can see an example of how that’s generated in our Ruby implementation [here](https://github.com/honeybadger-io/honeybadger-ruby/blob/991d7cb85ea3f224d6cf0943a87f690de9f9b051/lib/honeybadger/util/http.rb#L21), which generates a string like this: `HB-Ruby 2.1.1; 2.2.7; x86_64-linux-gnu`. If you don’t have all this information available to send, that’s OK, but the more the merrier. :) If all went well with your POST, you’ll get a response with the status code 201 and information about the just-logged error as a JSON hash: ```json { "id": "6840eec9-6903-4f13-b511-b91ee46fda6a" } ``` You can use that ID to jump directly to the error in our UI: E.g., `https://app.honeybadger.io/notice/6840eec9-6903-4f13-b511-b91ee46fda6a` If all *didn’t* go well, you could get a response with one of these status codes: | Status Code | Description | | ----------- | -------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | | `403` | Either the API key is incorrect or the account has been deactivated | | `413` | The payload size was too large. The maximum acceptable size is 262,144 bytes (256KB) | | `422` | The payload couldn’t be processed. Please note that we only do *minimal* checking of the payload when it hits our API. It’s entirely possible to get a 201 response, only to have the payload end up not being able to processed later in the pipeline and thus not show up in the UI. | | `429` | The API key was valid, but the payload was not accepted because you hit a rate limit (i.e., we have received too much traffic for this API key). | | `500` | Our bad! :) | ## Sample payload [Section titled “Sample payload”](#sample-payload) Your JSON will probably vary most from the example in the `request` key of the hash, which supplies info about the request made by the user, the web server environment, and so on. The `context` key of the `request` hash should have information about the logged-in user, if any, so that we can report on the users effected by application errors. The `backtrace` key of the `error` hash is essential, as that is used for grouping similar errors together in the Honeybadger UI. The `class` and `message` keys of the `error` hash are displayed in the Honeybadger UI and used for posting errors to other services, like Github issues. Here’s an annotated payload for your enjoyment: ```json { // Please use relevant values for the name, url, and version keys of the // `notifier` key that point back to your code/package. "notifier": { "name": "Honeybadger Notifier", "url": "https://github.com/honeybadger-io/honeybadger-ruby", "version": "1.0.0" }, // Here's where your exception's class, message tags and backtrace go. // The `class` and `message` attributes are what make up the error's "title" that we display in the UI. // The `fingerprint` attribute is an optional string that is used to force errors with the same fingerprint (regardless of error class, message, or location) to be grouped together. // The `backtrace` is a ruby-style backtrace. If the `source` attribute is included for a backtrace line, it will be displayed as a snippet in the UI, // Last but not least, `causes` is an optional list of causes for the error. // Honeybadger displays causes in the order they are listed here. "error": { "class": "RuntimeError", "message": "RuntimeError: This is a runtime error, generated by the crywolf app", "tags": ["wubba"], "fingerprint": "optional string to force errors with the same fingerprint to be grouped together", "backtrace": [ { "number": "4", "file": "/crywolf/app/controllers/pages_controller.rb", "method": "runtime_error", "source": { "2": "", "3": " def runtime_error", "4": " raise RuntimeError.new(\"This is a runtime error, generated by the crywolf app\")", "5": " end", "6": "" } }, { "number": "4", "file": "/gems/1.9.3-p194/lib/ruby/gems/1.9.1/gems/actionpack-3.2.8/lib/action_controller/metal/implicit_render.rb", "method": "send_action" } ], "causes": [ { "class": "StandardError", "message": "StandardError: This is the first cause", "backtrace": [ { "number": "8", "file": "/crywolf/app/models/page.rb", "method": "find" }, { "number": "13", "file": "/crywolf/app/services/find.rb", "method": "call" } ] } ] }, // `breadcrumbs` are any interesting events that happened within the request leading up to the error "breadcrumbs": { "enabled": true, "trail": [ { "category": "query", "message": "Active Record", "metadata": { "sql": "SELECT ?.? FROM ? ORDER BY ?.? ASC", "connection_id": 14200, "duration": 0.0001449 }, "timestamp": "2021-03-11T23:08:45.448Z" }, { "category": "request", "message": "Action Controller Start Process", "metadata": { "controller": "PagesController", "action": "home", "format": "html", "method": "GET", "path": "/pages/home", "duration": 0.0000136 }, "timestamp": "2021-03-11T23:08:45.451Z" }, { "category": "render", "message": "Action View Template Render", "metadata": { "identifier": "/usr/lib/ruby/gems/2.7.0/gems/actionpack-6.0.3.5/lib/action_dispatch/middleware/templates/rescues/ diagnostics.html.erb", "layout": "rescues/layout", "duration": 0.0092867 }, "timestamp": "2021-03-11T23:08:45.554Z" }, { "category": "error", "message": "RuntimeError", "metadata": { "exception_message": "This is a runtime error, generated by the crywolf app" }, "timestamp": "2021-03-11T23:08:45.555Z" }, { "category": "notice", "message": "Honeybadger Notice", "metadata": { "exception": "This is a runtime error, generated by the crywolf app" }, "timestamp": "2021-03-11T23:08:45.555Z" } ] }, // `request` contains information about the HTTP request that caused this exception. "request": { // We display this data on the error's details page. // `user_id` and `user_email` are special keys that are used to generate the "affected users" list in the UI. "context": { "user_id": 123, "user_email": "test@example.com" }, // In rails this is the Controller. "component": "pages", // In rails this is the Action. "action": "runtime_error", // The URL where the error occurred "url": "http://crywolf.dev/pages/runtime_error?a=1&b=2", // These are displayed under "params" on the error detail page "params": { "_method": "post", "authenticity_token": "tuZ7y1PUEMadgKevSzgSUK6T0p267I1+NL0+rnR7xrI=", "a": "1", "b": "2", "controller": "pages", "action": "runtime_error" }, // These are displayed under "session" on the error detail page "session": { "session_id": "57fb796258046e92b3201ece44531320", "_csrf_token": "tuZ7y1PUEMadgKevSzgSUK6T0p267I1+NL0+rnR7xrI=" }, // These are displayed under "web environment" on the error detail page. // Normally you'll just include the environment variables set by your web server. "cgi_data": { "REQUEST_METHOD": "POST", "PATH_INFO": "/pages/runtime_error", "QUERY_STRING": "a=1&b=2", "SCRIPT_NAME": "", "REMOTE_ADDR": "127.0.0.1", "SERVER_ADDR": "0.0.0.0", "SERVER_NAME": "crywolf.dev", "SERVER_PORT": "80", "HTTP_HOST": "crywolf.dev", "HTTP_CONNECTION": "keep-alive", "CONTENT_LENGTH": "82", "HTTP_CACHE_CONTROL": "max-age=0", "HTTP_ORIGIN": "http://crywolf.dev", "HTTP_USER_AGENT": "Mozilla/5.0 (Macintosh; Intel Mac OS X 10_7_4) AppleWebKit/537.4", "CONTENT_TYPE": "application/x-www-form-urlencoded", "HTTP_ACCEPT": "text/html,application/xhtml+xml,application/xml;q=0.9,*/*;q=0.8", "HTTP_REFERER": "http://crywolf.dev/", "HTTP_ACCEPT_ENCODING": "gzip,deflate,sdch", "HTTP_ACCEPT_LANGUAGE": "en-US,en;q=0.8", "HTTP_ACCEPT_CHARSET": "ISO-8859-1,utf-8;q=0.7,*;q=0.3", "HTTP_COOKIE": "_crywolf_session=BAh7B0kiD3Nlc3Npb25faWQGOgZFRkkiJTU3ZmI3OTYy", "REMOTE_PORT": "52509", "ORIGINAL_FULLPATH": "/pages/runtime_error?a=1&b=2" } }, "server": { // The directory where your code lives. This helps us to display more concise paths. "project_root": "/Users/josh/code/crywolf", // Your environment name "environment_name": "development", // The server's hostname "hostname": "Josh-MacBook-Air.local", // Optional: Git sha for the deployed version of the code, for linking to GitHub, Gitlab, and BitBucket "revision": "920201a", // Optional: ID of the process that raised the error "pid": 1138 } } ``` ## Payload tester [Section titled “Payload tester”](#payload-tester) While you’re developing an error collector in your language of choice that talks to our API, you can use our [payload tester](https://app.honeybadger.io/notice/test) to see how your payloads will be rendered in our UI. # Uploading source maps > API reference for uploading source maps to Honeybadger to get readable stack traces from minified JavaScript code. Honeybadger can automatically un-minify your JavaScript code if you provide a [source map](https://web.dev/articles/source-maps) along with your minified files. Use the Source Map Upload API to upload your source maps to Honeybadger. See [Using Source Maps](/lib/javascript/errors/using-source-maps/) to learn more. ## Overview [Section titled “Overview”](#overview) To upload your source map files to Honeybadger, POST them to `https://api.honeybadger.io/v1/source_maps` with the following parameters: | Param | Required | Description | | -------------------------- | --------------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | | `api_key` | Required | The API key of your Honeybadger project (see the API Key tab in project settings). | | `minified_url` | Required | The URL of your minified JavaScript file in production. `*` can be used as a [wildcard](#wildcards). Must be an absolute URL (query strings are ignored). | | `minified_file` | Required | The minified file itself. | | `source_map` | Required | The source map for your minified file. | | revision | Optional, default: `master` | The deploy revision (i.e. commit sha) that your source map applies to. This could also be a code version. For best results, set it to something unique every time your code changes. The `revision` option must also be configured in [honeybadger.js](/lib/javascript/reference/configuration/). | | \ | Optional | One or more additional source files which may be referenced by your source map. The name should be the URL that would normally be used to access the file, and the value should be the file itself. Many source map generators include the sources in the `sourcesContent` key inside the source map, so you may not need to send these. `*` in the name can be used as a [wildcard](#wildcards). | Here’s an example using `curl`: ```bash curl https://api.honeybadger.io/v1/source_maps \ -F api_key=Your project API key \ -F revision=dcc69529edf375c72df39b0e9195d60d59db18ff \ -F minified_url=https://example.com/assets/application.min.js \ -F source_map=@path/to/application.js.map \ -F minified_file=@path/to/application.min.js \ -F http://example.com/assets/application.js=@path/to/application.js \ -F http://example.com/assets/utils.js=@path/to/utils.js ``` ## Response codes [Section titled “Response codes”](#response-codes) The `/v1/source_maps` API endpoint responds with the following codes: | Code | Status | Description | | ----- | ------------ | ---------------------------------------------------------------------------------------------------------------------- | | `201` | Created | The files were uploaded successfully. | | `400` | Bad Request | You’re missing a required parameter or have exceeded the maximum file size of 80MB per file (check the error message). | | `401` | Unauthorized | Your API key is invalid. | ## Wildcards [Section titled “Wildcards”](#wildcards) In some cases you may want to upload the same source map for different URLs—for instance, if you serve your files from multiple subdomains, or via both HTTP and HTTPS. An asterisk (`*`) can be used in URLs to perform a wildcard match. For example, the following example will match both the `http://` and `https://` version of the URL: ```plaintext http*://example.com/assets/application.min.js ``` …matches the following URLs: ```plaintext http://example.com/assets/application.min.js https://example.com/assets/application.min.js ``` Wildcards are *not* supported in file names: ```plaintext // invalid (will be an exact match): https://example.com/assets/*.min.js ``` # Status pages API reference > API reference for managing status pages with endpoints to create, read, update, and delete resources. Create and manage status pages within your accounts. ## Get all status pages [Section titled “Get all status pages”](#get-all-status-pages) ```bash curl -u AUTH_TOKEN: https://app.honeybadger.io/v2/accounts/ACCOUNT_ID/status_pages ``` Returns a list of all status pages in this account. ```json { "results": [ { "id": "rMGSZB", "name": "My Awesome Status Page", "account_id": "Me3upk", "domain": "your.custom.domain", "url": "your.custom.domain", "created_at": "2022-01-29T11:26:19.120153Z", "domain_verified_at": "2022-01-29T14:02:32.570227Z", "sites": [], "check_ins": [ { "check_in_id": "XXXXXX", "display_name": "Nightly billing", "state": "reporting", "reported_at": "2022-01-29T00:00:02.523254Z" } ] }, { "id": "vWbSWr", "name": "Really Awesome Status Page", "account_id": "Me3upk", "domain": null, "url": "vWbSWr.status.hbuptime.com", "created_at": "2022-01-29T11:09:32.570227Z", "domain_verified_at": null, "sites": [ { "site_id": "7d25f58b-d1a9-49f1-b10a-ac7ee44a6537", "display_name": "Main site", "state": "up", "last_checked_at": "2022-01-29T11:09:30.982801Z" }, { "site_id": "7d25f58b-d1a9-49f1-b10a-ac7ee44a6557", "display_name": "API", "state": "up", "last_checked_at": "2022-01-29T11:04:28.675309Z" } ], "check_ins": [] } ], "links": { "self": "http://localhost:3000/v2/accounts/4bYurk/status_pages" } } ``` ## Get a single status page’s details [Section titled “Get a single status page’s details”](#get-a-single-status-pages-details) ```bash curl -u AUTH_TOKEN: https://app.honeybadger.io/v2/accounts/ACCOUNT_ID/status_pages/ID ``` ```json { "id": "vWbSWr", "name": "Really Awesome Status Page", "account_id": "Me3upk", "domain": null, "url": "vWbSWr.status.hbuptime.com", "created_at": "2022-01-29T11:09:32.570227Z", "domain_verified_at": null, "sites": [ { "site_id": "7d25f58b-d1a9-49f1-b10a-ac7ee44a6537", "display_name": "Main site", "state": "up", "last_checked_at": "2022-01-29T11:09:30.982801Z" }, { "site_id": "7d25f58b-d1a9-49f1-b10a-ac7ee44a6557", "display_name": "API", "state": "up", "last_checked_at": "2022-01-29T11:04:28.675309Z" } ], "check_ins": [] } ``` ## Create a status page [Section titled “Create a status page”](#create-a-status-page) ```bash curl -u AUTH_TOKEN: -X POST -H 'Content-type: application/json' \ -d '{ "status_page": { "name": "Really Awesome Status Page", "domain": "your.custom.domain", "sites": [ { "site_id": "7d25f58b-d1a9-49f1-b10a-ac7ee44a6537", "display_name": "Main site" } ] } }' https://app.honeybadger.io/v2/accounts/ACCOUNT_ID/status_pages ``` You can specify these fields within the `status page` object: | Field name | Type | Description | | --------------- | --------- | ----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | | `name` | string | The name of the status page | | `domain` | string | (Optional) A custom domain for the status page. Setting this will trigger the domain DNS verification check. | | `sites` | object\[] | (Optional) Details of sites to add to this status page. Each object references a site in a project in this account, and must contain the `site_id` and an optional `display_name` and `position`. The `position` field is a zero-indexed integer that controls how your sites will be ordered on the status page. | | `check_ins` | object\[] | (Optional) Details of check-ins to add to this status page. Each object references a check-in in a project in this account, and must contain the `check_in_id` and an optional `display_name` and `position`. The `position` field is a zero-indexed integer that controls how your check-ins will be ordered on the status page. | | `hide_branding` | boolean | Whether or not to hide the Honeybadger branding in the footer of the status page. Only available on the Team plan and above. | | features | object | Additional customization options only available on the Team plan and above. Available options:- `home_link`: URL to hyperlink the status page title or logo to. - `up_caption`: The caption displayed when all checks are passing. - `down_caption`: The caption displayed when all checks are failing. - `mixed_caption`: The caption displayed when some checks are failing. - `custom_css`: Custom CSS that will be injected into the status page. | Returns a 201 Created response containing the created status page’s details. ## Update a status page [Section titled “Update a status page”](#update-a-status-page) ```bash curl -u AUTH_TOKEN: -X PUT -H 'Content-type: application/json' \ -d '{ "status_page": { "domain": "different.custom.domain", "sites": [ { "site_id": "7d25f58b-d1a9-49f1-b10a-ac7ee44a6537", "display_name": "Main site" } ] } }' https://app.honeybadger.io/v2/accounts/ACCOUNT_ID/status_pages/ID ``` You can specify one or more of these fields within the `status page` object: | Field name | Type | Description | | --------------- | --------- | ----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | | `name` | string | The name of the status page | | `domain` | string | A custom domain for the status page. Changing this will trigger the domain DNS verification check. | | `sites` | object\[] | Details of sites to add to this status page. Each object references a site in a project in this account, and must contain the `site_id` and an optional `display_name`. | | `hide_branding` | boolean | Whether or not to hide the Honeybadger branding in the footer of the status page. Only available on the Team plan and above. | | `features` | object | Additional customization options only available on the Team plan and above. Available options:- `home_link`: URL to hyperlink the status page title or logo to. - `up_caption`: The caption displayed when all checks are passing. - `down_caption`: The caption displayed when all checks are failing. - `mixed_caption`: The caption displayed when some checks are failing. - `custom_css`: Custom CSS that will be injected into the status page. | Returns an empty response (204 No Content) if successful. ## Delete a status page [Section titled “Delete a status page”](#delete-a-status-page) ```bash curl -u AUTH_TOKEN: -X DELETE https://app.honeybadger.io/v2/accounts/ACCOUNT_ID/status_pages/ID ``` Returns an empty response (204 No Content) if successful. # Streams API reference > API reference for listing Insights streams and retrieving their IDs for use in queries and alarms. Insights events live in streams. Every project has two built-in streams: `default`, which receives events sent by your applications, and `internal`, which receives Honeybadger-generated events such as error occurrences, deployments, uptime checks, and check-ins. Use stream IDs in the `stream_ids` request field to choose which streams [Insights queries](/api/insights/) and [alarms](/api/alarms/) search. ## Get all streams [Section titled “Get all streams”](#get-all-streams) ```bash curl -u AUTH_TOKEN: https://app.honeybadger.io/v2/projects/ID/streams ``` Returns a list of the project’s streams. ```json { "results": [ { "id": "a1b2c3d4e5f6", "name": "Default", "slug": "default", "internal": false, "project_id": 1, "created_at": "2026-07-15T13:56:29.513358Z" }, { "id": "f6e5d4c3b2a1", "name": "Internal", "slug": "internal", "internal": true, "project_id": 1, "created_at": "2026-07-15T13:56:29.513358Z" } ], "links": { "self": "https://app.honeybadger.io/v2/projects/1/streams" } } ``` | Field name | Type | Description | | ------------ | ------- | ------------------------------------------------------------------------------------------------------ | | `id` | string | The stream ID accepted by the `stream_ids` request field in Insights queries and alarms. | | `name` | string | The stream’s display name. | | `slug` | string | The stable identifier for the stream’s role: `default` or `internal`. | | `internal` | boolean | Whether the stream holds Honeybadger-generated events (`notice`, `deploy`, `uptime_check`, and so on). | | `project_id` | integer | The project the stream belongs to. | | `created_at` | string | The ISO 8601 timestamp when the stream was created. | Streams also appear in the `streams` array of [project payloads](/api/projects/). ## Notes [Section titled “Notes”](#notes) * Stream selection is per-project. IDs that don’t belong to the project (whether unknown or from another project) are silently ignored. A request containing those IDs may therefore return fewer results than expected instead of an error. * Streams are provisioned asynchronously after project creation, so a just-created project’s stream list may be empty or partial for a short time. Retry the request before concluding that streams are missing. # Teams API reference > API reference for managing teams with endpoints to retrieve and update team members and permissions. ## Get a team list or team details [Section titled “Get a team list or team details”](#get-a-team-list-or-team-details) ```bash curl -u AUTH_TOKEN: https://app.honeybadger.io/v2/teams?account_id=ACCOUNT_ID curl -u AUTH_TOKEN: https://app.honeybadger.io/v2/teams/ID ``` Returns a list of teams ```json { "id": 1, "name": "The Avengers", "created_at": "2013-01-11T15:40:35Z", "owner": { "id": 1, "email": "thor@example.org", "name": "Thor" }, "members": [...], "projects": [...], "invitations": [...] } ``` If the `account_id` parameter is not supplied when requesting the list of teams, all teams will be returned across all accounts to which the provided AUTH\_TOKEN has access. ## Create a team [Section titled “Create a team”](#create-a-team) ```bash curl -u AUTH_TOKEN: -X POST -H 'Content-type: application/json' -d '{"team":{"name":"My team"}}' https://app.honeybadger.io/v2/teams?account_id=ACCOUNT_ID ``` You can specify these fields: | Field name | Type | Description | | ---------- | ------ | ----------- | | `name` | string | | If the `account_id` query parameter is not provided, the team will be associated with the first account accessible by the user associated with the AUTH\_TOKEN. ## Update a team [Section titled “Update a team”](#update-a-team) ```bash curl -u AUTH_TOKEN: -X PUT -H 'Content-type: application/json' -d '{"team":{"name":"Updated team name"}}' https://app.honeybadger.io/v2/teams/ID ``` ## Delete a team [Section titled “Delete a team”](#delete-a-team) ```bash curl -u AUTH_TOKEN: -X DELETE https://app.honeybadger.io/v2/teams/ID ``` ## Get a list of team members or team member details [Section titled “Get a list of team members or team member details”](#get-a-list-of-team-members-or-team-member-details) ```bash curl -u AUTH_TOKEN: https://app.honeybadger.io/v2/teams/ID/team_members ``` Returns all the members or a single team member for the given team: ```json { "id": 1, "created_at": "2012-12-13T15:00:47Z", "admin": true, "name": "", "email": "westley@example.com" } ``` ## Update a team member [Section titled “Update a team member”](#update-a-team-member) ```bash curl -u AUTH_TOKEN: -X PUT -H 'Content-type: application/json' -d '{"team_member":{"admin":true}}' https://app.honeybadger.io/v2/teams/ID/team_members/ID ``` The list of valid fields is as follows: | Field name | Type | Description | | ---------- | ------- | ----------- | | `admin` | boolean | | ## Delete a team member [Section titled “Delete a team member”](#delete-a-team-member) ```bash curl -u AUTH_TOKEN: -X DELETE https://app.honeybadger.io/v2/teams/ID/team_members/ID ``` ## Create a team invitation [Section titled “Create a team invitation”](#create-a-team-invitation) ```bash curl -u AUTH_TOKEN: -X POST -H 'Content-type: application/json' \ -d '{"team_invitation":{"email":"inigo@example.com"}}' \ https://app.honeybadger.io/v2/teams/ID/team_invitations ``` You can specify these fields: | Field name | Type | Description | | ---------- | ------- | ------------------------------------------------------------------ | | `email` | string | The invited user’s email address. | | `admin` | boolean | (Optional) Set this to true to make the invited user a team admin. | | `message` | string | (Optional) The message to be included in the invitation email. | Returns the created team invitation: ```json { "id": 9, "email": "inigo@example.com", "created_by": { "email": "westley@example.com", "name": "Westley" }, "accepted_by": null, "admin": false, "accepted_at": null, "created_at": "2013-01-08T15:42:16Z", "message": null } ``` ## Update a team invitation [Section titled “Update a team invitation”](#update-a-team-invitation) ```bash curl -u AUTH_TOKEN: -X PUT -H 'Content-type: application/json' \ -d '{"team_invitation":{"admin": true}}' \ https://app.honeybadger.io/v2/teams/ID/team_invitations/ID ``` You can specify either of these fields: | Field name | Type | Description | | ---------- | ------- | ------------------------------------------------------- | | `admin` | boolean | Set this to true to make the invited user a team admin. | | `message` | string | The message to be included in the invitation email. | ## Get a team invitation list or team invitation details [Section titled “Get a team invitation list or team invitation details”](#get-a-team-invitation-list-or-team-invitation-details) ```bash curl -u AUTH_TOKEN: https://app.honeybadger.io/v2/teams/ID/team_invitations curl -u AUTH_TOKEN: https://app.honeybadger.io/v2/teams/ID/team_invitations/ID ``` Returns a list of team invitations or a single team invitation for the given team: ```json { "id": 9, "email": "inigo@example.com", "created_by": { "email": "westley@example.com", "name": "Westley" }, "accepted_by": { "email": "inigo@example.com", "name": "Inigo Montoya" }, "admin": true, "accepted_at": "2013-01-08T15:42:41Z", "created_at": "2013-01-08T15:42:16Z", "message": null } ``` ## Delete a team invitation [Section titled “Delete a team invitation”](#delete-a-team-invitation) ```bash curl -u AUTH_TOKEN: -X DELETE https://app.honeybadger.io/v2/teams/ID/team_invitations/ID ``` # Uptime API reference > API reference for managing uptime monitors with endpoints to create, read, update, and delete resources. ## Get a site list or site details [Section titled “Get a site list or site details”](#get-a-site-list-or-site-details) ```bash curl -u AUTH_TOKEN: https://app.honeybadger.io/v2/projects/ID/sites curl -u AUTH_TOKEN: https://app.honeybadger.io/v2/projects/ID/sites/ID ``` Returns a list of sites or a single sites for the given project with the following format: ```json { "active": true, "frequency": 5, "id": "9eed6a7e-af77-4cc6-8c55-b7b17555330d", "last_checked_at": "2016-06-15T12:57:29.646956Z", "match": null, "match_type": "success", "name": "Main site", "state": "down", "url": "http://www.example.com" } ``` ## Create a site [Section titled “Create a site”](#create-a-site) ```bash curl -u AUTH_TOKEN: -X POST -H 'Content-type: application/json' -d '{"site":{"name":"My site","url":"https://www.example.com/"}}' https://app.honeybadger.io/v2/projects/ID/sites ``` Here is a list of the fields that can be specified: | Field name | Type | Description | | ----------------- | ------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ | | `name` | string | | | `url` | string | | | `frequency` | integer | Number of minutes between checks (valid values are 1, 5, or 15). | | `match` | string | The status code that will be returned or string to be present/absent to indicate a passing check, depending on the value of `match_type`. Unused when the match\_type is “success”. | | `match_type` | string | One of “success” for a status code of 200-299, “exact” for a particular status code (provided via the `match` field), “include” to require the text in `match` to be present on the page, and “exclude” to require the text in `match` to not be present on the page. | | `request_method` | string | One of GET, POST, PUT, PATCH, or DELETE. | | `request_body` | string | The body content to be sent with the check. | | `request_headers` | array | Array of hashes (e.g., `[{ key: "Content-type", value: "application/json" }]`) that will be added to the request headers. | | `locations` | array | Array of strings (e.g, `['London', 'Virginia']`) that will limit the locations that will be used for the checks. Providing an empty array (the default) will cause all locations to be used. Available locations are Virginia, Oregon, Frankfurt, Singapore, and London. | | `validate_ssl` | boolean | Whether to have the check fail if the SSL certificate is not valid or is expired. | | `timeout` | integer | **Business and Enterprise customers only.** How long the uptime check will wait for a response before reporting the site as down (in seconds). The default is 30 seconds and the maximum is 120 seconds. | | outage\_threshold | integer | The number of unsuccessful checks required to trigger an alert. If this is blank, then an alert will be sent after half of the locations return with failed checks. | | `active` | boolean | Whether to run the checks. | ## Update a site [Section titled “Update a site”](#update-a-site) ```bash curl -u AUTH_TOKEN: -X PUT -H 'Content-type: application/json' -d '{"site":{"name":"Updated site name"}}' https://app.honeybadger.io/v2/projects/ID/sites/ID ``` Update requests can change the same fields as create requests. ## Delete a site [Section titled “Delete a site”](#delete-a-site) ```bash curl -u AUTH_TOKEN: -X DELETE https://app.honeybadger.io/v2/projects/ID/sites/ID ``` ## Get a list of outages for a site [Section titled “Get a list of outages for a site”](#get-a-list-of-outages-for-a-site) ```bash curl -u AUTH_TOKEN: https://app.honeybadger.io/v2/projects/ID/sites/ID/outages ``` Returns a list of outages with the following format: ```json { "down_at": "2015-02-17T18:20:44.776959Z", "up_at": "2015-02-17T18:22:35.614678Z", "created_at": "2015-02-17T18:20:44.777914Z", "status": 301, "reason": "Expected 2xx status code. Got 301", "headers": { "Date": "Tue, 17 Feb 2015 18:20:44 GMT", "Server": "DNSME HTTP Redirection", "Location": "http://text.vote/polls", "Connection": "close", "Content-Length": "0" } } ``` The outage list can be filtered with these URL parameters: | Parameter | Description | | ---------------- | ---------------------------------------------------- | | `created_after` | A Unix timestamp (number of seconds since the epoch) | | `created_before` | A Unix timestamp (number of seconds since the epoch) | | `limit` | Number of results to return (max and default are 25) | The outage list is always ordered by creation time descending. ## Get a list of uptime checks for a site [Section titled “Get a list of uptime checks for a site”](#get-a-list-of-uptime-checks-for-a-site) ```bash curl -u AUTH_TOKEN: https://app.honeybadger.io/v2/projects/ID/sites/ID/uptime_checks ``` Returns a list of uptime checks with the following format: ```json { "created_at": "2016-06-16T20:19:32.852569Z", "duration": 1201, "location": "Singapore", "up": true } ``` The uptime check list can be filtered with these URL parameters: | Parameter | Description | | ---------------- | ---------------------------------------------------- | | `created_after` | A Unix timestamp (number of seconds since the epoch) | | `created_before` | A Unix timestamp (number of seconds since the epoch) | | `limit` | Number of results to return (max and default are 25) | The uptime check list is always ordered by creation time descending. # Accounts > Manage billing and users. ![Account switcher dropdown](/_astro/account_switcher.BaDg63p7_2e9Yx6.webp) Accounts are the primary billing entities in Honeybadger. An account is created for you when you first sign up, unless you are signing up as a result of being invited to another user’s account. You can create additional accounts and switch between accounts using the dropdown in the navigation bar. ## Account-wide information [Section titled “Account-wide information”](#account-wide-information) Honeybadger can display information from several projects on an account-wide basis, including the following: * Errors * Uptime Checks * Check-Ins Links to these views are available in the left-hand sidebar. [Status Pages](/guides/status-pages) are also managed at the account level, as they can include uptime checks and check-ins from multiple projects. ## Account settings [Section titled “Account settings”](#account-settings) From the account settings page, you can: * See the current billing subscription * Edit account options * Add & remove users * See past invoices * Change authentication settings * Manage the referral program * Park and delete accounts To learn more about adding, removing, and editing users currently registered to an account and changing the authentication settings, please check out the [User Management](/guides/user-management) page. ## Billing [Section titled “Billing”](#billing) Each account is billed separately based on a chosen subscription plan and has its own payment information. The following changes can be made from the Account Settings page for each account regarding billing: * Subscription plan * Payment information * Business details displayed on invoices A list of invoices for the account is also available from the Account Settings page. ### Changing the subscription plan [Section titled “Changing the subscription plan”](#changing-the-subscription-plan) You can change your subscription plan at any time. When you upgrade, downgrade, or change the payment period for your subscription (switch from monthly to yearly, or vice-versa), your account will be prorated for the difference in cost between the old and new plans. The prorated amount will show up as a credit on your next invoice. When you upgrade to a plan that costs more, the next invoice will be larger than normal, as it will have the prorated charge for the newly-selected plan for the remainder of the current billing period in addition to the full charge for the next billing period. On the payment information page we provide a link that can be used to update the account’s payment information without having to be logged in to Honeybadger. This can be useful if you are managing the account but don’t have access to a company credit card. Alternatively, you can invite additional account owners via the Users tab, and those individuals will be able to update the payment information once logged in. Payment via purchase order/invoice is available to subscribers on any of our Business plans when billed annually. Please \[contact support]\(mailto:support\@honeybadger.io?subject=Payment by invoice) to arrange that. Honeybadger is also available through [AWS Marketplace](/guides/aws-marketplace/), which lets you pay for your subscription through your AWS bill. If you already have a Honeybadger account, we can migrate your data to a new Marketplace-billed account for you. ## Account options [Section titled “Account options”](#account-options) From the account options tab, you can change the account name and the billing contact, as well as adjust whether or not overage billing is enabled. The tech contact email, if provided, will receive notifications from Honeybadger for non-billing-related information. ## Referral program [Section titled “Referral program”](#referral-program) Honeybadger offers a referral program that lets you earn up to 20% of referred customers’ payments as account credits. These credits can reduce your monthly bill—even down to $0. To join the program, navigate to the Referrals tab in your account settings, accept the terms, and share your unique referral link. See the [referral program guide](/resources/referral-program) to learn more about the referral program and how to get started. ## Account parking [Section titled “Account parking”](#account-parking) If you’d like to suspend billing for a while, but you’d also like to preserve all the projects, users, etc. associated with your account, then you can choose to park your account. Doing so will stop all error processing, uptime checks, and check-in monitoring for the projects associated with your account. Un-parking your account will cause billing and all processing to be resumed. ## Deleting your account [Section titled “Deleting your account”](#deleting-your-account) When you choose to delete an account, all the data associated with the account (projects, teams, etc.) will be immediately deleted, and billing will be stopped. There is no undo for this action, so be sure you’re ready before pushing the button! # AWS Marketplace > Subscribe to Honeybadger through AWS Marketplace or migrate an existing account to Marketplace billing. Honeybadger is available through [AWS Marketplace](https://aws.amazon.com/marketplace/), which lets you pay for your subscription through your AWS bill and apply your AWS committed spend toward Honeybadger. ## Subscribing through AWS Marketplace [Section titled “Subscribing through AWS Marketplace”](#subscribing-through-aws-marketplace) 1. Visit the [Honeybadger listing on AWS Marketplace](https://aws.amazon.com/marketplace/pp/prodview-yozbmqhcmlrkm) and subscribe to the plan that fits your needs. 2. Complete the AWS Marketplace signup flow. This creates a new Honeybadger account that is billed through AWS. 3. Sign in to your new Honeybadger account to confirm it was provisioned successfully. If you’re new to Honeybadger, you can start adding projects and team members to your new account right away. If you already have a Honeybadger account that you want to switch to Marketplace billing, see the next section. ## Migrating an existing account to AWS Marketplace [Section titled “Migrating an existing account to AWS Marketplace”](#migrating-an-existing-account-to-aws-marketplace) If you already have a Honeybadger account and want to switch to AWS Marketplace billing, we’ll transfer your projects, users, and historical data to the new Marketplace-billed account for you: 1. Subscribe through AWS Marketplace using the steps above. This creates a new, empty Honeybadger account. 2. [Contact support](mailto:support@honeybadger.io?subject=AWS%20Marketplace%20migration) from the email address associated with your existing account and let us know you’d like to migrate. Include the name of your existing account and the name of your new Marketplace account. 3. We’ll transfer your account settings, projects, team members, and historical data from your existing account to your new Marketplace-billed account. Your existing API keys come along with your projects, so your installed libraries and integrations will continue reporting to Honeybadger without any changes on your end. 4. Once the migration is complete and you’ve verified everything looks right in the new account, you can [close your old account](/guides/accounts/#deleting-your-account). ## Managing your subscription [Section titled “Managing your subscription”](#managing-your-subscription) Once your account is billed through AWS Marketplace, plan changes, cancellations, and payment method updates are managed through AWS Marketplace rather than the Honeybadger account settings page. Invoices and payment history are available in your AWS account. # Check-ins > Get notified when cron jobs and scheduled tasks have errors or don't run on time. Your Honeybadger account comes with check-ins, a way for the processes running on your servers to report that they are alive. Once configured, should a check-in go missing, Honeybadger will send you an alert to let you know that your process has stopped reporting. This is especially useful for monitoring cron jobs, so you can avoid having a cron job silently fail and go unnoticed. ![Check-Ins overview](/_astro/check_ins.-E2J2HRn_Z1FEJto.webp) ## Setup [Section titled “Setup”](#setup) When you create a check-in, you’ll configure the following options: ![Check-in creation form](/_astro/check_in_form.5H-aO53g_1iDIty.webp) ### Name [Section titled “Name”](#name) A label for your check-in. If not provided, a token identifier will be used. ### Slug [Section titled “Slug”](#slug) An optional human-readable identifier that can be used as an alternate check-in URL. See [Slugs](#slugs) below. ### Schedule type [Section titled “Schedule type”](#schedule-type) Choose **Simple** to check in at a regular interval, or **Cron** to use a cron expression for advanced scheduling. #### Simple [Section titled “Simple”](#simple) Honeybadger will watch the process at an interval you define. ##### Report period [Section titled “Report period”](#report-period) How often you expect the check-in to report (e.g., “1 hour”). #### Cron [Section titled “Cron”](#cron) Cron scheduling allows you to use a cron expression to create an advanced check-in schedule or mirror the cron schedule on your server. ##### Schedule [Section titled “Schedule”](#schedule) The cron expression (e.g., `*/5 * * * *`). ##### Time zone [Section titled “Time zone”](#time-zone) The time zone of the server where cron is running. ### Grace period [Section titled “Grace period”](#grace-period) An optional grace period allows some time for long-running tasks to be completed before Honeybadger sends a notification due to a lack of reporting. For example, if you have a job that reports every hour but can take up to twenty minutes to run, you can specify a grace period of twenty minutes, and Honeybadger will allow up to one hour and twenty minutes to elapse before a notification is sent. ## Reporting [Section titled “Reporting”](#reporting) When you create a new check-in, you’ll get a URL that you can use to report that your process is alive. The easiest way to report a check-in is with [the Honeybadger CLI’s `hb check-in` command](/resources/cli/#check-in): ```sh @hourly /usr/bin/do_something && hb check-in --id XyZZy ``` Or use `curl` to fetch the check-in URL directly: ```sh @hourly /usr/bin/do_something && curl https://api.honeybadger.io/v1/check_in/XyZZy &> /dev/null ``` See the [API docs](/api/reporting-check-ins/) for more information about the data you can send when reporting a check-in. You will also get an email address you can use for reporting the status of your process. No subject or body text is required, but the email address *is* case-sensitive: ```sh @hourly /usr/bin/do_something && echo | mail XyZZy@report.hbchk.in ``` Please note that while these examples use cron, you can trigger check-in reporting from the shell, a scheduled background job, or any other process that can request a URL or send an email. ## Slugs [Section titled “Slugs”](#slugs) A slug is an optional, human-readable identifier for a check-in. When you add a slug, you get an alternate check-in URL that uses the slug and a [project API key](/guides/projects/#api-keys) instead of the check-in ID. This is useful if you don’t want to embed check-in IDs in your code or automated systems. For example, if you specify a slug of `hourly-check`, your alternate check-in URL will look like: ```sh https://api.honeybadger.io/v1/check_in/hbp_ABC/hourly-check ``` You can add a slug when creating a check-in in the UI, via the [REST API](/api/check-ins/#create-a-check-in), or in a config file using our [PHP/Laravel](/lib/php/guides/configuring-checkins/) and [JavaScript](/lib/javascript/guides/check-ins/) client libraries. ## Payloads [Section titled “Payloads”](#payloads) You can POST a small payload to the UI that includes the results of the command you ran, including the command’s output, exit code, and duration. Please see our [API documentation](/api/reporting-check-ins/#check-in-payloads) for the format of that payload. ![Check-in payloads](/_astro/checkin-payloads.PhMr8LYv_Z22oS8s.webp)![Check-in payloads](/_astro/checkin-payloads-dark.C_0-ypPR_s56xH.webp) The easiest way to send check-in payloads is to use [the Honeybadger CLI’s `hb run` command](/resources/cli/#run) to wrap your scheduled command: ```shell hb run --id XyZZy -- /usr/local/bin/backup.sh ``` Or [POST directly to the check-in API](/api/reporting-check-ins/#check-in-payloads) with a JSON payload: ```bash curl -X POST https://api.honeybadger.io/v1/check_in/XyZZy \ -H "Content-Type: application/json" \ -d '{"check_in": {"status": "success", "duration": 1234, "stdout": "backup completed"}}' ``` You can view the payload data in your check-in history or query it in [Insights](/guides/insights/). ## Notifications [Section titled “Notifications”](#notifications) ![Check-in alerts configuration](/_astro/check_in_alerts.CfIwcD8D_1yKAqe.webp) When your check-in goes missing, we’ll notify you with information about which job failed to report on time. You can enable or disable these notifications along with the rest of the notification events in your Personal Alerts or Project Integrations settings. ## Status page integration [Section titled “Status page integration”](#status-page-integration) Check out our [Status Pages](/guides/status-pages/#uptime-checks) feature for information on how to present the status your check-ins to your users. # Dashboards & APM > Learn how to use dashboards to display widgets created from Insights queries and visualizations. Dashboards let you collect your most important [Honeybadger Insights](/guides/insights/) charts and data in one place so you can see what’s happening with your app at a glance. Instead of running queries repeatedly or jumping between pages, dashboards give you a single view of your application’s health and performance, helping you spot trends and fix issues. ## Getting started [Section titled “Getting started”](#getting-started) To create a dashboard, navigate to the *Dashboards* section in your Honeybadger project, click the dashboard selector in the top left, then click the **+** button next to the dashboard you want to add. ![Honeybadger dashboards overview showing the main dashboard interface](/_astro/insights-dashboards-overview.BTBQBdr2_Z2rEEY.webp)![Honeybadger dashboards overview showing the main dashboard interface](/_astro/insights-dashboards-overview-dark.DIG5G_k2_1jAkc1.webp) ## Project Overview dashboard [Section titled “Project Overview dashboard”](#project-overview-dashboard) The [Project Overview dashboard](/guides/dashboards/project-overview/) provides a comprehensive view of your application’s health and performance. It’s automatically added to every new Honeybadger project, giving you immediate visibility into alarms, deployments, errors, uptime checks, and check-ins. ## Automatic dashboards [Section titled “Automatic dashboards”](#automatic-dashboards) To help you get started quickly, Honeybadger provides pre-configured automatic dashboards with relevant widgets for common frameworks and platforms. These dashboards are automatically populated when you enable instrumentation for supported platforms. ### Getting started with automatic dashboards [Section titled “Getting started with automatic dashboards”](#getting-started-with-automatic-dashboards) To enable automatic dashboards for your applications, follow these steps: 1. Enable Honeybadger Insights instrumentation in your client library (e.g., [Ruby](/lib/ruby/insights/automatic-instrumentation/), [Elixir](/lib/elixir/insights/automatic-instrumentation/), [PHP](/lib/php/insights/automatic-instrumentation/), etc.) 2. Deploy your application with the updated configuration 3. Navigate to the *Dashboards* section in your Honeybadger project, click *Create dashboard*, select the dashboard you want, then click *Add dashboard*. Your dashboard will begin to populate with data as soon as your application starts sending events to Honeybadger. ## Customizing dashboards [Section titled “Customizing dashboards”](#customizing-dashboards) You can customize any dashboard by clicking the **…** menu in the top right corner of the dashboard. From there, you can: * **Edit** - Modify the dashboard layout and widgets * **Clone** - Create a copy of the dashboard * **Set as default dashboard** - Make this dashboard your default view * **Set default time range** - Configure the default time period * **Edit source** - View and edit the dashboard’s YAML configuration * **Delete dashboard** - Remove the dashboard ![Dashboard dropdown menu showing customization options including Edit, Clone, Set as default dashboard, Set default time range, Edit source, and Delete dashboard.](/_astro/insights-dashboard-edit.DSx7NB03_1kB8vO.webp)![Dashboard dropdown menu showing customization options including Edit, Clone, Set as default dashboard, Set default time range, Edit source, and Delete dashboard.](/_astro/insights-dashboard-edit-dark.DbO_dFHT_Z4xzBK.webp) ### Widget library [Section titled “Widget library”](#widget-library) When adding new widgets to a dashboard, you can choose from a library of pre-configured widget templates. The widget library includes templates for common data sources such as: * Error rates and deployments * Database performance metrics * Background job processing times * Request counts and response distributions * Cache hit rates To add a widget from the library, click the **+** *Add widget* menu in the top right corner of the dashboard and select a template. You can customize any widget after adding it to your dashboard. ![Widget library interface showing pre-built dashboard widget templates that can be added to customize dashboards.](/_astro/insights-dashboard-widget-library.DPmtz0pn_1tJIDj.webp)![Widget library interface showing pre-built dashboard widget templates that can be added to customize dashboards.](/_astro/insights-dashboard-widget-library-dark.DDrYI8EV_Zzs2PC.webp) ### Editing widgets [Section titled “Editing widgets”](#editing-widgets) In edit mode, you can configure any widget by clicking the **…** menu on the widget and selecting **Edit widget**. This opens the widget editor where you can modify the query, change the visualization type, and preview results before saving. ![Configure Widget panel with query editor showing filter and stats syntax, visualization type dropdown set to Histogram, and a live preview of the chart with Cancel and Update buttons.](/_astro/insights-dashboard-edit-widget.qZh1ObJZ_ZdKMbS.webp)![Configure Widget panel with query editor showing filter and stats syntax, visualization type dropdown set to Histogram, and a live preview of the chart with Cancel and Update buttons.](/_astro/insights-dashboard-edit-widget-dark.B8OpeGtq_Z1e9WXJ.webp) ### Parameterized queries [Section titled “Parameterized queries”](#parameterized-queries) You can make dashboard widgets dynamic by using parameters in your queries. Parameters let you create reusable dashboards where values can be changed via the URL or the **Parameters** button in the dashboard toolbar, without editing the widget configuration. For example, a single dashboard can be filtered to one host, environment, or customer at a time — and shared as a prefilled link. #### Adding a parameter to a widget [Section titled “Adding a parameter to a widget”](#adding-a-parameter-to-a-widget) To add a parameter to a dashboard widget: 1. Open the dashboard and click **Edit**. 2. Click the **…** menu on the widget and choose **Edit widget**. 3. Add a reference like `${hostname}` anywhere in the widget’s query — for example, `filter hostname::str == "${hostname}"`. 4. When the editor prompts you, provide a value for the new parameter so the preview can render. Click **Update** to save the widget. ![Configure Widget panel showing a BadgerQL query that filters by hostname using a parameter reference.](/_astro/insights-widget-edit-parameters.DhLRxEoZ_203DjI.webp)![Configure Widget panel showing a BadgerQL query that filters by hostname using a parameter reference.](/_astro/insights-widget-edit-parameters-dark.O_jFcEp-_1yTkOJ.webp) Once a parameter is defined, any widget on the dashboard that uses the same name will share the same value. To apply one parameter across several widgets, reference it from each widget’s query — either through the widget editor or by [editing the dashboard source](#editing-dashboard-source). #### Setting parameter values [Section titled “Setting parameter values”](#setting-parameter-values) There are three ways to set parameter values on a dashboard: 1. **URL parameters** — Add parameters directly to the URL (e.g., `?hostname=web-01`). Because parameters are URL-based, you can bookmark or share a link that already has the values filled in. 2. **Parameters popover** — Click the **Parameters** button (the slider icon in the dashboard toolbar, next to the date picker) to open a popover with a field for each parameter used on the dashboard. Enter values and click **Apply**, or click **Reset to defaults** to restore default values. ![Parameters popover open in a dashboard toolbar, showing a text field for the hostname parameter with Reset to defaults and Apply controls.](/_astro/insights-dashboard-edit-parameters.BAd3FTGm_XMSl9.webp)![Parameters popover open in a dashboard toolbar, showing a text field for the hostname parameter with Reset to defaults and Apply controls.](/_astro/insights-dashboard-edit-parameters-dark.EbYbzmGo_ZITVUx.webp) 3. **From widget results** — Click a field value in a widget’s results. If the field name matches a parameter used on the dashboard, you’ll see a “set parameter” option that updates every widget using that parameter. #### Default values [Section titled “Default values”](#default-values) Giving a parameter a default with `${name:-default}` means the widget can render even when no value has been supplied. Defaults are useful for: * Setting a sensible baseline (e.g., `${env:-production}`) that viewers can override. * Ensuring a dashboard renders on first load before anyone has edited parameters. #### Parameters required state [Section titled “Parameters required state”](#parameters-required-state) When a widget references a parameter that has no default and no value has been supplied via the URL or the parameters popover, the widget displays a **Parameters required** message with an **Edit parameters** button. The **Parameters** button in the dashboard toolbar also shows an indicator dot, signaling that one or more values need to be set. Click either to open the parameters popover and supply the missing values. ![Dashboard widgets showing the Parameters required empty state with an Edit parameters button, and a Parameters button in the toolbar with an indicator dot.](/_astro/insights-dashboard-parameters.DA6jsX9Q_6Hpa8.webp)![Dashboard widgets showing the Parameters required empty state with an Edit parameters button, and a Parameters button in the toolbar with an indicator dot.](/_astro/insights-dashboard-parameters-dark.BPri_FAi_26na1x.webp) ### Editing dashboard source [Section titled “Editing dashboard source”](#editing-dashboard-source) For advanced customization, select **Edit source** to view and modify the entire dashboard configuration as YAML. This is useful for: * Making bulk changes without navigating the UI * Copying dashboards between projects * Sharing configurations with team members The editor validates your configuration against a predefined schema and displays helpful error messages if something’s wrong. Stream IDs are automatically converted to human-readable names, so you don’t need to manually update identifiers when moving configurations between projects. ![Edit Source modal showing YAML configuration for dashboard widget settings.](/_astro/insights-dashboard-edit-source.Bq8NhHqI_Eseep.webp)![Edit Source modal showing YAML configuration for dashboard widget settings.](/_astro/insights-dashboard-edit-source-dark.CZwJ8Jr3_Z1Vz98E.webp) ## Available dashboards [Section titled “Available dashboards”](#available-dashboards) [Project Overview](/guides/dashboards/project-overview/)Deployments, errors, uptime, check-ins, and performance at a glance [Active Job](/guides/dashboards/active-job/)Job counts, durations, and failure rates by job class [Active Job Metrics](/guides/dashboards/active-job-metrics/)Pre-aggregated job throughput, durations, and stats by job class [Autotuner](/guides/dashboards/autotuner/)Heap growth, GC counts, and memory tuning suggestions [Celery](/guides/dashboards/celery/)Task counts by status, average durations, failures and retries [Django](/guides/dashboards/django/)Request durations, response status counts, slowest views and queries [Flask](/guides/dashboards/flask/)Request durations, response codes, and slowest views and queries by blueprint [Heroku](/guides/dashboards/heroku/)Router status codes, Postgres load averages, and slowest paths [Karafka](/guides/dashboards/karafka/)Consumer lag, processing durations, and broker errors by topic [Laravel](/guides/dashboards/laravel/)Request and job durations, response distributions, slowest controllers and queries [Net::HTTP Metrics](/guides/dashboards/net-http-metrics/)Outbound HTTP throughput, durations, and status codes by host [Oban](/guides/dashboards/oban/)Job counts by status, durations by worker, and slowest job runs [Phoenix](/guides/dashboards/phoenix/)Request stats, slowest controllers and Ecto queries, LiveView event performance [Puma](/guides/dashboards/puma/)Request backlog, running threads, and pool capacity over time [Rails](/guides/dashboards/rails/)Slow requests, queries, and partials; cache hit rates by controller [Rails Metrics](/guides/dashboards/rails-metrics/)Pre-aggregated throughput, controller durations, and DB/view timings [Sidekiq](/guides/dashboards/sidekiq/)Job counts, durations, and failure rates by worker [Sidekiq Metrics](/guides/dashboards/sidekiq-metrics/)Pre-aggregated job durations, queue depth, latency, and capacity [Solid Queue Metrics](/guides/dashboards/solid-queue-metrics/)Job statuses, active workers and dispatchers, and queue depths [System](/guides/dashboards/system/)CPU load averages, memory usage, and disk usage by device ## Next steps [Section titled “Next steps”](#next-steps) * Learn more about [Honeybadger Insights](/guides/insights/) * Try [BadgerQL](/guides/insights/badgerql/) to explore your data and create custom dashboard widgets * Set up [Insights Alarms](/guides/insights/alarms/) to turn your queries into actionable alerts * Send additional data from your [infrastructure](/guides/insights/#adding-data-from-other-sources) to Honeybadger # Active Job dashboard > Job counts, durations, and failure rates by job class Note Requires the `honeybadger` gem `>= 6.3`. Drop in Dashboard for your ActiveJob instrumentation data Works with Solid Queue, GoodJob, and other ActiveJob backends. **This dashboard includes:** * Job counts over time by job class * Average job duration by job class over time * Job duration distribution (binned by 100ms, by job class) * Job status counts (success/failure) by job class * Aggregate job stats: successes, failures, total and average execution time * 10 slowest job runs (with details) To get started, make sure you have updated your Honeybadger gem to `>= 6.3`, then enable Insights instrumentation by including this in your `config/honeybadger.yml`: ```yaml insights: enabled: true ``` Check out the [Honeybadger client documentation](https://docs.honeybadger.io/lib/ruby/getting-started/sending-events-to-insights/) for more information. ![Active Job dashboard](/_astro/active_job.DxGeJCVi_Z1lm3T3.webp)![Active Job dashboard](/_astro/active_job-dark.B-2ris-q_1wyvkB.webp) # Active Job Metrics dashboard > Pre-aggregated job throughput, durations, and stats by job class Note Requires the `honeybadger` gem `>= 6.3`. Drop in Dashboard for your ActiveJob metrics data This is the metrics-based counterpart to the ActiveJob (events) dashboard. Works with Solid Queue, GoodJob, and other ActiveJob backends. **This dashboard includes:** * Job throughput over time by job class * Job durations over time by job class * Job stats with min, max, avg durations To get started, make sure you have updated your Honeybadger gem to `>= 6.3`, then enable Insights metrics by including this in your `config/honeybadger.yml`: ```yaml insights: enabled: true rails: insights: metrics: true ``` Check out the [Honeybadger client documentation](https://docs.honeybadger.io/lib/ruby/getting-started/sending-events-to-insights/) for more information. ![Active Job Metrics dashboard](/_astro/active_job_metrics.BrCoMJ65_Z2iPK79.webp)![Active Job Metrics dashboard](/_astro/active_job_metrics-dark.CeUj6LzH_Dyxof.webp) # Autotuner dashboard > Heap growth, GC counts, and memory tuning suggestions Note Requires the `honeybadger` gem `>= 5.26`. Drop in Dashboard for your Autotuner stats and reports **This dashboard includes:** * Heap Pages over time * Request Time over time * Garbage Collection Count over time * Autotuner Report suggestions To get started, make sure you have updated your Honeybadger gem to `>= 5.26`, then enable Insights instrumentation by including this in your `config/honeybadger.yml`: ```yaml insights: enabled: true ``` Check out the [Honeybadger client documentation](https://docs.honeybadger.io/lib/ruby/getting-started/sending-events-to-insights/) for more information. ![Autotuner dashboard](/_astro/autotuner.DAqKk1cR_1euNbT.webp)![Autotuner dashboard](/_astro/autotuner-dark.Cio91bjZ_1gXYB7.webp) # Celery dashboard > Task counts by status, average durations, failures and retries Note Requires the `honeybadger` package `>= 1.1.0`. Drop in Dashboard for your Celery instrumentation data **This dashboard includes:** * Task counts over time by status (SUCCESS, FAILURE, etc.) * Average task durations across all tasks * Overall task counts & average durations per task * Top 10 slowest task runs * Breakdown of failures, retries & other statuses * Total successful job count To get started, make sure you have updated Honeybadger to version 1.1.0 or later. ```yaml pip install --upgrade honeybadger ``` And enable Insights instrumentation by including this in your config: ```py celery.conf.update( HONEYBADGER_INSIGHTS_ENABLED = True, ) ``` ![Celery dashboard](/_astro/celery.CWCrftSP_1kdleW.webp)![Celery dashboard](/_astro/celery-dark.CsJcuV-0_Z2mCUon.webp) # Django dashboard > Request durations, response status counts, slowest views and queries Note Requires the `honeybadger` package `>= 1.1.0`. Drop in Dashboard for your Django instrumentation data **This dashboard includes:** * Request duration distributions (binned by 100 ms) * Response counts over time, grouped by status codes (2XX, 3XX, 4XX, 5XX) * Average response durations by view * Average response durations by app * Total request counts over time * Slowest views (avg/max durations and Apdex) * Top 10 slowest database queries To get started, make sure you have updated Honeybadger to version 1.1.0 or later. ```yaml pip install --upgrade honeybadger ``` And enable Insights instrumentation by including this in your config: ```py HONEYBADGER = { 'INSIGHTS_ENABLED': True, } ``` ![Django dashboard](/_astro/django.41aLzvJe_pQG4s.webp)![Django dashboard](/_astro/django-dark.BVxHa12c_24wHXa.webp) # Flask dashboard > Request durations, response codes, and slowest views and queries by blueprint Note Requires the `honeybadger` package `>= 1.1.0`. Ready-made dashboard for monitoring Flask applications **This dashboard includes:** * Average response durations by view * Average response durations by blueprint * Response counts over time, grouped by status codes (2XX, 3XX, 4XX, 5XX) * Total request count over time * Top 10 slowest views (avg/max durations and Apdex) * Request duration distribution histogram (binned by 100 ms) * Top 10 slowest database queries To get started, make sure you have updated Honeybadger to version 1.1.0 or later. ```yaml pip install --upgrade honeybadger ``` And enable Insights instrumentation by including this in your config: ```py class Config: HONEYBADGER_INSIGHTS_ENABLED = True ``` ![Flask dashboard](/_astro/flask.ZblVZlYb_ZxkWPR.webp)![Flask dashboard](/_astro/flask-dark.BQHV8yUU_2eJmtR.webp) # Heroku dashboard > Router status codes, Postgres load averages, and slowest paths Ready made dashboard for monitoring Heroku apps. All that is required is to set up your [Heroku log drain](https://docs.honeybadger.io/guides/insights/integrations/heroku/). **This dashboard includes:** * Router response status code groupings * Postgres load averages (1m, 5m, 15m interval samples) * Query response time percentiles (50, 90, 99 percentiles) * Top 10 avg slowest response times by path ![Heroku dashboard](/_astro/heroku.DyuBSuwe_Z1ffPPm.webp)![Heroku dashboard](/_astro/heroku-dark.C7gEVaL8_1rpFor.webp) # Karafka dashboard > Consumer lag, processing durations, and broker errors by topic Note Requires the `honeybadger` gem `>= 5.26`. Drop in Dashboard for your Karafka instrumentation data **This dashboard includes:** * Average Consumer Duration * Average Consumer Lag * Number of Messages Processed by Topic * Average Consumer Consumption and Processing Duration * Broker Latency * Broker Errors To get started, make sure you have updated your Honeybadger gem to `>= 5.26`, then enable Insights instrumentation and Karafka metrics by including this in your `config/honeybadger.yml`: ```yaml insights: enabled: true karafka: insights: metrics: true ``` Check out the [Honeybadger client documentation](https://docs.honeybadger.io/lib/ruby/getting-started/sending-events-to-insights/) for more information. ![Karafka dashboard](/_astro/karafka.BTLiaL7m_Z2k2jIV.webp)![Karafka dashboard](/_astro/karafka-dark.AwOKtjvU_24HCO1.webp) # Laravel dashboard > Request and job durations, response distributions, slowest controllers and queries Note Requires the `honeybadger-laravel` package `>= 4.2.0`. Drop in Dashboard for your Laravel instrumentation data **This dashboard includes:** * Total requests over time * Response distributions binned by 100ms * Job durations over time * Slowest controllers w/ Apdex score * Overall slowest requests * Slowest overall queries & slowest queries per request * Slowest external requests To get started, make sure you have updated your honeybadger-laravel package to `>= 4.2.0 `, then enable Insights instrumentation by including this in your `config/honeybadger.php`: ```php 'events' => [ 'enabled' => true ] ``` ![Laravel dashboard](/_astro/laravel.Bf6GXJdr_1cUfid.webp)![Laravel dashboard](/_astro/laravel-dark.BAk4C0UY_23QBcu.webp) # Net::HTTP Metrics dashboard > Outbound HTTP throughput, durations, and status codes by host Note Requires the `honeybadger` gem `>= 5.11`. Drop in Dashboard for your Net::HTTP metrics data Monitor outbound HTTP requests made via Ruby’s Net::HTTP library, including request durations, throughput, and response status breakdowns by host. **This dashboard includes:** * Request throughput by host * Avg request duration by host * Responses grouped by status code * Request duration by HTTP method * Slowest hosts To get started, make sure you have updated your Honeybadger gem to `>= 5.11`, then enable Insights metrics by including this in your `config/honeybadger.yml`: ```yaml insights: enabled: true net_http: insights: metrics: true ``` Check out the [Honeybadger client documentation](https://docs.honeybadger.io/lib/ruby/getting-started/sending-events-to-insights/) for more information. ![Net::HTTP Metrics dashboard](/_astro/net_http_metrics.CugraTYv_1wbHih.webp)![Net::HTTP Metrics dashboard](/_astro/net_http_metrics-dark.BZ-MLBLL_Z19frSC.webp) # Oban dashboard > Job counts by status, durations by worker, and slowest job runs Note Requires the `honeybadger` package `>= 0.24`. Ready made dashboard for your Oban data. This dashboard includes: * Overall Job counts by status * Histogram of job counts by status * Job durations by Worker module * Overall Worker stats * Slowest 10 job runs To get started, make sure you have updated Honeybadger Elixir Client to `>= 0.24`, then enable Insights instrumentation by including this in your config: ```elixir config :honeybadger, insights_enabled: true ``` Check out the Honeybadger client documentation for more information. ![Oban dashboard](/_astro/oban.UazNXxU__1rkDxb.webp)![Oban dashboard](/_astro/oban-dark.BYRauAzK_Z2qJm4.webp) # Phoenix dashboard > Request stats, slowest controllers and Ecto queries, LiveView event performance Note Requires the `honeybadger` package `>= 0.24`. Ready made dashboard for your Phoenix data. This dashboard includes: * Request Stats * Response Counts by status code * 10 Slowest Controller Actions * 10 Slowest Ecto Queries * LiveView Event Performance * LiveView Mount Performance * LiveView Event Counts To get started, make sure you have updated Honeybadger Elixir Client to `>= 0.24`, then enable Insights instrumentation by including this in your config: ```elixir config :honeybadger, insights_enabled: true ``` Check out the Honeybadger client documentation for more information. ![Phoenix dashboard](/_astro/phoenix.DRqTCMKY_c1UL7.webp)![Phoenix dashboard](/_astro/phoenix-dark.CjQ-J7um_Z1OaIIC.webp) # Project Overview dashboard > Monitor application health with the Project Overview dashboard, featuring alarms, deployments, errors, uptime checks, check-ins, and performance metrics. The Project Overview dashboard provides a comprehensive view of your application’s health and is automatically added to every new Honeybadger project. **This dashboard includes:** * Alarms: Triggered and active alarms with recent check status * Deployments: Recent deployment activity * Errors: Top errors affecting your application * Uptime: Monitor status and response times * Check-ins: Health check status for critical services * Dynamic widgets (these may vary for your application): * Slowest Controller Actions: Performance bottlenecks * Response Status Codes: HTTP response trends * Database Query Performance: Query execution metrics ![Project Overview Dashboard](/_astro/project-overview.DuA7QeMH_ZzArTP.webp)![Project Overview Dashboard](/_astro/project-overview-dark._-a6RKEj_Z9o1H1.webp) # Puma dashboard > Request backlog, running threads, and pool capacity over time Note Requires the `honeybadger` gem `>= 5.26`. Drop in Dashboard for your Puma instrumentation data **This dashboard includes:** * Total requests over time * Backlog over time * Running threads over time * Pool capacity over time To get started, make sure you have updated your Honeybadger gem to `>= 5.26`, then enable Insights instrumentation by including this in your `config/honeybadger.yml`: ```yaml insights: enabled: true ``` Check out the [Honeybadger client documentation](https://docs.honeybadger.io/lib/ruby/getting-started/sending-events-to-insights/) for more information. ![Puma dashboard](/_astro/puma.BX5YYQIc_2mlVpR.webp)![Puma dashboard](/_astro/puma-dark.CgIr4TcE_Z2kafnE.webp) # Rails dashboard > Slow requests, queries, and partials; cache hit rates by controller Note Requires the `honeybadger` gem `>= 5.11`. Drop in Dashboard for your Rails instrumentation data **This dashboard includes:** * Total requests over time * Response distributions binned by 100ms * Controller durations & slowest controller actions * Slowest queries & slowest queries per request * Slowest partials * Cache hit rates To get started, make sure you have updated your Honeybadger gem to `>= 5.11`, then enable Insights instrumentation by including this in your `config/honeybadger.yml`: ```yaml insights: enabled: true ``` Check out the [Honeybadger client documentation](https://docs.honeybadger.io/lib/ruby/getting-started/sending-events-to-insights/) for more information. ![Rails dashboard](/_astro/rails.DXCbKE5S_1fV7s5.webp)![Rails dashboard](/_astro/rails-dark.D8pzyjol_1ihTc6.webp) # Rails Metrics dashboard > Pre-aggregated throughput, controller durations, and DB/view timings Note Requires the `honeybadger` gem `>= 5.11`. Drop in Dashboard for your Rails metrics data This is the metrics-based counterpart to the Rails (events) dashboard. Use this if you’ve enabled metrics without events, or if you prefer pre-aggregated metric data. **This dashboard includes:** * Request throughput over time * Controller durations (weighted average) * Responses grouped by status code * Slowest controller actions * DB & View runtime breakdown * SQL query durations * Cache operation durations To get started, make sure you have updated your Honeybadger gem to `>= 5.11`, then enable Insights metrics by including this in your `config/honeybadger.yml`: ```yaml insights: enabled: true rails: insights: metrics: true ``` Check out the [Honeybadger client documentation](https://docs.honeybadger.io/lib/ruby/getting-started/sending-events-to-insights/) for more information. ![Rails Metrics dashboard](/_astro/rails_metrics.CIOaHFip_Z22Fhju.webp)![Rails Metrics dashboard](/_astro/rails_metrics-dark.DZoO6fbH_9o21P.webp) # Sidekiq dashboard > Job counts, durations, and failure rates by worker Note Requires the `honeybadger` gem `>= 5.11`. Drop in Dashboard for your Sidekiq instrumentation data **This dashboard includes:** * Job counts over time by worker * Average job duration by worker over time * Job duration distribution (binned by 100ms, by worker) * Job status counts (success/failure) by worker * Aggregate worker stats: successes, failures, total and average execution time * 10 slowest job runs (with details) To get started, make sure you have updated your Honeybadger gem to `>= 5.11`, then enable Insights instrumentation by including this in your `config/honeybadger.yml`: ```yaml insights: enabled: true ``` Check out the [Honeybadger client documentation](https://docs.honeybadger.io/lib/ruby/getting-started/sending-events-to-insights/) for more information. ![Sidekiq dashboard](/_astro/sidekiq.Co3LCyLd_1dPGPW.webp)![Sidekiq dashboard](/_astro/sidekiq-dark.BG-6HU_b_ZeqMHx.webp) # Sidekiq Metrics dashboard > Pre-aggregated job durations, queue depth, latency, and capacity Note Requires the `honeybadger` gem `>= 5.11`. Drop in Dashboard for your Sidekiq metrics data This is the metrics-based counterpart to the Sidekiq (events) dashboard. In addition to job performance data, this dashboard includes infrastructure metrics like queue depth, latency, capacity, and utilization that are unique to the metrics pipeline. **This dashboard includes:** * Job durations by worker over time * Queue latency and depth per queue * Capacity and utilization * Infrastructure stats (processed, failed, scheduled, retry, dead) To get started, make sure you have updated your Honeybadger gem to `>= 5.11`, then enable Insights metrics by including this in your `config/honeybadger.yml`: ```yaml insights: enabled: true sidekiq: insights: metrics: true ``` Check out the [Honeybadger client documentation](https://docs.honeybadger.io/lib/ruby/getting-started/sending-events-to-insights/) for more information. ![Sidekiq Metrics dashboard](/_astro/sidekiq_metrics.ao6TYJgZ_Z1tWicB.webp)![Sidekiq Metrics dashboard](/_astro/sidekiq_metrics-dark.C8Q5560a_ZYEhrr.webp) # Solid Queue Metrics dashboard > Job statuses, active workers and dispatchers, and queue depths Note Requires the `honeybadger` gem `>= 6.3`. Drop in Dashboard for your Solid Queue metrics data Monitor your Solid Queue infrastructure including job counts, worker/dispatcher status, and queue depths. **This dashboard includes:** * Job status overview (in progress, blocked, failed, scheduled, processed) * Active workers and dispatchers * Job trends over time * Queue depths by queue To get started, make sure you have updated your Honeybadger gem to `>= 6.3`, then enable Insights metrics by including this in your `config/honeybadger.yml`: ```yaml insights: enabled: true solid_queue: insights: metrics: true ``` Check out the [Honeybadger client documentation](https://docs.honeybadger.io/lib/ruby/getting-started/sending-events-to-insights/) for more information. ![Solid Queue Metrics dashboard](/_astro/solid_queue_metrics.lsWvrgjy_6bzE8.webp)![Solid Queue Metrics dashboard](/_astro/solid_queue_metrics-dark.Cb2RMf7F_Z6rYEj.webp) # System dashboard > CPU load averages, memory usage, and disk usage by device Ready made dashboard for monitoring system resources reported by the [Honeybadger CLI agent](https://docs.honeybadger.io/resources/cli/#agent). **This dashboard includes:** * CPU load averages (1, 5, and 15 minute intervals) * Memory usage percentage * Disk usage percentage by device ![System dashboard](/_astro/system.kJPjDiov_7Ap4l.webp)![System dashboard](/_astro/system-dark.Dhm2U8ED_WaLrK.webp) # Deployments > Viewing and tracking deployments. Deployment tracking lets you record when your app is deployed, see a history of deployments, and correlate code changes with errors. When you deploy, Honeybadger can automatically resolve open errors and notify your team. ## The Deployments page [Section titled “The Deployments page”](#the-deployments-page) Your most recent deployments are listed on your project’s Deployments page, sorted by timestamp with the newest first. You can also filter by environment and adjust the time range, with presets for month to date, the last seven days, and yesterday. For each deployment, Honeybadger displays the timestamp, environment, deploying user, and revision. When GitHub or GitLab is connected, Honeybadger links the revision to a comparison page that shows a diff of what changed since the last deploy. ![Deployment screen showing recent deployments](/_astro/deployments.dFc7SaWN_Z25hpEV.webp)![Deployment screen showing recent deployments](/_astro/deployments-dark.B-68x4a__jgpSD.webp) If your app is on Heroku, the user field shows which Heroku component triggered the deployment. ## Auto-resolving errors on deploy [Section titled “Auto-resolving errors on deploy”](#auto-resolving-errors-on-deploy) By default, all [unresolved errors](/guides/errors/#resolve--unresolve) are automatically marked as resolved when a deployment is recorded, which helps keep your [error list](/guides/errors/#browsing-errors) clean. If a resolved error re-occurs after a deploy, you will receive a new notification to let you know the error is still happening. Auto-resolving assumes you fix errors between deploys (or at least want to be reminded about errors frequently). To disable auto-resolve, uncheck *Resolve errors on deploy* in your [project’s settings](/guides/projects/#resolve-errors-on-deploy). When disabled, you can still [mark individual errors to resolve on the next deploy](/guides/errors/#resolve-on-deploy) on the error page. ## Searching with deployments [Section titled “Searching with deployments”](#searching-with-deployments) Honeybadger’s [error search](/guides/errors/search/) supports several deployment-related tokens: | Token | Description | | ------------------------------ | ------------------------------------------------------------------------------------------------------------ | | `occurred.after:'last deploy'` | Errors that occurred since the most recent deployment | | `revision:"v1.0"` | Errors that occurred from a deployment with this revision | | `is:pending_resolution` | Errors set to resolve on the next deploy (when [auto-resolve](#auto-resolving-errors-on-deploy) is disabled) | The `occurred.after:'last deploy'` token is useful for spotting errors in new code, especially when combined with [environment or assignee filters](/guides/errors/search/#examples). ## Reporting deployments [Section titled “Reporting deployments”](#reporting-deployments) To track your deployments, you’ll need to notify Honeybadger each time you deploy. There are several ways to do this depending on your stack: ### Client libraries [Section titled “Client libraries”](#client-libraries) We have language-specific deployment tracking guides for [Ruby](/lib/ruby/errors/tracking-deployments/), [JavaScript](/lib/javascript/errors/tracking-deploys/), [PHP](/lib/php/errors/tracking-deploys/), [Python](/lib/python/errors/tracking-deployments/), and [Elixir](/lib/elixir/errors/tracking-deployments/). ### CI/CD and platform integrations [Section titled “CI/CD and platform integrations”](#cicd-and-platform-integrations) * **GitHub Actions**: Use the [Honeybadger Deploy Action](https://github.com/marketplace/actions/honeybadger-deploy-action) * **Heroku**: See the [Heroku guide](/guides/heroku/#heroku-deployment-tracking) * **Netlify**: See the [JavaScript guide](/lib/javascript/errors/tracking-deploys/#from-netlify) * **Laravel Forge**: See the [PHP guide](/lib/php/errors/tracking-deploys/#tracking-deploys-from-laravel-forge) * **DeployHQ**: [Native Honeybadger integration](https://www.deployhq.com/support/integrations/honeybadger) ### Direct API [Section titled “Direct API”](#direct-api) For any other tool or pipeline, make a request directly to the Honeybadger API. See the [API reference](/api/reporting-deployments/) for a full list of parameters. ```sh HONEYBADGER_ENV="production" \ HONEYBADGER_REVISION="$(git rev-parse HEAD)" \ HONEYBADGER_REPOSITORY="$(git config --get remote.origin.url)" \ HONEYBADGER_API_KEY="Your project API key" \ && curl -g "https://api.honeybadger.io/v1/deploys?deploy[environment]=$HONEYBADGER_ENV&deploy[local_username]=$USER&deploy[revision]=$HONEYBADGER_REVISION&deploy[repository]=$HONEYBADGER_REPOSITORY&api_key=$HONEYBADGER_API_KEY" ``` If you are using our [EU stack](/resources/data-residency/), use `eu-api.honeybadger.io` instead of `api.honeybadger.io`. ### Honeybadger CLI [Section titled “Honeybadger CLI”](#honeybadger-cli) Use the `hb deploy` command in the [Honeybadger CLI](/resources/cli/): ```shell hb deploy --environment production --repository github.com/org/repo --revision abc123 --user johndoe ``` ## Deployment notifications [Section titled “Deployment notifications”](#deployment-notifications) Honeybadger can notify your team when your app is deployed. Any of your configured [integrations](/guides/integrations/) — Slack, PagerDuty, email, and more — can be set up to receive deploy notifications. If you’re using the webhook integration, see the [deployed event payload](/guides/integrations/payloads/deployed/) for the payload format. # Error monitoring > Collect, manage, and resolve your application errors. ## Installation [Section titled “Installation”](#installation) Before you can start using Honeybadger to squash bugs, you will need to install our library into your app. Installation usually boils down to: 1. Installing the Honeybadger library 2. Setting the API key 3. Enabling error reporting The details vary a little depending on language and platform. But you can always find the correct installation instructions for YOUR app on the “Project Settings” page. In case you are wondering, we officially support: [Ruby](/lib/ruby/), [client-side JavaScript](/lib/javascript/), [Vue](/lib/javascript/integration/vue3/), [Elixir](/lib/elixir/), [Go](/lib/go/), [NodeJS](/lib/javascript/integration/node/), [Java](/lib/java/), [Python](/lib/python/), [PHP](/lib/php/), [Clojure](/lib/clojure/), and [Cocoa](/lib/cocoa/) Check out any of these pages to see how to install Honeybadger for your app. Once our client library is installed and configured, errors thrown by your application are automatically sent to our API. ## Error grouping [Section titled “Error grouping”](#error-grouping) Honeybadger groups similar exceptions together using rules which we’ve found to work the best in most cases. The default information we use to group errors is: 1. The file name, method name, and line number of the error’s location 2. The class name of the error 3. The component/controller name We use this information to construct a “fingerprint” of the exception. Exceptions with the same fingerprint are treated as the same error in Honeybadger. You can customize the grouping for each exception by changing the error class name, component, or stack trace—or by sending a custom fingerprint. ## Anatomy of an error [Section titled “Anatomy of an error”](#anatomy-of-an-error) When your app reports an error to us, we make the details available on a web page that looks like this: ![Error Detail Page Overview](/_astro/error_details_overview.CSFRsqS2_cgrK0.webp) Yeah, it looks a little complicated. But once you understand what all the pieces are, you will see it is quite simple. Let’s inspect this page, piece by piece. ### Navigating occurrences [Section titled “Navigating occurrences”](#navigating-occurrences) ![Navigate occurrences](/_astro/navigate_occurrences.6JYATbhN_ZTi5VN.webp) Honeybadger groups identical errors together. Using our navigation bar, you can still navigate between each individual occurrence (or notice, as we also call them) of the error. ### Resolve / unresolve [Section titled “Resolve / unresolve”](#resolve--unresolve) When an error is marked “unresolved” we will not send you any additional notifications when it re-occurs. Errors are auto-resolved on deploy by default, but that is [configurable](/guides/projects/#resolve-errors-on-deploy). ![Resolved and Unresolved](/_astro/resolved.Cjkp4K5y_2qVyuj.webp) ## Error actions [Section titled “Error actions”](#error-actions) Here you can perform many of the actions available to your error. Also, as you set up [integrations](/guides/integrations/) for the project, any that can link back to the error (say, an issue tracker like GitHub) can be managed here. ![Error actions](/_astro/error_actions.DAFSpFFX_1vdGSI.webp) ### Assign an error [Section titled “Assign an error”](#assign-an-error) Using this button, you can assign the error currently viewed to any user in the project. This can later be used to search by assignment, or, with assignment notifications enabled, to inform a user that a new error has been assigned to them. ### Pause or ignore an error [Section titled “Pause or ignore an error”](#pause-or-ignore-an-error) ![Ignore options](/_astro/ignore.fz4wIMMq_Z2d03xb.webp) One of the more common actions used is to ignore the occurrences of an error. #### Pausing [Section titled “Pausing”](#pausing) You can choose to “Pause” for a time duration or occurrence count. We will still record the occurrences, we just will not notify you. Pausing notifications does not affect the resolved/unresolved status of an error. If you resolve an error while notifications are paused, the next occurrence will still mark it as unresolved — you just won’t be notified about it. When notifications resume depends on the type of pause: * **Time-based pause:** Notifications resume on the first occurrence received after the time period has elapsed. * **Count-based pause:** Notifications resume on the occurrence that exhausts the count (e.g., the 10th occurrence when paused for 10). In both cases, a notification will be sent even if the error was already reopened by an earlier occurrence during the pause. #### Ignoring [Section titled “Ignoring”](#ignoring) When you “ignore” an error we will stop recording altogether, so it will not go against your quota. ### Resolve on deploy [Section titled “Resolve on deploy”](#resolve-on-deploy) By default, Honeybadger resolves all the errors in your project when you [report a deployment](/api/reporting-deployments/), causing new alerts to be sent for any of the errors that re-occur. You can turn off this behavior by unchecking the “Resolve errors on deploy” checkbox in [Project Settings](/guides/projects/#resolve-errors-on-deploy). When turned off, there is a new action in the [actions area](#error-actions) of the error detail page, allowing you to resolve individual errors on the next deploy. ![Error actions resolve on deploy](/_astro/error-actions-resolve-on-deploy.DLoP2DMn_Z2cBH3n.webp) To find errors waiting to be resolved on the next deploy, use the `is:pending_resolution` [search token](/guides/errors/search/#examples). ### Unsubscribe [Section titled “Unsubscribe”](#unsubscribe) Unsubscribing from an error disables it from sending notifications - but only for the user currently viewing the error. To silence it for all users, use the pause action. ### Export an error [Section titled “Export an error”](#export-an-error) The Export dropdown allows you to download the data for the current error as [Markdown](https://daringfireball.net/projects/markdown/), or export a JSON file of all occurrences via email. The Markdown version includes the error summary, stack trace, environment details, and breadcrumbs for the current error formatted in standard Markdown syntax compatible with GitHub, Notion, Google Docs, and other Markdown-capable tools. ![Export dropdown menu showing options: Download as Markdown, Copy Markdown to clipboard, Send details for all occurrences via email](/_astro/error-actions-export.CnW_k8gJ_1RiF4w.webp) When exporting all occurrences, you’ll receive an email to download a JSON file containing the data. This file is a [newline-delimited JSON file](https://en.wikipedia.org/wiki/JSON_streaming#Newline-delimited_JSON), which means each line is a valid JSON object. Each of those JSON objects has the data (parameters, context, etc.) for a single occurrence of the error. ### Merge errors [Section titled “Merge errors”](#merge-errors) Using the merge action, you can combine one error with another error. This takes all the existing notices from the “donor” error and adds them to the “receiver” error’s notice history. ### Share URL [Section titled “Share URL”](#share-url) Sharing the URL of the error will give you a link to a webpage displaying the error. This webpage does not allow for any actions, comments, or the ability to resolve the error. ### Delete [Section titled “Delete”](#delete) This removes the error and all of the notice history for that error. This is especially useful if your error information happens to accidentally include sensitive information. New instances of the error will appear again on a new error page. ### Action integrations [Section titled “Action integrations”](#action-integrations) GitHub and other project management integrations will add another action button - in GitHub’s case the button is labeled “Create issue”. Other integrations will behave similarly. ## Anatomy of an error, continued [Section titled “Anatomy of an error, continued”](#anatomy-of-an-error-continued) Each error page contains a substantial amount of detail related to the error itself and a history of all the actions done to the error. You can see how many times it was resolved or merged and who performed each action. From the top of the error page, you can see all of the categories and can click to any of them. There’s even a keyboard shortcut for each category. ![Error categories](/_astro/error_tabs.BxEcjvmc_2fO5vD.webp) ### Notices [Section titled “Notices”](#notices) Note **Notices** are the individual error events that are sent from your app. We also refer to them as **occurrences**. The Notices section allows you to see the distribution of occurrences over time. You can constrain the dates and filter using the same search criteria as our [error search](/guides/errors/search/). When you view an error after doing a search, the search criteria will be applied to the notice list. ![Notices](/_astro/notices_overview.9bBM40tS_16N5zT.webp) ### Comments [Section titled “Comments”](#comments) Communicate with team members, or record notes to retain context around an error. Your comments can be formatted in GitHub-flavored Markdown. ![Comments](/_astro/comments.CELe4Z9j_Z2kR574.webp) Type `@` in a comment to mention a teammate. An autocomplete menu lets you pick from the project’s members, and mentioned users are notified by email and by in-app notification (subject to their personal alert preferences). Editing a comment to add a new mention also notifies the newly-mentioned user. ### Backtrace [Section titled “Backtrace”](#backtrace) Each line in the backtrace links to the GitHub or Bitbucket repo. You can even click a button to open the file in your [local editor](#local-edits). ![Backtrace](/_astro/backtrace.B9Z__Xgi_ZyRTwo.webp) ### Request params, cookies, ENV, etc. [Section titled “Request params, cookies, ENV, etc.”](#request-params-cookies-env-etc) When an error occurs during a web request, we record all the relevant debug info like params, cookies, the session, etc. ![Params](/_astro/params.DTYlTQ-y_1z34i8.webp) ### Context data [Section titled “Context data”](#context-data) Our clients support providing a special set of data called **context**. This data is provided by you to help with debugging. You can use our [search functionality](/guides/errors/search/#search-by-request) to find errors with specific context. Tip `user_id` and `user_email` are special context keys that we use to help with looking up users or sending emails (as you can see below.) ![Context](/_astro/context.DH016mdG_Z14uLd2.webp) ## Browsing errors [Section titled “Browsing errors”](#browsing-errors) Once you start collecting errors, it can be difficult to keep track of them. To make it easier, we’ve built a great interface for browsing and searching errors. ![Navigating Errors](/_astro/error_index.BJSWxVqr_1Wc5e9.webp) ### Search [Section titled “Search”](#search) With advanced search, you can search by any field of params, environment, cookies or the session. Check out our dedicated [search guide](/guides/errors/search/) for more info. ### Batch actions [Section titled “Batch actions”](#batch-actions) ![Batch actions](/_astro/batch_actions.Dh7aOwX1_Z2cRJrF.webp) You can use the *Bulk Update* dropdown to update multiple errors simultaneously. You can apply actions to all search results (this is the default), or you can use the checkboxes in the error list to apply the actions to selected errors. 1. Use the search to select which errors you’d like change. 2. Click on “Actions” and select one or more options from the drop-down. #### Merging by batch [Section titled “Merging by batch”](#merging-by-batch) You can merge two or more errors to create a single error. There are two ways to merge errors: 1. Click the [Merge](#merge-errors) button in the [*Actions*](#error-actions) panel on the error detail page, as described above. 2. Select two or more errors to merge from the [error index page](#browsing-errors) using the checkboxes and use the “Merge to” action in the [*Bulk Update*](#batch-actions) dropdown. Note: The *Bulk Update* method can merge up to ten thousand error occurrences simultaneously. You can perform multiple updates if necessary. ## Local edits [Section titled “Local edits”](#local-edits) One of the advanced features in Honeybadger is configuring your local editor settings so that we can display links to open files locally when showing you an error backtrace: ![Open in editor](/_astro/open_in_editor.DOcSMHLT_1yE2Gk.webp) To configure your editor, [visit the Local Editor tab under My Settings](https://app.honeybadger.io/users/edit#editor). Select the editor you use (if you use a different editor that supports opening files via a custom protocol, [let us know about it](https://www.honeybadger.io/pages/contact)). Next, enter the absolute path to each project you wish to enable local editor links for and click “Save” at the bottom. Re-visit your error pages - they should now have the “Open in editor” links! Most editors work without any additional setup, but Sublime and Visual Studio Code don’t ship with a custom protocol by default. In order to make them work, you’ll need to install one of these libraries: * [Sublime 2 handler for OS X](https://github.com/asuth/subl-handler) * [Sublime 3 handler for OS X](https://github.com/saetia/sublime-url-protocol-mac) * [Visual Studio Code handler](https://github.com/robyoder/vscode-handler) If you’re using Atom, make sure you’re on version 1.23 or later for this to work. Disclaimer: We do not endorse nor support these libraries; they are 3rd party open source software. ## Content Security Policy reports [Section titled “Content Security Policy reports”](#content-security-policy-reports) If you use [Content Security Policy (CSP)](https://developer.mozilla.org/en-US/docs/Web/HTTP/CSP) headers to help mitigate XSS attacks, you can use Honeybadger to track policy violations. You can configure the required headers via code when using [Rails](/lib/ruby/integration-guides/rails-exception-tracking/#content-security-policy-reports) or [Sinatra](/lib/ruby/integration-guides/sinatra-exception-tracking/#content-security-policy-reports), or you can configure your web server or framework to emit the headers. Either way, configuring CSP reporting requires specifying the `report-uri` directive: ```plaintext Content-Security-Policy: ...; report-uri https://api.honeybadger.io/v1/browser/csp?api_key=PROJECT_API_KEY&env=production Content-Security-Policy-Report-Only: ...; report-uri https://api.honeybadger.io/v1/browser/csp?api_key=PROJECT_API_KEY&report_only=true&env=production ``` The `env` and `report_only` parameters are optional. When `report_only` is true, CSP report payloads will show up as “CSP Report” in our UI; otherwise, the label will be “CSP Error”. Since CSP violations can be noisy, we strongly suggest you track them in a separate Honeybadger project. # Error search > All the ways you can find your errors. Honeybadger provides powerful search features that let you easily find previously-occurred errors by type, location, meta-data and many other attributes. You can search for errors in a single project, or across all projects. To search by error type and message, you can simply enter those into the search box. More advanced searches are accomplished via a special query language. We’ve provided a query builder that lets you construct useful queries quickly and easily. ## How to search [Section titled “How to search”](#how-to-search) Enter a free-form text value, or one or more `key:"value"` tokens into the search box. Then press enter, or click on the magnifying glass button. Tokens are separated by spaces. Single and double quotes are allowed. Example query: `john class:UserError -tag:wip -tag:pending component:"UsersController" action:'update'`. Because these search queries can become quite complex, we’ve included a query builder that allows you to construct them without much typing. The query builder automatically opens when you focus the search box. ![Image of search box and search palette](/_astro/search_palette.Bk-yTBxd_lLcQ.webp) ## Natural language search [Section titled “Natural language search”](#natural-language-search) You can search for errors without writing the query yourself. Click the lightbulb icon next to the search box to open the “Describe your search” panel, then describe what you want to find. Click Translate and Honeybadger will turn it into a search query. ![The Describe your search panel on the errors page](/_astro/describe-your-search.DH9nBNck_2rWHyM.webp)![The Describe your search panel on the errors page](/_astro/describe-your-search-dark.5_gL5yXE_Z1PGYS2.webp) The translated filter is added to the search bar and runs immediately. You can then edit the query by hand or adjust it with the query builder. This can also be a useful way to learn the query syntax. **Note:** The NL search uses an LLM, so it may not always get things right. If the translations are not what you expected, please feel free to [reach out to support](mailto:support@honeybadger.io). ## Keyboard navigation [Section titled “Keyboard navigation”](#keyboard-navigation) Use the following keyboard shortcuts in the search box as you edit your query. Additional context-sensitive options will be shown to you as you type. | Key | Response | | ------------- | -------------------------------------------------- | | enter | Submits form | | tab | Tabs to next token and selects value inside quotes | | shift-tab | Reverse-cycles selected token | | mod backspace | Deletes selected token | | escape | Closes hint | ## Keyboard shortcuts [Section titled “Keyboard shortcuts”](#keyboard-shortcuts) Quickly search errors using the following keyboard shortcuts while on the error page in the project. Note that these shortcuts immediately trigger a page load and will not preserve the state of the search builder. | Key | Response | | ------ | ------------------------------------ | | / | Focus search box | | A or a | Show resolved And Unresolved Errors | | U or u | Show Unresolved Errors | | R or r | Show Resolved Errors | | M or m | Show Errors Assigned to Me | | T or t | Show All Users’ Errors | | J or j | Jump to another project \* | | E or e | Show errors in all environments \*\* | \*This shortcut can be used on any page of the project. \*\*Use first character of environment name to filter by environment. ## How tokens are combined [Section titled “How tokens are combined”](#how-tokens-are-combined) When combining different tokens, we use AND. So `class:MyError assignee:myemail@domain.com` searches for `MyError` instances that are assigned to me. When combining multiple values for the same token, we use OR. For example, `class:"Foo" class:"Bar" `will return errors with class `Foo` OR `Bar`. There’s one minor exception to this rule. Negative tokens, i.e. tokens preceded by `-` will be combined with AND. Here are a few examples: | Example query | Searches | | --------------------------------------- | --------------------------------------------------- | | `class:"Foo" is:resolved` | Resolved errors with class `Foo` | | `-class:"Foo" is:resolved` | Resolved errors without class `Foo` | | `-class:"Foo" -is:resolved` | Unresolved errors without class `Foo` | | `class:"Foo" class:"Bar" is:resolved` | Resolved errors with class `Foo` OR class `Bar` | | `-class:"Foo" -class:"Bar" is:resolved` | Resolved errors without class `Foo` AND class `Bar` | ## Examples [Section titled “Examples”](#examples) ### Search by state [Section titled “Search by state”](#search-by-state) Search errors that are resolved, ignored, paused, or pending resolution, and the inverse of those states. By default, Honeybadger sorts all errors by `-is:ignored` and `-is:resolved`, showing you everything that has not been set as ignored or resolved. These tokens are automatically populated in the search box. | Example query | Searches | | ------------------------ | -------------------------------------------------------- | | `is:resolved` | Resolved errors | | `-is:resolved` | Unresolved errors | | `is:paused` | Paused errors | | `-is:paused` | Errors that aren’t paused | | `is:ignored` | Ignored errors | | `-is:ignored` | Errors that aren’t ignored | | `is:pending_resolution` | Errors that are set to be resolved on the next deploy | | `-is:pending_resolution` | Errors that aren’t set to be resolved on the next deploy | ![Image of resolved, ignored, and paused requests](/_astro/resolved_ignored_paused.CFXPWmy-_1Ep1oh.webp) ### Search by assignee [Section titled “Search by assignee”](#search-by-assignee) Errors can be assigned to team members, and results can be refined by assignment. Tokens can be combined to search errors assigned to multiple team members. | Example query | Searches | | ---------------------------- | ---------------------------------------- | | `assignee:"nobody"` | Unassigned errors | | `assignee:"anybody"` | Errors assigned to anyone | | `assignee:"jane@email.com"` | Errors assigned to a specific person | | `-assignee:"jane@email.com"` | Errors not assigned to a specific person | If other, choose a team member from the drop-down list or begin typing to trigger auto-complete. ![Animation of assigned to menu](/_astro/assigned_to.BlEX6wQc_xIn07.webp) ### Search by environment [Section titled “Search by environment”](#search-by-environment) Search errors by your environment: | Example query | Searches | | ---------------------------------- | ----------------------------------- | | `environment:"production"` | Errors occurring in production | | `-environment:"production"` | Errors not occurring in production | | `environment:"development"` | Errors occurring in development | | `-environment:"development"` | Errors not occurring in development | | `environment:"custom_environment"` | Errors occurring in any environment | If other, choose an environment from the drop-down list or begin typing to trigger auto-complete. ![Animation of environment menu](/_astro/environment.Ls0nlmxW_Z1BKPR1.webp) ### Search by date [Section titled “Search by date”](#search-by-date) Search errors by their occurrence. Your timezone is automatically determined but can be changed manually. | Example query | Searches | | ----------------------------------------- | --------------------------------------------- | | `occurred.after:"YYYY-MM-DD 0:00 UTC-7"` | Errors last seen after an exact date | | `occurred.before:"YYYY-MM-DD 0:00 UTC-7"` | Errors last seen before an exact date | | `occurred.after:"24 hours ago"` | Errors last seen after a human-friendly date | | `occurred.before:"24 hours ago"` | Errors last seen before a human-friendly date | You can enter human-friendly dates like `today`, `this week`, or `July 1`, for example: `occurred.after:"this week"`. If you want to see errors that **last** occurred as of a certain date — that is, they haven’t occurred again since that date — you can use `last_occurred` instead of `occurred`, like so: `last_occurred.before:"1 week ago"`. ![Animation of last occurred query](/_astro/last_occurred.U3FJnzk-_d2Xlw.webp) ### Search by first seen [Section titled “Search by first seen”](#search-by-first-seen) Search errors by when they were first seen. Your timezone is automatically determined but can be changed manually. | Example query | Searches | | ---------------------------------------- | ---------------------------------------------- | | `created.after:"YYYY-MM-DD 0:00 UTC-7"` | Errors first seen after an exact date | | `created.before:"YYYY-MM-DD 0:00 UTC-7"` | Errors first seen before an exact date | | `created.after:"24 hours ago"` | Errors first seen after a human-friendly date | | `created.before:"24 hours ago"` | Errors first seen before a human-friendly date | You can enter human-friendly dates like `today`, `this week`, or `July 1`, for example: `created.after:"September 12"`. ### Search by error details [Section titled “Search by error details”](#search-by-error-details) Search error by class, tag, and message. | Example query | Searches | | -------------------------------- | ----------------------------------------------------------- | | `class:"PermissionDeniedError"` | Errors with a certain class | | `-class:"PermissionDeniedError"` | Errors without a certain class | | `tag:"tag_example"` | Errors with a tag | | `-tag:"tag_example"` | Errors Without a tag | | `message:"404"` | Errors with a message | | `-message:"404"` | Errors without message text | | `has:ticket` | Errors with an associated GitHub issue, Asana task, etc. | | `-has:ticket` | Errors without an associated GitHub issue, Asana task, etc. | | `has:comment` | Errors that have comments from team members | | `-has:comment` | Errors that have no comments from team members | Class, tag, and message can be combined for specific results. For example, the query: `message:"NameError" class:"TextOrganizer" tag:"priority"` searches errors containing “NameError” from the TextOrganizer class with a “priority” tag. ### Search by location [Section titled “Search by location”](#search-by-location) Search errors by component, action, URL, file name, and host. | Example query | Searches | | ----------------------------------- | ---------------------------------------------------------------------------------------------------------------------------------- | | `component:"UsersController"` | Errors occurring in a controller/component | | `-component:"UsersController"` | Errors not occurring in a controller/component | | `action:"update"` | Errors occurring in an action | | `-action:"update"` | Errors not occurring in an action | | `request.url:"https://google.com"` | Errors occurring at a URL | | `-request.url:"https://google.com"` | Errors not occurring at a URL | | `request.host:"api.yoursite.com"` | Errors occurring in an application with this in the HTTP\_HOST environment variable (the Host: header provided by the browser) | | `-request.host:"api.yoursite.com"` | Errors not occurring in an application with this in the HTTP\_HOST environment variable (the Host: header provided by the browser) | | `file:somefile.rb` | Errors occurring in this file | | `-file:somefile.rb` | Errors not occurring in this file | | `hostname:"api-east1-a"` | Errors occurring on a server with this hostname | | `-hostname:"api-east1-a"` | Errors not occurring on a server with this hostname | | `revision:"v1.10"` | Errors occurring from a deployment tagged with this revision | | `-revision:"v1.10"` | Errors not occurring from a deployment tagged with this revision | Locations can be combined for more specific results. For example, the query: `component:"UsersController" action:"update" request.url:"/docs"` searches errors generated from the update action in the UsersController in the URL `camera`. ### Search by request [Section titled “Search by request”](#search-by-request) Search errors by context, params, user agent, or session hashes. | Example query | Searches | | ----------------------------------------------- | --------------------------------------------------------------------- | | `context.user_id:*` | Errors that impacted a user (if you send user\_id in context) | | `context.user_email:*` | Errors that impacted a user (if you send user\_email in context) | | `context.user.email:"bob@example.io"` | Errors with a matching context value | | `-context.user.name:"Bob"` | Errors without a matching context value | | `params.user.first_name:"Bob"` | Errors with a matching param value | | `params.old:"useless"` | Errors without a matching param value | | `request.user_agent:"Googlebot` | Errors caused by a user with this user agent | | `-request.user_agent:"Googlebot` | Errors not caused by a user with this user agent | | `request.referer:"http://my.site.com/location` | Errors that occurred when the user came from a particular URL | | `-request.referer:"http://my.site.com/location` | Errors that occurred when the user did not come from a particular URL | Requests can be combined or nested for more specific results. For example, searching for context.user.email:bob\@example.com would match the following hash that was sent in the context with an error: `{ user: { email: "bob@example.com" } }` When searching these hashes, separate the nested levels of the hash with a period. For example `params.user.first_name:bob`. Searches against context, params, user agent, or session hashes use \* as a wild-card, so a search for `context.user.email:*@example.com` would match any email address at example.com. ### Searching for arrays [Section titled “Searching for arrays”](#searching-for-arrays) When searching for data within array values, one way is to do the search on a key that contains the array value. For example, you might have a sidekiq job that shows up with params in our UI like this: ```ruby {"job" => {"args" => [{"job_class" => "Foo", "job_id" => "123"}]}} ``` To search for “Foo”, your search should look like this: `params.job.args:*Foo*` You could be more explicit by including the array index in the query: `params.job.args.0.job_id:123` ## Sorting results [Section titled “Sorting results”](#sorting-results) Error results can be sorted by date or error count. ### Sort by date [Section titled “Sort by date”](#sort-by-date) Sorting by “Last seen” lets you quickly jump to the newest or oldest exceptions that match your search result. 1. Go to your project’s error list page 2. Click on the table header labeled “last seen” 3. Click on it again to reverse the sort order ![Image of sort by date button](/_astro/toggle_sort_order.JsgxHV_y_ZyovM2.webp) ### Sort by count [Section titled “Sort by count”](#sort-by-count) Sorting by “Times” lets you see which errors have happened the most or the fewest times. 1. Go to your project’s error index 2. Click on the table header labeled “times” 3. Click on it again to reverse the sort order ![Image of sort by count button](/_astro/toggle_count_order.Ck3I3KUF_Z1UIYTh.webp) ## Saved searches and default search [Section titled “Saved searches and default search”](#saved-searches-and-default-search) You can save a search using the button with the bookmark icon to the right of the button with the search icon. This allows to easily re-use a search. You can also pin a saved search to use that search as the default search. Once you have pinned a search, those search terms will be used as the default view for the project. ![Image of saving and pinning a search](/_astro/save_search.D1piFoQ__Z1WCiIF.webp) ## Batch actions [Section titled “Batch actions”](#batch-actions) ![Batch actions](/_astro/batch_actions.Dh7aOwX1_Z2cRJrF.webp) You can use the *Bulk Update* dropdown to update multiple errors simultaneously. You can apply actions to all search results (this is the default), or you can use the checkboxes in the error list to apply the actions to selected errors. 1. Use the search to select which errors you’d like change. 2. Click on “Actions” and select one or more options from the drop-down. ## Free-form text search [Section titled “Free-form text search”](#free-form-text-search) Search through your errors by **class** or error **message** by typing your search term into the search box. Free-form text queries can also be combined with `key:value` tokens, for example: `john class:UserError component:UsersController action:update`. # Heroku > Honeybadger + Heroku <3. Honeybadger has great built-in support for Heroku, including automated deployment tracking and monitoring of Heroku [platform errors](https://devcenter.heroku.com/articles/error-codes). ## Overview [Section titled “Overview”](#overview) There are two ways to use Honeybadger with Heroku: via our Heroku add-on, and via a regular Honeybadger account. Each has its own unique strengths. * **Heroku Add-On:** When you purchase the Honeybadger add-on through the Heroku marketplace, you’re buying access for a single project and a single user. If this is all you need, the Heroku add-on can be super convenient. But if you have several users managing errors for multiple projects, it can be a hassle…not to mention more expensive. * **“Regular” Honeybadger Account:** If you’ve signed up for a Honeybadger account via our website, good news! You still have access to all our Heroku-related features. We’ll cover how to set that up below. You’ll also get a plan that allows multiple projects and multiple users. ### Converting Heroku accounts [Section titled “Converting Heroku accounts”](#converting-heroku-accounts) If you are currently a Heroku add-on customer and would like to switch to a “regular” account, we can do that. Just email us at . ## Heroku deployment tracking [Section titled “Heroku deployment tracking”](#heroku-deployment-tracking) With deployment tracking, Honeybadger is notified when you deploy your app. It’s optional, but enabling it lets you do some really cool things, like: * Send alerts to Slack whenever your project is deployed. * Automatically resolve errors on deployment, so that any new occurrences **after** deployment will send you a new notification. * See which errors occurred after which deployments. It’s super easy to set up deployment tracking for your Heroku apps. Just run the following command, making sure to add your Honeybadger API key at the end: ```bash heroku webhooks:add -i api:release -l notify -u "https://api.honeybadger.io/v1/deploys/heroku?repository=git@github.com/username/projectname&environment=production&api_key=PROJECT_API_KEY" --app app-name ``` If you’re using our Ruby gem, you can use the `honeybadger` command line tool to do the same thing: ```bash bundle exec honeybadger heroku install_deploy_notification ``` ## Heroku platform errors [Section titled “Heroku platform errors”](#heroku-platform-errors) > If you’re a Heroku add-on customer, platform error monitoring may already be set up. To check, run `heroku drains -a APP_NAME` and see if it mentions Honeybadger or “logplex.honeybadger.io”. If it does, you don’t need to set anything else up. Normally, Honeybadger only sees errors that happen inside your application. On Heroku, we’re able to go one step farther and monitor [platform errors](https://devcenter.heroku.com/articles/error-codes). These include the dreaded H12 timeouts and R99 errors you may have seen in your Heroku logs. To capture these errors we use Heroku’s log drain feature. Each line of your logs is sent to our servers in the background. We pull out the errors and throw everything else away. To add the log drain, run the following command, replacing API\_KEY with your Honeybadger project’s secret token and APP\_NAME with the name of your Heroku app: ```bash heroku drains:add https://logplex.honeybadger.io/heroku/v1?api_key=PROJECT_API_KEY-a APP_NAME ``` To monitor different environments in the same Honeybadger project, add the `env` parameter to the log drain endpoint, i.e.: ```bash heroku drains:add https://logplex.honeybadger.io/heroku/v1?api_key=PROJECT_API_KEY&env=production -a APP_NAME ``` ## Heroku platform logs [Section titled “Heroku platform logs”](#heroku-platform-logs) To send all of your Heroku logs into [Insights](/guides/insights) (in addition to errors, as described above), create an additional log drain for your Heroku app using an API key displayed on the API keys tab of the project settings page: ```bash heroku drains:add "https://logplex.honeybadger.io/v1/events?api_key=PROJECT_API_KEY" ``` You can optionally add the `env` parameter to the log drain endpoint. If you do so, each payload recorded from Logplex will have a field named `environment` added to it. You can then add a filter for the desired environment to your queries, like `filter environment::str == 'production'`. ```bash heroku drains:add https://logplex.honeybadger.io/v1/events?api_key=PROJECT_API_KEY&env=production ``` # Insights & Logging > Dive into your Honeybadger and application events. You can use [Honeybadger Insights](https://www.honeybadger.io/tour/logging-observability/) to dive into the data collected by Honeybadger and the logs and other events that you send to our [Events API](/api/reporting-events/). We provide a query language (that we lovingly call [BadgerQL](/guides/insights/badgerql/)) that enables quick discovery of what’s happening inside your applications. The Insights UI also lets you chart the results of those queries and add those charts to [dashboards](/guides/dashboards/) that you can share with your team. ![Insights overview](/_astro/insights-overview.QfCgwxZs_1vgqdM.webp) ## Querying and visualization [Section titled “Querying and visualization”](#querying-and-visualization) Our [query language](/guides/insights/badgerql/) strives to be minimalist, yet powerful. With it you can specify which fields you want to see, filter the kinds of events that should be returned, perform aggregations and calculations, and more. When you first load the Insights UI, you will see a query box that has a default query to help you get started: ```badgerql fields @ts, @preview | sort @ts ``` This query selects a couple of special fields — the timestamp and a preview of the fields that are available in the event — and sorts the results by time, with the most recent results first. Each row of the query is piped through the following row, which allows you to apply filters, formatting functions, and so on. Let’s do a quick walk-through to see how it works, and to see how it can be used to create visualizations of your data. ### Walk-through [Section titled “Walk-through”](#walk-through) Here’s an example of working with some Honeybadger data. First, filter the data to see only the results of [uptime checks](/guides/uptime/): ```badgerql fields @ts, @preview | filter event_type::str == "uptime_check" | sort @ts ``` ![Filtered query results](/_astro/query-filter.CHlCuZ6L_ZkYWG3.webp) You can see that we’ve piped the initial results through `filter`, which accepts a variety of conditions, such as the string comparison shown here. You’ll also notice that we specified the data type of the `event_type` field (`str`) so the query parser can validate the functions and comparisons that you use on the field data. Clicking on the disclosure arrow will show the all the fields that were stored for an event: ![Event detail](/_astro/event-detail.FXaPoHe__EICVc.webp) Additional disclosure controls appear inside the event detail view when the event has nested objects. Let’s filter on some additional data that is present in these events. We can limit the results to show only the uptime checks that originated from our Virginia location, and we can change the fields that we display so we can see some info about the results of each check: ```badgerql fields @ts, location::str, response.status_code::int, duration::int | filter event_type::str == "uptime_check" | filter location::str == "Virginia" | sort @ts ``` ![Limiting the fields in a query](/_astro/limited-fields.lCHUE-Ou_29OtcT.webp) Now let’s summarize the data to find the average response duration for all successful checks: ```badgerql fields duration::int | filter event_type::str == "uptime_check" | filter location::str == "Virginia" | filter response.status_code::int == 200 | stats avg(duration) by bin(1h) as time | sort time ``` ![Using aggregates](/_astro/aggregates.Bnd1TDNK_1uVdtj.webp) We use `stats` to perform all kinds of calculations, such as averages, and `by` allows us to specify the grouping for those calculations. Grouping by `bin` gives us time-series data, which makes it easy to create a chart by clicking the Line button. ![Line chart of response times](/_astro/chart.D5s7aHUj_Z1Q49zf.webp) From there you can experiment with different visualizations, update the query to change the chart (try changing `1h` to `15m`), and add the chart to a custom dashboard. Of course, this functionality isn’t limited to only the data that is generated by Honeybadger. Your error data is also available for querying (`event_type::str == "notice"`), and you can send logs and events to our [API](/api/reporting-events/) to be able to query and chart your own data. ### Natural language queries [Section titled “Natural language queries”](#natural-language-queries) You don’t need to know [BadgerQL](/guides/insights/badgerql/) to query your data. Click the lightbulb icon to the right of the query editor to open the natural language translator panel. Describe what you want to see, then press `⌘+Enter` or click Translate and Honeybadger will write the query for you. ![The natural language translator panel](/_astro/describe-your-query.qlhHVxF5_Z2vA7Kd.webp)![The natural language translator panel](/_astro/describe-your-query-dark.CwkoMPuO_ZtkF7G.webp) The translator uses your current query as context, so you can build up a query in steps. Start broad, then ask for changes like including the duration, grouping by controller, or narrowing to just 5xx status codes. You can also include other display options in your description. For example, ask for “the last hour” or “as a line chart” and Honeybadger will update the time range or visualization. **Note:** The NL translator uses an LLM, so it may not always get things right. If the translations are not what you expected, please record your feedback via the thumbs, or feel free to [reach out to support](mailto:support@honeybadger.io). ### Streams [Section titled “Streams”](#streams) Streams are the fundamental data sources in Honeybadger Insights. They serve as the starting point for your queries and represent the data you want to analyze. When you create a new Honeybadger project, we automatically set up two streams for you: **Internal stream** The Internal Stream is a dedicated stream that stores all Honeybadger-generated events related to your project. This includes errors, deployments, notifications, uptime checks, and other internal Honeybadger data. You cannot directly send custom events to the Internal Stream, as it is managed by Honeybadger itself. **Default stream** The Default Stream is the primary stream for storing custom events that you send using Honeybadger client libraries or the Honeybadger API. Any event data you explicitly send to Honeybadger will be stored in the Default Stream. #### The stream selector [Section titled “The stream selector”](#the-stream-selector) You can select the active streams from the stream selector at the top of the query editor. This affects the data that Insights returns for your queries. ![Insights stream selector](/_astro/insights-stream-selector.CVDB6NrA_1vMagn.webp) Removing a stream you don’t need can improve your query response times, because then Insights doesn’t need to scan that data when executing your query. So for example, if you’re just querying your application logs, you can remove the *Internal* stream to get a faster response. ## Working with dashboards [Section titled “Working with dashboards”](#working-with-dashboards) [Dashboards](/guides/dashboards/) allow you to collect different types of charts and query results on a single page. Any query or chart that you generate can be added to a dashboard, which will then be shared with the rest of your team. Each widget on a dashboard includes a link to view the query and raw results behind the widget: ![Notices widget](/_astro/notices-widget.CcYkg-DL_Z2jAB5M.webp) If you change the query or the visualization, you can save those changes back to your dashboard, or add them as a widget to a new dashboard. We provide some [automatic dashboards](/guides/dashboards/#automatic-dashboards) to get you started. For example, when you [add a Heroku drain](/guides/insights/integrations/heroku/) to your app, the [automatic Heroku dashboard](/guides/dashboards/heroku/) will show data like the number of requests grouped by response code that we automatically collect from [Logplex](https://devcenter.heroku.com/articles/logplex). To learn more about dashboards, see the [dashboards guide](/guides/dashboards/). ## Adding data from other sources [Section titled “Adding data from other sources”](#adding-data-from-other-sources) Insights includes all the events that Honeybadger collects, such as error notifications, uptime checks, and check-in reports, but you can send your own event data as well. Our [API](/api/reporting-events/) accepts newline-delimited JSON, where each line is a JSON object that describes an event that you care about. You can send user audit trail events, metrics, or any other data you’d like to query and analyze. The type of data most frequently sent to Insights is application log data. Sending structured logs in a JSON format (like [lograge](https://github.com/roidrage/lograge) produces) allows you to correlate what’s happening in your app with the error data that Honeybadger is already recording for you. See our integration guides to learn how you can easily send log events from sources such as Heroku apps and CloudWatch Logs. [Ruby and Rails apps](/guides/insights/integrations/ruby-and-rails/)Send metrics and events from Ruby and Rails apps to Honeybadger Insights [Elixir/Phoenix apps](/guides/insights/integrations/elixir-phoenix/)Send logs and events from Elixir/Phoenix apps to Honeybadger Insights [JavaScript apps](/guides/insights/integrations/javascript/)Send metrics and events from JavaScript apps to Honeybadger Insights [PHP/Laravel apps](/guides/insights/integrations/php-laravel/)Send metrics and events from PHP/Laravel apps to Honeybadger Insights [OpenTelemetry (Beta)](/guides/insights/integrations/opentelemetry/)Send traces, metrics, and logs via the OpenTelemetry Protocol (OTLP) [CloudWatch Logs](/guides/insights/integrations/cloudwatch-logs/)Stream AWS CloudWatch Logs to Honeybadger Insights [Crunchy Bridge](/guides/insights/integrations/crunchy-bridge/)Send Crunchy Bridge metrics to Honeybadger Insights [Fly.io](/guides/insights/integrations/fly-io/)Send Fly.io app metrics to Honeybadger Insights [Heroku](/guides/insights/integrations/heroku/)Send Heroku app metrics to Honeybadger Insights [Host metrics](/guides/insights/integrations/host-metrics/)Send host metrics to Honeybadger Insights [Log files](/guides/insights/integrations/log-files/)Use Vector to ship your log files to Honeybadger Insights [Netlify](/guides/insights/integrations/netlify/)Send Netlify function logs to Honeybadger Insights [Rsyslog](/guides/insights/integrations/rsyslog/)Forward rsyslog messages to Honeybadger Insights over syslog-TLS [Systemd (journald)](/guides/insights/integrations/systemd/)Ship systemd journal logs to Honeybadger Insights # Alarms guide > Learn how to create Honeybadger alarms to monitor your Insights data in real time. Insights alarms allow you to monitor your data in real time and get notified under the conditions you set. Your Honeybadger data, such as errors, deployments, and uptime checks, are already available to query. To learn how to send your own custom data to Honeybadger, see the [Getting started guide](/guides/insights/). Then, you can create alarms for anything your business needs. ![Alarms dashboard](/_astro/alarms-overview.Ceggcxr9_g1jfW.webp) ## Viewing an alarm [Section titled “Viewing an alarm”](#viewing-an-alarm) Alarms combine a [BadgerQL](/guides/insights/badgerql/) query (“count all slow requests in the past five minutes”) with a threshold (“when count is > 2”) and trigger alerts when the query result exceeds the threshold. ![Alarms chart](/_astro/alarms-chart.Kudz72Aq_Z1X0J13.webp) In the above chart, the red line is the threshold for the alarm state. This query was in an alarm state for one period in the last hour but recently recovered. ## Creating or updating an alarm [Section titled “Creating or updating an alarm”](#creating-or-updating-an-alarm) ### Query and timing [Section titled “Query and timing”](#query-and-timing) Construct a `query` using [BadgerQL](/guides/insights/badgerql/) to return data you wish to monitor. You may want to use a `filter` function to isolate the relevant data. ![Alarms query](/_astro/alarms-query.Coj32v_v_1WumSn.webp) Use the `interval` field to specify the time window for the query. The `interval` field is a string that represents the time window for the query. The format is `1d`, `1h`, `1m`, etc. In other words, the `interval` is both the frequency and the time period over which the query is executed. The `lag` field can be used to delay the query execution by a specified time period. The `lag` field is also a string that represents the time delay for the query. The format is `1d`, `1h`, `1m`, etc. This is useful when you want to wait for slow or late data arriving. ![Alarms timing](/_astro/alarms-timing.Cel4pwrt_ZwbKhl.webp) ### Result count [Section titled “Result count”](#result-count) Alarms are triggered based on the number of results returned by the query. You can specify the logical comparison operator (`>`, `>=`, `<`, `<=`, `==`, `!=`) and a value count. The alarm will trigger when the number of results meets the condition. ![Alarms result count](/_astro/alarms-result-count.CV4PeM8T_Z2poEvs.webp) ### Description [Section titled “Description”](#description) It may be helpful to provide a description of the alarm to help you remember its purpose. The description is also delivered as part of the notification when you have integrations setup. Some useful information would be what the alarm is monitoring, what to do when the alarm triggers, and who to contact. ## Integrations [Section titled “Integrations”](#integrations) Integrations is where you can configured how to be notified when an alarm changes state. There are two states per integration that can be configured: `ok` and `alert`. All users can update their personal notification integrations (email, etc.), while users with administrator access to the project can manage the alert settings for all of the project’s integrations. ![Alarms integrations](/_astro/alarms-integrations.CyaPev7k_9pldr.webp) # Archive destinations > Replicate Honeybadger Insights stream data to an S3-compatible bucket you own. Archive destinations replicate the events flowing into your Honeybadger [Insights streams](/guides/insights/#streams) to an S3-compatible bucket that you own and control. Once a destination is configured and a stream is attached, Honeybadger writes a continuous archive of that stream’s events into your bucket. This is useful for long-term retention beyond your Insights data window or for feeding events into your own data warehouse or lake. ![Archive destinations overview](/_astro/archive-destinations-overview.DF_cgEQy_28WJf5.webp) ## What gets archived [Section titled “What gets archived”](#what-gets-archived) Only the events that flow through your Insights streams are replicated: * The custom events your application sends to Insights via the [Events API](/api/reporting-events/) or a Honeybadger client library. * The internal events Honeybadger generates for your project — error notifications, deployments, uptime checks, check-in reports, and so on. Detailed error data such as backtraces, breadcrumbs, and environment variables is **not** included. Archive destinations replicate distilled stream events, not full error payloads. You choose which streams replicate to which destination, so you can archive just your application events, just the internal Honeybadger events, or both. ## Supported providers [Section titled “Supported providers”](#supported-providers) You can point a destination at any of these S3-compatible providers: * Amazon S3 * Cloudflare R2 * Google Cloud Storage (S3-compatible interop endpoint) * Wasabi * Backblaze B2 * DigitalOcean Spaces The endpoint must use HTTPS. AWS S3 buckets are detected from the bucket name and don’t require an endpoint URL — for the others, set the provider’s S3-compatible endpoint URL on the destination. ## Setting up a destination [Section titled “Setting up a destination”](#setting-up-a-destination) Archive destinations are managed at the account level under **Account Settings → Archive Destinations**. ### 1. Create the bucket [Section titled “1. Create the bucket”](#1-create-the-bucket) Create a bucket on your provider of choice. A fresh bucket dedicated to Honeybadger archives is the simplest setup, but you can also add archives to an existing bucket by configuring a prefix on the destination. ### 2. Create credentials [Section titled “2. Create credentials”](#2-create-credentials) Create an access key and secret with permission to write to that bucket. The archiver only needs to upload objects — at minimum: * `s3:PutObject` on the bucket (scoped to your prefix is fine) No read, list, or delete permissions are required. We recommend creating a dedicated IAM user (or equivalent on your provider) scoped to just the archive bucket so the credentials you give Honeybadger can’t reach anything else. For example, on AWS S3 a minimal policy looks like: ```json { "Version": "2012-10-17", "Statement": [ { "Effect": "Allow", "Action": "s3:PutObject", "Resource": "arn:aws:s3:::your-bucket-name/*" } ] } ``` If you scope to a prefix, change the resource to `arn:aws:s3:::your-bucket-name/your-prefix/*`. Objects are uploaded with AES-256 server-side encryption (SSE-S3) by default. If your bucket policy enforces a specific encryption type, make sure SSE-S3 is allowed. ### 3. Add the destination in Honeybadger [Section titled “3. Add the destination in Honeybadger”](#3-add-the-destination-in-honeybadger) In **Account Settings → Archive Destinations**, click **New destination** and fill in: * **Name** — a short label that’s unique within your account. * **S3 bucket** — the bucket name. * **Prefix** *(optional)* — a key prefix that all archived objects will be written under. Useful if the bucket is shared with other data. * **Region** *(optional, required for AWS S3)* — e.g. `us-west-2`. * **Endpoint URL** *(optional)* — leave blank for AWS S3. Set this to the provider’s S3-compatible endpoint for R2, GCS, Wasabi, Backblaze, or DigitalOcean Spaces. * **Access key ID** and **Secret access key** — the credentials from step 2. Credentials are encrypted at rest. When editing an existing destination, leave the credential fields blank to keep the stored values; fill them in to rotate. ### 4. Attach streams [Section titled “4. Attach streams”](#4-attach-streams) A destination with no streams attached is **paused** — nothing replicates until you select at least one stream. On the destination form, pick the streams you want to replicate. Each stream can only be attached to one destination at a time. Streams start replicating on the next archive cycle. There’s no backfill — only events ingested after a stream is attached will land in your bucket. ## File structure [Section titled “File structure”](#file-structure) Objects are gzip-compressed JSON Lines (one event per line, served with `Content-Type: application/jsonl`). The key layout is: ```plaintext [prefix/]insights/{stream_id}/{YYYY}/{MM}/{DD}/{HH}/{unix_timestamp}_{random_hex}.jsonl.gz ``` For example, with prefix `honeybadger`: ```plaintext honeybadger/insights/abc123/2026/04/30/14/1714485612_a3f80c1d4e2b9876.jsonl.gz ``` The path components: * `prefix/` — the optional prefix you configured on the destination. * `insights/{stream_id}/` — fixed prefix plus the stream ID. * `{YYYY}/{MM}/{DD}/{HH}/` — UTC ingestion hour the events fell into. This is based on when the events were received by Honeybadger, not when the file was written, so a delayed write still lands in the hour it logically belongs to. * `{unix_timestamp}_{random_hex}.jsonl.gz` — a unique object name within the hour. Each object decompresses to JSON Lines: one JSON object per line, one event per line. ## Object frequency [Section titled “Object frequency”](#object-frequency) Honeybadger periodically writes new objects into your bucket for each active stream. The exact cadence isn’t guaranteed and may vary over time, so the important model to keep in mind is: > Concatenating every object under a stream’s prefix gives you that stream’s full event history. No single object contains all of a stream’s events — each object is a fragment. To reconstruct events for a time range, list every object under `insights/{stream_id}/{YYYY}/{MM}/{DD}/{HH}/` for the hours you care about and concatenate their decompressed contents. Tools like AWS Athena, DuckDB, ClickHouse, and most data warehouses can read directories of gzipped JSON Lines files directly without needing to merge them yourself. ## Status, pauses, and errors [Section titled “Status, pauses, and errors”](#status-pauses-and-errors) Each destination is in one of three states: * **Active** — at least one stream is attached and writes are succeeding. * **Paused** — the destination is configured but no streams are attached. Attach a stream to start. * **Errored** — Honeybadger has stopped writing to the bucket. Events for attached streams are dropped until you fix the destination and reactivate it. Honeybadger transparently handles short-term failures on the bucket’s side — we retry and buffer events through network blips, timeouts, and brief outages, so most disruptions recover without you noticing. If a destination keeps failing or hits a problem we can’t recover from on our own (invalid credentials, a missing bucket, a permission change), we move it to the **errored** state and email the account owner with the details. The destination card shows the last error message and when it occurred. To recover, fix the underlying issue and either save the destination with corrected credentials — a successful save reactivates it automatically — or click **Reactivate** if only a transient issue needed clearing. If the underlying problem isn’t actually fixed, the next archive write will flip the destination back to errored. ## Deleting a destination [Section titled “Deleting a destination”](#deleting-a-destination) Deleting a destination immediately stops new writes for any attached streams. Objects that have already been written to your bucket are **not** deleted — they’re yours, and Honeybadger never reads or removes them after upload. If you want to fully clean up, delete the bucket (or the objects under your prefix) yourself once you no longer need the archived data. # BadgerQL guide > Learn how to use BadgerQL to query your log events and observability data in Honeybadger Insights. BadgerQL is the language you use to interact with your data stored in Insights. It was designed to enable you to enrich, shape, and combine your events so you can craft any view of your data. Quick reference docs are also available in the application via the book icon in the top-right corner of the query box. ![Insights docs in Honeybadger](/_astro/insights-docs.DB5xdWpN_1i9gYG.webp) We also provide inline hints in the query editor that show info from the quick reference docs as you type: ![BadgerSense documentation tips](/_astro/docs-hints.Bb79VjY2_ipobM.webp) Need a hand crafting BadgerQL queries? The natural language query translator can [translate plain-English descriptions](/guides/insights/#natural-language-queries) into queries, visualizations, and time ranges. ## Example queries and use cases [Section titled “Example queries and use cases”](#example-queries-and-use-cases) Find N+1 queries in your Rails app: ```badgerql filter event_type::str == "sql.active_record" | stats count() as queryCt, sum(duration::float) by request_id::str, query::str | sort queryCt desc ``` ![N+1 query results](/_astro/n-plus-one.FcYjRYp__U3DiB.webp) What events are consuming my Insights quota? Be sure to deselect the [Internal Stream](/guides/insights/#streams) so you only see the data you are sending: ```badgerql stats sum(@size) as size by event_type::str | sort size | only toHumanString(size, "bytes"), event_type ``` ![Quota consumption query results](/_astro/quota-consumption.O4Ts2sZL_23HCT7.webp) See more examples in the [walk-through](/guides/insights/#walk-through) or review the full BadgerQL reference below for more information. ## Parameterized queries [Section titled “Parameterized queries”](#parameterized-queries) Parameterized queries let you swap values into a query at runtime without editing the query itself. You can filter a dashboard to a single host, environment, or customer; share a prefilled URL with a teammate; or reuse the same widget across multiple contexts. Parameters work anywhere you write BadgerQL, including dashboard widgets and the Insights query editor. Use `${name}` to reference a parameter in a query: ```badgerql filter hostname::str == "${hostname}" ``` Provide a default with `${name:-default}`: ```badgerql filter env::str == "${env:-production}" ``` Parameter names must start with a letter or underscore, followed by letters, numbers, or underscores. Parameter values can be provided in the URL (e.g., `?hostname=web-01`), allowing you to share query URLs with prefilled values, or by clicking the parameters button (the slider icon in the dashboard toolbar, next to the date picker) to open a popover with a field for each parameter used in the query. ## Functions to enrich, shape, and combine data [Section titled “Functions to enrich, shape, and combine data”](#functions-to-enrich-shape-and-combine-data) Functions are the core of BadgerQL. You can think of your data falling or piping through each function that you specify, getting filtered, aggregated, and so on along the way. The most common functions you will use are [`fields`](#fields) to select fields to view, [`filter`](#filter) to restrict what data appears in the results, and [`stats`](#stats) to do counts, averages, and other analyses. Keep reading to learn about all the functions we offer. ### Combining functions [Section titled “Combining functions”](#combining-functions) While calling a BadgerQL function on its own can produce interesting results, the real power comes when piping functions together via the pipe (`|`) operator: ```badgerql fields status_code::int, controller::str | filter startsWith(controller, "Stripe") | stats count() by status_code ``` Each function builds off the other to create a result showing the distribution of status codes just for Stripe controller requests. Note that BadgerQL does not work like SQL. Each successive function is applied to the result of the previous, so you can only reference fields down the pipeline. For example, if you want to convert a string to a number gathered from a `parse` function, you can pipe into another `fields` function: ```badgerql parse url::str /id=(?\d+)/ | fields toInt(id) as id ``` ### Expand [Section titled “Expand”](#expand) You can use `expand` to turn an event that has a field with array data into multiple events. ```badgerql expand array_field [as alias][, ...] ``` With data that has a single event like `{"id": 1, "charges": [700, 430, 200]}`, the following query will return three events, with `id` and `charge` fields: ```badgerql expand charges[*]::int as charge ``` See the [Arrays](#arrays) section for more detail on working with array data. ### Fill [Section titled “Fill”](#fill) Use `fill` to inject events for missing data points. ```badgerql fill field_expression [as alias] [asc|desc|up|down] [from ...] [to ...] [step ...] [across field [bounded | including [...]]]* [with field[ = expression][, ...]*] ``` Unless specified with `from` or `to`, `fill` will determine the min and max values of the `field_expression`, sort, and produce new events with missing `field_expression` values replaced by the incremented or decremented step value. `field_expression` only allows for `number` or `temporal` types. The resulting optional clause types differ based on the resolved type: ```badgerql fill number [from number] [to number] [step number] fill temporal [from temporal] [to temporal] [step interval] ``` Fill works best when referencing an already existing field. Since fill inserts data at a regular interval, you will also get the best results if the field follows the step size of the fill. #### Typical usage [Section titled “Typical usage”](#typical-usage) Take a `stats` call that bins the count of events per hour: ```badgerql stats count() as ct by bin(1h) as bin ``` You might get sparse results if there is not enough data to fill each bin: | ct | bin | | -- | ----------------------- | | 5 | 2023-04-05 02:00:00.000 | | 10 | 2023-04-05 04:00:00.000 | | 2 | 2023-04-05 06:00:00.000 | With the `fill` function (the step is inferred from `bin()`, so a bare `fill bin` is enough): ```badgerql stats count() as ct by bin(1h) as bin | fill bin ``` You can produce a full binned result set: | ct | bin | | -- | ----------------------- | | 5 | 2023-04-05 02:00:00.000 | | 0 | 2023-04-05 03:00:00.000 | | 10 | 2023-04-05 04:00:00.000 | | 0 | 2023-04-05 05:00:00.000 | | 2 | 2023-04-05 06:00:00.000 | #### Automatic step from `bin()` and `bucket()` [Section titled “Automatic step from bin() and bucket()”](#automatic-step-from-bin-and-bucket) If the fill field comes from a `bin()` or `bucket()`, you don’t need to repeat the step. `fill` picks it up automatically. `bin(1h)` gives you a 1-hour step, `bucket(x, 100)` gives you a 100-wide step, and the bounded form `bucket(x, 0, 1000, 20)` gives you from, to, and step all at once. You can still pass an explicit `step`, `from`, or `to` to override. ```badgerql stats count() as ct by bucket(duration::int, 0, 2000, 20) as ms | fill ms | sort ms asc ``` The bucket width is `2000 / 20 = 100`, so `fill` inserts a row for every 100-wide slot that had no matching events: | ct | ms | | -- | --- | | 12 | 0 | | 0 | 100 | | 0 | 200 | | 45 | 300 | | 30 | 400 | | 0 | 500 | | … | … | #### Filling across dimensions [Section titled “Filling across dimensions”](#filling-across-dimensions) Add `across ` to fill every combination of the fill field and a grouping dimension. This is useful for stacked charts, heatmaps, or any per-category series where you want explicit zeros instead of missing rows. ```badgerql stats count() as count by bin(1h) as t, status::str | fill t across status ``` Every combination of time bin and status gets a row, with 0 for missing cells: | count | t | status | | ----- | ----------------------- | ------ | | 8 | 2023-04-05 02:00:00.000 | 200 | | 0 | 2023-04-05 02:00:00.000 | 500 | | 0 | 2023-04-05 03:00:00.000 | 200 | | 3 | 2023-04-05 03:00:00.000 | 500 | You can chain multiple `across` clauses: ```badgerql stats count() as count by bin(1h) as t, status::str, region::str | fill t across status across region ``` Counting aggregates (`count`, `sum`, `unique` and their `*If` variants) default to 0 on filled cells. Everything else defaults to null. Use `with field = value` to pick a different default. ##### `bounded` [Section titled “bounded”](#bounded) Without `bounded`, `across` fills every category across the entire range of the fill field. Say `temp` reported from 02:00–04:00 and `humidity` only reported at 05:00. Plain `across` would create rows for both sensors across the full 02:00–05:00 range. `across field bounded` limits each category to its own observed range instead: ```badgerql stats count() as count by bin(1h) as t, sensor::str | fill t across sensor bounded ``` | count | t | sensor | | ----- | ----------------------- | -------- | | 5 | 2023-04-05 02:00:00.000 | temp | | 0 | 2023-04-05 03:00:00.000 | temp | | 3 | 2023-04-05 04:00:00.000 | temp | | 7 | 2023-04-05 05:00:00.000 | humidity | No rows for `humidity` at 02:00–04:00, and no rows for `temp` at 05:00. You can’t combine `bounded` with `including` on the same dimension, or with explicit `from`/`to`. ##### `including` [Section titled “including”](#including) `across field including [...]` ensures specific values show up in the result even if they’re missing from the data. The pinned values are added on top of whatever the query discovers, so you won’t lose any existing categories. All values in the array must be the same type. ```badgerql stats count() as count by bin(1h) as t, op::str | fill t across op including ["create", "delete"] ``` The `"create"` and `"delete"` values appear even if the data only contains `"update"` events: | count | t | op | | ----- | ----------------------- | ------ | | 0 | 2023-04-05 02:00:00.000 | create | | 0 | 2023-04-05 02:00:00.000 | delete | | 4 | 2023-04-05 02:00:00.000 | update | | 1 | 2023-04-05 03:00:00.000 | create | | 0 | 2023-04-05 03:00:00.000 | delete | | 0 | 2023-04-05 03:00:00.000 | update | This is also useful for keeping chart legends stable. If a category has zero events across the entire query range, `across` alone won’t include it. `including` pins those categories into the result so they always appear. Note `across` does not support fill direction (`up`/`down`) or carry-forward `with field`. Use `with field = value` instead. #### Fill order [Section titled “Fill order”](#fill-order) By default, the fill function sorts the `field_expression` in ascending order before injecting fill events. You can change this by providing an order direction after the `field_expression`: ```badgerql fill @ts desc step -1h ``` When filling in descending order, `from` must be greater than `to` and `step` must be a negative value. #### `@fill` internal field [Section titled “@fill internal field”](#fill-internal-field) Filled events have an additional internal `@fill` field added to the results. You can use this field to determine when an event is filled: ```badgerql fields @fill | fill duration::int from 100 to 500 step 100 ``` | @fill | duration | | ----- | -------- | | true | 200 | | true | 300 | | | 325 | | true | 400 | #### Filling other fields [Section titled “Filling other fields”](#filling-other-fields) Most fields other than `field_expression` will be filled with a null value for injected events. You can control what data is replaced using the `with` clause. Setting the `with` field to the `field_expression` will result in an error. If `with` is given only a field, it will carry over the field value from the previous event: ```badgerql fields @fill, controller::str | fill duration to 340 step 10 with controller ``` | @fill | duration | controller | | ----- | -------- | ---------- | | | 300 | login | | true | 310 | login | | | 320 | sign-up | | true | 330 | sign-up | `with` fields can also be set to specific values for filled events: ```badgerql stats avg(temp::float) as avgTemp by bin(1d) as bin | fill bin step 1d with avgTemp = 65.0 ``` | avgTemp | bin | | ------- | ---------- | | 73.3 | 2023-04-08 | | 65.0 | 2023-04-09 | | 68.9 | 2023-04-10 | | 65.0 | 2023-04-11 | Referencing other fields from previous events is also possible, acting like a `LAST_VALUE()` window function. #### Notes [Section titled “Notes”](#notes) * Having multiple fills is possible by piping together `fill` functions, but take care to ensure you are not injecting too many events. * `from` and `to` values are not inclusive when producing injected results. ### Fields [Section titled “Fields”](#fields) The `fields` function enriches your results by adding extra fields. Any fields that you select or alias can be referenced in later functions, and they will be returned in the final dataset unless rewritten by later functions. ```badgerql fields expr [as alias][, ...]* ``` Fields can be aliased with the `as` clause, and unsupported characters (like spaces) can be used by using backticks. ```badgerql fields user_name::str as `User name` ``` Aliased fields can be used in later functions: ```badgerql fields concat(first_name::str, " ", last_name::str) as full_name | filter full_name match /^Bob.*/ ``` #### Internal fields [Section titled “Internal fields”](#internal-fields) We set the following internal fields for you as the data is ingested: | Name | Type | Description | | ----------------- | ------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ | | `@id` | `String` | The event ID | | `@ts` | `DateTime` | The reported timestamp if provided as `ts` or `timestamp`; otherwise, the time when the event was received | | `@received_ts` | `DateTime` | The time when the event was received | | `@stream.id` | `String` | The ID of the stream that contains the event. Each project contains at least two streams: the internal Honeybadger stream used for notices, etc., and the stream used for storing events that you send to our API. | | `@stream.name` | `String` | The name of the stream | | `@query.start_at` | `DateTime` | The timestamp of start of the range queried. E.g., when searching back 3 hours (the default), this will be three hours ago | | `@query.end_at` | `DateTime` | The timestamp of end of the range queried. E.g., for the default query, this would be the time when the query was executed, since the default query searches for data up to the time the query was sent. | | `@size` | `Integer` | The size in bytes of the event | | `@fill` | `Boolean` | Whether the result has filled-in values | | `@preview` | `JSON Object` | A preview of the data stored for the event | ### Filter [Section titled “Filter”](#filter) Filter expects a body that results in a boolean expression, and it will exclude events where the expression returns false. ```badgerql filter boolean_expr [and|or ...]* ``` Multiple piped filter functions will act as AND operations. ```badgerql filter controller_name::str == "StripeController" and duration::float > 2000 | filter action_name::str == "hook" ``` ### Limit [Section titled “Limit”](#limit) Limit the number of results returned by the query. ```badgerql limit integer [by expr[, ...]*] ``` Caution Limiting can adversely affect piped function results. For example, adding a `limit` before a `stats` call will only gather stats on the limited events: ```badgerql limit 10 | stats count() by controller::str ``` If you want to restrict the number of returned results, make sure `limit` is at the end of your pipeline: ```badgerql stats count() by controller::str | limit 10 ``` Include a `by` clause to limit the number of results per group. ```badgerql limit 10 by user_id::int ``` Pipe into `limit` to restrict the final number of results returned by the query. ```badgerql limit 5 by user_id::int | limit 100 ``` ### Only [Section titled “Only”](#only) Use `only` to restrict which fields are rendered in the results and in which order they will appear. ```badgerql only expr [as alias][, ...]* ``` For example, if you want to filter on a particular field, but you don’t want that field to appear in the results, you can use `only` to select the fields you want to see: ```badgerql fields a, b, c | filter c > 2 | only b, a ``` ### Parse [Section titled “Parse”](#parse) Extract fields using regular expressions ```badgerql parse expr /regex/ ``` If your events have data that can be extracted using regular expressions, you can create fields from that data. The following example will extract “redis” from an event that has a field named “addon” that contains the value “redis-fitted-71581” and place it in a new field called “service”. Both the “addon” and “service” fields will appear in the results. ```badgerql fields addon::str | parse addon /(?[[:alpha:]]+)/ ``` ### Sort [Section titled “Sort”](#sort) Order events based on fields. ```badgerql sort expr [desc|asc][, ...]* ``` Queries without an explicit sort are unordered and non-deterministic. Sort direction can be either `desc` (descending) or `asc` (ascending). By default, fields are sorted in descending order if not specified. ```badgerql sort day desc, duration asc ``` Sort is useful to order results by time, or when calculating stats: ```badgerql fields email | filter action::str == "Logged in" | stats count() as count by email | sort count ``` It can make sense to call `sort` multiple times, as sorting after rewriting functions might be necessary. ### Stats [Section titled “Stats”](#stats) Aggregate event fields ```badgerql stats agg_expr[, ...]* by [expr][, ...]* ``` The workhorse of Insights, `stats` allows you to perform calculations on your data. You can count events, calculate averages, and more. ```badgerql stats avg(response_time::float) ``` Note Results from `stats` are unsorted by default, even if the events piped into `stats` are sorted. Pipe into `sort` if order matters. #### Aggregation [Section titled “Aggregation”](#aggregation) Available aggregate functions: | Function | Description | | ------------------------------- | ---------------------------------------------------------------------------------------- | | `count()` | Returns the total count of all results. Can contain an expression that filters the count | | `avg(field)` | Calculates the average (mean) value for a numeric field | | `min(field)`, `max(field)` | Returns the minimum/maximum value for the given field | | `sum(field)` | Calculates the sum of values for a numeric field | | `percentile(percentage, field)` | Returns the value at the specified percentile for the given numeric field | | `unique(field)` | Returns the number of unique values for the specified field | | `first(field)`, `last(field)` | Returns the first/last value of the specified field for the whole aggregate | | `apdex(field, threshold)` | Calculates an Apdex (Application Performance Index) score between 0 and 1 | Find the number of 500 errors over a time period: ```badgerql filter status_code::int == 500 | stats count() ``` Find the average response time for a specific endpoint: ```badgerql filter endpoint::str == "/api/v1/orders" | stats avg(duration::float) ``` Combine multiple aggregate functions in a single query: ```badgerql filter environment::str in ["production", "staging"] | stats count(), percentile(95, duration::float) ``` #### Grouping [Section titled “Grouping”](#grouping) The `by` clause allows you to group the results by one or more fields. ```badgerql stats avg(response_time::float) by location::str ``` One of the most common use cases for grouping is to create a time series by grouping with `bin()`. #### The `bin()` function [Section titled “The bin() function”](#the-bin-function) `bin()` rounds a datetime down to the nearest interval boundary, which lets you group events into time buckets (e.g., “all events in this 1-hour window”). ```plaintext bin([interval[, datetime]]) ``` Both arguments are optional: * **`interval`** — the bucket size, written using interval syntax (e.g. `1h`, `30m`, `2d`). If omitted, `bin()` automatically picks a reasonable size based on your selected time range. * **`datetime`** — the field to bin. Defaults to `@ts`. Use this when you want to bin on a field other than the event timestamp. ```badgerql stats count() by bin(1h) as time ``` ```badgerql stats count() by bin(1h, toDateTime(user.created_at::str)) as time ``` When no alias is given, the result column is named after the call itself (e.g. `bin(1h)`). Always alias `bin()` when you need to reference it in a later function like `sort` or `fill`. **Interval syntax** — an integer followed by a unit abbreviation: | Unit | Abbreviation | Example | | ------- | ------------ | ------- | | Seconds | `s` | `30s` | | Minutes | `m` | `15m` | | Hours | `h` | `1h` | | Days | `d` | `7d` | | Weeks | `w` | `1w` | | Months | `mon` | `1mon` | **Auto-sizing** — when `bin()` is called with no interval argument, the bin size is automatically chosen to produce a reasonable number of buckets for your selected time range. ```badgerql stats count() by bin() as time, status_code::int ``` You can use any field or expression in the `by` clause: ```badgerql stats avg(duration::float), max(duration::float) by bin() as time, concat(controller::str, "#", action::str) as controllerAction ``` ### Unique [Section titled “Unique”](#unique) The `unique` function filters out duplicate events based on the field(s) you specify. ```badgerql unique field[, ...] ``` ### Toggling functions [Section titled “Toggling functions”](#toggling-functions) **Hotkey: `CTRL + /`** When exploring data in BadgerQL, you might find it useful to temporarily ignore certain functions while keeping them in the query. To do this, add a bang (`!`) at the beginning of the BadgerQL function. This comments out the function, effectively ignoring it without removing it from the query. This is particularly useful for toggling conditions in statistical analyses. For example, you might want to alternate between including and excluding certain filters: ```badgerql fields event_type::str, duration::int | filter event_type == "page_view" | !filter duration > 100 | stats count() by bin(1d) ``` Note that if a function spans multiple lines, placing a bang (`!`) at the beginning will toggle the entire function, not just the first line: ```badgerql fields event_type::str, duration::int | filter event_type == "page_view" | !filter duration > 100 and duration < 200 | stats count() by bin(1d) ``` ## Types [Section titled “Types”](#types) In Insights, data is stored and accessed in its typed format. BadgerQL is a strongly typed language, which means it is particular about type consistency. We currently support storing data with these types: | Short | Long | | ------- | ------- | | `str` | String | | `bool` | Boolean | | `float` | Float | | `int` | Integer | ### Type hinting [Section titled “Type hinting”](#type-hinting) Type hinting is key in BadgerQL. You indicate the expected field type using `::` and the short type name. For example, if you know you are sending status codes as integers, you must augment your query to point to the field like: ```badgerql fields status_code::int ``` This only gives the system a hint for where to look for the event field. It does not coerce the value into another type. If you want to convert types, use one of the [conversion expression functions](#conversion). It’s not required to repeat type hints. If you use a field with a type hint earlier, it carries over: ```badgerql fields status_code::int | stats count() by status_code ``` Conflicting type hints or inaccurate hints can result in null values or errors. We also support using these types (either through conversion or as a function result) in queries: | Short | Long | | ------------ | ----------------------------------- | | `datetime` | Datetime | | `date` | Date | | `tzdatetime` | Datetime with timezone | | `interval` | Relative time intervals (e.g. `1h`) | **Note:** you can’t hint these types, as we don’t store data in these formats. ### Union types [Section titled “Union types”](#union-types) You may see `number` and `temporal` appear in function signatures throughout the docs. These are not types you can use directly in queries; they are shorthand for describing which concrete types a function accepts. `number` means the function works with either `int` or `float`, and `temporal` means it works with either `date` or `datetime`. ### Literal values [Section titled “Literal values”](#literal-values) Some function arguments don’t accept field references, only literals (e.g., `1.5`, `"hi"`). This is denoted in the type signature. For instance, `round(duration::float, 0)` is valid with the second argument as a literal integer. `round(duration::float, precision::int)` would produce an error. ## Dates [Section titled “Dates”](#dates) ### Creating dates [Section titled “Creating dates”](#creating-dates) We provide a shorthand for creating datetime literal values by wrapping the date in curly brackets `{}`: ```badgerql fields {2023-01-01} as baseDate ``` ### Casting dates [Section titled “Casting dates”](#casting-dates) There is no way to store native dates in Insights, so if you want to interact with a native `date` or `datetime`, you will need to cast a string column to one of the temporal types: ```badgerql fields toDateTime(created_at::str) as created_at | filter created_at > {2023-04-08 12:00:00} ``` ### Timezones [Section titled “Timezones”](#timezones) All datetimes are returned in your selected timezone by default. This means that if you input a datetime, it will be automatically converted to match your preferred timezone setting. To adjust datetimes to a specific timezone for a query, use the `toTimezone` function: ```badgerql fields toTimezone(@ts, "America/Los_Angeles") ``` This will show the timestamp in PST, which will be denoted in the timezone information contained within the field type (`tzdatetime.PST` for this example). ## Arrays [Section titled “Arrays”](#arrays) Insights is primarily designed to work with simple key/value data mappings, however, it does support ingesting and querying array data in your events. To access fields within an array, use bracket notation to specify an index. For example, `user.scopes[0].name::str` is a valid path into your event data. ### Expand function [Section titled “Expand function”](#expand-function) The most flexible tool for working with arrays is the `expand` BadgerQL function. `expand` unwraps array data into individual events, which you can then pipe into any other function. For example, given events containing this data: ```json {"id": 1, "charges": [700, 430, 200]} {"id": 2, "charges": [100]} ``` You can expand the charges field using wildcard notation: ```badgerql expand charges[*]::int as charge ``` This will expand each result to: | id | charge | | -- | ------ | | 1 | 700 | | 1 | 430 | | 1 | 200 | | 2 | 100 | **Note:** Just like looking up a field, the path must reference a set of values. You can’t expand into an object or another array. You can then use `stats` to group events back together after processing: ```badgerql expand charges[*]::int as charge | filter charge > 200 | stats sum(charge) as total_cost by id ``` Which will combine the filtered events back with summed charges: | id | total\_cost | | -- | ----------- | | 1 | 1130 | ### Conditional array matching [Section titled “Conditional array matching”](#conditional-array-matching) Sometimes you want to know if a value within an array passes some condition. We have [special expression functions](#arrays) just for this case. For example, to find events with a specific tag: ```badgerql filter any(tags[*]::str == "funky") ``` The `any` function also works with nested object data within an array: ```badgerql filter any(events[*].user.email::str like "kwebster%") ``` ### Performance implications [Section titled “Performance implications”](#performance-implications) Array support is limited in terms of performance optimizations. Where possible, consider flattening array data into separate events before sending them to Honeybadger. ## Expression functions [Section titled “Expression functions”](#expression-functions) Expression functions can be used in a variety of places, such as filtering data, creating fields, calculating aggregates, etc. They are used to compare fields, perform arithmetic, reformat data, and more. ### Comparison [Section titled “Comparison”](#comparison) The comparison operators work across `number`, `string`, `boolean`, and `datetime` types. `!=` and `<>` are equivalent operators. `between` and `not between` are inclusive on both ends: ```badgerql filter status_code::int between 200 and 299 ``` `either` returns the first non-null value from its arguments — useful as a fallback when a field may be stored under different names: ```badgerql fields either(name::str, full_name::str, username::str) as name ``` * `!=` Inequality comparison. Also written `<>`. Signature`t = number | string | boolean | datetime``t != t -> boolean` Example ```sql fields status_code::int != 200 ``` * `<` Signature`t = number | string | boolean | datetime``t < t -> boolean` Example ```sql fields status_code::int < 500 ``` * `<=` Signature`t = number | string | boolean | datetime``t <= t -> boolean` Example ```sql fields status_code::int <= 200 ``` * `<>` Inequality comparison. Also written `!=`. Signature`t = number | string | boolean | datetime``t <> t -> boolean` Example ```sql fields status_code::int <> 200 ``` * `==` Signature`t = number | number[] | string | string[] | boolean | boolean[] | datetime | datetime[]``t == t -> boolean` Example ```sql fields status_code::int == 200 ``` * `>` Signature`t = number | string | boolean | datetime``t > t -> boolean` Example ```sql fields status_code::int > 500 ``` * `>=` Signature`t = number | string | boolean | datetime``t >= t -> boolean` Example ```sql fields status_code::int >= 200 ``` * `between` Signature`t = number | string | datetime``t between t and t -> boolean` Example ```sql filter status_code::int between 200 and 300 ``` * `coalesce` Returns the first non-null value. Synonym of `either`. Signature`t = integer | float | string | boolean | datetime``coalesce(t, ...t) -> t` Example ```sql fields coalesce(name::str, full_name::str, username::str) as name ``` * `either` Returns the first non-null value. Also accepts `coalesce`. Signature`t = integer | float | string | boolean | datetime``either(t, ...t) -> t` Example ```sql fields either(name::str, full_name::str, username::str) as name ``` * `ilike` Returns true when the search string matches Can use these metacharacters: `%` - Matches an arbitrary amount of characters `_` - Matches single arbitrary character The matcher is case insensitive Signature`string ilike string -> boolean` Example ```sql filter email::str ilike "%compuserve%" ``` * `in` Return true if field value is contained within the array of literal values. The field type must match value type in the array. Signature`t = number | string | datetime``t in t[] -> boolean` Example ```sql filter status_code::int in [300, 301, 404] ``` * `isNotNull` Signature`t = number | string | boolean | datetime``isNotNull(t) -> boolean` Example ```sql filter isNotNull(status_code::int) ``` * `isNull` Signature`t = number | string | boolean | datetime``isNull(t) -> boolean` * `like` Returns true when the search string matches Can use these metacharacters: `%` - Matches an arbitrary amount of characters `_` - Matches single arbitrary character The string matcher is case sensitive Signature`string like string -> boolean` Example ```sql filter email::str like "%compuserve%" ``` * `match` Returns true when the regex matches The regex uses [re2 regex syntax](https://github.com/google/re2/wiki/Syntax) Signature`string match regex -> boolean` Example ```sql filter email::str match /.*compuserve.*/ ``` * `not between` Signature`t = number | string | datetime``t not between t and t -> boolean` Example ```sql filter status_code::int not between 300 and 400 ``` * `not ilike` Returns true when the search string does not match Can use these metacharacters: `%` - Matches an arbitrary amount of characters `_` - Matches single arbitrary character The matcher is case insensitive Signature`string not ilike string -> boolean` Example ```sql filter email::str not ilike "%compuserve%" ``` * `not in` Return true if field value is not contained within the array of literal values. The field type must match value type in the array. Signature`t = number | string | datetime``t not in t[] -> boolean` Example ```sql filter status_code::int not in [300, 301, 404] ``` * `not like` Returns true when the search string does not match Can use these metacharacters: `%` - Matches an arbitrary amount of characters `_` - Matches single arbitrary character The string matcher is case sensitive Signature`string not like string -> boolean` Example ```sql filter email::str not like "%compuserve%" ``` * `not match` Returns true when the regex does not match The regex uses [re2 regex syntax](https://github.com/google/re2/wiki/Syntax) Signature`string not match regex -> boolean` Example ```sql filter email::str not match /.*compuserve.*/ ``` ### Arrays [Section titled “Arrays”](#arrays-1) * `all` Return true if the predicate is true for every element of an expanded array. Returns true on empty arrays (vacuous truth). Signature`all(boolean) -> boolean` Example ```sql filter all(tags[*]::str != "severe") ``` ```sql filter all(coupon_ids[*]::int not in [123, 456]) ``` The predicate must reference at least one expanded array (a field with `[*]`). That tells `all()` which array to iterate over. ```sql filter all(tags[*]::str != "severe") ``` ### Empty arrays `all()` returns `true` on an empty array — there are no elements to violate the predicate. This is mathematically consistent (vacuous truth) but bites people who expect "all" to imply "at least one." If you need both "non-empty" and "all match," combine `all()` with a separate `any()` check. ### Nested object data `[*]` works inside object paths, so you can require a property on every element of an array of objects: ```sql filter all(events[*].status::str == "ok") ``` ### Performance Array operations don't benefit from the same indexing that scalar fields do. If you find yourself querying array data heavily, consider sending the events with the array already unrolled. * `any` Return true if the predicate is true for at least one element of an expanded array. Returns false on empty arrays. Signature`any(boolean) -> boolean` Example ```sql filter any(tags[*]::str == "severe") ``` ```sql filter any(coupon_ids[*]::int in [123, 456]) ``` The predicate must reference at least one expanded array (a field with `[*]`). That tells `any()` which array to iterate over. ```sql filter any(tags[*]::str == "severe") ``` ### Nested object data `[*]` works inside object paths, so you can check fields on each element of an array of objects: ```sql filter any(events[*].user.email::str like "kwebster%") ``` ### Empty arrays `any()` returns `false` on an empty array — there's nothing to match. ### Comparison vs membership predicates The predicate inside `any()` can be anything that returns a boolean — equality, `in`/`not in`, `like`, range checks, or expressions on nested fields: ```sql filter any(coupon_ids[*]::int in [123, 456]) filter any(prices[*]::float > 100.0) ``` You can't drop the `any()` and write `tags[*]::str in ["severe"]` directly — `in` needs a scalar on its left, and `tags[*]::str` is an array. `any()` is what unrolls the array and feeds each element into the predicate one at a time. ### Performance Array operations don't benefit from the same indexing that scalar fields do. If you find yourself querying array data heavily, consider sending the events with the array already unrolled. ### Array [Section titled “Array”](#array) * `contains` Returns true when the array contains the value. Use for simple array membership without writing `any(arr[*] == value)`. Signature`contains(string[], string) -> boolean``contains(number[], number) -> boolean` Example ```sql filter contains(tags[*]::str, "severe") ``` * `dedupe` Removes duplicate elements from an array, keeping one copy of each value. Compose with `collect` to gather distinct values per group. Signature`t = string[] | number[] | boolean[] | datetime[]``dedupe(t) -> t` Example ```sql fields dedupe(tags[*]::str) as tags ``` ```sql stats dedupe(collect(user_id::str)) as users by error_class::str ``` * `reverse` Returns the array with its element order reversed. Signature`t = string[] | number[] | boolean[] | datetime[]``reverse(t) -> t` Example ```sql fields reverse(sort(scores[*]::int)) as descending_scores ``` * `sort` Returns the array sorted ascending. This is the array function `sort(...)`, not the pipeline stage `| sort ...`; compose with `reverse` for descending order. Signature`t = string[] | number[] | boolean[] | datetime[]``sort(t) -> t` Example ```sql fields sort(scores[*]::int) as sorted_scores ``` * `subarray` Returns `length` elements of the array starting at `start`; array positions are 1-based, so `1` is the first element. Signature`t = string[] | number[] | boolean[] | datetime[]``subarray(t, integer, integer) -> t` Example ```sql fields subarray(tags[*]::str, 1, 3) as first_three ``` ### Logic [Section titled “Logic”](#logic) `if` is single-branch conditional: if the condition is true it returns the `then` value, otherwise it returns the `else` value. The `else` arm also fires when the condition evaluates to `null`. ```badgerql fields if(status_code::int >= 500, "error", "ok") as result ``` `cond` is multi-branch: condition/value pairs are evaluated in order and the value from the first matching pair is returned. A final bare value (no preceding condition) acts as the fallback: ```badgerql fields cond( status_code::int >= 500, "red", status_code::int >= 300, "yellow", "green" ) as severity ``` * `and` Signature`boolean and boolean -> boolean` * `cond` Multiple path conditional branching The `cond()` function allows for evaluating branches (ala. `if` and `else if`) through positional arguments. Each successive pair of arguments acts as an else if, with the first true boolean passing it's result as a return." Signature`t = string | boolean | number | datetime | date``cond(boolean, t, boolean, t, ..., t) -> t` Example ```sql fields cond( status_code >= 300, "yellow", status_code >= 500, "red", "green" ) as status_code_color ``` * `if` Single path conditional branching Signature`t = string | number | boolean | temporal | interval``if(boolean, t, t) -> t` Example ```sql fields if(toDayOfWeek(ts) == 2, "taco", "slop") as food_day ``` * `not` Signature`not(boolean) -> boolean` * `or` Signature`boolean or boolean -> boolean` ### Arithmetic [Section titled “Arithmetic”](#arithmetic) The standard operators (`+`, `-`, `*`, `/`, `%`) work on numbers. A few noteworthy behaviors: * Subtracting two `datetime` values returns the difference in **seconds** as an integer: `end_ts::datetime - start_ts::datetime` * Adding an interval to a datetime shifts it forward: `@ts + 1h` * The second argument to `round`, `floor`, and `ceil` is the number of decimal places and must be a **literal integer** — you cannot pass a field reference. `round(duration::float, 2)` is valid; `round(duration::float, precision::int)` is not. - `-` Signature`number - number -> number``datetime - number -> datetime``datetime - interval -> datetime``datetime - datetime -> integer` - `*` Signature`number * number -> number` - `/` Division. Dividing by an interval converts a number of seconds — such as a datetime difference — into that unit: `(finished - started) / 1h` is hours. Signature`t = number | interval``number / t -> float` Example ```sql fields (toDateTime(finished_at::str) - toDateTime(started_at::str)) / 1h as hours ``` - `%` Signature`number % number -> number` - `+` Signature`number + number -> number``datetime + number -> datetime``datetime + interval -> datetime` - `abs` Signature`abs(number) -> number` - `bucket` Assign a numeric value to a bucket and return that bucket's start value. `bucket(value, width)` uses `width`-sized steps anchored at zero. `bucket(value, min, max, n)` divides `[min, max]` into `n` equal bucket slots; values outside that range return null. Signature`bucket(number, literal number) -> number``bucket(number, literal number, literal number, literal integer) -> number` Example ```sql stats count() as ct by bucket(duration::int, 250) as ms ``` ```sql stats count() as ct by bucket(duration::int, 0, 5000, 16) as ms ``` The width form is the numeric counterpart of `bin()` for time: `bucket(duration::int, 100)` maps `250` to `200`, the start of its 100-wide bucket. Negative values land on the same grid (`-50` maps to `-100`). The bounded form fixes the range and bucket count instead: the width is `(max - min) / n`, so `bucket(duration::int, 0, 1000, 4)` creates starts at `0`, `250`, `500`, and `750`. `100` maps to `0`, `999` maps to `750`, and a value exactly equal to `max` also maps to the last bucket. Anything outside `[min, max]` returns null; filter the range first if you do not want an out-of-range null group. ### Histograms `bucket()` only assigns rows that already exist. Group by the bucket and count, then `fill` to make empty buckets explicit. The fill grid is inferred from the bucket — its width becomes the step, and the bounded form's min/max become from/to: ```sql stats count() as ct by bucket(duration::int, 0, 2000, 20) as ms | fill ms | sort ms asc ``` ### Why explicit parameters The width (or bounds and count) are part of the query, so the bucket grid is stable — the same query yesterday and today produces comparable buckets, and outliers can't warp the ranges. - `ceil` Signature`ceil(number, literal integer) -> float` - `exp` Signature`exp(number) -> float` - `floor` Signature`floor(number, literal integer) -> float` - `intDiv` Divide two numbers and return the integer quotient. Use `/` when you want a floating-point result. Signature`intDiv(number, number) -> integer` - `log` Signature`log(number) -> float` - `log10` Signature`log10(number) -> float` - `log2` Signature`log2(number) -> float` - `pow` Signature`pow(number, number) -> float` - `round` Signature`round(number, literal integer) -> float` - `sign` Returns -1 for negative numbers, 0 for zero, and 1 for positive numbers. Signature`sign(number) -> integer` - `sqrt` Signature`sqrt(number) -> float` - `truncate` Drop digits past the given number of decimal places without rounding. This is different from `floor`, which always rounds down. Signature`truncate(number, literal integer) -> float` ### Conversion [Section titled “Conversion”](#conversion) A few things worth knowing: * `toDateTime` from a string uses best-effort parsing, so it handles a wide variety of date formats (ISO 8601, RFC 2822, etc.) without needing an exact format string. * `toUnix` returns **milliseconds** since the Unix epoch, not seconds. * `toDate` strips the time component from a datetime and returns a date-only value. - `toDate` Signature`t = string | datetime``toDate(t) -> date` - `toDateTime` Signature`t = number | date | string | temporal``toDateTime(t) -> datetime` - `toFloat` Signature`toFloat(any) -> float` - `toInt` Signature`toInt(any) -> integer` - `toString` Signature`toString(any) -> string` - `toUnix` Signature`toUnix(datetime) -> integer` ### Dates [Section titled “Dates”](#dates-1) `now()` returns the current datetime in the query’s configured timezone. `toStartOf` and `toEndOf` are lower-level alternatives to `bin()` when you need the start or end of an interval boundary rather than grouping: ```badgerql fields toStartOf(1w) as week_start ``` ```badgerql fields toEndOf(1d) as end_of_day ``` `toDayOfWeek` returns 1–7 where 1 = Monday and 7 = Sunday. See also the [Dates](#dates) section above for creating and casting date literals. * `bin` Round a datetime down to the nearest interval boundary. Most often used in `stats ... by bin(...)` to bucket events into a time series. Signature``bin(datetime = `@ts`) -> datetime````bin(interval, datetime = `@ts`) -> datetime`` Example ```sql fields bin(1w) as beginning_of_week ``` ```sql stats count() by bin(1h, toDateTime(user.created_at::str)) ``` ### Choosing the interval If you pass an interval, that's the bin size: ```sql stats count() by bin(1h) ``` If you omit the interval, `bin()` picks a size based on the query's time range — small bins for short ranges, larger bins for longer ones. The exact thresholds aren't fixed, so pass an explicit interval if you need a specific size. ### Choosing the field By default `bin()` operates on the event timestamp (`@ts`). Pass a datetime field as the second argument to bin against something else: ```sql stats count() by bin(1d, toDateTime(user.created_at::str)) ``` ### Filling gaps Bins with no matching events don't appear in the result. To produce a continuous series, pipe through `fill` — the step is inferred from the bin: ```sql stats count() by bin(1h) as t | fill t ``` * `formatDate` Render a datetime as a string using a format pattern. Defaults to the event timestamp (`@ts`) if no datetime is given. Signature``formatDate(literal string, datetime = `@ts`) -> string`` Example ```sql fields formatDate("%Y-%m-%d") as day ``` ```sql stats count() by formatDate("%a", @ts) as weekday ``` ### Date tokens | | | | | ---- | ---------------------------------------------------------------------------------------------------------------------------------------------- | ---------- | | `%j` | day of the year (001-366) | 002 | | `%d` | day of the month, zero-padded (01-31) | 02 | | `%e` | day of the month, space-padded (1-31) | 2 | | | | | | `%V` | ISO 8601 week number (01-53) | 01 | | `%w` | weekday as a integer number with Sunday as 0 (0-6) | 2 | | `%u` | ISO 8601 weekday as number with Monday as 1 (1-7) | 2 | | `%a` | abbreviated weekday name (Mon-Sun) | Mon | | `%W` | full weekday name (Monday-Sunday) | Monday | | | | | | `%m` | month as an integer number (01-12) | 01 | | `%M` | full month name (January-December) | January | | `%b` | abbreviated month name (Jan-Dec) | Jan | | `%Q` | Quarter (1-4) | 1 | | | | | | `%y` | Year, last two digits (00-99) | 18 | | `%Y` | Year | 2018 | | `%C` | year divided by 100 and truncated to integer (00-99) | 20 | | `%g` | two-digit year format, aligned to ISO 8601, abbreviated from four-digit notation | 18 | | `%G` | four-digit year format for ISO week number, calculated from the week-based year defined by the ISO 8601 standard, normally useful only with %V | 2018 | | | | | | `%D` | Short MM/DD/YY date, equivalent to %m/%d/%y | 01/02/18 | | `%F` | short YYYY-MM-DD date, equivalent to %Y-%m-%d | 2018-01-02 | ### Time tokens | | | | | ---- | ------------------------------------------------------- | -------- | | `%s` | second (00-59) | 44 | | `%S` | second (00-59) | 44 | | `%f` | fractional second | 1234560 | | | | | | `%i` | minute (00-59) | 33 | | | | | | `%h` | hour in 12h format (01-12) | 09 | | `%I` | hour in 12h format (01-12) | 10 | | `%H` | hour in 24h format (00-23) | 22 | | `%l` | hour in 12h format (01-12) | 09 | | `%k` | hour in 24h format (00-23) | 22 | | `%r` | 12-hour HH:MM AM/PM time, equivalent to %H:%i %p | 10:30 PM | | `%R` | 24-hour HH:MM time, equivalent to %H:%i | 22:33 | | | | | | `%p` | AM or PM designation | PM | | `%T` | ISO 8601 time format (HH:MM:SS), equivalent to %H:%i:%S | 22:33:44 | | `%z` | Time offset from UTC as +HHMM or -HHMM | -0500 | ### Other tokens | | | | | ---- | ------------------------ | - | | `%n` | new-line character | | | `%t` | horizontal-tab character | | | `%%` | a % sign | % | * `now` Signature`now() -> datetime` * `toDay` Returns the day of month (1-31) for the supplied datetime. Signature`toDay(datetime) -> integer` * `toDayOfWeek` Returns the number of the day in a week (1-7, 1 = monday) for the supplied datetime. Signature`toDayOfWeek(datetime) -> integer` * `toDayOfYear` Returns the day of the year (1-366) from a datetime. Signature`toDayOfYear(datetime) -> integer` * `toEndOf` Signature``toEndOf(interval, datetime = `@ts`) -> datetime`` * `toHour` Returns the 24-hour number (0-23) for the supplied datetime. Signature`toHour(datetime) -> integer` * `toMinute` Returns the minute of the hour (0-59) from a datetime. Signature`toMinute(datetime) -> integer` * `toMonth` Returns the month number (1-12) from a datetime. Signature`toMonth(datetime) -> integer` * `toSecond` Returns the second of the minute (0-59) from a datetime. Signature`toSecond(datetime) -> integer` * `toStartOf` Signature``toStartOf(interval, datetime = `@ts`) -> datetime`` * `toTimezone` Convert datetimes to a specific timezone. **Note:** This does not explicitly embed the timezone into the datetime, but updates the type to reflect the selected timezone (tzdatetime). Signature`toTimezone(datetime, literal string) -> datetime` * `toYear` Signature`toYear(datetime) -> integer` ### URL [Section titled “URL”](#url) * `urlBaseDomain` Extracts the registrable/base domain from a URL's hostname, so subdomains can be grouped together. Signature`urlBaseDomain(string) -> string` * `urlDomain` Extracts the hostname from a URL. Signature`urlDomain(string) -> string` * `urlParameter` Parse out value from valid URL query string Signature`urlParameter(string, literal string) -> string` Example ```sql fields urlParameter(url::str, "user_id") as user_id_param ``` * `urlPath` Extracts the path from a URL. Example: `/hot/goss.html` The path does not include the query string. Signature`urlPath(string) -> string` * `urlPort` Extracts the explicit port from a URL, or returns 0 when the URL does not include one. Signature`urlPort(string) -> integer` * `urlProtocol` Extracts the URL protocol without `://`, for example `https`. Signature`urlProtocol(string) -> string` * `urlQueryString` Extracts the query string from a URL without the leading `?`, for example `page=2&sort=desc`. Signature`urlQueryString(string) -> string` ### Network [Section titled “Network”](#network) * `inCIDR` Returns true when the IP address falls within the CIDR range. Works for IPv4 and IPv6. The address must be a valid IP string. Malformed strings cause a query error. Signature`inCIDR(string, literal string) -> boolean` Example ```sql filter inCIDR(client_ip::str, "10.0.0.0/8") ``` ### Hashing [Section titled “Hashing”](#hashing) `cityHash64` and `xxHash64` are fast, non-cryptographic hashes for bucketing, sampling, or stable grouping. `MD5` and `SHA256` return hex strings for comparing against pre-hashed identifiers. * `cityHash64` Returns a fast, deterministic 64-bit hash of the value. Not cryptographic; use for bucketing, sampling, or stable grouping. Signature`cityHash64(any) -> integer` * `MD5` Returns the MD5 hash of a string as lowercase hexadecimal text. Useful for comparing against pre-hashed identifiers. Signature`MD5(string) -> string` * `SHA256` Returns the SHA-256 hash of a string as lowercase hexadecimal text. Useful for comparing against pre-hashed identifiers. Signature`SHA256(string) -> string` * `xxHash64` Returns a fast, deterministic 64-bit hash of the value. Not cryptographic; use for bucketing, sampling, or stable grouping. Signature`xxHash64(any) -> integer` ### JSON [Section titled “JSON”](#json) * `isValidJSON` Returns true when the string parses as JSON. Signature`isValidJSON(string) -> boolean` Example ```sql filter isValidJSON(payload::str) ``` * `json` Extract a scalar value from a JSON string using a JSONPath expression. Returns null if the path doesn't resolve to a scalar — arrays and objects are not valid targets. Signature`json(string, literal string) -> string` Example ```sql fields json(user_config::str, "$.login_info.last_login") as last_logged_in ``` ### Path syntax Paths follow [JSONPath](https://www.ietf.org/archive/id/draft-goessner-dispatch-jsonpath-00.html). Common patterns: | Path | Selects | | ---------------------- | ------------------------------------ | | `$.foo` | the value at key `foo` | | `$.foo.bar` | nested key `bar` under `foo` | | `$.items[0]` | the first element of an array | | `$.items[-1]` | the last element of an array | | `$['key with spaces']` | a key with non-identifier characters | ### Type handling `json()` returns the value as a string. To use it as a number or datetime, cast it with the appropriate conversion function: ```sql fields toInt(json(payload::str, "$.user.id")) as user_id ``` ### When it returns null * The path doesn't resolve (key missing, index out of range) * The path resolves to an object or array — only scalar values come back * The input isn't valid JSON ### Recommendation We support `json()` for ad-hoc digging into payloads, but querying it at scale is slower than querying real fields. If you find yourself reaching for it often on the same paths, send those values as top-level event fields instead. ### String [Section titled “String”](#string) `toHumanString` supports five format types: `"number"` (default), `"bytes"`, `"short"`, `"milliseconds"`, and `"microseconds"` for microsecond-precision duration fields. `startsWith` is a convenience wrapper around `like` — it is case-sensitive and does not accept wildcards in the match string. * `concat` Signature`concat(string, string...) -> string` * `editDistance` Returns the number of single-character edits (insertions, deletions, substitutions) needed to transform one string into the other. Lower values are more similar. Signature`editDistance(string, string) -> integer` Example ```sql filter editDistance(error_message::str, "connection timed out") < 5 ``` * `endsWith` Returns true when the first string ends with the second string. Signature`endsWith(string, string) -> boolean` Example ```sql filter endsWith(file::str, ".rb") ``` * `length` Returns the number of characters in a string, or the number of elements in an array. Signature`t = string | string[] | number[] | boolean[] | datetime[]``length(t) -> integer` * `lowercase` Signature`lowercase(string) -> string` * `position` Returns the 1-based position of the first occurrence of the search string, or 0 when it is not found. Signature`position(string, string) -> integer` Example ```sql fields position(message::str, "timeout") as timeout_at ``` * `replace` Replace all matches of a substring or regex pattern with another string. Signature`t = string | regex``replace(string, t, string) -> string` Example ```sql fields replace(controller::str, /Controller/, "") as controller ``` * `replaceFirst` Replace the first match of a substring or regex pattern with another string. Signature`t = string | regex``replaceFirst(string, t, string) -> string` Example ```sql fields replaceFirst(controller::str, /Controller/, "") as controller ``` * `similarity` Returns a 0-1 similarity score for two strings: 1 means identical, 0 means no similarity. Easier to threshold than `editDistance` when string lengths vary. Signature`similarity(string, string) -> float` Example ```sql filter similarity(error_message::str, "connection timed out") > 0.9 ``` * `split` Splits a string into an array of substrings around a literal separator. Null input returns an empty array. Signature`split(string, literal string) -> string[]` Example ```sql fields split(tags::str, ",") as tag_list ``` * `startsWith` Signature`startsWith(string, string) -> boolean` * `substring` Signature`substring(string, integer, integer) -> string` Example ```sql fields substring(token::str, 1, 3) as token_type ``` * `toHumanString` Transform a number into a human-readable string. Picks units, separators, and rounding based on the format type. Defaults to `"number"` (comma-separated) if no type is given. Signature`toHumanString(number, string = "number") -> string` Example ```sql fields toHumanString(duration::int, "milliseconds") ``` ```sql fields toHumanString(@size, "bytes") ``` ### Format types | Type | Output | Example input → output | | ---------------- | ------------------------- | ---------------------------- | | `"number"` | comma-separated digits | `1234567` → `"1,234,567"` | | `"short"` | rounded shorthand | `1234567` → `"1.23 million"` | | `"bytes"` | rounded binary size | `105906176` → `"101.0 MiB"` | | `"milliseconds"` | duration starting from ms | `1500` → `"1.5s"` | | `"microseconds"` | duration starting from µs | `1500` → `"1.5ms"` | ### Common usage ```sql stats avg(duration::int) as avg_ms | fields toHumanString(avg_ms, "milliseconds") as avg ``` ```sql stats sum(@size) as total | fields toHumanString(total, "bytes") as total_size ``` Mostly useful for charting and table output. For computation, keep the raw number and only format at the end. * `trim` Signature`trim(string) -> string` * `uppercase` Signature`uppercase(string) -> string` ### Aggregate [Section titled “Aggregate”](#aggregate) Aggregate functions are only valid inside a `stats` call. `count()` with no argument counts all events. Passing a boolean expression counts only events where the expression is true. Passing a field name counts only non-null occurrences of that field: ```badgerql stats count() -- all events stats count(status_code::int >= 500) -- events with 5xx status stats count(user_id::str) -- events where user_id is not null ``` `first` and `last` return the first or last value seen within the group. If the data is not sorted before `stats`, the result is non-deterministic. Pipe through `sort` first if order matters. `percentile` is an approximated result. * `apdex` Returns the Application Performance Index (Apdex) score, which measures user satisfaction with response time. Signature`apdex(number, number) -> float` Example ```sql stats apdex(duration::int, 500) as apdex_score ``` Apdex scores a sample of response times against a target threshold `T`. Each request counts as: * **Satisfied** (1.0) if it completed in `T` or less * **Tolerating** (0.5) if it completed between `T` and `4T` * **Frustrated** (0) if it took longer than `4T` The score is the average — so 1.0 means every request was satisfied, 0 means every request was frustrated. ```sql stats apdex(duration::int, 500) as score ``` ### Picking a threshold `T` should be the response time at which a typical user starts to notice latency. Common starting points: * User-facing web requests: 200–500ms * API endpoints: 100–300ms * Background jobs: depends on the job — pick something tied to user expectations ### Reading the score Rough rule of thumb: | Score | Reading | | ----------- | ------------ | | ≥ 0.94 | Excellent | | 0.85 – 0.94 | Good | | 0.70 – 0.85 | Fair | | 0.50 – 0.70 | Poor | | < 0.50 | Unacceptable | These bands aren't a Honeybadger-specific standard — they come from the Apdex specification. * `apdexIf` Returns the Apdex score computed only over events where the predicate is true. The predicate restricts the whole calculation — satisfied and tolerating counts as well as the total — so the score reads as "the apdex of this slice of events." See `apdex` for how the score itself works. Signature`apdexIf(number, number, boolean) -> float` Example ```sql stats apdexIf(duration::int, 500, route::str == "/checkout") as checkout_apdex ``` * `avg` Signature`avg(number) -> number` * `avgIf` Average a numeric value across events where the predicate is true. Signature`avgIf(number, boolean) -> number` Example ```sql stats avgIf(duration::int, route::str == "/checkout") as checkout_avg ``` * `avgWeighted` Returns a weighted average. Values with larger weights count more, which is useful when averaging pre-aggregated rows such as per-route latency weighted by request count. Signature`avgWeighted(number, number) -> float` Example ```sql stats avgWeighted(avg_latency::float, request_count::int) as typical_latency ``` * `collect` Collects the values from each group into an array. Compose with `dedupe` when you want distinct values. Signature`t = string | integer | float | boolean | datetime``collect(t) -> t[]` Example ```sql stats dedupe(collect(user_id::str)) as users by error_class::str ``` * `corr` Returns the correlation coefficient between two numeric expressions: -1 is inverse correlation, 0 is no linear correlation, and 1 is direct correlation. Signature`corr(number, number) -> float` Example ```sql stats corr(memory::float, response_time::float) as memory_vs_latency ``` * `count` Return the total counts of all results. The count can be affected by supplying a boolean expression argument. If given a field, it will implicitly count non-null occurrences. Signature`count() -> integer``count(boolean) -> integer``count(number) -> integer``count(string) -> integer` Example ```sql stats count() ``` ```sql stats count(status_code::int < 500) ``` * `countIf` Count events where the predicate is true. Signature`countIf(boolean) -> integer` Example ```sql stats countIf(status_code::int >= 500) as errors ``` * `first` Returns the first encountered value. Results could be random if the source is not sorted. Signature`t = string | number | boolean | datetime``first(t) -> t` Example ```sql stats first(user_name::str) by error_class::str ``` * `firstIf` Returns the first encountered value among events where the predicate is true. Use `pickMin(value, @ts)` when you need deterministic earliest-by-time semantics. Signature`t = string | number | boolean | datetime``firstIf(t, boolean) -> t` Example ```sql sort @ts asc | stats firstIf(message::str, level::str == "error") as first_error by host::str ``` * `last` Returns the last encountered value. Results could be random if the source is not sorted. Signature`t = string | number | boolean | datetime``last(t) -> t` Example ```sql stats last(severity::str) by error_class::str ``` * `lastIf` Returns the last encountered value among events where the predicate is true. Use `pickMax(value, @ts)` when you need deterministic latest-by-time semantics. Signature`t = string | number | boolean | datetime``lastIf(t, boolean) -> t` Example ```sql sort @ts asc | stats lastIf(message::str, level::str == "error") as last_error by host::str ``` * `max` Signature`t = string | number | datetime``max(t) -> t` * `maxIf` Return the maximum value across events where the predicate is true. Signature`t = string | number | datetime``maxIf(t, boolean) -> t` Example ```sql stats maxIf(duration::int, status_code::int >= 500) as slowest_error ``` * `median` Returns the median value. Equivalent to `percentile(50, value)` and approximated the same way. Signature`median(number) -> number` * `min` Signature`t = string | number | datetime``min(t) -> t` * `minIf` Return the minimum value across events where the predicate is true. Signature`t = string | number | datetime``minIf(t, boolean) -> t` Example ```sql stats minIf(duration::int, status_code::int >= 500) as fastest_error ``` * `percentile` Calculate the percentile. This is an approximated result. Signature`percentile(literal number, number) -> number` Example ```sql stats percentile(90, duration::int) ``` * `percentileIf` Calculate a percentile across events where the predicate is true. This is an approximated result. Signature`percentileIf(literal number, number, boolean) -> number` Example ```sql stats percentileIf(95, duration::int, status_code::int < 500) as p95_ok ``` * `pickMax` Returns the first argument from the row where the second argument is largest. `pickMax(error_message::str, @ts)` returns the most recent error message in each group. Signature`t = string | integer | float | boolean | datetime``pickMax(t, any) -> t` Example ```sql stats pickMax(error_message::str, @ts) as latest_error by error_class::str ``` * `pickMin` Returns the first argument from the row where the second argument is smallest. `pickMin(user_id::str, duration::int)` returns the user from the fastest request in each group. Signature`t = string | integer | float | boolean | datetime``pickMin(t, any) -> t` Example ```sql stats pickMin(user_id::str, duration::int) as fastest_user by controller::str ``` * `rate` Convert an aggregate into a rate by dividing it by the width of the query's `bin()` group. Defaults to a per-second rate; pass an interval to get a rate per minute, per hour, etc. Signature`rate(number) -> float``rate(number, interval) -> float` Example ```sql stats rate(count()) as rps by bin(1m) as t ``` ```sql stats rate(sum(bytes::int)) as bps by bin() as t ``` ```sql stats rate(count(), 1m) as rpm by bin(1h) as t ``` ### Following the bin The divisor is the width of the query's `bin()`. That includes auto-sized `bin()` — when the bin width changes with the query window, the divisor changes with it, and the result keeps the same unit: ```sql stats rate(count()) as rps by bin() as t ``` ### Choosing the interval The default is per second — the universal observability idiom (RPS, BPS, errors/sec). Pass an interval as the second argument for other units; the bin size doesn't have to match: ```sql stats rate(count(), 1m) as rpm by bin(1h) as t ``` ### Composing Rates are plain numbers, so they compose with arithmetic — two rates over the same bin make a unitless ratio: ```sql stats (rate(countIf(status::int >= 500)) / rate(count())) as error_rate by bin(1m) as t ``` ### Restrictions * Requires exactly one `bin()` group in the same stats stage (directly or via a renamed field). * The argument must be an aggregate. Rates are most natural over `count`/`sum`-style aggregates; `rate(min(x))` is computable but rarely what you want. * Month and year bins or intervals are rejected — they have no fixed second count, so use a fixed-period interval like `30d`. * `stddev` Returns the sample standard deviation of the numeric values. Pair with `avg` to see how spread out a metric is. Signature`stddev(number) -> float` * `sum` Signature`sum(number) -> number` * `sumIf` Sum a numeric value across events where the predicate is true. Signature`sumIf(number, boolean) -> number` Example ```sql stats sumIf(amount::float, status::str == "paid") as paid_total ``` * `unique` Count all unique values Signature`t = string | number | datetime``unique(t) -> integer` Example ```sql stats unique(concat(controller::str, action::str)) ``` * `uniqueIf` Count distinct values among events where the predicate is true. Signature`t = string | number | datetime``uniqueIf(t, boolean) -> integer` Example ```sql stats uniqueIf(user_id::str, event_type::str == "purchase") as purchasers ``` * `variance` Returns the sample variance of the numeric values. Variance is the square of standard deviation. Signature`variance(number) -> float` ### Grouping [Section titled “Grouping”](#grouping-1) * `top` Select the top N values of a field. By default, values are ranked by frequency. An optional third argument ranks values by an aggregate instead, such as `max`, `sum`, or `avg`. `top()` is context-aware: it caps groups, filters by membership, or returns an array depending on where it appears. Useful for high-cardinality fields like controllers, endpoints, queues, or workers. Signature`t = string | number``top(literal integer, t, any = null) -> t[] | t` Example ```sql stats count() by top(10, controller::str) ``` ```sql filter controller::str in top(5, controller::str) ``` ```sql stats top(10, controller::str) by env::str ``` ### In a stats group Caps the group to the top N values, dropping the rest. By default, "top" means most frequent. The default ranking is approximate. ```sql stats count() by top(10, controller::str) ``` Pass an `order_by` aggregate as the third argument to rank by something other than frequency. This switches to an exact ranking — slower than the default, but deterministic. ```sql stats count() by top(10, controller::str, max(duration::float)) ``` Combine with `bin()` to chart the top N series over time: ```sql stats avg(duration::float) by top(10, controller::str), bin() ``` Group-position `top()` may be wrapped in another expression (e.g. `lower(top(5, controller::str))`). The ranking matches the wrapped value so the result lines up with the group key. ### In a filter Tests membership against the top N values. Use `in` to keep matching events or `not in` to exclude them. ```sql filter controller::str in top(5, controller::str) ``` The check runs against raw events when used in a pre-stats filter, and against grouped results when used in a post-stats filter. In practice, `filter controller::str in top(5, controller::str) | stats count() by bin()` selects the top 5 controllers from the source events first, then charts only those events over time. ### As a stats aggregate Returns the top N values as an array. ```sql stats top(10, controller::str) by env::str ``` Aggregate-position `top()` does not accept an `order_by` argument. Given an expanded array field, it ranks the array's elements and still returns a flat array. This counts every element across all events, so it does not multiply rows the way `expand` does. ```sql stats top(3, tags[*]::str) as top_tags by fault_id::int ``` ### Restrictions * `n` must be a positive integer literal — not a field reference. * `top()` is not allowed inside an `or` condition. * In a filter, `top()` must be the right-hand side of `in` or `not in`. Other filter shapes (e.g. equality) are rejected. # Ship your CloudWatch Logs to Honeybadger Insights > Here's how to ship your logs from CloudWatch Logs to Honeybadger Insights. Ingesting logs from CloudWatch Logs requires setting up a [Data Firehose](https://aws.amazon.com/firehose/) stream with a [HTTP Endpoint destination](https://docs.aws.amazon.com/firehose/latest/dev/create-destination.html#create-destination-http) that sends events to our API. Once you create [subscription filters](https://docs.aws.amazon.com/AmazonCloudWatch/latest/logs/SubscriptionFilters.html#FirehoseExample) for the desired log groups, log data from those groups will start flowing into Insights. The easiest way to set this up is to use our [CloudFormation template](https://honeybadger-docs-assets.s3.amazonaws.com/insights-cloudformation-stack.yml) to create a CloudFormation stack in your AWS account. It will prompt you to enter your Honeybadger API key and the name of a log group that you want to connect to Data Firehose. You can quickly [launch this template in your AWS account](https://console.aws.amazon.com/cloudformation/home#/stacks/new?stackName=honeybadger-insights\&templateURL=https://honeybadger-docs-assets.s3.amazonaws.com/insights-cloudformation-stack.yml) and then create additional log group subscriptions for other log groups you wish to monitor. If you set up the Data Firehose stream manually, choose HTTP Endpoint as the destination and use the following URL as the HTTP Endpoint URL in the destination settings: ```plaintext https://api.honeybadger.io/v1/data-firehose-events?api_key=PROJECT_API_KEY ``` ## Setting default fields with a query parameter [Section titled “Setting default fields with a query parameter”](#setting-default-fields-with-a-query-parameter) Events from this endpoint are built from the CloudWatch Logs record, so they always have the same shape: a `ts`, a `message`, and the `logGroup` and `logStream` the record came from. If you want more than that — the environment, the region, the name of the app — you can add a `defaults` query parameter to the HTTP Endpoint URL containing a URL-encoded JSON object, and its fields will be merged into every event the stream delivers: ```plaintext https://api.honeybadger.io/v1/data-firehose-events?api_key=PROJECT_API_KEY&defaults={"environment":"production","region":"us-east-1"} ``` With that URL, an event that would otherwise be stored as: ```json {"ts": "2023-08-31T09:19:30.000Z", "logGroup": "/aws/lambda/checkout", "logStream": "2023/08/31/[$LATEST]abc123", "message": "This is a log line"} ``` …is stored as: ```json {"ts": "2023-08-31T09:19:30.000Z", "logGroup": "/aws/lambda/checkout", "logStream": "2023/08/31/[$LATEST]abc123", "message": "This is a log line", "environment": "production", "region": "us-east-1"} ``` Because the parameter lives on the destination URL, each Data Firehose stream can carry its own metadata — a useful way to tag events by environment or account when you’re shipping logs from more than one place, without running a transformation Lambda to rewrite the payloads. The `defaults` parameter has a few restrictions: * It must be a flat JSON object; values must be strings, numbers, or booleans. * The keys `event_type` and `ts` are reserved and will be ignored. * It’s limited to 16 keys and 2kB (URL-decoded). * Fields we build from the log record always win — a default named `message` or `logGroup` won’t overwrite the real one. An invalid `defaults` parameter never causes the delivery to fail: entries that break the rules above are dropped (an unparseable or oversized parameter is ignored entirely), and the events are ingested without them. Likewise, if merging the defaults would push an event past the 100kB per-event size limit, we drop the defaults for that event rather than the event itself. # Ship your Crunchy Bridge logs to Honeybadger Insights > Ship Postgres logs from Crunchy Bridge to Honeybadger Insights. You can have Crunchy Bridge ship the logs from your Postgres clusters by following their [setup instructions](https://docs.crunchybridge.com/how-to/logging). Use the following values for the logging destination: | Field | Value | | -------- | --------------------------------------------------------------------------------------------------------- | | Host | in.honeybadger.io | | Port | 6514 | | Template | `<$PRI>1 $ISODATE $HOST $PROGRAM $PID ${MSGID:--} [honeybadger@61642 api_key=\"PROJECT_API_KEY\"] $MSG\n` | You can choose to add additional key/value data to the structured data section of the template. E.g., if you want to add an environment field to the payload, you can specify it after the API key in the template: ```plaintext <$PRI>1 $ISODATE $HOST $PROGRAM $PID ${MSGID:--} [honeybadger@61642 api_key=\"PROJECT_API_KEY\" environment=\"production\"] $MSG\n ``` # Ship your Docker container logs to Honeybadger Insights > Here's how to use Vector to collect Docker container logs and send them to Honeybadger Insights. You can use [Vector](https://vector.dev) with its `docker_logs` source to collect logs from your Docker containers and send them to Honeybadger Insights. This example collects logs from all running containers: ```yaml # Put this in vector.yaml sources: docker: type: "docker_logs" transforms: enrich_docker: type: "remap" inputs: ["docker"] source: | # Try to parse JSON log messages payload, err = parse_json(string!(.message)) if err == null { .payload = payload del(.message) } sinks: honeybadger_events: type: "http" inputs: ["enrich_docker"] uri: "https://api.honeybadger.io/v1/events" request: headers: X-API-Key: "PROJECT_API_KEY" encoding: codec: "json" framing: method: "newline_delimited" ``` To run Vector with Docker and collect logs from other containers, you need to mount the Docker socket. Here’s a Docker Compose configuration: ```yaml services: vector: image: timberio/vector:latest-alpine volumes: - "./vector.yaml:/etc/vector/vector.yaml:ro" - "/var/run/docker.sock:/var/run/docker.sock:ro" # Example app container whose logs will be collected app: image: your-app:latest labels: vector.enable: "true" ``` You can filter which containers Vector collects logs from using labels. Update the source configuration to only collect logs from containers with a specific label: ```yaml sources: docker: type: "docker_logs" include_labels: - "vector.enable=true" ``` # Send logs and events from Elixir apps to Honeybadger Insights > Here's how to integrate your Elixir apps with Honeybadger Insights. When enabled, Honeybadger [automatically instruments your Elixir/Phoenix application](/lib/elixir/insights/automatic-instrumentation/) to send application events to Honeybadger Insights. This is the easiest way to get started with Insights and logging. To get started, enable Insights in your app configuration: ```elixir config :honeybadger, insights_enabled: true ``` See our [automatic instrumentation](/lib/elixir/insights/automatic-instrumentation/) guide to learn more. You can also [add extra context data](/lib/elixir/insights/event-context/) to events, [filter events](/lib/elixir/insights/filtering-events/) to remove PII, and [sample events](/lib/elixir/insights/sampling-events/) to reduce the amount of data sent to Honeybadger. ## Sending custom events [Section titled “Sending custom events”](#sending-custom-events) You can send custom events to Honeybadger Insights with the `Honeybadger.event/1` and `Honeybadger.event/2` functions. For example: ```elixir Honeybadger.event(%{ event_type: "user_created", user: user.id }) Honeybadger.event("project_deleted", %{ project: project.name }) ``` ## Sending logs from your infrastructure [Section titled “Sending logs from your infrastructure”](#sending-logs-from-your-infrastructure) Honeybadger isn’t just for errors and application data! You can use our [syslog](/guides/insights/integrations/systemd/), [Vector](/guides/insights/integrations/log-files/), or [PaaS integrations](/guides/insights/#adding-data-from-other-sources) to send additional data from your infrastructure to [Honeybadger Insights](/guides/insights/), where you can query, visualize, and analyze all of your production data in one place. # Ship your Fly.io logs to Honeybadger Insights > Here's how to ship your logs from Fly.io to Honeybadger Insights. Use [Fly.io’s log shipper app](https://github.com/superfly/fly-log-shipper) to ship logs from your apps hosted by Fly.io. First, create a new app config: ```shell # Make a directory for your log shipper app mkdir logshipper cd logshipper # Create the app but don't deploy just yet fly launch --no-deploy --image ghcr.io/superfly/fly-log-shipper:latest # Set some secrets. Setting HONEYBADGER_API_KEY enables the shipping of logs to your Honeybadger project. fly secrets set ORG=personal # The org you chose when running "fly launch" fly secrets set ACCESS_TOKEN=$(fly auth token) fly secrets set HONEYBADGER_API_KEY=PROJECT_API_KEY ``` Edit the generated `fly.toml` file, replacing the `[http_service]` section with this: ```toml [[services]] http_checks = [] internal_port = 8686 ``` Then deploy the app: ```shell fly deploy ``` Once that’s done, you should see logs from your apps flowing into Insights. See the [Fly.io docs](https://fly.io/docs/going-to-production/monitoring/exporting-logs/) for more information about using the log shipper app. # Ship your Heroku logs to Honeybadger Insights > Here's how to ship your logs from Heroku to Honeybadger Insights. To get your Heroku logs into Insights, create a new log drain for your Heroku app using an API key displayed on the API keys tab of the project settings page: ```bash heroku drains:add "https://logplex.honeybadger.io/v1/events?api_key=PROJECT_API_KEY" ``` You can optionally add the `env` parameter to the log drain endpoint. If you do so, each payload recorded from Logplex will have a field named `environment` added to it. You can then add a filter for the desired environment to your queries, like `filter environment::str == 'production'`. ```bash heroku drains:add https://logplex.honeybadger.io/v1/events?api_key=PROJECT_API_KEY&env=production ``` # Host metrics > Monitor CPU, memory, and disk usage on your servers with Honeybadger Insights. Track your infrastructure’s health by sending host metrics to [Honeybadger Insights](/guides/insights/). Monitor CPU usage, memory consumption, and disk space alongside your application errors and logs. ## Using the Honeybadger CLI [Section titled “Using the Honeybadger CLI”](#using-the-honeybadger-cli) The easiest way to collect host metrics is with the [Honeybadger CLI](/resources/cli/). Download a prebuilt binary from the [GitHub releases page](https://github.com/honeybadger-io/cli/releases), or install with Go: ```shell go install github.com/honeybadger-io/cli@latest ``` See the [CLI installation guide](/resources/cli/#installation) for other options, including Homebrew. Start the metrics agent with your project API key: ```shell hb agent --api-key PROJECT_API_KEY ``` The agent collects CPU, memory, and disk metrics every 60 seconds and sends them to Insights. You can customize the interval with the `-i, --interval` flag (see the [CLI reference](/resources/cli/#agent) for details). ### Tagging metrics [Section titled “Tagging metrics”](#tagging-metrics) If you’re running the agent on multiple hosts, add tags to identify and group them: ```shell hb agent --api-key PROJECT_API_KEY \ --tag environment=production \ --tag role=web-1 ``` Tags appear as top-level fields on every metric event. You can also override the default hostname with `--tag host=custom-name`, which is useful when hostnames are auto-generated (e.g. IP-based names from cloud providers). Tags can also be set in the configuration file (`~/.honeybadger-cli.yaml`): ```yaml api_key: PROJECT_API_KEY agent: tags: environment: production role: web-1 ``` CLI flags take precedence over configuration file tags. See the [CLI reference](/resources/cli/#agent) for details and examples of reserved field names that cannot be used as tag keys. Once tagged, you can filter and group metrics in Insights: ```badgerql fields @ts, host::str, used_percent::float | filter event_type::str == "report.system.cpu" | filter environment::str == "production" | filter role::str == "web-1" ``` ## Querying agent metrics in Insights [Section titled “Querying agent metrics in Insights”](#querying-agent-metrics-in-insights) Once metrics are flowing, you can query them in Insights. Each metric type sends a separate event: ```json {"@id": "ca4dee56-bede-453d-a41e-a6fd93d30eaf", "@stream.id": "3XepYQVyo5to", "@ts": "2026-01-12 22:22:11.000", "total_bytes": 994662584320, "used_bytes": 544694333440, "free_bytes": 449968250880, "used_percent": 54.76, "device": "/dev/disk3s1s1", "event_type": "report.system.disk", "host": "vonnegut.lan", "mountpoint": "/", "fstype": "apfs"} {"@id": "d76ca037-3bab-4c1c-beb1-a18b9e6ff765", "@stream.id": "3XepYQVyo5to", "@ts": "2026-01-12 22:22:11.000", "total_bytes": 51539607552, "used_bytes": 38632865792, "free_bytes": 164954112, "available_bytes": 12906741760, "used_percent": 74.96, "event_type": "report.system.memory", "host": "vonnegut.lan"} {"@id": "5b7c4060-1ff3-4d52-90d8-a9d3af17174a", "@stream.id": "3XepYQVyo5to", "@ts": "2026-01-12 22:22:11.000", "num_cpus": 14, "used_percent": 32.85, "load_avg_1": 3.35009765625, "load_avg_5": 3.73046875, "load_avg_15": 3.86083984375, "event_type": "report.system.cpu", "host": "vonnegut.lan"} ``` Here’s an example [BadgerQL](/guides/insights/badgerql/) query to get a snapshot of disk usage: ```badgerql fields @ts, mountpoint::str, used_percent::float | filter event_type::str == "report.system.disk" | sort used_percent desc | limit 1 by mountpoint::str ``` | @ts `TIME EDT` | mountpoint `STR` | used\_percent `FLOAT` | | ----------------------- | ---------------- | --------------------- | | 2026-01-12 16:15:06.000 | / | 55.01 | | 2026-01-12 16:14:21.000 | /data | 11.91 | ## Using Vector [Section titled “Using Vector”](#using-vector) If you need more flexibility or are already using [Vector](https://vector.dev) in your infrastructure, you can use it to send host metrics to Insights instead. Here’s a sample configuration: ```yaml # Put this in /etc/vector/vector.yaml sources: host: type: "host_metrics" sinks: honeybadger_events: type: "http" inputs: ["host"] uri: "https://api.honeybadger.io/v1/events" request: headers: X-API-Key: "PROJECT_API_KEY" encoding: codec: "json" framing: method: "newline_delimited" ``` The easiest way to run Vector is via Docker. Here’s a sample [Docker Compose](https://docs.docker.com/compose/) configuration, assuming your Vector configuration is in a file named `vector.yaml`: ```yaml version: "3.2" services: vector: image: timberio/vector:latest-alpine volumes: - "vector.yaml:/etc/vector/vector.yaml:ro" ``` See the [Vector documentation](https://vector.dev/docs/reference/configuration/sources/host_metrics/) for more configuration options. ## Querying Vector’s metrics [Section titled “Querying Vector’s metrics”](#querying-vectors-metrics) Vector’s [metrics](https://vector.dev/docs/reference/configuration/sources/host_metrics/#output-metrics) are structured like this: ```json { "@id": "01922983-149f-7a69-b5e1-ddca928d815e", "@stream.id": "cEhUcrZrnny0", "@ts": "2025-09-25 14:08:26.048", "gauge": { "value": 1.25 }, "tags": { "collector": "load", "host": "api-10-0-11-252" }, "kind": "absolute", "name": "load15", "namespace": "host" } ``` Here’s an example [BadgerQL](/guides/insights/badgerql/) query to get a snapshot of disk usage: ```badgerql fields @ts, tags.mountpoint::str, round(gauge.value::float * 100, 2) as used_percentage | filter namespace::str == "host" | filter name::str == "filesystem_used_ratio" | filter gauge.value::float > 0.0 | filter tags.filesystem::str not in ["tmpfs", "devtmpfs", "squashfs"] | sort @ts | limit 1 by tags.mountpoint ``` | @ts `TIME EDT` | tags.mountpoint `STR` | used\_percentage `FLOAT` | | ----------------------- | --------------------- | ------------------------ | | 2025-09-25 10:45:11.047 | / | 29.77 | | 2025-09-25 10:45:11.047 | /efs | 0 | # Send logs and events from JavaScript apps to Honeybadger Insights > Here's how to integrate your JavaScript apps with Honeybadger Insights. #### Automatic instrumentation [Section titled “Automatic instrumentation”](#automatic-instrumentation) Capture inbound HTTP requests from Express, Fastify, AWS Lambda, and Next.js as `request.handled` events. See [Automatic instrumentation](/lib/javascript/insights/automatic-instrumentation/) for configuration and framework setup. #### Logs [Section titled “Logs”](#logs) Instrument your JavaScript application, either backend or frontend, to send your logs automatically to Honeybadger Insights. More information can be found [here](/lib/javascript/insights/capturing-logs/). #### Events [Section titled “Events”](#events) If you have custom events you’d like to track, use `Honeybadger.event()` to report them to Insights: ```javascript Honeybadger.event("button_click", { action: "buy_now", user_id: 123, product_id: 456, }); ``` More information about sending events to Insights from your JavaScript apps can be found [here](/lib/javascript/insights/sending-events-to-insights/). # Use Vector to ship your log files to Honeybadger Insights > Here's how to use Vector to watch your log files and send the events they record to Honeybadger. You can use [Vector](https://vector.dev) to watch your existing log files and send the events they record. Here’s a sample configuration that will encode the log lines into the newline-delimited JSON format that our API expects: ```yaml # Put this in /etc/vector/vector.yaml sources: app: type: "file" include: ["/home/app/shared/log/*.log"] sinks: honeybadger_events: type: "http" inputs: ["app"] uri: "https://api.honeybadger.io/v1/events" request: headers: X-API-Key: "PROJECT_API_KEY" encoding: codec: "json" framing: method: "newline_delimited" ``` If you are using something like [Lograge](https://github.com/roidrage/lograge) to emit JSON-formatted logs (and you should — it’s awesome), you can have Vector replace the message field with a JSON payload: ```yaml # Put this in /etc/vector/vector.yaml sources: app: type: "file" include: ["/home/app/shared/log/*.log"] transforms: parse_logs: type: "remap" inputs: ["app"] source: | payload, err = parse_json(string!(.message)) if err == null { .payload = payload del(.message) } sinks: honeybadger_events: type: "http" inputs: ["parse_logs"] uri: "https://api.honeybadger.io/v1/events" request: headers: X-API-Key: "PROJECT_API_KEY" encoding: codec: "json" framing: method: "newline_delimited" ``` Or if you are using logfmt-style logs, like “controller=pages action=index”, then you can add a transform that parses that into JSON: ```yaml --- transforms: parse_logs: type: "remap" inputs: ["app"] source: | payload, err = parse_key_value(string!(.message)) if err == null { .payload = payload del(.message) } ``` Again, we **highly** recommend structured logging. 😉 By the way, Vector supports a variety of [input sources](https://vector.dev/docs/reference/configuration/sources/), such as Docker logs, Redis metrics, etc., in addition to log files. You can define whatever `sources` and `transforms` make sense for what you want to capture, then use the `sinks` section provided in the examples above to send everything to Insights. The easiest way to run Vector is via Docker. Here’s a sample [Docker Compose](https://docs.docker.com/compose/) configuration you can use, assuming your Vector configuration is in a file named `vector.yaml`: ```yaml version: "3.2" services: vector: image: timberio/vector:latest-alpine volumes: - "vector.yaml:/etc/vector/vector.yaml:ro" ``` ## Additional Vector configuration examples [Section titled “Additional Vector configuration examples”](#additional-vector-configuration-examples) ### Nginx logs [Section titled “Nginx logs”](#nginx-logs) You can use regular expressions to extract the fields of an Nginx log to create a JSON structure in a transform: ```yaml sources: nginx_logs: type: "file" ignore_older: 86400 include: - "/var/log/nginx/access.log" read_from: "end" transforms: parse_nginx: type: "remap" inputs: - "nginx_logs" source: | match, err = parse_regex(.message, r'(?P[^ ]*) - (?P[^ ]*) \[(?P[^\]]*)\] "(?P[^ ]*) ?(?P[^ ]*) ?(?P[^"]*)" (?P[^ ]*) (?P[^ ]*) "(?P[^"]*)" "(?P[^"]*)" (?[0-9\.]+)', true) if err == null { .remote_addr = match.remote_addr .user = match.user .timestamp = parse_timestamp(match.timestamp, "%d/%b/%Y:%H:%M:%S %z") ?? match.timestamp .request = match.request .method = match.method .url = match.url .protocol = match.protocol .status, err = to_int(match.status) .bytes_sent, err = to_int(match.bytes_sent) .referer = match.referer .user_agent = match.user_agent .duration, err = to_float(match.duration) del(.message) } else { log("Failed to parse log line: " + err, level: "error") } ``` # Ship your Netlify logs to Honeybadger Insights > Here's how to ship your logs from Netlify to Honeybadger Insights. You can use Netlify’s [General HTTP endpoint](https://docs.netlify.com/monitor-sites/log-drains/?monitoring-providers=general#general-http-endpoint) to send your Netlify logs to Insights. Choose NDJSON as the Log Drain Format and enter this URL as the Full URL: ```plaintext https://api.honeybadger.io/v1/events?api_key=PROJECT_API_KEY ``` # OpenTelemetry Protocol (OTLP) > Send traces, metrics, and logs to Honeybadger Insights using the OpenTelemetry Protocol. Honeybadger can ingest OpenTelemetry traces, metrics, and logs directly via the [OpenTelemetry Protocol (OTLP)](https://opentelemetry.io/docs/specs/otlp/). If you’re already using OpenTelemetry to instrument your applications, you can send that data to Honeybadger Insights without changing your instrumentation code—just point your OTLP exporter at our endpoint. ## Getting started [Section titled “Getting started”](#getting-started) The quickest way to send OpenTelemetry data to Honeybadger is by pointing your OTLP exporter at our endpoint: ```bash export OTEL_EXPORTER_OTLP_ENDPOINT=https://api.honeybadger.io export OTEL_EXPORTER_OTLP_HEADERS=X-API-Key=PROJECT_API_KEY ``` We accept the `http/protobuf` protocol, which is the default for most SDKs. See [Authentication](#authentication) below for other ways to pass your API key. ## Authentication [Section titled “Authentication”](#authentication) Honeybadger accepts your project API key via either the `X-API-Key` header or a standard `Authorization: Bearer` header. Use whichever fits your exporter or collector configuration: ```bash export OTEL_EXPORTER_OTLP_HEADERS=X-API-Key=PROJECT_API_KEY ``` ```bash export OTEL_EXPORTER_OTLP_HEADERS=Authorization=Bearer%20PROJECT_API_KEY ``` Note that `OTEL_EXPORTER_OTLP_HEADERS` requires the space between `Bearer` and your key to be URL-encoded as `%20`. Your API key is available on the API keys tab of your project settings page. ## Using the OpenTelemetry Collector [Section titled “Using the OpenTelemetry Collector”](#using-the-opentelemetry-collector) If you’re using the [OpenTelemetry Collector](https://opentelemetry.io/docs/collector/), add an `otlphttp` exporter to your configuration: ```yaml exporters: otlphttp/honeybadger: endpoint: https://api.honeybadger.io headers: X-API-Key: PROJECT_API_KEY ``` You can also authenticate using a bearer token: ```yaml exporters: otlphttp/honeybadger: endpoint: https://api.honeybadger.io headers: Authorization: Bearer PROJECT_API_KEY ``` Then add `otlphttp/honeybadger` to your pipeline exporters. ## Supported signals [Section titled “Supported signals”](#supported-signals) We accept traces, metrics, and logs at the following endpoints: | Signal | Endpoint | | ------- | --------------------------------------- | | Traces | `https://api.honeybadger.io/v1/traces` | | Metrics | `https://api.honeybadger.io/v1/metrics` | | Logs | `https://api.honeybadger.io/v1/logs` | ## Querying your data [Section titled “Querying your data”](#querying-your-data) Once your data is flowing, you can query it in [Insights](/guides/insights/) using [BadgerQL](/guides/insights/badgerql/). OpenTelemetry data appears as events with these types: * **Traces**: `event_type` = `otel.span` * **Metrics**: `event_type` = `otel.metric` * **Logs**: `event_type` = `otel.log` For example, to view recent spans: ```badgerql fields @ts, span_name::str, duration::float, status.code::str, resource.service.name::str | filter event_type::str == "otel.span" | sort @ts ``` # Send logs and events from PHP apps to Honeybadger Insights > Here's how to integrate your PHP apps with Honeybadger Insights. #### Logs [Section titled “Logs”](#logs) Instrument your PHP application, either a Lumen, a Laravel or a plain PHP app, to send your logs automatically to Honeybadger Insights. More information can be found [here](/lib/php/insights/capturing-logs/). #### Events [Section titled “Events”](#events) If you are using Laravel or Lumen, enable the automatic events instrumentation : ```php 'events' => [ 'enabled' => true, 'automatic' => HoneybadgerLaravel::DEFAULT_EVENTS, ], ``` If you have custom events you’d like to track, use `Honeybadger.event()` to report them to Insights: ```php Honeybadger.event('button_click', [ 'action' => 'buy_now', 'user_id' => 123, 'product_id' => 456 ]) ``` More information about sending events to Insights from your PHP apps can be found [here](/lib/php/insights/sending-events-to-insights/). # Send logs and events from Python apps to Honeybadger Insights > Here's how to integrate your Python apps with Honeybadger Insights. When enabled, Honeybadger [automatically instruments your Python application](/lib/python/insights/automatic-instrumentation/) to send application events to Honeybadger Insights. This is the easiest way to get started with Insights. To get started, enable Insights in your app configuration: ```python from honeybadger import honeybadger honeybadger.configure(insights_enabled=True) ``` Once integrated with our middleware or extensions, Honeybadger instruments the following libraries: * **Django** requests & database queries * **Flask** requests & database queries * **ASGI** requests (FastAPI, Starlette, etc.) * **Celery** tasks * **Oban** workers & maintenance loops See the [automatic instrumentation guide](/lib/python/insights/automatic-instrumentation/) to learn how to configure each integration, and the [Python event reference](/insights/event-types/python/) for every event the package emits, with field schemas and types. You can also [add extra context data](/lib/python/insights/event-context/) to events, [filter events](/lib/python/insights/filtering-events/) to remove PII, and [sample events](/lib/python/insights/sampling-events/) to reduce the amount of data sent to Honeybadger. ## Querying events with BadgerQL [Section titled “Querying events with BadgerQL”](#querying-events-with-badgerql) Once events are flowing into Insights, you can query them with [BadgerQL](/guides/insights/badgerql/). For example, to find your slowest Django views: ```plaintext filter event_type::str == "django.request" | stats avg(duration::float) as avg_duration, count() as requests by view::str | sort avg_duration desc ``` Or to see Oban background-job throughput and p95 duration by worker: ```plaintext filter event_type::str == "oban.job_finished" | stats count() as jobs, percentile(95, duration::float) as p95_ms by worker::str | sort jobs desc ``` The [Python event reference](/insights/event-types/python/) lists the fields available on each event type. ## Sending custom events [Section titled “Sending custom events”](#sending-custom-events) If you have custom events you’d like to track, use `honeybadger.event` to report them to Insights: ```python from honeybadger import honeybadger honeybadger.event("user.signup", {"user_id": user.id, "plan": user.plan}) ``` More information about sending events to Insights from your Python apps can be found [here](/lib/python/insights/sending-custom-events/). ## Sending logs from your infrastructure [Section titled “Sending logs from your infrastructure”](#sending-logs-from-your-infrastructure) Honeybadger isn’t just for errors and application data! You can use our [syslog](/guides/insights/integrations/systemd/), [Vector](/guides/insights/integrations/log-files/), or [PaaS integrations](/guides/insights/#adding-data-from-other-sources) to send additional data from your infrastructure to [Honeybadger Insights](/guides/insights/), where you can query, visualize, and analyze all of your production data in one place. # Ship your rsyslog logs to Honeybadger Insights > Use rsyslog to forward system and application logs to Honeybadger Insights over syslog-TLS. [rsyslog](https://www.rsyslog.com/) is the default syslog daemon on most Linux distributions. You can configure it to forward logs to Honeybadger Insights over syslog-TLS (RFC 5425), tagging each message with your project’s API key in the structured-data section of the RFC 5424 payload. ## Requirements [Section titled “Requirements”](#requirements) Install the TLS driver package for rsyslog. On Debian and Ubuntu: ```shell sudo apt-get install rsyslog-gnutls ``` On RHEL, Fedora, and derivatives: ```shell sudo dnf install rsyslog-gnutls ``` You’ll also need the CA certificate bundle for your system. On Debian/Ubuntu this is `/etc/ssl/certs/ca-certificates.crt`. On RHEL/Fedora it’s `/etc/pki/tls/certs/ca-bundle.crt`. ## Configuration [Section titled “Configuration”](#configuration) /etc/rsyslog.d/60-honeybadger.conf ```plaintext # Load the TLS network stream driver. Set the CA file to match your OS: # Debian/Ubuntu: /etc/ssl/certs/ca-certificates.crt # RHEL/Fedora: /etc/pki/tls/certs/ca-bundle.crt global(DefaultNetstreamDriver="gtls" DefaultNetstreamDriverCAFile="/etc/ssl/certs/ca-certificates.crt") # RFC 5424 template with Honeybadger structured data template(name="HoneybadgerFormat" type="string" string="<%PRI%>1 %TIMESTAMP:::date-rfc3339% %HOSTNAME% %APP-NAME% %PROCID% %MSGID% [honeybadger@61642 api_key=\"PROJECT_API_KEY\" event_type=\"rsyslog\"] %msg%\n") # Forward all logs to Honeybadger over syslog-TLS (RFC 5425) action(type="omfwd" Target="in.honeybadger.io" Port="6514" Protocol="tcp" TCP_Framing="octet-counted" StreamDriver="gtls" StreamDriverMode="1" StreamDriverAuthMode="x509/name" StreamDriverPermittedPeers="*.honeybadger.io" template="HoneybadgerFormat") ``` Restart rsyslog to pick up the change: ```shell sudo systemctl restart rsyslog ``` You can add additional key/value pairs to the structured-data section of the template. For example, to tag every event with an environment, replace the `string=` value inside the `template(name="HoneybadgerFormat" ...)` block above with the following: ```plaintext string="<%PRI%>1 %TIMESTAMP:::date-rfc3339% %HOSTNAME% %APP-NAME% %PROCID% %MSGID% [honeybadger@61642 api_key=\"PROJECT_API_KEY\" event_type=\"rsyslog\" environment=\"production\"] %msg%\n" ``` ## Shipping application log files with imfile [Section titled “Shipping application log files with imfile”](#shipping-application-log-files-with-imfile) rsyslog’s [`imfile`](https://www.rsyslog.com/doc/configuration/modules/imfile.html) module can tail arbitrary log files and feed them through the same pipeline, which is handy if your application writes to its own log file instead of stdout. Add the following to the top of `/etc/rsyslog.d/60-honeybadger.conf` (before the `action(...)` block): ```plaintext # Load the file input module module(load="imfile" PollingInterval="10") # Tail your application's log files input(type="imfile" File="/var/log/myapp/*.log" Tag="myapp" Severity="info" Facility="local7") ``` Each line written to a matching file will be forwarded to Honeybadger using the `HoneybadgerFormat` template, with `APP-NAME` set to the `Tag` value (`myapp`). Adjust `File`, `Tag`, `Severity`, and `Facility` to match your application. If you’d rather only forward the events captured by `imfile` (and not every other message rsyslog processes), wrap the action in a conditional: ```plaintext if ($programname == "myapp") then { action(type="omfwd" Target="in.honeybadger.io" Port="6514" Protocol="tcp" TCP_Framing="octet-counted" StreamDriver="gtls" StreamDriverMode="1" StreamDriverAuthMode="x509/name" StreamDriverPermittedPeers="*.honeybadger.io" template="HoneybadgerFormat") } ``` ## Querying your data [Section titled “Querying your data”](#querying-your-data) Once your data is flowing, you can query it in [Insights](/guides/insights/) using [BadgerQL](/guides/insights/badgerql/). The following query will return events sent via rsyslog: ```badgerql fields @ts, hostname::str, appname::str, severity::str, message::str | filter event_type::str == "rsyslog" | sort @ts ``` ## Troubleshooting [Section titled “Troubleshooting”](#troubleshooting) If events aren’t showing up in Insights, check rsyslog’s own log for TLS or forwarding errors: ```shell sudo journalctl -u rsyslog -f ``` A missing or incorrect CA file is the most common cause of connection failures — double-check the `DefaultNetstreamDriverCAFile` path against what’s installed on your system. # Send metrics and events from Ruby and Rails apps to Honeybadger Insights > Here's how to integrate your Ruby/Ruby on Rails apps with Honeybadger Insights. #### Logs [Section titled “Logs”](#logs) Sending your logs to Insights is a quick way to get some visibility into your app. There are two good options: ##### Semantic Logger [Section titled “Semantic Logger”](#semantic-logger) Use the [rails\_semantic\_logger gem](https://github.com/reidmorrison/rails_semantic_logger) and enable the `HoneybadgerInsights` appender by adding `config.semantic_logger.add_appender(appender: :honeybadger_insights)` to `config/application.rb`. Outside of Rails, you can use the same appender with the [semantic\_logger gem](https://github.com/reidmorrison/semantic_logger). Please note that if you are using SolidQueue, you will need to add the following snippet to `config/initializers/solid_queue.rb` to work around a [known issue with Semantic Logger](https://github.com/reidmorrison/rails_semantic_logger/issues/237) that causes SolidQueue/ActiveJob logging to not be sent to Insights: ```yaml # Re-open appenders after forking the worker, dispatcher, and scheduler processes SolidQueue.on_worker_start { SemanticLogger.reopen } SolidQueue.on_dispatcher_start { SemanticLogger.reopen } SolidQueue.on_scheduler_start { SemanticLogger.reopen } ``` ##### Lograge [Section titled “Lograge”](#lograge) Use [Lograge](https://github.com/roidrage/lograge) to emit JSON-formatted output to your log files and Vector to [forward them to Insights](/guides/insights/integrations/log-files/). If you go this route, be sure to disable the log tagging in your Rails environment config (`config/environments/production.rb`) by commenting out the `config.log_tags` line, as that will mess with the JSON output. #### Metrics [Section titled “Metrics”](#metrics) You can get more details about what’s happening in your application by enabling our gem’s automatic instrumentation, which will report information about every SQL query, HTTP request, etc. to Insights. This will consume more Insights quota than the logging approach, but you will get much more data to use for analyzing your app’s performance, and this will populate our ready-made Rails dashboard, which includes charts for request duration, SQL query counts, and more. More information can be found [here](/lib/ruby/insights/collecting-and-reporting-metrics). Alternatively, you can use [Yabeda](https://github.com/yabeda-rb/yabeda) and [our Yabeda integration](https://github.com/honeybadger-io/yabeda-honeybadger_insights) to collect and report metrics in your Ruby and Rails apps. Several default metrics, such as request counts, request duration, etc., will be reported automatically once you’ve added and configured the gems. Alternatively, you can use [Yabeda](https://github.com/yabeda-rb/yabeda) and [our Yabeda integration](https://github.com/honeybadger-io/yabeda-honeybadger_insights) to collect and report metrics in your Ruby and Rails apps. Several default metrics, such as request counts, request duration, etc., will be reported automatically once you’ve added and configured the gems. #### Events [Section titled “Events”](#events) If you have custom events you’d like to track, use `Honeybadger#event` to report those events to Insights: app/controllers/accounts\_controller.rb ```ruby class AccountsController < ApplicationController def create # Account.create(...) Honeybadger.event("Created account", account_id: account.id, account_name: account.name, plan: account.subscription.name) end end ``` More information about sending events to Insights from your Ruby and Rails apps can be found [here](/lib/ruby/insights/sending-events-to-insights). # Send CI/CD telemetry from RWX to Honeybadger Insights > Here's how to send CI/CD telemetry from RWX (Mint) to Honeybadger Insights using OpenTelemetry. [RWX](https://www.rwx.com/) can send CI/CD pipeline telemetry to Honeybadger Insights using [OpenTelemetry](/guides/insights/integrations/opentelemetry/), giving you visibility into pipeline runs, task durations, and failures. Tip RWX’s observability integration is organization-wide rather than per-repository. If you want to keep CI telemetry separate from your application data, consider creating a dedicated Honeybadger project for it. ## Configuration [Section titled “Configuration”](#configuration) 1. Go to your [RWX organization observability settings](https://cloud.rwx.com/org/deep_link/manage/mint/observability). 2. Select **Honeybadger** as the OpenTelemetry provider. 3. The endpoint will default to `https://api.honeybadger.io/v1/traces`. 4. Enter your Honeybadger API key, which is available on the API keys tab of your [project settings](/guides/projects/). ## Querying your data [Section titled “Querying your data”](#querying-your-data) Once you’re receiving telemetry, you can query your CI/CD data in [Insights](/guides/insights/) using [BadgerQL](/guides/insights/badgerql/). RWX sends OpenTelemetry spans with [CI/CD semantic convention](https://opentelemetry.io/docs/specs/semconv/cicd/cicd-metrics/) fields. View recent pipeline tasks: ```badgerql fields @ts, span_name::str, cicd.pipeline.task.run.result::str, duration::int | filter event_type::str == "otel.span" | filter resource.service.name::str == "rwx" | sort @ts desc ``` Find failed tasks: ```badgerql fields @ts, span_name::str, cicd.pipeline.run.git.repository::str, cicd.pipeline.run.git.branch::str | filter event_type::str == "otel.span" | filter resource.service.name::str == "rwx" | filter cicd.pipeline.task.run.result::str == "failure" | sort @ts desc ``` Analyze task durations: ```badgerql fields cicd.pipeline.task.name::str, cicd.pipeline.task.run.timing.runtime.ms::int | filter event_type::str == "otel.span" | filter resource.service.name::str == "rwx" | filter cicd.pipeline.task.name::str != "$run" | stats avg(cicd.pipeline.task.run.timing.runtime.ms::int), max(cicd.pipeline.task.run.timing.runtime.ms::int) by cicd.pipeline.task.name::str ``` ## Learn more [Section titled “Learn more”](#learn-more) * [RWX Honeybadger integration docs](https://www.rwx.com/docs/observability/honeybadger) * [OpenTelemetry CI/CD semantic conventions](https://opentelemetry.io/docs/specs/semconv/cicd/cicd-metrics/) * [Honeybadger OpenTelemetry integration](/guides/insights/integrations/opentelemetry/) # Use Vector to ship your systemd logs to Honeybadger Insights > Here's how to use Vector to watch journald and send events to Honeybadger. [Journald](https://www.freedesktop.org/software/systemd/man/latest/systemd-journald.service.html) is the logging system used by [systemd](https://systemd.io), the init system used on most modern Linux distributions. It’s a replacement for syslog and rsyslog, and it captures the logs for just about everything running on a Linux server, including services like web and database servers that are managed by systemd. Any systemd-managed process that sends output to stdout will show that output in journald. You can use [Vector](https://vector.dev) to watch journald and relay the events it captures. Here’s a sample configuration that will encode the journald’s data into the newline-delimited JSON format that our API expects: ```yaml # Put this in /etc/vector/vector.yaml sources: journald: type: journald include_matches: _TRANSPORT: - stdout # See the Vector Remap Language reference for more info: https://vrl.dev transforms: parse_logs: type: "remap" inputs: ["journald"] source: | . = {"host": .host, "unit": ._SYSTEMD_USER_UNIT || ._SYSTEMD_UNIT, "message": .message, "timestamp": .timestamp} structured = parse_json(.message) ?? {} . = merge!(., structured) sinks: honeybadger: type: "http" inputs: ["parse_logs"] uri: "https://api.honeybadger.io/v1/events" request: headers: X-API-Key: "PROJECT_API_KEY" encoding: codec: "json" framing: method: "newline_delimited" batch: max_bytes: 1000000 ``` Since journald captures *everything* that happens on your server, and since you probably don’t care about stuff like kernel messages, the `sources` section of the configuration limits what it will pass on to Honeybadger. This configuration will only relay events that were emitted to stdout, like web server logs, Rails application logs, and that sort of thing. If you really want to send everything that gets logged to journald, you can delete the `include_matches` portion of the configuration. See the [Vector documentation](https://vector.dev/docs/reference/configuration/sources/journald/) for more info on filtering the journald input. The `parse_logs` transformation also reduces the amount of data sent to Insights by stripping out things like the process ID, the user running the service, etc. If you decide you want to be able to query that data in Insights, you can remove the transform and change the `honeybadger` sink `inputs` from “parse\_logs” to “journald”. Please see our documentation on ingesting [log files](/guides/insights/integrations/log-files/) for a few more handy transformations you can use in your Vector configuration. ## Quick setup method [Section titled “Quick setup method”](#quick-setup-method) If you’re running a system that uses apt to manage packages, like Debian or Ubuntu, you can use the following command to fetch and run a [script](https://gist.github.com/stympy/9ccb5a809a6731f53b3335fb4e020c2c#file-install_vector-sh) that installs the Vector package, sets up the configuration file, and starts Vector as a service: ```shell curl -sL https://gist.github.com/stympy/9ccb5a809a6731f53b3335fb4e020c2c/raw/bc5741a4e277ea3a7d6d0f5e70a67e0767aec221/install_vector.sh > install_vector.sh && \ chmod a+x install_vector.sh && \ HONEYBADGER_API_KEY="PROJECT_API_KEY" ./install_vector.sh ``` # Integrations > Send Honeybadger data to other services. Honeybadger has deep support for a wide variety of [third-party integrations](#supported-integrations). This page provides an overview of some cool features available for every integration. These settings are located at **Project settings > Alerts & integrations**. You can click the edit icon and customize the notifications for each integration. ![Project settings showing Alerts & integrations navigation](/_astro/alerts-and-integrations-nav.k9DyuVEM_Z2cojnw.webp) ## Customizing integration notifications [Section titled “Customizing integration notifications”](#customizing-integration-notifications) ### Errors [Section titled “Errors”](#errors) ![Error event options](/_astro/channel_event.CpHSZMFm_Z3WmfP.webp) You get to choose which error events result in a notification or ticket being created: ### Uptime checks [Section titled “Uptime checks”](#uptime-checks) You can edit which uptime events are sent to the integration for all or a subset of the project’s uptime checks: ![Uptime](/_astro/channel_uptime.BERsvy7X_RYtkJ.webp) ### Check-Ins [Section titled “Check-Ins”](#check-ins) And you can also change what check-in events are reported: ![Channel check-in options](/_astro/channel_check-in.TvVWRVEX_2tCNbj.webp) ### Environments [Section titled “Environments”](#environments) You can ignore environments. We auto-populate the list based on environments we’ve seen in your app. ![Error environment options](/_astro/channel_environment.D4pLEOuX_xbqti.webp) ## Rate escalations [Section titled “Rate escalations”](#rate-escalations) Escalations let you receive extra notifications when your error rate exceeds a number you’ve configured. ![Escalation](/_astro/channel_escalation.DzkFbqJD_1yWMPq.webp) ## Error volume anomaly detection [Section titled “Error volume anomaly detection”](#error-volume-anomaly-detection) Anomaly detection alerts you when a project’s **total error volume** deviates from its learned baseline. Unlike [rate escalations](#rate-escalations), which fire at a fixed threshold you have set, anomaly detection learns each project’s normal hourly error volume and notifies you when the current rate is statistically unusual (for example, “errors are 4.7× your normal rate”). Turn it on per integration in the **Anomaly detection** section in the integration’s options. Honeybadger evaluates your projects every few minutes and sends a single notification when a spike begins. A two-hour cooldown then suppresses repeat alerts so a sustained spike notifies you once rather than continuously. Anomaly detection needs enough history to learn what’s normal — at least 48 hours of error activity. Brand-new or very quiet projects won’t trigger alerts until they’ve accumulated enough data. Spike alerts go to notification and alerting integrations (email, Slack, SMS, PagerDuty, Opsgenie, Microsoft Teams, webhooks, and similar). Issue-tracker integrations (GitHub, Jira, Linear, and the like) don’t receive spike alerts, since a spike is an alert rather than a fileable issue. See the structure of the JSON sent to webhook and event-based integrations in the [`volume_spike` payload](/guides/integrations/payloads/volume_spike/). ## Throttling [Section titled “Throttling”](#throttling) Avoid floods of notifications when everything goes wrong at once. ![Throttling](/_astro/channel_throttle.DTGlCAas_Z1wibAS.webp) ## Filters [Section titled “Filters”](#filters) With filters, you can be hyper-precise about which errors trigger notifications or issue creation. You could: * Create issues in separate trackers for staging, prepared and production * Route notifications to a certain team’s inbox whenever an error assigned to that team reoccurs. ![Filters](/_astro/channel_filter.BkRvfP-j_1oF9zN.webp) The syntax for error filters is essentially the same as our search syntax, with a few limitations: * You can’t filter on params, context, session or other per-notice data * Filters don’t support freeform text search. You must use the `key:val` syntax. Below is a list of fields you can use when constructing your queries. Note that you can prefix any query with `-` to create its inverse. | Example query | Matches | | ------------------------------- | ------------------------------------------ | | `is:resolved` | Resolved errors | | `is:paused` | Paused errors | | `is:ignored` | Ignored errors | | `assignee:"nobody"` | Unassigned errors | | `assignee:"anybody"` | Errors assigned to anyone | | `assignee:"jane@email.com"` | Errors assigned to a specific person | | `environment:"production"` | Errors occurring in production | | `class:"PermissionDeniedError"` | Errors with a certain class | | `tag:"tag_example"` | Errors with a tag | | `message:"404"` | Errors with a message | | `component:"UsersController"` | Errors occurring in a controller/component | | `action:"update"` | Errors occurring in an action | Multiple filters are evaluated using a logical OR. If any query matches the error, a notification will be sent. When using negative queries like `-class:Foo`, this OR behavior can give unexpected results. To combine multiple negative matches, use a single filter with a search term like `-class:"Foo" AND -class:"Bar"`. ## Custom formatters [Section titled “Custom formatters”](#custom-formatters) For some of our integrations, we allow the option to provide a custom format for specific fields (e.g., email subject line or Trello card title). Your custom format will be used for all events that are applicable for the integration (reported, assigned, marked as resolved, etc). The following is a list of valid formatter tokens: | Token | Description | | --------------- | ----------------------------------------------------------------------------------- | | `[project]` | The project name | | `[environment]` | The operating environment — production, development, etc. | | `[type]` | The event type — occurred, assigned, etc. | | `[class]` | The class of the error associated with the event | | `[message]` | The message of the error associated with the event | | `[component]` | The component name (might be null, usually maps to the controller name) | | `[action]` | The action name (might be null, usually maps to the controller action e.g. `index`) | | `[fault_id]` | A unique id for the fault event | | `[file]` | The filename with path and line number where the error occurred | | `[backtrace]` | The backtrace of the error associated with the event (first 3 lines) | | `[url]` | The URL of the event in the Honeybadger UI | ## Supported integrations [Section titled “Supported integrations”](#supported-integrations) Your Honeybadger data can be sent to a variety of third-party services, listed below. We support creating issues for errors in the SCM and project management tools, such as GitHub and Jira. For communication tools like Slack and PagerDuty, we can send notifications for errors, sites that go down (and come back up), and check-ins. [![alertops.png](/_astro/alertops.N4aLK7Tw.png)AlertOps](/guides/integrations/alertops/)Send alerts to AlertOps [Asana](/guides/integrations/asana/)Create Asana tasks from errors [Backlog](/guides/integrations/backlog/)Create Backlog issues from errors [Bitbucket](/guides/integrations/bitbucket/)Create Bitbucket issues from errors [Campfire](/guides/integrations/campfire/)Send notifications to Campfire [ClickUp](/guides/integrations/clickup/)Create ClickUp tasks from errors [ClickUp Chat](/guides/integrations/clickup-chat/)Send messages to ClickUp Chat [Datadog](/guides/integrations/datadog/)Send events to Datadog [Discord](/guides/integrations/discord/)Send notifications to Discord [Email](/guides/integrations/email/)Receive email notifications [GitHub](/guides/integrations/github/)Create GitHub issues from errors [GitLab](/guides/integrations/gitlab/)Create GitLab issues from errors [Google Chat](/guides/integrations/google-chat/)Send messages to Google Chat [![ilert.png](/_astro/ilert.CXUfRGif.png)ilert](/guides/integrations/ilert/)Create ilert alerts [incident.io](/guides/integrations/incident-io/)Create incidents in incident.io [Instatus](/guides/integrations/instatus/)Update Instatus status page [Intercom](/guides/integrations/intercom/)Send messages to Intercom [Jira & Jira Cloud](/guides/integrations/jira/)Create Jira issues from errors [Linear](/guides/integrations/linear/)Create Linear issues from errors [Mattermost](/guides/integrations/mattermost/)Send notifications to Mattermost [Microsoft Teams](/guides/integrations/microsoft-teams/)Send messages to Microsoft Teams [OpsGenie](/guides/integrations/opsgenie/)Create OpsGenie alerts [PagerDuty](/guides/integrations/pagerduty/)Create PagerDuty incidents [PagerTree](/guides/integrations/pagertree/)Create PagerTree alerts [Redmine](/guides/integrations/redmine/)Create Redmine issues from errors [![rootly.png](/_astro/rootly.CnXPv3q1.png)Rootly](/guides/integrations/rootly/)Create Rootly incidents [Shortcut](/guides/integrations/shortcut/)Create Shortcut stories from errors [Slack](/guides/integrations/slack/)Send notifications to Slack [Splunk On-Call](/guides/integrations/splunk-on-call/)Create Splunk On-Call incidents [![sprintly.png](/_astro/sprintly.Bm6r2OKO.png)Sprintly](/guides/integrations/sprintly/)Create Sprintly items from errors [Trello](/guides/integrations/trello/)Create Trello cards from errors [Webhook](/guides/integrations/webhook/)Send webhooks to custom endpoints [Zulip](/guides/integrations/zulip/)Send messages to Zulip # AlertOps > Connect Honeybadger to AlertOps to route notifications through your incident management and alerting system. Users with administrative privileges can find this integration below the list of personal alert integrations on the Alerts & Integrations tab of the Project Settings page. ## Setup [Section titled “Setup”](#setup) ### 1. Select the AlertOps integration [Section titled “1. Select the AlertOps integration”](#1-select-the-alertops-integration) ![alertops integration](/_astro/alertops.BcmsdekX_Z2rIBFx.webp) ![alertops form](/_astro/alertops_form.0me6t2fB_Zf5iiM.webp) ### 2. Enter the AlertOps URL [Section titled “2. Enter the AlertOps URL”](#2-enter-the-alertops-url) After you set up the [integration URL](https://honeybadger.alertops.com/admin/MappingRulesList.aspx) at AlertOps, you can enter that URL here. ### 3. Save [Section titled “3. Save”](#3-save) That’s it! You’re good to go. # Asana > Connect Honeybadger to Asana to automatically create tasks from errors and track bug fixes in your project workflow. Users with administrative privileges can find this integration below the list of personal alert integrations on the Alerts & Integrations tab of the Project Settings page. ## Setup [Section titled “Setup”](#setup) ### 1. Select the Asana integration [Section titled “1. Select the Asana integration”](#1-select-the-asana-integration) ![asana integration](/_astro/asana.B16YQCUU_Z1PNxdk.webp) ![asana integration](/_astro/asana_form.ByvnrMrl_ZB0vAo.webp) ### 2. Enter your project ID [Section titled “2. Enter your project ID”](#2-enter-your-project-id) You can find your Project ID from a project view. See the input hint for more details on where the ID is located. ### 3. Connect via OAuth [Section titled “3. Connect via OAuth”](#3-connect-via-oauth) Select the “Connect OAuth” button and give access to our app. ### 4. Save [Section titled “4. Save”](#4-save) That’s it! You can test the integration by clicking “Test”. Otherwise, just save it and you’re ready to go. # Backlog > Connect Honeybadger to Backlog to automatically create issues from errors and track bug fixes in your project workflow. Users with administrative privileges can find this integration below the list of personal alert integrations on the Alerts & Integrations tab of the Project Settings page. [Backlog](https://backlog.com/) is a project management and collaboration platform that helps teams track issues, tasks, and bugs. Honeybadger automatically creates issues in Backlog when errors occur and keeps the status in sync, making it easy to track bug fixes as part of your project workflow. ## Setup [Section titled “Setup”](#setup) ### 1. Select the Backlog integration [Section titled “1. Select the Backlog integration”](#1-select-the-backlog-integration) ![Backlog integration](/_astro/backlog.CcUnTNvK_BmfeY.webp)![Backlog integration](/_astro/backlog-dark.CZySJe3b_ZMo2mi.webp) ### 2. Enter your Space URL [Section titled “2. Enter your Space URL”](#2-enter-your-space-url) Your Space URL is the full URL of your Backlog space, including the protocol. For example: * `https://example.backlog.com` (for international spaces) * `https://example.backlog.jp` (for Japanese spaces) ### 3. Set the API key [Section titled “3. Set the API key”](#3-set-the-api-key) You can generate an API key from your Backlog account: 1. Go to **Personal Settings** in Backlog 2. Navigate to the **API** section 3. Generate a new API key 4. Copy the key and paste it into the API Key field ### 4. Fetch projects [Section titled “4. Fetch projects”](#4-fetch-projects) Click the **Fetch Projects** button to retrieve your Backlog projects. This will populate the project dropdown and enable the remaining configuration options. ### 5. Select project and configure issue settings [Section titled “5. Select project and configure issue settings”](#5-select-project-and-configure-issue-settings) Choose the Backlog project where issues should be created, then configure the required settings: * **Issue Type**: The type of issue to create (bug, task, etc.) * **Priority**: The priority level for created issues * **Closed Status**: The status to transition issues to when errors are marked as resolved * **Open Status**: The status to transition issues to when errors are reopened By default, Honeybadger will automatically create a Backlog issue when a new error occurs, and sync status updates between Backlog and Honeybadger. See [Two-way sync with Backlog](#two-way-sync-with-backlog) for additional options. ### 6. Save [Section titled “6. Save”](#6-save) That’s it! You can test the integration by clicking “Test this integration”. Otherwise, just save it and you’re ready to go. ## Two-way sync with Backlog [Section titled “Two-way sync with Backlog”](#two-way-sync-with-backlog) Honeybadger provides seamless two-way synchronization with Backlog by default. **From Honeybadger to Backlog:** * **Automatically create an issue when an error occurs:** When a new error occurs, Honeybadger creates a new issue in Backlog with the **Open Status** * **Automatically resolve issues**: When you resolve an error in Honeybadger, Honeybadger transitions the Backlog issue to the **Closed Status** * **Automatically reopen issues**: When you unresolve (reopen) an error in Honeybadger, Honeybadger transitions the Backlog issue to the **Open Status** **From Backlog to Honeybadger:** * **Sync status from Backlog**: Honeybadger creates [a webhook](https://support.nulab.com/hc/en-us/articles/8840133998489-How-to-add-and-manage-webhooks-in-Backlog) in your Backlog project that automatically syncs status changes back to Honeybadger: * When a Backlog issue’s status changes to your selected **Closed Status**: the error is automatically resolved in Honeybadger * When a Backlog issue’s status changes from your selected **Closed Status** to any other status: the error is automatically unresolved in Honeybadger These options are enabled by default to keep your Backlog issues and Honeybadger errors in sync automatically. You can uncheck any of these options if you prefer to create/update issues manually. For additional integration options, see the [integrations guide](/guides/integrations/). # Bitbucket > Connect Honeybadger to Bitbucket to automatically create issues from errors and link commits to deployments. Users with administrative privileges can find this integration below the list of personal alert integrations on the Alerts & Integrations tab of the Project Settings page. ## Setup [Section titled “Setup”](#setup) ### 1. Select the Bitbucket integration [Section titled “1. Select the Bitbucket integration”](#1-select-the-bitbucket-integration) ![bitbucket integration](/_astro/bitbucket.BXGm99fY_17FG4g.webp) ![bitbucket integration](/_astro/bitbucket_form.PiVWKyBP_TiNTI.webp) ### 2. Set the repository name [Section titled “2. Set the repository name”](#2-set-the-repository-name) The repository name includes the account name. For example, Honeybadger has a repo called “docs” the repository name we’d enter here is “honeybadger/docs”. ### 3. Authenticate [Section titled “3. Authenticate”](#3-authenticate) Click “Save and Authenticate With Bitbucket” to complete setup. This will send you to bitbucket.org to authenticate via OAuth. # Campfire > Connect Honeybadger to Campfire to receive real-time application monitoring alerts directly in your team's chat rooms. Users with administrative privileges can find this integration below the list of personal alert integrations on the Alerts & Integrations tab of the Project Settings page. ## Setup [Section titled “Setup”](#setup) ### 1. Select the Campfire integration [Section titled “1. Select the Campfire integration”](#1-select-the-campfire-integration) ![campfire integration](/_astro/campfire.CIhQMLSU_2DcoF.webp) ![campfire form](/_astro/campfire_form.autUylpi_1Hy4sg.webp) ### 2. Create a chatbot integration in Basecamp [Section titled “2. Create a chatbot integration in Basecamp”](#2-create-a-chatbot-integration-in-basecamp) You can configure chatbots under **Basecamp** → **\[Your project]** → **Chat** → **…** (click the three dots in the upper right-hand corner of the chat window to get the context menu). ![campfire chatbot](/_astro/campfire_chatbot.CkqHALFa_Z1pomCN.webp) To add a chatbot, click **Configure chatbots** → **Add a new chatbot**, and type “Honeybadger” in the `Name` field. ![campfire add chatbot](/_astro/campfire_add_chatbot.CUayODIS_HhjjF.webp) You can optionally upload an avatar (i.e. [our logo](https://www.honeybadger.io/assets/)). Leave `Command URL` blank. ### 3. Set the chatbot URL in Honeybadger [Section titled “3. Set the chatbot URL in Honeybadger”](#3-set-the-chatbot-url-in-honeybadger) After you create the chatbot in Basecamp, click on “Send line from this integration to Chat…” and copy/paste the URL in the example into the `Chatbot URL` field in Honeybadger. ![campfire chatbot url](/_astro/campfire_chatbot_url.BXID8aOu_HQ7tX.webp) ### 4. Save [Section titled “4. Save”](#4-save) That’s it! You can test the integration by clicking “Test”. Otherwise, just save it and you’re ready to go. # ClickUp > Connect Honeybadger to ClickUp to automatically create tasks from errors and track bug fixes in your workflow. Users with administrative privileges can find this integration below the list of personal alert integrations on the Alerts & Integrations tab of the Project Settings page. ## Setup [Section titled “Setup”](#setup) ### 1. Select the ClickUp integration [Section titled “1. Select the ClickUp integration”](#1-select-the-clickup-integration) ![clickup integration](/_astro/clickup.BpDnz5Bu_Z2rjuBV.webp) ### 2. Connect via OAuth [Section titled “2. Connect via OAuth”](#2-connect-via-oauth) An OAuth dialog should appear. Log in to your account and grant access to one or more workspaces. You’ll then be redirected back to the integration page. ### 3. Select workspace and teamspace [Section titled “3. Select workspace and teamspace”](#3-select-workspace-and-teamspace) Select one of the available workspaces and then a teamspace. ### 4. Select a list (or folder first) [Section titled “4. Select a list (or folder first)”](#4-select-a-list-or-folder-first) If the task list you are looking for is in a folder, select that folder first. Task lists that are not in a folder will be immediately listed in the dropdown. ### 5. Set statuses [Section titled “5. Set statuses”](#5-set-statuses) After selecting a task list, set the “initial”, “resolve”, and “reopen” statuses. ### 6. Tags [Section titled “6. Tags”](#6-tags) Add a list of comma-separated tags you wish to be associated when a task is created. ### 7. Save [Section titled “7. Save”](#7-save) That’s it! You can test the integration by clicking “Test”. Otherwise, just save it and you’re ready to go. # ClickUp Chat > Connect Honeybadger to ClickUp Chat to receive real-time application monitoring alerts in your team's chat workspace. Users with administrative privileges can find this integration below the list of personal alert integrations on the Alerts & Integrations tab of the Project Settings page. ## Setup [Section titled “Setup”](#setup) ### 1. Select the ClickUp Chat integration [Section titled “1. Select the ClickUp Chat integration”](#1-select-the-clickup-chat-integration) ![A screenshot of Honeybadger's ClickUp Chat integration setup page, showing the ClickUp logo and title 'Send alerts to ClickUp Chat channels'](/_astro/clickup-chat.D4Ik7IOw_1Mq99c.webp) ### 2. Connect via OAuth [Section titled “2. Connect via OAuth”](#2-connect-via-oauth) An OAuth dialog should appear. Log in to your account and grant access to one or more workspaces. You’ll then be redirected back to the integration page. ### 3. Select workspace and channel [Section titled “3. Select workspace and channel”](#3-select-workspace-and-channel) Select one of the available workspaces and then a channel where the bot will post. ### 4. Save [Section titled “4. Save”](#4-save) That’s it! You can test the integration by clicking “Test”. Otherwise, just save it and you’re ready to go. # Datadog > Connect Honeybadger to Datadog to send application events to your monitoring systems and create unified observability. Datadog is an enterprise platform for infrastructure and application monitoring. Connect Honeybadger to Datadog to surface errors, uptime events, and Insights alarms directly in your Datadog event stream—bringing developer-focused monitoring into your existing observability workflow. Users with administrative privileges can find this integration below the list of personal alert integrations on the Alerts & Integrations tab of the Project Settings page. ## Setup [Section titled “Setup”](#setup) ### 1. Install the integration in Datadog [Section titled “1. Install the integration in Datadog”](#1-install-the-integration-in-datadog) Click the **Install Integration** button on the [Honeybadger Integration Tile](https://app.datadoghq.com/account/settings#integrations/honeybadger) in Datadog. ### 2. Select the Datadog integration in Honeybadger [Section titled “2. Select the Datadog integration in Honeybadger”](#2-select-the-datadog-integration-in-honeybadger) ![datadog integration](/_astro/datadog.-N47MLgn_1LOziA.webp) ![datadog form](/_astro/datadog_form.CylJFRao_ZloKha.webp) ### 3. Set the API key [Section titled “3. Set the API key”](#3-set-the-api-key) You can generate a Datadog API key from your [Datadog organization settings page](https://app.datadoghq.com/organization-settings/api-keys). ### 4. Select region [Section titled “4. Select region”](#4-select-region) Choose from the following supported Datadog regions: US1, US3, US5, US1-FED, EU1, or AP1. ### 5. Select label (optional) [Section titled “5. Select label (optional)”](#5-select-label-optional) If you have multiple Datadog integrations, you can add a label to differentiate in the integration list view. ### 6. Choose whether to send metrics [Section titled “6. Choose whether to send metrics”](#6-choose-whether-to-send-metrics) Enabling the “Send metrics” option will result in the metric `honeybadger.occurrences_per_minute` to be reported to Datadog. ### 7. Save [Section titled “7. Save”](#7-save) That’s it! You can test the integration by clicking “Test”. Otherwise, just save it and you’re ready to go. # Discord > Connect Honeybadger to Discord to receive real-time application monitoring alerts directly in your team's channels. Users with administrative privileges can find this integration below the list of personal alert integrations on the Alerts & Integrations tab of the Project Settings page. ## Setup [Section titled “Setup”](#setup) ### 1. Select Discord from the integrations list [Section titled “1. Select Discord from the integrations list”](#1-select-discord-from-the-integrations-list) ![discord integration option](/_astro/discord.Umfl2FkU_Z1pjVkL.webp) ### 2. Enter your Discord webhook URL [Section titled “2. Enter your Discord webhook URL”](#2-enter-your-discord-webhook-url) ![discord integration form](/_astro/discord_form.gWAkjYca_1II5A5.webp) You can find your Discord Webhook URL under Channel Settings > Webhooks. ### 3. Save [Section titled “3. Save”](#3-save) That’s it! You can test the integration by clicking “Test”. Otherwise, just save it and you’re ready to go. # Email > Configure email notifications from Honeybadger to receive real-time application monitoring alerts and incident updates directly in your inbox. Users with administrative privileges can find this integration below the list of personal alert integrations on the Alerts & Integrations tab of the Project Settings page. Heads Up! This isn’t where you configure your personal email notifications. This email channel is specifically for integrating with services like Basecamp which consume inbound email. ## Setup [Section titled “Setup”](#setup) ### 1. Select the Email integration [Section titled “1. Select the Email integration”](#1-select-the-email-integration) ![email integration](/_astro/email.BXWHdmzl_Z1C6Ppe.webp) ![email form](/_astro/email_form.DNvUZNP3_hkRr1.webp) ### 2. Enter the email address [Section titled “2. Enter the email address”](#2-enter-the-email-address) It’s just an email address, folks. I’m sure you can figure it out. :wink: ### 3. Save [Section titled “3. Save”](#3-save) That’s it! Just save and you’re ready to go. # GitHub > Connect Honeybadger to GitHub to automatically create issues from errors and link commits to deployments. Users with administrative privileges can find this integration below the list of personal alert integrations on the Alerts & Integrations tab of the Project Settings page. ## Setup [Section titled “Setup”](#setup) ### 1. Select the GitHub integration [Section titled “1. Select the GitHub integration”](#1-select-the-github-integration) ![github integration](/_astro/github.36XIu_d3_Z1sJSlK.webp) ![github form](/_astro/github_form.HLT7MMZC_Z13n7nY.webp) ### 2. Authenticate [Section titled “2. Authenticate”](#2-authenticate) If you haven’t already granted our GitHub app access to your account, you will be prompted to do so. After that is done, you’ll be prompted to install our GitHub app in your GitHub repositories. Once that’s done, you’ll be able to create a new GitHub integration. ### 3. Set the repository name [Section titled “3. Set the repository name”](#3-set-the-repository-name) The repository name includes the account or organization name. For example, our gem is hosted at , so we’d enter “honeybadger-io/ruby” for the repo name to connect to that repository. ### 4. Enter labels (optional) [Section titled “4. Enter labels (optional)”](#4-enter-labels-optional) If you’d like us to label issues we create in GitHub, just enter a comma-separated list of tags here. ### 5. Title format (optional) [Section titled “5. Title format (optional)”](#5-title-format-optional) Customize the issue title, if you want, with our handy [custom formatters](/guides/integrations/#custom-formatters). ### 6. Send a detailed issue body (optional) [Section titled “6. Send a detailed issue body (optional)”](#6-send-a-detailed-issue-body-optional) By default, Honeybadger creates GitHub issues with a short backtrace excerpt and a link back to the fault in Honeybadger. Enable **Send a detailed issue body** to instead create issues with a full Markdown body that includes context, parameters, and the backtrace. Note that enabling this sends more potentially sensitive fault data to GitHub. ### 7. Save [Section titled “7. Save”](#7-save) That’s it! You can test the integration by clicking “Test”. Otherwise, just save it and you’re ready to go. # GitLab > Connect Honeybadger to GitLab to automatically create issues from errors and link commits to deployments. Users with administrative privileges can find this integration below the list of personal alert integrations on the Alerts & Integrations tab of the Project Settings page. ## Setup [Section titled “Setup”](#setup) ### 1. Select the GitLab integration [Section titled “1. Select the GitLab integration”](#1-select-the-gitlab-integration) ![gitlab integration](/_astro/gitlab.uP8sxxVx_Zjk7Se.webp) ![gitlab form](/_astro/gitlab_form.CDe1kHwI_Z20P7F2.webp) ### 2. Set the repository name [Section titled “2. Set the repository name”](#2-set-the-repository-name) The repository name includes the account or organization name. For example, if your project is hosted at , you’d enter “honeybadger-io/app” for the repo name to connect to that repository. ### 3. Enter labels (optional) [Section titled “3. Enter labels (optional)”](#3-enter-labels-optional) If you’d like us to label issues we create in GitLab, just enter a comma-separated list of tags here. ### 4. Enter server URL and personal access token (optional) [Section titled “4. Enter server URL and personal access token (optional)”](#4-enter-server-url-and-personal-access-token-optional) Our default configuration assumes you are hosting your code at gitlab.com and that we’ll use OAuth to connect to your account for creating issues. If you are using a self-hosted version of GitLab, then enter the URL of the GitLab installation and enter a personal access token. We will use that personal access token (generated in the GitLab UI at Settings -> Access Tokens) rather than OAuth. ### 5. Send a detailed issue body (optional) [Section titled “5. Send a detailed issue body (optional)”](#5-send-a-detailed-issue-body-optional) By default, Honeybadger creates GitLab issues with a short backtrace excerpt and a link back to the fault in Honeybadger. Enable **Send a detailed issue body** to instead create issues with a full Markdown body that includes context, parameters, and the backtrace. Note that enabling this sends more potentially sensitive fault data to GitLab. ### 6. Save [Section titled “6. Save”](#6-save) That’s it! You’ll be redirected to GitLab to grant OAuth access (if you left the server URL unchanged), or back to the integrations list if you used a custom server URL and a personal access token. Either way, once you’re back at the integrations list, you can Edit your new GitLab integration and use the Test button to test creating an issue in your repository. # Google Chat > Connect Honeybadger to Google Chat to receive real-time application monitoring alerts directly in your team's spaces. Users with administrative privileges can find this integration below the list of personal alert integrations on the Alerts & Integrations tab of the Project Settings page. ## Setup [Section titled “Setup”](#setup) ### 1. Select the Google Hangouts Chat integration [Section titled “1. Select the Google Hangouts Chat integration”](#1-select-the-google-hangouts-chat-integration) ![google hangouts chat integration](/_astro/google_hangouts_chat.CqG56YMn_1MaRvm.webp) ![google hangouts chat form](/_astro/google_hangouts_chat_form.CsqPt_oc_Mm9xS.webp) ### 2. Set the webhook URL [Section titled “2. Set the webhook URL”](#2-set-the-webhook-url) You can get the Webhook URL by clicking the channel name where you want the notifications to appear in the Hangouts Chat UI: ![Channel settings menu](/_astro/ghc-channel-settings.D-nsHMb9_FPFym.webp) Choosing the “Add webhooks” option presents a popup that allows you to create a new webhook. You can enter “Honeybadger” for the name, and grab a copy of HB’s [PNG bolt logo](https://honeybadger-static.s3.amazonaws.com/brand_assets/honeybadger_bolt/honeybadger_bolt.png) from our [brand assets page](https://www.honeybadger.io/assets/) for the avatar URL. Saving the webhook generates the webhook URL: ![Webhook popup](/_astro/ghc-webhook-url.DwXMKqqS_Z1QhwTa.webp) Choose the Copy link button from the actions menu to copy the URL to your clipboard, then enter that url in channel settings in the Honeybadger UI. ### 3. Save [Section titled “3. Save”](#3-save) That’s it! You can test the integration by clicking “Test”. Otherwise, just save it and you’re ready to go. ## Honeybadger chat bot [Section titled “Honeybadger chat bot”](#honeybadger-chat-bot) If you’d like to install our chat bot in Google Hangouts Chat, search for “Honeybadger” in the “Find people, rooms, bots” search box in the Chat UI. Adding our bot in Chat will prompt you to authorize the bot’s access to your Honeybadger account. Once you do that, you’ll be able to work with your Honeybadger data from within Chat. # ilert > Connect Honeybadger to ilert to receive real-time alerts and manage incidents from your on-call workflow. Users with administrative privileges can find this integration below the list of personal alert integrations on the Alerts & Integrations tab of the Project Settings page. [ilert](https://www.ilert.com/) provides alert routing, escalations, and on-call scheduling, ensuring critical issues always reach the right person at the right time. Honeybadger can send events to ilert to trigger alerts when your applications are having problems. ## Setup [Section titled “Setup”](#setup) ### 1. Select the ilert integration in Honeybadger [Section titled “1. Select the ilert integration in Honeybadger”](#1-select-the-ilert-integration-in-honeybadger) ![A screenshot of the ilert integration tile in Honeybadger's Alert Settings page](/_astro/ilert.DiqoaA6L_1La0iG.webp) ![A screenshot of the settings form in Honeybadger's alert settings for the ilter integration](/_astro/ilert_form.olqF___d_Z1skhcH.webp) ### 2. Create a Honeybadger alert source in ilert [Section titled “2. Create a Honeybadger alert source in ilert”](#2-create-a-honeybadger-alert-source-in-ilert) Follow ilert’s instructions to [create a new alert source for Honeybadger](https://docs.ilert.com/inbound-integrations/honeybadger), and copy the “Honeybadger URL” from the integration settings page. ### 3. Copy/paste the webhook URL from ilert into Honeybadger [Section titled “3. Copy/paste the webhook URL from ilert into Honeybadger”](#3-copypaste-the-webhook-url-from-ilert-into-honeybadger) Copy and paste the “Honeybadger URL” from the integration settings page in ilert into the “URL” field in Honeybadger. ### 4. Save [Section titled “4. Save”](#4-save) That’s it! You can test the integration by clicking “Test.” Otherwise, just save it and you’re ready to go. # incident.io > Connect Honeybadger to incident.io to automatically create incidents from critical errors and manage your response process. Users with administrative privileges can find this integration below the list of personal alert integrations on the Alerts & Integrations tab of the Project Settings page. ## Setup [Section titled “Setup”](#setup) ### 1. Create an API key in incident.io. [Section titled “1. Create an API key in incident.io.”](#1-create-an-api-key-in-incidentio) From your incident.io dashboard, go to Settings > API keys > Add new. Create an API key with the following permissions: * Create incidents * Edit incidents * Create and manage on-call resources ![incident.io API key permissions](/_astro/incident_io_api_key.3mCFih6P_1m89YN.webp) Make sure to copy the generated token. ### 2. In Honeybadger, locate the incident.io integration. [Section titled “2. In Honeybadger, locate the incident.io integration.”](#2-in-honeybadger-locate-the-incidentio-integration) In the project settings, click on the **Integrations** tab where you’ll find the incident.io integration. ![incident.io integration](/_astro/incident_io_integration.DTJabUcZ_ZzV27R.webp) ### 3. Fill in the required fields and save. [Section titled “3. Fill in the required fields and save.”](#3-fill-in-the-required-fields-and-save) Fill in API key field with the generated token from step 1 and then specify the alert source label. This will create an alert source in your incident.io account. ### 4. Test the integration. [Section titled “4. Test the integration.”](#4-test-the-integration) Click on the “Test this integration” button to send a test notification to your incident.io account. This is a great way to ensure that everything is set up correctly before you start receiving real notifications. ![incident.io notification](/_astro/incident_io_notification.DPbiKn2T_2dMqIt.webp) # Instatus > Connect Honeybadger to Instatus to automatically update your status page when critical errors and application issues are detected. Users with administrative privileges can find this integration below the list of personal alert integrations on the Alerts & Integrations tab of the Project Settings page. ## Setup [Section titled “Setup”](#setup) ### 1. Select the Instatus integration [Section titled “1. Select the Instatus integration”](#1-select-the-instatus-integration) ![instatus integration](/_astro/instatus.xbFJavY6_Z20OQLz.webp) ![instatus form](/_astro/instatus_form.DbvCzBZ9_Z1boOx0.webp) ### 2. Set the webhook URL [Section titled “2. Set the webhook URL”](#2-set-the-webhook-url) Go to Instatus dashboard, under Monitors, select Custom service (webhook). Copy your component’s webhook URL, and then enter that URL into the Webhook URL field in the Honeybadger UI. ### 3. Save [Section titled “3. Save”](#3-save) That’s it! You can test the integration by clicking “Test”. Otherwise, just save it and you’re ready to go. # Intercom > Connect Honeybadger to Intercom to track errors affecting specific users and provide better customer support. ## Setup [Section titled “Setup”](#setup) ### 1. Select the Intercom integration [Section titled “1. Select the Intercom integration”](#1-select-the-intercom-integration) ![intercom integration](/_astro/intercom.CSk3cSAH_2ufRl0.webp) ![intercom form](/_astro/intercom_form.CKZU_nAd_ZIBnEQ.webp) ### 2. Enter your context field [Section titled “2. Enter your context field”](#2-enter-your-context-field) This is the field that you set in the context in your application with the user ID that is associated with your Intercom users. For example, if you are identifying users with Intercom with `current_user.id`, and you have `current_user.id` in the `user_id` field of your context, then enter `user_id` in this field. ### 3. Connect via OAuth [Section titled “3. Connect via OAuth”](#3-connect-via-oauth) Select the “Connect OAuth” button and give access to our app. ### 4. Save [Section titled “4. Save”](#4-save) That’s it! You can test the integration by clicking “Test”. Otherwise, just save it and you’re ready to go. ## What gets sent to Intercom [Section titled “What gets sent to Intercom”](#what-gets-sent-to-intercom) When an error occurs, Honeybadger sends an event for the affected user with the following payload: | Field | Value | | ------------ | --------------------------------------------------------- | | `event_name` | `encountered-error` | | `user_id` | The value from your configured context field (see step 2) | | `created_at` | Unix timestamp in seconds since the epoch (UTC) | | `metadata` | `{ "url": "" }` | You can use this event in Intercom to build segments (e.g. “users who hit an error in the last 7 days”) or to drive a Workflow that sets a custom attribute on the user; for example, flipping a `has_honeybadger_error` attribute to `true` whenever the event fires. # Jira & Jira Cloud > Connect Honeybadger to Jira to automatically create tickets from errors and track bug fixes in your project workflow. Users with administrative privileges can find this integration below the list of personal alert integrations on the Alerts & Integrations tab of the Project Settings page. We currently have two different service integrations for Jira. Both versions provide the same features, but differ in the way they authenticate requests. ## Which integration to choose? [Section titled “Which integration to choose?”](#which-integration-to-choose) If you are running a Jira Server, then the original [Jira](#jira) Integration is your only option. You *may also* use this integration for Jira Cloud, but we don’t recommend it as it uses Basic Authentication which requires storing credentials to make a API request. If you are using Jira Cloud, then we highly recommend the newer [Jira Cloud](#jira-cloud) integration as this uses OAuth and only requires us to keep a token for authentication. ## Jira [Section titled “Jira”](#jira) ### 1. Select the Jira integration [Section titled “1. Select the Jira integration”](#1-select-the-jira-integration) ![jira integration](/_astro/jira.BQXQ3WY-_1p5Js9.webp) ![jira form](/_astro/jira_form.CkscybyW_Z2f0k2q.webp) ### 2. Configure [Section titled “2. Configure”](#2-configure) Here’s an overview of the options: * The **username** and **password** will be your login for Jira. * The **server url** is the subdomain of your Jira instance, such as “”. Don’t forget the “https\://”. * The **project key** was setup when you created the project. It can be found (on Jira) from Project Overview > Administration > Edit Project. * The **transition** ID’s can be set in your workflows on Jira when viewed in text mode. ID’s are unique, so make sure there are no conflicting values. * **Send a detailed issue description** controls how much fault data is included in new issues. By default, Honeybadger sends a short backtrace excerpt and a link back to the fault in Honeybadger. Enable this option to instead send a detailed Jira-wiki description that includes context, parameters, and the backtrace. Note that enabling this sends more potentially sensitive fault data to Jira. ### 3. Save [Section titled “3. Save”](#3-save) That’s it! You can test the integration by clicking “Test”. Otherwise, just save it and you’re ready to go. ## Jira Cloud [Section titled “Jira Cloud”](#jira-cloud) ### 1. Select the Jira Cloud integration [Section titled “1. Select the Jira Cloud integration”](#1-select-the-jira-cloud-integration) ![jira Cloud integration](/_astro/jira_cloud.CfKO0xLy_Z2d4grz.webp) ![jira Cloud form](/_astro/jira_cloud_form.CR3wyIIJ_T93no.webp) ### 2. Configure [Section titled “2. Configure”](#2-configure-1) Here’s an overview of the options: * The **project key** was setup when you created the project. It can be found (on Jira) from Project Overview > Administration > Edit Project. * The **transition** ID’s can be set in your workflows on Jira when viewed in text mode. ID’s are unique, so make sure there are no conflicting values. * **Send a detailed issue description** controls how much fault data is included in new issues. By default, Honeybadger sends a short backtrace excerpt and a link back to the fault in Honeybadger. Enable this option to instead send a detailed Jira-wiki description that includes context, parameters, and the backtrace. Note that enabling this sends more potentially sensitive fault data to Jira. ### 3. Save [Section titled “3. Save”](#3-save-1) Click “Save” to be sent to Atlassian to authorize our Honeybadger App. That’s it! Once we have an OAuth connection to your instance you can test the integration clicking “Test”. # Linear > Connect Honeybadger to Linear to automatically create issues from errors and track bug fixes in your project workflow. Users with administrative privileges can find this integration below the list of personal alert integrations on the Alerts & Integrations tab of the Project Settings page. ## Setup [Section titled “Setup”](#setup) ### 1. Select the Linear integration [Section titled “1. Select the Linear integration”](#1-select-the-linear-integration) ![linear integration](/_astro/linear.GzJ5c0yD_1Oissp.webp) ### 2. Connect via OAuth [Section titled “2. Connect via OAuth”](#2-connect-via-oauth) An OAuth dialog should appear. Log in to your account, and give access to our app. ![linear form](/_astro/linear_form.DmR5n7P8_2usvMH.webp) ### 3. Select team [Section titled “3. Select team”](#3-select-team) We gathered all teams associated with your account. Select the team you want to integrate with. ### 4. Project & labels (optional) [Section titled “4. Project & labels (optional)”](#4-project--labels-optional) We can associate a project or any labels when we create your issue. ### 5. Unresolved state [Section titled “5. Unresolved state”](#5-unresolved-state) This is both the initial and the state that we transition your issue back to if it is reopened. ### 6. Resolved state [Section titled “6. Resolved state”](#6-resolved-state) The issue state for resolved errors. ### 7. Save [Section titled “7. Save”](#7-save) That’s it! You can test the integration by clicking “Test”. Otherwise, just save it and you’re ready to go. # Mattermost > Connect Honeybadger to Mattermost to receive real-time application monitoring alerts directly in your team's chat channels. Users with administrative privileges can find this integration below the list of personal alert integrations on the Alerts & Integrations tab of the Project Settings page. ## Setup [Section titled “Setup”](#setup) ### 1. Select the Mattermost integration [Section titled “1. Select the Mattermost integration”](#1-select-the-mattermost-integration) ![mattermost integration](/_astro/mattermost.CZub2Sjr_eqf0b.webp) ![mattermost form](/_astro/mattermost_form.DlPzB8Zq_2qDl0j.webp) ### 2. Set the webhook URL [Section titled “2. Set the webhook URL”](#2-set-the-webhook-url) Choose Integrations from the Mattermost sidebar menu, then Incoming Webhooks, and click the “Add Incoming Webhook” button. Enter the options you want, then save the new webhook. Copy the URL displayed on the next page, and then enter that URL into the Webhook URL field in the Honeybadger UI. ### 3. Save [Section titled “3. Save”](#3-save) That’s it! You can test the integration by clicking “Test”. Otherwise, just save it and you’re ready to go. # Microsoft Teams > Connect Honeybadger to Microsoft Teams to receive real-time application monitoring alerts in your team collaboration workspace. Users with administrative privileges can find this integration below the list of personal alert integrations on the Alerts & Integrations tab of the Project Settings page. ## Setup [Section titled “Setup”](#setup) ### 1. Select the Microsoft Teams integration [Section titled “1. Select the Microsoft Teams integration”](#1-select-the-microsoft-teams-integration) ![teams integration](/_astro/microsoft_teams.BC7MszlK_Z1P8Ftv.webp) ![teams form](/_astro/microsoft_teams_form.CACAGgqL_ZnNs5B.webp) ### 2. Set the webhook URL [Section titled “2. Set the webhook URL”](#2-set-the-webhook-url) Choose Connectors from the popup channel menu, then Incoming Webhook, and click “Configure” or “Add”. Enter the options you want, then save the new webhook. Copy the provided URL, and then enter that URL into the Webhook URL field in the Honeybadger UI. ### 3. Save [Section titled “3. Save”](#3-save) That’s it! You can test the integration by clicking “Test”. Otherwise, just save it and you’re ready to go. # OpsGenie > Connect Honeybadger to OpsGenie to route critical errors and application issues through your incident management and on-call alerting system. Users with administrative privileges can find this integration below the list of personal alert integrations on the Alerts & Integrations tab of the Project Settings page. ## Setup [Section titled “Setup”](#setup) ### 1. Select the OpsGenie integration [Section titled “1. Select the OpsGenie integration”](#1-select-the-opsgenie-integration) ![opsgenie integration](/_astro/opsgenie.GE-hA0GM_k97Hy.webp) ![opsgenie form](/_astro/opsgenie_form.CC1z4Qpy_1P8Xak.webp) ### 2. Set the API key [Section titled “2. Set the API key”](#2-set-the-api-key) Caution Please note that the OpsGenie integration labeled “Honeybadger” is an older version that doesn’t currently support all the events we send. You can generate a OpsGenie API key by creating an [API Integration](https://support.atlassian.com/opsgenie/docs/create-a-default-api-integration/) by logging in to OpsGenie then going to Settings - Integrations and selecting “API”. ![opsgenie integration select](/_astro/opsgenie-integration-select.CBEEvdhW_Z1oe6xL.webp) ### 3. Select region [Section titled “3. Select region”](#3-select-region) We can send to both US and EU regions. ### 4. Select label (optional) [Section titled “4. Select label (optional)”](#4-select-label-optional) If you have multiple OpsGenie integrations, you can add a label to differentiate in the integration list view. ### 5. Save [Section titled “5. Save”](#5-save) That’s it! You can test the integration by clicking “Test”. Otherwise, just save it and you’re ready to go. ## Configuring OpsGenie alerts [Section titled “Configuring OpsGenie alerts”](#configuring-opsgenie-alerts) OpsGenie provides the option to route the alerts based on the kind of event that is reported to OpsGenie, and elements from the event payloads can be used in the alert rules. For example, when a check-in fails to report on time, Honeybadger will send the “Check-In Missing” event to OpsGenie. You can use the **Details (key-value)** condition to match that event by specifying “Event” as the **Key** and “Check-In Missing” as the **Value**: ![opsgenie alert configuration screen](/_astro/opsgenie-alert-filters.JR_yFJt8_Z7iPjz.webp) ## Event Payloads [Section titled “Event Payloads”](#event-payloads) The following events are supported by the OpsGenie integration: ### `Assigned` [Section titled “Assigned”](#assigned) Sent when an error is assigned to a user. **Additional Details keys:** `Error Details`, `Project`, `Environment`, `Assignee Name`, `Assignee Email` ### `Cert Will Expire` [Section titled “Cert Will Expire”](#cert-will-expire) Sent when an SSL certificate is about to expire. **Additional Details keys:** `Project`, `Name`, `URL` ### `Check-In Missing` [Section titled “Check-In Missing”](#check-in-missing) Sent when an expected check-in is missing. **Additional Details keys:** `Check-In Details`, `Project`, `Name` ### `Check-In Reporting` [Section titled “Check-In Reporting”](#check-in-reporting) Sent when a check-in reports successfully. **Additional Details keys:** `Check-In Details`, `Project`, `Name` ### `Commented` [Section titled “Commented”](#commented) Sent when a comment is added to an error. **Additional Details keys:** `Error Details`, `Project`, `Environment`, `Author` ### `Deployed` [Section titled “Deployed”](#deployed) Sent when a deployment is recorded. **Additional Details keys:** `Project`, `Environment`, `Revision`, `Repository` ### `Down` [Section titled “Down”](#down) Sent when an uptime check fails. **Additional Details keys:** `Outage Details`, `Project`, `Name`, `URL` ### `Occurred` [Section titled “Occurred”](#occurred) Sent when an error occurs. **Additional Details keys:** `Error Details`, `Project`, `Environment` ### `Rate Exceeded` [Section titled “Rate Exceeded”](#rate-exceeded) Sent when error rate threshold is exceeded. **Additional Details keys:** `Error Details`, `Project`, `Environment` ### `Resolved` [Section titled “Resolved”](#resolved) Sent when an error is marked as resolved. **Additional Details keys:** `Error Details`, `Project`, `Environment` ### `Unresolved` [Section titled “Unresolved”](#unresolved) Sent when a resolved error occurs again. **Additional Details keys:** `Error Details`, `Project`, `Environment` ### `Up` [Section titled “Up”](#up) Sent when an uptime check succeeds after being down. **Additional Details keys:** `Outage Details`, `Project`, `Name`, `URL` # PagerDuty > Connect Honeybadger to PagerDuty to route critical errors and application issues through your incident response workflow and on-call schedules. Users with administrative privileges can find this integration below the list of personal alert integrations on the Alerts & Integrations tab of the Project Settings page. ## Setup [Section titled “Setup”](#setup) ### 1. Select the PagerDuty integration [Section titled “1. Select the PagerDuty integration”](#1-select-the-pagerduty-integration) ![pagerduty integration](/_astro/pagerduty.CFkjcLMa_iuif4.webp) ![pagerduty form](/_astro/pagerduty_form.DWH8Vkny_Z2lHwUw.webp) ### 2. Set the API key [Section titled “2. Set the API key”](#2-set-the-api-key) You can generate an integration key for Honeybadger by logging in to PagerDuty then clicking on “Add New Service” and choosing “Honeybadger” as the service type. [Here’s a walkthrough](https://www.pagerduty.com/docs/guides/honeybadger-integration-guide/). ### 3. Save [Section titled “3. Save”](#3-save) That’s it! You can test the integration by clicking “Test”. Otherwise, just save it and you’re ready to go. ## Event rules in PagerDuty [Section titled “Event rules in PagerDuty”](#event-rules-in-pagerduty) You can use PagerDuty’s [event rules](https://support.pagerduty.com/docs/event-management#section-suppression-and-event-rules) feature to suppress an event or change its severity based on data sent from Honeybadger. For instance, when an exception is sent to PagerDuty, you could set the severity to “critical” for a specific environment when `fault.environment` equals “production”. The custom data payloads sent from Honeybadger are the same as our [webhook event payloads](/guides/integrations/webhook/#event-payloads). ## Upgrading a legacy PagerDuty integration [Section titled “Upgrading a legacy PagerDuty integration”](#upgrading-a-legacy-pagerduty-integration) If your integration is marked “legacy”, then you should upgrade by deleting your existing integration and then creating a new integration following the instructions above. If you use Event Rules in PagerDuty, see the next paragraph. The custom data payload sent to PagerDuty has changed to match our [webhook event payloads](/guides/integrations/webhook/#event-payloads). If you use [event rules in PagerDuty](#event-rules-in-pagerduty) based on the old payload, you will need to update your rules. # PagerTree > Connect Honeybadger to PagerTree to route critical errors and application issues through your incident management and on-call system. Users with administrative privileges can find this integration below the list of personal alert integrations on the Alerts & Integrations tab of the Project Settings page. ## Setup [Section titled “Setup”](#setup) ### 1. Select the PagerTree integration [Section titled “1. Select the PagerTree integration”](#1-select-the-pagertree-integration) ![PagerTree integration](/_astro/pagertree.CU-SYPZ9_Z2d7xdG.webp) ![PagerTree form](/_astro/pagertree_form.BjJGu4Du_Z2dj0uc.webp) ### 2. Set the integration URL [Section titled “2. Set the integration URL”](#2-set-the-integration-url) Follow the steps outlined in the [PagerTree documentation](https://pagertree.com/knowledge-base/integration-honeybadger/) to get the Endpoint URL. Enter that URL into the URL field in the Honeybadger UI. ### 3. Save [Section titled “3. Save”](#3-save) That’s it! You can test the integration by clicking “Test”. Otherwise, just save it and you’re ready to go. # Error assigned event payload > Sent when an error is assigned to a user. Sent when an error is assigned to a user. ```json { "event": "assigned", "message": "[Testy McTestFace/production] ActiveRecord::StatementInvalid assigned to George Jetson by Ben", "actor": { "id": 1, "email": "ben@example.com", "name": "Ben" }, "fault": { "project_id": 123321, "klass": "ActiveRecord::StatementInvalid", "component": "search", "action": "index", "environment": "production", "resolved": true, "ignored": false, "created_at": "2023-01-31T03:10:01.126549Z", "comments_count": 3, "message": "PG::SyntaxError: ERROR: syntax error in tsquery: \"厄瓜多尔Google霸屏【TG飞机:@bapingseo】腾讯视频谷歌完全无广告版【TG飞机:@bapingseo】不到外贸行业运营推广计划怎么写谷歌相机的广告怎么关掉?Em0atRS3g3F4.html\"", "notices_count": 5514, "last_notice_at": "2023-02-06T12:20:01.772130Z", "tags": [], "id": 42, "assignee": "george@example.com", "url": "https://app.honeybadger.io/projects/123321/faults/42", "deploy": { "environment": "production", "revision": "dd2ce1c1f5be3532e10fadf2224a19847f0c62e9", "repository": "https://github.com/spacely/testy-mctestface", "local_username": "heroku-redis@addons.heroku.com", "created_at": "2023-02-01T05:12:31.417405Z", "changelog": [], "url": "https://github.com/spacely/testy-mctestface/compare/3e51742fd5f43197891a67b74a54903513e59ce5...dd2ce1c1f5be3532e10fadf2224a19847f0c62e9" } }, "assignee": { "id": 99, "email": "george@example.com", "name": "George Jetson" } } ``` # Certificate expiration event payload > Sent when an SSL certificate is about to expire. Sent when an SSL certificate is about to expire. ```json { "event": "cert_will_expire", "message": "[My Private Project] SSL certificate for gerlach-bergnaum.net will expire on 11/2/2023 11:22:41 UTC", "project": { "id": 4, "name": "My Private Project" }, "site": { "id": "f0cacf21-8446-4545-9544-f764b9470c29", "name": "gerlach-bergnaum.net", "url": "http://steuber-ernser.com/martha_crona", "frequency": 5, "match_type": "success", "match": null, "state": "up", "active": true, "last_checked_at": "2023-07-21 17:46:24 UTC", "retries": 0, "proxy": 0, "cert_will_expire_at": "2023-11-02 11:22:41 UTC", "details_url": "http://localhost:3000/projects/4/sites/f0cacf21-8446-4545-9544-f764b9470c29" } } ``` # Check-in missing event payload > Sent when an expected check-in is missing. Sent when an expected check-in is missing. ```json { "event": "check_in_missing", "message": "[Voyager Test] MISSING: Voyager hasn't checked in for 4 years", "project": { "id": 67747, "name": "Voyager Test", "created_at": "2019-12-23T21:28:16.571090Z", "disable_public_links": false, "pivotal_project_id": null, "asana_workspace_id": null, "token": "abcd1234", "github_project": null, "environments": [ { "id": 94721, "project_id": 67747, "name": "development", "notifications": true, "created_at": "2020-01-08T16:00:02.343155Z", "updated_at": "2020-01-08T16:00:02.343155Z" }, { "id": 94355, "project_id": 67747, "name": "local", "notifications": true, "created_at": "2019-12-23T21:28:30.733084Z", "updated_at": "2019-12-23T21:28:30.733084Z" } ], "owner": { "id": 1, "email": "ben@example.com", "name": "Spacely Sprockets" }, "last_notice_at": "2020-11-10T20:07:04.000000Z", "earliest_notice_at": "2023-05-03T19:39:33.365387Z", "unresolved_fault_count": 3, "fault_count": 6, "active": true, "users": [ { "id": 1, "email": "ben@example.com", "name": "Ben" } ], "sites": [], "team_id": null }, "check_in": { "state": "missing", "schedule_type": "simple", "reported_at": "2019-12-23T21:39:37.124397Z", "expected_at": "2023-10-30T19:42:28.853152Z", "missed_count": 33385, "grace_period": "00:00:00", "id": "XYZLOL", "name": "Voyager", "slug": null, "url": "https://api.honeybadger.io/v1/check_in/XYZLOL", "details_url": "https://app.honeybadger.io/projects/67747/check_ins", "report_period": "1 hour" } } ``` # Check-in reporting event payload > Sent when a check-in reports successfully. Sent when a check-in reports successfully. ```json { "event": "check_in_reporting", "message": "[Voyager Test] REPORTING: Voyager is reporting again", "project": { "id": 67747, "name": "Voyager Test", "created_at": "2019-12-23T21:28:16.571090Z", "disable_public_links": false, "pivotal_project_id": null, "asana_workspace_id": null, "token": "abcd1234", "github_project": null, "environments": [ { "id": 94721, "project_id": 67747, "name": "development", "notifications": true, "created_at": "2020-01-08T16:00:02.343155Z", "updated_at": "2020-01-08T16:00:02.343155Z" }, { "id": 94355, "project_id": 67747, "name": "local", "notifications": true, "created_at": "2019-12-23T21:28:30.733084Z", "updated_at": "2019-12-23T21:28:30.733084Z" } ], "owner": { "id": 1, "email": "ben@example.com", "name": "Spacely Sprockets" }, "last_notice_at": "2020-11-10T20:07:04.000000Z", "earliest_notice_at": "2023-05-03T19:39:54.491724Z", "unresolved_fault_count": 3, "fault_count": 6, "active": true, "users": [ { "id": 1, "email": "ben@example.com", "name": "Ben" } ], "sites": [], "team_id": null }, "check_in": { "state": "missing", "schedule_type": "simple", "reported_at": "2019-12-23T21:39:37.124397Z", "expected_at": "2023-10-30T19:42:28.853152Z", "missed_count": 33385, "grace_period": "00:00:00", "id": "XYZLOL", "name": "Voyager", "slug": null, "url": "https://api.honeybadger.io/v1/check_in/XYZLOL", "details_url": "https://app.honeybadger.io/projects/67747/check_ins", "report_period": "1 hour" } } ``` # Error Comment event payload > Sent when a comment is added to an error. Sent when a comment is added to an error. ```json { "event": "commented", "message": "[Testy McTestFace/production] Ben commented on ActiveRecord::StatementInvalid: First post!", "actor": { "id": 1, "email": "ben@example.com", "name": "Ben" }, "fault": { "project_id": 123321, "klass": "ActiveRecord::StatementInvalid", "component": "search", "action": "index", "environment": "production", "resolved": true, "ignored": false, "created_at": "2023-01-31T03:10:01.126549Z", "comments_count": 3, "message": "PG::SyntaxError: ERROR: syntax error in tsquery: \"厄瓜多尔Google霸屏【TG飞机:@bapingseo】腾讯视频谷歌完全无广告版【TG飞机:@bapingseo】不到外贸行业运营推广计划怎么写谷歌相机的广告怎么关掉?Em0atRS3g3F4.html\"", "notices_count": 5514, "last_notice_at": "2023-02-06T12:20:01.772130Z", "tags": [], "id": 42, "assignee": "george@example.com", "url": "https://app.honeybadger.io/projects/123321/faults/42", "deploy": { "environment": "production", "revision": "dd2ce1c1f5be3532e10fadf2224a19847f0c62e9", "repository": "https://github.com/spacely/testy-mctestface", "local_username": "heroku-redis@addons.heroku.com", "created_at": "2023-02-01T05:12:31.417405Z", "changelog": [], "url": "https://github.com/spacely/testy-mctestface/compare/3e51742fd5f43197891a67b74a54903513e59ce5...dd2ce1c1f5be3532e10fadf2224a19847f0c62e9" } }, "comment": { "id": 7075, "fault_id": 2653, "event": null, "source": "web", "created_at": "2012-11-29T03:44:09.381543Z", "email": null, "author": "Starr", "body": "You might try shaving the yaks outside of the transaction." } } ``` # Deployed event payload > Sent when a deployment is recorded. Sent when a deployment is recorded. ```json { "event": "deployed", "message": "[Testy McTestFace/production] ben@example.com deployed Testy McTestFace to production", "project": { "id": 123321, "name": "Testy McTestFace", "created_at": "2017-08-30T12:54:33.156695Z", "disable_public_links": false, "pivotal_project_id": null, "asana_workspace_id": null, "token": "zzz111", "github_project": "spacely/testy-mctestface", "environments": [ { "id": 68210, "project_id": 123321, "name": "production", "notifications": true, "created_at": "2017-09-05T06:10:19.057794Z", "updated_at": "2017-09-05T06:10:19.057794Z" }, { "id": 68074, "project_id": 123321, "name": "development", "notifications": true, "created_at": "2017-08-30T12:55:29.297392Z", "updated_at": "2017-08-30T12:55:29.297392Z" } ], "owner": { "id": 1, "email": "ben@example.com", "name": "Spacely Sprockets" }, "last_notice_at": "2023-10-30T19:29:08.000000Z", "earliest_notice_at": "2023-05-03T19:50:44.677809Z", "unresolved_fault_count": 102, "fault_count": 925, "active": true, "users": [ { "id": 1, "email": "ben@example.com", "name": "Ben" }, { "id": 99, "email": "george@example.com", "name": "George Jetson" } ], "sites": [], "team_id": 1 }, "deploy": { "environment": "production", "revision": "d5b13eea87cd98b45e51b92d6382198f4c102d6d", "repository": "https://github.com/spacely/testy-mctestface", "local_username": "ben@example.com", "created_at": "2023-10-30T15:10:40.754174Z", "changelog": [], "url": "https://github.com/spacely/testy-mctestface/compare/5c9c677d9bb17cb3a211d1f65701b866e9ece5a7...d5b13eea87cd98b45e51b92d6382198f4c102d6d" } } ``` # Site down event payload > Sent when an uptime check fails. Sent when an uptime check fails. ```json { "event": "down", "message": "[Testy McTestFace] Heroku is down.", "project": { "id": 123321, "name": "Testy McTestFace", "created_at": "2017-08-30T12:54:33.156695Z", "disable_public_links": false, "pivotal_project_id": null, "asana_workspace_id": null, "token": "zzz111", "github_project": "spacely/testy-mctestface", "environments": [ { "id": 68210, "project_id": 123321, "name": "production", "notifications": true, "created_at": "2017-09-05T06:10:19.057794Z", "updated_at": "2017-09-05T06:10:19.057794Z" }, { "id": 68074, "project_id": 123321, "name": "development", "notifications": true, "created_at": "2017-08-30T12:55:29.297392Z", "updated_at": "2017-08-30T12:55:29.297392Z" } ], "owner": { "id": 1, "email": "ben@example.com", "name": "Spacely Sprockets" }, "last_notice_at": "2023-10-30T19:29:08.000000Z", "earliest_notice_at": "2023-05-03T19:38:32.092931Z", "unresolved_fault_count": 102, "fault_count": 925, "active": true, "users": [ { "id": 1, "email": "ben@example.com", "name": "Ben" }, { "id": 99, "email": "george@example.com", "name": "George Jetson" } ], "sites": [], "team_id": 1 }, "site": { "id": "c42c4c0a-6e3d-4303-9769-549ed2a5818e", "name": "Heroku", "url": "https://example.com", "frequency": 5, "match_type": "success", "match": null, "state": "down", "active": true, "last_checked_at": "2023-10-30T19:34:08.150725Z", "retries": 0, "proxy": 4, "cert_will_expire_at": null, "details_url": "https://app.honeybadger.io/projects/123321/sites/c42c4c0a-6e3d-4303-9769-549ed2a5818e" }, "outage": { "down_at": "2023-07-17T15:46:52.384701Z", "up_at": "2023-07-17T15:51:56.063948Z", "status": null, "reason": "Connection timed out", "headers": null, "details_url": "https://app.honeybadger.io/projects/123321/sites/c42c4c0a-6e3d-4303-9769-549ed2a5818e" } } ``` # Occurred event payload > Sent when an error occurs. Sent when an error occurs. ```json { "event": "occurred", "message": "[Testy McTestFace/production] ActiveRecord::NoDatabaseError: We could not find your database: d6ipl26lboesdi. Which can be found in the database configuration file located at config/database.yml.\n\nTo resolve this issue:\n\n- Did you create the database for th...", "project": { "id": 123321, "name": "Testy McTestFace", "created_at": "2017-08-30T12:54:33.156695Z", "disable_public_links": false, "pivotal_project_id": null, "asana_workspace_id": null, "token": "zzz111", "github_project": "spacely/testy-mctestface", "environments": [ { "id": 68210, "project_id": 123321, "name": "production", "notifications": true, "created_at": "2017-09-05T06:10:19.057794Z", "updated_at": "2017-09-05T06:10:19.057794Z" }, { "id": 68074, "project_id": 123321, "name": "development", "notifications": true, "created_at": "2017-08-30T12:55:29.297392Z", "updated_at": "2017-08-30T12:55:29.297392Z" } ], "owner": { "id": 1, "email": "ben@example.com", "name": "Spacely Sprockets" }, "last_notice_at": "2023-10-30T19:29:08.000000Z", "earliest_notice_at": "2023-05-03T19:35:56.783102Z", "unresolved_fault_count": 102, "fault_count": 925, "active": true, "users": [ { "id": 1, "email": "ben@example.com", "name": "Ben" }, { "id": 99, "email": "george@example.com", "name": "George Jetson" } ], "sites": [ { "id": "c42c4c0a-6e3d-4303-9769-549ed2a5818e", "active": true, "last_checked_at": "2023-10-30T19:34:08.150725Z", "name": "Heroku", "state": "up", "url": "https://example.com" } ], "team_id": 1 }, "fault": { "project_id": 123321, "klass": "ActiveRecord::NoDatabaseError", "component": "pages", "action": "home", "environment": "production", "resolved": false, "ignored": false, "created_at": "2023-10-13T18:07:55.692256Z", "comments_count": 0, "message": "We could not find your database: d6ipl26lboesdi. Which can be found in the database configuration file located at config/database.yml.\n\nTo resolve this issue:\n\n- Did you create the database for this app, or delete it? You may need to create your database.\n- Has the database name changed? Check your database.yml config has the correct database name.\n\nTo create your database, run:\n\n bin/rails db:create", "notices_count": 6, "last_notice_at": "2023-10-13T18:08:10.000000Z", "tags": [], "id": 101337516, "assignee": null, "url": "https://app.honeybadger.io/projects/123321/faults/101337516", "deploy": { "environment": "production", "revision": "0eaf61a9ec756be9f4bb511ad71b37baaa9b73ba", "repository": "https://github.com/spacely/testy-mctestface", "local_username": "ben@example.com", "created_at": "2023-10-06T20:52:51.878336Z", "changelog": [], "url": "https://github.com/spacely/testy-mctestface/compare/d4f90c876adf4a108ebb9a6f47b5562b59578d97...0eaf61a9ec756be9f4bb511ad71b37baaa9b73ba" } }, "notice": { "id": 1013375161697220500, "environment": {}, "created_at": "2023-10-13T18:08:10.141219Z", "message": null, "token": "babe1d9d-67e3-4438-8c57-c544cea24ffb", "fault_id": 101337516, "request": { "url": "https://example.com/", "component": "pages", "action": "home", "params": { "controller": "pages", "action": "home" }, "session": {}, "context": {} }, "backtrace": [ { "number": "81", "file": "[GEM_ROOT]/gems/activerecord-7.0.7.2/lib/active_record/connection_adapters/postgresql_adapter.rb", "method": "rescue in new_client", "source": { "79": " rescue ::PG::Error => error\n", "80": " if conn_params && conn_params[:dbname] && error.message.include?(conn_params[:dbname])\n", "81": " raise ActiveRecord::NoDatabaseError.db_error(conn_params[:dbname])\n", "82": " elsif conn_params && conn_params[:user] && error.message.include?(conn_params[:user])\n", "83": " raise ActiveRecord::DatabaseConnectionError.username_error(conn_params[:user])\n" }, "context": "all" }, { "number": "77", "file": "[GEM_ROOT]/gems/activerecord-7.0.7.2/lib/active_record/connection_adapters/postgresql_adapter.rb", "method": "new_client", "source": { "75": "\n", "76": " class << self\n", "77": " def new_client(conn_params)\n", "78": " PG.connect(**conn_params)\n", "79": " rescue ::PG::Error => error\n" }, "context": "all" }, { "number": "37", "file": "[GEM_ROOT]/gems/activerecord-7.0.7.2/lib/active_record/connection_adapters/postgresql_adapter.rb", "method": "postgresql_connection", "source": { "35": "\n", "36": " ConnectionAdapters::PostgreSQLAdapter.new(\n", "37": " ConnectionAdapters::PostgreSQLAdapter.new_client(conn_params),\n", "38": " logger,\n", "39": " conn_params,\n" }, "context": "all" }, { "number": "656", "file": "[GEM_ROOT]/gems/activerecord-7.0.7.2/lib/active_record/connection_adapters/abstract/connection_pool.rb", "method": "public_send", "source": { "654": "\n", "655": " def new_connection\n", "656": " Base.public_send(db_config.adapter_method, db_config.configuration_hash).tap do |conn|\n", "657": " conn.check_version\n", "658": " end\n" }, "context": "all" }, { "number": "656", "file": "[GEM_ROOT]/gems/activerecord-7.0.7.2/lib/active_record/connection_adapters/abstract/connection_pool.rb", "method": "new_connection", "source": { "654": "\n", "655": " def new_connection\n", "656": " Base.public_send(db_config.adapter_method, db_config.configuration_hash).tap do |conn|\n", "657": " conn.check_version\n", "658": " end\n" }, "context": "all" }, { "number": "700", "file": "[GEM_ROOT]/gems/activerecord-7.0.7.2/lib/active_record/connection_adapters/abstract/connection_pool.rb", "method": "checkout_new_connection", "source": { "698": " def checkout_new_connection\n", "699": " raise ConnectionNotEstablished unless @automatic_reconnect\n", "700": " new_connection\n", "701": " end\n", "702": "\n" }, "context": "all" }, { "number": "679", "file": "[GEM_ROOT]/gems/activerecord-7.0.7.2/lib/active_record/connection_adapters/abstract/connection_pool.rb", "method": "try_to_checkout_new_connection", "source": { "677": " # if successfully incremented @now_connecting establish new connection\n", "678": " # outside of synchronized section\n", "679": " conn = checkout_new_connection\n", "680": " ensure\n", "681": " synchronize do\n" }, "context": "all" }, { "number": "640", "file": "[GEM_ROOT]/gems/activerecord-7.0.7.2/lib/active_record/connection_adapters/abstract/connection_pool.rb", "method": "acquire_connection", "source": { "638": " # and +try_to_checkout_new_connection+ we can piggyback on +synchronize+ sections\n", "639": " # of the said methods and avoid an additional +synchronize+ overhead.\n", "640": " if conn = @available.poll || try_to_checkout_new_connection\n", "641": " conn\n", "642": " else\n" }, "context": "all" }, { "number": "341", "file": "[GEM_ROOT]/gems/activerecord-7.0.7.2/lib/active_record/connection_adapters/abstract/connection_pool.rb", "method": "checkout", "source": { "339": " # - ActiveRecord::ConnectionTimeoutError no connection can be obtained from the pool.\n", "340": " def checkout(checkout_timeout = @checkout_timeout)\n", "341": " checkout_and_verify(acquire_connection(checkout_timeout))\n", "342": " end\n", "343": "\n" }, "context": "all" }, { "number": "181", "file": "[GEM_ROOT]/gems/activerecord-7.0.7.2/lib/active_record/connection_adapters/abstract/connection_pool.rb", "method": "connection", "source": { "179": " # held in a cache keyed by a thread.\n", "180": " def connection\n", "181": " @thread_cached_conns[connection_cache_key(current_thread)] ||= checkout\n", "182": " end\n", "183": "\n" }, "context": "all" }, { "number": "211", "file": "[GEM_ROOT]/gems/activerecord-7.0.7.2/lib/active_record/connection_adapters/abstract/connection_handler.rb", "method": "retrieve_connection", "source": { "209": " end\n", "210": "\n", "211": " pool.connection\n", "212": " end\n", "213": "\n" }, "context": "all" }, { "number": "313", "file": "[GEM_ROOT]/gems/activerecord-7.0.7.2/lib/active_record/connection_handling.rb", "method": "retrieve_connection", "source": { "311": "\n", "312": " def retrieve_connection\n", "313": " connection_handler.retrieve_connection(connection_specification_name, role: current_role, shard: current_shard)\n", "314": " end\n", "315": "\n" }, "context": "all" }, { "number": "280", "file": "[GEM_ROOT]/gems/activerecord-7.0.7.2/lib/active_record/connection_handling.rb", "method": "connection", "source": { "278": " # to any of the specific Active Records.\n", "279": " def connection\n", "280": " retrieve_connection\n", "281": " end\n", "282": "\n" }, "context": "all" }, { "number": "433", "file": "[GEM_ROOT]/gems/activerecord-7.0.7.2/lib/active_record/core.rb", "method": "cached_find_by_statement", "source": { "431": "\n", "432": " def cached_find_by_statement(key, &block) # :nodoc:\n", "433": " cache = @find_by_statement_cache[connection.prepared_statements]\n", "434": " cache.compute_if_absent(key) { StatementCache.create(connection, &block) }\n", "435": " end\n" }, "context": "all" }, { "number": "317", "file": "[GEM_ROOT]/gems/activerecord-7.0.7.2/lib/active_record/core.rb", "method": "find_by", "source": { "315": "\n", "316": " keys = hash.keys\n", "317": " statement = cached_find_by_statement(keys) { |params|\n", "318": " wheres = keys.index_with { params.bind }\n", "319": " where(wheres).limit(1)\n" }, "context": "all" }, { "number": "69", "file": "[PROJECT_ROOT]/app/controllers/application_controller.rb", "method": "check_redirect", "source": { "67": "\n", "68": " def check_redirect\n", "69": " return unless (redirect = Redirect.find_by(slug: request.path.sub(%r{^/}, \"\")))\n", "70": " redirect_to redirect.url\n", "71": " end\n" }, "application_file": "app/controllers/application_controller.rb", "context": "app" }, { "number": "400", "file": "[GEM_ROOT]/gems/activesupport-7.0.7.2/lib/active_support/callbacks.rb", "method": "block in make_lambda", "source": { "398": " def make_lambda\n", "399": " lambda do |target, value, &block|\n", "400": " target.send(@method_name, &block)\n", "401": " end\n", "402": " end\n" }, "context": "all" }, { "number": "180", "file": "[GEM_ROOT]/gems/activesupport-7.0.7.2/lib/active_support/callbacks.rb", "method": "block (2 levels) in halting_and_conditional", "source": { "178": "\n", "179": " if !halted && user_conditions.all? { |c| c.call(target, value) }\n", "180": " result_lambda = -> { user_callback.call target, value }\n", "181": " env.halted = halted_lambda.call(target, result_lambda)\n", "182": " if env.halted\n" }, "context": "all" }, { "number": "34", "file": "[GEM_ROOT]/gems/actionpack-7.0.7.2/lib/abstract_controller/callbacks.rb", "method": "block (2 levels) in ", "source": { "32": " included do\n", "33": " define_callbacks :process_action,\n", "34": " terminator: ->(controller, result_lambda) { result_lambda.call; controller.performed? },\n", "35": " skip_after_callbacks_if_terminated: true\n", "36": " end\n" }, "context": "all" }, { "number": "181", "file": "[GEM_ROOT]/gems/activesupport-7.0.7.2/lib/active_support/callbacks.rb", "method": "block in halting_and_conditional", "source": { "179": " if !halted && user_conditions.all? { |c| c.call(target, value) }\n", "180": " result_lambda = -> { user_callback.call target, value }\n", "181": " env.halted = halted_lambda.call(target, result_lambda)\n", "182": " if env.halted\n", "183": " target.send :halted_callback_hook, filter, name\n" }, "context": "all" }, { "number": "595", "file": "[GEM_ROOT]/gems/activesupport-7.0.7.2/lib/active_support/callbacks.rb", "method": "block in invoke_before", "source": { "593": "\n", "594": " def invoke_before(arg)\n", "595": " @before.each { |b| b.call(arg) }\n", "596": " end\n", "597": "\n" }, "context": "all" }, { "number": "595", "file": "[GEM_ROOT]/gems/activesupport-7.0.7.2/lib/active_support/callbacks.rb", "method": "each", "source": { "593": "\n", "594": " def invoke_before(arg)\n", "595": " @before.each { |b| b.call(arg) }\n", "596": " end\n", "597": "\n" }, "context": "all" }, { "number": "595", "file": "[GEM_ROOT]/gems/activesupport-7.0.7.2/lib/active_support/callbacks.rb", "method": "invoke_before", "source": { "593": "\n", "594": " def invoke_before(arg)\n", "595": " @before.each { |b| b.call(arg) }\n", "596": " end\n", "597": "\n" }, "context": "all" }, { "number": "106", "file": "[GEM_ROOT]/gems/activesupport-7.0.7.2/lib/active_support/callbacks.rb", "method": "run_callbacks", "source": { "104": " # Common case: no 'around' callbacks defined\n", "105": " if next_sequence.final?\n", "106": " next_sequence.invoke_before(env)\n", "107": " env.value = !env.halted && (!block_given? || yield)\n", "108": " next_sequence.invoke_after(env)\n" }, "context": "all" }, { "number": "233", "file": "[GEM_ROOT]/gems/actionpack-7.0.7.2/lib/abstract_controller/callbacks.rb", "method": "process_action", "source": { "231": " # process_action callbacks around the normal behavior.\n", "232": " def process_action(...)\n", "233": " run_callbacks(:process_action) do\n", "234": " super\n", "235": " end\n" }, "context": "all" }, { "number": "23", "file": "[GEM_ROOT]/gems/actionpack-7.0.7.2/lib/action_controller/metal/rescue.rb", "method": "process_action", "source": { "21": " private\n", "22": " def process_action(*)\n", "23": " super\n", "24": " rescue Exception => exception\n", "25": " request.env[\"action_dispatch.show_detailed_exceptions\"] ||= show_detailed_exceptions?\n" }, "context": "all" }, { "number": "67", "file": "[GEM_ROOT]/gems/actionpack-7.0.7.2/lib/action_controller/metal/instrumentation.rb", "method": "block in process_action", "source": { "65": "\n", "66": " ActiveSupport::Notifications.instrument(\"process_action.action_controller\", raw_payload) do |payload|\n", "67": " result = super\n", "68": " payload[:response] = response\n", "69": " payload[:status] = response.status\n" }, "context": "all" }, { "number": "206", "file": "[GEM_ROOT]/gems/activesupport-7.0.7.2/lib/active_support/notifications.rb", "method": "block in instrument", "source": { "204": " def instrument(name, payload = {})\n", "205": " if notifier.listening?(name)\n", "206": " instrumenter.instrument(name, payload) { yield payload if block_given? }\n", "207": " else\n", "208": " yield payload if block_given?\n" }, "context": "all" }, { "number": "24", "file": "[GEM_ROOT]/gems/activesupport-7.0.7.2/lib/active_support/notifications/instrumenter.rb", "method": "instrument", "source": { "22": " listeners_state = start name, payload\n", "23": " begin\n", "24": " yield payload if block_given?\n", "25": " rescue Exception => e\n", "26": " payload[:exception] = [e.class.name, e.message]\n" }, "context": "all" }, { "number": "206", "file": "[GEM_ROOT]/gems/activesupport-7.0.7.2/lib/active_support/notifications.rb", "method": "instrument", "source": { "204": " def instrument(name, payload = {})\n", "205": " if notifier.listening?(name)\n", "206": " instrumenter.instrument(name, payload) { yield payload if block_given? }\n", "207": " else\n", "208": " yield payload if block_given?\n" }, "context": "all" }, { "number": "66", "file": "[GEM_ROOT]/gems/actionpack-7.0.7.2/lib/action_controller/metal/instrumentation.rb", "method": "process_action", "source": { "64": " ActiveSupport::Notifications.instrument(\"start_processing.action_controller\", raw_payload)\n", "65": "\n", "66": " ActiveSupport::Notifications.instrument(\"process_action.action_controller\", raw_payload) do |payload|\n", "67": " result = super\n", "68": " payload[:response] = response\n" }, "context": "all" }, { "number": "259", "file": "[GEM_ROOT]/gems/actionpack-7.0.7.2/lib/action_controller/metal/params_wrapper.rb", "method": "process_action", "source": { "257": " def process_action(*)\n", "258": " _perform_parameter_wrapping if _wrapper_enabled?\n", "259": " super\n", "260": " end\n", "261": "\n" }, "context": "all" }, { "number": "27", "file": "[GEM_ROOT]/gems/activerecord-7.0.7.2/lib/active_record/railties/controller_runtime.rb", "method": "process_action", "source": { "25": " # and it won't be cleaned up by the method below.\n", "26": " ActiveRecord::LogSubscriber.reset_runtime\n", "27": " super\n", "28": " end\n", "29": "\n" }, "context": "all" }, { "number": "120", "file": "[GEM_ROOT]/gems/scout_apm-5.3.5/lib/scout_apm/instruments/action_controller_rails_3_rails4.rb", "method": "process_action", "source": { "118": " req.start_layer( ScoutApm::Layer.new(\"Controller\", \"#{controller_path}/#{resolved_name}\") )\n", "119": " begin\n", "120": " super\n", "121": " rescue\n", "122": " req.error!\n" }, "context": "all" }, { "number": "151", "file": "[GEM_ROOT]/gems/actionpack-7.0.7.2/lib/abstract_controller/base.rb", "method": "process", "source": { "149": " @_response_body = nil\n", "150": "\n", "151": " process_action(action_name, *args)\n", "152": " end\n", "153": " ruby2_keywords(:process)\n" }, "context": "all" }, { "number": "39", "file": "[GEM_ROOT]/gems/actionview-7.0.7.2/lib/action_view/rendering.rb", "method": "process", "source": { "37": " def process(...) # :nodoc:\n", "38": " old_config, I18n.config = I18n.config, I18nProxy.new(I18n.config, lookup_context)\n", "39": " super\n", "40": " ensure\n", "41": " I18n.config = old_config\n" }, "context": "all" }, { "number": "188", "file": "[GEM_ROOT]/gems/actionpack-7.0.7.2/lib/action_controller/metal.rb", "method": "dispatch", "source": { "186": " set_request!(request)\n", "187": " set_response!(response)\n", "188": " process(name)\n", "189": " request.commit_flash\n", "190": " to_a\n" }, "context": "all" }, { "number": "251", "file": "[GEM_ROOT]/gems/actionpack-7.0.7.2/lib/action_controller/metal.rb", "method": "dispatch", "source": { "249": " middleware_stack.build(name) { |env| new.dispatch(name, req, res) }.call req.env\n", "250": " else\n", "251": " new.dispatch(name, req, res)\n", "252": " end\n", "253": " end\n" }, "context": "all" }, { "number": "49", "file": "[GEM_ROOT]/gems/actionpack-7.0.7.2/lib/action_dispatch/routing/route_set.rb", "method": "dispatch", "source": { "47": "\n", "48": " def dispatch(controller, action, req, res)\n", "49": " controller.dispatch(action, req, res)\n", "50": " end\n", "51": " end\n" }, "context": "all" }, { "number": "32", "file": "[GEM_ROOT]/gems/actionpack-7.0.7.2/lib/action_dispatch/routing/route_set.rb", "method": "serve", "source": { "30": " controller = controller req\n", "31": " res = controller.make_response! req\n", "32": " dispatch(controller, params[:action], req, res)\n", "33": " rescue ActionController::RoutingError\n", "34": " if @raise_on_name_error\n" }, "context": "all" }, { "number": "50", "file": "[GEM_ROOT]/gems/actionpack-7.0.7.2/lib/action_dispatch/journey/router.rb", "method": "block in serve", "source": { "48": " req.path_parameters = tmp_params\n", "49": "\n", "50": " status, headers, body = route.app.serve(req)\n", "51": "\n", "52": " if \"pass\" == headers[\"X-Cascade\"]\n" }, "context": "all" }, { "number": "32", "file": "[GEM_ROOT]/gems/actionpack-7.0.7.2/lib/action_dispatch/journey/router.rb", "method": "each", "source": { "30": "\n", "31": " def serve(req)\n", "32": " find_routes(req).each do |match, parameters, route|\n", "33": " set_params = req.path_parameters\n", "34": " path_info = req.path_info\n" }, "context": "all" }, { "number": "32", "file": "[GEM_ROOT]/gems/actionpack-7.0.7.2/lib/action_dispatch/journey/router.rb", "method": "serve", "source": { "30": "\n", "31": " def serve(req)\n", "32": " find_routes(req).each do |match, parameters, route|\n", "33": " set_params = req.path_parameters\n", "34": " path_info = req.path_info\n" }, "context": "all" }, { "number": "852", "file": "[GEM_ROOT]/gems/actionpack-7.0.7.2/lib/action_dispatch/routing/route_set.rb", "method": "call", "source": { "850": " req = make_request(env)\n", "851": " req.path_info = Journey::Router::Utils.normalize_path(req.path_info)\n", "852": " @router.serve(req)\n", "853": " end\n", "854": "\n" }, "context": "all" }, { "number": "29", "file": "[GEM_ROOT]/gems/scout_apm-5.3.5/lib/scout_apm/instruments/rails_router.rb", "method": "call_with_scout_instruments", "source": { "27": "\n", "28": " begin\n", "29": " call_without_scout_instruments(*args)\n", "30": " ensure\n", "31": " req.stop_layer\n" }, "context": "all" }, { "number": "17", "file": "[GEM_ROOT]/gems/scout_apm-5.3.5/lib/scout_apm/middleware.rb", "method": "call", "source": { "15": " def call(env)\n", "16": " if !@enabled || @started || @attempts > MAX_ATTEMPTS\n", "17": " @app.call(env)\n", "18": " else\n", "19": " attempt_to_start_agent\n" }, "context": "all" }, { "number": "36", "file": "[GEM_ROOT]/gems/warden-1.2.9/lib/warden/manager.rb", "method": "block in call", "source": { "34": " result = catch(:warden) do\n", "35": " env['warden'].on_request\n", "36": " @app.call(env)\n", "37": " end\n", "38": "\n" }, "context": "all" }, { "number": "34", "file": "[GEM_ROOT]/gems/warden-1.2.9/lib/warden/manager.rb", "method": "catch", "source": { "32": "\n", "33": " env['warden'] = Proxy.new(env, self)\n", "34": " result = catch(:warden) do\n", "35": " env['warden'].on_request\n", "36": " @app.call(env)\n" }, "context": "all" }, { "number": "34", "file": "[GEM_ROOT]/gems/warden-1.2.9/lib/warden/manager.rb", "method": "call", "source": { "32": "\n", "33": " env['warden'] = Proxy.new(env, self)\n", "34": " result = catch(:warden) do\n", "35": " env['warden'].on_request\n", "36": " @app.call(env)\n" }, "context": "all" }, { "number": "15", "file": "[GEM_ROOT]/gems/rack-2.2.8/lib/rack/tempfile_reaper.rb", "method": "call", "source": { "13": " def call(env)\n", "14": " env[RACK_TEMPFILES] ||= []\n", "15": " status, headers, body = @app.call(env)\n", "16": " body_proxy = BodyProxy.new(body) do\n", "17": " env[RACK_TEMPFILES].each(&:close!) unless env[RACK_TEMPFILES].nil?\n" }, "context": "all" }, { "number": "27", "file": "[GEM_ROOT]/gems/rack-2.2.8/lib/rack/conditional_get.rb", "method": "call", "source": { "25": " case env[REQUEST_METHOD]\n", "26": " when \"GET\", \"HEAD\"\n", "27": " status, headers, body = @app.call(env)\n", "28": " headers = Utils::HeaderHash[headers]\n", "29": " if status == 200 && fresh?(env, headers)\n" }, "context": "all" }, { "number": "12", "file": "[GEM_ROOT]/gems/rack-2.2.8/lib/rack/head.rb", "method": "call", "source": { "10": "\n", "11": " def call(env)\n", "12": " status, headers, body = @app.call(env)\n", "13": "\n", "14": " if env[REQUEST_METHOD] == HEAD\n" }, "context": "all" }, { "number": "38", "file": "[GEM_ROOT]/gems/actionpack-7.0.7.2/lib/action_dispatch/http/permissions_policy.rb", "method": "call", "source": { "36": " def call(env)\n", "37": " request = ActionDispatch::Request.new(env)\n", "38": " _, headers, _ = response = @app.call(env)\n", "39": "\n", "40": " return response unless html_response?(headers)\n" }, "context": "all" }, { "number": "36", "file": "[GEM_ROOT]/gems/actionpack-7.0.7.2/lib/action_dispatch/http/content_security_policy.rb", "method": "call", "source": { "34": " def call(env)\n", "35": " request = ActionDispatch::Request.new env\n", "36": " status, headers, _ = response = @app.call(env)\n", "37": "\n", "38": " # Returning CSP headers with a 304 Not Modified is harmful, since nonces in the new\n" }, "context": "all" }, { "number": "266", "file": "[GEM_ROOT]/gems/rack-2.2.8/lib/rack/session/abstract/id.rb", "method": "context", "source": { "264": " req = make_request env\n", "265": " prepare_session(req)\n", "266": " status, headers, body = app.call(req.env)\n", "267": " res = Rack::Response::Raw.new status, headers\n", "268": " commit_session(req, res)\n" }, "context": "all" }, { "number": "260", "file": "[GEM_ROOT]/gems/rack-2.2.8/lib/rack/session/abstract/id.rb", "method": "call", "source": { "258": "\n", "259": " def call(env)\n", "260": " context(env)\n", "261": " end\n", "262": "\n" }, "context": "all" }, { "number": "704", "file": "[GEM_ROOT]/gems/actionpack-7.0.7.2/lib/action_dispatch/middleware/cookies.rb", "method": "call", "source": { "702": " request = ActionDispatch::Request.new env\n", "703": "\n", "704": " status, headers, body = @app.call(env)\n", "705": "\n", "706": " if request.have_cookie_jar?\n" }, "context": "all" }, { "number": "27", "file": "[GEM_ROOT]/gems/actionpack-7.0.7.2/lib/action_dispatch/middleware/callbacks.rb", "method": "block in call", "source": { "25": " error = nil\n", "26": " result = run_callbacks :call do\n", "27": " @app.call(env)\n", "28": " rescue => error\n", "29": " end\n" }, "context": "all" }, { "number": "99", "file": "[GEM_ROOT]/gems/activesupport-7.0.7.2/lib/active_support/callbacks.rb", "method": "run_callbacks", "source": { "97": "\n", "98": " if callbacks.empty?\n", "99": " yield if block_given?\n", "100": " else\n", "101": " env = Filters::Environment.new(self, false, nil)\n" }, "context": "all" }, { "number": "26", "file": "[GEM_ROOT]/gems/actionpack-7.0.7.2/lib/action_dispatch/middleware/callbacks.rb", "method": "call", "source": { "24": " def call(env)\n", "25": " error = nil\n", "26": " result = run_callbacks :call do\n", "27": " @app.call(env)\n", "28": " rescue => error\n" }, "context": "all" }, { "number": "28", "file": "[GEM_ROOT]/gems/actionpack-7.0.7.2/lib/action_dispatch/middleware/debug_exceptions.rb", "method": "call", "source": { "26": " def call(env)\n", "27": " request = ActionDispatch::Request.new env\n", "28": " _, headers, body = response = @app.call(env)\n", "29": "\n", "30": " if headers[\"X-Cascade\"] == \"pass\"\n" }, "context": "all" }, { "number": "29", "file": "[GEM_ROOT]/gems/actionpack-7.0.7.2/lib/action_dispatch/middleware/show_exceptions.rb", "method": "call", "source": { "27": " def call(env)\n", "28": " request = ActionDispatch::Request.new env\n", "29": " @app.call(env)\n", "30": " rescue Exception => exception\n", "31": " if request.show_exceptions?\n" }, "context": "all" }, { "number": "18", "file": "[GEM_ROOT]/gems/lograge-0.12.0/lib/lograge/rails_ext/rack/logger.rb", "method": "call_app", "source": { "16": " def call_app(*args)\n", "17": " env = args.last\n", "18": " status, headers, body = @app.call(env)\n", "19": " # needs to have same return type as the Rails builtins being overridden, see https://github.com/roidrage/lograge/pull/333\n", "20": " # https://github.com/rails/rails/blob/be9d34b9bcb448b265114ebc28bef1a5b5e4c272/railties/lib/rails/rack/logger.rb#L37\n" }, "context": "all" }, { "number": "25", "file": "[GEM_ROOT]/gems/railties-7.0.7.2/lib/rails/rack/logger.rb", "method": "block in call", "source": { "23": "\n", "24": " if logger.respond_to?(:tagged)\n", "25": " logger.tagged(compute_tags(request)) { call_app(request, env) }\n", "26": " else\n", "27": " call_app(request, env)\n" }, "context": "all" }, { "number": "99", "file": "[GEM_ROOT]/gems/activesupport-7.0.7.2/lib/active_support/tagged_logging.rb", "method": "block in tagged", "source": { "97": " def tagged(*tags)\n", "98": " if block_given?\n", "99": " formatter.tagged(*tags) { yield self }\n", "100": " else\n", "101": " logger = ActiveSupport::TaggedLogging.new(self)\n" }, "context": "all" }, { "number": "37", "file": "[GEM_ROOT]/gems/activesupport-7.0.7.2/lib/active_support/tagged_logging.rb", "method": "tagged", "source": { "35": " def tagged(*tags)\n", "36": " new_tags = push_tags(*tags)\n", "37": " yield self\n", "38": " ensure\n", "39": " pop_tags(new_tags.size)\n" }, "context": "all" }, { "number": "99", "file": "[GEM_ROOT]/gems/activesupport-7.0.7.2/lib/active_support/tagged_logging.rb", "method": "tagged", "source": { "97": " def tagged(*tags)\n", "98": " if block_given?\n", "99": " formatter.tagged(*tags) { yield self }\n", "100": " else\n", "101": " logger = ActiveSupport::TaggedLogging.new(self)\n" }, "context": "all" }, { "number": "25", "file": "[GEM_ROOT]/gems/railties-7.0.7.2/lib/rails/rack/logger.rb", "method": "call", "source": { "23": "\n", "24": " if logger.respond_to?(:tagged)\n", "25": " logger.tagged(compute_tags(request)) { call_app(request, env) }\n", "26": " else\n", "27": " call_app(request, env)\n" }, "context": "all" }, { "number": "93", "file": "[GEM_ROOT]/gems/actionpack-7.0.7.2/lib/action_dispatch/middleware/remote_ip.rb", "method": "call", "source": { "91": " req = ActionDispatch::Request.new env\n", "92": " req.remote_ip = GetIp.new(req, check_ip, proxies)\n", "93": " @app.call(req.env)\n", "94": " end\n", "95": "\n" }, "context": "all" }, { "number": "19", "file": "[GEM_ROOT]/gems/request_store-1.5.1/lib/request_store/middleware.rb", "method": "call", "source": { "17": " RequestStore.begin!\r\n", "18": "\r\n", "19": " status, headers, body = @app.call(env)\r\n", "20": "\r\n", "21": " body = Rack::BodyProxy.new(body) do\r\n" }, "context": "all" }, { "number": "26", "file": "[GEM_ROOT]/gems/actionpack-7.0.7.2/lib/action_dispatch/middleware/request_id.rb", "method": "call", "source": { "24": " req = ActionDispatch::Request.new env\n", "25": " req.request_id = make_request_id(req.headers[@header])\n", "26": " @app.call(env).tap { |_status, headers, _body| headers[@header] = req.request_id }\n", "27": " end\n", "28": "\n" }, "context": "all" }, { "number": "24", "file": "[GEM_ROOT]/gems/rack-2.2.8/lib/rack/method_override.rb", "method": "call", "source": { "22": " end\n", "23": "\n", "24": " @app.call(env)\n", "25": " end\n", "26": "\n" }, "context": "all" }, { "number": "22", "file": "[GEM_ROOT]/gems/rack-2.2.8/lib/rack/runtime.rb", "method": "call", "source": { "20": " def call(env)\n", "21": " start_time = Utils.clock_time\n", "22": " status, headers, body = @app.call(env)\n", "23": " headers = Utils::HeaderHash[headers]\n", "24": "\n" }, "context": "all" }, { "number": "148", "file": "[GEM_ROOT]/gems/rack-timeout-0.6.3/lib/rack/timeout/core.rb", "method": "block in call", "source": { "146": "\n", "147": " response = timeout.timeout(info.timeout) do # perform request with timeout\n", "148": " begin @app.call(env) # boom, send request down the middleware chain\n", "149": " rescue RequestTimeoutException => e # will actually hardly ever get to this point because frameworks tend to catch this. see README for more\n", "150": " raise RequestTimeoutError.new(env), e.message, e.backtrace # but in case it does get here, re-raise RequestTimeoutException as RequestTimeoutError\n" }, "context": "all" }, { "number": "19", "file": "[GEM_ROOT]/gems/rack-timeout-0.6.3/lib/rack/timeout/support/timeout.rb", "method": "timeout", "source": { "17": " thr = Thread.current # reference to current thread to be used in timeout thread\n", "18": " job = @scheduler.run_in(secs) { @on_timeout.call thr } # schedule this thread to be timed out; should get cancelled if block completes on time\n", "19": " return block.call # do what you gotta do\n", "20": " ensure #\n", "21": " job.cancel! if job # cancel the scheduled timeout job; if the block completed on time, this\n" }, "context": "all" }, { "number": "147", "file": "[GEM_ROOT]/gems/rack-timeout-0.6.3/lib/rack/timeout/core.rb", "method": "call", "source": { "145": " end\n", "146": "\n", "147": " response = timeout.timeout(info.timeout) do # perform request with timeout\n", "148": " begin @app.call(env) # boom, send request down the middleware chain\n", "149": " rescue RequestTimeoutException => e # will actually hardly ever get to this point because frameworks tend to catch this. see README for more\n" }, "context": "all" }, { "number": "41", "file": "[GEM_ROOT]/gems/judoscale-ruby-1.4.1/lib/judoscale/request_middleware.rb", "method": "call", "source": { "39": " end\n", "40": "\n", "41": " @app.call(env)\n", "42": " end\n", "43": " end\n" }, "context": "all" }, { "number": "29", "file": "[GEM_ROOT]/gems/activesupport-7.0.7.2/lib/active_support/cache/strategy/local_cache_middleware.rb", "method": "call", "source": { "27": " def call(env)\n", "28": " LocalCacheRegistry.set_cache_for(local_cache_key, LocalStore.new)\n", "29": " response = @app.call(env)\n", "30": " response[2] = ::Rack::BodyProxy.new(response[2]) do\n", "31": " LocalCacheRegistry.set_cache_for(local_cache_key, nil)\n" }, "context": "all" }, { "number": "24", "file": "[GEM_ROOT]/gems/rack-rewrite-1.5.1/lib/rack/rewrite.rb", "method": "call", "source": { "22": " return rack_response unless rack_response === true\n", "23": " end\n", "24": " @app.call(env)\n", "25": " end\n", "26": " \n" }, "context": "all" }, { "number": "14", "file": "[GEM_ROOT]/gems/actionpack-7.0.7.2/lib/action_dispatch/middleware/executor.rb", "method": "call", "source": { "12": " state = @executor.run!(reset: true)\n", "13": " begin\n", "14": " response = @app.call(env)\n", "15": " returned = response << ::Rack::BodyProxy.new(response.pop) { state.complete! }\n", "16": " rescue => error\n" }, "context": "all" }, { "number": "23", "file": "[GEM_ROOT]/gems/actionpack-7.0.7.2/lib/action_dispatch/middleware/static.rb", "method": "call", "source": { "21": "\n", "22": " def call(env)\n", "23": " @file_handler.attempt(env) || @app.call(env)\n", "24": " end\n", "25": " end\n" }, "context": "all" }, { "number": "110", "file": "[GEM_ROOT]/gems/rack-2.2.8/lib/rack/sendfile.rb", "method": "call", "source": { "108": "\n", "109": " def call(env)\n", "110": " status, headers, body = @app.call(env)\n", "111": " if body.respond_to?(:to_path)\n", "112": " case type = variation(env)\n" }, "context": "all" }, { "number": "77", "file": "[GEM_ROOT]/gems/actionpack-7.0.7.2/lib/action_dispatch/middleware/ssl.rb", "method": "call", "source": { "75": "\n", "76": " if request.ssl?\n", "77": " @app.call(env).tap do |status, headers, body|\n", "78": " set_hsts_header! headers\n", "79": " flag_cookies_as_secure! headers if @secure_cookies && !@exclude.call(request)\n" }, "context": "all" }, { "number": "131", "file": "[GEM_ROOT]/gems/actionpack-7.0.7.2/lib/action_dispatch/middleware/host_authorization.rb", "method": "call", "source": { "129": "\n", "130": " def call(env)\n", "131": " return @app.call(env) if @permissions.empty?\n", "132": "\n", "133": " request = Request.new(env)\n" }, "context": "all" }, { "number": "58", "file": "[GEM_ROOT]/gems/scout_apm-5.3.5/lib/scout_apm/instruments/middleware_summary.rb", "method": "call", "source": { "56": " layer = ScoutApm::Layer.new(\"Middleware\", \"Summary\")\n", "57": " req.start_layer(layer)\n", "58": " @app.call(env)\n", "59": " ensure\n", "60": " req.stop_layer\n" }, "context": "all" }, { "number": "530", "file": "[GEM_ROOT]/gems/railties-7.0.7.2/lib/rails/engine.rb", "method": "call", "source": { "528": " def call(env)\n", "529": " req = build_request env\n", "530": " app.call req.env\n", "531": " end\n", "532": "\n" }, "context": "all" }, { "number": "270", "file": "[GEM_ROOT]/gems/puma-6.3.1/lib/puma/configuration.rb", "method": "call", "source": { "268": " def call(env)\n", "269": " env[Const::PUMA_CONFIG] = @config\n", "270": " @app.call(env)\n", "271": " end\n", "272": " end\n" }, "context": "all" }, { "number": "100", "file": "[GEM_ROOT]/gems/puma-6.3.1/lib/puma/request.rb", "method": "block in handle_request", "source": { "98": " if @supported_http_methods == :any || @supported_http_methods.key?(env[REQUEST_METHOD])\n", "99": " status, headers, app_body = @thread_pool.with_force_shutdown do\n", "100": " @app.call(env)\n", "101": " end\n", "102": " else\n" }, "context": "all" }, { "number": "344", "file": "[GEM_ROOT]/gems/puma-6.3.1/lib/puma/thread_pool.rb", "method": "with_force_shutdown", "source": { "342": " t[:with_force_shutdown] = true\n", "343": " end\n", "344": " yield\n", "345": " ensure\n", "346": " t[:with_force_shutdown] = false\n" }, "context": "all" }, { "number": "99", "file": "[GEM_ROOT]/gems/puma-6.3.1/lib/puma/request.rb", "method": "handle_request", "source": { "97": " begin\n", "98": " if @supported_http_methods == :any || @supported_http_methods.key?(env[REQUEST_METHOD])\n", "99": " status, headers, app_body = @thread_pool.with_force_shutdown do\n", "100": " @app.call(env)\n", "101": " end\n" }, "context": "all" }, { "number": "443", "file": "[GEM_ROOT]/gems/puma-6.3.1/lib/puma/server.rb", "method": "process_client", "source": { "441": " while true\n", "442": " @requests_count += 1\n", "443": " case handle_request(client, requests + 1)\n", "444": " when false\n", "445": " break\n" }, "context": "all" }, { "number": "245", "file": "[GEM_ROOT]/gems/puma-6.3.1/lib/puma/server.rb", "method": "block in run", "source": { "243": " @status = :run\n", "244": "\n", "245": " @thread_pool = ThreadPool.new(thread_name, @options) { |client| process_client client }\n", "246": "\n", "247": " if @queue_requests\n" }, "context": "all" }, { "number": "151", "file": "[GEM_ROOT]/gems/puma-6.3.1/lib/puma/thread_pool.rb", "method": "block in spawn_thread", "source": { "149": "\n", "150": " begin\n", "151": " @out_of_band_pending = true if block.call(work)\n", "152": " rescue Exception => e\n", "153": " STDERR.puts \"Error reached top of thread-pool: #{e.message} (#{e.class})\"\n" }, "context": "all" } ], "application_trace": [ { "number": "69", "file": "[PROJECT_ROOT]/app/controllers/application_controller.rb", "method": "check_redirect", "source": { "67": "\n", "68": " def check_redirect\n", "69": " return unless (redirect = Redirect.find_by(slug: request.path.sub(%r{^/}, \"\")))\n", "70": " redirect_to redirect.url\n", "71": " end\n" }, "application_file": "app/controllers/application_controller.rb", "context": "app" } ], "web_environment": { "SERVER_SOFTWARE": "puma 6.3.1 Mugi No Toki Itaru", "GATEWAY_INTERFACE": "CGI/1.2", "REQUEST_METHOD": "GET", "SERVER_PROTOCOL": "HTTP/1.1", "HTTP_HOST": "example.com", "HTTP_CONNECTION": "close", "HTTP_USER_AGENT": "Amazon CloudFront", "HTTP_X_AMZ_CF_ID": "yai2eezeewaipahthieN-Yt3y0gAunRuwBHH8A==", "HTTP_IF_NONE_MATCH": "W/\"fde6ca645252fa81edfdae38dbeef178\"", "HTTP_ACCEPT": "text/html,application/xhtml+xml,application/xml;q=0.9,image/avif,image/webp,image/apng,*/*;q=0.8,application/signed-exchange;v=b3;q=0.7", "HTTP_X_FORWARDED_FOR": "199.175.219.155, 64.252.73.106", "HTTP_VIA": "2.0 yai2eezeewaipahthieN.cloudfront.net (CloudFront), 1.1 vegur", "HTTP_ACCEPT_ENCODING": "gzip", "HTTP_IF_MODIFIED_SINCE": "Wed, 11 Oct 2023 20:51:58 GMT", "HTTP_SEC_CH_UA": "\"Google Chrome\";v=\"117\", \"Not;A=Brand\";v=\"8\", \"Chromium\";v=\"117\"", "HTTP_SEC_CH_UA_MOBILE": "?0", "HTTP_SEC_CH_UA_PLATFORM": "\"Windows\"", "HTTP_UPGRADE_INSECURE_REQUESTS": "1", "HTTP_SEC_PURPOSE": "prefetch;prerender", "HTTP_PURPOSE": "prefetch", "HTTP_SEC_FETCH_SITE": "none", "HTTP_SEC_FETCH_MODE": "navigate", "HTTP_SEC_FETCH_USER": "?1", "HTTP_SEC_FETCH_DEST": "document", "HTTP_X_REQUEST_ID": "fb536bf3-76d0-4936-a354-2a3d023b2cf4", "HTTP_X_FORWARDED_PROTO": "https", "HTTP_X_FORWARDED_PORT": "443", "HTTP_CONNECT_TIME": "1", "HTTP_X_REQUEST_START": "1697220489932", "HTTP_TOTAL_ROUTE_TIME": "0", "SERVER_NAME": "example.com", "SERVER_PORT": "443", "REMOTE_ADDR": "10.1.5.53", "HTTP_VERSION": "HTTP/1.1" }, "deploy": { "environment": "production", "revision": "0eaf61a9ec756be9f4bb511ad71b37baaa9b73ba", "repository": "https://github.com/spacely/testy-mctestface", "local_username": "ben@example.com", "created_at": "2023-10-06T20:52:51.878336Z", "changelog": [], "url": "https://github.com/spacely/testy-mctestface/compare/d4f90c876adf4a108ebb9a6f47b5562b59578d97...0eaf61a9ec756be9f4bb511ad71b37baaa9b73ba" }, "url": "https://app.honeybadger.io/projects/123321/faults/101337516/01HCN3JWWXRQX511BB83WM2X95" } } ``` # Rate exceeded event payload > Sent when error rate threshold is exceeded. Sent when error rate threshold is exceeded. ```json { "event": "rate_exceeded", "message": "[Testy McTestFace/production] ActiveRecord::NoDatabaseError has occurred time(s) in the past ", "project": { "id": 123321, "name": "Testy McTestFace", "created_at": "2017-08-30T12:54:33.156695Z", "disable_public_links": false, "pivotal_project_id": null, "asana_workspace_id": null, "token": "zzz111", "github_project": "spacely/testy-mctestface", "environments": [ { "id": 68210, "project_id": 123321, "name": "production", "notifications": true, "created_at": "2017-09-05T06:10:19.057794Z", "updated_at": "2017-09-05T06:10:19.057794Z" }, { "id": 68074, "project_id": 123321, "name": "development", "notifications": true, "created_at": "2017-08-30T12:55:29.297392Z", "updated_at": "2017-08-30T12:55:29.297392Z" } ], "owner": { "id": 1, "email": "ben@example.com", "name": "Spacely Sprockets" }, "last_notice_at": "2023-10-30T19:29:08.000000Z", "earliest_notice_at": "2023-05-03T19:37:25.519130Z", "unresolved_fault_count": 102, "fault_count": 925, "active": true, "users": [ { "id": 1, "email": "ben@example.com", "name": "Ben" }, { "id": 99, "email": "george@example.com", "name": "George Jetson" } ], "sites": [ { "id": "c42c4c0a-6e3d-4303-9769-549ed2a5818e", "active": true, "last_checked_at": "2023-10-30T19:34:08.150725Z", "name": "Heroku", "state": "up", "url": "https://example.com" } ], "team_id": 1 }, "fault": { "project_id": 123321, "klass": "ActiveRecord::NoDatabaseError", "component": "pages", "action": "home", "environment": "production", "resolved": false, "ignored": false, "created_at": "2023-10-13T18:07:55.692256Z", "comments_count": 0, "message": "We could not find your database: d6ipl26lboesdi. Which can be found in the database configuration file located at config/database.yml.\n\nTo resolve this issue:\n\n- Did you create the database for this app, or delete it? You may need to create your database.\n- Has the database name changed? Check your database.yml config has the correct database name.\n\nTo create your database, run:\n\n bin/rails db:create", "notices_count": 6, "last_notice_at": "2023-10-13T18:08:10.000000Z", "tags": [], "id": 101337516, "assignee": null, "url": "https://app.honeybadger.io/projects/123321/faults/101337516", "deploy": { "environment": "production", "revision": "0eaf61a9ec756be9f4bb511ad71b37baaa9b73ba", "repository": "https://github.com/spacely/testy-mctestface", "local_username": "ben@example.com", "created_at": "2023-10-06T20:52:51.878336Z", "changelog": [], "url": "https://github.com/spacely/testy-mctestface/compare/d4f90c876adf4a108ebb9a6f47b5562b59578d97...0eaf61a9ec756be9f4bb511ad71b37baaa9b73ba" } }, "notice": { "id": 1013375161697220500, "environment": {}, "created_at": "2023-10-13T18:08:10.141219Z", "message": null, "token": "babe1d9d-67e3-4438-8c57-c544cea24ffb", "fault_id": 101337516, "request": { "url": "https://example.com/", "component": "pages", "action": "home", "params": { "controller": "pages", "action": "home" }, "session": {}, "context": {} }, "backtrace": [ { "number": "81", "file": "[GEM_ROOT]/gems/activerecord-7.0.7.2/lib/active_record/connection_adapters/postgresql_adapter.rb", "method": "rescue in new_client", "source": { "79": " rescue ::PG::Error => error\n", "80": " if conn_params && conn_params[:dbname] && error.message.include?(conn_params[:dbname])\n", "81": " raise ActiveRecord::NoDatabaseError.db_error(conn_params[:dbname])\n", "82": " elsif conn_params && conn_params[:user] && error.message.include?(conn_params[:user])\n", "83": " raise ActiveRecord::DatabaseConnectionError.username_error(conn_params[:user])\n" }, "context": "all" }, { "number": "77", "file": "[GEM_ROOT]/gems/activerecord-7.0.7.2/lib/active_record/connection_adapters/postgresql_adapter.rb", "method": "new_client", "source": { "75": "\n", "76": " class << self\n", "77": " def new_client(conn_params)\n", "78": " PG.connect(**conn_params)\n", "79": " rescue ::PG::Error => error\n" }, "context": "all" }, { "number": "37", "file": "[GEM_ROOT]/gems/activerecord-7.0.7.2/lib/active_record/connection_adapters/postgresql_adapter.rb", "method": "postgresql_connection", "source": { "35": "\n", "36": " ConnectionAdapters::PostgreSQLAdapter.new(\n", "37": " ConnectionAdapters::PostgreSQLAdapter.new_client(conn_params),\n", "38": " logger,\n", "39": " conn_params,\n" }, "context": "all" }, { "number": "656", "file": "[GEM_ROOT]/gems/activerecord-7.0.7.2/lib/active_record/connection_adapters/abstract/connection_pool.rb", "method": "public_send", "source": { "654": "\n", "655": " def new_connection\n", "656": " Base.public_send(db_config.adapter_method, db_config.configuration_hash).tap do |conn|\n", "657": " conn.check_version\n", "658": " end\n" }, "context": "all" }, { "number": "656", "file": "[GEM_ROOT]/gems/activerecord-7.0.7.2/lib/active_record/connection_adapters/abstract/connection_pool.rb", "method": "new_connection", "source": { "654": "\n", "655": " def new_connection\n", "656": " Base.public_send(db_config.adapter_method, db_config.configuration_hash).tap do |conn|\n", "657": " conn.check_version\n", "658": " end\n" }, "context": "all" }, { "number": "700", "file": "[GEM_ROOT]/gems/activerecord-7.0.7.2/lib/active_record/connection_adapters/abstract/connection_pool.rb", "method": "checkout_new_connection", "source": { "698": " def checkout_new_connection\n", "699": " raise ConnectionNotEstablished unless @automatic_reconnect\n", "700": " new_connection\n", "701": " end\n", "702": "\n" }, "context": "all" }, { "number": "679", "file": "[GEM_ROOT]/gems/activerecord-7.0.7.2/lib/active_record/connection_adapters/abstract/connection_pool.rb", "method": "try_to_checkout_new_connection", "source": { "677": " # if successfully incremented @now_connecting establish new connection\n", "678": " # outside of synchronized section\n", "679": " conn = checkout_new_connection\n", "680": " ensure\n", "681": " synchronize do\n" }, "context": "all" }, { "number": "640", "file": "[GEM_ROOT]/gems/activerecord-7.0.7.2/lib/active_record/connection_adapters/abstract/connection_pool.rb", "method": "acquire_connection", "source": { "638": " # and +try_to_checkout_new_connection+ we can piggyback on +synchronize+ sections\n", "639": " # of the said methods and avoid an additional +synchronize+ overhead.\n", "640": " if conn = @available.poll || try_to_checkout_new_connection\n", "641": " conn\n", "642": " else\n" }, "context": "all" }, { "number": "341", "file": "[GEM_ROOT]/gems/activerecord-7.0.7.2/lib/active_record/connection_adapters/abstract/connection_pool.rb", "method": "checkout", "source": { "339": " # - ActiveRecord::ConnectionTimeoutError no connection can be obtained from the pool.\n", "340": " def checkout(checkout_timeout = @checkout_timeout)\n", "341": " checkout_and_verify(acquire_connection(checkout_timeout))\n", "342": " end\n", "343": "\n" }, "context": "all" }, { "number": "181", "file": "[GEM_ROOT]/gems/activerecord-7.0.7.2/lib/active_record/connection_adapters/abstract/connection_pool.rb", "method": "connection", "source": { "179": " # held in a cache keyed by a thread.\n", "180": " def connection\n", "181": " @thread_cached_conns[connection_cache_key(current_thread)] ||= checkout\n", "182": " end\n", "183": "\n" }, "context": "all" }, { "number": "211", "file": "[GEM_ROOT]/gems/activerecord-7.0.7.2/lib/active_record/connection_adapters/abstract/connection_handler.rb", "method": "retrieve_connection", "source": { "209": " end\n", "210": "\n", "211": " pool.connection\n", "212": " end\n", "213": "\n" }, "context": "all" }, { "number": "313", "file": "[GEM_ROOT]/gems/activerecord-7.0.7.2/lib/active_record/connection_handling.rb", "method": "retrieve_connection", "source": { "311": "\n", "312": " def retrieve_connection\n", "313": " connection_handler.retrieve_connection(connection_specification_name, role: current_role, shard: current_shard)\n", "314": " end\n", "315": "\n" }, "context": "all" }, { "number": "280", "file": "[GEM_ROOT]/gems/activerecord-7.0.7.2/lib/active_record/connection_handling.rb", "method": "connection", "source": { "278": " # to any of the specific Active Records.\n", "279": " def connection\n", "280": " retrieve_connection\n", "281": " end\n", "282": "\n" }, "context": "all" }, { "number": "433", "file": "[GEM_ROOT]/gems/activerecord-7.0.7.2/lib/active_record/core.rb", "method": "cached_find_by_statement", "source": { "431": "\n", "432": " def cached_find_by_statement(key, &block) # :nodoc:\n", "433": " cache = @find_by_statement_cache[connection.prepared_statements]\n", "434": " cache.compute_if_absent(key) { StatementCache.create(connection, &block) }\n", "435": " end\n" }, "context": "all" }, { "number": "317", "file": "[GEM_ROOT]/gems/activerecord-7.0.7.2/lib/active_record/core.rb", "method": "find_by", "source": { "315": "\n", "316": " keys = hash.keys\n", "317": " statement = cached_find_by_statement(keys) { |params|\n", "318": " wheres = keys.index_with { params.bind }\n", "319": " where(wheres).limit(1)\n" }, "context": "all" }, { "number": "69", "file": "[PROJECT_ROOT]/app/controllers/application_controller.rb", "method": "check_redirect", "source": { "67": "\n", "68": " def check_redirect\n", "69": " return unless (redirect = Redirect.find_by(slug: request.path.sub(%r{^/}, \"\")))\n", "70": " redirect_to redirect.url\n", "71": " end\n" }, "application_file": "app/controllers/application_controller.rb", "context": "app" }, { "number": "400", "file": "[GEM_ROOT]/gems/activesupport-7.0.7.2/lib/active_support/callbacks.rb", "method": "block in make_lambda", "source": { "398": " def make_lambda\n", "399": " lambda do |target, value, &block|\n", "400": " target.send(@method_name, &block)\n", "401": " end\n", "402": " end\n" }, "context": "all" }, { "number": "180", "file": "[GEM_ROOT]/gems/activesupport-7.0.7.2/lib/active_support/callbacks.rb", "method": "block (2 levels) in halting_and_conditional", "source": { "178": "\n", "179": " if !halted && user_conditions.all? { |c| c.call(target, value) }\n", "180": " result_lambda = -> { user_callback.call target, value }\n", "181": " env.halted = halted_lambda.call(target, result_lambda)\n", "182": " if env.halted\n" }, "context": "all" }, { "number": "34", "file": "[GEM_ROOT]/gems/actionpack-7.0.7.2/lib/abstract_controller/callbacks.rb", "method": "block (2 levels) in ", "source": { "32": " included do\n", "33": " define_callbacks :process_action,\n", "34": " terminator: ->(controller, result_lambda) { result_lambda.call; controller.performed? },\n", "35": " skip_after_callbacks_if_terminated: true\n", "36": " end\n" }, "context": "all" }, { "number": "181", "file": "[GEM_ROOT]/gems/activesupport-7.0.7.2/lib/active_support/callbacks.rb", "method": "block in halting_and_conditional", "source": { "179": " if !halted && user_conditions.all? { |c| c.call(target, value) }\n", "180": " result_lambda = -> { user_callback.call target, value }\n", "181": " env.halted = halted_lambda.call(target, result_lambda)\n", "182": " if env.halted\n", "183": " target.send :halted_callback_hook, filter, name\n" }, "context": "all" }, { "number": "595", "file": "[GEM_ROOT]/gems/activesupport-7.0.7.2/lib/active_support/callbacks.rb", "method": "block in invoke_before", "source": { "593": "\n", "594": " def invoke_before(arg)\n", "595": " @before.each { |b| b.call(arg) }\n", "596": " end\n", "597": "\n" }, "context": "all" }, { "number": "595", "file": "[GEM_ROOT]/gems/activesupport-7.0.7.2/lib/active_support/callbacks.rb", "method": "each", "source": { "593": "\n", "594": " def invoke_before(arg)\n", "595": " @before.each { |b| b.call(arg) }\n", "596": " end\n", "597": "\n" }, "context": "all" }, { "number": "595", "file": "[GEM_ROOT]/gems/activesupport-7.0.7.2/lib/active_support/callbacks.rb", "method": "invoke_before", "source": { "593": "\n", "594": " def invoke_before(arg)\n", "595": " @before.each { |b| b.call(arg) }\n", "596": " end\n", "597": "\n" }, "context": "all" }, { "number": "106", "file": "[GEM_ROOT]/gems/activesupport-7.0.7.2/lib/active_support/callbacks.rb", "method": "run_callbacks", "source": { "104": " # Common case: no 'around' callbacks defined\n", "105": " if next_sequence.final?\n", "106": " next_sequence.invoke_before(env)\n", "107": " env.value = !env.halted && (!block_given? || yield)\n", "108": " next_sequence.invoke_after(env)\n" }, "context": "all" }, { "number": "233", "file": "[GEM_ROOT]/gems/actionpack-7.0.7.2/lib/abstract_controller/callbacks.rb", "method": "process_action", "source": { "231": " # process_action callbacks around the normal behavior.\n", "232": " def process_action(...)\n", "233": " run_callbacks(:process_action) do\n", "234": " super\n", "235": " end\n" }, "context": "all" }, { "number": "23", "file": "[GEM_ROOT]/gems/actionpack-7.0.7.2/lib/action_controller/metal/rescue.rb", "method": "process_action", "source": { "21": " private\n", "22": " def process_action(*)\n", "23": " super\n", "24": " rescue Exception => exception\n", "25": " request.env[\"action_dispatch.show_detailed_exceptions\"] ||= show_detailed_exceptions?\n" }, "context": "all" }, { "number": "67", "file": "[GEM_ROOT]/gems/actionpack-7.0.7.2/lib/action_controller/metal/instrumentation.rb", "method": "block in process_action", "source": { "65": "\n", "66": " ActiveSupport::Notifications.instrument(\"process_action.action_controller\", raw_payload) do |payload|\n", "67": " result = super\n", "68": " payload[:response] = response\n", "69": " payload[:status] = response.status\n" }, "context": "all" }, { "number": "206", "file": "[GEM_ROOT]/gems/activesupport-7.0.7.2/lib/active_support/notifications.rb", "method": "block in instrument", "source": { "204": " def instrument(name, payload = {})\n", "205": " if notifier.listening?(name)\n", "206": " instrumenter.instrument(name, payload) { yield payload if block_given? }\n", "207": " else\n", "208": " yield payload if block_given?\n" }, "context": "all" }, { "number": "24", "file": "[GEM_ROOT]/gems/activesupport-7.0.7.2/lib/active_support/notifications/instrumenter.rb", "method": "instrument", "source": { "22": " listeners_state = start name, payload\n", "23": " begin\n", "24": " yield payload if block_given?\n", "25": " rescue Exception => e\n", "26": " payload[:exception] = [e.class.name, e.message]\n" }, "context": "all" }, { "number": "206", "file": "[GEM_ROOT]/gems/activesupport-7.0.7.2/lib/active_support/notifications.rb", "method": "instrument", "source": { "204": " def instrument(name, payload = {})\n", "205": " if notifier.listening?(name)\n", "206": " instrumenter.instrument(name, payload) { yield payload if block_given? }\n", "207": " else\n", "208": " yield payload if block_given?\n" }, "context": "all" }, { "number": "66", "file": "[GEM_ROOT]/gems/actionpack-7.0.7.2/lib/action_controller/metal/instrumentation.rb", "method": "process_action", "source": { "64": " ActiveSupport::Notifications.instrument(\"start_processing.action_controller\", raw_payload)\n", "65": "\n", "66": " ActiveSupport::Notifications.instrument(\"process_action.action_controller\", raw_payload) do |payload|\n", "67": " result = super\n", "68": " payload[:response] = response\n" }, "context": "all" }, { "number": "259", "file": "[GEM_ROOT]/gems/actionpack-7.0.7.2/lib/action_controller/metal/params_wrapper.rb", "method": "process_action", "source": { "257": " def process_action(*)\n", "258": " _perform_parameter_wrapping if _wrapper_enabled?\n", "259": " super\n", "260": " end\n", "261": "\n" }, "context": "all" }, { "number": "27", "file": "[GEM_ROOT]/gems/activerecord-7.0.7.2/lib/active_record/railties/controller_runtime.rb", "method": "process_action", "source": { "25": " # and it won't be cleaned up by the method below.\n", "26": " ActiveRecord::LogSubscriber.reset_runtime\n", "27": " super\n", "28": " end\n", "29": "\n" }, "context": "all" }, { "number": "120", "file": "[GEM_ROOT]/gems/scout_apm-5.3.5/lib/scout_apm/instruments/action_controller_rails_3_rails4.rb", "method": "process_action", "source": { "118": " req.start_layer( ScoutApm::Layer.new(\"Controller\", \"#{controller_path}/#{resolved_name}\") )\n", "119": " begin\n", "120": " super\n", "121": " rescue\n", "122": " req.error!\n" }, "context": "all" }, { "number": "151", "file": "[GEM_ROOT]/gems/actionpack-7.0.7.2/lib/abstract_controller/base.rb", "method": "process", "source": { "149": " @_response_body = nil\n", "150": "\n", "151": " process_action(action_name, *args)\n", "152": " end\n", "153": " ruby2_keywords(:process)\n" }, "context": "all" }, { "number": "39", "file": "[GEM_ROOT]/gems/actionview-7.0.7.2/lib/action_view/rendering.rb", "method": "process", "source": { "37": " def process(...) # :nodoc:\n", "38": " old_config, I18n.config = I18n.config, I18nProxy.new(I18n.config, lookup_context)\n", "39": " super\n", "40": " ensure\n", "41": " I18n.config = old_config\n" }, "context": "all" }, { "number": "188", "file": "[GEM_ROOT]/gems/actionpack-7.0.7.2/lib/action_controller/metal.rb", "method": "dispatch", "source": { "186": " set_request!(request)\n", "187": " set_response!(response)\n", "188": " process(name)\n", "189": " request.commit_flash\n", "190": " to_a\n" }, "context": "all" }, { "number": "251", "file": "[GEM_ROOT]/gems/actionpack-7.0.7.2/lib/action_controller/metal.rb", "method": "dispatch", "source": { "249": " middleware_stack.build(name) { |env| new.dispatch(name, req, res) }.call req.env\n", "250": " else\n", "251": " new.dispatch(name, req, res)\n", "252": " end\n", "253": " end\n" }, "context": "all" }, { "number": "49", "file": "[GEM_ROOT]/gems/actionpack-7.0.7.2/lib/action_dispatch/routing/route_set.rb", "method": "dispatch", "source": { "47": "\n", "48": " def dispatch(controller, action, req, res)\n", "49": " controller.dispatch(action, req, res)\n", "50": " end\n", "51": " end\n" }, "context": "all" }, { "number": "32", "file": "[GEM_ROOT]/gems/actionpack-7.0.7.2/lib/action_dispatch/routing/route_set.rb", "method": "serve", "source": { "30": " controller = controller req\n", "31": " res = controller.make_response! req\n", "32": " dispatch(controller, params[:action], req, res)\n", "33": " rescue ActionController::RoutingError\n", "34": " if @raise_on_name_error\n" }, "context": "all" }, { "number": "50", "file": "[GEM_ROOT]/gems/actionpack-7.0.7.2/lib/action_dispatch/journey/router.rb", "method": "block in serve", "source": { "48": " req.path_parameters = tmp_params\n", "49": "\n", "50": " status, headers, body = route.app.serve(req)\n", "51": "\n", "52": " if \"pass\" == headers[\"X-Cascade\"]\n" }, "context": "all" }, { "number": "32", "file": "[GEM_ROOT]/gems/actionpack-7.0.7.2/lib/action_dispatch/journey/router.rb", "method": "each", "source": { "30": "\n", "31": " def serve(req)\n", "32": " find_routes(req).each do |match, parameters, route|\n", "33": " set_params = req.path_parameters\n", "34": " path_info = req.path_info\n" }, "context": "all" }, { "number": "32", "file": "[GEM_ROOT]/gems/actionpack-7.0.7.2/lib/action_dispatch/journey/router.rb", "method": "serve", "source": { "30": "\n", "31": " def serve(req)\n", "32": " find_routes(req).each do |match, parameters, route|\n", "33": " set_params = req.path_parameters\n", "34": " path_info = req.path_info\n" }, "context": "all" }, { "number": "852", "file": "[GEM_ROOT]/gems/actionpack-7.0.7.2/lib/action_dispatch/routing/route_set.rb", "method": "call", "source": { "850": " req = make_request(env)\n", "851": " req.path_info = Journey::Router::Utils.normalize_path(req.path_info)\n", "852": " @router.serve(req)\n", "853": " end\n", "854": "\n" }, "context": "all" }, { "number": "29", "file": "[GEM_ROOT]/gems/scout_apm-5.3.5/lib/scout_apm/instruments/rails_router.rb", "method": "call_with_scout_instruments", "source": { "27": "\n", "28": " begin\n", "29": " call_without_scout_instruments(*args)\n", "30": " ensure\n", "31": " req.stop_layer\n" }, "context": "all" }, { "number": "17", "file": "[GEM_ROOT]/gems/scout_apm-5.3.5/lib/scout_apm/middleware.rb", "method": "call", "source": { "15": " def call(env)\n", "16": " if !@enabled || @started || @attempts > MAX_ATTEMPTS\n", "17": " @app.call(env)\n", "18": " else\n", "19": " attempt_to_start_agent\n" }, "context": "all" }, { "number": "36", "file": "[GEM_ROOT]/gems/warden-1.2.9/lib/warden/manager.rb", "method": "block in call", "source": { "34": " result = catch(:warden) do\n", "35": " env['warden'].on_request\n", "36": " @app.call(env)\n", "37": " end\n", "38": "\n" }, "context": "all" }, { "number": "34", "file": "[GEM_ROOT]/gems/warden-1.2.9/lib/warden/manager.rb", "method": "catch", "source": { "32": "\n", "33": " env['warden'] = Proxy.new(env, self)\n", "34": " result = catch(:warden) do\n", "35": " env['warden'].on_request\n", "36": " @app.call(env)\n" }, "context": "all" }, { "number": "34", "file": "[GEM_ROOT]/gems/warden-1.2.9/lib/warden/manager.rb", "method": "call", "source": { "32": "\n", "33": " env['warden'] = Proxy.new(env, self)\n", "34": " result = catch(:warden) do\n", "35": " env['warden'].on_request\n", "36": " @app.call(env)\n" }, "context": "all" }, { "number": "15", "file": "[GEM_ROOT]/gems/rack-2.2.8/lib/rack/tempfile_reaper.rb", "method": "call", "source": { "13": " def call(env)\n", "14": " env[RACK_TEMPFILES] ||= []\n", "15": " status, headers, body = @app.call(env)\n", "16": " body_proxy = BodyProxy.new(body) do\n", "17": " env[RACK_TEMPFILES].each(&:close!) unless env[RACK_TEMPFILES].nil?\n" }, "context": "all" }, { "number": "27", "file": "[GEM_ROOT]/gems/rack-2.2.8/lib/rack/conditional_get.rb", "method": "call", "source": { "25": " case env[REQUEST_METHOD]\n", "26": " when \"GET\", \"HEAD\"\n", "27": " status, headers, body = @app.call(env)\n", "28": " headers = Utils::HeaderHash[headers]\n", "29": " if status == 200 && fresh?(env, headers)\n" }, "context": "all" }, { "number": "12", "file": "[GEM_ROOT]/gems/rack-2.2.8/lib/rack/head.rb", "method": "call", "source": { "10": "\n", "11": " def call(env)\n", "12": " status, headers, body = @app.call(env)\n", "13": "\n", "14": " if env[REQUEST_METHOD] == HEAD\n" }, "context": "all" }, { "number": "38", "file": "[GEM_ROOT]/gems/actionpack-7.0.7.2/lib/action_dispatch/http/permissions_policy.rb", "method": "call", "source": { "36": " def call(env)\n", "37": " request = ActionDispatch::Request.new(env)\n", "38": " _, headers, _ = response = @app.call(env)\n", "39": "\n", "40": " return response unless html_response?(headers)\n" }, "context": "all" }, { "number": "36", "file": "[GEM_ROOT]/gems/actionpack-7.0.7.2/lib/action_dispatch/http/content_security_policy.rb", "method": "call", "source": { "34": " def call(env)\n", "35": " request = ActionDispatch::Request.new env\n", "36": " status, headers, _ = response = @app.call(env)\n", "37": "\n", "38": " # Returning CSP headers with a 304 Not Modified is harmful, since nonces in the new\n" }, "context": "all" }, { "number": "266", "file": "[GEM_ROOT]/gems/rack-2.2.8/lib/rack/session/abstract/id.rb", "method": "context", "source": { "264": " req = make_request env\n", "265": " prepare_session(req)\n", "266": " status, headers, body = app.call(req.env)\n", "267": " res = Rack::Response::Raw.new status, headers\n", "268": " commit_session(req, res)\n" }, "context": "all" }, { "number": "260", "file": "[GEM_ROOT]/gems/rack-2.2.8/lib/rack/session/abstract/id.rb", "method": "call", "source": { "258": "\n", "259": " def call(env)\n", "260": " context(env)\n", "261": " end\n", "262": "\n" }, "context": "all" }, { "number": "704", "file": "[GEM_ROOT]/gems/actionpack-7.0.7.2/lib/action_dispatch/middleware/cookies.rb", "method": "call", "source": { "702": " request = ActionDispatch::Request.new env\n", "703": "\n", "704": " status, headers, body = @app.call(env)\n", "705": "\n", "706": " if request.have_cookie_jar?\n" }, "context": "all" }, { "number": "27", "file": "[GEM_ROOT]/gems/actionpack-7.0.7.2/lib/action_dispatch/middleware/callbacks.rb", "method": "block in call", "source": { "25": " error = nil\n", "26": " result = run_callbacks :call do\n", "27": " @app.call(env)\n", "28": " rescue => error\n", "29": " end\n" }, "context": "all" }, { "number": "99", "file": "[GEM_ROOT]/gems/activesupport-7.0.7.2/lib/active_support/callbacks.rb", "method": "run_callbacks", "source": { "97": "\n", "98": " if callbacks.empty?\n", "99": " yield if block_given?\n", "100": " else\n", "101": " env = Filters::Environment.new(self, false, nil)\n" }, "context": "all" }, { "number": "26", "file": "[GEM_ROOT]/gems/actionpack-7.0.7.2/lib/action_dispatch/middleware/callbacks.rb", "method": "call", "source": { "24": " def call(env)\n", "25": " error = nil\n", "26": " result = run_callbacks :call do\n", "27": " @app.call(env)\n", "28": " rescue => error\n" }, "context": "all" }, { "number": "28", "file": "[GEM_ROOT]/gems/actionpack-7.0.7.2/lib/action_dispatch/middleware/debug_exceptions.rb", "method": "call", "source": { "26": " def call(env)\n", "27": " request = ActionDispatch::Request.new env\n", "28": " _, headers, body = response = @app.call(env)\n", "29": "\n", "30": " if headers[\"X-Cascade\"] == \"pass\"\n" }, "context": "all" }, { "number": "29", "file": "[GEM_ROOT]/gems/actionpack-7.0.7.2/lib/action_dispatch/middleware/show_exceptions.rb", "method": "call", "source": { "27": " def call(env)\n", "28": " request = ActionDispatch::Request.new env\n", "29": " @app.call(env)\n", "30": " rescue Exception => exception\n", "31": " if request.show_exceptions?\n" }, "context": "all" }, { "number": "18", "file": "[GEM_ROOT]/gems/lograge-0.12.0/lib/lograge/rails_ext/rack/logger.rb", "method": "call_app", "source": { "16": " def call_app(*args)\n", "17": " env = args.last\n", "18": " status, headers, body = @app.call(env)\n", "19": " # needs to have same return type as the Rails builtins being overridden, see https://github.com/roidrage/lograge/pull/333\n", "20": " # https://github.com/rails/rails/blob/be9d34b9bcb448b265114ebc28bef1a5b5e4c272/railties/lib/rails/rack/logger.rb#L37\n" }, "context": "all" }, { "number": "25", "file": "[GEM_ROOT]/gems/railties-7.0.7.2/lib/rails/rack/logger.rb", "method": "block in call", "source": { "23": "\n", "24": " if logger.respond_to?(:tagged)\n", "25": " logger.tagged(compute_tags(request)) { call_app(request, env) }\n", "26": " else\n", "27": " call_app(request, env)\n" }, "context": "all" }, { "number": "99", "file": "[GEM_ROOT]/gems/activesupport-7.0.7.2/lib/active_support/tagged_logging.rb", "method": "block in tagged", "source": { "97": " def tagged(*tags)\n", "98": " if block_given?\n", "99": " formatter.tagged(*tags) { yield self }\n", "100": " else\n", "101": " logger = ActiveSupport::TaggedLogging.new(self)\n" }, "context": "all" }, { "number": "37", "file": "[GEM_ROOT]/gems/activesupport-7.0.7.2/lib/active_support/tagged_logging.rb", "method": "tagged", "source": { "35": " def tagged(*tags)\n", "36": " new_tags = push_tags(*tags)\n", "37": " yield self\n", "38": " ensure\n", "39": " pop_tags(new_tags.size)\n" }, "context": "all" }, { "number": "99", "file": "[GEM_ROOT]/gems/activesupport-7.0.7.2/lib/active_support/tagged_logging.rb", "method": "tagged", "source": { "97": " def tagged(*tags)\n", "98": " if block_given?\n", "99": " formatter.tagged(*tags) { yield self }\n", "100": " else\n", "101": " logger = ActiveSupport::TaggedLogging.new(self)\n" }, "context": "all" }, { "number": "25", "file": "[GEM_ROOT]/gems/railties-7.0.7.2/lib/rails/rack/logger.rb", "method": "call", "source": { "23": "\n", "24": " if logger.respond_to?(:tagged)\n", "25": " logger.tagged(compute_tags(request)) { call_app(request, env) }\n", "26": " else\n", "27": " call_app(request, env)\n" }, "context": "all" }, { "number": "93", "file": "[GEM_ROOT]/gems/actionpack-7.0.7.2/lib/action_dispatch/middleware/remote_ip.rb", "method": "call", "source": { "91": " req = ActionDispatch::Request.new env\n", "92": " req.remote_ip = GetIp.new(req, check_ip, proxies)\n", "93": " @app.call(req.env)\n", "94": " end\n", "95": "\n" }, "context": "all" }, { "number": "19", "file": "[GEM_ROOT]/gems/request_store-1.5.1/lib/request_store/middleware.rb", "method": "call", "source": { "17": " RequestStore.begin!\r\n", "18": "\r\n", "19": " status, headers, body = @app.call(env)\r\n", "20": "\r\n", "21": " body = Rack::BodyProxy.new(body) do\r\n" }, "context": "all" }, { "number": "26", "file": "[GEM_ROOT]/gems/actionpack-7.0.7.2/lib/action_dispatch/middleware/request_id.rb", "method": "call", "source": { "24": " req = ActionDispatch::Request.new env\n", "25": " req.request_id = make_request_id(req.headers[@header])\n", "26": " @app.call(env).tap { |_status, headers, _body| headers[@header] = req.request_id }\n", "27": " end\n", "28": "\n" }, "context": "all" }, { "number": "24", "file": "[GEM_ROOT]/gems/rack-2.2.8/lib/rack/method_override.rb", "method": "call", "source": { "22": " end\n", "23": "\n", "24": " @app.call(env)\n", "25": " end\n", "26": "\n" }, "context": "all" }, { "number": "22", "file": "[GEM_ROOT]/gems/rack-2.2.8/lib/rack/runtime.rb", "method": "call", "source": { "20": " def call(env)\n", "21": " start_time = Utils.clock_time\n", "22": " status, headers, body = @app.call(env)\n", "23": " headers = Utils::HeaderHash[headers]\n", "24": "\n" }, "context": "all" }, { "number": "148", "file": "[GEM_ROOT]/gems/rack-timeout-0.6.3/lib/rack/timeout/core.rb", "method": "block in call", "source": { "146": "\n", "147": " response = timeout.timeout(info.timeout) do # perform request with timeout\n", "148": " begin @app.call(env) # boom, send request down the middleware chain\n", "149": " rescue RequestTimeoutException => e # will actually hardly ever get to this point because frameworks tend to catch this. see README for more\n", "150": " raise RequestTimeoutError.new(env), e.message, e.backtrace # but in case it does get here, re-raise RequestTimeoutException as RequestTimeoutError\n" }, "context": "all" }, { "number": "19", "file": "[GEM_ROOT]/gems/rack-timeout-0.6.3/lib/rack/timeout/support/timeout.rb", "method": "timeout", "source": { "17": " thr = Thread.current # reference to current thread to be used in timeout thread\n", "18": " job = @scheduler.run_in(secs) { @on_timeout.call thr } # schedule this thread to be timed out; should get cancelled if block completes on time\n", "19": " return block.call # do what you gotta do\n", "20": " ensure #\n", "21": " job.cancel! if job # cancel the scheduled timeout job; if the block completed on time, this\n" }, "context": "all" }, { "number": "147", "file": "[GEM_ROOT]/gems/rack-timeout-0.6.3/lib/rack/timeout/core.rb", "method": "call", "source": { "145": " end\n", "146": "\n", "147": " response = timeout.timeout(info.timeout) do # perform request with timeout\n", "148": " begin @app.call(env) # boom, send request down the middleware chain\n", "149": " rescue RequestTimeoutException => e # will actually hardly ever get to this point because frameworks tend to catch this. see README for more\n" }, "context": "all" }, { "number": "41", "file": "[GEM_ROOT]/gems/judoscale-ruby-1.4.1/lib/judoscale/request_middleware.rb", "method": "call", "source": { "39": " end\n", "40": "\n", "41": " @app.call(env)\n", "42": " end\n", "43": " end\n" }, "context": "all" }, { "number": "29", "file": "[GEM_ROOT]/gems/activesupport-7.0.7.2/lib/active_support/cache/strategy/local_cache_middleware.rb", "method": "call", "source": { "27": " def call(env)\n", "28": " LocalCacheRegistry.set_cache_for(local_cache_key, LocalStore.new)\n", "29": " response = @app.call(env)\n", "30": " response[2] = ::Rack::BodyProxy.new(response[2]) do\n", "31": " LocalCacheRegistry.set_cache_for(local_cache_key, nil)\n" }, "context": "all" }, { "number": "24", "file": "[GEM_ROOT]/gems/rack-rewrite-1.5.1/lib/rack/rewrite.rb", "method": "call", "source": { "22": " return rack_response unless rack_response === true\n", "23": " end\n", "24": " @app.call(env)\n", "25": " end\n", "26": " \n" }, "context": "all" }, { "number": "14", "file": "[GEM_ROOT]/gems/actionpack-7.0.7.2/lib/action_dispatch/middleware/executor.rb", "method": "call", "source": { "12": " state = @executor.run!(reset: true)\n", "13": " begin\n", "14": " response = @app.call(env)\n", "15": " returned = response << ::Rack::BodyProxy.new(response.pop) { state.complete! }\n", "16": " rescue => error\n" }, "context": "all" }, { "number": "23", "file": "[GEM_ROOT]/gems/actionpack-7.0.7.2/lib/action_dispatch/middleware/static.rb", "method": "call", "source": { "21": "\n", "22": " def call(env)\n", "23": " @file_handler.attempt(env) || @app.call(env)\n", "24": " end\n", "25": " end\n" }, "context": "all" }, { "number": "110", "file": "[GEM_ROOT]/gems/rack-2.2.8/lib/rack/sendfile.rb", "method": "call", "source": { "108": "\n", "109": " def call(env)\n", "110": " status, headers, body = @app.call(env)\n", "111": " if body.respond_to?(:to_path)\n", "112": " case type = variation(env)\n" }, "context": "all" }, { "number": "77", "file": "[GEM_ROOT]/gems/actionpack-7.0.7.2/lib/action_dispatch/middleware/ssl.rb", "method": "call", "source": { "75": "\n", "76": " if request.ssl?\n", "77": " @app.call(env).tap do |status, headers, body|\n", "78": " set_hsts_header! headers\n", "79": " flag_cookies_as_secure! headers if @secure_cookies && !@exclude.call(request)\n" }, "context": "all" }, { "number": "131", "file": "[GEM_ROOT]/gems/actionpack-7.0.7.2/lib/action_dispatch/middleware/host_authorization.rb", "method": "call", "source": { "129": "\n", "130": " def call(env)\n", "131": " return @app.call(env) if @permissions.empty?\n", "132": "\n", "133": " request = Request.new(env)\n" }, "context": "all" }, { "number": "58", "file": "[GEM_ROOT]/gems/scout_apm-5.3.5/lib/scout_apm/instruments/middleware_summary.rb", "method": "call", "source": { "56": " layer = ScoutApm::Layer.new(\"Middleware\", \"Summary\")\n", "57": " req.start_layer(layer)\n", "58": " @app.call(env)\n", "59": " ensure\n", "60": " req.stop_layer\n" }, "context": "all" }, { "number": "530", "file": "[GEM_ROOT]/gems/railties-7.0.7.2/lib/rails/engine.rb", "method": "call", "source": { "528": " def call(env)\n", "529": " req = build_request env\n", "530": " app.call req.env\n", "531": " end\n", "532": "\n" }, "context": "all" }, { "number": "270", "file": "[GEM_ROOT]/gems/puma-6.3.1/lib/puma/configuration.rb", "method": "call", "source": { "268": " def call(env)\n", "269": " env[Const::PUMA_CONFIG] = @config\n", "270": " @app.call(env)\n", "271": " end\n", "272": " end\n" }, "context": "all" }, { "number": "100", "file": "[GEM_ROOT]/gems/puma-6.3.1/lib/puma/request.rb", "method": "block in handle_request", "source": { "98": " if @supported_http_methods == :any || @supported_http_methods.key?(env[REQUEST_METHOD])\n", "99": " status, headers, app_body = @thread_pool.with_force_shutdown do\n", "100": " @app.call(env)\n", "101": " end\n", "102": " else\n" }, "context": "all" }, { "number": "344", "file": "[GEM_ROOT]/gems/puma-6.3.1/lib/puma/thread_pool.rb", "method": "with_force_shutdown", "source": { "342": " t[:with_force_shutdown] = true\n", "343": " end\n", "344": " yield\n", "345": " ensure\n", "346": " t[:with_force_shutdown] = false\n" }, "context": "all" }, { "number": "99", "file": "[GEM_ROOT]/gems/puma-6.3.1/lib/puma/request.rb", "method": "handle_request", "source": { "97": " begin\n", "98": " if @supported_http_methods == :any || @supported_http_methods.key?(env[REQUEST_METHOD])\n", "99": " status, headers, app_body = @thread_pool.with_force_shutdown do\n", "100": " @app.call(env)\n", "101": " end\n" }, "context": "all" }, { "number": "443", "file": "[GEM_ROOT]/gems/puma-6.3.1/lib/puma/server.rb", "method": "process_client", "source": { "441": " while true\n", "442": " @requests_count += 1\n", "443": " case handle_request(client, requests + 1)\n", "444": " when false\n", "445": " break\n" }, "context": "all" }, { "number": "245", "file": "[GEM_ROOT]/gems/puma-6.3.1/lib/puma/server.rb", "method": "block in run", "source": { "243": " @status = :run\n", "244": "\n", "245": " @thread_pool = ThreadPool.new(thread_name, @options) { |client| process_client client }\n", "246": "\n", "247": " if @queue_requests\n" }, "context": "all" }, { "number": "151", "file": "[GEM_ROOT]/gems/puma-6.3.1/lib/puma/thread_pool.rb", "method": "block in spawn_thread", "source": { "149": "\n", "150": " begin\n", "151": " @out_of_band_pending = true if block.call(work)\n", "152": " rescue Exception => e\n", "153": " STDERR.puts \"Error reached top of thread-pool: #{e.message} (#{e.class})\"\n" }, "context": "all" } ], "application_trace": [ { "number": "69", "file": "[PROJECT_ROOT]/app/controllers/application_controller.rb", "method": "check_redirect", "source": { "67": "\n", "68": " def check_redirect\n", "69": " return unless (redirect = Redirect.find_by(slug: request.path.sub(%r{^/}, \"\")))\n", "70": " redirect_to redirect.url\n", "71": " end\n" }, "application_file": "app/controllers/application_controller.rb", "context": "app" } ], "web_environment": { "SERVER_SOFTWARE": "puma 6.3.1 Mugi No Toki Itaru", "GATEWAY_INTERFACE": "CGI/1.2", "REQUEST_METHOD": "GET", "SERVER_PROTOCOL": "HTTP/1.1", "HTTP_HOST": "example.com", "HTTP_CONNECTION": "close", "HTTP_USER_AGENT": "Amazon CloudFront", "HTTP_X_AMZ_CF_ID": "yai2eezeewaipahthieN-Yt3y0gAunRuwBHH8A==", "HTTP_IF_NONE_MATCH": "W/\"fde6ca645252fa81edfdae38dbeef178\"", "HTTP_ACCEPT": "text/html,application/xhtml+xml,application/xml;q=0.9,image/avif,image/webp,image/apng,*/*;q=0.8,application/signed-exchange;v=b3;q=0.7", "HTTP_X_FORWARDED_FOR": "199.175.219.155, 64.252.73.106", "HTTP_VIA": "2.0 yai2eezeewaipahthieN.cloudfront.net (CloudFront), 1.1 vegur", "HTTP_ACCEPT_ENCODING": "gzip", "HTTP_IF_MODIFIED_SINCE": "Wed, 11 Oct 2023 20:51:58 GMT", "HTTP_SEC_CH_UA": "\"Google Chrome\";v=\"117\", \"Not;A=Brand\";v=\"8\", \"Chromium\";v=\"117\"", "HTTP_SEC_CH_UA_MOBILE": "?0", "HTTP_SEC_CH_UA_PLATFORM": "\"Windows\"", "HTTP_UPGRADE_INSECURE_REQUESTS": "1", "HTTP_SEC_PURPOSE": "prefetch;prerender", "HTTP_PURPOSE": "prefetch", "HTTP_SEC_FETCH_SITE": "none", "HTTP_SEC_FETCH_MODE": "navigate", "HTTP_SEC_FETCH_USER": "?1", "HTTP_SEC_FETCH_DEST": "document", "HTTP_X_REQUEST_ID": "fb536bf3-76d0-4936-a354-2a3d023b2cf4", "HTTP_X_FORWARDED_PROTO": "https", "HTTP_X_FORWARDED_PORT": "443", "HTTP_CONNECT_TIME": "1", "HTTP_X_REQUEST_START": "1697220489932", "HTTP_TOTAL_ROUTE_TIME": "0", "SERVER_NAME": "example.com", "SERVER_PORT": "443", "REMOTE_ADDR": "10.1.5.53", "HTTP_VERSION": "HTTP/1.1" }, "deploy": { "environment": "production", "revision": "0eaf61a9ec756be9f4bb511ad71b37baaa9b73ba", "repository": "https://github.com/spacely/testy-mctestface", "local_username": "ben@example.com", "created_at": "2023-10-06T20:52:51.878336Z", "changelog": [], "url": "https://github.com/spacely/testy-mctestface/compare/d4f90c876adf4a108ebb9a6f47b5562b59578d97...0eaf61a9ec756be9f4bb511ad71b37baaa9b73ba" }, "url": "https://app.honeybadger.io/projects/123321/faults/101337516/01HCN3JWWXRQX511BB83WM2X95" } } ``` # Error resolved event payload > Sent when an error is marked as resolved. Sent when an error is marked as resolved. ```json { "event": "resolved", "message": "[Testy McTestFace/production] ActiveRecord::NoDatabaseError resolved by ", "fault": { "project_id": 123321, "klass": "ActiveRecord::NoDatabaseError", "component": "pages", "action": "home", "environment": "production", "resolved": false, "ignored": false, "created_at": "2023-10-13T18:07:55.692256Z", "comments_count": 0, "message": "We could not find your database: d6ipl26lboesdi. Which can be found in the database configuration file located at config/database.yml.\n\nTo resolve this issue:\n\n- Did you create the database for this app, or delete it? You may need to create your database.\n- Has the database name changed? Check your database.yml config has the correct database name.\n\nTo create your database, run:\n\n bin/rails db:create", "notices_count": 6, "last_notice_at": "2023-10-13T18:08:10.000000Z", "tags": [], "id": 101337516, "assignee": null, "url": "https://app.honeybadger.io/projects/123321/faults/101337516", "deploy": { "environment": "production", "revision": "0eaf61a9ec756be9f4bb511ad71b37baaa9b73ba", "repository": "https://github.com/spacely/testy-mctestface", "local_username": "ben@example.com", "created_at": "2023-10-06T20:52:51.878336Z", "changelog": [], "url": "https://github.com/spacely/testy-mctestface/compare/d4f90c876adf4a108ebb9a6f47b5562b59578d97...0eaf61a9ec756be9f4bb511ad71b37baaa9b73ba" } } } ``` # Error unresolved event payload > Sent when a resolved error occurs again. Sent when a resolved error occurs again. ```json { "event": "unresolved", "message": "[Testy McTestFace/production] ActiveRecord::NoDatabaseError unresolved by ", "fault": { "project_id": 123321, "klass": "ActiveRecord::NoDatabaseError", "component": "pages", "action": "home", "environment": "production", "resolved": false, "ignored": false, "created_at": "2023-10-13T18:07:55.692256Z", "comments_count": 0, "message": "We could not find your database: d6ipl26lboesdi. Which can be found in the database configuration file located at config/database.yml.\n\nTo resolve this issue:\n\n- Did you create the database for this app, or delete it? You may need to create your database.\n- Has the database name changed? Check your database.yml config has the correct database name.\n\nTo create your database, run:\n\n bin/rails db:create", "notices_count": 6, "last_notice_at": "2023-10-13T18:08:10.000000Z", "tags": [], "id": 101337516, "assignee": null, "url": "https://app.honeybadger.io/projects/123321/faults/101337516", "deploy": { "environment": "production", "revision": "0eaf61a9ec756be9f4bb511ad71b37baaa9b73ba", "repository": "https://github.com/spacely/testy-mctestface", "local_username": "ben@example.com", "created_at": "2023-10-06T20:52:51.878336Z", "changelog": [], "url": "https://github.com/spacely/testy-mctestface/compare/d4f90c876adf4a108ebb9a6f47b5562b59578d97...0eaf61a9ec756be9f4bb511ad71b37baaa9b73ba" } } } ``` # Site up event payload > Sent when an uptime check succeeds after being down. Sent when an uptime check succeeds after being down. ```json { "event": "up", "message": "[Testy McTestFace] Heroku is back up after 0m.", "project": { "id": 123321, "name": "Testy McTestFace", "created_at": "2017-08-30T12:54:33.156695Z", "disable_public_links": false, "pivotal_project_id": null, "asana_workspace_id": null, "token": "zzz111", "github_project": "spacely/testy-mctestface", "environments": [ { "id": 68210, "project_id": 123321, "name": "production", "notifications": true, "created_at": "2017-09-05T06:10:19.057794Z", "updated_at": "2017-09-05T06:10:19.057794Z" }, { "id": 68074, "project_id": 123321, "name": "development", "notifications": true, "created_at": "2017-08-30T12:55:29.297392Z", "updated_at": "2017-08-30T12:55:29.297392Z" } ], "owner": { "id": 1, "email": "ben@example.com", "name": "Spacely Sprockets" }, "last_notice_at": "2023-10-30T19:29:08.000000Z", "earliest_notice_at": "2023-05-03T19:38:14.971778Z", "unresolved_fault_count": 102, "fault_count": 925, "active": true, "users": [ { "id": 1, "email": "ben@example.com", "name": "Ben" }, { "id": 99, "email": "george@example.com", "name": "George Jetson" } ], "sites": [ { "id": "c42c4c0a-6e3d-4303-9769-549ed2a5818e", "active": true, "last_checked_at": "2023-10-30T19:34:08.150725Z", "name": "Heroku", "state": "up", "url": "https://example.com" } ], "team_id": 1 }, "site": { "id": "c42c4c0a-6e3d-4303-9769-549ed2a5818e", "name": "Heroku", "url": "https://example.com", "frequency": 5, "match_type": "success", "match": null, "state": "up", "active": true, "last_checked_at": "2023-10-30T19:34:08.150725Z", "retries": 0, "proxy": 4, "cert_will_expire_at": null, "details_url": "https://app.honeybadger.io/projects/123321/sites/c42c4c0a-6e3d-4303-9769-549ed2a5818e" }, "outage": { "down_at": "2023-07-17T15:46:52.384701Z", "up_at": "2023-07-17T15:51:56.063948Z", "status": null, "reason": "Connection timed out", "headers": null, "details_url": "https://app.honeybadger.io/projects/123321/sites/c42c4c0a-6e3d-4303-9769-549ed2a5818e" } } ``` # Volume spike event payload > Sent when a project's error volume spikes above its learned baseline. Sent when a project’s total error volume spikes above its learned baseline. See [Error volume anomaly detection](/guides/integrations/#error-volume-anomaly-detection) for details on how spikes are detected. The subject of this event is the **project** (not an individual error), so the payload has no `fault`. Spike facts are in the `volume_spike` object: * `observed` — the number of errors in the most recent one-hour window * `baseline_median` — the project’s typical errors-per-hour (median of the trailing baseline window) * `factor` — the observed volume as a multiple of the baseline median (e.g. `4.7` means 4.7× the typical rate); `null` when the baseline is near zero * `z_score` — the modified z-score that triggered the alert * `window_minutes` — the length of the observed window, in minutes ```json { "event": "volume_spike", "message": "[Testy McTestFace] Errors are 4.7× your normal rate (412 in the last hour vs ~87/hr typical)", "project": { "id": 123321, "name": "Testy McTestFace", "created_at": "2017-08-30T12:54:33.156695Z", "disable_public_links": false, "pivotal_project_id": null, "asana_workspace_id": null, "token": "zzz111", "github_project": "spacely/testy-mctestface", "environments": [ { "id": 68210, "project_id": 123321, "name": "production", "notifications": true, "created_at": "2017-09-05T06:10:19.057794Z", "updated_at": "2017-09-05T06:10:19.057794Z" } ], "owner": { "id": 1, "email": "ben@example.com", "name": "Spacely Sprockets" }, "last_notice_at": "2023-10-30T19:29:08.000000Z", "earliest_notice_at": "2023-05-03T19:37:25.519130Z", "unresolved_fault_count": 102, "fault_count": 925, "active": true, "users": [ { "id": 1, "email": "ben@example.com", "name": "Ben" } ], "sites": [], "team_id": 1 }, "volume_spike": { "observed": 412, "baseline_median": 87, "factor": 4.7, "z_score": 6.2, "window_minutes": 60 } } ``` # Redmine > Connect Honeybadger to Redmine to automatically create issues from errors and track bug fixes in your project. Users with administrative privileges can find this integration below the list of personal alert integrations on the Alerts & Integrations tab of the Project Settings page. ## Setup [Section titled “Setup”](#setup) ### 1. Select the Redmine integration [Section titled “1. Select the Redmine integration”](#1-select-the-redmine-integration) ![redmine integration](/_astro/redmine.D-pcL-w9_ZseKh7.webp) ![redmine form](/_astro/redmine_form.BTsPm9-5_Z14794M.webp) ### 2. Set the server & API key [Section titled “2. Set the server & API key”](#2-set-the-server--api-key) The server URL is the full URL of your server - including `https://`. You can find your API key on your account page when logged into Redmine ### 3. Configure transitions (optional) [Section titled “3. Configure transitions (optional)”](#3-configure-transitions-optional) You can specify the ids of transitions to be run when issues are resolved and reopened. ### 4. Save [Section titled “4. Save”](#4-save) That’s it! You can test the integration by clicking “Test”. Otherwise, just save it and you’re ready to go. # Rootly > Connect Honeybadger to Rootly to automatically trigger incidents from critical errors and application events, and streamline your response workflow. Users with administrative privileges can find this integration below the list of personal alert integrations on the Alerts & Integrations tab of the Project Settings page. ## Setup [Section titled “Setup”](#setup) ### 1. Create a generic webhook alert source in Rootly. [Section titled “1. Create a generic webhook alert source in Rootly.”](#1-create-a-generic-webhook-alert-source-in-rootly) Navigate to the [Alert Sources](https://rootly.com/account/alerts?tab=alert-sources) page in your Rootly account. Locate the **Generic Webhook** alert source and click **Add Source**. Set the Alert Source Name to “Honeybadger”. ![Rootly Webhook Alert Source](/_astro/rootly_webhook.fMHJIpOr_2ihF63.webp) ### 2. Locate the authorization header - credentials [Section titled “2. Locate the authorization header - credentials”](#2-locate-the-authorization-header---credentials) Rootly will generate a webhook token. Copy this value. ![Rootly Webhook Credentials](/_astro/rootly_webhook_credentials.CoG2LWg-_2mbhzg.webp) ### 3. In Honeybadger, locate the Rootly integration. [Section titled “3. In Honeybadger, locate the Rootly integration.”](#3-in-honeybadger-locate-the-rootly-integration) In the project settings, click on the **Integrations** tab where you’ll find the Rootly integration. ![Rootly integration](/_astro/rootly_integration.GNkkiOP0_1NFC89.webp) ### 4. Fill in the required fields and save. [Section titled “4. Fill in the required fields and save.”](#4-fill-in-the-required-fields-and-save) Fill in the Webhook authorization token field with the generated token you copied from step 2. You may optionally specify a target type and target ID. Save the integration. ### 5. Test the integration. [Section titled “5. Test the integration.”](#5-test-the-integration) Click on the “Test this integration” button to send a test notification to your Rootly account. This will send a test payload to the Rootly webhook alert source. ### 6. Configure the Rootly alert source. [Section titled “6. Configure the Rootly alert source.”](#6-configure-the-rootly-alert-source) Now that Rootly has a sample payload, you can easily configure the alert. In your Rootly account, find the configuration settings for the Webhook alert source. Edit the Alert Content and set the following values: * Alert Title: `{{ alert.data.title }}` * Alert Description: `{{ alert.data.description }}` * Link to Alert: `{{ alert.data.url }}` ![Rootly Webhook Configuration](/_astro/rootly_webhook_configuration.DK2KniP__1GspVC.webp) # Shortcut > Connect Honeybadger to Shortcut to automatically create stories from errors and track bug fixes in your project workflow. Users with administrative privileges can find this integration below the list of personal alert integrations on the Alerts & Integrations tab of the Project Settings page. ![shortcut integration](/_astro/shortcut.BwtTJqay_Z1SMc2a.webp) ![shortcut form](/_astro/shortcut_form.DM-ej-5Z_Z211lwa.webp) ## Setup [Section titled “Setup”](#setup) ### 1. Set the organization [Section titled “1. Set the organization”](#1-set-the-organization) This is the name of the organization that you created when you set up your account. You can find this immediately after the domain name in the URL: e.g., for the organization name is honeybadger. ### 2. Set the API token [Section titled “2. Set the API token”](#2-set-the-api-token) Your API Token can be found in the Shortcut UI by clicking on the gear icon for settings, choosing the Your Account link, then choosing the API Tokens link. Choose a name for your token (like Honeybadger) and click Generate Token. Copy the highlighted token, and paste that in the API Token field. ### 3. Fetch custom fields and workflow data [Section titled “3. Fetch custom fields and workflow data”](#3-fetch-custom-fields-and-workflow-data) Click the Fetch custom fields and workflow data button to make a request to the Shortcut API to get your list of teams, custom fields, and workflow states. This will populate and enable the remaining dropdowns on the form. ### 4. Choose the team, custom fields, and workflow states [Section titled “4. Choose the team, custom fields, and workflow states”](#4-choose-the-team-custom-fields-and-workflow-states) Each Honeybadger project is associated with one Shortcut team, and you can make that choice here. In addition, you may also specify custom field choices to apply to your stories. You can also choose which of your Shortcut workflow states will be chosen for stories when they are marked as resolved or unresolved. The stories will be updated to those states if you also enable the respective Error Events options. ## Creating stories from the UI [Section titled “Creating stories from the UI”](#creating-stories-from-the-ui) Users can create stories in Shortcut by clicking the Create Story button on the error detail page in the Honeybadger UI. By default, these stories will be created as the Shortcut user whose API Token is configured in the integration settings. Users can have stories associated with their own Shortcut account by getting an API Token as described previously and adding it to their [authentication settings](https://app.honeybadger.io/users/edit#authentication). # Slack > Connect Honeybadger to Slack to receive real-time application monitoring alerts and resolve issues directly from your team's channels. Users with administrative privileges can find this integration below the list of personal alert integrations on the Alerts & Integrations tab of the Project Settings page. ## Setup [Section titled “Setup”](#setup) ### 1. Select the integration for Slack [Section titled “1. Select the integration for Slack”](#1-select-the-integration-for-slack) ![slack integration](/_astro/slack.CLddJSPe_1GFP9Y.webp) When you click on the link to add Slack to your project, you will be redirected to Slack to approve the connection to your Slack team. After you choose the channel to receive Honeybadger messages and click the Authorize button, you will be redirected back to Honeybadger to finish editing the optional channel settings. ### 2. Save [Section titled “2. Save”](#2-save) That’s it! You can test the integration by clicking “Test”. Otherwise, just save it and you’re ready to go. ## Interactive messages [Section titled “Interactive messages”](#interactive-messages) Messages about errors include a button to resolve or reopen the error: ![Slack notification](/_astro/slack_notification.DW_wrxfK_Z2nbqSN.webp) The first time you click one of the buttons, you will be given a link that will allow you to connect your Slack account to your Honeybadger account. This connection only needs to be done once, and then you will be able to use the buttons and interact with the bot. ## Using the bot [Section titled “Using the bot”](#using-the-bot) Once you have installed the Honeybadger app for Slack, you will have a Honeybadger bot available to your Slack team. You can message the bot directly or you can invite it to join a channel and address it… either way, it understands the following commands: | Command | Description | | ---------------------------------- | ------------------------------------------------------------------------------------------- | | **help** | Get help :) | | **show project *\*** | Returns a list of faults that occurred recently in the *Project Name* project. | | **show fault *\*** | See details about the requested fault. The fault number can be found in the Honeybadger UI. | | **resolve fault *\*** | Mark the specified fault as resolved. | | **reopen fault *\*** | Mark the specified fault as reopened. | # Splunk On-Call > Connect Honeybadger to Splunk On-Call to route critical errors and application monitoring alerts through your incident response and on-call workflow. Users with administrative privileges can find this integration below the list of personal alert integrations on the Alerts & Integrations tab of the Project Settings page. ## Setup [Section titled “Setup”](#setup) ### 1. Select the Splunk On-Call integration [Section titled “1. Select the Splunk On-Call integration”](#1-select-the-splunk-on-call-integration) ![splunk on-call integration](/_astro/splunk_oncall.BylZKKEP_ZrqLvV.webp) ![splunk on-call form](/_astro/splunk_oncall_form.mTOWjcNk_1KpAIo.webp) ### 2. Set the API key [Section titled “2. Set the API key”](#2-set-the-api-key) You can generate a Splunk On-Call API key on the Splunk On-Call integrations page. ### 3. Set the routing key (optional) [Section titled “3. Set the routing key (optional)”](#3-set-the-routing-key-optional) If you like, you can specify an arbitrary routing key for use by Splunk On-Call. ### 4. Save [Section titled “4. Save”](#4-save) That’s it! You can test the integration by clicking “Test”. Otherwise, just save it and you’re ready to go. # Sprintly > Connect Honeybadger to Sprintly to automatically create defects from errors and track bug fixes in your workflow. Users with administrative privileges can find this integration below the list of personal alert integrations on the Alerts & Integrations tab of the Project Settings page. ## Setup [Section titled “Setup”](#setup) ### 1. Select the Sprintly integration [Section titled “1. Select the Sprintly integration”](#1-select-the-sprintly-integration) ![sprintly integration](/_astro/sprintly.DYJu0FNR_ZqMNir.webp) ![sprintly form](/_astro/sprintly_form.CDfEtANi_Z1VVna1.webp) ### 2. Set the email & API key [Section titled “2. Set the email & API key”](#2-set-the-email--api-key) You can get your Sprintly API key by logging into Sprintly and going to your Profile page. The key is at the bottom. ### 3. Set the product ID [Section titled “3. Set the product ID”](#3-set-the-product-id) You can find your product’s id by examining the URL. If your product’s url is `sprint.ly/product/777` then the product id is “777”. ### 4. Save [Section titled “4. Save”](#4-save) That’s it! You can test the integration by clicking “Test”. Otherwise, just save it and you’re ready to go. # Trello > Connect Honeybadger to Trello to automatically create cards from errors and track bug fixes on your Trello boards. Users with administrative privileges can find this integration below the list of personal alert integrations on the Alerts & Integrations tab of the Project Settings page. ## Setup [Section titled “Setup”](#setup) ### 1. Select the Trello integration [Section titled “1. Select the Trello integration”](#1-select-the-trello-integration) ![trello integration](/_astro/trello.C7zKDEjV_Z2pGMxt.webp) ![trello form](/_astro/trello_form.CGdNy2yz_Z10xhEj.webp) ### 2. Connect your Trello account [Section titled “2. Connect your Trello account”](#2-connect-your-trello-account) Just click the button to connect to trello via OAuth. ### 3. Select the board and list [Section titled “3. Select the board and list”](#3-select-the-board-and-list) These two dropdowns will be populated when you connect your account. ### 4. Save [Section titled “4. Save”](#4-save) That’s it! Hit save and you’re good to go. # Webhook > Configure custom webhooks to send Honeybadger error notifications and events to any third-party service or API. Honeybadger sends webhooks when certain events occur in your Honeybadger projects. Each event type has a specific payload structure with relevant data about the event. Users with administrative privileges can find this integration below the list of personal alert integrations on the Alerts & Integrations tab of the Project Settings page. ## Setup [Section titled “Setup”](#setup) ### 1. Select the Webhook integration [Section titled “1. Select the Webhook integration”](#1-select-the-webhook-integration) ![webhook integration](/_astro/webhook.BW8iCqLj_1Kl85L.webp) ![webhook form](/_astro/webhook_form.BWAAfJ1j_1Ci7QR.webp) ### 2. Set the URL for your webhook [Section titled “2. Set the URL for your webhook”](#2-set-the-url-for-your-webhook) We’ll post notifications to this URL. Make sure to include the protocol: e.g., `https://mysite.com/hook`. Make sure you have a service running that can accept POST requests, and hopefully do something interesting with JSON payloads like this one: ```plaintext { "event":"occurred", "message":"[Crywolf/test] RuntimeError - oops", "fault":{ "id":3151009, "project_id":1717, "klass":"RuntimeError", "component":null, "action":null, "environment":"development", "resolved":true, "ignored":false, "created_at":"2014-01-08T18:55:48Z", "comments_count":1, "message":"oops", "notices_count":9, "last_notice_at":"2014-01-08T19:02:21Z" } } ``` See [Event Payloads](#payload-structure) for all available events and their structure. ### 3. Set a bearer token (optional) [Section titled “3. Set a bearer token (optional)”](#3-set-a-bearer-token-optional) Every webhook we send already includes a [`Honeybadger-Token` header](/resources/security/#authenticating-requests-from-honeybadger) you can use to verify that the request came from us. Some services reject a request outright unless it arrives with an `Authorization` header, before your own code ever sees it. If yours is one of them, put the key in the **Bearer token** field and we’ll send it with every request: ```plaintext Authorization: Bearer your-token ``` Leave the field blank if you don’t need it. The token is encrypted at rest, and it’s masked when you come back to the form later. ### 4. Save [Section titled “4. Save”](#4-save) That’s it! Hit save and you’re good to go. ## Payload structure [Section titled “Payload structure”](#payload-structure) Each event payload is sent as a JSON object with the following properties: * `event` - The type of event (e.g., `occurred`, `resolved`, `deployed`) * `message` - A human-readable description of the event * Additional event-specific data (varies by event type) ## Event payloads [Section titled “Event payloads”](#event-payloads) The following events are supported by the Webhook integration: ### [`assigned`](/guides/integrations/payloads/assigned/) [Section titled “assigned”](#assigned) Sent when an error is assigned to a user. **Top-level properties:** `event`, `message`, `actor`, `fault`, `assignee` ### [`cert_will_expire`](/guides/integrations/payloads/cert_will_expire/) [Section titled “cert\_will\_expire”](#cert_will_expire) Sent when an SSL certificate is about to expire. **Top-level properties:** `event`, `message`, `project`, `site` ### [`check_in_missing`](/guides/integrations/payloads/check_in_missing/) [Section titled “check\_in\_missing”](#check_in_missing) Sent when an expected check-in is missing. **Top-level properties:** `event`, `message`, `project`, `check_in` ### [`check_in_reporting`](/guides/integrations/payloads/check_in_reporting/) [Section titled “check\_in\_reporting”](#check_in_reporting) Sent when a check-in reports successfully. **Top-level properties:** `event`, `message`, `project`, `check_in` ### [`commented`](/guides/integrations/payloads/commented/) [Section titled “commented”](#commented) Sent when a comment is added to an error. **Top-level properties:** `event`, `message`, `actor`, `fault`, `comment` ### [`deployed`](/guides/integrations/payloads/deployed/) [Section titled “deployed”](#deployed) Sent when a deployment is recorded. **Top-level properties:** `event`, `message`, `project`, `deploy` ### [`down`](/guides/integrations/payloads/down/) [Section titled “down”](#down) Sent when an uptime check fails. **Top-level properties:** `event`, `message`, `project`, `site`, `outage` ### [`occurred`](/guides/integrations/payloads/occurred/) [Section titled “occurred”](#occurred) Sent when an error occurs. **Top-level properties:** `event`, `message`, `project`, `fault`, `notice` ### [`rate_exceeded`](/guides/integrations/payloads/rate_exceeded/) [Section titled “rate\_exceeded”](#rate_exceeded) Sent when error rate threshold is exceeded. **Top-level properties:** `event`, `message`, `project`, `fault` ### [`resolved`](/guides/integrations/payloads/resolved/) [Section titled “resolved”](#resolved) Sent when an error is marked as resolved. **Top-level properties:** `event`, `message`, `project`, `fault` ### [`unresolved`](/guides/integrations/payloads/unresolved/) [Section titled “unresolved”](#unresolved) Sent when a resolved error occurs again. **Top-level properties:** `event`, `message`, `project`, `fault` ### [`up`](/guides/integrations/payloads/up/) [Section titled “up”](#up) Sent when an uptime check succeeds after being down. **Top-level properties:** `event`, `message`, `project`, `site`, `outage` ### [`volume_spike`](/guides/integrations/payloads/volume_spike/) [Section titled “volume\_spike”](#volume_spike) Sent when a project’s error volume spikes above its learned baseline. **Top-level properties:** `event`, `message`, `project`, `volume_spike` # Zulip > Connect Honeybadger to Zulip to receive real-time application monitoring alerts directly in your team's streams. Users with administrative privileges can find this integration below the list of personal alert integrations on the Alerts & Integrations tab of the Project Settings page. ## Setup [Section titled “Setup”](#setup) ### 1. In Zulip, create a new incoming webhook bot. [Section titled “1. In Zulip, create a new incoming webhook bot.”](#1-in-zulip-create-a-new-incoming-webhook-bot) You’ll need to create a new Incoming Webhook Bot in Zulip. This is done by going to the **Settings** page of your Zulip organization and selecting **Bots** from the left-hand menu. ![zulip incoming webhook](/_astro/zulip_incoming_webhook.BNl3bYqQ_ZN5wfd.webp) ### 2. In Honeybadger, locate the Zulip integration. [Section titled “2. In Honeybadger, locate the Zulip integration.”](#2-in-honeybadger-locate-the-zulip-integration) In the project settings, click on the **Integrations** tab where you’ll find the Zulip integration. ![zulip integration](/_astro/zulip_integration.BHJN9itz_2tfUl9.webp) ### 3. Fill in the required fields and save. [Section titled “3. Fill in the required fields and save.”](#3-fill-in-the-required-fields-and-save) Fill in the required fields which you generated in step 1. Configure which notifications you wish to receive and then save. You can also click on the “Test this integration” button to send a test notification to your Zulip stream. This is a great way to ensure that everything is set up correctly before you start receiving real notifications. ![zulip notification](/_astro/zulip_notification.oeKSD_Do_Z1rGcUp.webp) # Projects > Projects contain your errors, check-ins & uptime. Almost everything in Honeybadger is scoped to a project. We have some powerful configuration features to help you manage your errors. At the top of the project page, there are tabs for the windows containing all aspects of the project. ![Project navigation bar with tabs for Errors, Insights, Dashboards, Alarms, Uptime, Check-Ins, Deployments, Reports, and Settings](/_astro/project-subnav-settings.U7L_k3Qe_DHHIy.webp)![Project navigation bar with tabs for Errors, Insights, Dashboards, Alarms, Uptime, Check-Ins, Deployments, Reports, and Settings](/_astro/project-subnav-settings-dark.E8kvOATT_ZNb0ax.webp) ## General project settings [Section titled “General project settings”](#general-project-settings) ![Project settings page with the General tab selected in the left sidebar, showing the Name, Error Retention, Resolve errors on deploy, User URL, and Source URL fields](/_astro/project-general-settings.Dtm5n6dD_1X0Bnd.webp)![Project settings page with the General tab selected in the left sidebar, showing the Name, Error Retention, Resolve errors on deploy, User URL, and Source URL fields](/_astro/project-general-settings-dark.D4yJzH8x_Z9XfsU.webp) The General tab holds the project’s core settings. ### Error retention [Section titled “Error retention”](#error-retention) **Error retention** is the number of days an error is kept after its last occurrence. The maximum for your project is shown below the field. Lower it if you need to enforce a data retention policy for compliance reasons. Error data, including any context you send, is deleted once the retention period expires. ### Resolve errors on deploy [Section titled “Resolve errors on deploy”](#resolve-errors-on-deploy) The **Resolve errors on deploy** setting automatically marks all errors “resolved” when you [report a deployment](/api/reporting-deployments/), causing new alerts to be sent for any errors that re-occur. When turned off, you can resolve individual errors on the next deploy from the [actions area](/guides/errors/#resolve-on-deploy) on the error page. ### Linking to your users and code [Section titled “Linking to your users and code”](#linking-to-your-users-and-code) Honeybadger can only show what your app sends it, but these settings let the error detail page connect that data back to the systems you already use: your admin tools, your source repository, and your own domains. The **User URL** field can be used to add a link in the Honeybadger UI to a URL you specify (such as an internal admin tool) with the user ID populated from the `context.user_id` data in your error report. When this field is populated and an error notification includes the user\_id data, a button labeled “View user” is added to the error detail page that you can use to click through to the User URL: ![Project context showing User URL button](/_astro/project_user_url.DTuOCaZL_Eaqnj.webp) If your context includes the user ID in a field other than `context.user_id`, you can use the **User search field** setting to specify where in your payload the user ID exists. You can also use this to override what field should be used as your user ID — e.g., you could specify `context.user_email` if you’d prefer to use email addresses rather than IDs. Regardless of the field you use, that field’s value will be stored as the **user** in the search index and displayed in the notice timeline list and elsewhere in the UI. ![User value displayed in notice timeline on error detail page](/_astro/project_user_in_timeline.C82aNEs0_Z1jREAH.webp) The **Source URL** field customizes the source code links in error backtraces. If you use the [GitHub integration](/guides/integrations/github/), links are generated automatically and you can leave this blank. For other hosts, enter a URL template using the `[sha]`, `[file]`, `[line]`, and `[method]` placeholders. For example: ```plaintext https://github.com/your-username/your-repo/blob/[sha]/[file]#L[line] ``` **Linkable domains** restricts which request URLs are rendered as clickable links on the error detail page. Enter a space-delimited list of domains, or leave it blank to link all URLs. ### Throttle [Section titled “Throttle”](#throttle) The **Throttle** field allows you to set a limit for the number of errors the project can receive per minute. This can be useful for preventing a noisy project (like one dedicated to a QA or staging environment) from consuming too much of your quota. ### Public error pages [Section titled “Public error pages”](#public-error-pages) You can make an error public by clicking “Share URL” in the [actions area](/guides/errors/#error-actions) of the error you want to share. We provide you with a unique URL to give to collaborators. This is great but can be cumbersome when sharing multiple errors. Public Error Pages are a place where collaborators can view shared errors. Once you enable the Public Error Page (**Project settings → General → Enable public dashboard**), collaborators can find shared errors in a similar view as the error listing page (with some restrictions). This can be especially useful if you pair this feature with [Project Actions](#project-actions). If you never want errors shared outside your team, check **Disable public links**. This removes the “Share URL” button from error pages and also disables the public dashboard. ### Transfer project [Section titled “Transfer project”](#transfer-project) You can transfer a project to another account by choosing it from the dropdown. Before you do, note that: * The new owner becomes responsible for payment. * You keep access to the project unless the new owner removes you. * The project is removed from any teams it was assigned to, so members of those teams lose access. To move *everything* (projects, teams, and billing) to another user, add them as an account owner on the Account Settings page instead. See [Accounts](/guides/accounts/) for details. ### Delete project [Section titled “Delete project”](#delete-project) At the bottom of the General tab is the project delete button. Deleting a project removes all of its data immediately and cannot be undone. ![Delete project button](/_astro/delete_project.DJrjaF9c_ZpqVtE.webp) ## Insights [Section titled “Insights”](#insights) The Insights tab shows your current Insights data limits and has a link to the Insights stats page, which can also be found by navigating to the API stats for a project. To read more about configuring Insights, check out the [Insights](/guides/insights/) documentation page. ## Users [Section titled “Users”](#users) From the Users settings tab, you can see and manage which users have access to the project and what teams are assigned to the project. This page also lets you see the members of each team currently assigned to the project. Users can have admin privileges for a project if you add them individually while specifying the admin permission or if they have admin privileges on a team that is assigned to the project. Users having admin privileges at the account level (managed via the Users tab of the Account Settings page) will also have admin rights on the project. To read more about user management, check out the [User Management](/guides/user-management/) documentation page. ## Environments [Section titled “Environments”](#environments) ![Environments settings tab showing a search for production-web, three matching environments with two selected, per-row notification and forget buttons, and a Bulk actions dropdown](/_astro/manage-project-environments.DW47F2pc_25Qm1o.webp)![Environments settings tab showing a search for production-web, three matching environments with two selected, per-row notification and forget buttons, and a Bulk actions dropdown](/_astro/manage-project-environments-dark.o_stNvB-_1twmfX.webp) The Environments tab lists every environment that has reported errors to the project. Environments are added automatically as errors arrive from them, so you don’t need to create them ahead of time. For each environment, you can: * **Toggle notifications** with the bell icon. Turning notifications off for an environment (such as `development` or `staging`) keeps its errors in your project without alerting your team. * **Forget the environment** with the trash icon. This removes the environment from the list. It will be re-added if the environment reports another error. If you deploy to many environments (for example, one per pull request or per-customer instance), use the search box to filter the list by name. Long lists are paginated. Select one or more environments with the checkboxes, then use the **Bulk actions** dropdown to toggle notifications or forget all of the selected environments at once. Environments can also be managed with the [Environments API](/api/environments/) or the [`hb environments` CLI command](/resources/cli/environments/). ## Alerts & integrations [Section titled “Alerts & integrations”](#alerts--integrations) The Alerts and Integrations tab allows you to edit the notifications you receive as a user for the project. If you have admin privileges for the project, you can also manage the integrations (such as GitHub, Slack, etc.) that are connected to the project. To read more about managing integrations, check out the [Integrations](/guides/integrations/) documentation page. ## API keys [Section titled “API keys”](#api-keys) Project API keys grant access to our reporting APIs. The list of reporting endpoints is in our [API docs](/api/). If an API key is leaked or misused, you can rotate your key by adding a new key and removing the old one. Note Project API keys don’t grant access to our REST API. You will need to use your [personal token](/api/getting-started/#authentication) for that. ## Project actions [Section titled “Project actions”](#project-actions) Project Actions let you customize your errors as we receive them. Through actions, you can automatically: * Assign errors to yourself or another team member * Add tags * Pause notifications * Share errors publicly One exciting usage example for Project Actions is assigning errors to specific code owners. For example, Ben takes care of most of the billing code here at Honeybadger. It would make sense that he should be assigned any errors related to billing. Here is a simple setup to route `StripeController` errors to Ben: ![Basic Project Actions setup](/_astro/project_action_create.CVdz3v1T_Zz7ylI.webp) You can run all your incoming errors through the actions, or you can use the query box to constrain which errors have actions applied to them. The query box works identically to the search box when navigating on the error tab. ## Source maps [Section titled “Source maps”](#source-maps) Honeybadger can automatically un-minify your code if you provide a source map along with your minified JavaScript files. The tab for Source Maps in Project Settings allows you to choose whether or not to download your source maps. It also contains a list of the currently stored source maps and a debugging tool that you can use to diagnose problems with source map processing. For more on source maps, check out the [Source Maps](/lib/javascript/errors/using-source-maps/) documentation page. ## One language per project [Section titled “One language per project”](#one-language-per-project) We often get asked if users can have multiple programming languages in a project. While it is technically possible, we recommend that you create a separate project for each application or repository. # Reports > Viewing and understanding reports. The Reports page of a project includes summary charts of error data grouped by location, class, day, and affected user, as well as a summary of the project’s uptime checks. ![Errors by class chart](/_astro/reports.rZz-jEZH_Z1LvBUe.webp) Clicking on a bar in one of the bar charts will take you to a search for errors matching the selected location, class, or user. # Status pages > Give users insight into your system status. Your Honeybadger account comes with customizable status pages. Give your users insights into the working state of your system by connecting uptime checks or providing updates during problems via incidents. Here’s a [live example](https://uptime.honeybadger.io/) of our Honeybadger status page. Tip You can find your status pages and create a new one [here](https://app.honeybadger.io/status_pages). ## Customizing your status page [Section titled “Customizing your status page”](#customizing-your-status-page) You can customize your status page with your company logo and favicon from *Status Pages* → *Your Status Page* → *Edit*. If you upload a dark logo variant, we’ll use that version with our built-in dark mode theme. ![Status page settings](/_astro/status-page-settings.BhJ84Wsq_JCOQX.webp) For more control over the look and feel of your status page, see the “Custom CSS” option under *Customization* at the bottom of the settings form. ## Adding a custom domain [Section titled “Adding a custom domain”](#adding-a-custom-domain) To add a custom domain, enter the domain (without the http(s)://) when editing your status page. To verify your domain, add a CNAME DNS record with a value of **status.hbuptime.com**. For example, if your domain is status.example.com, then you should add the following CNAME through your DNS provider (Google Domains, Amazon Route 53, GoDaddy, etc.): | Record type | Label/Host field | Time To Live (TTL) | Destination/value | | ----------- | ------------------ | --------------------------- | ------------------- | | CNAME | status.example.com | default is fine (i.e. 3600) | status.hbuptime.com | **Once the record has been created, click the “Verify” button under your status page back in Honeybadger:** ![Verify status page domain](/_astro/verify_status_page_domain.apJyFu6U_ZbDg8y.webp) Now you can visit your domain in a browser. We automatically generate SSL certificates; it should be ready to go on the first visit, but in some cases you may need to refresh a few times. If you have trouble, don’t hesitate to [get in touch](https://www.honeybadger.io/contact/). ## Uptime checks [Section titled “Uptime checks”](#uptime-checks) Connect any currently running uptime checks to your status page if you’d like to share your uptime status with the world. Status pages may include uptime checks across all of the projects in your account. ![Status page index](/_astro/status_page_index.BXmVFDZM_1t5lIW.webp) ### Connecting checks [Section titled “Connecting checks”](#connecting-checks) While editing your status page, toggle which uptime checks you would like included with your status page. ![New status page form](/_astro/new_status_page.CQQ2xUkH_Z2n0wXh.webp) Give each uptime check an optional display name if you want to customize the name displayed publicly. That’s it! We will show each uptime check’s current status and history on your public status page. ## Incidents [Section titled “Incidents”](#incidents) ![Active public incident update](/_astro/active_public_incident_update.BxCfwfGx_1IdXlV.webp) An incident is an effective way to communicate system issues to your users. It can also inform your users of upcoming planned maintenance or downtime. Conceptually, an incident is a container for timestamped updates that describe the context surrounding a problem affecting your system. An incident can be as simple as a single update that explains some minor downtime, or it can span multiple days with many updates, each representing the changing severity and status of the incident. ### Creating incidents [Section titled “Creating incidents”](#creating-incidents) We provide three scenarios when creating incidents: `Current`, `Scheduled Maintenance`, and `Retroactive`: #### Current [Section titled “Current”](#current) ![Current incident input](/_astro/current_input.BR_a7ckp_ZgHx7t.webp) Current incidents start with one update and are typically open after creation (meaning you would not select “Resolved” as the starting status.) #### Scheduled maintenance [Section titled “Scheduled maintenance”](#scheduled-maintenance) ![Scheduled maintenance input](/_astro/scheduled_maintenance_input.CR-KNs4F_2biwBf.webp) Scheduled Maintenance incidents are notable because you can queue updates for later posting. Note This is the only place you can submit an update to post in the future. You can create up to three future updates, which we will post at the supplied `Start Time`. Typically you will send out a `Maintenance scheduled` update that describes the type of maintenance you will perform and when. After that, we have both `In Maintenance` and `Maintenence complete` statuses that you can queue up as individual updates. It’s up to you how much lead time to give your users, based on how you stagger the timing of each update. ![Send now button](/_astro/send_now.-U_Bx2Vw_Z2QKt9.webp) If you complete your maintenance sooner than expected, you can always edit the queued update and use the “send now?” button to post the update immediately. #### Retroactive [Section titled “Retroactive”](#retroactive) ![Retroactive incident input](/_astro/retroactive_input.BHxr_mhT_Z1Nd8wf.webp) Retroactive incidents give you a tool to create multiple incident updates in one operation. You can create a closed incident from months ago or an open incident that started minutes ago. If you don’t end with a [closing update](#open-and-closed-incidents), the incident will be considered open. A retroactive incident also allows you to craft a single [announcement](#announcing-updates) message to accompany your incident updates. This way, you have the option to summarize the incident yet keep each event as separate updates. Note You can not announce each update individually via a retroactive incident. ### Posting an update [Section titled “Posting an update”](#posting-an-update) ![Posting updates interface](/_astro/posting_updates.CfZXPDul_Zl0aRS.webp) When you are ready to inform your users with an update to your incident, click the button in the incident header and fill in your update inline. ### Severity and status [Section titled “Severity and status”](#severity-and-status) When you create an incident or post a new update, you choose a `status` and `severity`. `status` describes where you are in the process of resolving your incident and `severity` describes how your system is currently affected by the incident. Scheduled maintenance incidents have a special set of statuses. You can, however, post an update during scheduled maintenance with an incident status, say if things go awry. ### Open and closed incidents [Section titled “Open and closed incidents”](#open-and-closed-incidents) Note An incident update with a `Resolved` or `Maintenance complete` status will close the containing incident. An incident, when created, is considered “open.” It will be prominently displayed on your internal status page and made visible as an “active incident” on your public status page. When you provide an update containing a status that closes the incident, it will be “closed” and moved to the historical list of closed incidents. Even if you have closed an incident with an update, you can always re-open it by posting an update with a new status. While this is possible and useful if something comes up right after closing an incident, we recommend you open a new incident if a significant amount of time has passed. ### Announcing updates [Section titled “Announcing updates”](#announcing-updates) ![Tweet announcement](/_astro/tweet.DZxPd6zU_Z1WkNqJ.webp) We provide the option to connect your status page to a Twitter account (while editing the status page). Linking your Twitter enables us to announce your incident updates to the world. Once connected, a new “Announce” option will be available while crafting any incident updates. ![Twitter authentication](/_astro/twitter_auth.CNxmM2Kk_VJ74t.webp) If your account is on a Business or Enterprise plan, the “Announce” option is also available without a connected Twitter account, and it sends the update to your [email subscribers](#email-subscriptions) as well. ## Email subscriptions [Section titled “Email subscriptions”](#email-subscriptions) Visitors to your status page can subscribe by email to receive a message whenever you announce an incident update or a scheduled maintenance event. No setup is required: when your account is on a Business or Enterprise plan, a “Subscribe” button appears automatically on each of your status pages. ### How subscribing works [Section titled “How subscribing works”](#how-subscribing-works) 1. A visitor enters their email address in the Subscribe form. 2. We send a confirmation email from `notifications@honeybadger.io`. The subscription isn’t active until the visitor clicks the confirmation link (double opt-in). Unconfirmed subscriptions expire after 7 days. 3. Once confirmed, the subscriber receives an email each time you post an update with the “Announce” option checked. Confirming doesn’t send anything by itself—new subscribers hear from you the next time you announce an update. Every notification email includes a one-click unsubscribe link, and subscribers can unsubscribe at any time. Addresses that hard-bounce or report a message as spam are unsubscribed automatically. ### What gets sent [Section titled “What gets sent”](#what-gets-sent) * Updates to [current](#current) incidents and [scheduled maintenance](#scheduled-maintenance) with the “Announce” option checked get sent * Scheduled events send an email at the event’s start time * Multiple updates to the same incident posted within a minute or two are combined into a single email, so a flurry of quick edits doesn’t flood your subscribers’ inboxes. ### What doesn’t get sent [Section titled “What doesn’t get sent”](#what-doesnt-get-sent) * Updates posted with the “Announce” option unchecked are not sent. * [Retroactive](#retroactive) incidents are never emailed to subscribers. ### Managing subscribers [Section titled “Managing subscribers”](#managing-subscribers) Your status page’s info page in Honeybadger shows an “Email Subscribers” card with the current subscriber count. Click “Manage” to see the list of confirmed subscribers and remove any of them. A removed subscriber will not receive further emails and can’t re-subscribe with the same address. Each status page can have up to 500 subscribers (pending confirmations count toward this limit). ### Subscribing to password-protected pages [Section titled “Subscribing to password-protected pages”](#subscribing-to-password-protected-pages) If your status page is [password protected](#password-protection), visitors must enter the page’s username and password before they can subscribe. To avoid leaking private details, notification emails for protected pages contain only a generic “status changed” message and a link back to the page, not the incident text. ### Plan changes [Section titled “Plan changes”](#plan-changes) If your account moves to a plan that doesn’t include this feature, the Subscribe button disappears and no further emails are sent. Your subscriber list is kept, and notifications resume for future updates if you upgrade again. ## Password protection [Section titled “Password protection”](#password-protection) Honeybadger status pages can be configured to require a username and password before they can be viewed. This is useful for private or internal status pages that only those in your company should be able to view. To enable password protection, edit your status page and check the “Require a username and password” checkbox. Set your desired username and password in the fields below. If you are using a password manager, be sure you don’t overwrite your login information for the Honeybadger app itself. ![Password protection settings](/_astro/status_page_password_protection.C8VGDXUf_14vo7D.webp) ## Embedding status updates [Section titled “Embedding status updates”](#embedding-status-updates) ![Status page embed example](/_astro/status_page_embed_example.DPO1Xqde_2lUECV.webp) Incident management often requires communicating outages with your customers. With the status page embed feature, you can keep your users up to date when they visit your website. ### Setup and usage [Section titled “Setup and usage”](#setup-and-usage) Each of your status pages will have their own unique installation instructions, go to your status page info page, you’ll find the link towards the bottom of the page. ![Embed link](/_astro/status_page_embed_link.DuyPibn7_1jFBrb.webp) Copy the snippet of code and paste it anywhere in the HTML of your site. ![Embed instructions](/_astro/status_page_embed_instructions.00VMly2j_N7Iiz.webp) Like the status page, when you start an incident, the embed feature will always display the latest update to your users. ### Customization [Section titled “Customization”](#customization) The embed pop-up can be customized to better fit the look and feel of your site. Use the customization tool to adjust how you want it too look. When you are ready, copy and paste the HTML snippet onto your site. Here are some of the options you can customize: * **Position** — Change where the popup will appear: bottom left (default), bottom right, top left, or top right. * **Font color** — Set the font color of the text. Any valid CSS font color value can be used. * **Background color** — Set the background color of the pop up. Any valid CSS color value can be used. * **Close button behavior** — By default, the pop up will always show on page load. You can enable the persist feature so that when your visitor closes the pop-up, a browser cookie will be set so that it doesn’t pop up again until your next update. The cookie gets set to expire upon browser or session close. ![Embed customization](/_astro/status_page_embed_customization.CpIB-bSg_Nto31.webp) ### Displaying scheduled maintenance [Section titled “Displaying scheduled maintenance”](#displaying-scheduled-maintenance) The status page embed works great with the schedule maintenance feature. Create your scheduled maintenance messages as noted above. Once the “Start Time” for your messages have passed, your visitors will see the latest update on your site via the embed pop up. ### Displaying non-incident messages [Section titled “Displaying non-incident messages”](#displaying-non-incident-messages) If you have both an ongoing incident and a non-incident message enabled at the same time, the incident update messages will take precendence over the non-incident message. ### Password-protected status pages [Section titled “Password-protected status pages”](#password-protected-status-pages) If your account has the password protected feature and you have enabled the feature for your status page, the embed feature will become disabled. To use the embed feature, you’ll need to disable the password protection feature. ## SEO and analytics [Section titled “SEO and analytics”](#seo-and-analytics) ![SEO and analytics settings](/_astro/status_page_seo_and_analytics.CEZ-Fc_X_GDmQu.webp) ### Search engine indexing [Section titled “Search engine indexing”](#search-engine-indexing) By default, search engines can find and index your status pages—meaning they can end up in search results. You can turn off this behavior by checking the “Do not allow search engines to index my search page” checkbox. Search engines may take time to update their results if your status page is already indexed. If you want added protection and privacy, look at our [Password Protection](#password-protection) feature to prevent unwanted access to your Status Page. ### Google Analytics [Section titled “Google Analytics”](#google-analytics) You can also add your Google Analytics ID to enable Google Analytics tracking for your Status Page. # Uptime monitoring > Get notified when your API is unresponsive. Your Honeybadger account comes with uptime monitoring. Our geographically distributed network of friendly robots will ping your site every few minutes. If a check fails, we’ll let you know. You can set up fairly sophisticated checks based on the HTTP status code, or the response body. ![Site overview](/_astro/site_overview.Cpi0Z8zf_cCqCU.webp) ## Setup [Section titled “Setup”](#setup) Note Enabling bot protection on Cloudflare-hosted websites may prevent uptime checks from working. ![New uptime check form](/_astro/new_site.5p4bv1U-_1UOTUx.webp) When creating an uptime check, just tell us what URL you want monitored. You can choose what counts as a success response from these options: * **Success** - notifies you that your site is down when your server responds with a non-20x status code. When in doubt, this is the one you probably want. * **Exact** - prompts you to enter an HTTP status code. If you entered 302 it would ensure that the server responds with a 302 status code. * **Response body includes string** - prompts you for a string (i.e. “Error”) and notifies you when the response body matches. * **Response body excludes string** - prompts you for a string and notifies you if the response body does *not* match. * **Response body matches JMESPath expression** - allows you to specify a [JMESPath](https://jmespath.org) expression that is evaluated against the JSON returned in the response. For example, an expression like ``queue.depth < `10` ``will evaluate to true for a JSON response like `{"queue":{"depth":2}}`. You have the option to specify response header checks. For example, you can check if the response header `Content-Type` contains `application/json`, or whether the `location` header redirects to the correct URL. All response header checks must evaluate to true for the check to be considered successful, and the check values are case-sensitive. You can also choose to send custom request headers or a custom request body, check the validity of the SSL certificate, and select which locations should be used for monitoring. You can optionally give each of your uptime checks a custom name, which will be the default label for when included on a Status Page. Hit “save” and you’re done! ### Timeouts [Section titled “Timeouts”](#timeouts) Each uptime check has a timeout of 30 seconds by default. If your URL does not respond within this time, it will be marked as failed for that location. Business and Enterprise customers can customize the timeout setting for their uptime checks. The timeout field allows you to specify how long the uptime check will wait for a response before reporting the site as down. The default is 30 seconds and the maximum is 120 seconds. ## Outage notifications [Section titled “Outage notifications”](#outage-notifications) ![Site down email notification](/_astro/down_email.DvYcmIxg_Zxey40.webp) When your site goes down, we’ll notify you with all the details about what went wrong, including how your check failed. For example, you will see receive a notification like this one when the uptime check expected a successful status code but returned a 500. By default, the notification is sent after half of the locations report a failing check. This means that if you are using five locations, there would need to be three failures in a row before you would receive an alert. You can override this default by specifying a value for the Outage Threshold field. ## Outage details [Section titled “Outage details”](#outage-details) When you get a notification that a check has failed, we’ll also link you to a web page with details. This detailed view can be accessed by clicking the “View” link for any particular uptime check in the UI. At the top, the average load time over the past week will be displayed, as well as the uptime check itself. ![Outage details load time](/_astro/outage_details_load.C8TIeG1Q_ZtkdrF.webp) Scrolling down, you can see the uptime on a percentage-monthly basis. ![Outage details history](/_astro/outage_details_history.BnGEaECf_ZnzBJt.webp) Finally, the most recent checks will be displayed, and below that, a list of the uptime check’s most recent outages. ![Recent outages](/_astro/outage_details_recent_outages.CfdXxMmr_1dKtvx.webp) ## SSL certificate warnings [Section titled “SSL certificate warnings”](#ssl-certificate-warnings) We’ll send you a daily warning when your SSL certificates are about to expire. To enable warnings, check the “Check SSL certificate” option when editing your uptime check: ![Check SSL certificate option](/_astro/check_ssl_certificate.C1-tOt8L_1yhLPQ.webp) You should also check the “When my SSL certificates are about to expire” event when editing [alerts and integrations](/guides/integrations/): ![Uptime alert events](/_astro/uptime_alert_events.Dl2yGSVY_MLECb.webp) ## Status page integration [Section titled “Status page integration”](#status-page-integration) Check out our [Status pages](/guides/status-pages/#uptime-checks) feature for presenting your uptime checks to your users. # User management > User membership for projects, teams, and accounts. Honeybadger is much more fun when you bring some friends to the party. The easiest way to do so is to assign projects to a team, then [invite users to join your team](#how-to-invite-a-team-user). ## What can users do? [Section titled “What can users do?”](#what-can-users-do) Our paid plans let you invite your co-workers to collaborate on your projects. The table below gives examples of what different kinds of users can do. | | Account Owner | Admin | Member | | --------------------------------------------------------- | :-----------: | :---: | :----: | | Work with errors, uptime, check-ins, etc. | ✅ | ✅ | ✅ | | Configure personal alerts, like email | ✅ | ✅ | ✅ | | Configure chat, issue tracker and repository integrations | ✅ | ✅ | | | Invite and manage users | ✅ | ✅ | | | Assign projects to teams | ✅ | ✅ | | | Manage account billing | ✅ | ✅ | | | Transfer projects to another account | ✅ | | | | Cancel subscription and delete account | ✅ | | | ## Inviting users [Section titled “Inviting users”](#inviting-users) You have three options when inviting users. You can invite them… * **To a project:** Inviting a user directly to your project is the easiest route, as long as you only have one or two projects. * **To a team, which has been assigned the project:** This is the best route if you have more than a handful of users and projects. * **To an account:** Users are automatically added to an account when added to a project or team, but adding users to an account is the way to go when you want those users to have the Owner role. ### How to invite a project user [Section titled “How to invite a project user”](#how-to-invite-a-project-user) To invite a project user, go to the “Settings” tab when viewing a project and click on “Users” in the sidebar. Use the form to enter their email address and choose their permissions for the project. Your invitee will get an email with instructions on how to proceed. ![Invite project collaborator](/_astro/add_user.BgWTJLYs_ZVWGgR.webp) ### How to invite a team user [Section titled “How to invite a team user”](#how-to-invite-a-team-user) View the Users tab on the team detail page to invite a team user. You’ll see a form where you can enter their email address and choose their permissions for the team. ![Invite team member](/_astro/team_invite.DagCiKMS_1vX7xO.webp) If you’re not sure which team is associated with a project, you can see the list of teams that are connected to a project on the Users tab of the Project Settings page. ![Finding the team for a project](/_astro/team_link.CTdaijbi_2iTy9T.webp) ### How to invite an account user [Section titled “How to invite an account user”](#how-to-invite-an-account-user) Go to the Users tab of the [account settings](/guides/accounts/#account-settings) page to add a new user to your account: ![Invite account user](/_astro/add_account_user.D4iBbkZ9_Z2lpvsI.webp) When adding a user, you can choose which role the user should have (Owner, Admin, or Member), and which teams that user will be able to access. As with project and team invitations, users will receive an email with a link to join the account. ## SAML SSO [Section titled “SAML SSO”](#saml-sso) You can optionally provide single-sign on (SSO) to your team members via one of our supported SSO providers: Google Apps for Work, Okta, or OneLogin. Provider-specific configuration instructions are found on the Authentication tab in [account settings](/guides/accounts/#account-settings). Generally speaking, the configuration process goes like this: 1. Create a custom SAML app in your provider’s admin dashboard. 2. Download the IdP metadata from your provider and add it to your Honeybadger SAML configuration. 3. Configure the custom SAML app with the information provided on the SAML configuration page in the app. After those steps are completed, your team members can log in through your SSO provider’s dashboard, or they can enter the SSO name provided in the SAML configuration when signing in to Honeybadger. ### Role mapping [Section titled “Role mapping”](#role-mapping) You can assign account roles automatically based on a SAML assertion attribute, such as a Google Workspace group. In the **Role Mapping** section of your SAML configuration, enter the name of the attribute that carries group membership (e.g., `groups`), then add rules that map attribute values to account roles. On each SAML login, we compare the values of the configured attribute against your rules and apply the highest-privilege matching role (Owner over Admin over Member). A few things to keep in mind: * Values are matched exactly (case-insensitive) — a rule’s value must equal what your identity provider sends. To help you write rules, the SAML configuration page displays the attribute names and values from the most recent sign-in. * Users who match no rule keep their current role — removing a user from all mapped groups does not demote them. * Role mapping will never demote the account’s only remaining Owner, and only account Owners can add or change rules that grant the Owner role. ### Team mapping [Section titled “Team mapping”](#team-mapping) You can also manage team memberships and permissions from your identity provider. In the **Team Mapping** section of your SAML configuration (shown when your account has at least one team), add rules that assign an attribute value — a group, for example — to a team and a permission level (Member or Admin). Team mapping rules use the attribute name configured in the **Role Mapping** section, so be sure to set that first. On each SAML login, the user’s SAML-managed team memberships are synced from their groups: * When an attribute value matches a rule, the user is added to the mapped team with the mapped permission. * When the user’s groups (or your rules) change, their team permission is updated in place — their per-project notification settings are preserved. * When the user no longer has a group that maps to a team, they are removed from that team. * If multiple rules match the same team with different permissions, Admin wins over Member. Team mapping only manages memberships that it created. Memberships created by a manual invitation or by the **Team Access** option (which automatically adds all SSO users to the selected teams) are never modified or removed by team mapping. If a user already belongs to a team via one of those, a team-mapping rule won’t change their permission. When a team has both a mapping rule and **Team Access** enabled, a user who loses their mapped group stays on the team as a regular Team Access member instead of being removed. ## Restricted authentication [Section titled “Restricted authentication”](#restricted-authentication) We provide more control over your users’ login sources when enabling “Restricted Authentication” for your account. You can manage restricted authentication from the Authentication tab in [account settings](/guides/accounts/#account-settings). A common use case is to require users to use SSO instead of being able to log in with a password. #### Auth sources [Section titled “Auth sources”](#auth-sources) ![Auth sources](/_astro/account_auth_sources.BimUnNAP_ZkKc0q.webp) You can select which authentication sources are allowed to access your account. If you require only SAML login, you can disable all other available sources. When a user accesses your account via password, we will redirect them to your custom sign-in page with a link to your SAML provider. #### Session duration [Section titled “Session duration”](#session-duration) You also have control of your users’ session duration, per auth source. For example, daily reauthentication with your SAML provider can be achieved by updating the “Session expire duration” for your SAML auth source. #### Custom sign-in page [Section titled “Custom sign-in page”](#custom-sign-in-page) Restricted auth accounts have access to a custom sign-in page. We will only show your active auth sources as sign-in options. ![Account custom sign-in](/_astro/account_sign_in.BV_ah0SB_Z1IS7Xs.webp) ## Multi-factor authentication [Section titled “Multi-factor authentication”](#multi-factor-authentication) Honeybadger supports multi-factor authentication (also known as two-factor authentication, 2FA, or MFA) via Google Authenticator, Authy, and similar 2FA providers. Account owners can require multi-factor authentication for all users from the Authentication tab in [account settings](/guides/accounts/#account-settings). ![MFA requirement interface showing notification 'All account users must have MFA enabled to access this account' with Disable MFA Requirement button, Compliance Status at 100% compliant, and Users Requiring MFA section confirming all users have MFA enabled](/_astro/account_mfa_requirement.CZYKglJ-_OBfES.webp) When enabled, we’ll notify the users who need to set it up via email, and prompt them to enable it on their next login. # User settings > Your personal preferences. Note For information about inviting users to your projects or teams, check out our [User Management Guide](/guides/user-management/). This guide is meant to help people configure their personal preferences when they’ve already joined a project. User accounts in Honeybadger are very similar to those in GitHub. Each user is his or her own person. While project admins can configure project-level integrations like Slack, each individual user has complete control over their personal alerts and other user settings on the [User Settings](https://app.honeybadger.io/users/edit) page. Here are some examples of “personal settings”: * Name and connected email * Localized date and time preferences * Connection to GitHub and other 3rd-party accounts * Daily and weekly digest email settings for all projects * Local editor selection for links displayed on backtraces The user settings page is also where you can: * Add or remove connections for mobile devices * Leave projects where you are not the sole owner * Set up local editors for your projects * Cancel the user account ## Configuring personal alerts [Section titled “Configuring personal alerts”](#configuring-personal-alerts) Alerts sent via email, SMS and our mobile apps are considered “personal” integrations. You and only you control which personal integrations are enabled and which events they receive. As you log in to the mobile apps on new devices, they are added to the personal integrations list for all the projects you can access. You have a separate set of alert preferences for each project you work with. One way to edit them is by going to each project’s settings page and clicking on the “Alerts” tab. There’s a section for “Personal Alerts.” ![Personal alerts](/_astro/personal_alerts.Cel1VW9R_157fAY.webp) While the account owner can see what notifications other users in the accounts have enabled, they cannot customize them. ### Mobile device connections [Section titled “Mobile device connections”](#mobile-device-connections) From the User Settings page, you can customize your connected mobile devices via the “Mobile Devices” tab on the sidebar. Here you will find links to download the Honeybadger app so you can connect your devices to receive important alerts on the go. ### SMS phone numbers [Section titled “SMS phone numbers”](#sms-phone-numbers) Honeybadger sends SMS alerts from a pool of phone numbers. To ensure that you receive alerts, download our vCard and add it to your contacts on your desktop or smartphone: [Download Honeybadger Outgoing Numbers vCard](/Honeybadger%20Outgoing%20Numbers.vcf) In iOS you can optionally [configure a custom text tone and enable the *Emergency Bypass* option](https://support.apple.com/guide/iphone/allow-or-silence-notifications-for-a-focus-iph21d43af5b/17.0/ios/17.0#iph68077cc0d) for the Honeybadger contact. Android has a [similar option](https://support.google.com/android/thread/219866813?hl=en\&msgid=220251463). This will ensure that you receive alerts even when your phone is in *Do Not Disturb* mode. Our current outgoing numbers (from the [vCard](/Honeybadger%20Outgoing%20Numbers.vcf)) are: * (206) 535-1618 * (206) 203-4914 * (206) 203-6150 * (206) 203-8212 * (206) 203-1222 * (206) 203-5571 Please note that these numbers are subject to change. We recommend checking this page periodically for updates. *Last updated: 2024-03-20* ### Configuring alerts across multiple projects [Section titled “Configuring alerts across multiple projects”](#configuring-alerts-across-multiple-projects) If you work with lots of projects, it can be a hassle to visit each settings page. That’s why we’ve added a single page UI where you can enable/disable all personal notifications in one place. This is available on the [Notifications tab](https://app.honeybadger.io/users/edit#notifications) of the [User Settings](https://app.honeybadger.io/users/edit) page. To access the detailed project notification options, click the project links displayed on this page to customize what kind of alerts you can receive. ## Connected apps [Section titled “Connected apps”](#connected-apps) The Connected Apps tab allows you to configure personal connections to Slack and project management tools such as GitHub. These connections enable Honeybadger to create and manage issues as your user account on the platforms you connect. ### GitHub sign in [Section titled “GitHub sign in”](#github-sign-in) ![Connect GitHub](/_astro/connect_github.7-4zseel_Z2n692.webp) To be able to sign in with GitHub, you’ll need to connect your Honeybadger and GitHub accounts. To do this: 1. Log in to Honeybadger 2. Go to the [User Settings](https://app.honeybadger.io/users/edit) page 3. Click on “Connect your GitHub Account” 4. Tell GitHub to allow Honeybadger to use your account for sign in > Note that this only sets up GitHub login. It doesn’t connect your projects to GitHub. You’ll have to do that in project settings. ## Cancel user [Section titled “Cancel user”](#cancel-user) You are immediately removed from all accounts, teams, and projects when you cancel your user account. Your user info will be deleted, and all accounts for which you are the only owner will also be immediately deleted. This action cannot be undone. # Event types > Index of every Insights event type captured by Honeybadger clients. Every Insights event type emitted by Honeybadger’s client libraries and the platform itself, grouped by what kind of activity the event represents. Select an event type to see its full field schema, emitter, and example queries. Filter event types… Showing **116** of **116** event types across **8** clients ## Cache 19Active Support · Cache · Action Controller | Event type | Client | Description | | ------------------------------------------------------------------------------------------------------------- | ------- | --------------------------------------- | | [cache\_cleanup.active\_support](/insights/event-types/ruby/cache_cleanup.active_support/) | ruby | A Rails cache cleanup. | | [cache\_decrement.active\_support](/insights/event-types/ruby/cache_decrement.active_support/) | ruby | A Rails cache decrement. | | [cache\_delete\_multi.active\_support](/insights/event-types/ruby/cache_delete_multi.active_support/) | ruby | A Rails multi-key cache delete. | | [cache\_delete.active\_support](/insights/event-types/ruby/cache_delete.active_support/) | ruby | A Rails cache delete. | | [cache\_exist?.active\_support](/insights/event-types/ruby/cache_exist_predicate.active_support/) | ruby | A Rails cache existence check. | | [cache\_fetch\_hit.active\_support](/insights/event-types/ruby/cache_fetch_hit.active_support/) | ruby | A Rails cache fetch hit. | | [cache\_generate.active\_support](/insights/event-types/ruby/cache_generate.active_support/) | ruby | A Rails cache generate call. | | [cache\_increment.active\_support](/insights/event-types/ruby/cache_increment.active_support/) | ruby | A Rails cache increment. | | [cache\_prune.active\_support](/insights/event-types/ruby/cache_prune.active_support/) | ruby | A Rails cache prune call. | | [cache\_read\_multi.active\_support](/insights/event-types/ruby/cache_read_multi.active_support/) | ruby | A Rails multi-key cache read. | | [cache\_read.active\_support](/insights/event-types/ruby/cache_read.active_support/) | ruby | A Rails cache read. | | [cache\_write\_multi.active\_support](/insights/event-types/ruby/cache_write_multi.active_support/) | ruby | A Rails multi-key cache write. | | [cache\_write.active\_support](/insights/event-types/ruby/cache_write.active_support/) | ruby | A Rails cache write. | | [cache.hit](/insights/event-types/laravel/cache.hit/) | laravel | A cache key was found (hit). | | [cache.miss](/insights/event-types/laravel/cache.miss/) | laravel | A cache key was not found (miss). | | [exist\_fragment?.action\_controller](/insights/event-types/ruby/exist_fragment_predicate.action_controller/) | ruby | A Rails fragment cache existence check. | | [expire\_fragment.action\_controller](/insights/event-types/ruby/expire_fragment.action_controller/) | ruby | A Rails fragment cache expire call. | | [read\_fragment.action\_controller](/insights/event-types/ruby/read_fragment.action_controller/) | ruby | A Rails fragment cache read. | | [write\_fragment.action\_controller](/insights/event-types/ruby/write_fragment.action_controller/) | ruby | A Rails fragment cache write. | ## Check-ins 1 | Event type | Client | Description | | -------------------------------------------------------- | ----------- | ----------------------------------------------------------- | | [check\_in](/insights/event-types/honeybadger/check_in/) | honeybadger | A heartbeat or report from a scheduled job or cron monitor. | ## Database 11Ash · Database · Ecto · Redis · Active Record | Event type | Client | Description | | ------------------------------------------------------------------------------------- | ------- | --------------------------------------------------- | | [ash.action.stop](/insights/event-types/elixir/ash.action.stop/) | elixir | An Ash action span finished. | | [ash.custom.stop](/insights/event-types/elixir/ash.custom.stop/) | elixir | An Ash custom span finished. | | [ash.query.stop](/insights/event-types/elixir/ash.query.stop/) | elixir | An Ash query span finished. | | [db.executed](/insights/event-types/laravel/db.executed/) | laravel | A Laravel database query. | | [db.query](/insights/event-types/python/db.query/) | python | A database query from the Django ORM or SQLAlchemy. | | [db.transaction.committed](/insights/event-types/laravel/db.transaction.committed/) | laravel | A database transaction was committed. | | [db.transaction.rolledback](/insights/event-types/laravel/db.transaction.rolledback/) | laravel | A database transaction was rolled back. | | [db.transaction.started](/insights/event-types/laravel/db.transaction.started/) | laravel | A database transaction was started. | | [ecto.query](/insights/event-types/elixir/ecto.query/) | elixir | An Ecto repository ran a database query. | | [redis.executed](/insights/event-types/laravel/redis.executed/) | laravel | A Redis command was executed. | | [sql.active\_record](/insights/event-types/ruby/sql.active_record/) | ruby | A SQL query from Rails Active Record. | ## Deploys 1 | Event type | Client | Description | | --------------------------------------------------- | ----------- | -------------------------------------- | | [deploy](/insights/event-types/honeybadger/deploy/) | honeybadger | A code deploy reported to Honeybadger. | ## Errors 1 | Event type | Client | Description | | --------------------------------------------------- | ----------- | ---------------------------------------------------- | | [notice](/insights/event-types/honeybadger/notice/) | honeybadger | An unhandled error captured by a Honeybadger client. | ## Feature flags 1Flipper | Event type | Client | Description | | ----------------------------------------------------------------------------------- | ------ | ----------------------------------------------------------------- | | [feature\_operation.flipper](/insights/event-types/ruby/feature_operation.flipper/) | ruby | A Flipper feature flag check or mutation recorded by Honeybadger. | ## GraphQL 3Absinthe | Event type | Client | Description | | ---------------------------------------------------------------------------------------------------------- | ------ | -------------------------------------------------- | | [absinthe.execute.operation.exception](/insights/event-types/elixir/absinthe.execute.operation.exception/) | elixir | An Absinthe GraphQL operation raised an exception. | | [absinthe.execute.operation.stop](/insights/event-types/elixir/absinthe.execute.operation.stop/) | elixir | An Absinthe GraphQL operation finished. | | [absinthe.resolve.field.stop](/insights/event-types/elixir/absinthe.resolve.field.stop/) | elixir | An Absinthe field resolver finished. | ## HTTP 5Finch · Net::HTTP · HTTP client · Tesla | Event type | Client | Description | | -------------------------------------------------------------------------------- | ------- | ---------------------------------------------------- | | [finch.request.stop](/insights/event-types/elixir/finch.request.stop/) | elixir | A Finch HTTP request finished. | | [request.net\_http](/insights/event-types/ruby/request.net_http/) | ruby | An outbound HTTP request made with Ruby's Net::HTTP. | | [response.received](/insights/event-types/laravel/response.received/) | laravel | Laravel's HTTP client received a response. | | [tesla.request.exception](/insights/event-types/elixir/tesla.request.exception/) | elixir | A Tesla HTTP request raised an exception. | | [tesla.request.stop](/insights/event-types/elixir/tesla.request.stop/) | elixir | A Tesla HTTP request finished. | ## Jobs 24Celery · Karafka · Active Job · Sidekiq · Queue · Oban | Event type | Client | Description | | ----------------------------------------------------------------------------------- | ------- | ------------------------------------------------------------------------------------------------------ | | [celery.task\_finished](/insights/event-types/python/celery.task_finished/) | python | A Celery task finished, whether it succeeded or failed. | | [consumer.consumed.karafka](/insights/event-types/ruby/consumer.consumed.karafka/) | ruby | A Karafka consumer processed a batch of Kafka messages. | | [discard.active\_job](/insights/event-types/ruby/discard.active_job/) | ruby | An Active Job job was discarded. | | [enqueue\_all.active\_job](/insights/event-types/ruby/enqueue_all.active_job/) | ruby | A batch of Active Job jobs was enqueued. | | [enqueue\_at.active\_job](/insights/event-types/ruby/enqueue_at.active_job/) | ruby | An Active Job job was scheduled to run later. | | [enqueue\_retry.active\_job](/insights/event-types/ruby/enqueue_retry.active_job/) | ruby | An Active Job job was queued for retry. | | [enqueue.active\_job](/insights/event-types/ruby/enqueue.active_job/) | ruby | An Active Job job was enqueued. | | [enqueue.sidekiq](/insights/event-types/ruby/enqueue.sidekiq/) | ruby | A job was enqueued to a Sidekiq queue. | | [error.occurred.karafka](/insights/event-types/ruby/error.occurred.karafka/) | ruby | A Karafka consumer or the Karafka framework raised an error. | | [job.processed](/insights/event-types/laravel/job.processed/) | laravel | A Laravel queue job finished processing. | | [job.queued](/insights/event-types/laravel/job.queued/) | laravel | A Laravel job was pushed onto a queue. | | [oban.job\_finished](/insights/event-types/python/oban.job_finished/) | python | An Oban job finished, whether it succeeded or failed. | | [oban.job.exception](/insights/event-types/elixir/oban.job.exception/) | elixir | An Oban job raised an exception or exited. | | [oban.job.stop](/insights/event-types/elixir/oban.job.stop/) | elixir | An Oban job finished without an error. | | [oban.leader\_exception](/insights/event-types/python/oban.leader_exception/) | python | Oban's leader election loop raised an exception. | | [oban.lifeline\_exception](/insights/event-types/python/oban.lifeline_exception/) | python | Oban's lifeline loop, which rescues orphaned executing jobs, raised an exception. | | [oban.producer\_exception](/insights/event-types/python/oban.producer_exception/) | python | An Oban queue producer raised an exception while fetching or acking jobs. | | [oban.pruner\_exception](/insights/event-types/python/oban.pruner_exception/) | python | Oban's pruner loop, which deletes old completed jobs, raised an exception. | | [oban.refresher\_exception](/insights/event-types/python/oban.refresher_exception/) | python | Oban's refresher loop, which refreshes producer records and cleans up stale ones, raised an exception. | | [oban.scheduler\_exception](/insights/event-types/python/oban.scheduler_exception/) | python | Oban's cron scheduler loop raised an exception while evaluating schedules. | | [oban.stager\_exception](/insights/event-types/python/oban.stager_exception/) | python | Oban's stager loop, which moves scheduled jobs to available, raised an exception. | | [perform.active\_job](/insights/event-types/ruby/perform.active_job/) | ruby | An Active Job job ran, whether it succeeded or raised an exception. | | [perform.sidekiq](/insights/event-types/ruby/perform.sidekiq/) | ruby | A Sidekiq job ran. | | [retry\_stopped.active\_job](/insights/event-types/ruby/retry_stopped.active_job/) | ruby | An Active Job job stopped retrying after too many failed attempts. | ## LLM 6Active Agent | Event type | Client | Description | | ------------------------------------------------------------------------------------ | ------ | ------------------------------------------------ | | [embed.active\_agent](/insights/event-types/ruby/embed.active_agent/) | ruby | An embedding request made through ActiveAgent. | | [process.active\_agent](/insights/event-types/ruby/process.active_agent/) | ruby | An ActiveAgent action ran. | | [prompt.active\_agent](/insights/event-types/ruby/prompt.active_agent/) | ruby | A model prompt request made through ActiveAgent. | | [stream\_close.active\_agent](/insights/event-types/ruby/stream_close.active_agent/) | ruby | An ActiveAgent streaming response closed. | | [stream\_open.active\_agent](/insights/event-types/ruby/stream_open.active_agent/) | ruby | An ActiveAgent streaming response opened. | | [tool\_call.active\_agent](/insights/event-types/ruby/tool_call.active_agent/) | ruby | An ActiveAgent tool call ran. | ## Log 1 | Event type | Client | Description | | ------------------------------------ | ------ | ----------------------------------------------------------------------------- | | [log](/insights/event-types/js/log/) | js | A console log message forwarded to Insights when insights.console is enabled. | ## Mail 3Mail · Action Mailer | Event type | Client | Description | | --------------------------------------------------------------------------- | ------- | ----------------------------------------- | | [mail.sending](/insights/event-types/laravel/mail.sending/) | laravel | A mail message is about to be sent. | | [mail.sent](/insights/event-types/laravel/mail.sent/) | laravel | A mail message was sent. | | [process.action\_mailer](/insights/event-types/ruby/process.action_mailer/) | ruby | Rails generated an Action Mailer message. | ## Metrics 8Heroku Postgres · Autotuner · Karafka · Puma · Sidekiq · Solid Queue | Event type | Client | Description | | ------------------------------------------------------------------------------------- | ------ | ------------------------------------------------------------------------------------------------ | | [metric.hb](/insights/event-types/ruby/metric.hb/) | ruby | A metric recorded through Honeybadger's instrumentation API and flushed by the metrics registry. | | [postgres](/insights/event-types/heroku/postgres/) | heroku | A Heroku Postgres log line from a Heroku log drain. | | [report.autotuner](/insights/event-types/ruby/report.autotuner/) | ruby | A tuning recommendation from the Autotuner gem. | | [statistics\_emitted.karafka](/insights/event-types/ruby/statistics_emitted.karafka/) | ruby | Kafka broker and consumer statistics from librdkafka. | | [stats.autotuner](/insights/event-types/ruby/stats.autotuner/) | ruby | Periodic Ruby process memory and object metrics from Autotuner. | | [stats.puma](/insights/event-types/ruby/stats.puma/) | ruby | A periodic Puma stats snapshot. | | [stats.sidekiq](/insights/event-types/ruby/stats.sidekiq/) | ruby | Sidekiq cluster statistics from the Honeybadger agent. | | [stats.solid\_queue](/insights/event-types/ruby/stats.solid_queue/) | ruby | Solid Queue cluster statistics from the Honeybadger agent. | ## Notifications 3Notifications | Event type | Client | Description | | --------------------------------------------------------------------------- | ------- | ----------------------------------- | | [notification.failed](/insights/event-types/laravel/notification.failed/) | laravel | A notification failed to send. | | [notification.sending](/insights/event-types/laravel/notification.sending/) | laravel | A notification is about to be sent. | | [notification.sent](/insights/event-types/laravel/notification.sent/) | laravel | A notification was sent. | ## Request 18ASGI · Django · Flask · Action Controller · Phoenix · Phoenix LiveView · Routing · Heroku Router | Event type | Client | Description | | -------------------------------------------------------------------------------------------------------------------- | ------- | ----------------------------------------------------------------- | | [asgi.request](/insights/event-types/python/asgi.request/) | python | An ASGI app finished handling an HTTP request. | | [django.request](/insights/event-types/python/django.request/) | python | A Django view finished handling an HTTP request. | | [flask.request](/insights/event-types/python/flask.request/) | python | A Flask route finished handling an HTTP request. | | [halted\_callback.action\_controller](/insights/event-types/ruby/halted_callback.action_controller/) | ruby | A before/around filter halted the Rails request processing chain. | | [phoenix.endpoint.stop](/insights/event-types/elixir/phoenix.endpoint.stop/) | elixir | A Phoenix or Plug request finished. | | [phoenix.live\_component.handle\_event.stop](/insights/event-types/elixir/phoenix.live_component.handle_event.stop/) | elixir | A Phoenix LiveComponent handled a client event. | | [phoenix.live\_component.update.stop](/insights/event-types/elixir/phoenix.live_component.update.stop/) | elixir | A Phoenix LiveComponent updated. | | [phoenix.live\_view.handle\_event.stop](/insights/event-types/elixir/phoenix.live_view.handle_event.stop/) | elixir | A Phoenix LiveView handled a client event such as phx-click. | | [phoenix.live\_view.handle\_params.stop](/insights/event-types/elixir/phoenix.live_view.handle_params.stop/) | elixir | A Phoenix LiveView handled URL params from a navigate or patch. | | [phoenix.live\_view.mount.stop](/insights/event-types/elixir/phoenix.live_view.mount.stop/) | elixir | A Phoenix LiveView mounted for a client connection. | | [process\_action.action\_controller](/insights/event-types/ruby/process_action.action_controller/) | ruby | A Rails controller action finished handling an HTTP request. | | [redirect\_to.action\_controller](/insights/event-types/ruby/redirect_to.action_controller/) | ruby | A Rails controller issued a redirect. | | [request.handled](/insights/event-types/js/request.handled/) | js | An inbound HTTP request finished. | | [request.handled](/insights/event-types/laravel/request.handled/) | laravel | A Laravel controller handled an HTTP request. | | [route.matched](/insights/event-types/laravel/route.matched/) | laravel | Laravel matched a route before running the controller. | | [router](/insights/event-types/heroku/router/) | heroku | A Heroku router log line from a Heroku log drain. | | [send\_file.action\_controller](/insights/event-types/ruby/send_file.action_controller/) | ruby | A Rails controller started sending a file. | | [unpermitted\_parameters.action\_controller](/insights/event-types/ruby/unpermitted_parameters.action_controller/) | ruby | Rails strong parameters filtered out unpermitted keys. | ## Storage 2Active Storage | Event type | Client | Description | | ------------------------------------------------------------------------------------------------ | ------ | -------------------------------- | | [service\_download.active\_storage](/insights/event-types/ruby/service_download.active_storage/) | ruby | A Rails Active Storage download. | | [service\_upload.active\_storage](/insights/event-types/ruby/service_upload.active_storage/) | ruby | A Rails Active Storage upload. | ## System 4 | Event type | Client | Description | | -------------------------------------------------------------------------- | ------ | ------------------------------------------------------------------------------- | | [report.system](/insights/event-types/ruby/report.system/) | ruby | A periodic memory and load average snapshot from the Honeybadger system plugin. | | [report.system.cpu](/insights/event-types/system/report.system.cpu/) | system | CPU and load average metrics from the Honeybadger CLI agent. | | [report.system.disk](/insights/event-types/system/report.system.disk/) | system | Disk partition usage metrics from the Honeybadger CLI agent. | | [report.system.memory](/insights/event-types/system/report.system.memory/) | system | Virtual memory metrics from the Honeybadger CLI agent. | ## Uptime 1 | Event type | Client | Description | | ----------------------------------------------- | ----------- | ------------------------------------------------------- | | [site](/insights/event-types/honeybadger/site/) | honeybadger | A snapshot of an uptime-monitored site's configuration. | ## View 4Action View · Blade | Event type | Client | Description | | -------------------------------------------------------------------------------------------- | ------- | -------------------------- | | [render\_collection.action\_view](/insights/event-types/ruby/render_collection.action_view/) | ruby | A Rails view render. | | [render\_partial.action\_view](/insights/event-types/ruby/render_partial.action_view/) | ruby | A Rails view render. | | [render\_template.action\_view](/insights/event-types/ruby/render_template.action_view/) | ruby | A Rails view render. | | [view.rendered](/insights/event-types/laravel/view.rendered/) | laravel | A Blade view was rendered. | # Elixir event reference > Insights event types emitted by Elixir. Every event the Honeybadger Elixir package sends to Insights when instrumentation is enabled: Phoenix requests and LiveView lifecycles, Ecto queries, Oban jobs, Absinthe GraphQL operations, Ash actions, and Finch and Tesla HTTP client requests. Each entry lists the event's fields with their types, and links to its raw JSON Schema. **18** events emitted by [`honeybadger-elixir`](/lib/elixir/). *** ## Absinthe ### absinthe.execute.operation.exception[](/insights/event-types/elixir/absinthe.execute.operation.exception/ "View event details")[](/insights/event-types/elixir/absinthe.execute.operation.exception.schema.json "View JSON Schema") An Absinthe GraphQL operation raised an exception. Uses the same fields as absinthe.execute.operation.stop. | Field | Type | Description | | ---------------- | -------------- | --------------------------------------------------------- | | `event_type` | string | Allowed value: `absinthe.execute.operation.exception`. | | `operation_name` | string | Named operation from the GraphQL query, if present. | | `operation_type` | string | Operation type: "query", "mutation", or "subscription". | | `selections` | array\ | Top-level field names selected in the operation. | | `schema` | string | Absinthe schema module name. | | `errors` | array\ | GraphQL errors returned in the result, if any. | | `duration` | number | Duration in microseconds before the exception was raised. | | `request_id` | string | Request ID from the current EventContext. | Example ```json { "event_type": "absinthe.execute.operation.exception", "operation_name": "CreateUser", "operation_type": "mutation", "selections": [ "createUser" ], "schema": "Elixir.MyAppWeb.Schema", "errors": [ { "message": "An unexpected error occurred", "path": [ "createUser" ] } ], "duration": 12000, "request_id": "F8ZBOg1zcBQDqDgAAADx" } ``` ### absinthe.execute.operation.stop[](/insights/event-types/elixir/absinthe.execute.operation.stop/ "View event details")[](/insights/event-types/elixir/absinthe.execute.operation.stop.schema.json "View JSON Schema") An Absinthe GraphQL operation finished. | Field | Type | Description | | ---------------- | -------------- | ------------------------------------------------------- | | `event_type` | string | Allowed value: `absinthe.execute.operation.stop`. | | `operation_name` | string | Named operation from the GraphQL query, if present. | | `operation_type` | string | Operation type: "query", "mutation", or "subscription". | | `selections` | array\ | Top-level field names selected in the operation. | | `schema` | string | Absinthe schema module name. | | `errors` | array\ | GraphQL errors returned in the result, if any. | | `duration` | number | Operation execution duration in microseconds. | | `request_id` | string | Request ID from the current EventContext. | Example ```json { "event_type": "absinthe.execute.operation.stop", "operation_name": "GetUser", "operation_type": "query", "selections": [ "user" ], "schema": "Elixir.MyAppWeb.Schema", "duration": 25000, "request_id": "F8ZBOg1zcBQDqDgAAADx" } ``` ### absinthe.resolve.field.stop[](/insights/event-types/elixir/absinthe.resolve.field.stop/ "View event details")[](/insights/event-types/elixir/absinthe.resolve.field.stop.schema.json "View JSON Schema") An Absinthe field resolver finished. Enable this in insights\_config telemetry\_events. This can create a lot of events. | Field | Type | Description | | ------------- | ------ | ------------------------------------------------ | | `event_type` | string | Allowed value: `absinthe.resolve.field.stop`. | | `field_name` | string | The field being resolved. | | `parent_type` | string | The parent type containing the field. | | `state` | string | Resolution state, e.g. "resolved", "unresolved". | | `duration` | number | Field resolution duration in microseconds. | | `request_id` | string | Request ID from the current EventContext. | Example ```json { "event_type": "absinthe.resolve.field.stop", "field_name": "user", "parent_type": "RootQueryType", "state": "resolved", "duration": 1800, "request_id": "F8ZBOg1zcBQDqDgAAADx" } ``` ## Ash ### ash.action.stop[](/insights/event-types/elixir/ash.action.stop/ "View event details")[](/insights/event-types/elixir/ash.action.stop.schema.json "View JSON Schema") An Ash action span finished. Honeybadger records this when :action is included in trace\_types. The default trace\_types are \[:custom, :action]. | Field | Type | Description | | ---------------- | ------ | -------------------------------------------------------------- | | `event_type` | string | Allowed value: `ash.action.stop`. | | `span_id` | string | Unique ID for this span, for correlating nested spans. | | `name` | string | Span name, typically the action or operation name. | | `parent_span_id` | string | ID of the parent span, enabling operation tree reconstruction. | | `duration` | number | Span duration in microseconds. | | `metadata` | object | Additional metadata set via set\_metadata/2. | | `metadata.*` | any | Additional caller-defined keys. | | `error` | object | Present when the span records an error with set\_error/2. | | `error.class` | string | Exception module name. | | `error.message` | string | Exception message. | | `request_id` | string | Request ID from the current EventContext. | Example ```json { "event_type": "ash.action.stop", "span_id": "a7c3e9f1b5d2480c9e6a1f3b7d5c2e80", "name": "accounts:user.create", "parent_span_id": "4f8b2d6c0a1e3957b8d4f6a2c0e91b37", "duration": 18500, "metadata": { "resource_short_name": "user", "action": "create" }, "request_id": "F8ZBOg1zcBQDqDgAAADx" } ``` ### ash.custom.stop[](/insights/event-types/elixir/ash.custom.stop/ "View event details")[](/insights/event-types/elixir/ash.custom.stop.schema.json "View JSON Schema") An Ash custom span finished. Honeybadger records this when :custom is included in trace\_types. The default trace\_types are \[:custom, :action]. | Field | Type | Description | | ---------------- | ------ | -------------------------------------------------------------- | | `event_type` | string | Allowed value: `ash.custom.stop`. | | `span_id` | string | Unique ID for this span, for correlating nested spans. | | `name` | string | Span name, typically the action or operation name. | | `parent_span_id` | string | ID of the parent span, enabling operation tree reconstruction. | | `duration` | number | Span duration in microseconds. | | `metadata` | object | Additional metadata set via set\_metadata/2. | | `metadata.*` | any | Additional caller-defined keys. | | `error` | object | Present when the span records an error with set\_error/2. | | `error.class` | string | Exception module name. | | `error.message` | string | Exception message. | | `request_id` | string | Request ID from the current EventContext. | Example ```json { "event_type": "ash.custom.stop", "span_id": "e1f3a5c7d9b2486e0a2c4f6b8d105397", "name": "sync_external_accounts", "parent_span_id": "a7c3e9f1b5d2480c9e6a1f3b7d5c2e80", "duration": 32000, "metadata": { "source": "crm", "batch_size": 100 }, "request_id": "F8ZBOg1zcBQDqDgAAADx" } ``` ### ash.query.stop[](/insights/event-types/elixir/ash.query.stop/ "View event details")[](/insights/event-types/elixir/ash.query.stop.schema.json "View JSON Schema") An Ash query span finished. Honeybadger records this when :query is included in trace\_types. | Field | Type | Description | | ---------------- | ------ | -------------------------------------------------------------- | | `event_type` | string | Allowed value: `ash.query.stop`. | | `span_id` | string | Unique ID for this span, for correlating nested spans. | | `name` | string | Span name, typically the action or operation name. | | `parent_span_id` | string | ID of the parent span, enabling operation tree reconstruction. | | `duration` | number | Span duration in microseconds. | | `metadata` | object | Additional metadata set via set\_metadata/2. | | `metadata.*` | any | Additional caller-defined keys. | | `error` | object | Present when the span records an error with set\_error/2. | | `error.class` | string | Exception module name. | | `error.message` | string | Exception message. | | `request_id` | string | Request ID from the current EventContext. | Example ```json { "event_type": "ash.query.stop", "span_id": "c2e4a6f8b0d1395c7e9a1b3d5f70c284", "name": "accounts:user.read", "parent_span_id": "a7c3e9f1b5d2480c9e6a1f3b7d5c2e80", "duration": 4200, "metadata": { "resource_short_name": "user", "action": "read" }, "request_id": "F8ZBOg1zcBQDqDgAAADx" } ``` ## Ecto ### ecto.query[](/insights/event-types/elixir/ecto.query/ "View event details")[](/insights/event-types/elixir/ecto.query.schema.json "View JSON Schema") An Ecto repository ran a database query. The event\_type comes from the repo telemetry\_prefix, so \[:my\_app, :repo, :query] becomes "my\_app.repo.query". Honeybadger skips transaction bookkeeping, schema migrations, and Oban job table queries by default. | Field | Type | Description | | ------------- | ---------------------- | ----------------------------------------------------------------------------------------------------------------- | | `event_type` | string | | | `query` | string | Obfuscated SQL with bind parameters replaced by ?. | | `source` | string | Table/source name the query targets. | | `query_time` | number | Time spent executing the query in microseconds. | | `decode_time` | number | Time spent decoding the result in microseconds. | | `queue_time` | number | Time spent waiting for a database connection in microseconds. | | `total_time` | number | Total time including queue, query, and decode in microseconds. | | `stacktrace` | array\> | Formatted call stack at query time. Present when include\_stacktrace is true and the repo has stacktrace enabled. | | `params` | array\ | Query parameters. Present when include\_params is true. | | `request_id` | string | Request ID from the current EventContext. | | `idle_time` | number | Time the connection spent idle before the query in microseconds. | Example ```json { "event_type": "my_app.repo.query", "query": "SELECT u0.\"id\", u0.\"email\", u0.\"name\" FROM \"users\" AS u0 WHERE (u0.\"id\" = $?)", "source": "users", "query_time": 3200, "decode_time": 180, "queue_time": 45, "total_time": 3425, "stacktrace": [ [ "lib/my_app/accounts.ex:27", "MyApp.Accounts.get_user!/1" ], [ "lib/my_app_web/controllers/user_controller.ex:14", "MyAppWeb.UserController.show/2" ] ], "params": [ 42 ], "request_id": "F8ZBOg1zcBQDqDgAAADx", "idle_time": 120000 } ``` ## Finch ### finch.request.stop[](/insights/event-types/elixir/finch.request.stop/ "View event details")[](/insights/event-types/elixir/finch.request.stop.schema.json "View JSON Schema") A Finch HTTP request finished. By default, Honeybadger stores only the hostname. Enable full\_url in insights\_config to include the path. | Field | Type | Description | | ------------ | ------- | --------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `finch.request.stop`. | | `name` | string | Finch pool name. | | `method` | string | HTTP method, e.g. "GET", "POST". | | `host` | string | Destination hostname. | | `url` | string | Full URL without query params. Present when full\_url is true. | | `status` | integer | HTTP response status code. Present on successful (non-streaming) responses. | | `streaming` | boolean | True for streaming requests where no status code is available. | | `error` | string | Error message if the request failed. | | `duration` | number | Request round-trip duration in microseconds. | | `request_id` | string | Request ID from the current EventContext. | Example ```json { "event_type": "finch.request.stop", "name": "Elixir.MyApp.Finch", "method": "GET", "host": "api.example.com", "url": "https://api.example.com/v1/users", "status": 200, "streaming": false, "duration": 85000, "request_id": "F8ZBOg1zcBQDqDgAAADx" } ``` ## Oban ### oban.job.exception[](/insights/event-types/elixir/oban.job.exception/ "View event details")[](/insights/event-types/elixir/oban.job.exception.schema.json "View JSON Schema") An Oban job raised an exception or exited. Uses the same fields as oban.job.stop. | Field | Type | Description | | ------------ | -------------- | ------------------------------------------------------------------------------------ | | `event_type` | string | Allowed value: `oban.job.exception`. | | `id` | integer | Oban job database ID. | | `worker` | string | Worker module name. | | `queue` | string | Queue the job ran on. | | `state` | string | Final job state, e.g. "failure", "discard". | | `attempt` | integer | Attempt number (1-based). | | `prefix` | string | Oban database prefix (schema). | | `tags` | array\ | Tags assigned to the job. | | `args` | object | Job arguments map. | | `args.*` | any | Additional caller-defined keys. | | `duration` | number | Job execution duration in microseconds. | | `request_id` | string | Request ID propagated from the originating request or generated for background jobs. | Example ```json { "event_type": "oban.job.exception", "id": 123457, "worker": "MyApp.Workers.WelcomeEmail", "queue": "default", "state": "failure", "attempt": 2, "prefix": "public", "tags": [ "mailer" ], "args": { "user_id": 42 }, "duration": 125000, "request_id": "f2a9c81d4e6b3a7f0c5d9e2b8a4f6c1d" } ``` ### oban.job.stop[](/insights/event-types/elixir/oban.job.stop/ "View event details")[](/insights/event-types/elixir/oban.job.stop.schema.json "View JSON Schema") An Oban job finished without an error. | Field | Type | Description | | ------------ | -------------- | ---------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `oban.job.stop`. | | `id` | integer | Oban job database ID. | | `worker` | string | Worker module name. | | `queue` | string | Queue the job ran on. | | `state` | string | Final job state, e.g. "success", "cancelled", "discard". | | `attempt` | integer | Attempt number (1-based). | | `prefix` | string | Oban database prefix (schema). | | `tags` | array\ | Tags assigned to the job. | | `args` | object | Job arguments map. | | `args.*` | any | Additional caller-defined keys. | | `duration` | number | Job execution duration in microseconds. | | `request_id` | string | Request ID propagated from the originating request via Oban job metadata, or a newly generated ID for background jobs. | Example ```json { "event_type": "oban.job.stop", "id": 123456, "worker": "MyApp.Workers.WelcomeEmail", "queue": "default", "state": "success", "attempt": 1, "prefix": "public", "tags": [ "mailer" ], "args": { "user_id": 42 }, "duration": 350000, "request_id": "f2a9c81d4e6b3a7f0c5d9e2b8a4f6c1d" } ``` ## Phoenix ### phoenix.endpoint.stop[](/insights/event-types/elixir/phoenix.endpoint.stop/ "View event details")[](/insights/event-types/elixir/phoenix.endpoint.stop.schema.json "View JSON Schema") A Phoenix or Plug request finished. Honeybadger records this from the Plug.Telemetry :stop event. | Field | Type | Description | | -------------- | ------- | ---------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `phoenix.endpoint.stop`. | | `method` | string | HTTP method, e.g. "GET", "POST". | | `request_path` | string | Request path, e.g. "/users/42". | | `status` | integer | HTTP response status code. | | `params` | object | Request params map. | | `params.*` | any | Additional caller-defined keys. | | `route_type` | string | How the request was routed. Allowed values: `controller`, `live`, `unknown`. | | `controller` | string | Phoenix controller module name. Present when route\_type is "controller". | | `action` | string | Controller action name. Present when route\_type is "controller". | | `live_view` | string | LiveView module name. Present when route\_type is "live". | | `live_action` | string | LiveView action atom. Present when route\_type is "live". | | `format` | string | Response format, e.g. "html", "json". | | `view` | string | Phoenix view module name. | | `template` | string | Template rendered. | | `duration` | number | Total request duration in microseconds. | | `request_id` | string | Request ID set from the x-request-id response header or assigns. Present on all events fired within a request context. | Example ```json { "event_type": "phoenix.endpoint.stop", "method": "GET", "request_path": "/users/42", "status": 200, "params": { "id": "42" }, "route_type": "controller", "controller": "MyAppWeb.UserController", "action": "show", "live_view": "MyAppWeb.UserLive.Show", "live_action": "show", "format": "html", "view": "MyAppWeb.UserHTML", "template": "show.html", "duration": 150000, "request_id": "F8ZBOg1zcBQDqDgAAADx" } ``` ## Phoenix LiveView ### phoenix.live\_component.handle\_event.stop[](/insights/event-types/elixir/phoenix.live_component.handle_event.stop/ "View event details")[](/insights/event-types/elixir/phoenix.live_component.handle_event.stop.schema.json "View JSON Schema") A Phoenix LiveComponent handled a client event. | Field | Type | Description | | ------------ | ------ | ------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `phoenix.live_component.handle_event.stop`. | | `url` | string | URL of the LiveView at the time of the event. | | `socket_id` | string | LiveView socket ID. | | `view` | string | LiveView module name. | | `component` | string | LiveComponent module name, if applicable. | | `assigns` | object | Socket assigns at the time of the event. | | `assigns.*` | any | Additional caller-defined keys. | | `params` | object | Params passed to the event handler. | | `params.*` | any | Additional caller-defined keys. | | `event` | string | Event name for handle\_event events. | | `duration` | number | Duration in microseconds. | | `request_id` | string | Request ID generated at LiveView mount and shared by events on the same socket. | Example ```json { "event_type": "phoenix.live_component.handle_event.stop", "url": "https://www.example.com/users/42/edit", "socket_id": "phx-F8ZBOg1zcBQDqDgAAACB", "view": "MyAppWeb.UserLive.Show", "component": "MyAppWeb.UserLive.FormComponent", "assigns": { "page_title": "Edit user", "current_user_id": 42 }, "params": { "user": { "name": "Jane Doe" } }, "event": "validate", "duration": 15000, "request_id": "b3d5a1f0c2e4968a7d1b3f5c9e0a2d4f" } ``` ### phoenix.live\_component.update.stop[](/insights/event-types/elixir/phoenix.live_component.update.stop/ "View event details")[](/insights/event-types/elixir/phoenix.live_component.update.stop.schema.json "View JSON Schema") A Phoenix LiveComponent updated. | Field | Type | Description | | ------------ | ------ | ------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `phoenix.live_component.update.stop`. | | `url` | string | URL of the LiveView at the time of the event. | | `socket_id` | string | LiveView socket ID. | | `view` | string | LiveView module name. | | `component` | string | LiveComponent module name, if applicable. | | `assigns` | object | Socket assigns at the time of the event. | | `assigns.*` | any | Additional caller-defined keys. | | `params` | object | Params passed to the event handler. | | `params.*` | any | Additional caller-defined keys. | | `event` | string | Event name for handle\_event events. | | `duration` | number | Duration in microseconds. | | `request_id` | string | Request ID generated at LiveView mount and shared by events on the same socket. | Example ```json { "event_type": "phoenix.live_component.update.stop", "url": "https://www.example.com/users/42/edit", "socket_id": "phx-F8ZBOg1zcBQDqDgAAACB", "view": "MyAppWeb.UserLive.Show", "component": "MyAppWeb.UserLive.FormComponent", "assigns": { "page_title": "Edit user", "current_user_id": 42 }, "params": { "id": "42" }, "duration": 8500, "request_id": "b3d5a1f0c2e4968a7d1b3f5c9e0a2d4f" } ``` ### phoenix.live\_view\.handle\_event.stop[](/insights/event-types/elixir/phoenix.live_view.handle_event.stop/ "View event details")[](/insights/event-types/elixir/phoenix.live_view.handle_event.stop.schema.json "View JSON Schema") A Phoenix LiveView handled a client event such as phx-click. | Field | Type | Description | | ------------ | ------ | ------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `phoenix.live_view.handle_event.stop`. | | `url` | string | URL of the LiveView at the time of the event. | | `socket_id` | string | LiveView socket ID. | | `view` | string | LiveView module name. | | `component` | string | LiveComponent module name, if applicable. | | `assigns` | object | Socket assigns at the time of the event. | | `assigns.*` | any | Additional caller-defined keys. | | `params` | object | Params passed to the event handler. | | `params.*` | any | Additional caller-defined keys. | | `event` | string | Event name for handle\_event events. | | `duration` | number | Duration in microseconds. | | `request_id` | string | Request ID generated at LiveView mount and shared by events on the same socket. | Example ```json { "event_type": "phoenix.live_view.handle_event.stop", "url": "https://www.example.com/users/42/edit", "socket_id": "phx-F8ZBOg1zcBQDqDgAAACB", "view": "MyAppWeb.UserLive.Show", "assigns": { "page_title": "Edit user", "current_user_id": 42 }, "params": { "user": { "name": "Jane Doe" } }, "event": "save", "duration": 28000, "request_id": "b3d5a1f0c2e4968a7d1b3f5c9e0a2d4f" } ``` ### phoenix.live\_view\.handle\_params.stop[](/insights/event-types/elixir/phoenix.live_view.handle_params.stop/ "View event details")[](/insights/event-types/elixir/phoenix.live_view.handle_params.stop.schema.json "View JSON Schema") A Phoenix LiveView handled URL params from a navigate or patch. | Field | Type | Description | | ------------ | ------ | ------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `phoenix.live_view.handle_params.stop`. | | `url` | string | URL of the LiveView at the time of the event. | | `socket_id` | string | LiveView socket ID. | | `view` | string | LiveView module name. | | `component` | string | LiveComponent module name, if applicable. | | `assigns` | object | Socket assigns at the time of the event. | | `assigns.*` | any | Additional caller-defined keys. | | `params` | object | Params passed to the event handler. | | `params.*` | any | Additional caller-defined keys. | | `event` | string | Event name for handle\_event events. | | `duration` | number | Duration in microseconds. | | `request_id` | string | Request ID generated at LiveView mount and shared by events on the same socket. | Example ```json { "event_type": "phoenix.live_view.handle_params.stop", "url": "https://www.example.com/users/42?tab=activity", "socket_id": "phx-F8ZBOg1zcBQDqDgAAACB", "view": "MyAppWeb.UserLive.Show", "assigns": { "page_title": "Show user", "current_user_id": 42 }, "params": { "id": "42", "tab": "activity" }, "duration": 12000, "request_id": "b3d5a1f0c2e4968a7d1b3f5c9e0a2d4f" } ``` ### phoenix.live\_view\.mount.stop[](/insights/event-types/elixir/phoenix.live_view.mount.stop/ "View event details")[](/insights/event-types/elixir/phoenix.live_view.mount.stop.schema.json "View JSON Schema") A Phoenix LiveView mounted for a client connection. | Field | Type | Description | | ------------ | ------ | ------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `phoenix.live_view.mount.stop`. | | `url` | string | URL of the LiveView at the time of the event. | | `socket_id` | string | LiveView socket ID. | | `view` | string | LiveView module name. | | `component` | string | LiveComponent module name, if applicable. | | `assigns` | object | Socket assigns at the time of the event. | | `assigns.*` | any | Additional caller-defined keys. | | `params` | object | Params passed to the event handler. | | `params.*` | any | Additional caller-defined keys. | | `event` | string | Event name for handle\_event events. | | `duration` | number | Duration in microseconds. | | `request_id` | string | Request ID generated at LiveView mount and shared by events on the same socket. | Example ```json { "event_type": "phoenix.live_view.mount.stop", "url": "https://www.example.com/users/42", "socket_id": "phx-F8ZBOg1zcBQDqDgAAACB", "view": "MyAppWeb.UserLive.Show", "assigns": { "page_title": "Show user", "current_user_id": 42 }, "params": { "id": "42" }, "duration": 45000, "request_id": "b3d5a1f0c2e4968a7d1b3f5c9e0a2d4f" } ``` ## Tesla ### tesla.request.exception[](/insights/event-types/elixir/tesla.request.exception/ "View event details")[](/insights/event-types/elixir/tesla.request.exception.schema.json "View JSON Schema") A Tesla HTTP request raised an exception. By default, Honeybadger stores only the hostname. Enable full\_url in insights\_config to include the path. If Tesla uses Finch, Honeybadger records the Finch event instead of a second Tesla event. | Field | Type | Description | | ------------- | ------- | ------------------------------------------------- | | `event_type` | string | Allowed value: `tesla.request.exception`. | | `method` | string | HTTP method in uppercase, e.g. "GET", "POST". | | `host` | string | Destination hostname. | | `status_code` | integer | HTTP response status code. | | `url` | string | Full request URL. Present when full\_url is true. | | `duration` | number | Request round-trip duration in microseconds. | | `request_id` | string | Request ID from the current EventContext. | Example ```json { "event_type": "tesla.request.exception", "method": "POST", "host": "api.example.com", "status_code": 500, "url": "https://api.example.com/v1/payments", "duration": 30000, "request_id": "F8ZBOg1zcBQDqDgAAADx" } ``` ### tesla.request.stop[](/insights/event-types/elixir/tesla.request.stop/ "View event details")[](/insights/event-types/elixir/tesla.request.stop.schema.json "View JSON Schema") A Tesla HTTP request finished. By default, Honeybadger stores only the hostname. Enable full\_url in insights\_config to include the path. If Tesla uses Finch, Honeybadger records the Finch event instead of a second Tesla event. | Field | Type | Description | | ------------- | ------- | ------------------------------------------------- | | `event_type` | string | Allowed value: `tesla.request.stop`. | | `method` | string | HTTP method in uppercase, e.g. "GET", "POST". | | `host` | string | Destination hostname. | | `status_code` | integer | HTTP response status code. | | `url` | string | Full request URL. Present when full\_url is true. | | `duration` | number | Request round-trip duration in microseconds. | | `request_id` | string | Request ID from the current EventContext. | Example ```json { "event_type": "tesla.request.stop", "method": "GET", "host": "api.example.com", "status_code": 200, "url": "https://api.example.com/v1/users", "duration": 92000, "request_id": "F8ZBOg1zcBQDqDgAAADx" } ``` # absinthe.execute.operation.exception > An Absinthe GraphQL operation raised an exception. Uses the same fields as absinthe.execute.operation.stop. An Absinthe GraphQL operation raised an exception. Uses the same fields as absinthe.execute.operation.stop. Source **Absinthe** Category **GraphQL** Fields **8** [honeybadger-elixir](/lib/elixir/) ## Fields 8 | Field | Type | Description | | ---------------- | -------------- | --------------------------------------------------------- | | `event_type` | string | Allowed value: `absinthe.execute.operation.exception`. | | `operation_name` | string | Named operation from the GraphQL query, if present. | | `operation_type` | string | Operation type: "query", "mutation", or "subscription". | | `selections` | array\ | Top-level field names selected in the operation. | | `schema` | string | Absinthe schema module name. | | `errors` | array\ | GraphQL errors returned in the result, if any. | | `duration` | number | Duration in microseconds before the exception was raised. | | `request_id` | string | Request ID from the current EventContext. | ## Example ```json { "event_type": "absinthe.execute.operation.exception", "operation_name": "CreateUser", "operation_type": "mutation", "selections": [ "createUser" ], "schema": "Elixir.MyAppWeb.Schema", "errors": [ { "message": "An unexpected error occurred", "path": [ "createUser" ] } ], "duration": 12000, "request_id": "F8ZBOg1zcBQDqDgAAADx" } ``` # absinthe.execute.operation.stop > An Absinthe GraphQL operation finished. An Absinthe GraphQL operation finished. Source **Absinthe** Category **GraphQL** Fields **8** [honeybadger-elixir](/lib/elixir/) ## Fields 8 | Field | Type | Description | | ---------------- | -------------- | ------------------------------------------------------- | | `event_type` | string | Allowed value: `absinthe.execute.operation.stop`. | | `operation_name` | string | Named operation from the GraphQL query, if present. | | `operation_type` | string | Operation type: "query", "mutation", or "subscription". | | `selections` | array\ | Top-level field names selected in the operation. | | `schema` | string | Absinthe schema module name. | | `errors` | array\ | GraphQL errors returned in the result, if any. | | `duration` | number | Operation execution duration in microseconds. | | `request_id` | string | Request ID from the current EventContext. | ## Example ```json { "event_type": "absinthe.execute.operation.stop", "operation_name": "GetUser", "operation_type": "query", "selections": [ "user" ], "schema": "Elixir.MyAppWeb.Schema", "duration": 25000, "request_id": "F8ZBOg1zcBQDqDgAAADx" } ``` # absinthe.resolve.field.stop > An Absinthe field resolver finished. Enable this in insights_config telemetry_events. This can create a lot of events. An Absinthe field resolver finished. Enable this in insights\_config telemetry\_events. This can create a lot of events. Source **Absinthe** Category **GraphQL** Fields **6** [honeybadger-elixir](/lib/elixir/) ## Fields 6 | Field | Type | Description | | ------------- | ------ | ------------------------------------------------ | | `event_type` | string | Allowed value: `absinthe.resolve.field.stop`. | | `field_name` | string | The field being resolved. | | `parent_type` | string | The parent type containing the field. | | `state` | string | Resolution state, e.g. "resolved", "unresolved". | | `duration` | number | Field resolution duration in microseconds. | | `request_id` | string | Request ID from the current EventContext. | ## Example ```json { "event_type": "absinthe.resolve.field.stop", "field_name": "user", "parent_type": "RootQueryType", "state": "resolved", "duration": 1800, "request_id": "F8ZBOg1zcBQDqDgAAADx" } ``` # ash.action.stop > An Ash action span finished. Honeybadger records this when :action is included in trace_types. The default trace_types are [:custom, :action]. An Ash action span finished. Honeybadger records this when :action is included in trace\_types. The default trace\_types are \[:custom, :action]. Source **Ash** Category **Database** Fields **11** [honeybadger-elixir](/lib/elixir/) ## Fields 11 | Field | Type | Description | | ---------------- | ------ | -------------------------------------------------------------- | | `event_type` | string | Allowed value: `ash.action.stop`. | | `span_id` | string | Unique ID for this span, for correlating nested spans. | | `name` | string | Span name, typically the action or operation name. | | `parent_span_id` | string | ID of the parent span, enabling operation tree reconstruction. | | `duration` | number | Span duration in microseconds. | | `metadata` | object | Additional metadata set via set\_metadata/2. | | `metadata.*` | any | Additional caller-defined keys. | | `error` | object | Present when the span records an error with set\_error/2. | | `error.class` | string | Exception module name. | | `error.message` | string | Exception message. | | `request_id` | string | Request ID from the current EventContext. | ## Example ```json { "event_type": "ash.action.stop", "span_id": "a7c3e9f1b5d2480c9e6a1f3b7d5c2e80", "name": "accounts:user.create", "parent_span_id": "4f8b2d6c0a1e3957b8d4f6a2c0e91b37", "duration": 18500, "metadata": { "resource_short_name": "user", "action": "create" }, "request_id": "F8ZBOg1zcBQDqDgAAADx" } ``` # ash.custom.stop > An Ash custom span finished. Honeybadger records this when :custom is included in trace_types. The default trace_types are [:custom, :action]. An Ash custom span finished. Honeybadger records this when :custom is included in trace\_types. The default trace\_types are \[:custom, :action]. Source **Ash** Category **Database** Fields **11** [honeybadger-elixir](/lib/elixir/) ## Fields 11 | Field | Type | Description | | ---------------- | ------ | -------------------------------------------------------------- | | `event_type` | string | Allowed value: `ash.custom.stop`. | | `span_id` | string | Unique ID for this span, for correlating nested spans. | | `name` | string | Span name, typically the action or operation name. | | `parent_span_id` | string | ID of the parent span, enabling operation tree reconstruction. | | `duration` | number | Span duration in microseconds. | | `metadata` | object | Additional metadata set via set\_metadata/2. | | `metadata.*` | any | Additional caller-defined keys. | | `error` | object | Present when the span records an error with set\_error/2. | | `error.class` | string | Exception module name. | | `error.message` | string | Exception message. | | `request_id` | string | Request ID from the current EventContext. | ## Example ```json { "event_type": "ash.custom.stop", "span_id": "e1f3a5c7d9b2486e0a2c4f6b8d105397", "name": "sync_external_accounts", "parent_span_id": "a7c3e9f1b5d2480c9e6a1f3b7d5c2e80", "duration": 32000, "metadata": { "source": "crm", "batch_size": 100 }, "request_id": "F8ZBOg1zcBQDqDgAAADx" } ``` # ash.query.stop > An Ash query span finished. Honeybadger records this when :query is included in trace_types. An Ash query span finished. Honeybadger records this when :query is included in trace\_types. Source **Ash** Category **Database** Fields **11** [honeybadger-elixir](/lib/elixir/) ## Fields 11 | Field | Type | Description | | ---------------- | ------ | -------------------------------------------------------------- | | `event_type` | string | Allowed value: `ash.query.stop`. | | `span_id` | string | Unique ID for this span, for correlating nested spans. | | `name` | string | Span name, typically the action or operation name. | | `parent_span_id` | string | ID of the parent span, enabling operation tree reconstruction. | | `duration` | number | Span duration in microseconds. | | `metadata` | object | Additional metadata set via set\_metadata/2. | | `metadata.*` | any | Additional caller-defined keys. | | `error` | object | Present when the span records an error with set\_error/2. | | `error.class` | string | Exception module name. | | `error.message` | string | Exception message. | | `request_id` | string | Request ID from the current EventContext. | ## Example ```json { "event_type": "ash.query.stop", "span_id": "c2e4a6f8b0d1395c7e9a1b3d5f70c284", "name": "accounts:user.read", "parent_span_id": "a7c3e9f1b5d2480c9e6a1f3b7d5c2e80", "duration": 4200, "metadata": { "resource_short_name": "user", "action": "read" }, "request_id": "F8ZBOg1zcBQDqDgAAADx" } ``` # ecto.query > An Ecto repository ran a database query. The event_type comes from the repo telemetry_prefix, so [:my_app, :repo, :query] becomes "my_app.repo.query". Honeybadger skips transaction bookkeeping, schema migrations, and Oban job table queries by default. An Ecto repository ran a database query. The event\_type comes from the repo telemetry\_prefix, so \[:my\_app, :repo, :query] becomes “my\_app.repo.query”. Honeybadger skips transaction bookkeeping, schema migrations, and Oban job table queries by default. Source **Ecto** Category **Database** Fields **11** [honeybadger-elixir](/lib/elixir/) ## Fields 11 | Field | Type | Description | | ------------- | ---------------------- | ----------------------------------------------------------------------------------------------------------------- | | `event_type` | string | | | `query` | string | Obfuscated SQL with bind parameters replaced by ?. | | `source` | string | Table/source name the query targets. | | `query_time` | number | Time spent executing the query in microseconds. | | `decode_time` | number | Time spent decoding the result in microseconds. | | `queue_time` | number | Time spent waiting for a database connection in microseconds. | | `total_time` | number | Total time including queue, query, and decode in microseconds. | | `stacktrace` | array\> | Formatted call stack at query time. Present when include\_stacktrace is true and the repo has stacktrace enabled. | | `params` | array\ | Query parameters. Present when include\_params is true. | | `request_id` | string | Request ID from the current EventContext. | | `idle_time` | number | Time the connection spent idle before the query in microseconds. | ## Example ```json { "event_type": "my_app.repo.query", "query": "SELECT u0.\"id\", u0.\"email\", u0.\"name\" FROM \"users\" AS u0 WHERE (u0.\"id\" = $?)", "source": "users", "query_time": 3200, "decode_time": 180, "queue_time": 45, "total_time": 3425, "stacktrace": [ [ "lib/my_app/accounts.ex:27", "MyApp.Accounts.get_user!/1" ], [ "lib/my_app_web/controllers/user_controller.ex:14", "MyAppWeb.UserController.show/2" ] ], "params": [ 42 ], "request_id": "F8ZBOg1zcBQDqDgAAADx", "idle_time": 120000 } ``` # finch.request.stop > A Finch HTTP request finished. By default, Honeybadger stores only the hostname. Enable full_url in insights_config to include the path. A Finch HTTP request finished. By default, Honeybadger stores only the hostname. Enable full\_url in insights\_config to include the path. Source **Finch** Category **HTTP** Fields **10** [honeybadger-elixir](/lib/elixir/) ## Fields 10 | Field | Type | Description | | ------------ | ------- | --------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `finch.request.stop`. | | `name` | string | Finch pool name. | | `method` | string | HTTP method, e.g. "GET", "POST". | | `host` | string | Destination hostname. | | `url` | string | Full URL without query params. Present when full\_url is true. | | `status` | integer | HTTP response status code. Present on successful (non-streaming) responses. | | `streaming` | boolean | True for streaming requests where no status code is available. | | `error` | string | Error message if the request failed. | | `duration` | number | Request round-trip duration in microseconds. | | `request_id` | string | Request ID from the current EventContext. | ## Example ```json { "event_type": "finch.request.stop", "name": "Elixir.MyApp.Finch", "method": "GET", "host": "api.example.com", "url": "https://api.example.com/v1/users", "status": 200, "streaming": false, "duration": 85000, "request_id": "F8ZBOg1zcBQDqDgAAADx" } ``` # oban.job.exception > An Oban job raised an exception or exited. Uses the same fields as oban.job.stop. An Oban job raised an exception or exited. Uses the same fields as oban.job.stop. Source **Oban** Category **Jobs** Fields **12** [honeybadger-elixir](/lib/elixir/) ## Fields 12 | Field | Type | Description | | ------------ | -------------- | ------------------------------------------------------------------------------------ | | `event_type` | string | Allowed value: `oban.job.exception`. | | `id` | integer | Oban job database ID. | | `worker` | string | Worker module name. | | `queue` | string | Queue the job ran on. | | `state` | string | Final job state, e.g. "failure", "discard". | | `attempt` | integer | Attempt number (1-based). | | `prefix` | string | Oban database prefix (schema). | | `tags` | array\ | Tags assigned to the job. | | `args` | object | Job arguments map. | | `args.*` | any | Additional caller-defined keys. | | `duration` | number | Job execution duration in microseconds. | | `request_id` | string | Request ID propagated from the originating request or generated for background jobs. | ## Example ```json { "event_type": "oban.job.exception", "id": 123457, "worker": "MyApp.Workers.WelcomeEmail", "queue": "default", "state": "failure", "attempt": 2, "prefix": "public", "tags": [ "mailer" ], "args": { "user_id": 42 }, "duration": 125000, "request_id": "f2a9c81d4e6b3a7f0c5d9e2b8a4f6c1d" } ``` # oban.job.stop > An Oban job finished without an error. An Oban job finished without an error. Source **Oban** Category **Jobs** Fields **12** [honeybadger-elixir](/lib/elixir/) ## Fields 12 | Field | Type | Description | | ------------ | -------------- | ---------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `oban.job.stop`. | | `id` | integer | Oban job database ID. | | `worker` | string | Worker module name. | | `queue` | string | Queue the job ran on. | | `state` | string | Final job state, e.g. "success", "cancelled", "discard". | | `attempt` | integer | Attempt number (1-based). | | `prefix` | string | Oban database prefix (schema). | | `tags` | array\ | Tags assigned to the job. | | `args` | object | Job arguments map. | | `args.*` | any | Additional caller-defined keys. | | `duration` | number | Job execution duration in microseconds. | | `request_id` | string | Request ID propagated from the originating request via Oban job metadata, or a newly generated ID for background jobs. | ## Example ```json { "event_type": "oban.job.stop", "id": 123456, "worker": "MyApp.Workers.WelcomeEmail", "queue": "default", "state": "success", "attempt": 1, "prefix": "public", "tags": [ "mailer" ], "args": { "user_id": 42 }, "duration": 350000, "request_id": "f2a9c81d4e6b3a7f0c5d9e2b8a4f6c1d" } ``` # phoenix.endpoint.stop > A Phoenix or Plug request finished. Honeybadger records this from the Plug.Telemetry :stop event. A Phoenix or Plug request finished. Honeybadger records this from the Plug.Telemetry :stop event. Source **Phoenix** Category **Request** Fields **16** [honeybadger-elixir](/lib/elixir/) ## Fields 16 | Field | Type | Description | | -------------- | ------- | ---------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `phoenix.endpoint.stop`. | | `method` | string | HTTP method, e.g. "GET", "POST". | | `request_path` | string | Request path, e.g. "/users/42". | | `status` | integer | HTTP response status code. | | `params` | object | Request params map. | | `params.*` | any | Additional caller-defined keys. | | `route_type` | string | How the request was routed. Allowed values: `controller`, `live`, `unknown`. | | `controller` | string | Phoenix controller module name. Present when route\_type is "controller". | | `action` | string | Controller action name. Present when route\_type is "controller". | | `live_view` | string | LiveView module name. Present when route\_type is "live". | | `live_action` | string | LiveView action atom. Present when route\_type is "live". | | `format` | string | Response format, e.g. "html", "json". | | `view` | string | Phoenix view module name. | | `template` | string | Template rendered. | | `duration` | number | Total request duration in microseconds. | | `request_id` | string | Request ID set from the x-request-id response header or assigns. Present on all events fired within a request context. | ## Example ```json { "event_type": "phoenix.endpoint.stop", "method": "GET", "request_path": "/users/42", "status": 200, "params": { "id": "42" }, "route_type": "controller", "controller": "MyAppWeb.UserController", "action": "show", "live_view": "MyAppWeb.UserLive.Show", "live_action": "show", "format": "html", "view": "MyAppWeb.UserHTML", "template": "show.html", "duration": 150000, "request_id": "F8ZBOg1zcBQDqDgAAADx" } ``` # phoenix.live_component.handle_event.stop > A Phoenix LiveComponent handled a client event. A Phoenix LiveComponent handled a client event. Source **Phoenix LiveView** Category **Request** Fields **12** [honeybadger-elixir](/lib/elixir/) ## Fields 12 | Field | Type | Description | | ------------ | ------ | ------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `phoenix.live_component.handle_event.stop`. | | `url` | string | URL of the LiveView at the time of the event. | | `socket_id` | string | LiveView socket ID. | | `view` | string | LiveView module name. | | `component` | string | LiveComponent module name, if applicable. | | `assigns` | object | Socket assigns at the time of the event. | | `assigns.*` | any | Additional caller-defined keys. | | `params` | object | Params passed to the event handler. | | `params.*` | any | Additional caller-defined keys. | | `event` | string | Event name for handle\_event events. | | `duration` | number | Duration in microseconds. | | `request_id` | string | Request ID generated at LiveView mount and shared by events on the same socket. | ## Example ```json { "event_type": "phoenix.live_component.handle_event.stop", "url": "https://www.example.com/users/42/edit", "socket_id": "phx-F8ZBOg1zcBQDqDgAAACB", "view": "MyAppWeb.UserLive.Show", "component": "MyAppWeb.UserLive.FormComponent", "assigns": { "page_title": "Edit user", "current_user_id": 42 }, "params": { "user": { "name": "Jane Doe" } }, "event": "validate", "duration": 15000, "request_id": "b3d5a1f0c2e4968a7d1b3f5c9e0a2d4f" } ``` # phoenix.live_component.update.stop > A Phoenix LiveComponent updated. A Phoenix LiveComponent updated. Source **Phoenix LiveView** Category **Request** Fields **12** [honeybadger-elixir](/lib/elixir/) ## Fields 12 | Field | Type | Description | | ------------ | ------ | ------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `phoenix.live_component.update.stop`. | | `url` | string | URL of the LiveView at the time of the event. | | `socket_id` | string | LiveView socket ID. | | `view` | string | LiveView module name. | | `component` | string | LiveComponent module name, if applicable. | | `assigns` | object | Socket assigns at the time of the event. | | `assigns.*` | any | Additional caller-defined keys. | | `params` | object | Params passed to the event handler. | | `params.*` | any | Additional caller-defined keys. | | `event` | string | Event name for handle\_event events. | | `duration` | number | Duration in microseconds. | | `request_id` | string | Request ID generated at LiveView mount and shared by events on the same socket. | ## Example ```json { "event_type": "phoenix.live_component.update.stop", "url": "https://www.example.com/users/42/edit", "socket_id": "phx-F8ZBOg1zcBQDqDgAAACB", "view": "MyAppWeb.UserLive.Show", "component": "MyAppWeb.UserLive.FormComponent", "assigns": { "page_title": "Edit user", "current_user_id": 42 }, "params": { "id": "42" }, "duration": 8500, "request_id": "b3d5a1f0c2e4968a7d1b3f5c9e0a2d4f" } ``` # phoenix.live_view.handle_event.stop > A Phoenix LiveView handled a client event such as phx-click. A Phoenix LiveView handled a client event such as phx-click. Source **Phoenix LiveView** Category **Request** Fields **12** [honeybadger-elixir](/lib/elixir/) ## Fields 12 | Field | Type | Description | | ------------ | ------ | ------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `phoenix.live_view.handle_event.stop`. | | `url` | string | URL of the LiveView at the time of the event. | | `socket_id` | string | LiveView socket ID. | | `view` | string | LiveView module name. | | `component` | string | LiveComponent module name, if applicable. | | `assigns` | object | Socket assigns at the time of the event. | | `assigns.*` | any | Additional caller-defined keys. | | `params` | object | Params passed to the event handler. | | `params.*` | any | Additional caller-defined keys. | | `event` | string | Event name for handle\_event events. | | `duration` | number | Duration in microseconds. | | `request_id` | string | Request ID generated at LiveView mount and shared by events on the same socket. | ## Example ```json { "event_type": "phoenix.live_view.handle_event.stop", "url": "https://www.example.com/users/42/edit", "socket_id": "phx-F8ZBOg1zcBQDqDgAAACB", "view": "MyAppWeb.UserLive.Show", "assigns": { "page_title": "Edit user", "current_user_id": 42 }, "params": { "user": { "name": "Jane Doe" } }, "event": "save", "duration": 28000, "request_id": "b3d5a1f0c2e4968a7d1b3f5c9e0a2d4f" } ``` # phoenix.live_view.handle_params.stop > A Phoenix LiveView handled URL params from a navigate or patch. A Phoenix LiveView handled URL params from a navigate or patch. Source **Phoenix LiveView** Category **Request** Fields **12** [honeybadger-elixir](/lib/elixir/) ## Fields 12 | Field | Type | Description | | ------------ | ------ | ------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `phoenix.live_view.handle_params.stop`. | | `url` | string | URL of the LiveView at the time of the event. | | `socket_id` | string | LiveView socket ID. | | `view` | string | LiveView module name. | | `component` | string | LiveComponent module name, if applicable. | | `assigns` | object | Socket assigns at the time of the event. | | `assigns.*` | any | Additional caller-defined keys. | | `params` | object | Params passed to the event handler. | | `params.*` | any | Additional caller-defined keys. | | `event` | string | Event name for handle\_event events. | | `duration` | number | Duration in microseconds. | | `request_id` | string | Request ID generated at LiveView mount and shared by events on the same socket. | ## Example ```json { "event_type": "phoenix.live_view.handle_params.stop", "url": "https://www.example.com/users/42?tab=activity", "socket_id": "phx-F8ZBOg1zcBQDqDgAAACB", "view": "MyAppWeb.UserLive.Show", "assigns": { "page_title": "Show user", "current_user_id": 42 }, "params": { "id": "42", "tab": "activity" }, "duration": 12000, "request_id": "b3d5a1f0c2e4968a7d1b3f5c9e0a2d4f" } ``` # phoenix.live_view.mount.stop > A Phoenix LiveView mounted for a client connection. A Phoenix LiveView mounted for a client connection. Source **Phoenix LiveView** Category **Request** Fields **12** [honeybadger-elixir](/lib/elixir/) ## Fields 12 | Field | Type | Description | | ------------ | ------ | ------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `phoenix.live_view.mount.stop`. | | `url` | string | URL of the LiveView at the time of the event. | | `socket_id` | string | LiveView socket ID. | | `view` | string | LiveView module name. | | `component` | string | LiveComponent module name, if applicable. | | `assigns` | object | Socket assigns at the time of the event. | | `assigns.*` | any | Additional caller-defined keys. | | `params` | object | Params passed to the event handler. | | `params.*` | any | Additional caller-defined keys. | | `event` | string | Event name for handle\_event events. | | `duration` | number | Duration in microseconds. | | `request_id` | string | Request ID generated at LiveView mount and shared by events on the same socket. | ## Example ```json { "event_type": "phoenix.live_view.mount.stop", "url": "https://www.example.com/users/42", "socket_id": "phx-F8ZBOg1zcBQDqDgAAACB", "view": "MyAppWeb.UserLive.Show", "assigns": { "page_title": "Show user", "current_user_id": 42 }, "params": { "id": "42" }, "duration": 45000, "request_id": "b3d5a1f0c2e4968a7d1b3f5c9e0a2d4f" } ``` # tesla.request.exception > A Tesla HTTP request raised an exception. By default, Honeybadger stores only the hostname. Enable full_url in insights_config to include the path. If Tesla uses Finch, Honeybadger records the Finch event instead of a second Tesla event. A Tesla HTTP request raised an exception. By default, Honeybadger stores only the hostname. Enable full\_url in insights\_config to include the path. If Tesla uses Finch, Honeybadger records the Finch event instead of a second Tesla event. Source **Tesla** Category **HTTP** Fields **7** [honeybadger-elixir](/lib/elixir/) ## Fields 7 | Field | Type | Description | | ------------- | ------- | ------------------------------------------------- | | `event_type` | string | Allowed value: `tesla.request.exception`. | | `method` | string | HTTP method in uppercase, e.g. "GET", "POST". | | `host` | string | Destination hostname. | | `status_code` | integer | HTTP response status code. | | `url` | string | Full request URL. Present when full\_url is true. | | `duration` | number | Request round-trip duration in microseconds. | | `request_id` | string | Request ID from the current EventContext. | ## Example ```json { "event_type": "tesla.request.exception", "method": "POST", "host": "api.example.com", "status_code": 500, "url": "https://api.example.com/v1/payments", "duration": 30000, "request_id": "F8ZBOg1zcBQDqDgAAADx" } ``` # tesla.request.stop > A Tesla HTTP request finished. By default, Honeybadger stores only the hostname. Enable full_url in insights_config to include the path. If Tesla uses Finch, Honeybadger records the Finch event instead of a second Tesla event. A Tesla HTTP request finished. By default, Honeybadger stores only the hostname. Enable full\_url in insights\_config to include the path. If Tesla uses Finch, Honeybadger records the Finch event instead of a second Tesla event. Source **Tesla** Category **HTTP** Fields **7** [honeybadger-elixir](/lib/elixir/) ## Fields 7 | Field | Type | Description | | ------------- | ------- | ------------------------------------------------- | | `event_type` | string | Allowed value: `tesla.request.stop`. | | `method` | string | HTTP method in uppercase, e.g. "GET", "POST". | | `host` | string | Destination hostname. | | `status_code` | integer | HTTP response status code. | | `url` | string | Full request URL. Present when full\_url is true. | | `duration` | number | Request round-trip duration in microseconds. | | `request_id` | string | Request ID from the current EventContext. | ## Example ```json { "event_type": "tesla.request.stop", "method": "GET", "host": "api.example.com", "status_code": 200, "url": "https://api.example.com/v1/users", "duration": 92000, "request_id": "F8ZBOg1zcBQDqDgAAADx" } ``` # Heroku event reference > Insights event types emitted by Heroku. Events parsed from your Heroku log drain: router request lines and Heroku Postgres metrics. Each entry lists the event's fields with their types, and links to its raw JSON Schema. **2** events emitted by [`heroku`](/guides/insights/integrations/heroku/). *** ### postgres[](/insights/event-types/heroku/postgres/ "View event details")[](/insights/event-types/heroku/postgres.schema.json "View JSON Schema") A Heroku Postgres log line from a Heroku log drain. Honeybadger recognizes it by proc\_id == 'heroku-postgres'. | Field | Type | Description | | ---------------------- | ------- | ----------------------------------------------------------------------------------------------------- | | `event_type` | string | | | `proc_id` | string | Heroku process identifier. Always 'heroku-postgres' for this event. Allowed value: `heroku-postgres`. | | `source` | string | Postgres source identifier, e.g. "HEROKU\_POSTGRESQL\_CRIMSON". | | `addon` | string | Add-on name. | | `active_connections` | integer | Number of active database connections. | | `waiting_connections` | integer | Number of connections waiting on a lock. | | `index_cache_hit_rate` | number | Index cache hit rate (0.0–1.0). | | `table_cache_hit_rate` | number | Table cache hit rate (0.0–1.0). | | `load_avg_1m` | number | 1-minute load average. | | `load_avg_5m` | number | 5-minute load average. | | `load_avg_15m` | number | 15-minute load average. | | `read_iops` | number | Read I/O operations per second. | | `write_iops` | number | Write I/O operations per second. | | `tmp_disk_used` | integer | Bytes used on temporary disk. | | `tmp_disk_available` | integer | Bytes available on temporary disk. | | `memory_total` | integer | Total memory in bytes. | | `memory_free` | integer | Free memory in bytes. | | `memory_cached` | integer | Cached memory in bytes. | | `memory_postgres` | integer | Memory used by Postgres in bytes. | Example ```json { "event_type": "logplex", "proc_id": "heroku-postgres", "source": "HEROKU_POSTGRESQL_CRIMSON", "addon": "postgresql-curved-12345", "active_connections": 12, "waiting_connections": 0, "index_cache_hit_rate": 0.99957, "table_cache_hit_rate": 0.98309, "load_avg_1m": 0.31, "load_avg_5m": 0.28, "load_avg_15m": 0.25, "read_iops": 12.5, "write_iops": 35.625, "tmp_disk_used": 33849344, "tmp_disk_available": 72944943104, "memory_total": 8589934592, "memory_free": 1342177280, "memory_cached": 5368709120, "memory_postgres": 1610612736 } ``` ### router[](/insights/event-types/heroku/router/ "View event details")[](/insights/event-types/heroku/router.schema.json "View JSON Schema") A Heroku router log line from a Heroku log drain. Honeybadger recognizes it by proc\_id == 'router'. | Field | Type | Description | | ------------ | ------- | ----------------------------------------------------------------------------------- | | `event_type` | string | | | `proc_id` | string | Heroku process identifier. Always 'router' for this event. Allowed value: `router`. | | `method` | string | HTTP method, e.g. "GET", "POST". | | `path` | string | Request path. | | `host` | string | Request host header. | | `fwd` | string | Forwarded client IP address. | | `dyno` | string | Dyno that handled the request, e.g. "web.1". | | `connect` | number | Time in milliseconds to establish the connection. | | `service` | number | Time in milliseconds the dyno spent processing the request. | | `status` | integer | HTTP response status code. | | `bytes` | integer | Number of bytes returned in the response. | | `protocol` | string | Protocol used, e.g. "https". | Example ```json { "event_type": "logplex", "proc_id": "router", "method": "GET", "path": "/users/123", "host": "www.example.com", "fwd": "203.0.113.42", "dyno": "web.1", "connect": 1, "service": 45, "status": 200, "bytes": 15342, "protocol": "https" } ``` # postgres > A Heroku Postgres log line from a Heroku log drain. Honeybadger recognizes it by proc_id == 'heroku-postgres'. A Heroku Postgres log line from a Heroku log drain. Honeybadger recognizes it by proc\_id == ‘heroku-postgres’. Source **Heroku Postgres** Category **Metrics** Fields **19** [heroku](/guides/insights/integrations/heroku/) ## Fields 19 | Field | Type | Description | | ---------------------- | ------- | ----------------------------------------------------------------------------------------------------- | | `event_type` | string | | | `proc_id` | string | Heroku process identifier. Always 'heroku-postgres' for this event. Allowed value: `heroku-postgres`. | | `source` | string | Postgres source identifier, e.g. "HEROKU\_POSTGRESQL\_CRIMSON". | | `addon` | string | Add-on name. | | `active_connections` | integer | Number of active database connections. | | `waiting_connections` | integer | Number of connections waiting on a lock. | | `index_cache_hit_rate` | number | Index cache hit rate (0.0–1.0). | | `table_cache_hit_rate` | number | Table cache hit rate (0.0–1.0). | | `load_avg_1m` | number | 1-minute load average. | | `load_avg_5m` | number | 5-minute load average. | | `load_avg_15m` | number | 15-minute load average. | | `read_iops` | number | Read I/O operations per second. | | `write_iops` | number | Write I/O operations per second. | | `tmp_disk_used` | integer | Bytes used on temporary disk. | | `tmp_disk_available` | integer | Bytes available on temporary disk. | | `memory_total` | integer | Total memory in bytes. | | `memory_free` | integer | Free memory in bytes. | | `memory_cached` | integer | Cached memory in bytes. | | `memory_postgres` | integer | Memory used by Postgres in bytes. | ## Example ```json { "event_type": "logplex", "proc_id": "heroku-postgres", "source": "HEROKU_POSTGRESQL_CRIMSON", "addon": "postgresql-curved-12345", "active_connections": 12, "waiting_connections": 0, "index_cache_hit_rate": 0.99957, "table_cache_hit_rate": 0.98309, "load_avg_1m": 0.31, "load_avg_5m": 0.28, "load_avg_15m": 0.25, "read_iops": 12.5, "write_iops": 35.625, "tmp_disk_used": 33849344, "tmp_disk_available": 72944943104, "memory_total": 8589934592, "memory_free": 1342177280, "memory_cached": 5368709120, "memory_postgres": 1610612736 } ``` # router > A Heroku router log line from a Heroku log drain. Honeybadger recognizes it by proc_id == 'router'. A Heroku router log line from a Heroku log drain. Honeybadger recognizes it by proc\_id == ‘router’. Source **Heroku Router** Category **Request** Fields **12** [heroku](/guides/insights/integrations/heroku/) ## Fields 12 | Field | Type | Description | | ------------ | ------- | ----------------------------------------------------------------------------------- | | `event_type` | string | | | `proc_id` | string | Heroku process identifier. Always 'router' for this event. Allowed value: `router`. | | `method` | string | HTTP method, e.g. "GET", "POST". | | `path` | string | Request path. | | `host` | string | Request host header. | | `fwd` | string | Forwarded client IP address. | | `dyno` | string | Dyno that handled the request, e.g. "web.1". | | `connect` | number | Time in milliseconds to establish the connection. | | `service` | number | Time in milliseconds the dyno spent processing the request. | | `status` | integer | HTTP response status code. | | `bytes` | integer | Number of bytes returned in the response. | | `protocol` | string | Protocol used, e.g. "https". | ## Example ```json { "event_type": "logplex", "proc_id": "router", "method": "GET", "path": "/users/123", "host": "www.example.com", "fwd": "203.0.113.42", "dyno": "web.1", "connect": 1, "service": 45, "status": 200, "bytes": 15342, "protocol": "https" } ``` # Honeybadger event reference > Insights event types emitted by Honeybadger. Events Honeybadger itself adds to your project's Insights data: error notices, check-in reports, deploys, and uptime site state changes. Each entry lists the event's fields with their types, and links to its raw JSON Schema. **4** events emitted by `honeybadger`. *** ### check\_in[](/insights/event-types/honeybadger/check_in/ "View event details")[](/insights/event-types/honeybadger/check_in.schema.json "View JSON Schema") A heartbeat or report from a scheduled job or cron monitor. The state field shows whether the monitor is reporting on schedule, missing a heartbeat, or paused. | Field | Type | Description | | ------------------- | ------- | ----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `check_in`. | | `check_in_id` | string | Stable identifier for the monitored check-in / job. | | `state` | string | Reported state of the run. reporting means the job sent a heartbeat for the scheduled window. missing means the window expired without a heartbeat. paused means the monitor is paused. Allowed values: `reporting`, `missing`, `paused`. | | `payload` | object | Optional report sent with advanced check-ins. The fields listed below are common, but the job can send other fields too. | | `payload.status` | string | Job outcome label. "success" appears as a check icon in the UI. Any other value is treated as a failure label. | | `payload.duration` | number | How long the job took, in milliseconds. | | `payload.exit_code` | integer | Process exit code reported by the job. 0 conventionally means success. | | `payload.stdout` | string | Captured stdout from the job run. | | `payload.stderr` | string | Captured stderr from the job run. | | `payload.*` | any | Additional caller-defined keys. | Example ```json { "event_type": "check_in", "check_in_id": "wNgxJv", "state": "reporting", "payload": { "status": "success", "duration": 4523, "exit_code": 0, "stdout": "Processed 1240 records", "stderr": "" } } ``` ### deploy[](/insights/event-types/honeybadger/deploy/ "View event details")[](/insights/event-types/honeybadger/deploy.schema.json "View JSON Schema") A code deploy reported to Honeybadger. Each deploy creates one event per environment. There is no separate started or finished event. | Field | Type | Description | | ---------------- | -------------- | ---------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `deploy`. | | `environment` | string | Target environment of the deploy, e.g. "production", "staging". | | `revision` | string | Source revision (commit SHA) being deployed. | | `repository` | string | Repository URL, when reported. | | `local_username` | string | Username on the deploying machine. | | `commits` | array\ | Commits included in this deploy when reported. Omitted on deploys without a commit list. | Example ```json { "event_type": "deploy", "environment": "production", "revision": "a3f8c12d9b4e6f7a8c01d2e3f4a5b6c7d8e9f0a1", "repository": "https://github.com/example/myapp", "local_username": "deploy", "commits": [ { "revision": "a3f8c12d9b4e6f7a8c01d2e3f4a5b6c7d8e9f0a1", "message": "Fix checkout total calculation", "author": "Jane Developer" } ] } ``` ### notice[](/insights/event-types/honeybadger/notice/ "View event details")[](/insights/event-types/honeybadger/notice.schema.json "View JSON Schema") An unhandled error captured by a Honeybadger client. Notices with the same root cause are grouped under one fault\_id. | Field | Type | Description | | ---------------------------- | -------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `notice`. | | `uuid` | string | Stable per-notice token (use to look up a specific notice in the UI). | | `ulid` | string | ULID for the notice. It is sortable and encodes the receive timestamp. | | `fault_id` | integer | Aggregated error group ID. Each fault\_id groups notices that share a root cause. | | `project_id` | integer | Project the notice belongs to. | | `klass` | string | Error class name, e.g. "NoMethodError", "ActiveRecord::RecordNotFound". | | `message` | string | Error message text from the exception. | | `file` | string | Top-frame source file from the backtrace. | | `hostname` | string | Hostname of the server that reported the error. | | `environment` | string | Deploy environment, e.g. "production", "staging". | | `revision` | string | Source revision (commit SHA) the app was running at. | | `user` | string | Resolved from the project's user-search field (typically email or user\_id). | | `request_id` | string | Per-request correlation id. | | `tags` | array\ | Tags applied to the notice. | | `request` | object | HTTP request metadata from the error context. | | `request.url` | string | | | `request.referer` | string | | | `request.host` | string | | | `request.request_method` | string | | | `request.remote_addr` | string | | | `user_agent` | object | Parsed user-agent from the request. | | `user_agent.browser` | object | | | `user_agent.browser.name` | string | | | `user_agent.browser.major` | string | | | `user_agent.browser.version` | string | | | `user_agent.os` | object | | | `user_agent.os.name` | string | | | `user_agent.os.version` | string | | | `user_agent.device` | object | | | `user_agent.device.model` | string | | | `user_agent.bot` | boolean | | | `context` | object | Context data your application set when the error was reported, such as values from Honeybadger.context. Keys are whatever your code sends. Common examples include context.user\_email, context.user\_id, and context.username. | | `context.*` | any | Additional caller-defined keys. | | `session` | object | The HTTP session at the time of the error. Keys are whatever your application stores in the session. | | `session.*` | any | Additional caller-defined keys. | | `params` | object | The HTTP request parameters at the time of the error. Keys depend on the request. | | `params.*` | any | Additional caller-defined keys. | Example ```json { "event_type": "notice", "uuid": "3e6c9a1d-7f2b-4e8a-b5c3-9d0e1f2a3b4c", "ulid": "01JXF7Q2M3N4P5R6S7T8V9W0XA", "fault_id": 84512937, "project_id": 12345, "klass": "ActiveRecord::RecordNotFound", "message": "Couldn't find User with 'id'=123", "file": "app/controllers/users_controller.rb", "hostname": "web-1.example.com", "environment": "production", "revision": "a3f8c12d9b4e6f7a8c01d2e3f4a5b6c7d8e9f0a1", "user": "user@example.com", "request_id": "1f9f6f1a-2b3c-4d5e-8f6a-7b8c9d0e1f2a", "tags": [ "billing", "critical" ], "request": { "url": "https://www.example.com/users/123", "referer": "https://www.example.com/users", "host": "www.example.com", "request_method": "GET", "remote_addr": "203.0.113.42" }, "user_agent": { "browser": { "name": "Chrome", "major": "126", "version": "126.0.0.0" }, "os": { "name": "Mac OS X", "version": "10.15.7" }, "device": { "model": "Mac" }, "bot": false }, "context": { "user_id": 123, "user_email": "user@example.com", "plan": "pro" }, "session": { "session_id": "9d0e1f2a3b4c5d6e", "cart_items": 2 }, "params": { "controller": "users", "action": "show", "id": "123" } } ``` ### site[](/insights/event-types/honeybadger/site/ "View event details")[](/insights/event-types/honeybadger/site.schema.json "View JSON Schema") A snapshot of an uptime-monitored site's configuration. Honeybadger records this when a site is created or its config changes. Probe results use event\_type "uptime\_check" and include duration, location, site.id, site.name, and response.status\_code. | Field | Type | Description | | ------------ | ------- | --------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `site`. | | `id` | integer | Site DB id (matches the site.id nested key on probe events). | | `name` | string | Display name of the site (matches site.name::str on probe events). | | `url` | string | Target URL being monitored. | | `state` | string | Last observed reachability state of the site. Allowed values: `up`, `down`. | Example ```json { "event_type": "site", "id": 67890, "name": "Marketing site", "url": "https://www.example.com", "state": "up" } ``` # check_in > A heartbeat or report from a scheduled job or cron monitor. The state field shows whether the monitor is reporting on schedule, missing a heartbeat, or paused. A heartbeat or report from a scheduled job or cron monitor. The state field shows whether the monitor is reporting on schedule, missing a heartbeat, or paused. Category **Check-ins** Fields **10** honeybadger ## Fields 10 | Field | Type | Description | | ------------------- | ------- | ----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `check_in`. | | `check_in_id` | string | Stable identifier for the monitored check-in / job. | | `state` | string | Reported state of the run. reporting means the job sent a heartbeat for the scheduled window. missing means the window expired without a heartbeat. paused means the monitor is paused. Allowed values: `reporting`, `missing`, `paused`. | | `payload` | object | Optional report sent with advanced check-ins. The fields listed below are common, but the job can send other fields too. | | `payload.status` | string | Job outcome label. "success" appears as a check icon in the UI. Any other value is treated as a failure label. | | `payload.duration` | number | How long the job took, in milliseconds. | | `payload.exit_code` | integer | Process exit code reported by the job. 0 conventionally means success. | | `payload.stdout` | string | Captured stdout from the job run. | | `payload.stderr` | string | Captured stderr from the job run. | | `payload.*` | any | Additional caller-defined keys. | ## Example ```json { "event_type": "check_in", "check_in_id": "wNgxJv", "state": "reporting", "payload": { "status": "success", "duration": 4523, "exit_code": 0, "stdout": "Processed 1240 records", "stderr": "" } } ``` # deploy > A code deploy reported to Honeybadger. Each deploy creates one event per environment. There is no separate started or finished event. A code deploy reported to Honeybadger. Each deploy creates one event per environment. There is no separate started or finished event. Category **Deploys** Fields **6** honeybadger ## Fields 6 | Field | Type | Description | | ---------------- | -------------- | ---------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `deploy`. | | `environment` | string | Target environment of the deploy, e.g. "production", "staging". | | `revision` | string | Source revision (commit SHA) being deployed. | | `repository` | string | Repository URL, when reported. | | `local_username` | string | Username on the deploying machine. | | `commits` | array\ | Commits included in this deploy when reported. Omitted on deploys without a commit list. | ## Example ```json { "event_type": "deploy", "environment": "production", "revision": "a3f8c12d9b4e6f7a8c01d2e3f4a5b6c7d8e9f0a1", "repository": "https://github.com/example/myapp", "local_username": "deploy", "commits": [ { "revision": "a3f8c12d9b4e6f7a8c01d2e3f4a5b6c7d8e9f0a1", "message": "Fix checkout total calculation", "author": "Jane Developer" } ] } ``` # notice > An unhandled error captured by a Honeybadger client. Notices with the same root cause are grouped under one fault_id. An unhandled error captured by a Honeybadger client. Notices with the same root cause are grouped under one fault\_id. Category **Errors** Fields **37** honeybadger ## Fields 37 | Field | Type | Description | | ---------------------------- | -------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `notice`. | | `uuid` | string | Stable per-notice token (use to look up a specific notice in the UI). | | `ulid` | string | ULID for the notice. It is sortable and encodes the receive timestamp. | | `fault_id` | integer | Aggregated error group ID. Each fault\_id groups notices that share a root cause. | | `project_id` | integer | Project the notice belongs to. | | `klass` | string | Error class name, e.g. "NoMethodError", "ActiveRecord::RecordNotFound". | | `message` | string | Error message text from the exception. | | `file` | string | Top-frame source file from the backtrace. | | `hostname` | string | Hostname of the server that reported the error. | | `environment` | string | Deploy environment, e.g. "production", "staging". | | `revision` | string | Source revision (commit SHA) the app was running at. | | `user` | string | Resolved from the project's user-search field (typically email or user\_id). | | `request_id` | string | Per-request correlation id. | | `tags` | array\ | Tags applied to the notice. | | `request` | object | HTTP request metadata from the error context. | | `request.url` | string | | | `request.referer` | string | | | `request.host` | string | | | `request.request_method` | string | | | `request.remote_addr` | string | | | `user_agent` | object | Parsed user-agent from the request. | | `user_agent.browser` | object | | | `user_agent.browser.name` | string | | | `user_agent.browser.major` | string | | | `user_agent.browser.version` | string | | | `user_agent.os` | object | | | `user_agent.os.name` | string | | | `user_agent.os.version` | string | | | `user_agent.device` | object | | | `user_agent.device.model` | string | | | `user_agent.bot` | boolean | | | `context` | object | Context data your application set when the error was reported, such as values from Honeybadger.context. Keys are whatever your code sends. Common examples include context.user\_email, context.user\_id, and context.username. | | `context.*` | any | Additional caller-defined keys. | | `session` | object | The HTTP session at the time of the error. Keys are whatever your application stores in the session. | | `session.*` | any | Additional caller-defined keys. | | `params` | object | The HTTP request parameters at the time of the error. Keys depend on the request. | | `params.*` | any | Additional caller-defined keys. | ## Example ```json { "event_type": "notice", "uuid": "3e6c9a1d-7f2b-4e8a-b5c3-9d0e1f2a3b4c", "ulid": "01JXF7Q2M3N4P5R6S7T8V9W0XA", "fault_id": 84512937, "project_id": 12345, "klass": "ActiveRecord::RecordNotFound", "message": "Couldn't find User with 'id'=123", "file": "app/controllers/users_controller.rb", "hostname": "web-1.example.com", "environment": "production", "revision": "a3f8c12d9b4e6f7a8c01d2e3f4a5b6c7d8e9f0a1", "user": "user@example.com", "request_id": "1f9f6f1a-2b3c-4d5e-8f6a-7b8c9d0e1f2a", "tags": [ "billing", "critical" ], "request": { "url": "https://www.example.com/users/123", "referer": "https://www.example.com/users", "host": "www.example.com", "request_method": "GET", "remote_addr": "203.0.113.42" }, "user_agent": { "browser": { "name": "Chrome", "major": "126", "version": "126.0.0.0" }, "os": { "name": "Mac OS X", "version": "10.15.7" }, "device": { "model": "Mac" }, "bot": false }, "context": { "user_id": 123, "user_email": "user@example.com", "plan": "pro" }, "session": { "session_id": "9d0e1f2a3b4c5d6e", "cart_items": 2 }, "params": { "controller": "users", "action": "show", "id": "123" } } ``` # site > A snapshot of an uptime-monitored site's configuration. Honeybadger records this when a site is created or its config changes. Probe results use event_type "uptime_check" and include duration, location, site.id, site.name, and response.status_code. A snapshot of an uptime-monitored site’s configuration. Honeybadger records this when a site is created or its config changes. Probe results use event\_type “uptime\_check” and include duration, location, site.id, site.name, and response.status\_code. Category **Uptime** Fields **5** honeybadger ## Fields 5 | Field | Type | Description | | ------------ | ------- | --------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `site`. | | `id` | integer | Site DB id (matches the site.id nested key on probe events). | | `name` | string | Display name of the site (matches site.name::str on probe events). | | `url` | string | Target URL being monitored. | | `state` | string | Last observed reachability state of the site. Allowed values: `up`, `down`. | ## Example ```json { "event_type": "site", "id": 67890, "name": "Marketing site", "url": "https://www.example.com", "state": "up" } ``` # JavaScript event reference > Insights event types emitted by JavaScript. Every event the Honeybadger JavaScript client sends to Insights when instrumentation is enabled: inbound HTTP requests from Express, Fastify, and AWS Lambda (@honeybadger-io/js) and Next.js (@honeybadger-io/nextjs), and console log messages. Each entry lists the event's fields with their types, and links to its raw JSON Schema. **2** events emitted by [`@honeybadger-io/js`](/lib/javascript/), [`@honeybadger-io/nextjs`](/lib/javascript/integration/nextjs/). *** ### log[](/insights/event-types/js/log/ "View event details")[](/insights/event-types/js/log.schema.json "View JSON Schema") A console log message forwarded to Insights when insights.console is enabled. | Field | Type | Description | | ------------ | ----------- | -------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `log`. | | `severity` | string | Console method that produced the message, e.g. "log", "info", "warn", "error", "debug". | | `message` | string | First argument when it is a string. Omitted when the first argument is not a string. | | `args` | array\ | Remaining console arguments when the first argument is a string, or all arguments otherwise. | Example ```json { "event_type": "log", "severity": "info", "message": "User signed in", "args": [ 123, { "ok": true } ] } ``` ### request.handled[](/insights/event-types/js/request.handled/ "View event details")[](/insights/event-types/js/request.handled.schema.json "View JSON Schema") An inbound HTTP request finished. Emitted by the Express, Fastify, and AWS Lambda integrations in @honeybadger-io/js, and by withHoneybadger in @honeybadger-io/nextjs, when insights.http is enabled. | Field | Type | Description | | ---------------- | -------------- | ---------------------------------------------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `request.handled`. | | `method` | string | HTTP method, e.g. "GET", "POST". | | `path` | string | Request path. | | `route` | string \| null | Matched route pattern when the framework provides one (for example Express `req.route.path` or Fastify `req.routeOptions.url`). Not set for AWS Lambda. | | `status` | integer | HTTP response status code. | | `duration` | integer | Request duration in milliseconds. | | `request_id` | string | Unique ID for this request. Read from the `x-request-id` or `request-id` header, or generated when neither is present. Merged from event context. | | `correlation_id` | string | ID that may span related requests. Read from the `x-correlation-id` or `x-amzn-trace-id` header, or falls back to `request_id`. Merged from event context. | Example ```json { "event_type": "request.handled", "method": "GET", "path": "/users/123", "route": "/users/:id", "status": 200, "duration": 42, "request_id": "f3b2c1d0-4e5a-4b6c-8d7e-9f0a1b2c3d4e", "correlation_id": "f3b2c1d0-4e5a-4b6c-8d7e-9f0a1b2c3d4e" } ``` # log > A console log message forwarded to Insights when insights.console is enabled. A console log message forwarded to Insights when insights.console is enabled. Category **Log** Fields **4** [@honeybadger-io/js](/lib/javascript/) ## Fields 4 | Field | Type | Description | | ------------ | ----------- | -------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `log`. | | `severity` | string | Console method that produced the message, e.g. "log", "info", "warn", "error", "debug". | | `message` | string | First argument when it is a string. Omitted when the first argument is not a string. | | `args` | array\ | Remaining console arguments when the first argument is a string, or all arguments otherwise. | ## Example ```json { "event_type": "log", "severity": "info", "message": "User signed in", "args": [ 123, { "ok": true } ] } ``` # request.handled > An inbound HTTP request finished. Emitted by the Express, Fastify, and AWS Lambda integrations in @honeybadger-io/js, and by withHoneybadger in @honeybadger-io/nextjs, when insights.http is enabled. An inbound HTTP request finished. Emitted by the Express, Fastify, and AWS Lambda integrations in @honeybadger-io/js, and by withHoneybadger in @honeybadger-io/nextjs, when insights.http is enabled. Category **Request** Fields **8** [@honeybadger-io/js](/lib/javascript/) [@honeybadger-io/nextjs](/lib/javascript/integration/nextjs/) ## Fields 8 | Field | Type | Description | | ---------------- | -------------- | ---------------------------------------------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `request.handled`. | | `method` | string | HTTP method, e.g. "GET", "POST". | | `path` | string | Request path. | | `route` | string \| null | Matched route pattern when the framework provides one (for example Express `req.route.path` or Fastify `req.routeOptions.url`). Not set for AWS Lambda. | | `status` | integer | HTTP response status code. | | `duration` | integer | Request duration in milliseconds. | | `request_id` | string | Unique ID for this request. Read from the `x-request-id` or `request-id` header, or generated when neither is present. Merged from event context. | | `correlation_id` | string | ID that may span related requests. Read from the `x-correlation-id` or `x-amzn-trace-id` header, or falls back to `request_id`. Merged from event context. | ## Example ```json { "event_type": "request.handled", "method": "GET", "path": "/users/123", "route": "/users/:id", "status": 200, "duration": 42, "request_id": "f3b2c1d0-4e5a-4b6c-8d7e-9f0a1b2c3d4e", "correlation_id": "f3b2c1d0-4e5a-4b6c-8d7e-9f0a1b2c3d4e" } ``` # Laravel event reference > Insights event types emitted by Laravel. Every event the Honeybadger Laravel package sends to Insights when events are enabled: handled requests, database queries and transactions, cache hits and misses, queued and processed jobs, mail, notifications, Redis commands, route matches, and view renders. Each entry lists the event's fields with their types, and links to its raw JSON Schema. **18** events emitted by [`honeybadger-laravel`](/lib/php/integration/laravel/). *** ## Blade ### view\.rendered[](/insights/event-types/laravel/view.rendered/ "View event details")[](/insights/event-types/laravel/view.rendered.schema.json "View JSON Schema") A Blade view was rendered. | Field | Type | Description | | ------------ | ------ | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `view.rendered`. | | `name` | string | View name, e.g. "users.show". | | `path` | string | Filesystem path to the view file. | | `duration` | number | Duration in microseconds. The client sends a value with an ms suffix, such as "5.123ms". The ingestion pipeline converts it to microseconds. | | `requestId` | string | Correlation ID for the request, set by the AssignRequestId middleware via Laravel's shared log context. The value comes from the Request-Id or X-Request-Id request header, or is a generated UUID. Present only when that middleware is enabled. | Example ```json { "event_type": "view.rendered", "name": "users.show", "path": "/var/www/html/resources/views/users/show.blade.php", "duration": 3500, "requestId": "f3b2c1d0-4e5a-4b6c-8d7e-9f0a1b2c3d4e" } ``` ## Cache ### cache.hit[](/insights/event-types/laravel/cache.hit/ "View event details")[](/insights/event-types/laravel/cache.hit.schema.json "View JSON Schema") A cache key was found (hit). | Field | Type | Description | | ------------ | ------ | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `cache.hit`. | | `key` | string | Cache key that was hit. | | `requestId` | string | Correlation ID for the request, set by the AssignRequestId middleware via Laravel's shared log context. The value comes from the Request-Id or X-Request-Id request header, or is a generated UUID. Present only when that middleware is enabled. | Example ```json { "event_type": "cache.hit", "key": "users:123", "requestId": "f3b2c1d0-4e5a-4b6c-8d7e-9f0a1b2c3d4e" } ``` ### cache.miss[](/insights/event-types/laravel/cache.miss/ "View event details")[](/insights/event-types/laravel/cache.miss.schema.json "View JSON Schema") A cache key was not found (miss). | Field | Type | Description | | ------------ | ------ | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `cache.miss`. | | `key` | string | Cache key that was missed. | | `requestId` | string | Correlation ID for the request, set by the AssignRequestId middleware via Laravel's shared log context. The value comes from the Request-Id or X-Request-Id request header, or is a generated UUID. Present only when that middleware is enabled. | Example ```json { "event_type": "cache.miss", "key": "users:123", "requestId": "f3b2c1d0-4e5a-4b6c-8d7e-9f0a1b2c3d4e" } ``` ## Database ### db.executed[](/insights/event-types/laravel/db.executed/ "View event details")[](/insights/event-types/laravel/db.executed.schema.json "View JSON Schema") A Laravel database query. SQL literals are replaced with ?. | Field | Type | Description | | ---------------- | ------ | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `db.executed`. | | `connectionName` | string | Database connection name, e.g. "mysql", "pgsql". | | `sql` | string | Sanitized SQL with literals replaced by ?. | | `duration` | number | Duration in microseconds. The client sends a value with an ms suffix, such as "5.123ms". The ingestion pipeline converts it to microseconds. | | `requestId` | string | Correlation ID for the request, set by the AssignRequestId middleware via Laravel's shared log context. The value comes from the Request-Id or X-Request-Id request header, or is a generated UUID. Present only when that middleware is enabled. | Example ```json { "event_type": "db.executed", "connectionName": "mysql", "sql": "select * from `users` where `id` = ? limit ?", "duration": 2340, "requestId": "f3b2c1d0-4e5a-4b6c-8d7e-9f0a1b2c3d4e" } ``` ### db.transaction.committed[](/insights/event-types/laravel/db.transaction.committed/ "View event details")[](/insights/event-types/laravel/db.transaction.committed.schema.json "View JSON Schema") A database transaction was committed. | Field | Type | Description | | ---------------- | ------ | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `db.transaction.committed`. | | `connectionName` | string | Database connection name. | | `requestId` | string | Correlation ID for the request, set by the AssignRequestId middleware via Laravel's shared log context. The value comes from the Request-Id or X-Request-Id request header, or is a generated UUID. Present only when that middleware is enabled. | Example ```json { "event_type": "db.transaction.committed", "connectionName": "mysql", "requestId": "f3b2c1d0-4e5a-4b6c-8d7e-9f0a1b2c3d4e" } ``` ### db.transaction.rolledback[](/insights/event-types/laravel/db.transaction.rolledback/ "View event details")[](/insights/event-types/laravel/db.transaction.rolledback.schema.json "View JSON Schema") A database transaction was rolled back. | Field | Type | Description | | ---------------- | ------ | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `db.transaction.rolledback`. | | `connectionName` | string | Database connection name. | | `requestId` | string | Correlation ID for the request, set by the AssignRequestId middleware via Laravel's shared log context. The value comes from the Request-Id or X-Request-Id request header, or is a generated UUID. Present only when that middleware is enabled. | Example ```json { "event_type": "db.transaction.rolledback", "connectionName": "mysql", "requestId": "f3b2c1d0-4e5a-4b6c-8d7e-9f0a1b2c3d4e" } ``` ### db.transaction.started[](/insights/event-types/laravel/db.transaction.started/ "View event details")[](/insights/event-types/laravel/db.transaction.started.schema.json "View JSON Schema") A database transaction was started. | Field | Type | Description | | ---------------- | ------ | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `db.transaction.started`. | | `connectionName` | string | Database connection name. | | `requestId` | string | Correlation ID for the request, set by the AssignRequestId middleware via Laravel's shared log context. The value comes from the Request-Id or X-Request-Id request header, or is a generated UUID. Present only when that middleware is enabled. | Example ```json { "event_type": "db.transaction.started", "connectionName": "mysql", "requestId": "f3b2c1d0-4e5a-4b6c-8d7e-9f0a1b2c3d4e" } ``` ## HTTP client ### response.received[](/insights/event-types/laravel/response.received/ "View event details")[](/insights/event-types/laravel/response.received.schema.json "View JSON Schema") Laravel's HTTP client received a response. | Field | Type | Description | | ------------ | ------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `response.received`. | | `uri` | string | URL of the outbound request. | | `statusCode` | integer | HTTP response status code. | | `duration` | number | Duration in microseconds. The client sends a value with an ms suffix, such as "5.123ms". The ingestion pipeline converts it to microseconds. | | `requestId` | string | Correlation ID for the request, set by the AssignRequestId middleware via Laravel's shared log context. The value comes from the Request-Id or X-Request-Id request header, or is a generated UUID. Present only when that middleware is enabled. | Example ```json { "event_type": "response.received", "uri": "https://api.example.com/v1/payments", "statusCode": 200, "duration": 87000, "requestId": "f3b2c1d0-4e5a-4b6c-8d7e-9f0a1b2c3d4e" } ``` ## Mail ### mail.sending[](/insights/event-types/laravel/mail.sending/ "View event details")[](/insights/event-types/laravel/mail.sending.schema.json "View JSON Schema") A mail message is about to be sent. | Field | Type | Description | | ------------ | -------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `mail.sending`. | | `to` | string \| null | Comma-separated recipient addresses. Null when none are set. | | `subject` | string \| null | Email subject. Null when not set. | | `cc` | string \| null | Comma-separated CC addresses. | | `bcc` | string \| null | Comma-separated BCC addresses. | | `replyTo` | string \| null | Comma-separated reply-to addresses. | | `queue` | string \| null | Queue name if the mail was queued. | | `requestId` | string | Correlation ID for the request, set by the AssignRequestId middleware via Laravel's shared log context. The value comes from the Request-Id or X-Request-Id request header, or is a generated UUID. Present only when that middleware is enabled. | Example ```json { "event_type": "mail.sending", "to": "user@example.com", "subject": "Welcome to Example App", "cc": "manager@example.com", "bcc": "audit@example.com", "replyTo": "support@example.com", "queue": "default", "requestId": "f3b2c1d0-4e5a-4b6c-8d7e-9f0a1b2c3d4e" } ``` ### mail.sent[](/insights/event-types/laravel/mail.sent/ "View event details")[](/insights/event-types/laravel/mail.sent.schema.json "View JSON Schema") A mail message was sent. | Field | Type | Description | | ------------ | -------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `mail.sent`. | | `to` | string \| null | Comma-separated recipient addresses. Null when none are set. | | `subject` | string \| null | Email subject. Null when not set. | | `cc` | string \| null | Comma-separated CC addresses. | | `bcc` | string \| null | Comma-separated BCC addresses. | | `replyTo` | string \| null | Comma-separated reply-to addresses. | | `queue` | string \| null | Queue name if the mail was queued. | | `requestId` | string | Correlation ID for the request, set by the AssignRequestId middleware via Laravel's shared log context. The value comes from the Request-Id or X-Request-Id request header, or is a generated UUID. Present only when that middleware is enabled. | Example ```json { "event_type": "mail.sent", "to": "user@example.com", "subject": "Welcome to Example App", "cc": "manager@example.com", "bcc": "audit@example.com", "replyTo": "support@example.com", "queue": "default", "requestId": "f3b2c1d0-4e5a-4b6c-8d7e-9f0a1b2c3d4e" } ``` ## Notifications ### notification.failed[](/insights/event-types/laravel/notification.failed/ "View event details")[](/insights/event-types/laravel/notification.failed.schema.json "View JSON Schema") A notification failed to send. | Field | Type | Description | | -------------- | -------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `notification.failed`. | | `notification` | string | Notification class name. | | `channel` | string | Channel that failed. | | `notifiable` | string | Notifiable class name. | | `queue` | string \| null | Queue name if queued. | | `requestId` | string | Correlation ID for the request, set by the AssignRequestId middleware via Laravel's shared log context. The value comes from the Request-Id or X-Request-Id request header, or is a generated UUID. Present only when that middleware is enabled. | Example ```json { "event_type": "notification.failed", "notification": "App\\Notifications\\InvoicePaid", "channel": "mail", "notifiable": "App\\Models\\User", "queue": "default", "requestId": "f3b2c1d0-4e5a-4b6c-8d7e-9f0a1b2c3d4e" } ``` ### notification.sending[](/insights/event-types/laravel/notification.sending/ "View event details")[](/insights/event-types/laravel/notification.sending.schema.json "View JSON Schema") A notification is about to be sent. | Field | Type | Description | | -------------- | -------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `notification.sending`. | | `notification` | string | Notification class name. | | `channel` | string | Channel the notification is sent through, e.g. "mail", "slack". | | `notifiable` | string | Notifiable class name (the recipient model). | | `queue` | string \| null | Queue name if the notification was queued. | | `requestId` | string | Correlation ID for the request, set by the AssignRequestId middleware via Laravel's shared log context. The value comes from the Request-Id or X-Request-Id request header, or is a generated UUID. Present only when that middleware is enabled. | Example ```json { "event_type": "notification.sending", "notification": "App\\Notifications\\InvoicePaid", "channel": "mail", "notifiable": "App\\Models\\User", "queue": "default", "requestId": "f3b2c1d0-4e5a-4b6c-8d7e-9f0a1b2c3d4e" } ``` ### notification.sent[](/insights/event-types/laravel/notification.sent/ "View event details")[](/insights/event-types/laravel/notification.sent.schema.json "View JSON Schema") A notification was sent. | Field | Type | Description | | -------------- | -------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `notification.sent`. | | `notification` | string | Notification class name. | | `channel` | string | Channel used. | | `notifiable` | string | Notifiable class name. | | `queue` | string \| null | Queue name if queued. | | `requestId` | string | Correlation ID for the request, set by the AssignRequestId middleware via Laravel's shared log context. The value comes from the Request-Id or X-Request-Id request header, or is a generated UUID. Present only when that middleware is enabled. | Example ```json { "event_type": "notification.sent", "notification": "App\\Notifications\\InvoicePaid", "channel": "mail", "notifiable": "App\\Models\\User", "queue": "default", "requestId": "f3b2c1d0-4e5a-4b6c-8d7e-9f0a1b2c3d4e" } ``` ## Queue ### job.processed[](/insights/event-types/laravel/job.processed/ "View event details")[](/insights/event-types/laravel/job.processed.schema.json "View JSON Schema") A Laravel queue job finished processing. | Field | Type | Description | | ---------------- | --------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `job.processed`. | | `connectionName` | string | Queue connection name, e.g. "redis", "database". | | `job` | string | Resolved job class name. | | `id` | string | Job ID. | | `attempts` | integer | Number of attempts made. | | `hasFailed` | boolean | Whether the job was marked as failed. | | `isReleased` | boolean | Whether the job was released back to the queue. | | `isDeleted` | boolean | Whether the job was deleted from the queue. | | `maxTries` | integer \| null | Maximum retry attempts allowed. | | `maxExceptions` | integer \| null | Maximum exceptions before the job is failed. | | `timeout` | integer \| null | Job timeout in seconds. | | `retryUntil` | integer \| null | Timestamp after which the job should not be retried. | | `duration` | number | Duration in microseconds. The client sends a value with an ms suffix, such as "5.123ms". The ingestion pipeline converts it to microseconds. | | `requestId` | string | Correlation ID for the request, set by the AssignRequestId middleware via Laravel's shared log context. The value comes from the Request-Id or X-Request-Id request header, or is a generated UUID. Present only when that middleware is enabled. | Example ```json { "event_type": "job.processed", "connectionName": "redis", "job": "App\\Jobs\\SendWelcomeEmail", "id": "9c2e1f7a-3b4d-4e5f-8a6b-1c2d3e4f5a6b", "attempts": 1, "hasFailed": false, "isReleased": false, "isDeleted": true, "maxTries": 3, "maxExceptions": 3, "timeout": 60, "retryUntil": 1781272800, "duration": 312000, "requestId": "f3b2c1d0-4e5a-4b6c-8d7e-9f0a1b2c3d4e" } ``` ### job.queued[](/insights/event-types/laravel/job.queued/ "View event details")[](/insights/event-types/laravel/job.queued.schema.json "View JSON Schema") A Laravel job was pushed onto a queue. Requires Laravel 8.24+. | Field | Type | Description | | ---------------- | --------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `job.queued`. | | `connectionName` | string | Queue connection name. | | `job` | string | Job class name. | | `id` | string | Job ID. | | `queue` | string \| null | Queue name, if available. | | `delay` | integer \| null | Delay in seconds before the job becomes available. | | `requestId` | string | Correlation ID for the request, set by the AssignRequestId middleware via Laravel's shared log context. The value comes from the Request-Id or X-Request-Id request header, or is a generated UUID. Present only when that middleware is enabled. | Example ```json { "event_type": "job.queued", "connectionName": "redis", "job": "App\\Jobs\\SendWelcomeEmail", "id": "9c2e1f7a-3b4d-4e5f-8a6b-1c2d3e4f5a6b", "queue": "default", "delay": 30, "requestId": "f3b2c1d0-4e5a-4b6c-8d7e-9f0a1b2c3d4e" } ``` ## Redis ### redis.executed[](/insights/event-types/laravel/redis.executed/ "View event details")[](/insights/event-types/laravel/redis.executed.schema.json "View JSON Schema") A Redis command was executed. | Field | Type | Description | | ---------------- | ------ | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `redis.executed`. | | `connectionName` | string | Redis connection name. | | `command` | string | Formatted Redis command with parameters. | | `duration` | number | Duration in microseconds. The client sends a value with an ms suffix, such as "5.123ms". The ingestion pipeline converts it to microseconds. | | `requestId` | string | Correlation ID for the request, set by the AssignRequestId middleware via Laravel's shared log context. The value comes from the Request-Id or X-Request-Id request header, or is a generated UUID. Present only when that middleware is enabled. | Example ```json { "event_type": "redis.executed", "connectionName": "default", "command": "get users:123", "duration": 450, "requestId": "f3b2c1d0-4e5a-4b6c-8d7e-9f0a1b2c3d4e" } ``` ## Request ### request.handled[](/insights/event-types/laravel/request.handled/ "View event details")[](/insights/event-types/laravel/request.handled.schema.json "View JSON Schema") A Laravel controller handled an HTTP request. | Field | Type | Description | | ------------ | -------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `request.handled`. | | `uri` | string | Full request URL. | | `method` | string | HTTP method, e.g. "GET", "POST". | | `statusCode` | integer | HTTP response status code. | | `duration` | number | Duration in microseconds. The client sends a value with an ms suffix, such as "5.123ms". The ingestion pipeline converts it to microseconds. | | `controller` | string \| null | Controller class name. Null for closure routes or when no route was matched. | | `action` | string \| null | Controller action method name. Null when no route was matched. | | `routeName` | string \| null | Name of the matched route. Null when the route is unnamed or no route was matched. | | `requestId` | string | Correlation ID for the request, set by the AssignRequestId middleware via Laravel's shared log context. The value comes from the Request-Id or X-Request-Id request header, or is a generated UUID. Present only when that middleware is enabled. | Example ```json { "event_type": "request.handled", "uri": "https://app.example.com/users/123", "method": "GET", "statusCode": 200, "duration": 124000, "controller": "App\\Http\\Controllers\\UserController", "action": "show", "routeName": "users.show", "requestId": "f3b2c1d0-4e5a-4b6c-8d7e-9f0a1b2c3d4e" } ``` ## Routing ### route.matched[](/insights/event-types/laravel/route.matched/ "View event details")[](/insights/event-types/laravel/route.matched.schema.json "View JSON Schema") Laravel matched a route before running the controller. | Field | Type | Description | | ------------ | -------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `route.matched`. | | `uri` | string | Route URI pattern, e.g. "users/{id}". | | `methods` | string | Comma-separated HTTP methods the route accepts. | | `handler` | string | Controller\@method string or closure class name. | | `name` | string \| null | Named route, if defined. | | `requestId` | string | Correlation ID for the request, set by the AssignRequestId middleware via Laravel's shared log context. The value comes from the Request-Id or X-Request-Id request header, or is a generated UUID. Present only when that middleware is enabled. | Example ```json { "event_type": "route.matched", "uri": "users/{id}", "methods": "GET,HEAD", "handler": "App\\Http\\Controllers\\UserController@show", "name": "users.show", "requestId": "f3b2c1d0-4e5a-4b6c-8d7e-9f0a1b2c3d4e" } ``` # cache.hit > A cache key was found (hit). A cache key was found (hit). Source **Cache** Category **Cache** Fields **3** [honeybadger-laravel](/lib/php/integration/laravel/) ## Fields 3 | Field | Type | Description | | ------------ | ------ | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `cache.hit`. | | `key` | string | Cache key that was hit. | | `requestId` | string | Correlation ID for the request, set by the AssignRequestId middleware via Laravel's shared log context. The value comes from the Request-Id or X-Request-Id request header, or is a generated UUID. Present only when that middleware is enabled. | ## Example ```json { "event_type": "cache.hit", "key": "users:123", "requestId": "f3b2c1d0-4e5a-4b6c-8d7e-9f0a1b2c3d4e" } ``` # cache.miss > A cache key was not found (miss). A cache key was not found (miss). Source **Cache** Category **Cache** Fields **3** [honeybadger-laravel](/lib/php/integration/laravel/) ## Fields 3 | Field | Type | Description | | ------------ | ------ | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `cache.miss`. | | `key` | string | Cache key that was missed. | | `requestId` | string | Correlation ID for the request, set by the AssignRequestId middleware via Laravel's shared log context. The value comes from the Request-Id or X-Request-Id request header, or is a generated UUID. Present only when that middleware is enabled. | ## Example ```json { "event_type": "cache.miss", "key": "users:123", "requestId": "f3b2c1d0-4e5a-4b6c-8d7e-9f0a1b2c3d4e" } ``` # db.executed > A Laravel database query. SQL literals are replaced with ?. A Laravel database query. SQL literals are replaced with ?. Source **Database** Category **Database** Fields **5** [honeybadger-laravel](/lib/php/integration/laravel/) ## Fields 5 | Field | Type | Description | | ---------------- | ------ | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `db.executed`. | | `connectionName` | string | Database connection name, e.g. "mysql", "pgsql". | | `sql` | string | Sanitized SQL with literals replaced by ?. | | `duration` | number | Duration in microseconds. The client sends a value with an ms suffix, such as "5.123ms". The ingestion pipeline converts it to microseconds. | | `requestId` | string | Correlation ID for the request, set by the AssignRequestId middleware via Laravel's shared log context. The value comes from the Request-Id or X-Request-Id request header, or is a generated UUID. Present only when that middleware is enabled. | ## Example ```json { "event_type": "db.executed", "connectionName": "mysql", "sql": "select * from `users` where `id` = ? limit ?", "duration": 2340, "requestId": "f3b2c1d0-4e5a-4b6c-8d7e-9f0a1b2c3d4e" } ``` # db.transaction.committed > A database transaction was committed. A database transaction was committed. Source **Database** Category **Database** Fields **3** [honeybadger-laravel](/lib/php/integration/laravel/) ## Fields 3 | Field | Type | Description | | ---------------- | ------ | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `db.transaction.committed`. | | `connectionName` | string | Database connection name. | | `requestId` | string | Correlation ID for the request, set by the AssignRequestId middleware via Laravel's shared log context. The value comes from the Request-Id or X-Request-Id request header, or is a generated UUID. Present only when that middleware is enabled. | ## Example ```json { "event_type": "db.transaction.committed", "connectionName": "mysql", "requestId": "f3b2c1d0-4e5a-4b6c-8d7e-9f0a1b2c3d4e" } ``` # db.transaction.rolledback > A database transaction was rolled back. A database transaction was rolled back. Source **Database** Category **Database** Fields **3** [honeybadger-laravel](/lib/php/integration/laravel/) ## Fields 3 | Field | Type | Description | | ---------------- | ------ | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `db.transaction.rolledback`. | | `connectionName` | string | Database connection name. | | `requestId` | string | Correlation ID for the request, set by the AssignRequestId middleware via Laravel's shared log context. The value comes from the Request-Id or X-Request-Id request header, or is a generated UUID. Present only when that middleware is enabled. | ## Example ```json { "event_type": "db.transaction.rolledback", "connectionName": "mysql", "requestId": "f3b2c1d0-4e5a-4b6c-8d7e-9f0a1b2c3d4e" } ``` # db.transaction.started > A database transaction was started. A database transaction was started. Source **Database** Category **Database** Fields **3** [honeybadger-laravel](/lib/php/integration/laravel/) ## Fields 3 | Field | Type | Description | | ---------------- | ------ | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `db.transaction.started`. | | `connectionName` | string | Database connection name. | | `requestId` | string | Correlation ID for the request, set by the AssignRequestId middleware via Laravel's shared log context. The value comes from the Request-Id or X-Request-Id request header, or is a generated UUID. Present only when that middleware is enabled. | ## Example ```json { "event_type": "db.transaction.started", "connectionName": "mysql", "requestId": "f3b2c1d0-4e5a-4b6c-8d7e-9f0a1b2c3d4e" } ``` # job.processed > A Laravel queue job finished processing. A Laravel queue job finished processing. Source **Queue** Category **Jobs** Fields **14** [honeybadger-laravel](/lib/php/integration/laravel/) ## Fields 14 | Field | Type | Description | | ---------------- | --------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `job.processed`. | | `connectionName` | string | Queue connection name, e.g. "redis", "database". | | `job` | string | Resolved job class name. | | `id` | string | Job ID. | | `attempts` | integer | Number of attempts made. | | `hasFailed` | boolean | Whether the job was marked as failed. | | `isReleased` | boolean | Whether the job was released back to the queue. | | `isDeleted` | boolean | Whether the job was deleted from the queue. | | `maxTries` | integer \| null | Maximum retry attempts allowed. | | `maxExceptions` | integer \| null | Maximum exceptions before the job is failed. | | `timeout` | integer \| null | Job timeout in seconds. | | `retryUntil` | integer \| null | Timestamp after which the job should not be retried. | | `duration` | number | Duration in microseconds. The client sends a value with an ms suffix, such as "5.123ms". The ingestion pipeline converts it to microseconds. | | `requestId` | string | Correlation ID for the request, set by the AssignRequestId middleware via Laravel's shared log context. The value comes from the Request-Id or X-Request-Id request header, or is a generated UUID. Present only when that middleware is enabled. | ## Example ```json { "event_type": "job.processed", "connectionName": "redis", "job": "App\\Jobs\\SendWelcomeEmail", "id": "9c2e1f7a-3b4d-4e5f-8a6b-1c2d3e4f5a6b", "attempts": 1, "hasFailed": false, "isReleased": false, "isDeleted": true, "maxTries": 3, "maxExceptions": 3, "timeout": 60, "retryUntil": 1781272800, "duration": 312000, "requestId": "f3b2c1d0-4e5a-4b6c-8d7e-9f0a1b2c3d4e" } ``` # job.queued > A Laravel job was pushed onto a queue. Requires Laravel 8.24+. A Laravel job was pushed onto a queue. Requires Laravel 8.24+. Source **Queue** Category **Jobs** Fields **7** [honeybadger-laravel](/lib/php/integration/laravel/) ## Fields 7 | Field | Type | Description | | ---------------- | --------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `job.queued`. | | `connectionName` | string | Queue connection name. | | `job` | string | Job class name. | | `id` | string | Job ID. | | `queue` | string \| null | Queue name, if available. | | `delay` | integer \| null | Delay in seconds before the job becomes available. | | `requestId` | string | Correlation ID for the request, set by the AssignRequestId middleware via Laravel's shared log context. The value comes from the Request-Id or X-Request-Id request header, or is a generated UUID. Present only when that middleware is enabled. | ## Example ```json { "event_type": "job.queued", "connectionName": "redis", "job": "App\\Jobs\\SendWelcomeEmail", "id": "9c2e1f7a-3b4d-4e5f-8a6b-1c2d3e4f5a6b", "queue": "default", "delay": 30, "requestId": "f3b2c1d0-4e5a-4b6c-8d7e-9f0a1b2c3d4e" } ``` # mail.sending > A mail message is about to be sent. A mail message is about to be sent. Source **Mail** Category **Mail** Fields **8** [honeybadger-laravel](/lib/php/integration/laravel/) ## Fields 8 | Field | Type | Description | | ------------ | -------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `mail.sending`. | | `to` | string \| null | Comma-separated recipient addresses. Null when none are set. | | `subject` | string \| null | Email subject. Null when not set. | | `cc` | string \| null | Comma-separated CC addresses. | | `bcc` | string \| null | Comma-separated BCC addresses. | | `replyTo` | string \| null | Comma-separated reply-to addresses. | | `queue` | string \| null | Queue name if the mail was queued. | | `requestId` | string | Correlation ID for the request, set by the AssignRequestId middleware via Laravel's shared log context. The value comes from the Request-Id or X-Request-Id request header, or is a generated UUID. Present only when that middleware is enabled. | ## Example ```json { "event_type": "mail.sending", "to": "user@example.com", "subject": "Welcome to Example App", "cc": "manager@example.com", "bcc": "audit@example.com", "replyTo": "support@example.com", "queue": "default", "requestId": "f3b2c1d0-4e5a-4b6c-8d7e-9f0a1b2c3d4e" } ``` # mail.sent > A mail message was sent. A mail message was sent. Source **Mail** Category **Mail** Fields **8** [honeybadger-laravel](/lib/php/integration/laravel/) ## Fields 8 | Field | Type | Description | | ------------ | -------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `mail.sent`. | | `to` | string \| null | Comma-separated recipient addresses. Null when none are set. | | `subject` | string \| null | Email subject. Null when not set. | | `cc` | string \| null | Comma-separated CC addresses. | | `bcc` | string \| null | Comma-separated BCC addresses. | | `replyTo` | string \| null | Comma-separated reply-to addresses. | | `queue` | string \| null | Queue name if the mail was queued. | | `requestId` | string | Correlation ID for the request, set by the AssignRequestId middleware via Laravel's shared log context. The value comes from the Request-Id or X-Request-Id request header, or is a generated UUID. Present only when that middleware is enabled. | ## Example ```json { "event_type": "mail.sent", "to": "user@example.com", "subject": "Welcome to Example App", "cc": "manager@example.com", "bcc": "audit@example.com", "replyTo": "support@example.com", "queue": "default", "requestId": "f3b2c1d0-4e5a-4b6c-8d7e-9f0a1b2c3d4e" } ``` # notification.failed > A notification failed to send. A notification failed to send. Source **Notifications** Category **Notifications** Fields **6** [honeybadger-laravel](/lib/php/integration/laravel/) ## Fields 6 | Field | Type | Description | | -------------- | -------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `notification.failed`. | | `notification` | string | Notification class name. | | `channel` | string | Channel that failed. | | `notifiable` | string | Notifiable class name. | | `queue` | string \| null | Queue name if queued. | | `requestId` | string | Correlation ID for the request, set by the AssignRequestId middleware via Laravel's shared log context. The value comes from the Request-Id or X-Request-Id request header, or is a generated UUID. Present only when that middleware is enabled. | ## Example ```json { "event_type": "notification.failed", "notification": "App\\Notifications\\InvoicePaid", "channel": "mail", "notifiable": "App\\Models\\User", "queue": "default", "requestId": "f3b2c1d0-4e5a-4b6c-8d7e-9f0a1b2c3d4e" } ``` # notification.sending > A notification is about to be sent. A notification is about to be sent. Source **Notifications** Category **Notifications** Fields **6** [honeybadger-laravel](/lib/php/integration/laravel/) ## Fields 6 | Field | Type | Description | | -------------- | -------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `notification.sending`. | | `notification` | string | Notification class name. | | `channel` | string | Channel the notification is sent through, e.g. "mail", "slack". | | `notifiable` | string | Notifiable class name (the recipient model). | | `queue` | string \| null | Queue name if the notification was queued. | | `requestId` | string | Correlation ID for the request, set by the AssignRequestId middleware via Laravel's shared log context. The value comes from the Request-Id or X-Request-Id request header, or is a generated UUID. Present only when that middleware is enabled. | ## Example ```json { "event_type": "notification.sending", "notification": "App\\Notifications\\InvoicePaid", "channel": "mail", "notifiable": "App\\Models\\User", "queue": "default", "requestId": "f3b2c1d0-4e5a-4b6c-8d7e-9f0a1b2c3d4e" } ``` # notification.sent > A notification was sent. A notification was sent. Source **Notifications** Category **Notifications** Fields **6** [honeybadger-laravel](/lib/php/integration/laravel/) ## Fields 6 | Field | Type | Description | | -------------- | -------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `notification.sent`. | | `notification` | string | Notification class name. | | `channel` | string | Channel used. | | `notifiable` | string | Notifiable class name. | | `queue` | string \| null | Queue name if queued. | | `requestId` | string | Correlation ID for the request, set by the AssignRequestId middleware via Laravel's shared log context. The value comes from the Request-Id or X-Request-Id request header, or is a generated UUID. Present only when that middleware is enabled. | ## Example ```json { "event_type": "notification.sent", "notification": "App\\Notifications\\InvoicePaid", "channel": "mail", "notifiable": "App\\Models\\User", "queue": "default", "requestId": "f3b2c1d0-4e5a-4b6c-8d7e-9f0a1b2c3d4e" } ``` # redis.executed > A Redis command was executed. A Redis command was executed. Source **Redis** Category **Database** Fields **5** [honeybadger-laravel](/lib/php/integration/laravel/) ## Fields 5 | Field | Type | Description | | ---------------- | ------ | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `redis.executed`. | | `connectionName` | string | Redis connection name. | | `command` | string | Formatted Redis command with parameters. | | `duration` | number | Duration in microseconds. The client sends a value with an ms suffix, such as "5.123ms". The ingestion pipeline converts it to microseconds. | | `requestId` | string | Correlation ID for the request, set by the AssignRequestId middleware via Laravel's shared log context. The value comes from the Request-Id or X-Request-Id request header, or is a generated UUID. Present only when that middleware is enabled. | ## Example ```json { "event_type": "redis.executed", "connectionName": "default", "command": "get users:123", "duration": 450, "requestId": "f3b2c1d0-4e5a-4b6c-8d7e-9f0a1b2c3d4e" } ``` # request.handled > A Laravel controller handled an HTTP request. A Laravel controller handled an HTTP request. Category **Request** Fields **9** [honeybadger-laravel](/lib/php/integration/laravel/) ## Fields 9 | Field | Type | Description | | ------------ | -------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `request.handled`. | | `uri` | string | Full request URL. | | `method` | string | HTTP method, e.g. "GET", "POST". | | `statusCode` | integer | HTTP response status code. | | `duration` | number | Duration in microseconds. The client sends a value with an ms suffix, such as "5.123ms". The ingestion pipeline converts it to microseconds. | | `controller` | string \| null | Controller class name. Null for closure routes or when no route was matched. | | `action` | string \| null | Controller action method name. Null when no route was matched. | | `routeName` | string \| null | Name of the matched route. Null when the route is unnamed or no route was matched. | | `requestId` | string | Correlation ID for the request, set by the AssignRequestId middleware via Laravel's shared log context. The value comes from the Request-Id or X-Request-Id request header, or is a generated UUID. Present only when that middleware is enabled. | ## Example ```json { "event_type": "request.handled", "uri": "https://app.example.com/users/123", "method": "GET", "statusCode": 200, "duration": 124000, "controller": "App\\Http\\Controllers\\UserController", "action": "show", "routeName": "users.show", "requestId": "f3b2c1d0-4e5a-4b6c-8d7e-9f0a1b2c3d4e" } ``` # response.received > Laravel's HTTP client received a response. Laravel’s HTTP client received a response. Source **HTTP client** Category **HTTP** Fields **5** [honeybadger-laravel](/lib/php/integration/laravel/) ## Fields 5 | Field | Type | Description | | ------------ | ------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `response.received`. | | `uri` | string | URL of the outbound request. | | `statusCode` | integer | HTTP response status code. | | `duration` | number | Duration in microseconds. The client sends a value with an ms suffix, such as "5.123ms". The ingestion pipeline converts it to microseconds. | | `requestId` | string | Correlation ID for the request, set by the AssignRequestId middleware via Laravel's shared log context. The value comes from the Request-Id or X-Request-Id request header, or is a generated UUID. Present only when that middleware is enabled. | ## Example ```json { "event_type": "response.received", "uri": "https://api.example.com/v1/payments", "statusCode": 200, "duration": 87000, "requestId": "f3b2c1d0-4e5a-4b6c-8d7e-9f0a1b2c3d4e" } ``` # route.matched > Laravel matched a route before running the controller. Laravel matched a route before running the controller. Source **Routing** Category **Request** Fields **6** [honeybadger-laravel](/lib/php/integration/laravel/) ## Fields 6 | Field | Type | Description | | ------------ | -------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `route.matched`. | | `uri` | string | Route URI pattern, e.g. "users/{id}". | | `methods` | string | Comma-separated HTTP methods the route accepts. | | `handler` | string | Controller\@method string or closure class name. | | `name` | string \| null | Named route, if defined. | | `requestId` | string | Correlation ID for the request, set by the AssignRequestId middleware via Laravel's shared log context. The value comes from the Request-Id or X-Request-Id request header, or is a generated UUID. Present only when that middleware is enabled. | ## Example ```json { "event_type": "route.matched", "uri": "users/{id}", "methods": "GET,HEAD", "handler": "App\\Http\\Controllers\\UserController@show", "name": "users.show", "requestId": "f3b2c1d0-4e5a-4b6c-8d7e-9f0a1b2c3d4e" } ``` # view.rendered > A Blade view was rendered. A Blade view was rendered. Source **Blade** Category **View** Fields **5** [honeybadger-laravel](/lib/php/integration/laravel/) ## Fields 5 | Field | Type | Description | | ------------ | ------ | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `view.rendered`. | | `name` | string | View name, e.g. "users.show". | | `path` | string | Filesystem path to the view file. | | `duration` | number | Duration in microseconds. The client sends a value with an ms suffix, such as "5.123ms". The ingestion pipeline converts it to microseconds. | | `requestId` | string | Correlation ID for the request, set by the AssignRequestId middleware via Laravel's shared log context. The value comes from the Request-Id or X-Request-Id request header, or is a generated UUID. Present only when that middleware is enabled. | ## Example ```json { "event_type": "view.rendered", "name": "users.show", "path": "/var/www/html/resources/views/users/show.blade.php", "duration": 3500, "requestId": "f3b2c1d0-4e5a-4b6c-8d7e-9f0a1b2c3d4e" } ``` # Python event reference > Insights event types emitted by Python. Every event the Honeybadger Python package sends to Insights when instrumentation is enabled: Django, Flask, and ASGI requests, database queries, and Celery tasks. Each entry lists the event's fields with their types, and links to its raw JSON Schema. **13** events emitted by [`honeybadger-python`](/lib/python/). *** ## ASGI ### asgi.request[](/insights/event-types/python/asgi.request/ "View event details")[](/insights/event-types/python/asgi.request.schema.json "View JSON Schema") An ASGI app finished handling an HTTP request. Used by FastAPI, Starlette, and similar frameworks. | Field | Type | Description | | ------------ | ------- | --------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `asgi.request`. | | `path` | string | Request path from the ASGI scope. | | `method` | string | HTTP method, e.g. "GET", "POST". | | `status` | integer | HTTP response status code. | | `duration` | number | Request duration in milliseconds. | | `params` | object | Parsed query string params. Only present when include\_params is enabled in insights\_config. | | `params.*` | any | Additional caller-defined keys. | | `request_id` | string | Request ID from event context, if set. | Example ```json { "event_type": "asgi.request", "path": "/users/123", "method": "GET", "status": 200, "duration": 23.4567, "params": { "page": "2", "sort": "name" }, "request_id": "1f9f6f1a-2b3c-4d5e-8f6a-7b8c9d0e1f2a" } ``` ## Celery ### celery.task\_finished[](/insights/event-types/python/celery.task_finished/ "View event details")[](/insights/event-types/python/celery.task_finished.schema.json "View JSON Schema") A Celery task finished, whether it succeeded or failed. | Field | Type | Description | | ------------ | ----------- | -------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `celery.task_finished`. | | `task_id` | string | Celery task UUID. | | `task_name` | string | Fully qualified task name, e.g. "myapp.tasks.send\_email". | | `state` | string | Final task state, e.g. "SUCCESS", "FAILURE", "RETRY". | | `retries` | integer | Number of retries so far. | | `group` | string | Celery group ID if the task is part of a group. | | `duration` | number | Task execution duration in milliseconds. | | `args` | array\ | Positional task arguments. Only present when include\_args is enabled in insights\_config. | | `kwargs` | object | Keyword task arguments (filtered). Only present when include\_args is enabled in insights\_config. | | `kwargs.*` | any | Additional caller-defined keys. | | `request_id` | string | Request ID propagated from the originating request via Celery task headers. | Example ```json { "event_type": "celery.task_finished", "task_id": "9c5e8a2f-1b3d-4c6e-9f7a-2d4b6c8e0a1f", "task_name": "myapp.tasks.send_email", "state": "SUCCESS", "retries": 0, "group": "5a7d3e9b-8c1f-4b2a-9d6e-3f5a7c9e1b4d", "duration": 845.2103, "args": [ "user@example.com" ], "kwargs": { "subject": "Welcome to MyApp" }, "request_id": "1f9f6f1a-2b3c-4d5e-8f6a-7b8c9d0e1f2a" } ``` ## Database ### db.query[](/insights/event-types/python/db.query/ "View event details")[](/insights/event-types/python/db.query.schema.json "View JSON Schema") A database query from the Django ORM or SQLAlchemy. Honeybadger skips queries that match exclude\_queries. | Field | Type | Description | | ------------ | ------ | ----------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `db.query`. | | `query` | string | SQL query string. Bind parameters may appear as literals, depending on the driver. | | `duration` | number | Query execution duration in milliseconds. | | `params` | any | Query parameters. Only present when include\_params is enabled in insights\_config. | | `request_id` | string | Request ID from event context, ties this query to the enclosing request. | Example ```json { "event_type": "db.query", "query": "SELECT \"users\".* FROM \"users\" WHERE \"users\".\"id\" = %s LIMIT 1", "duration": 2.4815, "params": [ 123 ], "request_id": "1f9f6f1a-2b3c-4d5e-8f6a-7b8c9d0e1f2a" } ``` ## Django ### django.request[](/insights/event-types/python/django.request/ "View event details")[](/insights/event-types/python/django.request.schema.json "View JSON Schema") A Django view finished handling an HTTP request. | Field | Type | Description | | ------------ | ------- | ---------------------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `django.request`. | | `path` | string | Request path, e.g. "/users/42". | | `method` | string | HTTP method, e.g. "GET", "POST". | | `status` | integer | HTTP response status code. | | `view` | string | Resolved view function name. | | `module` | string | Module containing the view function. | | `app` | string | Django app name from the URL resolver. | | `duration` | number | Request duration in milliseconds. | | `params` | object | GET and POST params. Only present when include\_params is enabled in insights\_config. | | `params.*` | any | Additional caller-defined keys. | | `request_id` | string | Request ID from X-Request-ID header, request.id/request\_id attribute, or a generated UUID. Set in event context at request start. | Example ```json { "event_type": "django.request", "path": "/users/123", "method": "GET", "status": 200, "view": "user_detail", "module": "myapp.views", "app": "users", "duration": 58.3214, "params": { "page": "2", "sort": "name" }, "request_id": "1f9f6f1a-2b3c-4d5e-8f6a-7b8c9d0e1f2a" } ``` ## Flask ### flask.request[](/insights/event-types/python/flask.request/ "View event details")[](/insights/event-types/python/flask.request.schema.json "View JSON Schema") A Flask route finished handling an HTTP request. | Field | Type | Description | | ------------ | ------- | ----------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `flask.request`. | | `path` | string | Request path, e.g. "/users/42". | | `method` | string | HTTP method, e.g. "GET", "POST". | | `status` | integer | HTTP response status code. | | `view` | string | Flask endpoint name (request.endpoint). | | `blueprint` | string | Flask blueprint name, if the route belongs to one. | | `duration` | number | Request duration in milliseconds. | | `params` | object | Query and form params. Only present when include\_params is enabled in insights\_config. | | `params.*` | any | Additional caller-defined keys. | | `request_id` | string | Request ID from X-Request-ID header or a generated UUID. Set in event context at request start. | Example ```json { "event_type": "flask.request", "path": "/users/123", "method": "GET", "status": 200, "view": "users.show", "blueprint": "users", "duration": 32.1875, "params": { "page": "2", "sort": "name" }, "request_id": "1f9f6f1a-2b3c-4d5e-8f6a-7b8c9d0e1f2a" } ``` ## Oban ### oban.job\_finished[](/insights/event-types/python/oban.job_finished/ "View event details")[](/insights/event-types/python/oban.job_finished.schema.json "View JSON Schema") An Oban job finished, whether it succeeded or failed. Emitted for both oban.job.stop and oban.job.exception telemetry events. | Field | Type | Description | | --------------- | -------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `oban.job_finished`. | | `job_id` | integer | Oban job database ID. | | `worker` | string | Fully qualified worker name ("module.Class"). | | `queue` | string | Queue the job ran on. | | `state` | string | Resulting job state: "completed", "retryable", "discarded", "cancelled", or "scheduled" (snoozed). Failures are "retryable" until max\_attempts is exhausted, then "discarded". | | `attempt` | integer | Attempt number (1-based). | | `max_attempts` | integer | Maximum number of attempts before the job is discarded. | | `duration` | number | Job execution duration in milliseconds. | | `queue_time` | number | Time the job spent waiting in the queue (scheduled\_at to attempted\_at) in milliseconds. | | `tags` | array\ | Tags assigned to the job. | | `error_type` | string | Exception class name. Only present when the job failed (state "retryable" or "discarded"). | | `error_message` | string | Exception message. Only present when the job failed (state "retryable" or "discarded"). | | `args` | object | Job arguments (filtered). Only present when include\_args is enabled in insights\_config. | | `args.*` | any | Additional caller-defined keys. | | `meta` | object | Job metadata (filtered). Only present when include\_args is enabled in insights\_config. | | `meta.*` | any | Additional caller-defined keys. | | `request_id` | string | Request ID propagated from the originating request's event context via Oban job metadata. | Example ```json { "event_type": "oban.job_finished", "job_id": 123456, "worker": "myapp.workers.WelcomeEmail", "queue": "default", "state": "completed", "attempt": 1, "max_attempts": 20, "duration": 845.2103, "queue_time": 12.5, "tags": [ "mailer" ], "error_type": "ValueError", "error_message": "invalid user id", "args": { "user_id": 42 }, "meta": { "source": "signup" }, "request_id": "1f9f6f1a-2b3c-4d5e-8f6a-7b8c9d0e1f2a" } ``` ### oban.leader\_exception[](/insights/event-types/python/oban.leader_exception/ "View event details")[](/insights/event-types/python/oban.leader_exception.schema.json "View JSON Schema") Oban's leader election loop raised an exception. | Field | Type | Description | | --------------- | ------ | ------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `oban.leader_exception`. | | `loop` | string | Name of the Oban maintenance loop that raised. Allowed value: `leader`. | | `event` | string | The underlying Oban telemetry event name. Allowed values: `oban.leader.election.exception`. | | `error_type` | string | Exception class name. | | `error_message` | string | Exception message. | | `duration` | number | Duration of the failed loop iteration in milliseconds. | Example ```json { "event_type": "oban.leader_exception", "loop": "leader", "event": "oban.leader.election.exception", "error_type": "OperationalError", "error_message": "connection to server was lost", "duration": 3.1415 } ``` ### oban.lifeline\_exception[](/insights/event-types/python/oban.lifeline_exception/ "View event details")[](/insights/event-types/python/oban.lifeline_exception.schema.json "View JSON Schema") Oban's lifeline loop, which rescues orphaned executing jobs, raised an exception. | Field | Type | Description | | --------------- | ------ | ------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `oban.lifeline_exception`. | | `loop` | string | Name of the Oban maintenance loop that raised. Allowed value: `lifeline`. | | `event` | string | The underlying Oban telemetry event name. Allowed values: `oban.lifeline.rescue.exception`. | | `error_type` | string | Exception class name. | | `error_message` | string | Exception message. | | `duration` | number | Duration of the failed loop iteration in milliseconds. | Example ```json { "event_type": "oban.lifeline_exception", "loop": "lifeline", "event": "oban.lifeline.rescue.exception", "error_type": "OperationalError", "error_message": "connection to server was lost", "duration": 3.1415 } ``` ### oban.producer\_exception[](/insights/event-types/python/oban.producer_exception/ "View event details")[](/insights/event-types/python/oban.producer_exception.schema.json "View JSON Schema") An Oban queue producer raised an exception while fetching or acking jobs. | Field | Type | Description | | --------------- | ------ | ----------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `oban.producer_exception`. | | `loop` | string | Name of the Oban maintenance loop that raised. Allowed value: `producer`. | | `event` | string | The underlying Oban telemetry event name. Allowed values: `oban.producer.get.exception`, `oban.producer.ack.exception`. | | `error_type` | string | Exception class name. | | `error_message` | string | Exception message. | | `duration` | number | Duration of the failed loop iteration in milliseconds. | Example ```json { "event_type": "oban.producer_exception", "loop": "producer", "event": "oban.producer.get.exception", "error_type": "OperationalError", "error_message": "connection to server was lost", "duration": 3.1415 } ``` ### oban.pruner\_exception[](/insights/event-types/python/oban.pruner_exception/ "View event details")[](/insights/event-types/python/oban.pruner_exception.schema.json "View JSON Schema") Oban's pruner loop, which deletes old completed jobs, raised an exception. | Field | Type | Description | | --------------- | ------ | ---------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `oban.pruner_exception`. | | `loop` | string | Name of the Oban maintenance loop that raised. Allowed value: `pruner`. | | `event` | string | The underlying Oban telemetry event name. Allowed values: `oban.pruner.prune.exception`. | | `error_type` | string | Exception class name. | | `error_message` | string | Exception message. | | `duration` | number | Duration of the failed loop iteration in milliseconds. | Example ```json { "event_type": "oban.pruner_exception", "loop": "pruner", "event": "oban.pruner.prune.exception", "error_type": "OperationalError", "error_message": "connection to server was lost", "duration": 3.1415 } ``` ### oban.refresher\_exception[](/insights/event-types/python/oban.refresher_exception/ "View event details")[](/insights/event-types/python/oban.refresher_exception.schema.json "View JSON Schema") Oban's refresher loop, which refreshes producer records and cleans up stale ones, raised an exception. | Field | Type | Description | | --------------- | ------ | --------------------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `oban.refresher_exception`. | | `loop` | string | Name of the Oban maintenance loop that raised. Allowed value: `refresher`. | | `event` | string | The underlying Oban telemetry event name. Allowed values: `oban.refresher.refresh.exception`, `oban.refresher.cleanup.exception`. | | `error_type` | string | Exception class name. | | `error_message` | string | Exception message. | | `duration` | number | Duration of the failed loop iteration in milliseconds. | Example ```json { "event_type": "oban.refresher_exception", "loop": "refresher", "event": "oban.refresher.refresh.exception", "error_type": "OperationalError", "error_message": "connection to server was lost", "duration": 3.1415 } ``` ### oban.scheduler\_exception[](/insights/event-types/python/oban.scheduler_exception/ "View event details")[](/insights/event-types/python/oban.scheduler_exception.schema.json "View JSON Schema") Oban's cron scheduler loop raised an exception while evaluating schedules. | Field | Type | Description | | --------------- | ------ | ---------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `oban.scheduler_exception`. | | `loop` | string | Name of the Oban maintenance loop that raised. Allowed value: `scheduler`. | | `event` | string | The underlying Oban telemetry event name. Allowed values: `oban.scheduler.evaluate.exception`. | | `error_type` | string | Exception class name. | | `error_message` | string | Exception message. | | `duration` | number | Duration of the failed loop iteration in milliseconds. | Example ```json { "event_type": "oban.scheduler_exception", "loop": "scheduler", "event": "oban.scheduler.evaluate.exception", "error_type": "OperationalError", "error_message": "connection to server was lost", "duration": 3.1415 } ``` ### oban.stager\_exception[](/insights/event-types/python/oban.stager_exception/ "View event details")[](/insights/event-types/python/oban.stager_exception.schema.json "View JSON Schema") Oban's stager loop, which moves scheduled jobs to available, raised an exception. | Field | Type | Description | | --------------- | ------ | ---------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `oban.stager_exception`. | | `loop` | string | Name of the Oban maintenance loop that raised. Allowed value: `stager`. | | `event` | string | The underlying Oban telemetry event name. Allowed values: `oban.stager.stage.exception`. | | `error_type` | string | Exception class name. | | `error_message` | string | Exception message. | | `duration` | number | Duration of the failed loop iteration in milliseconds. | Example ```json { "event_type": "oban.stager_exception", "loop": "stager", "event": "oban.stager.stage.exception", "error_type": "OperationalError", "error_message": "connection to server was lost", "duration": 3.1415 } ``` # asgi.request > An ASGI app finished handling an HTTP request. Used by FastAPI, Starlette, and similar frameworks. An ASGI app finished handling an HTTP request. Used by FastAPI, Starlette, and similar frameworks. Source **ASGI** Category **Request** Fields **8** [honeybadger-python](/lib/python/) ## Fields 8 | Field | Type | Description | | ------------ | ------- | --------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `asgi.request`. | | `path` | string | Request path from the ASGI scope. | | `method` | string | HTTP method, e.g. "GET", "POST". | | `status` | integer | HTTP response status code. | | `duration` | number | Request duration in milliseconds. | | `params` | object | Parsed query string params. Only present when include\_params is enabled in insights\_config. | | `params.*` | any | Additional caller-defined keys. | | `request_id` | string | Request ID from event context, if set. | ## Example ```json { "event_type": "asgi.request", "path": "/users/123", "method": "GET", "status": 200, "duration": 23.4567, "params": { "page": "2", "sort": "name" }, "request_id": "1f9f6f1a-2b3c-4d5e-8f6a-7b8c9d0e1f2a" } ``` # celery.task_finished > A Celery task finished, whether it succeeded or failed. A Celery task finished, whether it succeeded or failed. Source **Celery** Category **Jobs** Fields **11** [honeybadger-python](/lib/python/) ## Fields 11 | Field | Type | Description | | ------------ | ----------- | -------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `celery.task_finished`. | | `task_id` | string | Celery task UUID. | | `task_name` | string | Fully qualified task name, e.g. "myapp.tasks.send\_email". | | `state` | string | Final task state, e.g. "SUCCESS", "FAILURE", "RETRY". | | `retries` | integer | Number of retries so far. | | `group` | string | Celery group ID if the task is part of a group. | | `duration` | number | Task execution duration in milliseconds. | | `args` | array\ | Positional task arguments. Only present when include\_args is enabled in insights\_config. | | `kwargs` | object | Keyword task arguments (filtered). Only present when include\_args is enabled in insights\_config. | | `kwargs.*` | any | Additional caller-defined keys. | | `request_id` | string | Request ID propagated from the originating request via Celery task headers. | ## Example ```json { "event_type": "celery.task_finished", "task_id": "9c5e8a2f-1b3d-4c6e-9f7a-2d4b6c8e0a1f", "task_name": "myapp.tasks.send_email", "state": "SUCCESS", "retries": 0, "group": "5a7d3e9b-8c1f-4b2a-9d6e-3f5a7c9e1b4d", "duration": 845.2103, "args": [ "user@example.com" ], "kwargs": { "subject": "Welcome to MyApp" }, "request_id": "1f9f6f1a-2b3c-4d5e-8f6a-7b8c9d0e1f2a" } ``` # db.query > A database query from the Django ORM or SQLAlchemy. Honeybadger skips queries that match exclude_queries. A database query from the Django ORM or SQLAlchemy. Honeybadger skips queries that match exclude\_queries. Category **Database** Fields **5** [honeybadger-python](/lib/python/) ## Fields 5 | Field | Type | Description | | ------------ | ------ | ----------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `db.query`. | | `query` | string | SQL query string. Bind parameters may appear as literals, depending on the driver. | | `duration` | number | Query execution duration in milliseconds. | | `params` | any | Query parameters. Only present when include\_params is enabled in insights\_config. | | `request_id` | string | Request ID from event context, ties this query to the enclosing request. | ## Example ```json { "event_type": "db.query", "query": "SELECT \"users\".* FROM \"users\" WHERE \"users\".\"id\" = %s LIMIT 1", "duration": 2.4815, "params": [ 123 ], "request_id": "1f9f6f1a-2b3c-4d5e-8f6a-7b8c9d0e1f2a" } ``` # django.request > A Django view finished handling an HTTP request. A Django view finished handling an HTTP request. Source **Django** Category **Request** Fields **11** [honeybadger-python](/lib/python/) ## Fields 11 | Field | Type | Description | | ------------ | ------- | ---------------------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `django.request`. | | `path` | string | Request path, e.g. "/users/42". | | `method` | string | HTTP method, e.g. "GET", "POST". | | `status` | integer | HTTP response status code. | | `view` | string | Resolved view function name. | | `module` | string | Module containing the view function. | | `app` | string | Django app name from the URL resolver. | | `duration` | number | Request duration in milliseconds. | | `params` | object | GET and POST params. Only present when include\_params is enabled in insights\_config. | | `params.*` | any | Additional caller-defined keys. | | `request_id` | string | Request ID from X-Request-ID header, request.id/request\_id attribute, or a generated UUID. Set in event context at request start. | ## Example ```json { "event_type": "django.request", "path": "/users/123", "method": "GET", "status": 200, "view": "user_detail", "module": "myapp.views", "app": "users", "duration": 58.3214, "params": { "page": "2", "sort": "name" }, "request_id": "1f9f6f1a-2b3c-4d5e-8f6a-7b8c9d0e1f2a" } ``` # flask.request > A Flask route finished handling an HTTP request. A Flask route finished handling an HTTP request. Source **Flask** Category **Request** Fields **10** [honeybadger-python](/lib/python/) ## Fields 10 | Field | Type | Description | | ------------ | ------- | ----------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `flask.request`. | | `path` | string | Request path, e.g. "/users/42". | | `method` | string | HTTP method, e.g. "GET", "POST". | | `status` | integer | HTTP response status code. | | `view` | string | Flask endpoint name (request.endpoint). | | `blueprint` | string | Flask blueprint name, if the route belongs to one. | | `duration` | number | Request duration in milliseconds. | | `params` | object | Query and form params. Only present when include\_params is enabled in insights\_config. | | `params.*` | any | Additional caller-defined keys. | | `request_id` | string | Request ID from X-Request-ID header or a generated UUID. Set in event context at request start. | ## Example ```json { "event_type": "flask.request", "path": "/users/123", "method": "GET", "status": 200, "view": "users.show", "blueprint": "users", "duration": 32.1875, "params": { "page": "2", "sort": "name" }, "request_id": "1f9f6f1a-2b3c-4d5e-8f6a-7b8c9d0e1f2a" } ``` # oban.job_finished > An Oban job finished, whether it succeeded or failed. Emitted for both oban.job.stop and oban.job.exception telemetry events. An Oban job finished, whether it succeeded or failed. Emitted for both oban.job.stop and oban.job.exception telemetry events. Source **Oban** Category **Jobs** Fields **17** [honeybadger-python](/lib/python/) ## Fields 17 | Field | Type | Description | | --------------- | -------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `oban.job_finished`. | | `job_id` | integer | Oban job database ID. | | `worker` | string | Fully qualified worker name ("module.Class"). | | `queue` | string | Queue the job ran on. | | `state` | string | Resulting job state: "completed", "retryable", "discarded", "cancelled", or "scheduled" (snoozed). Failures are "retryable" until max\_attempts is exhausted, then "discarded". | | `attempt` | integer | Attempt number (1-based). | | `max_attempts` | integer | Maximum number of attempts before the job is discarded. | | `duration` | number | Job execution duration in milliseconds. | | `queue_time` | number | Time the job spent waiting in the queue (scheduled\_at to attempted\_at) in milliseconds. | | `tags` | array\ | Tags assigned to the job. | | `error_type` | string | Exception class name. Only present when the job failed (state "retryable" or "discarded"). | | `error_message` | string | Exception message. Only present when the job failed (state "retryable" or "discarded"). | | `args` | object | Job arguments (filtered). Only present when include\_args is enabled in insights\_config. | | `args.*` | any | Additional caller-defined keys. | | `meta` | object | Job metadata (filtered). Only present when include\_args is enabled in insights\_config. | | `meta.*` | any | Additional caller-defined keys. | | `request_id` | string | Request ID propagated from the originating request's event context via Oban job metadata. | ## Example ```json { "event_type": "oban.job_finished", "job_id": 123456, "worker": "myapp.workers.WelcomeEmail", "queue": "default", "state": "completed", "attempt": 1, "max_attempts": 20, "duration": 845.2103, "queue_time": 12.5, "tags": [ "mailer" ], "error_type": "ValueError", "error_message": "invalid user id", "args": { "user_id": 42 }, "meta": { "source": "signup" }, "request_id": "1f9f6f1a-2b3c-4d5e-8f6a-7b8c9d0e1f2a" } ``` # oban.leader_exception > Oban's leader election loop raised an exception. Oban’s leader election loop raised an exception. Source **Oban** Category **Jobs** Fields **6** [honeybadger-python](/lib/python/) ## Fields 6 | Field | Type | Description | | --------------- | ------ | ------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `oban.leader_exception`. | | `loop` | string | Name of the Oban maintenance loop that raised. Allowed value: `leader`. | | `event` | string | The underlying Oban telemetry event name. Allowed values: `oban.leader.election.exception`. | | `error_type` | string | Exception class name. | | `error_message` | string | Exception message. | | `duration` | number | Duration of the failed loop iteration in milliseconds. | ## Example ```json { "event_type": "oban.leader_exception", "loop": "leader", "event": "oban.leader.election.exception", "error_type": "OperationalError", "error_message": "connection to server was lost", "duration": 3.1415 } ``` # oban.lifeline_exception > Oban's lifeline loop, which rescues orphaned executing jobs, raised an exception. Oban’s lifeline loop, which rescues orphaned executing jobs, raised an exception. Source **Oban** Category **Jobs** Fields **6** [honeybadger-python](/lib/python/) ## Fields 6 | Field | Type | Description | | --------------- | ------ | ------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `oban.lifeline_exception`. | | `loop` | string | Name of the Oban maintenance loop that raised. Allowed value: `lifeline`. | | `event` | string | The underlying Oban telemetry event name. Allowed values: `oban.lifeline.rescue.exception`. | | `error_type` | string | Exception class name. | | `error_message` | string | Exception message. | | `duration` | number | Duration of the failed loop iteration in milliseconds. | ## Example ```json { "event_type": "oban.lifeline_exception", "loop": "lifeline", "event": "oban.lifeline.rescue.exception", "error_type": "OperationalError", "error_message": "connection to server was lost", "duration": 3.1415 } ``` # oban.producer_exception > An Oban queue producer raised an exception while fetching or acking jobs. An Oban queue producer raised an exception while fetching or acking jobs. Source **Oban** Category **Jobs** Fields **6** [honeybadger-python](/lib/python/) ## Fields 6 | Field | Type | Description | | --------------- | ------ | ----------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `oban.producer_exception`. | | `loop` | string | Name of the Oban maintenance loop that raised. Allowed value: `producer`. | | `event` | string | The underlying Oban telemetry event name. Allowed values: `oban.producer.get.exception`, `oban.producer.ack.exception`. | | `error_type` | string | Exception class name. | | `error_message` | string | Exception message. | | `duration` | number | Duration of the failed loop iteration in milliseconds. | ## Example ```json { "event_type": "oban.producer_exception", "loop": "producer", "event": "oban.producer.get.exception", "error_type": "OperationalError", "error_message": "connection to server was lost", "duration": 3.1415 } ``` # oban.pruner_exception > Oban's pruner loop, which deletes old completed jobs, raised an exception. Oban’s pruner loop, which deletes old completed jobs, raised an exception. Source **Oban** Category **Jobs** Fields **6** [honeybadger-python](/lib/python/) ## Fields 6 | Field | Type | Description | | --------------- | ------ | ---------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `oban.pruner_exception`. | | `loop` | string | Name of the Oban maintenance loop that raised. Allowed value: `pruner`. | | `event` | string | The underlying Oban telemetry event name. Allowed values: `oban.pruner.prune.exception`. | | `error_type` | string | Exception class name. | | `error_message` | string | Exception message. | | `duration` | number | Duration of the failed loop iteration in milliseconds. | ## Example ```json { "event_type": "oban.pruner_exception", "loop": "pruner", "event": "oban.pruner.prune.exception", "error_type": "OperationalError", "error_message": "connection to server was lost", "duration": 3.1415 } ``` # oban.refresher_exception > Oban's refresher loop, which refreshes producer records and cleans up stale ones, raised an exception. Oban’s refresher loop, which refreshes producer records and cleans up stale ones, raised an exception. Source **Oban** Category **Jobs** Fields **6** [honeybadger-python](/lib/python/) ## Fields 6 | Field | Type | Description | | --------------- | ------ | --------------------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `oban.refresher_exception`. | | `loop` | string | Name of the Oban maintenance loop that raised. Allowed value: `refresher`. | | `event` | string | The underlying Oban telemetry event name. Allowed values: `oban.refresher.refresh.exception`, `oban.refresher.cleanup.exception`. | | `error_type` | string | Exception class name. | | `error_message` | string | Exception message. | | `duration` | number | Duration of the failed loop iteration in milliseconds. | ## Example ```json { "event_type": "oban.refresher_exception", "loop": "refresher", "event": "oban.refresher.refresh.exception", "error_type": "OperationalError", "error_message": "connection to server was lost", "duration": 3.1415 } ``` # oban.scheduler_exception > Oban's cron scheduler loop raised an exception while evaluating schedules. Oban’s cron scheduler loop raised an exception while evaluating schedules. Source **Oban** Category **Jobs** Fields **6** [honeybadger-python](/lib/python/) ## Fields 6 | Field | Type | Description | | --------------- | ------ | ---------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `oban.scheduler_exception`. | | `loop` | string | Name of the Oban maintenance loop that raised. Allowed value: `scheduler`. | | `event` | string | The underlying Oban telemetry event name. Allowed values: `oban.scheduler.evaluate.exception`. | | `error_type` | string | Exception class name. | | `error_message` | string | Exception message. | | `duration` | number | Duration of the failed loop iteration in milliseconds. | ## Example ```json { "event_type": "oban.scheduler_exception", "loop": "scheduler", "event": "oban.scheduler.evaluate.exception", "error_type": "OperationalError", "error_message": "connection to server was lost", "duration": 3.1415 } ``` # oban.stager_exception > Oban's stager loop, which moves scheduled jobs to available, raised an exception. Oban’s stager loop, which moves scheduled jobs to available, raised an exception. Source **Oban** Category **Jobs** Fields **6** [honeybadger-python](/lib/python/) ## Fields 6 | Field | Type | Description | | --------------- | ------ | ---------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `oban.stager_exception`. | | `loop` | string | Name of the Oban maintenance loop that raised. Allowed value: `stager`. | | `event` | string | The underlying Oban telemetry event name. Allowed values: `oban.stager.stage.exception`. | | `error_type` | string | Exception class name. | | `error_message` | string | Exception message. | | `duration` | number | Duration of the failed loop iteration in milliseconds. | ## Example ```json { "event_type": "oban.stager_exception", "loop": "stager", "event": "oban.stager.stage.exception", "error_type": "OperationalError", "error_message": "connection to server was lost", "duration": 3.1415 } ``` # Ruby event reference > Insights event types emitted by Ruby. Every event the Honeybadger Ruby gem sends to Insights when instrumentation is enabled: Rails requests, database queries, view renders, and cache operations; Active Job, Sidekiq, SolidQueue, and Karafka job processing; Net::HTTP requests; Puma, system, and GC stats; and ActiveAgent LLM instrumentation. Each entry lists the event's fields with their types, and links to its raw JSON Schema. **56** events emitted by [`honeybadger-ruby`](/lib/ruby/). *** ## Action Controller ### exist\_fragment?.action\_controller[](/insights/event-types/ruby/exist_fragment_predicate.action_controller/ "View event details")[](/insights/event-types/ruby/exist_fragment_predicate.action_controller.schema.json "View JSON Schema") A Rails fragment cache existence check. | Field | Type | Description | | ----------------- | ------ | ---------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `exist_fragment?.action_controller`. | | `key` | string | Fragment cache key. | | `duration` | number | Duration in milliseconds. | | `instrumenter_id` | string | | | `request_id` | string | Rails request UUID, present on any event fired during a web request context. Merged globally by the Honeybadger agent. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | Example ```json { "event_type": "exist_fragment?.action_controller", "key": "views/users/123-20260612143000000000/a1b2c3d4e5f6", "duration": 0.31, "instrumenter_id": "d6a5b3f4c2e1908a7b6c", "request_id": "0f5e4bb2-3c46-4b1c-91d5-2f4e8a6b9c01", "hostname": "web-1.example.com", "environment": "production" } ``` ### expire\_fragment.action\_controller[](/insights/event-types/ruby/expire_fragment.action_controller/ "View event details")[](/insights/event-types/ruby/expire_fragment.action_controller.schema.json "View JSON Schema") A Rails fragment cache expire call. | Field | Type | Description | | ----------------- | ------ | ---------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `expire_fragment.action_controller`. | | `key` | string | Fragment cache key. | | `duration` | number | Duration in milliseconds. | | `instrumenter_id` | string | | | `request_id` | string | Rails request UUID, present on any event fired during a web request context. Merged globally by the Honeybadger agent. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | Example ```json { "event_type": "expire_fragment.action_controller", "key": "views/users/123-20260612143000000000/a1b2c3d4e5f6", "duration": 0.52, "instrumenter_id": "d6a5b3f4c2e1908a7b6c", "request_id": "0f5e4bb2-3c46-4b1c-91d5-2f4e8a6b9c01", "hostname": "web-1.example.com", "environment": "production" } ``` ### halted\_callback.action\_controller[](/insights/event-types/ruby/halted_callback.action_controller/ "View event details")[](/insights/event-types/ruby/halted_callback.action_controller.schema.json "View JSON Schema") A before/around filter halted the Rails request processing chain. | Field | Type | Description | | ----------------- | ------ | ---------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `halted_callback.action_controller`. | | `filter` | string | Name of the filter/callback that halted the chain. | | `duration` | number | Duration in milliseconds. | | `instrumenter_id` | string | Rails instrumenter UUID. | | `request_id` | string | Rails request UUID, present on any event fired during a web request context. Merged globally by the Honeybadger agent. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | Example ```json { "event_type": "halted_callback.action_controller", "filter": "require_login", "duration": 2.15, "instrumenter_id": "d6a5b3f4c2e1908a7b6c", "request_id": "0f5e4bb2-3c46-4b1c-91d5-2f4e8a6b9c01", "hostname": "web-1.example.com", "environment": "production" } ``` ### process\_action.action\_controller[](/insights/event-types/ruby/process_action.action_controller/ "View event details")[](/insights/event-types/ruby/process_action.action_controller.schema.json "View JSON Schema") A Rails controller action finished handling an HTTP request. Includes total duration, database time, view time, route details, and response status. | Field | Type | Description | | ----------------- | ------- | -------------------------------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `process_action.action_controller`. | | `controller` | string | Controller class name, e.g. "SearchController". | | `action` | string | Action method on the controller, e.g. "index", "destroy". | | `method` | string | HTTP method, e.g. "GET", "POST", "PUT". | | `path` | string | Request path, e.g. "/follows". Often high-cardinality due to ids. | | `format` | string | Response format, e.g. "html", "json". | | `status` | integer | HTTP status code returned to the client. | | `duration` | number | Total wall-clock time the action took, in milliseconds. Includes db\_runtime and view\_runtime. | | `db_runtime` | number | Milliseconds spent in DB queries during this action. | | `view_runtime` | number | Milliseconds spent rendering views during this action. | | `request_id` | string | Rails request UUID. Also appears on sql.active\_record, render\_\*.action\_view, and cache\_\*.active\_support events from the same request. | | `instrumenter_id` | string | Unique identifier for the ActiveSupport::Notifications instrumentation request, assigned by Rails. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | Example ```json { "event_type": "process_action.action_controller", "controller": "UsersController", "action": "show", "method": "GET", "path": "/users/123", "format": "html", "status": 200, "duration": 145.2, "db_runtime": 38.7, "view_runtime": 52.4, "request_id": "0f5e4bb2-3c46-4b1c-91d5-2f4e8a6b9c01", "instrumenter_id": "d6a5b3f4c2e1908a7b6c", "hostname": "web-1.example.com", "environment": "production" } ``` ### read\_fragment.action\_controller[](/insights/event-types/ruby/read_fragment.action_controller/ "View event details")[](/insights/event-types/ruby/read_fragment.action_controller.schema.json "View JSON Schema") A Rails fragment cache read. | Field | Type | Description | | ----------------- | ------ | ---------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `read_fragment.action_controller`. | | `key` | string | Fragment cache key. | | `duration` | number | Duration in milliseconds. | | `instrumenter_id` | string | | | `request_id` | string | Rails request UUID, present on any event fired during a web request context. Merged globally by the Honeybadger agent. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | Example ```json { "event_type": "read_fragment.action_controller", "key": "views/users/123-20260612143000000000/a1b2c3d4e5f6", "duration": 0.45, "instrumenter_id": "d6a5b3f4c2e1908a7b6c", "request_id": "0f5e4bb2-3c46-4b1c-91d5-2f4e8a6b9c01", "hostname": "web-1.example.com", "environment": "production" } ``` ### redirect\_to.action\_controller[](/insights/event-types/ruby/redirect_to.action_controller/ "View event details")[](/insights/event-types/ruby/redirect_to.action_controller.schema.json "View JSON Schema") A Rails controller issued a redirect. | Field | Type | Description | | ----------------- | ------- | ---------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `redirect_to.action_controller`. | | `status` | integer | HTTP redirect status code, e.g. 301, 302. | | `location` | string | URL the client is redirected to. | | `duration` | number | Duration in milliseconds. | | `instrumenter_id` | string | Rails instrumenter UUID. | | `request_id` | string | Rails request UUID, present on any event fired during a web request context. Merged globally by the Honeybadger agent. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | Example ```json { "event_type": "redirect_to.action_controller", "status": 302, "location": "https://app.example.com/users/123", "duration": 0.85, "instrumenter_id": "d6a5b3f4c2e1908a7b6c", "request_id": "0f5e4bb2-3c46-4b1c-91d5-2f4e8a6b9c01", "hostname": "web-1.example.com", "environment": "production" } ``` ### send\_file.action\_controller[](/insights/event-types/ruby/send_file.action_controller/ "View event details")[](/insights/event-types/ruby/send_file.action_controller.schema.json "View JSON Schema") A Rails controller started sending a file. | Field | Type | Description | | ----------------- | ------ | ---------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `send_file.action_controller`. | | `path` | string | Filesystem path of the file being sent. | | `duration` | number | Duration in milliseconds. | | `instrumenter_id` | string | Rails instrumenter UUID. | | `request_id` | string | Rails request UUID, present on any event fired during a web request context. Merged globally by the Honeybadger agent. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | Example ```json { "event_type": "send_file.action_controller", "path": "/app/storage/exports/report-2026-06.pdf", "duration": 3.42, "instrumenter_id": "d6a5b3f4c2e1908a7b6c", "request_id": "0f5e4bb2-3c46-4b1c-91d5-2f4e8a6b9c01", "hostname": "web-1.example.com", "environment": "production" } ``` ### unpermitted\_parameters.action\_controller[](/insights/event-types/ruby/unpermitted_parameters.action_controller/ "View event details")[](/insights/event-types/ruby/unpermitted_parameters.action_controller.schema.json "View JSON Schema") Rails strong parameters filtered out unpermitted keys. | Field | Type | Description | | -------------------- | -------------- | ---------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `unpermitted_parameters.action_controller`. | | `keys` | array\ | Parameter keys that were not permitted. | | `context` | object | Request context at the time of the violation. | | `context.controller` | string | | | `context.action` | string | | | `context.request` | object | | | `duration` | number | Duration in milliseconds. | | `instrumenter_id` | string | Rails instrumenter UUID. | | `request_id` | string | Rails request UUID, present on any event fired during a web request context. Merged globally by the Honeybadger agent. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | Example ```json { "event_type": "unpermitted_parameters.action_controller", "keys": [ "admin", "role" ], "context": { "controller": "UsersController", "action": "update", "request": { "method": "PATCH", "path": "/users/123" } }, "duration": 0.12, "instrumenter_id": "d6a5b3f4c2e1908a7b6c", "request_id": "0f5e4bb2-3c46-4b1c-91d5-2f4e8a6b9c01", "hostname": "web-1.example.com", "environment": "production" } ``` ### write\_fragment.action\_controller[](/insights/event-types/ruby/write_fragment.action_controller/ "View event details")[](/insights/event-types/ruby/write_fragment.action_controller.schema.json "View JSON Schema") A Rails fragment cache write. | Field | Type | Description | | ----------------- | ------ | ---------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `write_fragment.action_controller`. | | `key` | string | Fragment cache key. | | `duration` | number | Duration in milliseconds. | | `instrumenter_id` | string | | | `request_id` | string | Rails request UUID, present on any event fired during a web request context. Merged globally by the Honeybadger agent. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | Example ```json { "event_type": "write_fragment.action_controller", "key": "views/users/123-20260612143000000000/a1b2c3d4e5f6", "duration": 0.62, "instrumenter_id": "d6a5b3f4c2e1908a7b6c", "request_id": "0f5e4bb2-3c46-4b1c-91d5-2f4e8a6b9c01", "hostname": "web-1.example.com", "environment": "production" } ``` ## Action Mailer ### process.action\_mailer[](/insights/event-types/ruby/process.action_mailer/ "View event details")[](/insights/event-types/ruby/process.action_mailer.schema.json "View JSON Schema") Rails generated an Action Mailer message. | Field | Type | Description | | ---------------------- | -------------- | ---------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `process.action_mailer`. | | `mailer` | string | Mailer class name, e.g. "UserMailer". | | `action` | string | Mailer action method, e.g. "welcome\_email". | | `message_id` | string | Message-ID header of the generated email. | | `subject` | string | Email subject line. | | `to` | array\ | Recipient addresses. | | `cc` | array\ | CC addresses. | | `bcc` | array\ | BCC addresses. | | `date` | string | Email date header as a string. | | `attachments` | array\ | File attachments included in the email. | | `attachments.filename` | string | | | `params` | object | Params passed to the mailer action. | | `params.*` | any | Additional caller-defined keys. | | `duration` | number | Duration in milliseconds. | | `instrumenter_id` | string | Rails instrumenter UUID. | | `request_id` | string | Rails request UUID, present on any event fired during a web request context. Merged globally by the Honeybadger agent. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | Example ```json { "event_type": "process.action_mailer", "mailer": "UserMailer", "action": "welcome_email", "message_id": "684af2d1c3b4a_1a2b3c4d5e6f@web-1.example.com.mail", "subject": "Welcome to Example App", "to": [ "user@example.com" ], "cc": [ "support@example.com" ], "bcc": [ "audit@example.com" ], "date": "Fri, 12 Jun 2026 14:30:00 +0000", "attachments": [ { "filename": "welcome-guide.pdf" } ], "params": { "user_id": 123 }, "duration": 84.21, "instrumenter_id": "d6a5b3f4c2e1908a7b6c", "request_id": "0f5e4bb2-3c46-4b1c-91d5-2f4e8a6b9c01", "hostname": "web-1.example.com", "environment": "production" } ``` ## Action View ### render\_collection.action\_view[](/insights/event-types/ruby/render_collection.action_view/ "View event details")[](/insights/event-types/ruby/render_collection.action_view.schema.json "View JSON Schema") A Rails view render. This shape is shared by template, partial, and collection render events. A typical request has one template render and several partial renders. | Field | Type | Description | | ----------------- | -------------- | ------------------------------------------------------------------------------------------------------------ | | `event_type` | string | Allowed value: `render_collection.action_view`. | | `view` | string | Path of the template file, e.g. "\[PROJECT\_ROOT]/app/views/users/show\.html.erb". | | `layout` | string \| null | Layout the template was rendered into, e.g. "application". Null when the render skipped layouts. | | `duration` | number | Render duration in milliseconds. | | `request_id` | string | Rails request UUID. Shared by all events from the same HTTP request. | | `instrumenter_id` | string | Unique identifier for the ActiveSupport::Notifications instrumentation request, assigned by Rails. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | Example ```json { "event_type": "render_collection.action_view", "view": "[PROJECT_ROOT]/app/views/comments/_comment.html.erb", "layout": null, "duration": 6.4, "request_id": "0f5e4bb2-3c46-4b1c-91d5-2f4e8a6b9c01", "instrumenter_id": "d6a5b3f4c2e1908a7b6c", "hostname": "web-1.example.com", "environment": "production" } ``` ### render\_partial.action\_view[](/insights/event-types/ruby/render_partial.action_view/ "View event details")[](/insights/event-types/ruby/render_partial.action_view.schema.json "View JSON Schema") A Rails view render. This shape is shared by template, partial, and collection render events. A typical request has one template render and several partial renders. | Field | Type | Description | | ----------------- | -------------- | ------------------------------------------------------------------------------------------------------------ | | `event_type` | string | Allowed value: `render_partial.action_view`. | | `view` | string | Path of the template file, e.g. "\[PROJECT\_ROOT]/app/views/users/show\.html.erb". | | `layout` | string \| null | Layout the template was rendered into, e.g. "application". Null when the render skipped layouts. | | `duration` | number | Render duration in milliseconds. | | `request_id` | string | Rails request UUID. Shared by all events from the same HTTP request. | | `instrumenter_id` | string | Unique identifier for the ActiveSupport::Notifications instrumentation request, assigned by Rails. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | Example ```json { "event_type": "render_partial.action_view", "view": "[PROJECT_ROOT]/app/views/users/_user.html.erb", "layout": null, "duration": 1.8, "request_id": "0f5e4bb2-3c46-4b1c-91d5-2f4e8a6b9c01", "instrumenter_id": "d6a5b3f4c2e1908a7b6c", "hostname": "web-1.example.com", "environment": "production" } ``` ### render\_template.action\_view[](/insights/event-types/ruby/render_template.action_view/ "View event details")[](/insights/event-types/ruby/render_template.action_view.schema.json "View JSON Schema") A Rails view render. This shape is shared by template, partial, and collection render events. A typical request has one template render and several partial renders. | Field | Type | Description | | ----------------- | -------------- | ------------------------------------------------------------------------------------------------------------ | | `event_type` | string | Allowed value: `render_template.action_view`. | | `view` | string | Path of the template file, e.g. "\[PROJECT\_ROOT]/app/views/users/show\.html.erb". | | `layout` | string \| null | Layout the template was rendered into, e.g. "application". Null when the render skipped layouts. | | `duration` | number | Render duration in milliseconds. | | `request_id` | string | Rails request UUID. Shared by all events from the same HTTP request. | | `instrumenter_id` | string | Unique identifier for the ActiveSupport::Notifications instrumentation request, assigned by Rails. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | Example ```json { "event_type": "render_template.action_view", "view": "[PROJECT_ROOT]/app/views/users/show.html.erb", "layout": "layouts/application", "duration": 24.6, "request_id": "0f5e4bb2-3c46-4b1c-91d5-2f4e8a6b9c01", "instrumenter_id": "d6a5b3f4c2e1908a7b6c", "hostname": "web-1.example.com", "environment": "production" } ``` ## Active Agent ### embed.active\_agent[](/insights/event-types/ruby/embed.active_agent/ "View event details")[](/insights/event-types/ruby/embed.active_agent.schema.json "View JSON Schema") An embedding request made through ActiveAgent. | Field | Type | Description | | -------------------- | ------- | ---------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `embed.active_agent`. | | `provider` | string | Model provider name. | | `provider_module` | string | ActiveAgent provider module class name. | | `model` | string | Embedding model identifier. | | `trace_id` | string | Trace ID for correlating events within a single agent run. | | `input_size` | integer | Number of input strings submitted for embedding. | | `embedding_count` | integer | Number of embedding vectors returned. | | `encoding_format` | string | Encoding format requested, e.g. "float". | | `dimensions` | integer | Embedding vector dimensions. | | `response_model` | string | Model identifier as returned by the provider. | | `response_id` | string | Provider-assigned response ID. | | `usage` | object | Token usage reported by the provider. | | `usage.input_tokens` | integer | | | `usage.total_tokens` | integer | | | `duration` | number | Duration in milliseconds. | | `instrumenter_id` | string | Rails instrumenter UUID. | | `request_id` | string | Rails request UUID, present on any event fired during a web request context. Merged globally by the Honeybadger agent. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | Example ```json { "event_type": "embed.active_agent", "provider": "OpenAI", "provider_module": "OpenAI::Embeddings", "model": "text-embedding-3-small", "trace_id": "9b4f2a6e-1c8d-4e7a-b3f5-6d2c9e0a4b18", "input_size": 3, "embedding_count": 3, "encoding_format": "float", "dimensions": 1536, "response_model": "text-embedding-3-small", "response_id": "embd-9f8e7d6c5b4a3210fedc", "usage": { "input_tokens": 42, "total_tokens": 42 }, "duration": 184.27, "instrumenter_id": "d9f4a7b2c1e8d3f6a0b5", "request_id": "0f5e4bb2-3c46-4b1c-91d5-2f4e8a6b9c01", "hostname": "web-1.example.com", "environment": "production" } ``` ### process.active\_agent[](/insights/event-types/ruby/process.active_agent/ "View event details")[](/insights/event-types/ruby/process.active_agent.schema.json "View JSON Schema") An ActiveAgent action ran. Honeybadger forwards the ActiveAgent payload as-is, so extra fields depend on your ActiveAgent version and provider. | Field | Type | Description | | ----------------- | ------ | ------------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `process.active_agent`. | | `trace_id` | string | Trace ID for correlating events within a single agent run. | | `provider` | string | Model provider name. | | `duration` | number | Duration in milliseconds. | | `instrumenter_id` | string | ActiveSupport::Notifications instrumenter UUID, added by the Honeybadger notification subscriber. | | `request_id` | string | Rails request UUID, present on any event fired during a web request context. Set by the Honeybadger agent when available. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | Example ```json { "event_type": "process.active_agent", "trace_id": "7c9e6679-7425-40de-944b-e07fc1f90ae7", "provider": "openai", "duration": 2310.47, "instrumenter_id": "d6a5b3f4c2e1908a7b6c", "request_id": "0f5e4bb2-3c46-4b1c-91d5-2f4e8a6b9c01", "hostname": "web-1.example.com", "environment": "production" } ``` ### prompt.active\_agent[](/insights/event-types/ruby/prompt.active_agent/ "View event details")[](/insights/event-types/ruby/prompt.active_agent.schema.json "View JSON Schema") A model prompt request made through ActiveAgent. | Field | Type | Description | | --------------------- | ------- | ------------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `prompt.active_agent`. | | `provider` | string | Model provider name, e.g. "openai", "anthropic". | | `provider_module` | string | ActiveAgent provider module class name. | | `model` | string | Model identifier, e.g. "gpt-4o", "claude-3-opus". | | `trace_id` | string | Trace ID for correlating events within a single agent run. | | `message_count` | integer | Number of messages in the prompt context. | | `stream` | boolean | Whether the response was streamed. | | `finish_reason` | string | Stop reason returned by the provider, e.g. "stop", "length". | | `response_model` | string | Model identifier as returned by the provider response. | | `response_id` | string | Provider-assigned response ID. | | `temperature` | number | Sampling temperature used. | | `max_tokens` | integer | Max tokens parameter. | | `top_p` | number | Top-p nucleus sampling parameter. | | `tool_count` | integer | Number of tools available to the model. | | `has_instructions` | boolean | Whether a system instructions block was included. | | `usage` | object | Token usage reported by the provider. | | `usage.input_tokens` | integer | | | `usage.output_tokens` | integer | | | `usage.total_tokens` | integer | | | `duration` | number | Duration in milliseconds. | | `instrumenter_id` | string | ActiveSupport::Notifications instrumenter UUID, added by the Honeybadger notification subscriber. | | `request_id` | string | Rails request UUID, present on any event fired during a web request context. Set by the Honeybadger agent when available. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | Example ```json { "event_type": "prompt.active_agent", "provider": "openai", "provider_module": "ActiveAgent::GenerationProvider::OpenAIProvider", "model": "gpt-4o", "trace_id": "7c9e6679-7425-40de-944b-e07fc1f90ae7", "message_count": 4, "stream": false, "finish_reason": "stop", "response_model": "gpt-4o-2024-08-06", "response_id": "chatcmpl-Bx7Qk2T9fJ3aV1mN5pR8sLwY", "temperature": 0.7, "max_tokens": 1024, "top_p": 1, "tool_count": 3, "has_instructions": true, "usage": { "input_tokens": 412, "output_tokens": 186, "total_tokens": 598 }, "duration": 1820.43, "instrumenter_id": "d6a5b3f4c2e1908a7b6c", "request_id": "0f5e4bb2-3c46-4b1c-91d5-2f4e8a6b9c01", "hostname": "web-1.example.com", "environment": "production" } ``` ### stream\_close.active\_agent[](/insights/event-types/ruby/stream_close.active_agent/ "View event details")[](/insights/event-types/ruby/stream_close.active_agent.schema.json "View JSON Schema") An ActiveAgent streaming response closed. Honeybadger forwards the ActiveAgent payload as-is, so extra fields depend on your ActiveAgent version and provider. | Field | Type | Description | | ----------------- | ------ | ------------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `stream_close.active_agent`. | | `trace_id` | string | Trace ID for correlating events within a single agent run. | | `provider` | string | Model provider name. | | `duration` | number | Duration in milliseconds. | | `instrumenter_id` | string | ActiveSupport::Notifications instrumenter UUID, added by the Honeybadger notification subscriber. | | `request_id` | string | Rails request UUID, present on any event fired during a web request context. Set by the Honeybadger agent when available. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | Example ```json { "event_type": "stream_close.active_agent", "trace_id": "7c9e6679-7425-40de-944b-e07fc1f90ae7", "provider": "openai", "duration": 1864.92, "instrumenter_id": "d6a5b3f4c2e1908a7b6c", "request_id": "0f5e4bb2-3c46-4b1c-91d5-2f4e8a6b9c01", "hostname": "web-1.example.com", "environment": "production" } ``` ### stream\_open.active\_agent[](/insights/event-types/ruby/stream_open.active_agent/ "View event details")[](/insights/event-types/ruby/stream_open.active_agent.schema.json "View JSON Schema") An ActiveAgent streaming response opened. Honeybadger forwards the ActiveAgent payload as-is, so extra fields depend on your ActiveAgent version and provider. | Field | Type | Description | | ----------------- | ------ | ------------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `stream_open.active_agent`. | | `trace_id` | string | Trace ID for correlating events within a single agent run. | | `provider` | string | Model provider name. | | `duration` | number | Duration in milliseconds. | | `instrumenter_id` | string | ActiveSupport::Notifications instrumenter UUID, added by the Honeybadger notification subscriber. | | `request_id` | string | Rails request UUID, present on any event fired during a web request context. Set by the Honeybadger agent when available. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | Example ```json { "event_type": "stream_open.active_agent", "trace_id": "7c9e6679-7425-40de-944b-e07fc1f90ae7", "provider": "openai", "duration": 412.78, "instrumenter_id": "d6a5b3f4c2e1908a7b6c", "request_id": "0f5e4bb2-3c46-4b1c-91d5-2f4e8a6b9c01", "hostname": "web-1.example.com", "environment": "production" } ``` ### tool\_call.active\_agent[](/insights/event-types/ruby/tool_call.active_agent/ "View event details")[](/insights/event-types/ruby/tool_call.active_agent.schema.json "View JSON Schema") An ActiveAgent tool call ran. Honeybadger forwards the ActiveAgent payload as-is, so extra fields depend on your ActiveAgent version and provider. | Field | Type | Description | | ----------------- | ------ | ------------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `tool_call.active_agent`. | | `trace_id` | string | Trace ID for correlating events within a single agent run. | | `provider` | string | Model provider name. | | `duration` | number | Duration in milliseconds. | | `instrumenter_id` | string | ActiveSupport::Notifications instrumenter UUID, added by the Honeybadger notification subscriber. | | `request_id` | string | Rails request UUID, present on any event fired during a web request context. Set by the Honeybadger agent when available. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | Example ```json { "event_type": "tool_call.active_agent", "trace_id": "7c9e6679-7425-40de-944b-e07fc1f90ae7", "provider": "openai", "duration": 35.61, "instrumenter_id": "d6a5b3f4c2e1908a7b6c", "request_id": "0f5e4bb2-3c46-4b1c-91d5-2f4e8a6b9c01", "hostname": "web-1.example.com", "environment": "production" } ``` ## Active Job ### discard.active\_job[](/insights/event-types/ruby/discard.active_job/ "View event details")[](/insights/event-types/ruby/discard.active_job.schema.json "View JSON Schema") An Active Job job was discarded. | Field | Type | Description | | ----------------- | ------ | ------------------------------------------------------------------------------------------------------------ | | `event_type` | string | Allowed value: `discard.active_job`. | | `job_class` | string | ActiveJob class name. | | `job_id` | string | Unique job identifier. | | `queue_name` | string | Queue the job is on. | | `adapter_class` | string | ActiveJob adapter class, e.g. "SidekiqAdapter". | | `duration` | number | Duration in milliseconds. | | `instrumenter_id` | string | Rails ActiveSupport::Notifications instrumenter UUID. | | `request_id` | string | Rails request UUID from the active web request context, if any. Merged globally by the Honeybadger agent. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | Example ```json { "event_type": "discard.active_job", "job_class": "WelcomeEmailJob", "job_id": "c6e1f6b2-8d4a-4f0e-9b7c-1a2d3e4f5a6b", "queue_name": "default", "adapter_class": "ActiveJob::QueueAdapters::SidekiqAdapter", "duration": 0.34, "instrumenter_id": "a3c8e1f5b7d2c4e9f0a6", "request_id": "3d9c2f81-6e5a-4f7b-9c0d-8a1b2c3d4e5f", "hostname": "worker-1.example.com", "environment": "production" } ``` ### enqueue\_all.active\_job[](/insights/event-types/ruby/enqueue_all.active_job/ "View event details")[](/insights/event-types/ruby/enqueue_all.active_job.schema.json "View JSON Schema") A batch of Active Job jobs was enqueued. | Field | Type | Description | | ----------------- | -------------- | ------------------------------------------------------------------------------------------------------------ | | `event_type` | string | Allowed value: `enqueue_all.active_job`. | | `adapter_class` | string | ActiveJob adapter class. | | `jobs` | array\ | Jobs included in the batch. | | `jobs.job_class` | string | | | `jobs.job_id` | string | | | `jobs.queue_name` | string | | | `duration` | number | Duration in milliseconds. | | `instrumenter_id` | string | Rails ActiveSupport::Notifications instrumenter UUID. | | `request_id` | string | Rails request UUID from the active web request context, if any. Merged globally by the Honeybadger agent. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | Example ```json { "event_type": "enqueue_all.active_job", "adapter_class": "ActiveJob::QueueAdapters::SidekiqAdapter", "jobs": [ { "job_class": "WelcomeEmailJob", "job_id": "c6e1f6b2-8d4a-4f0e-9b7c-1a2d3e4f5a6b", "queue_name": "default" }, { "job_class": "SyncCrmContactJob", "job_id": "8a2b4c6d-0e1f-4a3b-8c5d-7e9f1a2b3c4d", "queue_name": "default" } ], "duration": 3.86, "instrumenter_id": "d9f4a7b2c1e8d3f6a0b5", "request_id": "0f5e4bb2-3c46-4b1c-91d5-2f4e8a6b9c01", "hostname": "web-1.example.com", "environment": "production" } ``` ### enqueue\_at.active\_job[](/insights/event-types/ruby/enqueue_at.active_job/ "View event details")[](/insights/event-types/ruby/enqueue_at.active_job.schema.json "View JSON Schema") An Active Job job was scheduled to run later. | Field | Type | Description | | ----------------- | ------ | ------------------------------------------------------------------------------------------------------------ | | `event_type` | string | Allowed value: `enqueue_at.active_job`. | | `job_class` | string | ActiveJob class name. | | `job_id` | string | Unique job identifier. | | `queue_name` | string | Queue the job is on. | | `adapter_class` | string | ActiveJob adapter class, e.g. "SidekiqAdapter". | | `duration` | number | Duration in milliseconds. | | `instrumenter_id` | string | Rails ActiveSupport::Notifications instrumenter UUID. | | `request_id` | string | Rails request UUID from the active web request context, if any. Merged globally by the Honeybadger agent. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | Example ```json { "event_type": "enqueue_at.active_job", "job_class": "WeeklyDigestJob", "job_id": "5f7e9d1c-3b2a-4c8e-a6f0-9d8c7b6a5e4f", "queue_name": "low", "adapter_class": "ActiveJob::QueueAdapters::SidekiqAdapter", "duration": 2.11, "instrumenter_id": "d9f4a7b2c1e8d3f6a0b5", "request_id": "0f5e4bb2-3c46-4b1c-91d5-2f4e8a6b9c01", "hostname": "web-1.example.com", "environment": "production" } ``` ### enqueue\_retry.active\_job[](/insights/event-types/ruby/enqueue_retry.active_job/ "View event details")[](/insights/event-types/ruby/enqueue_retry.active_job.schema.json "View JSON Schema") An Active Job job was queued for retry. | Field | Type | Description | | ----------------- | ------ | ------------------------------------------------------------------------------------------------------------ | | `event_type` | string | Allowed value: `enqueue_retry.active_job`. | | `job_class` | string | ActiveJob class name. | | `job_id` | string | Unique job identifier. | | `queue_name` | string | Queue the job is on. | | `adapter_class` | string | ActiveJob adapter class, e.g. "SidekiqAdapter". | | `duration` | number | Duration in milliseconds. | | `instrumenter_id` | string | Rails ActiveSupport::Notifications instrumenter UUID. | | `request_id` | string | Rails request UUID from the active web request context, if any. Merged globally by the Honeybadger agent. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | Example ```json { "event_type": "enqueue_retry.active_job", "job_class": "WelcomeEmailJob", "job_id": "c6e1f6b2-8d4a-4f0e-9b7c-1a2d3e4f5a6b", "queue_name": "default", "adapter_class": "ActiveJob::QueueAdapters::SidekiqAdapter", "duration": 1.27, "instrumenter_id": "a3c8e1f5b7d2c4e9f0a6", "request_id": "3d9c2f81-6e5a-4f7b-9c0d-8a1b2c3d4e5f", "hostname": "worker-1.example.com", "environment": "production" } ``` ### enqueue.active\_job[](/insights/event-types/ruby/enqueue.active_job/ "View event details")[](/insights/event-types/ruby/enqueue.active_job.schema.json "View JSON Schema") An Active Job job was enqueued. | Field | Type | Description | | ----------------- | ------ | ------------------------------------------------------------------------------------------------------------ | | `event_type` | string | Allowed value: `enqueue.active_job`. | | `job_class` | string | ActiveJob class name. | | `job_id` | string | Unique job identifier. | | `queue_name` | string | Queue the job is on. | | `adapter_class` | string | ActiveJob adapter class, e.g. "SidekiqAdapter". | | `duration` | number | Duration in milliseconds. | | `instrumenter_id` | string | Rails ActiveSupport::Notifications instrumenter UUID. | | `request_id` | string | Rails request UUID from the active web request context, if any. Merged globally by the Honeybadger agent. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | Example ```json { "event_type": "enqueue.active_job", "job_class": "WelcomeEmailJob", "job_id": "c6e1f6b2-8d4a-4f0e-9b7c-1a2d3e4f5a6b", "queue_name": "default", "adapter_class": "ActiveJob::QueueAdapters::SidekiqAdapter", "duration": 1.94, "instrumenter_id": "d9f4a7b2c1e8d3f6a0b5", "request_id": "0f5e4bb2-3c46-4b1c-91d5-2f4e8a6b9c01", "hostname": "web-1.example.com", "environment": "production" } ``` ### perform.active\_job[](/insights/event-types/ruby/perform.active_job/ "View event details")[](/insights/event-types/ruby/perform.active_job.schema.json "View JSON Schema") An Active Job job ran, whether it succeeded or raised an exception. | Field | Type | Description | | ------------------ | ------ | -------------------------------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `perform.active_job`. | | `job_class` | string | ActiveJob class name. | | `job_id` | string | Unique job identifier. | | `queue_name` | string | Queue the job ran on. | | `adapter_class` | string | ActiveJob adapter class, e.g. "SidekiqAdapter". | | `status` | string | Job execution outcome: 'success' if completed without exception, 'failure' if an exception was raised. Allowed values: `success`, `failure`. | | `exception_object` | string | The exception instance if the job raised, absent on success. Serialized as a string in JSON format. | | `duration` | number | Duration in milliseconds. | | `instrumenter_id` | string | Rails ActiveSupport::Notifications instrumenter UUID. | | `request_id` | string | Rails request UUID from the active web request context, if any. Merged globally by the Honeybadger agent. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | Example ```json { "event_type": "perform.active_job", "job_class": "WelcomeEmailJob", "job_id": "b1d2e3f4-5a6b-4c7d-8e9f-0a1b2c3d4e5f", "queue_name": "default", "adapter_class": "ActiveJob::QueueAdapters::SidekiqAdapter", "status": "success", "duration": 532.18, "instrumenter_id": "d6a5b3f4c2e1908a7b6c", "request_id": "0f5e4bb2-3c46-4b1c-91d5-2f4e8a6b9c01", "hostname": "worker-1.example.com", "environment": "production" } ``` ### retry\_stopped.active\_job[](/insights/event-types/ruby/retry_stopped.active_job/ "View event details")[](/insights/event-types/ruby/retry_stopped.active_job.schema.json "View JSON Schema") An Active Job job stopped retrying after too many failed attempts. | Field | Type | Description | | ----------------- | ------ | ------------------------------------------------------------------------------------------------------------ | | `event_type` | string | Allowed value: `retry_stopped.active_job`. | | `job_class` | string | ActiveJob class name. | | `job_id` | string | Unique job identifier. | | `queue_name` | string | Queue the job is on. | | `adapter_class` | string | ActiveJob adapter class, e.g. "SidekiqAdapter". | | `duration` | number | Duration in milliseconds. | | `instrumenter_id` | string | Rails ActiveSupport::Notifications instrumenter UUID. | | `request_id` | string | Rails request UUID from the active web request context, if any. Merged globally by the Honeybadger agent. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | Example ```json { "event_type": "retry_stopped.active_job", "job_class": "SyncInventoryJob", "job_id": "c2e3f4a5-6b7c-4d8e-9f0a-1b2c3d4e5f6a", "queue_name": "default", "adapter_class": "ActiveJob::QueueAdapters::SidekiqAdapter", "duration": 1.05, "instrumenter_id": "d6a5b3f4c2e1908a7b6c", "request_id": "0f5e4bb2-3c46-4b1c-91d5-2f4e8a6b9c01", "hostname": "worker-1.example.com", "environment": "production" } ``` ## Active Record ### sql.active\_record[](/insights/event-types/ruby/sql.active_record/ "View event details")[](/insights/event-types/ruby/sql.active_record.schema.json "View JSON Schema") A SQL query from Rails Active Record. Use request\_id to group queries from the same HTTP request. | Field | Type | Description | | ----------------- | ------- | ------------------------------------------------------------------------------------------------------------ | | `event_type` | string | Allowed value: `sql.active_record`. | | `query` | string | The SQL text with bind parameters obfuscated. | | `duration` | number | Wall-clock time the query took, in milliseconds. | | `cached` | boolean | Whether the query result was served from the ActiveRecord query cache. | | `async` | boolean | Whether the query was executed asynchronously. | | `request_id` | string | Rails request UUID. Shared by all events from the same HTTP request. | | `instrumenter_id` | string | Unique identifier for the ActiveSupport::Notifications instrumentation request, assigned by Rails. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | Example ```json { "event_type": "sql.active_record", "query": "SELECT \"users\".* FROM \"users\" WHERE \"users\".\"id\" = ? LIMIT ?", "duration": 2.34, "cached": false, "async": false, "request_id": "0f5e4bb2-3c46-4b1c-91d5-2f4e8a6b9c01", "instrumenter_id": "d6a5b3f4c2e1908a7b6c", "hostname": "web-1.example.com", "environment": "production" } ``` ## Active Storage ### service\_download.active\_storage[](/insights/event-types/ruby/service_download.active_storage/ "View event details")[](/insights/event-types/ruby/service_download.active_storage.schema.json "View JSON Schema") A Rails Active Storage download. | Field | Type | Description | | ----------------- | ------ | ---------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `service_download.active_storage`. | | `key` | string | Storage key (blob identifier). | | `service` | string | Storage service name, e.g. "disk", "s3". | | `checksum` | string | Content checksum. | | `duration` | number | Duration in milliseconds. | | `instrumenter_id` | string | Rails instrumenter UUID. | | `request_id` | string | Rails request UUID, present on any event fired during a web request context. Merged globally by the Honeybadger agent. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | Example ```json { "event_type": "service_download.active_storage", "key": "xtapjjcjiudrlk3tdwirsnz4dawl", "service": "S3", "checksum": "9X2k1mFqLpZ3vR8sT4wYuA==", "duration": 45.3, "instrumenter_id": "d6a5b3f4c2e1908a7b6c", "request_id": "0f5e4bb2-3c46-4b1c-91d5-2f4e8a6b9c01", "hostname": "web-1.example.com", "environment": "production" } ``` ### service\_upload.active\_storage[](/insights/event-types/ruby/service_upload.active_storage/ "View event details")[](/insights/event-types/ruby/service_upload.active_storage.schema.json "View JSON Schema") A Rails Active Storage upload. | Field | Type | Description | | ----------------- | ------ | ---------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `service_upload.active_storage`. | | `key` | string | Storage key (blob identifier). | | `service` | string | Storage service name, e.g. "disk", "s3". | | `checksum` | string | Content checksum. | | `duration` | number | Duration in milliseconds. | | `instrumenter_id` | string | Rails instrumenter UUID. | | `request_id` | string | Rails request UUID, present on any event fired during a web request context. Merged globally by the Honeybadger agent. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | Example ```json { "event_type": "service_upload.active_storage", "key": "xtapjjcjiudrlk3tdwirsnz4dawl", "service": "S3", "checksum": "9X2k1mFqLpZ3vR8sT4wYuA==", "duration": 182.64, "instrumenter_id": "d6a5b3f4c2e1908a7b6c", "request_id": "0f5e4bb2-3c46-4b1c-91d5-2f4e8a6b9c01", "hostname": "web-1.example.com", "environment": "production" } ``` ## Active Support ### cache\_cleanup.active\_support[](/insights/event-types/ruby/cache_cleanup.active_support/ "View event details")[](/insights/event-types/ruby/cache_cleanup.active_support.schema.json "View JSON Schema") A Rails cache cleanup. | Field | Type | Description | | ----------------- | ------ | ---------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `cache_cleanup.active_support`. | | `key` | string | Cache key. | | `store` | string | Cache store class name. | | `duration` | number | Duration in milliseconds. | | `instrumenter_id` | string | Rails instrumenter UUID. | | `request_id` | string | Rails request UUID, present on any event fired during a web request context. Merged globally by the Honeybadger agent. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | Example ```json { "event_type": "cache_cleanup.active_support", "key": "262144", "store": "ActiveSupport::Cache::MemoryStore", "duration": 4.87, "instrumenter_id": "d9f4a7b2c1e8d3f6a0b5", "request_id": "0f5e4bb2-3c46-4b1c-91d5-2f4e8a6b9c01", "hostname": "web-1.example.com", "environment": "production" } ``` ### cache\_decrement.active\_support[](/insights/event-types/ruby/cache_decrement.active_support/ "View event details")[](/insights/event-types/ruby/cache_decrement.active_support.schema.json "View JSON Schema") A Rails cache decrement. | Field | Type | Description | | ----------------- | ------ | ---------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `cache_decrement.active_support`. | | `key` | string | Cache key. | | `store` | string | Cache store class name. | | `duration` | number | Duration in milliseconds. | | `instrumenter_id` | string | Rails instrumenter UUID. | | `request_id` | string | Rails request UUID, present on any event fired during a web request context. Merged globally by the Honeybadger agent. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | Example ```json { "event_type": "cache_decrement.active_support", "key": "counters/available_slots", "store": "ActiveSupport::Cache::RedisCacheStore", "duration": 0.31, "instrumenter_id": "d9f4a7b2c1e8d3f6a0b5", "request_id": "0f5e4bb2-3c46-4b1c-91d5-2f4e8a6b9c01", "hostname": "web-1.example.com", "environment": "production" } ``` ### cache\_delete\_multi.active\_support[](/insights/event-types/ruby/cache_delete_multi.active_support/ "View event details")[](/insights/event-types/ruby/cache_delete_multi.active_support.schema.json "View JSON Schema") A Rails multi-key cache delete. | Field | Type | Description | | ----------------- | -------------- | ---------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `cache_delete_multi.active_support`. | | `key` | array\ | Cache keys deleted. | | `store` | string | Cache store class name. | | `duration` | number | Duration in milliseconds. | | `instrumenter_id` | string | | | `request_id` | string | Rails request UUID, present on any event fired during a web request context. Merged globally by the Honeybadger agent. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | Example ```json { "event_type": "cache_delete_multi.active_support", "key": [ "views/users/123", "views/users/124" ], "store": "ActiveSupport::Cache::RedisCacheStore", "duration": 0.74, "instrumenter_id": "d9f4a7b2c1e8d3f6a0b5", "request_id": "0f5e4bb2-3c46-4b1c-91d5-2f4e8a6b9c01", "hostname": "web-1.example.com", "environment": "production" } ``` ### cache\_delete.active\_support[](/insights/event-types/ruby/cache_delete.active_support/ "View event details")[](/insights/event-types/ruby/cache_delete.active_support.schema.json "View JSON Schema") A Rails cache delete. | Field | Type | Description | | ----------------- | ------ | ---------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `cache_delete.active_support`. | | `key` | string | Cache key. | | `store` | string | Cache store class name. | | `duration` | number | Duration in milliseconds. | | `instrumenter_id` | string | Rails instrumenter UUID. | | `request_id` | string | Rails request UUID, present on any event fired during a web request context. Merged globally by the Honeybadger agent. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | Example ```json { "event_type": "cache_delete.active_support", "key": "users/123", "store": "ActiveSupport::Cache::RedisCacheStore", "duration": 0.38, "instrumenter_id": "d9f4a7b2c1e8d3f6a0b5", "request_id": "0f5e4bb2-3c46-4b1c-91d5-2f4e8a6b9c01", "hostname": "web-1.example.com", "environment": "production" } ``` ### cache\_exist?.active\_support[](/insights/event-types/ruby/cache_exist_predicate.active_support/ "View event details")[](/insights/event-types/ruby/cache_exist_predicate.active_support.schema.json "View JSON Schema") A Rails cache existence check. | Field | Type | Description | | ----------------- | ------ | ---------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `cache_exist?.active_support`. | | `key` | string | Cache key. | | `store` | string | Cache store class name. | | `duration` | number | Duration in milliseconds. | | `instrumenter_id` | string | Rails instrumenter UUID. | | `request_id` | string | Rails request UUID, present on any event fired during a web request context. Merged globally by the Honeybadger agent. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | Example ```json { "event_type": "cache_exist?.active_support", "key": "users/123", "store": "ActiveSupport::Cache::RedisCacheStore", "duration": 0.21, "instrumenter_id": "d9f4a7b2c1e8d3f6a0b5", "request_id": "0f5e4bb2-3c46-4b1c-91d5-2f4e8a6b9c01", "hostname": "web-1.example.com", "environment": "production" } ``` ### cache\_fetch\_hit.active\_support[](/insights/event-types/ruby/cache_fetch_hit.active_support/ "View event details")[](/insights/event-types/ruby/cache_fetch_hit.active_support.schema.json "View JSON Schema") A Rails cache fetch hit. | Field | Type | Description | | ----------------- | ------ | ---------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `cache_fetch_hit.active_support`. | | `key` | string | Cache key. | | `store` | string | Cache store class name. | | `duration` | number | Duration in milliseconds. | | `instrumenter_id` | string | Rails instrumenter UUID. | | `request_id` | string | Rails request UUID, present on any event fired during a web request context. Merged globally by the Honeybadger agent. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | Example ```json { "event_type": "cache_fetch_hit.active_support", "key": "users/123", "store": "ActiveSupport::Cache::RedisCacheStore", "duration": 0.05, "instrumenter_id": "d9f4a7b2c1e8d3f6a0b5", "request_id": "0f5e4bb2-3c46-4b1c-91d5-2f4e8a6b9c01", "hostname": "web-1.example.com", "environment": "production" } ``` ### cache\_generate.active\_support[](/insights/event-types/ruby/cache_generate.active_support/ "View event details")[](/insights/event-types/ruby/cache_generate.active_support.schema.json "View JSON Schema") A Rails cache generate call. | Field | Type | Description | | ----------------- | ------ | ---------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `cache_generate.active_support`. | | `key` | string | Cache key. | | `store` | string | Cache store class name. | | `duration` | number | Duration in milliseconds. | | `instrumenter_id` | string | Rails instrumenter UUID. | | `request_id` | string | Rails request UUID, present on any event fired during a web request context. Merged globally by the Honeybadger agent. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | Example ```json { "event_type": "cache_generate.active_support", "key": "users/123", "store": "ActiveSupport::Cache::RedisCacheStore", "duration": 12.84, "instrumenter_id": "d9f4a7b2c1e8d3f6a0b5", "request_id": "0f5e4bb2-3c46-4b1c-91d5-2f4e8a6b9c01", "hostname": "web-1.example.com", "environment": "production" } ``` ### cache\_increment.active\_support[](/insights/event-types/ruby/cache_increment.active_support/ "View event details")[](/insights/event-types/ruby/cache_increment.active_support.schema.json "View JSON Schema") A Rails cache increment. | Field | Type | Description | | ----------------- | ------ | ---------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `cache_increment.active_support`. | | `key` | string | Cache key. | | `store` | string | Cache store class name. | | `duration` | number | Duration in milliseconds. | | `instrumenter_id` | string | Rails instrumenter UUID. | | `request_id` | string | Rails request UUID, present on any event fired during a web request context. Merged globally by the Honeybadger agent. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | Example ```json { "event_type": "cache_increment.active_support", "key": "counters/page_views", "store": "ActiveSupport::Cache::RedisCacheStore", "duration": 0.33, "instrumenter_id": "d9f4a7b2c1e8d3f6a0b5", "request_id": "0f5e4bb2-3c46-4b1c-91d5-2f4e8a6b9c01", "hostname": "web-1.example.com", "environment": "production" } ``` ### cache\_prune.active\_support[](/insights/event-types/ruby/cache_prune.active_support/ "View event details")[](/insights/event-types/ruby/cache_prune.active_support.schema.json "View JSON Schema") A Rails cache prune call. | Field | Type | Description | | ----------------- | ------ | ---------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `cache_prune.active_support`. | | `key` | string | Cache key. | | `store` | string | Cache store class name. | | `duration` | number | Duration in milliseconds. | | `instrumenter_id` | string | Rails instrumenter UUID. | | `request_id` | string | Rails request UUID, present on any event fired during a web request context. Merged globally by the Honeybadger agent. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | Example ```json { "event_type": "cache_prune.active_support", "key": "262144", "store": "ActiveSupport::Cache::MemoryStore", "duration": 3.52, "instrumenter_id": "d9f4a7b2c1e8d3f6a0b5", "request_id": "0f5e4bb2-3c46-4b1c-91d5-2f4e8a6b9c01", "hostname": "web-1.example.com", "environment": "production" } ``` ### cache\_read\_multi.active\_support[](/insights/event-types/ruby/cache_read_multi.active_support/ "View event details")[](/insights/event-types/ruby/cache_read_multi.active_support.schema.json "View JSON Schema") A Rails multi-key cache read. | Field | Type | Description | | ----------------- | -------------- | ---------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `cache_read_multi.active_support`. | | `key` | array\ | Cache keys read. | | `hits` | array\ | Keys that were cache hits. | | `store` | string | Cache store class name. | | `duration` | number | Duration in milliseconds. | | `instrumenter_id` | string | | | `request_id` | string | Rails request UUID, present on any event fired during a web request context. Merged globally by the Honeybadger agent. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | Example ```json { "event_type": "cache_read_multi.active_support", "key": [ "views/users/123", "views/users/124" ], "hits": [ "views/users/123" ], "store": "ActiveSupport::Cache::RedisCacheStore", "duration": 0.88, "instrumenter_id": "d9f4a7b2c1e8d3f6a0b5", "request_id": "0f5e4bb2-3c46-4b1c-91d5-2f4e8a6b9c01", "hostname": "web-1.example.com", "environment": "production" } ``` ### cache\_read.active\_support[](/insights/event-types/ruby/cache_read.active_support/ "View event details")[](/insights/event-types/ruby/cache_read.active_support.schema.json "View JSON Schema") A Rails cache read. | Field | Type | Description | | ----------------- | ------ | ---------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `cache_read.active_support`. | | `key` | string | Cache key. | | `store` | string | Cache store class name. | | `duration` | number | Duration in milliseconds. | | `instrumenter_id` | string | Rails instrumenter UUID. | | `request_id` | string | Rails request UUID, present on any event fired during a web request context. Merged globally by the Honeybadger agent. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | Example ```json { "event_type": "cache_read.active_support", "key": "users/123", "store": "ActiveSupport::Cache::RedisCacheStore", "duration": 0.42, "instrumenter_id": "d9f4a7b2c1e8d3f6a0b5", "request_id": "0f5e4bb2-3c46-4b1c-91d5-2f4e8a6b9c01", "hostname": "web-1.example.com", "environment": "production" } ``` ### cache\_write\_multi.active\_support[](/insights/event-types/ruby/cache_write_multi.active_support/ "View event details")[](/insights/event-types/ruby/cache_write_multi.active_support.schema.json "View JSON Schema") A Rails multi-key cache write. | Field | Type | Description | | ----------------- | -------------- | ---------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `cache_write_multi.active_support`. | | `key` | array\ | Cache keys written. | | `store` | string | Cache store class name. | | `duration` | number | Duration in milliseconds. | | `instrumenter_id` | string | | | `request_id` | string | Rails request UUID, present on any event fired during a web request context. Merged globally by the Honeybadger agent. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | Example ```json { "event_type": "cache_write_multi.active_support", "key": [ "views/users/123", "views/users/124" ], "store": "ActiveSupport::Cache::RedisCacheStore", "duration": 1.12, "instrumenter_id": "d9f4a7b2c1e8d3f6a0b5", "request_id": "0f5e4bb2-3c46-4b1c-91d5-2f4e8a6b9c01", "hostname": "web-1.example.com", "environment": "production" } ``` ### cache\_write.active\_support[](/insights/event-types/ruby/cache_write.active_support/ "View event details")[](/insights/event-types/ruby/cache_write.active_support.schema.json "View JSON Schema") A Rails cache write. | Field | Type | Description | | ----------------- | ------ | ---------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `cache_write.active_support`. | | `key` | string | Cache key. | | `store` | string | Cache store class name. | | `duration` | number | Duration in milliseconds. | | `instrumenter_id` | string | Rails instrumenter UUID. | | `request_id` | string | Rails request UUID, present on any event fired during a web request context. Merged globally by the Honeybadger agent. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | Example ```json { "event_type": "cache_write.active_support", "key": "users/123", "store": "ActiveSupport::Cache::RedisCacheStore", "duration": 0.61, "instrumenter_id": "d9f4a7b2c1e8d3f6a0b5", "request_id": "0f5e4bb2-3c46-4b1c-91d5-2f4e8a6b9c01", "hostname": "web-1.example.com", "environment": "production" } ``` ## Autotuner ### report.autotuner[](/insights/event-types/ruby/report.autotuner/ "View event details")[](/insights/event-types/ruby/report.autotuner.schema.json "View JSON Schema") A tuning recommendation from the Autotuner gem. | Field | Type | Description | | ------------- | ------ | ------------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `report.autotuner`. | | `report` | string | Human-readable tuning recommendation text. | | `request_id` | string | Rails request UUID, present on any event fired during a web request context. Set by the Honeybadger agent when available. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | Example ```json { "event_type": "report.autotuner", "report": "The following suggestions reduce the number of major GC collections during requests.\nSuggested tuning values:\n RUBY_GC_HEAP_OLDOBJECT_LIMIT_FACTOR=1.2 (default: 2.0)", "request_id": "0f5e4bb2-3c46-4b1c-91d5-2f4e8a6b9c01", "hostname": "web-1.example.com", "environment": "production" } ``` ### stats.autotuner[](/insights/event-types/ruby/stats.autotuner/ "View event details")[](/insights/event-types/ruby/stats.autotuner.schema.json "View JSON Schema") Periodic Ruby process memory and object metrics from Autotuner. Field names depend on the Autotuner version and enabled checks. | Field | Type | Description | | ------------- | ------ | ------------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `stats.autotuner`. | | `request_id` | string | Rails request UUID, present on any event fired during a web request context. Set by the Honeybadger agent when available. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | Example ```json { "event_type": "stats.autotuner", "request_time": 145.2, "gc_time": 12.4, "minor_gc_count": 3, "major_gc_count": 0, "heap_pages": 5460, "hostname": "web-1.example.com", "environment": "production" } ``` ## Flipper ### feature\_operation.flipper[](/insights/event-types/ruby/feature_operation.flipper/ "View event details")[](/insights/event-types/ruby/feature_operation.flipper.schema.json "View JSON Schema") A Flipper feature flag check or mutation recorded by Honeybadger. | Field | Type | Description | | ----------------- | ------ | ------------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `feature_operation.flipper`. | | `feature_name` | string | Name of the Flipper feature flag. | | `operation` | string | Operation performed, e.g. "enabled?", "enable", "disable". | | `result` | any | Result of the operation. Checks return booleans, while mutations can return other values. | | `request_id` | string | Rails request UUID, present on any event fired during a web request context. Set by the Honeybadger agent when available. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | | `instrumenter_id` | string | ActiveSupport::Notifications instrumenter UUID, added by the Honeybadger notification subscriber. | | `duration` | number | Duration of the instrumented operation in milliseconds. | Example ```json { "event_type": "feature_operation.flipper", "feature_name": "new_dashboard", "operation": "enabled?", "result": true, "request_id": "0f5e4bb2-3c46-4b1c-91d5-2f4e8a6b9c01", "hostname": "web-1.example.com", "environment": "production", "instrumenter_id": "d6a5b3f4c2e1908a7b6c", "duration": 0.42 } ``` ## Karafka ### consumer.consumed.karafka[](/insights/event-types/ruby/consumer.consumed.karafka/ "View event details")[](/insights/event-types/ruby/consumer.consumed.karafka.schema.json "View JSON Schema") A Karafka consumer processed a batch of Kafka messages. | Field | Type | Description | | ----------------- | ------- | ------------------------------------------------------------------------------------------------------------ | | `event_type` | string | Allowed value: `consumer.consumed.karafka`. | | `topic` | string | Kafka topic consumed from. | | `partition` | integer | Kafka partition consumed from. | | `consumer_group` | string | Consumer group identifier. | | `consumer` | string | Consumer class name. | | `processed` | integer | Number of messages processed in this batch. | | `duration` | number | Processing duration in milliseconds. | | `processing_lag` | integer | Latency between when the first message in the batch was produced and when processing began, in milliseconds. | | `consumption_lag` | integer | Latency between the last committed offset and the newest available offset, in milliseconds. | | `request_id` | string | Rails request UUID from the active web request context, if any. Merged globally by the Honeybadger agent. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | Example ```json { "event_type": "consumer.consumed.karafka", "topic": "orders", "partition": 0, "consumer_group": "orders_consumers", "consumer": "OrdersConsumer", "processed": 25, "duration": 845.3, "processing_lag": 213, "consumption_lag": 1378, "request_id": "3d9c2f81-6e5a-4f7b-9c0d-8a1b2c3d4e5f", "hostname": "worker-1.example.com", "environment": "production" } ``` ### error.occurred.karafka[](/insights/event-types/ruby/error.occurred.karafka/ "View event details")[](/insights/event-types/ruby/error.occurred.karafka.schema.json "View JSON Schema") A Karafka consumer or the Karafka framework raised an error. | Field | Type | Description | | ---------------- | ------- | ------------------------------------------------------------------------------------------------------------ | | `event_type` | string | Allowed value: `error.occurred.karafka`. | | `type` | string | Error source identifier, e.g., 'consumer.consume.error' or 'connection.error'. | | `error` | string | Exception message and class name. | | `topic` | string | Kafka topic where the error occurred, if applicable. | | `partition` | integer | Kafka partition where the error occurred, if applicable. | | `consumer_group` | string | Consumer group where the error occurred, if applicable. | | `request_id` | string | Rails request UUID from the active web request context, if any. Merged globally by the Honeybadger agent. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | Example ```json { "event_type": "error.occurred.karafka", "type": "consumer.consume.error", "error": "JSON::ParserError: unexpected token at 'invalid'", "topic": "orders", "partition": 0, "consumer_group": "orders_consumers", "request_id": "3d9c2f81-6e5a-4f7b-9c0d-8a1b2c3d4e5f", "hostname": "worker-1.example.com", "environment": "production" } ``` ### statistics\_emitted.karafka[](/insights/event-types/ruby/statistics_emitted.karafka/ "View event details")[](/insights/event-types/ruby/statistics_emitted.karafka.schema.json "View JSON Schema") Kafka broker and consumer statistics from librdkafka. | Field | Type | Description | | ------------------- | ------ | ------------------------------------------------------------------------------------------------------------------------------------------------ | | `event_type` | string | Allowed value: `statistics_emitted.karafka`. | | `consumer_group_id` | string | Karafka consumer group identifier. | | `statistics` | object | Raw librdkafka statistics payload. The shape is defined by librdkafka. See https\://github.com/confluentinc/librdkafka/blob/master/STATISTICS.md | | `statistics.*` | any | Additional caller-defined keys. | | `request_id` | string | Rails request UUID from the active web request context, if any. Merged globally by the Honeybadger agent. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | Example ```json { "event_type": "statistics_emitted.karafka", "consumer_group_id": "example_app_group", "statistics": { "client_id": "example_app", "type": "consumer", "rxmsgs": 12840 }, "request_id": "0f5e4bb2-3c46-4b1c-91d5-2f4e8a6b9c01", "hostname": "worker-1.example.com", "environment": "production" } ``` ## Metrics ### metric.hb[](/insights/event-types/ruby/metric.hb/ "View event details")[](/insights/event-types/ruby/metric.hb.schema.json "View JSON Schema") A metric recorded through Honeybadger's instrumentation API and flushed by the metrics registry. The metric\_type field tells you whether the event came from gauge, increment\_counter, decrement\_counter, histogram, or time. | Field | Type | Description | | --------------- | ---------------------- | ------------------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `metric.hb`. | | `metric_name` | string | Name of the metric as passed to the recording call. | | `metric_type` | string | The metric type. Timers are gauges recorded via Honeybadger.time. Allowed values: `gauge`, `counter`, `histogram`, `timer`. | | `samples` | integer | Number of observations recorded in this flush window. | | `interval` | integer | Length of the aggregation/flush window in seconds (insights.registry\_flush\_interval, default 60). | | `total` | number | Sum of all recorded values in the window (gauge, timer, and histogram metrics). | | `min` | number | Minimum recorded value in the window (gauge, timer, and histogram metrics). | | `max` | number | Maximum recorded value in the window (gauge, timer, and histogram metrics). | | `avg` | number | Average of recorded values in the window (gauge, timer, and histogram metrics). | | `latest` | number | Most recently recorded value in the window (gauge, timer, and histogram metrics). | | `counter` | number | Accumulated counter value for the window (counter metrics). | | `bins` | array\> | Histogram bin counts as \[upper\_bound, count] pairs. The final bin's upper bound is 1e20, which represents infinity. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | | `metric_source` | string | Source plugin or component that recorded the metric, e.g. "rails", "sidekiq", "solid\_queue", "net\_http", "puma", "autotuner". | Example ```json { "event_type": "metric.hb", "metric_name": "duration.process_action.action_controller", "metric_type": "gauge", "metric_source": "rails", "samples": 20, "interval": 60, "total": 1820.5, "min": 12.3, "max": 210.4, "avg": 91.03, "latest": 88.6, "hostname": "web-1.example.com", "environment": "production" } ``` ## Net::HTTP ### request.net\_http[](/insights/event-types/ruby/request.net_http/ "View event details")[](/insights/event-types/ruby/request.net_http.schema.json "View JSON Schema") An outbound HTTP request made with Ruby's Net::HTTP. | Field | Type | Description | | ------------- | ------- | ------------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `request.net_http`. | | `method` | string | HTTP method, e.g. "GET", "POST". | | `host` | string | Destination host. | | `url` | string | Full request URL. Only present when the net\_http.insights.full\_url config option is enabled. | | `status` | integer | HTTP response status code. | | `duration` | number | Round-trip duration in milliseconds. | | `request_id` | string | Rails request UUID, present on any event fired during a web request context. Set by the Honeybadger agent when available. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | Example ```json { "event_type": "request.net_http", "method": "GET", "host": "api.example.com", "url": "https://api.example.com/v2/items/42", "status": 200, "duration": 89.4, "request_id": "0f5e4bb2-3c46-4b1c-91d5-2f4e8a6b9c01", "hostname": "web-1.example.com", "environment": "production" } ``` ## Puma ### stats.puma[](/insights/event-types/ruby/stats.puma/ "View event details")[](/insights/event-types/ruby/stats.puma.schema.json "View JSON Schema") A periodic Puma stats snapshot. Cluster mode records one event per worker. Single mode records one event per cycle. Fields come directly from Puma.stats. | Field | Type | Description | | ---------------- | ------- | ------------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `stats.puma`. | | `worker` | integer | Worker index in cluster mode. Absent in single mode. | | `pool_capacity` | integer | Number of threads available to pick up new requests. | | `max_threads` | integer | Maximum number of threads configured for this worker. | | `requests_count` | integer | Total requests processed by this worker since start. | | `backlog` | integer | Number of connections waiting for a thread. | | `running` | integer | Number of threads currently running. | | `request_id` | string | Rails request UUID, present on any event fired during a web request context. Set by the Honeybadger agent when available. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | Example ```json { "event_type": "stats.puma", "worker": 0, "pool_capacity": 3, "max_threads": 5, "requests_count": 18342, "backlog": 0, "running": 5, "request_id": "0f5e4bb2-3c46-4b1c-91d5-2f4e8a6b9c01", "hostname": "web-1.example.com", "environment": "production" } ``` ## Sidekiq ### enqueue.sidekiq[](/insights/event-types/ruby/enqueue.sidekiq/ "View event details")[](/insights/event-types/ruby/enqueue.sidekiq.schema.json "View JSON Schema") A job was enqueued to a Sidekiq queue. | Field | Type | Description | | ------------- | ------ | ------------------------------------------------------------------------------------------------------------ | | `event_type` | string | Allowed value: `enqueue.sidekiq`. | | `jid` | string | Sidekiq job ID. | | `worker` | string | Worker class name. | | `queue` | string | Queue the job was pushed to. | | `request_id` | string | Rails request UUID from the active web request context, if any. Merged globally by the Honeybadger agent. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | Example ```json { "event_type": "enqueue.sidekiq", "jid": "f8a1c2d3e4b5a6c7d8e9f0a1", "worker": "WelcomeEmailJob", "queue": "default", "request_id": "0f5e4bb2-3c46-4b1c-91d5-2f4e8a6b9c01", "hostname": "web-1.example.com", "environment": "production" } ``` ### perform.sidekiq[](/insights/event-types/ruby/perform.sidekiq/ "View event details")[](/insights/event-types/ruby/perform.sidekiq.schema.json "View JSON Schema") A Sidekiq job ran. | Field | Type | Description | | ------------- | ------ | ------------------------------------------------------------------------------------------------------------ | | `event_type` | string | Allowed value: `perform.sidekiq`. | | `jid` | string | Sidekiq job ID. | | `worker` | string | Worker class name. | | `queue` | string | Queue the job ran on. | | `status` | string | Job execution outcome: 'success' if completed without exception, 'failure' if an exception was raised. | | `duration` | number | Execution duration in milliseconds. | | `request_id` | string | Rails request UUID from the active web request context, if any. Merged globally by the Honeybadger agent. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | Example ```json { "event_type": "perform.sidekiq", "jid": "8f0c1d2e3a4b5c6d7e8f9a0b", "worker": "WelcomeEmailWorker", "queue": "default", "status": "success", "duration": 487.32, "request_id": "0f5e4bb2-3c46-4b1c-91d5-2f4e8a6b9c01", "hostname": "worker-1.example.com", "environment": "production" } ``` ### stats.sidekiq[](/insights/event-types/ruby/stats.sidekiq/ "View event details")[](/insights/event-types/ruby/stats.sidekiq.schema.json "View JSON Schema") Sidekiq cluster statistics from the Honeybadger agent. | Field | Type | Description | | ----------------------- | ------- | ----------------------------------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `stats.sidekiq`. | | `processed` | integer | Total jobs processed (lifetime counter). | | `failed` | integer | Total jobs failed (lifetime counter). | | `scheduled_size` | integer | Jobs in the scheduled set. | | `retry_size` | integer | Jobs in the retry set. | | `dead_size` | integer | Jobs in the dead set. | | `processes_size` | integer | Number of running Sidekiq processes. | | `default_queue_latency` | number | Latency of the default queue in seconds (the raw Sidekiq::Stats value; note that per-queue latency under `queues` is reported in milliseconds). | | `capacity` | integer | Total worker thread capacity across all processes. | | `utilization` | number | Worker utilization ratio (0.0–1.0). | | `queues` | object | Per-queue stats keyed by queue name. | | `queues.*` | any | Additional caller-defined keys. | | `request_id` | string | Rails request UUID from the active web request context, if any. Merged globally by the Honeybadger agent. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | Example ```json { "event_type": "stats.sidekiq", "processed": 1284512, "failed": 1432, "scheduled_size": 87, "retry_size": 12, "dead_size": 3, "processes_size": 2, "default_queue_latency": 0.42, "capacity": 20, "utilization": 0.35, "queues": { "default": { "latency": 420, "depth": 6, "busy": 5 }, "mailers": { "latency": 0, "depth": 0, "busy": 2 } }, "request_id": "0f5e4bb2-3c46-4b1c-91d5-2f4e8a6b9c01", "hostname": "worker-1.example.com", "environment": "production" } ``` ## Solid Queue ### stats.solid\_queue[](/insights/event-types/ruby/stats.solid_queue/ "View event details")[](/insights/event-types/ruby/stats.solid_queue.schema.json "View JSON Schema") Solid Queue cluster statistics from the Honeybadger agent. | Field | Type | Description | | -------------------- | ------- | ------------------------------------------------------------------------------------------------------------ | | `event_type` | string | Allowed value: `stats.solid_queue`. | | `jobs_in_progress` | integer | Jobs currently being executed. | | `jobs_blocked` | integer | Jobs blocked waiting on a concurrency limit. | | `jobs_failed` | integer | Jobs in the failed state. | | `jobs_scheduled` | integer | Jobs scheduled for future execution. | | `jobs_processed` | integer | Total jobs processed (lifetime counter). | | `active_workers` | integer | Number of active worker processes. | | `active_dispatchers` | integer | Number of active dispatcher processes. | | `queues` | object | Per-queue depth keyed by queue name. | | `queues.*` | any | Additional caller-defined keys. | | `request_id` | string | Rails request UUID from the active web request context, if any. Merged globally by the Honeybadger agent. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | Example ```json { "event_type": "stats.solid_queue", "jobs_in_progress": 4, "jobs_blocked": 2, "jobs_failed": 7, "jobs_scheduled": 156, "jobs_processed": 184329, "active_workers": 2, "active_dispatchers": 1, "queues": { "default": { "depth": 23 }, "mailers": { "depth": 2 } }, "request_id": "0f5e4bb2-3c46-4b1c-91d5-2f4e8a6b9c01", "hostname": "worker-1.example.com", "environment": "production" } ``` ## System ### report.system[](/insights/event-types/ruby/report.system/ "View event details")[](/insights/event-types/ruby/report.system.schema.json "View JSON Schema") A periodic memory and load average snapshot from the Honeybadger system plugin. | Field | Type | Description | | ---------------- | ------ | ------------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `report.system`. | | `mem` | object | Memory statistics in megabytes. | | `mem.total` | number | Total system memory. | | `mem.free` | number | Free memory. | | `mem.buffers` | number | Memory used for buffers. | | `mem.cached` | number | Memory used for cache. | | `mem.free_total` | number | Total available memory (free + buffers + cached). | | `load` | object | System load averages. | | `load.one` | number | 1-minute load average. | | `load.five` | number | 5-minute load average. | | `load.fifteen` | number | 15-minute load average. | | `request_id` | string | Rails request UUID, present on any event fired during a web request context. Set by the Honeybadger agent when available. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | Example ```json { "event_type": "report.system", "mem": { "total": 16384, "free": 2048.5, "buffers": 512.25, "cached": 6144.75, "free_total": 8705.5 }, "load": { "one": 0.42, "five": 0.38, "fifteen": 0.35 }, "request_id": "0f5e4bb2-3c46-4b1c-91d5-2f4e8a6b9c01", "hostname": "web-1.example.com", "environment": "production" } ``` # cache_cleanup.active_support > A Rails cache cleanup. A Rails cache cleanup. Source **Active Support** Category **Cache** Fields **8** [honeybadger-ruby](/lib/ruby/) ## Fields 8 | Field | Type | Description | | ----------------- | ------ | ---------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `cache_cleanup.active_support`. | | `key` | string | Cache key. | | `store` | string | Cache store class name. | | `duration` | number | Duration in milliseconds. | | `instrumenter_id` | string | Rails instrumenter UUID. | | `request_id` | string | Rails request UUID, present on any event fired during a web request context. Merged globally by the Honeybadger agent. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | ## Example ```json { "event_type": "cache_cleanup.active_support", "key": "262144", "store": "ActiveSupport::Cache::MemoryStore", "duration": 4.87, "instrumenter_id": "d9f4a7b2c1e8d3f6a0b5", "request_id": "0f5e4bb2-3c46-4b1c-91d5-2f4e8a6b9c01", "hostname": "web-1.example.com", "environment": "production" } ``` # cache_decrement.active_support > A Rails cache decrement. A Rails cache decrement. Source **Active Support** Category **Cache** Fields **8** [honeybadger-ruby](/lib/ruby/) ## Fields 8 | Field | Type | Description | | ----------------- | ------ | ---------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `cache_decrement.active_support`. | | `key` | string | Cache key. | | `store` | string | Cache store class name. | | `duration` | number | Duration in milliseconds. | | `instrumenter_id` | string | Rails instrumenter UUID. | | `request_id` | string | Rails request UUID, present on any event fired during a web request context. Merged globally by the Honeybadger agent. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | ## Example ```json { "event_type": "cache_decrement.active_support", "key": "counters/available_slots", "store": "ActiveSupport::Cache::RedisCacheStore", "duration": 0.31, "instrumenter_id": "d9f4a7b2c1e8d3f6a0b5", "request_id": "0f5e4bb2-3c46-4b1c-91d5-2f4e8a6b9c01", "hostname": "web-1.example.com", "environment": "production" } ``` # cache_delete_multi.active_support > A Rails multi-key cache delete. A Rails multi-key cache delete. Source **Active Support** Category **Cache** Fields **8** [honeybadger-ruby](/lib/ruby/) ## Fields 8 | Field | Type | Description | | ----------------- | -------------- | ---------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `cache_delete_multi.active_support`. | | `key` | array\ | Cache keys deleted. | | `store` | string | Cache store class name. | | `duration` | number | Duration in milliseconds. | | `instrumenter_id` | string | | | `request_id` | string | Rails request UUID, present on any event fired during a web request context. Merged globally by the Honeybadger agent. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | ## Example ```json { "event_type": "cache_delete_multi.active_support", "key": [ "views/users/123", "views/users/124" ], "store": "ActiveSupport::Cache::RedisCacheStore", "duration": 0.74, "instrumenter_id": "d9f4a7b2c1e8d3f6a0b5", "request_id": "0f5e4bb2-3c46-4b1c-91d5-2f4e8a6b9c01", "hostname": "web-1.example.com", "environment": "production" } ``` # cache_delete.active_support > A Rails cache delete. A Rails cache delete. Source **Active Support** Category **Cache** Fields **8** [honeybadger-ruby](/lib/ruby/) ## Fields 8 | Field | Type | Description | | ----------------- | ------ | ---------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `cache_delete.active_support`. | | `key` | string | Cache key. | | `store` | string | Cache store class name. | | `duration` | number | Duration in milliseconds. | | `instrumenter_id` | string | Rails instrumenter UUID. | | `request_id` | string | Rails request UUID, present on any event fired during a web request context. Merged globally by the Honeybadger agent. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | ## Example ```json { "event_type": "cache_delete.active_support", "key": "users/123", "store": "ActiveSupport::Cache::RedisCacheStore", "duration": 0.38, "instrumenter_id": "d9f4a7b2c1e8d3f6a0b5", "request_id": "0f5e4bb2-3c46-4b1c-91d5-2f4e8a6b9c01", "hostname": "web-1.example.com", "environment": "production" } ``` # cache_exist?.active_support > A Rails cache existence check. A Rails cache existence check. Source **Active Support** Category **Cache** Fields **8** [honeybadger-ruby](/lib/ruby/) ## Fields 8 | Field | Type | Description | | ----------------- | ------ | ---------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `cache_exist?.active_support`. | | `key` | string | Cache key. | | `store` | string | Cache store class name. | | `duration` | number | Duration in milliseconds. | | `instrumenter_id` | string | Rails instrumenter UUID. | | `request_id` | string | Rails request UUID, present on any event fired during a web request context. Merged globally by the Honeybadger agent. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | ## Example ```json { "event_type": "cache_exist?.active_support", "key": "users/123", "store": "ActiveSupport::Cache::RedisCacheStore", "duration": 0.21, "instrumenter_id": "d9f4a7b2c1e8d3f6a0b5", "request_id": "0f5e4bb2-3c46-4b1c-91d5-2f4e8a6b9c01", "hostname": "web-1.example.com", "environment": "production" } ``` # cache_fetch_hit.active_support > A Rails cache fetch hit. A Rails cache fetch hit. Source **Active Support** Category **Cache** Fields **8** [honeybadger-ruby](/lib/ruby/) ## Fields 8 | Field | Type | Description | | ----------------- | ------ | ---------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `cache_fetch_hit.active_support`. | | `key` | string | Cache key. | | `store` | string | Cache store class name. | | `duration` | number | Duration in milliseconds. | | `instrumenter_id` | string | Rails instrumenter UUID. | | `request_id` | string | Rails request UUID, present on any event fired during a web request context. Merged globally by the Honeybadger agent. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | ## Example ```json { "event_type": "cache_fetch_hit.active_support", "key": "users/123", "store": "ActiveSupport::Cache::RedisCacheStore", "duration": 0.05, "instrumenter_id": "d9f4a7b2c1e8d3f6a0b5", "request_id": "0f5e4bb2-3c46-4b1c-91d5-2f4e8a6b9c01", "hostname": "web-1.example.com", "environment": "production" } ``` # cache_generate.active_support > A Rails cache generate call. A Rails cache generate call. Source **Active Support** Category **Cache** Fields **8** [honeybadger-ruby](/lib/ruby/) ## Fields 8 | Field | Type | Description | | ----------------- | ------ | ---------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `cache_generate.active_support`. | | `key` | string | Cache key. | | `store` | string | Cache store class name. | | `duration` | number | Duration in milliseconds. | | `instrumenter_id` | string | Rails instrumenter UUID. | | `request_id` | string | Rails request UUID, present on any event fired during a web request context. Merged globally by the Honeybadger agent. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | ## Example ```json { "event_type": "cache_generate.active_support", "key": "users/123", "store": "ActiveSupport::Cache::RedisCacheStore", "duration": 12.84, "instrumenter_id": "d9f4a7b2c1e8d3f6a0b5", "request_id": "0f5e4bb2-3c46-4b1c-91d5-2f4e8a6b9c01", "hostname": "web-1.example.com", "environment": "production" } ``` # cache_increment.active_support > A Rails cache increment. A Rails cache increment. Source **Active Support** Category **Cache** Fields **8** [honeybadger-ruby](/lib/ruby/) ## Fields 8 | Field | Type | Description | | ----------------- | ------ | ---------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `cache_increment.active_support`. | | `key` | string | Cache key. | | `store` | string | Cache store class name. | | `duration` | number | Duration in milliseconds. | | `instrumenter_id` | string | Rails instrumenter UUID. | | `request_id` | string | Rails request UUID, present on any event fired during a web request context. Merged globally by the Honeybadger agent. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | ## Example ```json { "event_type": "cache_increment.active_support", "key": "counters/page_views", "store": "ActiveSupport::Cache::RedisCacheStore", "duration": 0.33, "instrumenter_id": "d9f4a7b2c1e8d3f6a0b5", "request_id": "0f5e4bb2-3c46-4b1c-91d5-2f4e8a6b9c01", "hostname": "web-1.example.com", "environment": "production" } ``` # cache_prune.active_support > A Rails cache prune call. A Rails cache prune call. Source **Active Support** Category **Cache** Fields **8** [honeybadger-ruby](/lib/ruby/) ## Fields 8 | Field | Type | Description | | ----------------- | ------ | ---------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `cache_prune.active_support`. | | `key` | string | Cache key. | | `store` | string | Cache store class name. | | `duration` | number | Duration in milliseconds. | | `instrumenter_id` | string | Rails instrumenter UUID. | | `request_id` | string | Rails request UUID, present on any event fired during a web request context. Merged globally by the Honeybadger agent. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | ## Example ```json { "event_type": "cache_prune.active_support", "key": "262144", "store": "ActiveSupport::Cache::MemoryStore", "duration": 3.52, "instrumenter_id": "d9f4a7b2c1e8d3f6a0b5", "request_id": "0f5e4bb2-3c46-4b1c-91d5-2f4e8a6b9c01", "hostname": "web-1.example.com", "environment": "production" } ``` # cache_read_multi.active_support > A Rails multi-key cache read. A Rails multi-key cache read. Source **Active Support** Category **Cache** Fields **9** [honeybadger-ruby](/lib/ruby/) ## Fields 9 | Field | Type | Description | | ----------------- | -------------- | ---------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `cache_read_multi.active_support`. | | `key` | array\ | Cache keys read. | | `hits` | array\ | Keys that were cache hits. | | `store` | string | Cache store class name. | | `duration` | number | Duration in milliseconds. | | `instrumenter_id` | string | | | `request_id` | string | Rails request UUID, present on any event fired during a web request context. Merged globally by the Honeybadger agent. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | ## Example ```json { "event_type": "cache_read_multi.active_support", "key": [ "views/users/123", "views/users/124" ], "hits": [ "views/users/123" ], "store": "ActiveSupport::Cache::RedisCacheStore", "duration": 0.88, "instrumenter_id": "d9f4a7b2c1e8d3f6a0b5", "request_id": "0f5e4bb2-3c46-4b1c-91d5-2f4e8a6b9c01", "hostname": "web-1.example.com", "environment": "production" } ``` # cache_read.active_support > A Rails cache read. A Rails cache read. Source **Active Support** Category **Cache** Fields **8** [honeybadger-ruby](/lib/ruby/) ## Fields 8 | Field | Type | Description | | ----------------- | ------ | ---------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `cache_read.active_support`. | | `key` | string | Cache key. | | `store` | string | Cache store class name. | | `duration` | number | Duration in milliseconds. | | `instrumenter_id` | string | Rails instrumenter UUID. | | `request_id` | string | Rails request UUID, present on any event fired during a web request context. Merged globally by the Honeybadger agent. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | ## Example ```json { "event_type": "cache_read.active_support", "key": "users/123", "store": "ActiveSupport::Cache::RedisCacheStore", "duration": 0.42, "instrumenter_id": "d9f4a7b2c1e8d3f6a0b5", "request_id": "0f5e4bb2-3c46-4b1c-91d5-2f4e8a6b9c01", "hostname": "web-1.example.com", "environment": "production" } ``` # cache_write_multi.active_support > A Rails multi-key cache write. A Rails multi-key cache write. Source **Active Support** Category **Cache** Fields **8** [honeybadger-ruby](/lib/ruby/) ## Fields 8 | Field | Type | Description | | ----------------- | -------------- | ---------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `cache_write_multi.active_support`. | | `key` | array\ | Cache keys written. | | `store` | string | Cache store class name. | | `duration` | number | Duration in milliseconds. | | `instrumenter_id` | string | | | `request_id` | string | Rails request UUID, present on any event fired during a web request context. Merged globally by the Honeybadger agent. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | ## Example ```json { "event_type": "cache_write_multi.active_support", "key": [ "views/users/123", "views/users/124" ], "store": "ActiveSupport::Cache::RedisCacheStore", "duration": 1.12, "instrumenter_id": "d9f4a7b2c1e8d3f6a0b5", "request_id": "0f5e4bb2-3c46-4b1c-91d5-2f4e8a6b9c01", "hostname": "web-1.example.com", "environment": "production" } ``` # cache_write.active_support > A Rails cache write. A Rails cache write. Source **Active Support** Category **Cache** Fields **8** [honeybadger-ruby](/lib/ruby/) ## Fields 8 | Field | Type | Description | | ----------------- | ------ | ---------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `cache_write.active_support`. | | `key` | string | Cache key. | | `store` | string | Cache store class name. | | `duration` | number | Duration in milliseconds. | | `instrumenter_id` | string | Rails instrumenter UUID. | | `request_id` | string | Rails request UUID, present on any event fired during a web request context. Merged globally by the Honeybadger agent. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | ## Example ```json { "event_type": "cache_write.active_support", "key": "users/123", "store": "ActiveSupport::Cache::RedisCacheStore", "duration": 0.61, "instrumenter_id": "d9f4a7b2c1e8d3f6a0b5", "request_id": "0f5e4bb2-3c46-4b1c-91d5-2f4e8a6b9c01", "hostname": "web-1.example.com", "environment": "production" } ``` # consumer.consumed.karafka > A Karafka consumer processed a batch of Kafka messages. A Karafka consumer processed a batch of Kafka messages. Source **Karafka** Category **Jobs** Fields **12** [honeybadger-ruby](/lib/ruby/) ## Fields 12 | Field | Type | Description | | ----------------- | ------- | ------------------------------------------------------------------------------------------------------------ | | `event_type` | string | Allowed value: `consumer.consumed.karafka`. | | `topic` | string | Kafka topic consumed from. | | `partition` | integer | Kafka partition consumed from. | | `consumer_group` | string | Consumer group identifier. | | `consumer` | string | Consumer class name. | | `processed` | integer | Number of messages processed in this batch. | | `duration` | number | Processing duration in milliseconds. | | `processing_lag` | integer | Latency between when the first message in the batch was produced and when processing began, in milliseconds. | | `consumption_lag` | integer | Latency between the last committed offset and the newest available offset, in milliseconds. | | `request_id` | string | Rails request UUID from the active web request context, if any. Merged globally by the Honeybadger agent. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | ## Example ```json { "event_type": "consumer.consumed.karafka", "topic": "orders", "partition": 0, "consumer_group": "orders_consumers", "consumer": "OrdersConsumer", "processed": 25, "duration": 845.3, "processing_lag": 213, "consumption_lag": 1378, "request_id": "3d9c2f81-6e5a-4f7b-9c0d-8a1b2c3d4e5f", "hostname": "worker-1.example.com", "environment": "production" } ``` # discard.active_job > An Active Job job was discarded. An Active Job job was discarded. Source **Active Job** Category **Jobs** Fields **10** [honeybadger-ruby](/lib/ruby/) ## Fields 10 | Field | Type | Description | | ----------------- | ------ | ------------------------------------------------------------------------------------------------------------ | | `event_type` | string | Allowed value: `discard.active_job`. | | `job_class` | string | ActiveJob class name. | | `job_id` | string | Unique job identifier. | | `queue_name` | string | Queue the job is on. | | `adapter_class` | string | ActiveJob adapter class, e.g. "SidekiqAdapter". | | `duration` | number | Duration in milliseconds. | | `instrumenter_id` | string | Rails ActiveSupport::Notifications instrumenter UUID. | | `request_id` | string | Rails request UUID from the active web request context, if any. Merged globally by the Honeybadger agent. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | ## Example ```json { "event_type": "discard.active_job", "job_class": "WelcomeEmailJob", "job_id": "c6e1f6b2-8d4a-4f0e-9b7c-1a2d3e4f5a6b", "queue_name": "default", "adapter_class": "ActiveJob::QueueAdapters::SidekiqAdapter", "duration": 0.34, "instrumenter_id": "a3c8e1f5b7d2c4e9f0a6", "request_id": "3d9c2f81-6e5a-4f7b-9c0d-8a1b2c3d4e5f", "hostname": "worker-1.example.com", "environment": "production" } ``` # embed.active_agent > An embedding request made through ActiveAgent. An embedding request made through ActiveAgent. Source **Active Agent** Category **LLM** Fields **19** [honeybadger-ruby](/lib/ruby/) ## Fields 19 | Field | Type | Description | | -------------------- | ------- | ---------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `embed.active_agent`. | | `provider` | string | Model provider name. | | `provider_module` | string | ActiveAgent provider module class name. | | `model` | string | Embedding model identifier. | | `trace_id` | string | Trace ID for correlating events within a single agent run. | | `input_size` | integer | Number of input strings submitted for embedding. | | `embedding_count` | integer | Number of embedding vectors returned. | | `encoding_format` | string | Encoding format requested, e.g. "float". | | `dimensions` | integer | Embedding vector dimensions. | | `response_model` | string | Model identifier as returned by the provider. | | `response_id` | string | Provider-assigned response ID. | | `usage` | object | Token usage reported by the provider. | | `usage.input_tokens` | integer | | | `usage.total_tokens` | integer | | | `duration` | number | Duration in milliseconds. | | `instrumenter_id` | string | Rails instrumenter UUID. | | `request_id` | string | Rails request UUID, present on any event fired during a web request context. Merged globally by the Honeybadger agent. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | ## Example ```json { "event_type": "embed.active_agent", "provider": "OpenAI", "provider_module": "OpenAI::Embeddings", "model": "text-embedding-3-small", "trace_id": "9b4f2a6e-1c8d-4e7a-b3f5-6d2c9e0a4b18", "input_size": 3, "embedding_count": 3, "encoding_format": "float", "dimensions": 1536, "response_model": "text-embedding-3-small", "response_id": "embd-9f8e7d6c5b4a3210fedc", "usage": { "input_tokens": 42, "total_tokens": 42 }, "duration": 184.27, "instrumenter_id": "d9f4a7b2c1e8d3f6a0b5", "request_id": "0f5e4bb2-3c46-4b1c-91d5-2f4e8a6b9c01", "hostname": "web-1.example.com", "environment": "production" } ``` # enqueue_all.active_job > A batch of Active Job jobs was enqueued. A batch of Active Job jobs was enqueued. Source **Active Job** Category **Jobs** Fields **11** [honeybadger-ruby](/lib/ruby/) ## Fields 11 | Field | Type | Description | | ----------------- | -------------- | ------------------------------------------------------------------------------------------------------------ | | `event_type` | string | Allowed value: `enqueue_all.active_job`. | | `adapter_class` | string | ActiveJob adapter class. | | `jobs` | array\ | Jobs included in the batch. | | `jobs.job_class` | string | | | `jobs.job_id` | string | | | `jobs.queue_name` | string | | | `duration` | number | Duration in milliseconds. | | `instrumenter_id` | string | Rails ActiveSupport::Notifications instrumenter UUID. | | `request_id` | string | Rails request UUID from the active web request context, if any. Merged globally by the Honeybadger agent. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | ## Example ```json { "event_type": "enqueue_all.active_job", "adapter_class": "ActiveJob::QueueAdapters::SidekiqAdapter", "jobs": [ { "job_class": "WelcomeEmailJob", "job_id": "c6e1f6b2-8d4a-4f0e-9b7c-1a2d3e4f5a6b", "queue_name": "default" }, { "job_class": "SyncCrmContactJob", "job_id": "8a2b4c6d-0e1f-4a3b-8c5d-7e9f1a2b3c4d", "queue_name": "default" } ], "duration": 3.86, "instrumenter_id": "d9f4a7b2c1e8d3f6a0b5", "request_id": "0f5e4bb2-3c46-4b1c-91d5-2f4e8a6b9c01", "hostname": "web-1.example.com", "environment": "production" } ``` # enqueue_at.active_job > An Active Job job was scheduled to run later. An Active Job job was scheduled to run later. Source **Active Job** Category **Jobs** Fields **10** [honeybadger-ruby](/lib/ruby/) ## Fields 10 | Field | Type | Description | | ----------------- | ------ | ------------------------------------------------------------------------------------------------------------ | | `event_type` | string | Allowed value: `enqueue_at.active_job`. | | `job_class` | string | ActiveJob class name. | | `job_id` | string | Unique job identifier. | | `queue_name` | string | Queue the job is on. | | `adapter_class` | string | ActiveJob adapter class, e.g. "SidekiqAdapter". | | `duration` | number | Duration in milliseconds. | | `instrumenter_id` | string | Rails ActiveSupport::Notifications instrumenter UUID. | | `request_id` | string | Rails request UUID from the active web request context, if any. Merged globally by the Honeybadger agent. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | ## Example ```json { "event_type": "enqueue_at.active_job", "job_class": "WeeklyDigestJob", "job_id": "5f7e9d1c-3b2a-4c8e-a6f0-9d8c7b6a5e4f", "queue_name": "low", "adapter_class": "ActiveJob::QueueAdapters::SidekiqAdapter", "duration": 2.11, "instrumenter_id": "d9f4a7b2c1e8d3f6a0b5", "request_id": "0f5e4bb2-3c46-4b1c-91d5-2f4e8a6b9c01", "hostname": "web-1.example.com", "environment": "production" } ``` # enqueue_retry.active_job > An Active Job job was queued for retry. An Active Job job was queued for retry. Source **Active Job** Category **Jobs** Fields **10** [honeybadger-ruby](/lib/ruby/) ## Fields 10 | Field | Type | Description | | ----------------- | ------ | ------------------------------------------------------------------------------------------------------------ | | `event_type` | string | Allowed value: `enqueue_retry.active_job`. | | `job_class` | string | ActiveJob class name. | | `job_id` | string | Unique job identifier. | | `queue_name` | string | Queue the job is on. | | `adapter_class` | string | ActiveJob adapter class, e.g. "SidekiqAdapter". | | `duration` | number | Duration in milliseconds. | | `instrumenter_id` | string | Rails ActiveSupport::Notifications instrumenter UUID. | | `request_id` | string | Rails request UUID from the active web request context, if any. Merged globally by the Honeybadger agent. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | ## Example ```json { "event_type": "enqueue_retry.active_job", "job_class": "WelcomeEmailJob", "job_id": "c6e1f6b2-8d4a-4f0e-9b7c-1a2d3e4f5a6b", "queue_name": "default", "adapter_class": "ActiveJob::QueueAdapters::SidekiqAdapter", "duration": 1.27, "instrumenter_id": "a3c8e1f5b7d2c4e9f0a6", "request_id": "3d9c2f81-6e5a-4f7b-9c0d-8a1b2c3d4e5f", "hostname": "worker-1.example.com", "environment": "production" } ``` # enqueue.active_job > An Active Job job was enqueued. An Active Job job was enqueued. Source **Active Job** Category **Jobs** Fields **10** [honeybadger-ruby](/lib/ruby/) ## Fields 10 | Field | Type | Description | | ----------------- | ------ | ------------------------------------------------------------------------------------------------------------ | | `event_type` | string | Allowed value: `enqueue.active_job`. | | `job_class` | string | ActiveJob class name. | | `job_id` | string | Unique job identifier. | | `queue_name` | string | Queue the job is on. | | `adapter_class` | string | ActiveJob adapter class, e.g. "SidekiqAdapter". | | `duration` | number | Duration in milliseconds. | | `instrumenter_id` | string | Rails ActiveSupport::Notifications instrumenter UUID. | | `request_id` | string | Rails request UUID from the active web request context, if any. Merged globally by the Honeybadger agent. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | ## Example ```json { "event_type": "enqueue.active_job", "job_class": "WelcomeEmailJob", "job_id": "c6e1f6b2-8d4a-4f0e-9b7c-1a2d3e4f5a6b", "queue_name": "default", "adapter_class": "ActiveJob::QueueAdapters::SidekiqAdapter", "duration": 1.94, "instrumenter_id": "d9f4a7b2c1e8d3f6a0b5", "request_id": "0f5e4bb2-3c46-4b1c-91d5-2f4e8a6b9c01", "hostname": "web-1.example.com", "environment": "production" } ``` # enqueue.sidekiq > A job was enqueued to a Sidekiq queue. A job was enqueued to a Sidekiq queue. Source **Sidekiq** Category **Jobs** Fields **7** [honeybadger-ruby](/lib/ruby/) ## Fields 7 | Field | Type | Description | | ------------- | ------ | ------------------------------------------------------------------------------------------------------------ | | `event_type` | string | Allowed value: `enqueue.sidekiq`. | | `jid` | string | Sidekiq job ID. | | `worker` | string | Worker class name. | | `queue` | string | Queue the job was pushed to. | | `request_id` | string | Rails request UUID from the active web request context, if any. Merged globally by the Honeybadger agent. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | ## Example ```json { "event_type": "enqueue.sidekiq", "jid": "f8a1c2d3e4b5a6c7d8e9f0a1", "worker": "WelcomeEmailJob", "queue": "default", "request_id": "0f5e4bb2-3c46-4b1c-91d5-2f4e8a6b9c01", "hostname": "web-1.example.com", "environment": "production" } ``` # error.occurred.karafka > A Karafka consumer or the Karafka framework raised an error. A Karafka consumer or the Karafka framework raised an error. Source **Karafka** Category **Jobs** Fields **9** [honeybadger-ruby](/lib/ruby/) ## Fields 9 | Field | Type | Description | | ---------------- | ------- | ------------------------------------------------------------------------------------------------------------ | | `event_type` | string | Allowed value: `error.occurred.karafka`. | | `type` | string | Error source identifier, e.g., 'consumer.consume.error' or 'connection.error'. | | `error` | string | Exception message and class name. | | `topic` | string | Kafka topic where the error occurred, if applicable. | | `partition` | integer | Kafka partition where the error occurred, if applicable. | | `consumer_group` | string | Consumer group where the error occurred, if applicable. | | `request_id` | string | Rails request UUID from the active web request context, if any. Merged globally by the Honeybadger agent. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | ## Example ```json { "event_type": "error.occurred.karafka", "type": "consumer.consume.error", "error": "JSON::ParserError: unexpected token at 'invalid'", "topic": "orders", "partition": 0, "consumer_group": "orders_consumers", "request_id": "3d9c2f81-6e5a-4f7b-9c0d-8a1b2c3d4e5f", "hostname": "worker-1.example.com", "environment": "production" } ``` # exist_fragment?.action_controller > A Rails fragment cache existence check. A Rails fragment cache existence check. Source **Action Controller** Category **Cache** Fields **7** [honeybadger-ruby](/lib/ruby/) ## Fields 7 | Field | Type | Description | | ----------------- | ------ | ---------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `exist_fragment?.action_controller`. | | `key` | string | Fragment cache key. | | `duration` | number | Duration in milliseconds. | | `instrumenter_id` | string | | | `request_id` | string | Rails request UUID, present on any event fired during a web request context. Merged globally by the Honeybadger agent. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | ## Example ```json { "event_type": "exist_fragment?.action_controller", "key": "views/users/123-20260612143000000000/a1b2c3d4e5f6", "duration": 0.31, "instrumenter_id": "d6a5b3f4c2e1908a7b6c", "request_id": "0f5e4bb2-3c46-4b1c-91d5-2f4e8a6b9c01", "hostname": "web-1.example.com", "environment": "production" } ``` # expire_fragment.action_controller > A Rails fragment cache expire call. A Rails fragment cache expire call. Source **Action Controller** Category **Cache** Fields **7** [honeybadger-ruby](/lib/ruby/) ## Fields 7 | Field | Type | Description | | ----------------- | ------ | ---------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `expire_fragment.action_controller`. | | `key` | string | Fragment cache key. | | `duration` | number | Duration in milliseconds. | | `instrumenter_id` | string | | | `request_id` | string | Rails request UUID, present on any event fired during a web request context. Merged globally by the Honeybadger agent. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | ## Example ```json { "event_type": "expire_fragment.action_controller", "key": "views/users/123-20260612143000000000/a1b2c3d4e5f6", "duration": 0.52, "instrumenter_id": "d6a5b3f4c2e1908a7b6c", "request_id": "0f5e4bb2-3c46-4b1c-91d5-2f4e8a6b9c01", "hostname": "web-1.example.com", "environment": "production" } ``` # feature_operation.flipper > A Flipper feature flag check or mutation recorded by Honeybadger. A Flipper feature flag check or mutation recorded by Honeybadger. Source **Flipper** Category **Feature flags** Fields **9** [honeybadger-ruby](/lib/ruby/) ## Fields 9 | Field | Type | Description | | ----------------- | ------ | ------------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `feature_operation.flipper`. | | `feature_name` | string | Name of the Flipper feature flag. | | `operation` | string | Operation performed, e.g. "enabled?", "enable", "disable". | | `result` | any | Result of the operation. Checks return booleans, while mutations can return other values. | | `request_id` | string | Rails request UUID, present on any event fired during a web request context. Set by the Honeybadger agent when available. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | | `instrumenter_id` | string | ActiveSupport::Notifications instrumenter UUID, added by the Honeybadger notification subscriber. | | `duration` | number | Duration of the instrumented operation in milliseconds. | ## Example ```json { "event_type": "feature_operation.flipper", "feature_name": "new_dashboard", "operation": "enabled?", "result": true, "request_id": "0f5e4bb2-3c46-4b1c-91d5-2f4e8a6b9c01", "hostname": "web-1.example.com", "environment": "production", "instrumenter_id": "d6a5b3f4c2e1908a7b6c", "duration": 0.42 } ``` # halted_callback.action_controller > A before/around filter halted the Rails request processing chain. A before/around filter halted the Rails request processing chain. Source **Action Controller** Category **Request** Fields **7** [honeybadger-ruby](/lib/ruby/) ## Fields 7 | Field | Type | Description | | ----------------- | ------ | ---------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `halted_callback.action_controller`. | | `filter` | string | Name of the filter/callback that halted the chain. | | `duration` | number | Duration in milliseconds. | | `instrumenter_id` | string | Rails instrumenter UUID. | | `request_id` | string | Rails request UUID, present on any event fired during a web request context. Merged globally by the Honeybadger agent. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | ## Example ```json { "event_type": "halted_callback.action_controller", "filter": "require_login", "duration": 2.15, "instrumenter_id": "d6a5b3f4c2e1908a7b6c", "request_id": "0f5e4bb2-3c46-4b1c-91d5-2f4e8a6b9c01", "hostname": "web-1.example.com", "environment": "production" } ``` # metric.hb > A metric recorded through Honeybadger's instrumentation API and flushed by the metrics registry. The metric_type field tells you whether the event came from gauge, increment_counter, decrement_counter, histogram, or time. A metric recorded through Honeybadger’s instrumentation API and flushed by the metrics registry. The metric\_type field tells you whether the event came from gauge, increment\_counter, decrement\_counter, histogram, or time. Category **Metrics** Fields **15** [honeybadger-ruby](/lib/ruby/) ## Fields 15 | Field | Type | Description | | --------------- | ---------------------- | ------------------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `metric.hb`. | | `metric_name` | string | Name of the metric as passed to the recording call. | | `metric_type` | string | The metric type. Timers are gauges recorded via Honeybadger.time. Allowed values: `gauge`, `counter`, `histogram`, `timer`. | | `samples` | integer | Number of observations recorded in this flush window. | | `interval` | integer | Length of the aggregation/flush window in seconds (insights.registry\_flush\_interval, default 60). | | `total` | number | Sum of all recorded values in the window (gauge, timer, and histogram metrics). | | `min` | number | Minimum recorded value in the window (gauge, timer, and histogram metrics). | | `max` | number | Maximum recorded value in the window (gauge, timer, and histogram metrics). | | `avg` | number | Average of recorded values in the window (gauge, timer, and histogram metrics). | | `latest` | number | Most recently recorded value in the window (gauge, timer, and histogram metrics). | | `counter` | number | Accumulated counter value for the window (counter metrics). | | `bins` | array\> | Histogram bin counts as \[upper\_bound, count] pairs. The final bin's upper bound is 1e20, which represents infinity. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | | `metric_source` | string | Source plugin or component that recorded the metric, e.g. "rails", "sidekiq", "solid\_queue", "net\_http", "puma", "autotuner". | ## Example ```json { "event_type": "metric.hb", "metric_name": "duration.process_action.action_controller", "metric_type": "gauge", "metric_source": "rails", "samples": 20, "interval": 60, "total": 1820.5, "min": 12.3, "max": 210.4, "avg": 91.03, "latest": 88.6, "hostname": "web-1.example.com", "environment": "production" } ``` # perform.active_job > An Active Job job ran, whether it succeeded or raised an exception. An Active Job job ran, whether it succeeded or raised an exception. Source **Active Job** Category **Jobs** Fields **12** [honeybadger-ruby](/lib/ruby/) ## Fields 12 | Field | Type | Description | | ------------------ | ------ | -------------------------------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `perform.active_job`. | | `job_class` | string | ActiveJob class name. | | `job_id` | string | Unique job identifier. | | `queue_name` | string | Queue the job ran on. | | `adapter_class` | string | ActiveJob adapter class, e.g. "SidekiqAdapter". | | `status` | string | Job execution outcome: 'success' if completed without exception, 'failure' if an exception was raised. Allowed values: `success`, `failure`. | | `exception_object` | string | The exception instance if the job raised, absent on success. Serialized as a string in JSON format. | | `duration` | number | Duration in milliseconds. | | `instrumenter_id` | string | Rails ActiveSupport::Notifications instrumenter UUID. | | `request_id` | string | Rails request UUID from the active web request context, if any. Merged globally by the Honeybadger agent. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | ## Example ```json { "event_type": "perform.active_job", "job_class": "WelcomeEmailJob", "job_id": "b1d2e3f4-5a6b-4c7d-8e9f-0a1b2c3d4e5f", "queue_name": "default", "adapter_class": "ActiveJob::QueueAdapters::SidekiqAdapter", "status": "success", "duration": 532.18, "instrumenter_id": "d6a5b3f4c2e1908a7b6c", "request_id": "0f5e4bb2-3c46-4b1c-91d5-2f4e8a6b9c01", "hostname": "worker-1.example.com", "environment": "production" } ``` # perform.sidekiq > A Sidekiq job ran. A Sidekiq job ran. Source **Sidekiq** Category **Jobs** Fields **9** [honeybadger-ruby](/lib/ruby/) ## Fields 9 | Field | Type | Description | | ------------- | ------ | ------------------------------------------------------------------------------------------------------------ | | `event_type` | string | Allowed value: `perform.sidekiq`. | | `jid` | string | Sidekiq job ID. | | `worker` | string | Worker class name. | | `queue` | string | Queue the job ran on. | | `status` | string | Job execution outcome: 'success' if completed without exception, 'failure' if an exception was raised. | | `duration` | number | Execution duration in milliseconds. | | `request_id` | string | Rails request UUID from the active web request context, if any. Merged globally by the Honeybadger agent. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | ## Example ```json { "event_type": "perform.sidekiq", "jid": "8f0c1d2e3a4b5c6d7e8f9a0b", "worker": "WelcomeEmailWorker", "queue": "default", "status": "success", "duration": 487.32, "request_id": "0f5e4bb2-3c46-4b1c-91d5-2f4e8a6b9c01", "hostname": "worker-1.example.com", "environment": "production" } ``` # process_action.action_controller > A Rails controller action finished handling an HTTP request. Includes total duration, database time, view time, route details, and response status. A Rails controller action finished handling an HTTP request. Includes total duration, database time, view time, route details, and response status. Source **Action Controller** Category **Request** Fields **14** [honeybadger-ruby](/lib/ruby/) ## Fields 14 | Field | Type | Description | | ----------------- | ------- | -------------------------------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `process_action.action_controller`. | | `controller` | string | Controller class name, e.g. "SearchController". | | `action` | string | Action method on the controller, e.g. "index", "destroy". | | `method` | string | HTTP method, e.g. "GET", "POST", "PUT". | | `path` | string | Request path, e.g. "/follows". Often high-cardinality due to ids. | | `format` | string | Response format, e.g. "html", "json". | | `status` | integer | HTTP status code returned to the client. | | `duration` | number | Total wall-clock time the action took, in milliseconds. Includes db\_runtime and view\_runtime. | | `db_runtime` | number | Milliseconds spent in DB queries during this action. | | `view_runtime` | number | Milliseconds spent rendering views during this action. | | `request_id` | string | Rails request UUID. Also appears on sql.active\_record, render\_\*.action\_view, and cache\_\*.active\_support events from the same request. | | `instrumenter_id` | string | Unique identifier for the ActiveSupport::Notifications instrumentation request, assigned by Rails. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | ## Example ```json { "event_type": "process_action.action_controller", "controller": "UsersController", "action": "show", "method": "GET", "path": "/users/123", "format": "html", "status": 200, "duration": 145.2, "db_runtime": 38.7, "view_runtime": 52.4, "request_id": "0f5e4bb2-3c46-4b1c-91d5-2f4e8a6b9c01", "instrumenter_id": "d6a5b3f4c2e1908a7b6c", "hostname": "web-1.example.com", "environment": "production" } ``` # process.action_mailer > Rails generated an Action Mailer message. Rails generated an Action Mailer message. Source **Action Mailer** Category **Mail** Fields **18** [honeybadger-ruby](/lib/ruby/) ## Fields 18 | Field | Type | Description | | ---------------------- | -------------- | ---------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `process.action_mailer`. | | `mailer` | string | Mailer class name, e.g. "UserMailer". | | `action` | string | Mailer action method, e.g. "welcome\_email". | | `message_id` | string | Message-ID header of the generated email. | | `subject` | string | Email subject line. | | `to` | array\ | Recipient addresses. | | `cc` | array\ | CC addresses. | | `bcc` | array\ | BCC addresses. | | `date` | string | Email date header as a string. | | `attachments` | array\ | File attachments included in the email. | | `attachments.filename` | string | | | `params` | object | Params passed to the mailer action. | | `params.*` | any | Additional caller-defined keys. | | `duration` | number | Duration in milliseconds. | | `instrumenter_id` | string | Rails instrumenter UUID. | | `request_id` | string | Rails request UUID, present on any event fired during a web request context. Merged globally by the Honeybadger agent. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | ## Example ```json { "event_type": "process.action_mailer", "mailer": "UserMailer", "action": "welcome_email", "message_id": "684af2d1c3b4a_1a2b3c4d5e6f@web-1.example.com.mail", "subject": "Welcome to Example App", "to": [ "user@example.com" ], "cc": [ "support@example.com" ], "bcc": [ "audit@example.com" ], "date": "Fri, 12 Jun 2026 14:30:00 +0000", "attachments": [ { "filename": "welcome-guide.pdf" } ], "params": { "user_id": 123 }, "duration": 84.21, "instrumenter_id": "d6a5b3f4c2e1908a7b6c", "request_id": "0f5e4bb2-3c46-4b1c-91d5-2f4e8a6b9c01", "hostname": "web-1.example.com", "environment": "production" } ``` # process.active_agent > An ActiveAgent action ran. Honeybadger forwards the ActiveAgent payload as-is, so extra fields depend on your ActiveAgent version and provider. An ActiveAgent action ran. Honeybadger forwards the ActiveAgent payload as-is, so extra fields depend on your ActiveAgent version and provider. Source **Active Agent** Category **LLM** Fields **8** [honeybadger-ruby](/lib/ruby/) ## Fields 8 | Field | Type | Description | | ----------------- | ------ | ------------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `process.active_agent`. | | `trace_id` | string | Trace ID for correlating events within a single agent run. | | `provider` | string | Model provider name. | | `duration` | number | Duration in milliseconds. | | `instrumenter_id` | string | ActiveSupport::Notifications instrumenter UUID, added by the Honeybadger notification subscriber. | | `request_id` | string | Rails request UUID, present on any event fired during a web request context. Set by the Honeybadger agent when available. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | ## Example ```json { "event_type": "process.active_agent", "trace_id": "7c9e6679-7425-40de-944b-e07fc1f90ae7", "provider": "openai", "duration": 2310.47, "instrumenter_id": "d6a5b3f4c2e1908a7b6c", "request_id": "0f5e4bb2-3c46-4b1c-91d5-2f4e8a6b9c01", "hostname": "web-1.example.com", "environment": "production" } ``` # prompt.active_agent > A model prompt request made through ActiveAgent. A model prompt request made through ActiveAgent. Source **Active Agent** Category **LLM** Fields **24** [honeybadger-ruby](/lib/ruby/) ## Fields 24 | Field | Type | Description | | --------------------- | ------- | ------------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `prompt.active_agent`. | | `provider` | string | Model provider name, e.g. "openai", "anthropic". | | `provider_module` | string | ActiveAgent provider module class name. | | `model` | string | Model identifier, e.g. "gpt-4o", "claude-3-opus". | | `trace_id` | string | Trace ID for correlating events within a single agent run. | | `message_count` | integer | Number of messages in the prompt context. | | `stream` | boolean | Whether the response was streamed. | | `finish_reason` | string | Stop reason returned by the provider, e.g. "stop", "length". | | `response_model` | string | Model identifier as returned by the provider response. | | `response_id` | string | Provider-assigned response ID. | | `temperature` | number | Sampling temperature used. | | `max_tokens` | integer | Max tokens parameter. | | `top_p` | number | Top-p nucleus sampling parameter. | | `tool_count` | integer | Number of tools available to the model. | | `has_instructions` | boolean | Whether a system instructions block was included. | | `usage` | object | Token usage reported by the provider. | | `usage.input_tokens` | integer | | | `usage.output_tokens` | integer | | | `usage.total_tokens` | integer | | | `duration` | number | Duration in milliseconds. | | `instrumenter_id` | string | ActiveSupport::Notifications instrumenter UUID, added by the Honeybadger notification subscriber. | | `request_id` | string | Rails request UUID, present on any event fired during a web request context. Set by the Honeybadger agent when available. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | ## Example ```json { "event_type": "prompt.active_agent", "provider": "openai", "provider_module": "ActiveAgent::GenerationProvider::OpenAIProvider", "model": "gpt-4o", "trace_id": "7c9e6679-7425-40de-944b-e07fc1f90ae7", "message_count": 4, "stream": false, "finish_reason": "stop", "response_model": "gpt-4o-2024-08-06", "response_id": "chatcmpl-Bx7Qk2T9fJ3aV1mN5pR8sLwY", "temperature": 0.7, "max_tokens": 1024, "top_p": 1, "tool_count": 3, "has_instructions": true, "usage": { "input_tokens": 412, "output_tokens": 186, "total_tokens": 598 }, "duration": 1820.43, "instrumenter_id": "d6a5b3f4c2e1908a7b6c", "request_id": "0f5e4bb2-3c46-4b1c-91d5-2f4e8a6b9c01", "hostname": "web-1.example.com", "environment": "production" } ``` # read_fragment.action_controller > A Rails fragment cache read. A Rails fragment cache read. Source **Action Controller** Category **Cache** Fields **7** [honeybadger-ruby](/lib/ruby/) ## Fields 7 | Field | Type | Description | | ----------------- | ------ | ---------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `read_fragment.action_controller`. | | `key` | string | Fragment cache key. | | `duration` | number | Duration in milliseconds. | | `instrumenter_id` | string | | | `request_id` | string | Rails request UUID, present on any event fired during a web request context. Merged globally by the Honeybadger agent. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | ## Example ```json { "event_type": "read_fragment.action_controller", "key": "views/users/123-20260612143000000000/a1b2c3d4e5f6", "duration": 0.45, "instrumenter_id": "d6a5b3f4c2e1908a7b6c", "request_id": "0f5e4bb2-3c46-4b1c-91d5-2f4e8a6b9c01", "hostname": "web-1.example.com", "environment": "production" } ``` # redirect_to.action_controller > A Rails controller issued a redirect. A Rails controller issued a redirect. Source **Action Controller** Category **Request** Fields **8** [honeybadger-ruby](/lib/ruby/) ## Fields 8 | Field | Type | Description | | ----------------- | ------- | ---------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `redirect_to.action_controller`. | | `status` | integer | HTTP redirect status code, e.g. 301, 302. | | `location` | string | URL the client is redirected to. | | `duration` | number | Duration in milliseconds. | | `instrumenter_id` | string | Rails instrumenter UUID. | | `request_id` | string | Rails request UUID, present on any event fired during a web request context. Merged globally by the Honeybadger agent. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | ## Example ```json { "event_type": "redirect_to.action_controller", "status": 302, "location": "https://app.example.com/users/123", "duration": 0.85, "instrumenter_id": "d6a5b3f4c2e1908a7b6c", "request_id": "0f5e4bb2-3c46-4b1c-91d5-2f4e8a6b9c01", "hostname": "web-1.example.com", "environment": "production" } ``` # render_collection.action_view > A Rails view render. This shape is shared by template, partial, and collection render events. A typical request has one template render and several partial renders. A Rails view render. This shape is shared by template, partial, and collection render events. A typical request has one template render and several partial renders. Source **Action View** Category **View** Fields **8** [honeybadger-ruby](/lib/ruby/) ## Fields 8 | Field | Type | Description | | ----------------- | -------------- | ------------------------------------------------------------------------------------------------------------ | | `event_type` | string | Allowed value: `render_collection.action_view`. | | `view` | string | Path of the template file, e.g. "\[PROJECT\_ROOT]/app/views/users/show\.html.erb". | | `layout` | string \| null | Layout the template was rendered into, e.g. "application". Null when the render skipped layouts. | | `duration` | number | Render duration in milliseconds. | | `request_id` | string | Rails request UUID. Shared by all events from the same HTTP request. | | `instrumenter_id` | string | Unique identifier for the ActiveSupport::Notifications instrumentation request, assigned by Rails. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | ## Example ```json { "event_type": "render_collection.action_view", "view": "[PROJECT_ROOT]/app/views/comments/_comment.html.erb", "layout": null, "duration": 6.4, "request_id": "0f5e4bb2-3c46-4b1c-91d5-2f4e8a6b9c01", "instrumenter_id": "d6a5b3f4c2e1908a7b6c", "hostname": "web-1.example.com", "environment": "production" } ``` # render_partial.action_view > A Rails view render. This shape is shared by template, partial, and collection render events. A typical request has one template render and several partial renders. A Rails view render. This shape is shared by template, partial, and collection render events. A typical request has one template render and several partial renders. Source **Action View** Category **View** Fields **8** [honeybadger-ruby](/lib/ruby/) ## Fields 8 | Field | Type | Description | | ----------------- | -------------- | ------------------------------------------------------------------------------------------------------------ | | `event_type` | string | Allowed value: `render_partial.action_view`. | | `view` | string | Path of the template file, e.g. "\[PROJECT\_ROOT]/app/views/users/show\.html.erb". | | `layout` | string \| null | Layout the template was rendered into, e.g. "application". Null when the render skipped layouts. | | `duration` | number | Render duration in milliseconds. | | `request_id` | string | Rails request UUID. Shared by all events from the same HTTP request. | | `instrumenter_id` | string | Unique identifier for the ActiveSupport::Notifications instrumentation request, assigned by Rails. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | ## Example ```json { "event_type": "render_partial.action_view", "view": "[PROJECT_ROOT]/app/views/users/_user.html.erb", "layout": null, "duration": 1.8, "request_id": "0f5e4bb2-3c46-4b1c-91d5-2f4e8a6b9c01", "instrumenter_id": "d6a5b3f4c2e1908a7b6c", "hostname": "web-1.example.com", "environment": "production" } ``` # render_template.action_view > A Rails view render. This shape is shared by template, partial, and collection render events. A typical request has one template render and several partial renders. A Rails view render. This shape is shared by template, partial, and collection render events. A typical request has one template render and several partial renders. Source **Action View** Category **View** Fields **8** [honeybadger-ruby](/lib/ruby/) ## Fields 8 | Field | Type | Description | | ----------------- | -------------- | ------------------------------------------------------------------------------------------------------------ | | `event_type` | string | Allowed value: `render_template.action_view`. | | `view` | string | Path of the template file, e.g. "\[PROJECT\_ROOT]/app/views/users/show\.html.erb". | | `layout` | string \| null | Layout the template was rendered into, e.g. "application". Null when the render skipped layouts. | | `duration` | number | Render duration in milliseconds. | | `request_id` | string | Rails request UUID. Shared by all events from the same HTTP request. | | `instrumenter_id` | string | Unique identifier for the ActiveSupport::Notifications instrumentation request, assigned by Rails. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | ## Example ```json { "event_type": "render_template.action_view", "view": "[PROJECT_ROOT]/app/views/users/show.html.erb", "layout": "layouts/application", "duration": 24.6, "request_id": "0f5e4bb2-3c46-4b1c-91d5-2f4e8a6b9c01", "instrumenter_id": "d6a5b3f4c2e1908a7b6c", "hostname": "web-1.example.com", "environment": "production" } ``` # report.autotuner > A tuning recommendation from the Autotuner gem. A tuning recommendation from the Autotuner gem. Source **Autotuner** Category **Metrics** Fields **5** [honeybadger-ruby](/lib/ruby/) ## Fields 5 | Field | Type | Description | | ------------- | ------ | ------------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `report.autotuner`. | | `report` | string | Human-readable tuning recommendation text. | | `request_id` | string | Rails request UUID, present on any event fired during a web request context. Set by the Honeybadger agent when available. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | ## Example ```json { "event_type": "report.autotuner", "report": "The following suggestions reduce the number of major GC collections during requests.\nSuggested tuning values:\n RUBY_GC_HEAP_OLDOBJECT_LIMIT_FACTOR=1.2 (default: 2.0)", "request_id": "0f5e4bb2-3c46-4b1c-91d5-2f4e8a6b9c01", "hostname": "web-1.example.com", "environment": "production" } ``` # report.system > A periodic memory and load average snapshot from the Honeybadger system plugin. A periodic memory and load average snapshot from the Honeybadger system plugin. Category **System** Fields **14** [honeybadger-ruby](/lib/ruby/) ## Fields 14 | Field | Type | Description | | ---------------- | ------ | ------------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `report.system`. | | `mem` | object | Memory statistics in megabytes. | | `mem.total` | number | Total system memory. | | `mem.free` | number | Free memory. | | `mem.buffers` | number | Memory used for buffers. | | `mem.cached` | number | Memory used for cache. | | `mem.free_total` | number | Total available memory (free + buffers + cached). | | `load` | object | System load averages. | | `load.one` | number | 1-minute load average. | | `load.five` | number | 5-minute load average. | | `load.fifteen` | number | 15-minute load average. | | `request_id` | string | Rails request UUID, present on any event fired during a web request context. Set by the Honeybadger agent when available. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | ## Example ```json { "event_type": "report.system", "mem": { "total": 16384, "free": 2048.5, "buffers": 512.25, "cached": 6144.75, "free_total": 8705.5 }, "load": { "one": 0.42, "five": 0.38, "fifteen": 0.35 }, "request_id": "0f5e4bb2-3c46-4b1c-91d5-2f4e8a6b9c01", "hostname": "web-1.example.com", "environment": "production" } ``` # request.net_http > An outbound HTTP request made with Ruby's Net::HTTP. An outbound HTTP request made with Ruby’s Net::HTTP. Source **Net::HTTP** Category **HTTP** Fields **9** [honeybadger-ruby](/lib/ruby/) ## Fields 9 | Field | Type | Description | | ------------- | ------- | ------------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `request.net_http`. | | `method` | string | HTTP method, e.g. "GET", "POST". | | `host` | string | Destination host. | | `url` | string | Full request URL. Only present when the net\_http.insights.full\_url config option is enabled. | | `status` | integer | HTTP response status code. | | `duration` | number | Round-trip duration in milliseconds. | | `request_id` | string | Rails request UUID, present on any event fired during a web request context. Set by the Honeybadger agent when available. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | ## Example ```json { "event_type": "request.net_http", "method": "GET", "host": "api.example.com", "url": "https://api.example.com/v2/items/42", "status": 200, "duration": 89.4, "request_id": "0f5e4bb2-3c46-4b1c-91d5-2f4e8a6b9c01", "hostname": "web-1.example.com", "environment": "production" } ``` # retry_stopped.active_job > An Active Job job stopped retrying after too many failed attempts. An Active Job job stopped retrying after too many failed attempts. Source **Active Job** Category **Jobs** Fields **10** [honeybadger-ruby](/lib/ruby/) ## Fields 10 | Field | Type | Description | | ----------------- | ------ | ------------------------------------------------------------------------------------------------------------ | | `event_type` | string | Allowed value: `retry_stopped.active_job`. | | `job_class` | string | ActiveJob class name. | | `job_id` | string | Unique job identifier. | | `queue_name` | string | Queue the job is on. | | `adapter_class` | string | ActiveJob adapter class, e.g. "SidekiqAdapter". | | `duration` | number | Duration in milliseconds. | | `instrumenter_id` | string | Rails ActiveSupport::Notifications instrumenter UUID. | | `request_id` | string | Rails request UUID from the active web request context, if any. Merged globally by the Honeybadger agent. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | ## Example ```json { "event_type": "retry_stopped.active_job", "job_class": "SyncInventoryJob", "job_id": "c2e3f4a5-6b7c-4d8e-9f0a-1b2c3d4e5f6a", "queue_name": "default", "adapter_class": "ActiveJob::QueueAdapters::SidekiqAdapter", "duration": 1.05, "instrumenter_id": "d6a5b3f4c2e1908a7b6c", "request_id": "0f5e4bb2-3c46-4b1c-91d5-2f4e8a6b9c01", "hostname": "worker-1.example.com", "environment": "production" } ``` # send_file.action_controller > A Rails controller started sending a file. A Rails controller started sending a file. Source **Action Controller** Category **Request** Fields **7** [honeybadger-ruby](/lib/ruby/) ## Fields 7 | Field | Type | Description | | ----------------- | ------ | ---------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `send_file.action_controller`. | | `path` | string | Filesystem path of the file being sent. | | `duration` | number | Duration in milliseconds. | | `instrumenter_id` | string | Rails instrumenter UUID. | | `request_id` | string | Rails request UUID, present on any event fired during a web request context. Merged globally by the Honeybadger agent. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | ## Example ```json { "event_type": "send_file.action_controller", "path": "/app/storage/exports/report-2026-06.pdf", "duration": 3.42, "instrumenter_id": "d6a5b3f4c2e1908a7b6c", "request_id": "0f5e4bb2-3c46-4b1c-91d5-2f4e8a6b9c01", "hostname": "web-1.example.com", "environment": "production" } ``` # service_download.active_storage > A Rails Active Storage download. A Rails Active Storage download. Source **Active Storage** Category **Storage** Fields **9** [honeybadger-ruby](/lib/ruby/) ## Fields 9 | Field | Type | Description | | ----------------- | ------ | ---------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `service_download.active_storage`. | | `key` | string | Storage key (blob identifier). | | `service` | string | Storage service name, e.g. "disk", "s3". | | `checksum` | string | Content checksum. | | `duration` | number | Duration in milliseconds. | | `instrumenter_id` | string | Rails instrumenter UUID. | | `request_id` | string | Rails request UUID, present on any event fired during a web request context. Merged globally by the Honeybadger agent. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | ## Example ```json { "event_type": "service_download.active_storage", "key": "xtapjjcjiudrlk3tdwirsnz4dawl", "service": "S3", "checksum": "9X2k1mFqLpZ3vR8sT4wYuA==", "duration": 45.3, "instrumenter_id": "d6a5b3f4c2e1908a7b6c", "request_id": "0f5e4bb2-3c46-4b1c-91d5-2f4e8a6b9c01", "hostname": "web-1.example.com", "environment": "production" } ``` # service_upload.active_storage > A Rails Active Storage upload. A Rails Active Storage upload. Source **Active Storage** Category **Storage** Fields **9** [honeybadger-ruby](/lib/ruby/) ## Fields 9 | Field | Type | Description | | ----------------- | ------ | ---------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `service_upload.active_storage`. | | `key` | string | Storage key (blob identifier). | | `service` | string | Storage service name, e.g. "disk", "s3". | | `checksum` | string | Content checksum. | | `duration` | number | Duration in milliseconds. | | `instrumenter_id` | string | Rails instrumenter UUID. | | `request_id` | string | Rails request UUID, present on any event fired during a web request context. Merged globally by the Honeybadger agent. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | ## Example ```json { "event_type": "service_upload.active_storage", "key": "xtapjjcjiudrlk3tdwirsnz4dawl", "service": "S3", "checksum": "9X2k1mFqLpZ3vR8sT4wYuA==", "duration": 182.64, "instrumenter_id": "d6a5b3f4c2e1908a7b6c", "request_id": "0f5e4bb2-3c46-4b1c-91d5-2f4e8a6b9c01", "hostname": "web-1.example.com", "environment": "production" } ``` # sql.active_record > A SQL query from Rails Active Record. Use request_id to group queries from the same HTTP request. A SQL query from Rails Active Record. Use request\_id to group queries from the same HTTP request. Source **Active Record** Category **Database** Fields **9** [honeybadger-ruby](/lib/ruby/) ## Fields 9 | Field | Type | Description | | ----------------- | ------- | ------------------------------------------------------------------------------------------------------------ | | `event_type` | string | Allowed value: `sql.active_record`. | | `query` | string | The SQL text with bind parameters obfuscated. | | `duration` | number | Wall-clock time the query took, in milliseconds. | | `cached` | boolean | Whether the query result was served from the ActiveRecord query cache. | | `async` | boolean | Whether the query was executed asynchronously. | | `request_id` | string | Rails request UUID. Shared by all events from the same HTTP request. | | `instrumenter_id` | string | Unique identifier for the ActiveSupport::Notifications instrumentation request, assigned by Rails. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | ## Example ```json { "event_type": "sql.active_record", "query": "SELECT \"users\".* FROM \"users\" WHERE \"users\".\"id\" = ? LIMIT ?", "duration": 2.34, "cached": false, "async": false, "request_id": "0f5e4bb2-3c46-4b1c-91d5-2f4e8a6b9c01", "instrumenter_id": "d6a5b3f4c2e1908a7b6c", "hostname": "web-1.example.com", "environment": "production" } ``` # statistics_emitted.karafka > Kafka broker and consumer statistics from librdkafka. Kafka broker and consumer statistics from librdkafka. Source **Karafka** Category **Metrics** Fields **7** [honeybadger-ruby](/lib/ruby/) ## Fields 7 | Field | Type | Description | | ------------------- | ------ | ------------------------------------------------------------------------------------------------------------------------------------------------ | | `event_type` | string | Allowed value: `statistics_emitted.karafka`. | | `consumer_group_id` | string | Karafka consumer group identifier. | | `statistics` | object | Raw librdkafka statistics payload. The shape is defined by librdkafka. See https\://github.com/confluentinc/librdkafka/blob/master/STATISTICS.md | | `statistics.*` | any | Additional caller-defined keys. | | `request_id` | string | Rails request UUID from the active web request context, if any. Merged globally by the Honeybadger agent. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | ## Example ```json { "event_type": "statistics_emitted.karafka", "consumer_group_id": "example_app_group", "statistics": { "client_id": "example_app", "type": "consumer", "rxmsgs": 12840 }, "request_id": "0f5e4bb2-3c46-4b1c-91d5-2f4e8a6b9c01", "hostname": "worker-1.example.com", "environment": "production" } ``` # stats.autotuner > Periodic Ruby process memory and object metrics from Autotuner. Field names depend on the Autotuner version and enabled checks. Periodic Ruby process memory and object metrics from Autotuner. Field names depend on the Autotuner version and enabled checks. Source **Autotuner** Category **Metrics** Fields **4** [honeybadger-ruby](/lib/ruby/) ## Fields 4 | Field | Type | Description | | ------------- | ------ | ------------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `stats.autotuner`. | | `request_id` | string | Rails request UUID, present on any event fired during a web request context. Set by the Honeybadger agent when available. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | ## Example ```json { "event_type": "stats.autotuner", "request_time": 145.2, "gc_time": 12.4, "minor_gc_count": 3, "major_gc_count": 0, "heap_pages": 5460, "hostname": "web-1.example.com", "environment": "production" } ``` # stats.puma > A periodic Puma stats snapshot. Cluster mode records one event per worker. Single mode records one event per cycle. Fields come directly from Puma.stats. A periodic Puma stats snapshot. Cluster mode records one event per worker. Single mode records one event per cycle. Fields come directly from Puma.stats. Source **Puma** Category **Metrics** Fields **10** [honeybadger-ruby](/lib/ruby/) ## Fields 10 | Field | Type | Description | | ---------------- | ------- | ------------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `stats.puma`. | | `worker` | integer | Worker index in cluster mode. Absent in single mode. | | `pool_capacity` | integer | Number of threads available to pick up new requests. | | `max_threads` | integer | Maximum number of threads configured for this worker. | | `requests_count` | integer | Total requests processed by this worker since start. | | `backlog` | integer | Number of connections waiting for a thread. | | `running` | integer | Number of threads currently running. | | `request_id` | string | Rails request UUID, present on any event fired during a web request context. Set by the Honeybadger agent when available. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | ## Example ```json { "event_type": "stats.puma", "worker": 0, "pool_capacity": 3, "max_threads": 5, "requests_count": 18342, "backlog": 0, "running": 5, "request_id": "0f5e4bb2-3c46-4b1c-91d5-2f4e8a6b9c01", "hostname": "web-1.example.com", "environment": "production" } ``` # stats.sidekiq > Sidekiq cluster statistics from the Honeybadger agent. Sidekiq cluster statistics from the Honeybadger agent. Source **Sidekiq** Category **Metrics** Fields **15** [honeybadger-ruby](/lib/ruby/) ## Fields 15 | Field | Type | Description | | ----------------------- | ------- | ----------------------------------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `stats.sidekiq`. | | `processed` | integer | Total jobs processed (lifetime counter). | | `failed` | integer | Total jobs failed (lifetime counter). | | `scheduled_size` | integer | Jobs in the scheduled set. | | `retry_size` | integer | Jobs in the retry set. | | `dead_size` | integer | Jobs in the dead set. | | `processes_size` | integer | Number of running Sidekiq processes. | | `default_queue_latency` | number | Latency of the default queue in seconds (the raw Sidekiq::Stats value; note that per-queue latency under `queues` is reported in milliseconds). | | `capacity` | integer | Total worker thread capacity across all processes. | | `utilization` | number | Worker utilization ratio (0.0–1.0). | | `queues` | object | Per-queue stats keyed by queue name. | | `queues.*` | any | Additional caller-defined keys. | | `request_id` | string | Rails request UUID from the active web request context, if any. Merged globally by the Honeybadger agent. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | ## Example ```json { "event_type": "stats.sidekiq", "processed": 1284512, "failed": 1432, "scheduled_size": 87, "retry_size": 12, "dead_size": 3, "processes_size": 2, "default_queue_latency": 0.42, "capacity": 20, "utilization": 0.35, "queues": { "default": { "latency": 420, "depth": 6, "busy": 5 }, "mailers": { "latency": 0, "depth": 0, "busy": 2 } }, "request_id": "0f5e4bb2-3c46-4b1c-91d5-2f4e8a6b9c01", "hostname": "worker-1.example.com", "environment": "production" } ``` # stats.solid_queue > Solid Queue cluster statistics from the Honeybadger agent. Solid Queue cluster statistics from the Honeybadger agent. Source **Solid Queue** Category **Metrics** Fields **13** [honeybadger-ruby](/lib/ruby/) ## Fields 13 | Field | Type | Description | | -------------------- | ------- | ------------------------------------------------------------------------------------------------------------ | | `event_type` | string | Allowed value: `stats.solid_queue`. | | `jobs_in_progress` | integer | Jobs currently being executed. | | `jobs_blocked` | integer | Jobs blocked waiting on a concurrency limit. | | `jobs_failed` | integer | Jobs in the failed state. | | `jobs_scheduled` | integer | Jobs scheduled for future execution. | | `jobs_processed` | integer | Total jobs processed (lifetime counter). | | `active_workers` | integer | Number of active worker processes. | | `active_dispatchers` | integer | Number of active dispatcher processes. | | `queues` | object | Per-queue depth keyed by queue name. | | `queues.*` | any | Additional caller-defined keys. | | `request_id` | string | Rails request UUID from the active web request context, if any. Merged globally by the Honeybadger agent. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | ## Example ```json { "event_type": "stats.solid_queue", "jobs_in_progress": 4, "jobs_blocked": 2, "jobs_failed": 7, "jobs_scheduled": 156, "jobs_processed": 184329, "active_workers": 2, "active_dispatchers": 1, "queues": { "default": { "depth": 23 }, "mailers": { "depth": 2 } }, "request_id": "0f5e4bb2-3c46-4b1c-91d5-2f4e8a6b9c01", "hostname": "worker-1.example.com", "environment": "production" } ``` # stream_close.active_agent > An ActiveAgent streaming response closed. Honeybadger forwards the ActiveAgent payload as-is, so extra fields depend on your ActiveAgent version and provider. An ActiveAgent streaming response closed. Honeybadger forwards the ActiveAgent payload as-is, so extra fields depend on your ActiveAgent version and provider. Source **Active Agent** Category **LLM** Fields **8** [honeybadger-ruby](/lib/ruby/) ## Fields 8 | Field | Type | Description | | ----------------- | ------ | ------------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `stream_close.active_agent`. | | `trace_id` | string | Trace ID for correlating events within a single agent run. | | `provider` | string | Model provider name. | | `duration` | number | Duration in milliseconds. | | `instrumenter_id` | string | ActiveSupport::Notifications instrumenter UUID, added by the Honeybadger notification subscriber. | | `request_id` | string | Rails request UUID, present on any event fired during a web request context. Set by the Honeybadger agent when available. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | ## Example ```json { "event_type": "stream_close.active_agent", "trace_id": "7c9e6679-7425-40de-944b-e07fc1f90ae7", "provider": "openai", "duration": 1864.92, "instrumenter_id": "d6a5b3f4c2e1908a7b6c", "request_id": "0f5e4bb2-3c46-4b1c-91d5-2f4e8a6b9c01", "hostname": "web-1.example.com", "environment": "production" } ``` # stream_open.active_agent > An ActiveAgent streaming response opened. Honeybadger forwards the ActiveAgent payload as-is, so extra fields depend on your ActiveAgent version and provider. An ActiveAgent streaming response opened. Honeybadger forwards the ActiveAgent payload as-is, so extra fields depend on your ActiveAgent version and provider. Source **Active Agent** Category **LLM** Fields **8** [honeybadger-ruby](/lib/ruby/) ## Fields 8 | Field | Type | Description | | ----------------- | ------ | ------------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `stream_open.active_agent`. | | `trace_id` | string | Trace ID for correlating events within a single agent run. | | `provider` | string | Model provider name. | | `duration` | number | Duration in milliseconds. | | `instrumenter_id` | string | ActiveSupport::Notifications instrumenter UUID, added by the Honeybadger notification subscriber. | | `request_id` | string | Rails request UUID, present on any event fired during a web request context. Set by the Honeybadger agent when available. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | ## Example ```json { "event_type": "stream_open.active_agent", "trace_id": "7c9e6679-7425-40de-944b-e07fc1f90ae7", "provider": "openai", "duration": 412.78, "instrumenter_id": "d6a5b3f4c2e1908a7b6c", "request_id": "0f5e4bb2-3c46-4b1c-91d5-2f4e8a6b9c01", "hostname": "web-1.example.com", "environment": "production" } ``` # tool_call.active_agent > An ActiveAgent tool call ran. Honeybadger forwards the ActiveAgent payload as-is, so extra fields depend on your ActiveAgent version and provider. An ActiveAgent tool call ran. Honeybadger forwards the ActiveAgent payload as-is, so extra fields depend on your ActiveAgent version and provider. Source **Active Agent** Category **LLM** Fields **8** [honeybadger-ruby](/lib/ruby/) ## Fields 8 | Field | Type | Description | | ----------------- | ------ | ------------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `tool_call.active_agent`. | | `trace_id` | string | Trace ID for correlating events within a single agent run. | | `provider` | string | Model provider name. | | `duration` | number | Duration in milliseconds. | | `instrumenter_id` | string | ActiveSupport::Notifications instrumenter UUID, added by the Honeybadger notification subscriber. | | `request_id` | string | Rails request UUID, present on any event fired during a web request context. Set by the Honeybadger agent when available. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | ## Example ```json { "event_type": "tool_call.active_agent", "trace_id": "7c9e6679-7425-40de-944b-e07fc1f90ae7", "provider": "openai", "duration": 35.61, "instrumenter_id": "d6a5b3f4c2e1908a7b6c", "request_id": "0f5e4bb2-3c46-4b1c-91d5-2f4e8a6b9c01", "hostname": "web-1.example.com", "environment": "production" } ``` # unpermitted_parameters.action_controller > Rails strong parameters filtered out unpermitted keys. Rails strong parameters filtered out unpermitted keys. Source **Action Controller** Category **Request** Fields **11** [honeybadger-ruby](/lib/ruby/) ## Fields 11 | Field | Type | Description | | -------------------- | -------------- | ---------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `unpermitted_parameters.action_controller`. | | `keys` | array\ | Parameter keys that were not permitted. | | `context` | object | Request context at the time of the violation. | | `context.controller` | string | | | `context.action` | string | | | `context.request` | object | | | `duration` | number | Duration in milliseconds. | | `instrumenter_id` | string | Rails instrumenter UUID. | | `request_id` | string | Rails request UUID, present on any event fired during a web request context. Merged globally by the Honeybadger agent. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | ## Example ```json { "event_type": "unpermitted_parameters.action_controller", "keys": [ "admin", "role" ], "context": { "controller": "UsersController", "action": "update", "request": { "method": "PATCH", "path": "/users/123" } }, "duration": 0.12, "instrumenter_id": "d6a5b3f4c2e1908a7b6c", "request_id": "0f5e4bb2-3c46-4b1c-91d5-2f4e8a6b9c01", "hostname": "web-1.example.com", "environment": "production" } ``` # write_fragment.action_controller > A Rails fragment cache write. A Rails fragment cache write. Source **Action Controller** Category **Cache** Fields **7** [honeybadger-ruby](/lib/ruby/) ## Fields 7 | Field | Type | Description | | ----------------- | ------ | ---------------------------------------------------------------------------------------------------------------------- | | `event_type` | string | Allowed value: `write_fragment.action_controller`. | | `key` | string | Fragment cache key. | | `duration` | number | Duration in milliseconds. | | `instrumenter_id` | string | | | `request_id` | string | Rails request UUID, present on any event fired during a web request context. Merged globally by the Honeybadger agent. | | `hostname` | string | Server hostname. Attached to every event by default (events.attach\_hostname). | | `environment` | string | Application environment, e.g. "production". Attached to every event by default (events.attach\_environment). | ## Example ```json { "event_type": "write_fragment.action_controller", "key": "views/users/123-20260612143000000000/a1b2c3d4e5f6", "duration": 0.62, "instrumenter_id": "d6a5b3f4c2e1908a7b6c", "request_id": "0f5e4bb2-3c46-4b1c-91d5-2f4e8a6b9c01", "hostname": "web-1.example.com", "environment": "production" } ``` # System event reference > Insights event types emitted by System. System events the Honeybadger CLI agent reports from your servers: CPU, memory, and disk usage. Each entry lists the event's fields with their types, and links to its raw JSON Schema. **3** events emitted by [`honeybadger-cli`](/resources/cli/). *** ### report.system.cpu[](/insights/event-types/system/report.system.cpu/ "View event details")[](/insights/event-types/system/report.system.cpu.schema.json "View JSON Schema") CPU and load average metrics from the Honeybadger CLI agent. Recorded once per reporting interval. | Field | Type | Description | | -------------- | ------- | ------------------------------------------------------------------- | | `event_type` | string | Allowed value: `report.system.cpu`. | | `host` | string | Hostname of the machine running the agent. | | `ts` | string | ISO 8601 timestamp set by the CLI agent at collection time. | | `used_percent` | number | CPU usage as a percentage (0.0–100.0), rounded to 2 decimal places. | | `load_avg_1` | number | 1-minute load average. | | `load_avg_5` | number | 5-minute load average. | | `load_avg_15` | number | 15-minute load average. | | `num_cpus` | integer | Number of logical CPUs. | Example ```json { "event_type": "report.system.cpu", "host": "web-1.example.com", "ts": "2026-06-12T14:30:00Z", "used_percent": 32.85, "load_avg_1": 3.35, "load_avg_5": 3.73, "load_avg_15": 3.86, "num_cpus": 14 } ``` ### report.system.disk[](/insights/event-types/system/report.system.disk/ "View event details")[](/insights/event-types/system/report.system.disk.schema.json "View JSON Schema") Disk partition usage metrics from the Honeybadger CLI agent. Recorded once per non-pseudo partition per reporting interval. | Field | Type | Description | | -------------- | ------- | --------------------------------------------------------------- | | `event_type` | string | Allowed value: `report.system.disk`. | | `host` | string | Hostname of the machine running the agent. | | `ts` | string | ISO 8601 timestamp set by the CLI agent at collection time. | | `mountpoint` | string | Mount point of the partition, e.g. "/" or "/data". | | `device` | string | Device path, e.g. "/dev/sda1". | | `fstype` | string | Filesystem type, e.g. "ext4", "apfs". | | `total_bytes` | integer | Total partition size in bytes. | | `used_bytes` | integer | Used bytes. | | `free_bytes` | integer | Free bytes. | | `used_percent` | number | Usage as a percentage (0.0–100.0), rounded to 2 decimal places. | Example ```json { "event_type": "report.system.disk", "host": "web-1.example.com", "ts": "2026-06-12T14:30:00Z", "mountpoint": "/", "device": "/dev/sda1", "fstype": "ext4", "total_bytes": 107374182400, "used_bytes": 58798465024, "free_bytes": 48575717376, "used_percent": 54.76 } ``` ### report.system.memory[](/insights/event-types/system/report.system.memory/ "View event details")[](/insights/event-types/system/report.system.memory.schema.json "View JSON Schema") Virtual memory metrics from the Honeybadger CLI agent. Recorded once per reporting interval. | Field | Type | Description | | ----------------- | ------- | ---------------------------------------------------------------------- | | `event_type` | string | Allowed value: `report.system.memory`. | | `host` | string | Hostname of the machine running the agent. | | `ts` | string | ISO 8601 timestamp set by the CLI agent at collection time. | | `total_bytes` | integer | Total virtual memory in bytes. | | `used_bytes` | integer | Used memory in bytes. | | `free_bytes` | integer | Free memory in bytes. | | `available_bytes` | integer | Available memory in bytes (free + reclaimable). | | `used_percent` | number | Memory usage as a percentage (0.0–100.0), rounded to 2 decimal places. | Example ```json { "event_type": "report.system.memory", "host": "web-1.example.com", "ts": "2026-06-12T14:30:00Z", "total_bytes": 17179869184, "used_bytes": 11811160064, "free_bytes": 1610612736, "available_bytes": 5368709120, "used_percent": 68.75 } ``` # report.system.cpu > CPU and load average metrics from the Honeybadger CLI agent. Recorded once per reporting interval. CPU and load average metrics from the Honeybadger CLI agent. Recorded once per reporting interval. Category **System** Fields **8** [honeybadger-cli](/resources/cli/) ## Fields 8 | Field | Type | Description | | -------------- | ------- | ------------------------------------------------------------------- | | `event_type` | string | Allowed value: `report.system.cpu`. | | `host` | string | Hostname of the machine running the agent. | | `ts` | string | ISO 8601 timestamp set by the CLI agent at collection time. | | `used_percent` | number | CPU usage as a percentage (0.0–100.0), rounded to 2 decimal places. | | `load_avg_1` | number | 1-minute load average. | | `load_avg_5` | number | 5-minute load average. | | `load_avg_15` | number | 15-minute load average. | | `num_cpus` | integer | Number of logical CPUs. | ## Example ```json { "event_type": "report.system.cpu", "host": "web-1.example.com", "ts": "2026-06-12T14:30:00Z", "used_percent": 32.85, "load_avg_1": 3.35, "load_avg_5": 3.73, "load_avg_15": 3.86, "num_cpus": 14 } ``` # report.system.disk > Disk partition usage metrics from the Honeybadger CLI agent. Recorded once per non-pseudo partition per reporting interval. Disk partition usage metrics from the Honeybadger CLI agent. Recorded once per non-pseudo partition per reporting interval. Category **System** Fields **10** [honeybadger-cli](/resources/cli/) ## Fields 10 | Field | Type | Description | | -------------- | ------- | --------------------------------------------------------------- | | `event_type` | string | Allowed value: `report.system.disk`. | | `host` | string | Hostname of the machine running the agent. | | `ts` | string | ISO 8601 timestamp set by the CLI agent at collection time. | | `mountpoint` | string | Mount point of the partition, e.g. "/" or "/data". | | `device` | string | Device path, e.g. "/dev/sda1". | | `fstype` | string | Filesystem type, e.g. "ext4", "apfs". | | `total_bytes` | integer | Total partition size in bytes. | | `used_bytes` | integer | Used bytes. | | `free_bytes` | integer | Free bytes. | | `used_percent` | number | Usage as a percentage (0.0–100.0), rounded to 2 decimal places. | ## Example ```json { "event_type": "report.system.disk", "host": "web-1.example.com", "ts": "2026-06-12T14:30:00Z", "mountpoint": "/", "device": "/dev/sda1", "fstype": "ext4", "total_bytes": 107374182400, "used_bytes": 58798465024, "free_bytes": 48575717376, "used_percent": 54.76 } ``` # report.system.memory > Virtual memory metrics from the Honeybadger CLI agent. Recorded once per reporting interval. Virtual memory metrics from the Honeybadger CLI agent. Recorded once per reporting interval. Category **System** Fields **8** [honeybadger-cli](/resources/cli/) ## Fields 8 | Field | Type | Description | | ----------------- | ------- | ---------------------------------------------------------------------- | | `event_type` | string | Allowed value: `report.system.memory`. | | `host` | string | Hostname of the machine running the agent. | | `ts` | string | ISO 8601 timestamp set by the CLI agent at collection time. | | `total_bytes` | integer | Total virtual memory in bytes. | | `used_bytes` | integer | Used memory in bytes. | | `free_bytes` | integer | Free memory in bytes. | | `available_bytes` | integer | Available memory in bytes (free + reclaimable). | | `used_percent` | number | Memory usage as a percentage (0.0–100.0), rounded to 2 decimal places. | ## Example ```json { "event_type": "report.system.memory", "host": "web-1.example.com", "ts": "2026-06-12T14:30:00Z", "total_bytes": 17179869184, "used_bytes": 11811160064, "free_bytes": 1610612736, "available_bytes": 5368709120, "used_percent": 68.75 } ``` # Honeybadger client libraries > Official Honeybadger client libraries for error tracking and application monitoring across all major platforms. [Ruby](/lib/ruby/) [JavaScript](/lib/javascript/) [PHP](/lib/php/) [Python](/lib/python/) [Elixir](/lib/elixir/) [Java](/lib/java/) [Go](/lib/go/) [Cocoa](/lib/cocoa/) [.NET/C#](/lib/dotnet/) [Crystal](/lib/crystal/) [Clojure](/lib/clojure/) [Other platforms](/lib/other/) # Honeybadger for Clojure > Honeybadger monitors your Clojure applications for errors and exceptions so that you can fix them wicked fast. **Typical installation time:** \~5 minutes Hi there! You’ve found Honeybadger’s guide to **Clojure exception and error tracking**. Once installed, Honeybadger will report errors in your Clojure application. [Source Code](https://github.com/camdez/honeybadger) ## Getting started [Section titled “Getting started”](#getting-started) The library only has one public endpoint: `notify`. You can pass `notify` a `String`, or anything which inherits from [`Throwable`](https://docs.oracle.com/javase/7/docs/api/java/lang/Throwable.html) (e.g. [`Exception`](https://docs.oracle.com/javase/7/docs/api/java/lang/Exception.html)): ```clj (require '[honeybadger.core :as hb]) (def hb-config {:api-key "PROJECT_API_KEY" :env "development"}) (hb/notify hb-config "Something happened") (hb/notify hb-config (Exception. "Things ain't good")) (hb/notify hb-config (ex-info "99 problems" {:yet "Clojure isn't one of them"})) ``` * `:api-key` is the only required entry in the configuration map. * `notify` returns a [Manifold deferred](https://github.com/ztellman/manifold#deferreds) wrapping the ID (`String`) of the newly-created Honeybadger fault—or `nil` if a filter (see below) caused the data not to be sent to Honeybadger. Because a deferred is used, the call returns immediately, not blocking your (e.g., web server) thread. This comes with the typical [Clojure caveats about exceptions thrown on background threads](http://stuartsierra.com/2015/05/27/clojure-uncaught-exceptions), so I strongly recommend dereferencing these calls on the main thread unless / until you have an async error handling plan in place. * Honeybadger fault IDs can be handy—log them, pass them to other systems, or display them to your users as incident identifiers they can send to your support team. [Manifold](https://github.com/ztellman/manifold) offers ways of receiving this data asynchronously, but for a simple (synchronous) approach, simply [`deref`](https://clojuredocs.org/clojure.core/deref) the return value: ```clj (try ("kaboom") ; Strings aren't functions (catch Exception e (let [hb-id @(hb/notify hb-config e)] (println (str "Exception! Learn more here:\n" "https://www.honeybadger.io/notice/" hb-id))))) ;; (Output) ;; Exception! Learn more here: ;; https://www.honeybadger.io/notice/12345678-669c-4178-b456-be3d0feb1551 ``` ### Metadata [Section titled “Metadata”](#metadata) The optional third parameter to `notify` can be used to pass all manner of additional Honeybadger metadata. The following example shows all possible metadata values: ```clj (hb/notify hb-config (Exception. "Vapor Lock") {:tags [:serious :business] :component "robot-brain" ; ~= a Rails controller :action "think" ; ~= a Rails action :context {:name "Winston" :power 42 :grease 12} :request {:method :get :url "http://camdez.com" :params {"robot" "true"} :session {"session-id" "d34dc0d3"}}}) ``` All metadata is optional, so pick and choose what is useful for your project. Keys and tags can be strings or keywords. `:context` and `:request` support nested values. If you’re working with Ring, use the corresponding [ring-honeybadger](https://github.com/camdez/ring-honeybadger) library and the `:request` metadata will be populated for you. ### Filters [Section titled “Filters”](#filters) For more advanced behavior, the library allows us to provide a sequence of functions which will be invoked with all key details (viz. exception + configuration) prior to reporting to Honeybadger. These functions can be used to transform the data in arbitrary ways, or they can return `nil`, halting the function chain and indicating that nothing should be reported. For maximum flexibility we can provide a custom function, but we can handle many common cases with the preexisting filters / filter combinators in `honeybadger.filter`: ```clj (require '[honeybadger.core :as hb] '[honeybadger.filter :as hbf]) (def hb-config {:api-key "PROJECT_API_KEY" :env "development" :filters [(hbf/only (hbf/env? :production)) (hbf/except (hbf/instance? ArithmeticException)) (hbf/obscure-params [[:config :password]])]}) (hb/notify hb-config "dag, yo") ``` In this example, the first two filters are used to control which errors get reported to Honeybadger, and the third is used to transform the data we *do* send. More precisely, the first two filter lines say *only report errors in the production environment, and don’t report errors of type `ArithmeticException`*. The third filter uses the `obscure-params` convenience function to replace parameters at the given keypaths with a fixed string so that sensitive parameters are not sent to be stored in Honeybadger. (Of course there isn’t a param at `[:config :password]` in this case as we haven’t provided any request metadata, so the filter won’t change anything here). To make filtering both possible and convenient, all details about the error / config / metadata / etc. are bundled up in a consistent format which filters are expected to consume and produce (with the sole exception of filters which return `nil` to suppress reporting of an error). You can see the details of that format at `honeybadger.schemas/Event`, and if you use [Prismatic/schema](https://github.com/Prismatic/schema) in your own project, then you can use the provided schemas to enforce correctness. One detail worth calling out is that all map keys are normalized to keywords so that filters don’t have to handle variations. Here’s an example of a fully-custom filter, applying a `logged-in` tag to all exception reports where we have a `session-id`: ```clj (defn tag-logged-in [e] (if (get-in e [:metadata :request :session :session-id]) (update-in e [:metadata :tags] conj :logged-in) e)) ``` Using that is as simple as adding `tag-logged-in` to the list of filters. Filters that suppress certain errors can typically be written with a simple predicate function over `Event`s which is passed to `only?` or `except?`: ```clj (defn logged-in? [e] (get-in e [:metadata :request :session :session-id])) (def hb-config {;; ... :filters [(hbf/only logged-in?)]}) ``` Last but not least, note that the (deferred) value returned by `notify` allows us to ascertain whether or not a given error was reported because it will be `nil` iff the error reporting was filtered out. We can use this to take conditional actions: ```clj (if-let [hb-id @(hb/notify {:api-key "PROJECT_API_KEY" :filters [(hbf/only (constantly nil))]} "chunky bacon")] (str "Reported error with ID " hb-id) "Error reporting suppressed by filter") ``` ### Ring [Section titled “Ring”](#ring) If you’d like to use this project with Ring, check out [camdez/ring-honeybadger](https://github.com/camdez/ring-honeybadger). # Honeybadger for iOS and MacOS > Honeybadger monitors your iOS and macOS apps for errors and exceptions so that you can fix them wicked fast. **Typical installation time:** \~5 minutes Hi there! You’ve found Honeybadger’s guide to **Cocoa exception and error tracking for iOS and MacOS**. Once installed, Honeybadger will automatically report errors in your iOS/macOS application. ## Getting started [Section titled “Getting started”](#getting-started) ### CocoaPods [Section titled “CocoaPods”](#cocoapods) To install via CocoaPods, create/open your **Pods** file and add a pod entry for **‘Honeybadger’**. Make sure **use\_frameworks!** is specified. ```shell use_frameworks! target 'MyApp' do pod 'Honeybadger' end ``` ### Swift Package Manager [Section titled “Swift Package Manager”](#swift-package-manager) Open your app in Xcode, then go to **File** > **Swift Packages** > **Add Package Dependency**, and specify the Honeybadger Cocoa GitHub repo: **** ### Initialization [Section titled “Initialization”](#initialization) You will need your Honeybadger API key to initialize the Honeybadger library. You can log into your [Honeybadger](https://honeybadger.io) account to obtain your API key. In your App Delegate, import the Honeybadger library: #### Swift [Section titled “Swift”](#swift) ```swift import Honeybadger ``` #### Objective-C [Section titled “Objective-C”](#objective-c) ```objc @import Honeybadger; ``` In your `didFinishLaunchingWithOptions` method, add the following code to initialize Honeybadger: #### Swift [Section titled “Swift”](#swift-1) ```swift Honeybadger.configure(apiKey:"PROJECT_API_KEY") ``` #### Objective-C [Section titled “Objective-C”](#objective-c-1) ```objc [Honeybadger configureWithAPIKey:@"PROJECT_API_KEY"]; ``` ## Usage examples [Section titled “Usage examples”](#usage-examples) Errors and exceptions will be automatically handled by the Honeybadger library, but you can also use the following API to customize error handling in your application. ### notify [Section titled “notify”](#notify) You can use the **notify** methods to manually send an error as a string or Error/NSError object. If available, the Honeybadger library will attempt to extract a stack trace and any relevant information that might be useful. You can also optionally provide **context**, to include any relevant information about the error. #### Swift [Section titled “Swift”](#swift-2) ```swift Honeybadger.notify( errorString: "My error" ); Honeybadger.notify( errorString: "My error", context: ["user_id" : "123abc"] ); Honeybadger.notify( error: MyError("This is my custom error.") ); Honeybadger.notify( error: MyError("This is my custom error."), context: ["user_id" : "123abc"] ); ``` #### Objective-C [Section titled “Objective-C”](#objective-c-2) ```objc [Honeybadger notifyWithString:@"My error"]; [Honeybadger notifyWithString:@"My error" context:@{ @"user_id" : @"123abc" } ]; [Honeybadger notifyWithError: [[NSError alloc] initWithDomain:@"my.test.error" code:-1 userInfo: @{}] ]; [Honeybadger notifyWithError:[[NSError alloc] initWithDomain:@"my.test.error" code:-1 userInfo: @{}] context:@{ @"user_id" : @"123abc" } ]; ``` ### setContext [Section titled “setContext”](#setcontext) If you have data that you would like to include whenever an error or an exception occurs, you can provide that data using the **setContext** method. You can call **setContext** as many times as needed. New context data will be merged with any previously-set context data. #### Swift [Section titled “Swift”](#swift-3) ```swift Honeybadger.setContext(context: ["user_id" : "123abc"]); ``` #### Objective-C [Section titled “Objective-C”](#objective-c-3) ```objc [Honeybadger setContext:@{@"user_id" : @"123abc"}]; ``` ### resetContext [Section titled “resetContext”](#resetcontext) If you’ve used **setContext** to store data, you can use **resetContext** to clear that data. #### Swift [Section titled “Swift”](#swift-4) ```swift Honeybadger.resetContext(); ``` #### Objective-C [Section titled “Objective-C”](#objective-c-4) ```objc [Honeybadger setContext]; ``` # Honeybadger for Crystal > Honeybadger monitors your Crystal applications for errors and exceptions so that you can fix them wicked fast. **Typical installation time:** \~2 minutes Hi there! You’ve found Honeybadger’s guide to **Crystal exception and error tracking**. Once installed, Honeybadger will automatically report errors in your Crystal application. ## Getting started [Section titled “Getting started”](#getting-started) [Source Code](https://github.com/honeybadger-io/honeybadger-crystal) ### Installation [Section titled “Installation”](#installation) Update your `shard.yml` to include honeybadger: ```diff dependencies: honeybadger: github: honeybadger-io/honeybadger-crystal ``` Configure your API key (available under Project Settings in Honeybadger): ```crystal Honeybadger.configure do |config| config.api_key = ENV["HONEYBADGER_API_KEY"]? || "PROJECT_API_KEY" config.environment = ENV["HONEYBADGER_ENVIRONMENT"]? || "production" end ``` ### Reporting errors [Section titled “Reporting errors”](#reporting-errors) #### Reporting errors in web frameworks [Section titled “Reporting errors in web frameworks”](#reporting-errors-in-web-frameworks) If you’re using a web framework, add the `Honeybadger::Handler` to the `HTTP::Server` stack: ```crystal HTTP::Server.new([Honeybadger::Handler.new]) do |context| # ... end ``` Details for adding the handler to: ##### Reporting errors in [Lucky Framework](https://luckyframework.org) [Section titled “Reporting errors in Lucky Framework”](#reporting-errors-in-lucky-framework) 1. Add the shard to `shard.yml` 2. Add `Honeybadger::AuthenticHandler` to your middleware stack: ```crystal require "honeybadger" require "honeybadger/framework_handlers/authentic_handler.cr" def middleware : Array(HTTP::Handler) [ # ... Lucky::ErrorHandler.new(action: Errors::Show), Honeybadger::AuthenticHandler.new, # ... ] of HTTP::Handler end ``` Read more about HTTP Handlers in Lucky [here](https://luckyframework.org/guides/http-and-routing/http-handlers). ##### Reporting errors in [Amber Framework](https://amberframework.org) [Section titled “Reporting errors in Amber Framework”](#reporting-errors-in-amber-framework) Read more about Pipelines in Amber [here](https://docs.amberframework.org/amber/guides/routing/pipelines#sharing-pipelines). #### Reporting errors manually [Section titled “Reporting errors manually”](#reporting-errors-manually) For non-web contexts, or to manually report exceptions to Honeybadger, use `Honeybadger.notify`: ```crystal begin # run application code raise "OH NO!" rescue exception Honeybadger.notify(exception) end ``` ### Identifying users [Section titled “Identifying users”](#identifying-users) Honeybadger can track what users have encountered each error. To identify the current user in error reports, add a user identifier and/or email address to Honeybadger’s `context` hash: ```crystal # Explicit context Honeybadger.notify(exception, context: { "user_id" => user.id, "user_email" => "user@example.com" }) # Managed context Honeybadger.context(user_id: user.id) ``` For an example of identifying users in HTTP handlers, see [demo/http\_context.cr](https://github.com/honeybadger-io/honeybadger-crystal/blob/main/demo/http_context.cr) [Learn more about context data in Honeybadger](https://docs.honeybadger.io/guides/errors/#context-data) ### Sending events to Honeybadger Insights [Section titled “Sending events to Honeybadger Insights”](#sending-events-to-honeybadger-insights) You can send custom events to [Honeybadger Insights](https://docs.honeybadger.io/guides/insights/) to track important business metrics and user actions in your application: ```crystal # Send a simple event Honeybadger.event(name: "user.signup") # Send an event with properties Honeybadger.event( name: "order.completed", total: 99.99, items: ["book", "shirt"], user_id: 123 ) ``` Events are buffered and sent in batches to optimize performance. The buffer is flushed when either: * 60 seconds have elapsed * The buffer size exceeds 5MB Events are sent asynchronously by default, so they won’t block your application’s execution. ## Configuration [Section titled “Configuration”](#configuration) To set configuration options, use the `Honeybadger.configure` method: ```crystal Honeybadger.configure do |config| config.api_key = "PROJECT_API_KEY" config.environment = "production" end ``` The following configuration options are available: | Name | Type | Default | Example | Environment Var | | ------------------------- | ------------- | ----------------------------------- | ------------------------------------ | -------------------------------------- | | api\_key | String | `""` | `"badgers"` | HONEYBADGER\_API\_KEY | | endpoint | Path\|String | `"https://api.honeybadger.io"` | `"https://honeybadger.example.com/"` | HONEYBADGER\_ENDPOINT | | hostname | String | The hostname of the current server. | `"badger"` | HONEYBADGER\_HOSTNAME | | project\_root | String | The current working directory | `"/path/to/project"` | HONEYBADGER\_PROJECT\_ROOT | | report\_data | `bool` | `true` | `false` | HONEYBADGER\_REPORT\_DATA | | development\_environments | Array(String) | \[“development”,“test”] | | HONEYBADGER\_DEVELOPMENT\_ENVIRONMENTS | | environment | String? | `nil` | `"production"` | HONEYBADGER\_ENVIRONMENT | | merge\_log\_context | `bool` | `true` | `false` | n/a | Documentation for context variables can be found [in the Configuration class](https://github.com/honeybadger-io/honeybadger-crystal/blob/main/src/honeybadger/configuration.cr) ### Environment based config [Section titled “Environment based config”](#environment-based-config) Honeybadger can also be configured from environment variables. Each variable has a correlated environment variable and is prefixed with `HONEYBADGER_`. For example: ```plaintext env HONEYBADGER_API_KEY=2468 ./server ``` All environment variables are documented in the configuration table above. ## Version requirements [Section titled “Version requirements”](#version-requirements) Crystal > 0.36.1 # Honeybadger for .NET > Honeybadger monitors your .NET applications for errors and exceptions so that you can fix them wicked fast. **Typical installation time:** \~5 minutes Hi there! You’ve found Honeybadger’s guide to **.NET exception and error tracking**. Once installed, Honeybadger will automatically report errors from your .NET or C# application. ## Getting started [Section titled “Getting started”](#getting-started) [Source Code](https://github.com/honeybadger-io/honeybadger-dotnet) ### Configuration [Section titled “Configuration”](#configuration) The Honeybadger Notifier can be configured using the `HoneybadgerOptions` class. Honeybadger can be configured by passing the options when registering the service, or through your `appsettings.json` file. Honeybadger will attempt to automatically figure out the `ProjectRoot` directory, which should be the root of your project or solution. A valid `ProjectRoot` directory will allow Honeybadger to classify stack frames as either *application* code or *all* other code (e.g. framework code) and hence provide better error reports. See below for examples on how to configure Honeybadger for different types of applications. ### For .NET Core web app [Section titled “For .NET Core web app”](#for-net-core-web-app) #### 1. Install Honeybadger.DotNetCore from NuGet [Section titled “1. Install Honeybadger.DotNetCore from NuGet”](#1-install-honeybadgerdotnetcore-from-nuget) ```sh dotnet add package Honeybadger.DotNetCore ``` #### 2. Register the Honeybadger middleware: [Section titled “2. Register the Honeybadger middleware:”](#2-register-the-honeybadger-middleware) ```c# var builder = WebApplication.CreateBuilder(args); builder.AddHoneybadger(configure => { configure.ApiKey = "PROJECT_API_KEY"; }); ``` Or you can configure Honeybadger through your `appsettings.json` file, by adding a `Honeybadger` section: ```json { "Honeybadger": { "ApiKey": "PROJECT_API_KEY", "AppEnvironment": "Development", "ReportData": true } } ``` Note You should probably set your API key through environment variables or use the Secrets Manager, instead of hardcoding it in the `appsettings.json` file. You can read the [official documentation](https://learn.microsoft.com/en-us/aspnet/core/security/app-secrets) for more information on how to do that in a .Net Core app. And simply call `AddHoneybadger` without any parameters: ```c# var builder = WebApplication.CreateBuilder(args); builder.AddHoneybadger(); ``` #### Usage [Section titled “Usage”](#usage) You can access the *Honeybadger Client* using *DI*: ```c# app.MapGet("/", ([FromServices] IHoneybadgerClient honeybadger) => { honeybadger.AddBreadcrumb("reached index route", "route", new Dictionary()); return "Hello World!"; }); ``` Any unhandled exceptions should be reported to Honeybadger automatically (unless `ReportUnhandledExceptions` is set to `false`): ```c# app.MapGet("/debug", () => { throw new Exception("hello from .Net Core Web App!"); }); ``` See example project in `examples/Honeybadger.DotNetCoreWebApp`. ### As a custom logging provider [Section titled “As a custom logging provider”](#as-a-custom-logging-provider) #### 1. Install Honeybadger.Extensions.Logging from Nuget [Section titled “1. Install Honeybadger.Extensions.Logging from Nuget”](#1-install-honeybadgerextensionslogging-from-nuget) ```sh dotnet add package Honeybadger.Extensions.Logging ``` #### 2. Register Honeybadger and additionally the custom logging provider: [Section titled “2. Register Honeybadger and additionally the custom logging provider:”](#2-register-honeybadger-and-additionally-the-custom-logging-provider) ```c# var builder = WebApplication.CreateBuilder(args); // or set the configuration in the appsettings.json file builder.AddHoneybadger(configure => { configure.ApiKey = "PROJECT_API_KEY"; }); builder.Logging.AddHoneybadger(); ``` You should also configure the minimum log level as you would configure other log providers in .Net Core. The following would report only logged errors: ```json { "Logging": { "Honeybadger": { "Default": "Error" } } } ``` And simply call `AddHoneybadger` and `Logging.AddHoneybadger` without any parameters: ```c# var builder = WebApplication.CreateBuilder(args); builder.AddHoneybadger(); builder.Logging.AddHoneybadger(); ``` #### Usage [Section titled “Usage”](#usage-1) Errors from the `logger` will be reported to Honeybadger: ```c# app.MapGet("/notify", ([FromServices] ILogger logger) => { logger.LogError("hello from Honeybadger.Logger!"); return "Log reported to Honeybadger. Check your dashboard!"; }); ``` See example project in `examples/Honeybadger.DotNetCoreWebApp.Logger`. ### Send a test notification [Section titled “Send a test notification”](#send-a-test-notification) Note Honeybadger, by default, will not report errors in development environments. You can override the development environments by setting the `DevelopmentEnvironments` property in the options. Alternatively, you can set the `ReportData` property to `true` to report errors in all environments. You can send a test notification to Honeybadger to verify that the configuration is working. Add the following to your `Program.cs` file: ```c# // ... builder.AddHoneybadger(); // ... var app = builder.Build(); var honeybadger = app.Services.GetRequiredService(); await honeybadger.NotifyAsync("Hello from .Net!"); ``` Run the app. If the configuration is correctly set, you should see the notification in your Honeybadger dashboard. ### Automatic error reporting [Section titled “Automatic error reporting”](#automatic-error-reporting) Automatic error reporting is enabled by default, but you can disable it by setting the `ReportUnhandledExceptions` property to `false` in `HoneybadgerOptions`: ```json { "Honeybadger": { "ApiKey": "PROJECT_API_KEY", "AppEnvironment": "Development", "ReportData": true, "ReportUnhandledExceptions": false } } ``` ### Using the SDK manually [Section titled “Using the SDK manually”](#using-the-sdk-manually) #### 1. Install the [Honeybadger Nuget](https://www.nuget.org/packages/Honeybadger). [Section titled “1. Install the Honeybadger Nuget.”](#1-install-the-honeybadger-nuget) ```sh dotnet add package Honeybadger ``` #### 2. Initialize the Honeybadger client: [Section titled “2. Initialize the Honeybadger client:”](#2-initialize-the-honeybadger-client) ```c# using Microsoft.Extensions.Options; var options = new HoneybadgerOptions("PROJECT_API_KEY"); var honeybadger = new HoneybadgerClient(Options.Create(options)); ``` #### 3. Call `notify` to report to Honeybadger: [Section titled “3. Call notify to report to Honeybadger:”](#3-call-notify-to-report-to-honeybadger) ```c# // fire and forget honeybadger.Notify("hello from .Net !"); // or async await honeybadger.NotifyAsync("hello from .Net !"); ``` See example project in `examples/Honeybadger.Console`. ## Supported .NET versions [Section titled “Supported .NET versions”](#supported-net-versions) All modern .Net Core applications are supported, up to .Net 9.0. # Honeybadger for Elixir > Honeybadger monitors your Elixir applications for errors and performance bottlenecks so that you can fix them wicked fast. Hi there! You’ve found Honeybadger’s guide to **Elixir error tracking and performance monitoring**. Once installed, Honeybadger will automatically report errors and telemetry in your Elixir application. ## How you should read the docs [Section titled “How you should read the docs”](#how-you-should-read-the-docs) * If you’re installing Honeybadger in your **Phoenix** application for the first time, check out the **[Phoenix Integration Guide](/lib/elixir/integrations/phoenix/)**. If you use a different framework, start with the **[General Integration Guide](/lib/elixir/integrations/other/)** instead. * The **How-To Guides** (in the left-hand navigation menu) are general guides on how to do things with the library, and should apply to all types of applications. * There is a wealth of additional knowledge about Honeybadger in the **Package Reference** and **Support** sections. ## Getting support [Section titled “Getting support”](#getting-support) If you’re having trouble working with the package (such as you aren’t receiving error reports when you should be): 1. Read [Frequently asked questions](/lib/elixir/support/faq/) 2. Upgrade to the latest package version if possible (you can find a list of bugfixes and other changes in the [CHANGELOG](https://github.com/honeybadger-io/honeybadger-elixir/blob/master/CHANGELOG.md)) 3. Run through our [Troubleshooting guide](/lib/elixir/support/troubleshooting/) 4. If you believe you’ve found a bug, [submit an issue on GitHub](https://github.com/honeybadger-io/honeybadger-elixir/issues/) For all other problems, contact support for help: # Breadcrumbs > Add breadcrumbs to Elixir error reports to track events leading up to errors and improve debugging. Breadcrumbs are a useful debugging tool that give you the ability to record contextual data as an event called a `breadcrumb`. When your Project reports an Error (Notice), we send along the breadcrumbs recorded during the execution (request, job, task, etc…). [Context](/lib/elixir/errors/context/) is another way to store extra data to help with debugging. Context is still a great way to attach global data to an error, however, there are scenarios where Breadcrumbs might be a better choice: * You want to record metadata that contains duplicate keys * You want to group related data * You care about when an event happened in relation to an error `Honeybadger.add_breadcrumb/2` appends a breadcrumb to the notice. Use this when you want to add some custom data to your breadcrumb trace in effort to help debugging. If a notice is reported to Honeybadger, all breadcrumbs within the execution path will be appended to the notice. You will be able to view the breadcrumb trace in the Honeybadger interface to see what events led up to the notice. ```elixir Honeybadger.add_breadcrumb("Email sent", metadata: %{ user: user.id, message: message }) ``` # Adding context to errors > Add context to Elixir error reports with custom metadata to improve debugging and error resolution. Honeybadger can display additional custom key/value metadata — or “context” — with each error report. Context is what you’re looking for if: * You want to record the current user’s id or email address at the time of an exception * You need to send raw POST data for use in debugging * You have any other metadata you’d like to send with an exception There are two ways to add context to errors in your code: [global](#global-context) and [local](#local-context). While you can add any key/value data to context, a few keys [have a special meaning in Honeybadger](#special-context-keys). ## Global context [Section titled “Global context”](#global-context) `Honeybadger.context/1` is provided for adding extra data to the notification that gets sent to Honeybadger. You can make use of this in places such as a Plug in your Phoenix Router or Controller to ensure useful debugging data is sent along. ```elixir def MyPhoenixApp.Controller use MyPhoenixApp.Web, :controller plug :set_honeybadger_context def set_honeybadger_context(conn, _opts) do user = get_user(conn) Honeybadger.context(user_id: user.id, account: user.account.name) conn end end ``` `Honeybadger.context/1` stores the context data in the process dictionary, so it will be sent with errors/notifications on the same process. The following `Honeybadger.notify/1` call will not see the context data set in the previous line. ```elixir Honeybadger.context(user_id: 5) Task.start(fn -> # this notify does not see the context set earlier # as this runs in a different elixir/erlang process. Honeybadger.notify(%RuntimeError{message: "critical error"}) end) ``` ## Local context [Section titled “Local context”](#local-context) You can also add context to a manual error report using the `metadata` option, like this: ```elixir context = %{user_id: 5, account_name: "Foo"} Honeybadger.notify(exception, metadata: context, stacktrace: __STACKTRACE__) ``` Local context always overrides any global values when the error is reported. ## Special context keys [Section titled “Special context keys”](#special-context-keys) While you can add any key/value data to context, a few keys have special meaning in Honeybadger: | Option | Description | | ------------ | ----------------------------------------------------------------------------------------------------- | | `user_id` | The `String` user ID used by Honeybadger to aggregate user data across occurrences on the error page. | | `user_email` | Same as `user_id`, but for email addresses | ## Limits [Section titled “Limits”](#limits) Honeybadger uses the following limits to ensure the service operates smoothly for everyone: * Nested objects have a max depth of 20 * Context values have a max size of 64Kb When an error notification includes context data that exceed these limits, the context data will be truncated, and the notification will still be processed. # Customizing error grouping > Customize how errors are grouped in Elixir applications to better organize and prioritize error reports. Honeybadger groups similar exceptions together using rules which we’ve found to work the best in most cases. The default information we use to group errors is: 1. The file name, method name, and line number of the error’s location 2. The class name of the error 3. The component/controller name We use this information to construct a “fingerprint” of the exception. Exceptions with the same fingerprint are treated as the same error in Honeybadger. You can customize the grouping for each exception by changing the error class name, component, or stack trace—or by sending a custom fingerprint. See the [Error Monitoring Guide](https://docs.honeybadger.io/guides/errors/#error-grouping) for more information about how honeybadger groups similar exception together. You can customize the grouping for each exception in Elixir by sending a custom *fingerprint* when the exception is reported. To customize the fingerprint for all exceptions that are reported from your app, use the `fingerprint_adapter` configuration option in `config.ex`: ```elixir config :honeybadger, fingerprint_adapter: MyApp.CustomFingerprint ``` Then, implement the `Honeybadger.FingerprintAdapter` behaviour in your module: ```elixir defmodule MyApp.CustomFingerprint do @behaviour Honeybadger.FingerprintAdapter def parse(notice) do notice.notifier.language <> "-" <> notice.notifier.name end end ``` You can also customize the fingerprint for individual exceptions when calling `Honeybadger.notify`: ```elixir Honeybadger.notify(%RuntimeError{}, fingerprint: "culprit_id-123") ``` # Environments > Configure environment-specific error tracking settings for Elixir applications across development, staging, and production. Honeybadger groups errors by the environment they belong to. You don’t have to set an environment, but it can be useful if you’re running your app in different locations, such as “production” and “staging”. The best way to set the environment is to use [Elixir’s `config_env()` function](https://hexdocs.pm/elixir/main/Config.html#config_env/0) in your `config.exs` file: ```elixir config :honeybadger, environment_name: config_env() ``` You can also configure Honeybadger for each of your Mix environments—for example, by adding the following to each of your `config/#{env}.exs` files in Phoenix: config/dev.exs ```elixir config :honeybadger, environment_name: :dev # config/test.exs config :honeybadger, environment_name: :test # config/prod.exs config :honeybadger, environment_name: :prod ``` Tip Honeybadger’s `environment_name` setting takes precedence over `Mix.env()`. If `environment_name` is not set we will fall back to the value of `Mix.env()`. `Mix.env()` uses the atomized value of the `MIX_ENV` environment variable and defaults to `:prod` when the environment variable is not set. If you want to have an `environment_name` which is different from `Mix.env()` (`:dev`, for example), you should set `environment_name` in your `config.exs` as described above. This ensures that we can give you accurate environment information at compile time. ## Development environments [Section titled “Development environments”](#development-environments) Some environments should usually not report errors at all, such as when you are developing on your local machine or running your test suite (locally or in CI). The *honeybadger* package has an internal list of environment names which it considers development environments: ```plaintext dev test ``` Honeybadger **does not** report errors in these environments. To send data to all environments, you can set the `exclude_envs` configuration option to an empty list: ```elixir config :honeybadger, exclude_envs: [] ``` # Filtering sensitive data > Filter sensitive data from Elixir error reports to protect user privacy and comply with security requirements. You have complete control over the data that Honeybadger reports when an error occurs. Before data is sent to Honeybadger, it is passed through a filter to remove sensitive fields and do other processing on the data. The default configuration is equivalent to: ```elixir config :honeybadger, filter: Honeybadger.Filter.Default, filter_keys: [:password, :credit_card] ``` This will remove any entries in the `context`, `session`, `cgi_data` and `params` that match one of the filter keys. The filter is case insensitive and matches atoms or strings. If `Honeybadger.Filter.Default` does not suit your needs, you can implement your own filter. See the `Honeybadger.Filter.Mixin` module doc for details on implementing your own filter. ## Filtering arguments [Section titled “Filtering arguments”](#filtering-arguments) Honeybadger can show arguments in the stacktrace for `FunctionClauseError` exceptions. To enable argument reporting, set `filter_args` to `false`: ```elixir config :honeybadger, filter_args: false ``` # Reducing noise > Reduce error noise in Elixir applications by ignoring specific errors and filtering unwanted notifications. Sometimes there are errors that you would rather not send to Honeybadger because they are not actionable or are handled internally. By default Honeybadger will be notified when any error occurs. To override this configuration in order not to send out errors to Honeybadger, set `exclude_errors` option in `config/config.exs`. This can be done by passing a list of errors to be excluded: ```elixir config :honeybadger, exclude_errors: ["RuntimeError"] ``` or ```elixir config :honeybadger, exclude_errors: [RuntimeError] ``` Also you can implement the `Honeybadger.ExcludeErrors` behaviour function `exclude_error?/1`, which receives the full `Honeybadger.Notice` and returns a boolean signalling the error exclusion or not. ```elixir defmodule ExcludeFunClauseErrors do alias Honeybadger.ExcludeErrors @behaviour ExcludeErrors @impl ExcludeErrors def exclude_error?(notice) do notice.error.class == "FunctionClauseError" end end ``` ```elixir config :honeybadger, exclude_errors: ExcludeFunClauseErrors ``` # Reporting errors > Report errors from Elixir applications to Honeybadger with automatic notifications and custom error handling. Honeybadger reports uncaught errors automatically. In all other cases, use `Honeybadger.notify/1,2` to send errors to Honeybadger. Use the `Honeybadger.notify/2` function to send exception information to the [Exceptions API](/api/reporting-exceptions/). The first parameter is the exception and the second parameter is the context/metadata/fingerprint. ```elixir try do File.read! "this_file_really_should_exist_dang_it.txt" rescue exception -> Honeybadger.notify(exception, metadata: %{}, stacktrace: __STACKTRACE__, fingerprint: "") end ``` There is also a `Honeybadger.notify/1` which doesn’t require the second parameter. ```elixir Honeybadger.notify("Send this to Honeybadger") ``` # Tagging errors > Add tags to Elixir error reports to categorize and filter errors for better organization and analysis. Each error in Honeybadger has tags. Tags can be used to filter results when searching and can even apply to integrations so that only errors with a combination of certain tags trigger an email or a Slack message, for example. Tags can be used to create custom workflows, such as: * Find all errors tagged “badgers” and resolve them. * Tag critical errors as “critical” and configure PagerDuty to alert you only when a critical error happens. * If you have errors which aren’t actionable (but you still want to know about them), you could tag them with “low\_priority” and exclude those errors when automatically creating issues via the GitHub integration. * Tag all errors that happen in an area of your app with the name of the team that is responsible for them, then notify their Slack channel for only those errors. These are just examples: you can use tags however you want! While you can always add tags to existing errors through the Honeybadger UI, they are most useful when you add them programmatically as the exceptions happen. There are two ways to add tags to errors from your Elixir app: ## Tagging errors in global context [Section titled “Tagging errors in global context”](#tagging-errors-in-global-context) Every exception which is reported within the current context will have the tags “critical” and “badgers” added: ```elixir Honeybadger.context(tags: "critical, badgers") ``` ## Tagging errors in `Honeybadger.notify` [Section titled “Tagging errors in Honeybadger.notify”](#tagging-errors-in-honeybadgernotify) The tags will be added for just the current error being reported: ```elixir context = %{tags: "critical, badgers"} Honeybadger.notify(exception, metadata: context, stacktrace: __STACKTRACE__) ``` # Tracking deployments > Track deployments from Elixir applications to correlate errors with releases and identify problematic code changes. Honeybadger has an API to keep track of project deployments. Whenever you deploy, all errors for that environment will be resolved automatically. You can choose to enable or disable the auto-resolve feature from your Honeybadger project settings page. ## Deploying with GitHub Actions [Section titled “Deploying with GitHub Actions”](#deploying-with-github-actions) If your CI/CD pipeline is hosted with GitHub Actions, you can use the [Honeybadger Deploy Action](https://github.com/marketplace/actions/honeybadger-deploy-action) to notify our API about deployments. ## Deploying with `curl` [Section titled “Deploying with curl”](#deploying-with-curl) ```sh HONEYBADGER_ENV="production" \ HONEYBADGER_REVISION="$(git rev-parse HEAD)" \ HONEYBADGER_REPOSITORY="$(git config --get remote.origin.url)" \ HONEYBADGER_API_KEY="Your project API key" \ && curl -g "https://api.honeybadger.io/v1/deploys?deploy[environment]=$HONEYBADGER_ENV&deploy[local_username]=$USER&deploy[revision]=$HONEYBADGER_REVISION&deploy[repository]=$HONEYBADGER_REPOSITORY&api_key=$HONEYBADGER_API_KEY" ``` If you are using our EU stack, you should use `eu-api.honeybadger.io` instead of `api.honeybadger.io` for the domain name. # Insights overview > Query automatic Phoenix, Ecto, Oban, and Absinthe instrumentation alongside custom application events from Elixir in Honeybadger Insights. [Insights](/guides/insights/) lets you observe what your Elixir application does in production. Honeybadger records common Elixir activity automatically, including Phoenix requests, Ecto queries, LiveView lifecycle events, Oban jobs, Absinthe operations, and Finch and Tesla HTTP calls. From there, you can add context and custom events from your own code, then use [BadgerQL](/guides/insights/badgerql/) to ask questions across the whole event stream. Any field you send is queryable as soon as it arrives, with no schema to define ahead of time. ## Start with automatic instrumentation [Section titled “Start with automatic instrumentation”](#start-with-automatic-instrumentation) Set `insights_enabled: true` in your config and the package starts recording events as soon as your app boots. [Automatic instrumentation](/lib/elixir/insights/automatic-instrumentation/)Configure what the package captures. [Elixir event reference](/insights/event-types/elixir/)See every Elixir event type and field. ## Add a built-in dashboard [Section titled “Add a built-in dashboard”](#add-a-built-in-dashboard) Automatic events power built-in dashboards. [Oban](/guides/dashboards/oban/)Job counts by status, durations by worker, and slowest job runs [Phoenix](/guides/dashboards/phoenix/)Request stats, slowest controllers and Ecto queries, LiveView event performance ## Add application context [Section titled “Add application context”](#add-application-context) Context adds fields to the current process. Once set, every event emitted from that process carries them. Say the app is A/B testing a new checkout flow against the control. Each checkout request sets context like this: Set the variant on context ```elixir Honeybadger.event_context(%{ checkout_variant: checkout_variant }) ``` The `checkout_variant` field is now on every Ecto event for that request. You can group by it like any other field. Ecto work by checkout variant ```badgerql filter event_type::str == "MyApp.Repo.query" and isNotNull(checkout_variant::str) | stats count() as queries, avg(query_time::float) as avg_us by checkout_variant::str | sort queries desc ``` | queries | avg\_us | checkout\_variant | | ------- | ------- | ----------------- | | 26815 | 287 | new | | 11873 | 261 | control | (`MyApp.Repo.query` is the telemetry prefix from your Ecto repo configuration. Substitute your own.) The new variant ran more than twice as many queries with similar per-query time. Keep in mind that adding another A/B variant will extend any of the examples here without the need to change anything on the Honeybadger side. Go deeper: check for possible N+1 queries The package attaches a `request_id` to every event from the same request. To turn total Ecto work into queries per request, group events by `request_id` first to get a per-request count, then aggregate by variant. ```badgerql filter event_type::str == "MyApp.Repo.query" and isNotNull(checkout_variant::str) | stats count() as queries by request_id::str, checkout_variant::str | stats count() as request_count, avg(queries) as avg_q, percentile(95, queries) as p95_q by checkout_variant | sort p95_q desc | only toHumanString(request_count) as requests, toHumanString(avg_q) as avg_queries, toHumanString(p95_q) as p95_queries, checkout_variant ``` | requests | avg\_queries | p95\_queries | checkout\_variant | | -------- | ------------ | ------------ | ----------------- | | 631 | 42.18 | 97 | new | | 638 | 18.61 | 31 | control | The new variant runs more queries per request, and the p95 is much higher than control. That pattern often points at an N+1. [Event context](/lib/elixir/insights/event-context/)Plug setup, process inheritance, and cross-process propagation. ## Record application events [Section titled “Record application events”](#record-application-events) Custom events record activity the framework cannot see at all. Phoenix knows a checkout request ran. Only your app knows whether the payment authorized: Send a custom payment event ```elixir Honeybadger.event("payment.authorized", %{ payment_provider: payment.provider, amount: checkout.total, currency: checkout.currency, authorization_id: payment.authorization_id }) ``` This query breaks down the amounts collected by variant and provider: Payments by variant and provider ```badgerql filter event_type::str == "payment.authorized" | stats count() as authorizations, sum(amount::float) as authorized_amount by checkout_variant::str, payment_provider::str | sort authorized_amount desc ``` | authorizations | authorized\_amount | checkout\_variant | payment\_provider | | -------------- | ------------------ | ----------------- | ----------------- | | 413 | 34108.00 | new | stripe | | 218 | 18722.00 | new | paypal | | 418 | 32167.00 | control | stripe | | 220 | 13639.00 | control | paypal | Go deeper: more insights, same instrumentation Conversion rate by variant ```badgerql filter event_type::str == "payment.authorized" or controller::str == "MyAppWeb.CheckoutsController" | stats count(event_type::str == "payment.authorized") as auth_events by request_id::str, checkout_variant::str | stats count() as auths, count(auth_events > 0) as checkouts, checkouts / auths as conv_rate by checkout_variant::str | only conv_rate, checkout_variant ``` | conv\_rate | checkout\_variant | | ---------- | ----------------- | | 0.92 | new | | 0.86 | control | Revenue per payment provider per variant ```badgerql filter event_type::str == "payment.authorized" | stats sum(amount::float) as total by payment_provider::str, checkout_variant::str | sort total desc | only toHumanString(total) as revenue, payment_provider, checkout_variant ``` | revenue | payment\_provider | checkout\_variant | | ------- | ----------------- | ----------------- | | 34,108 | stripe | new | | 32,167 | stripe | control | | 18,722 | paypal | new | | 13,639 | paypal | control | Average checkout response time by variant ```badgerql filter event_type::str == "phoenix.endpoint.stop" and controller::str == "MyAppWeb.CheckoutsController" | stats avg(duration::float) as avg_us by checkout_variant::str | only toHumanString(avg_us, "microseconds") as avg, checkout_variant ``` | avg | checkout\_variant | | ---- | ----------------- | | 38ms | new | | 15ms | control | Conversion rate over time, by variant ```badgerql filter event_type::str == "payment.authorized" or controller::str == "MyAppWeb.CheckoutsController" | stats count(event_type::str == "payment.authorized") as auth_events, min(@ts) as request_ts by request_id::str, checkout_variant::str | stats count(auth_events > 0) / count() as conv_rate by checkout_variant::str, bin(1h, request_ts) as hour | sort hour asc ``` | conv\_rate | checkout\_variant | hour | | ---------- | ----------------- | ------------------- | | 0.93 | new | 2026-06-26 14:00:00 | | 0.86 | control | 2026-06-26 14:00:00 | | 0.92 | new | 2026-06-26 15:00:00 | | 0.86 | control | 2026-06-26 15:00:00 | | 0.91 | new | 2026-06-26 16:00:00 | | 0.87 | control | 2026-06-26 16:00:00 | The new variant holds a consistent lead over control across the rollout window. [Sending custom events](/lib/elixir/insights/sending-custom-events/)The full Honeybadger.event API. # Automatic instrumentation > Events the Honeybadger Elixir package captures automatically from Ecto, Phoenix, Oban, and more for Honeybadger Insights. Honeybadger Insights allows you to automatically track various events in your application. To enable Insights automatic instrumentation, add the following to your configuration: ```elixir config :honeybadger, insights_enabled: true ``` Honeybadger automatically instruments the following libraries when they are available: * **Ecto**: Database queries * **Plug/Phoenix**: HTTP requests * **LiveView**: Phoenix LiveView lifecycle events * **Oban**: Background job processing * **Absinthe**: GraphQL query execution * **Finch**: HTTP client requests, often used by other libraries like Req * **Tesla**: HTTP client requests The following libraries require additional setup (see [Instrumented libraries](#instrumented-libraries)): * **Ash**: Ash Framework actions and operations See the [Elixir event reference](/insights/event-types/elixir/) for every event the package emits, with field schemas and types. ## Instrumented libraries [Section titled “Instrumented libraries”](#instrumented-libraries) Each instrumented library has its own configuration options. You can customize the telemetry events that are captured, as well as the data that is sent to Honeybadger. *** ### Ecto [Section titled “Ecto”](#ecto) Captures database query telemetry events from Ecto repositories. #### Default configuration [Section titled “Default configuration”](#default-configuration) By default, this module listens for telemetry events from all configured Ecto repositories. It reads the `:ecto_repos` configuration to identify repositories and their telemetry prefixes: ```elixir config :honeybadger, ecto_repos: [MyApp.Repo] ``` #### Custom configuration [Section titled “Custom configuration”](#custom-configuration) You can customize this module’s behavior with the following configuration options: ```elixir config :honeybadger, insights_config: %{ ecto: %{ # Disable Ecto telemetry events disabled: false, # A list of strings or regex patterns of queries to exclude excluded_queries: [ ~r/^(begin|commit)( immediate)?( transaction)?$/i, ~r/SELECT pg_notify/, ~r/schema_migrations/ ], # Format & include the stacktrace with each query. You must also # update your repo config to enable: # # config :my_app, MyApp.Repo, # stacktrace: true # # Can be a boolean to enable for all or a list of sources to enable. include_stacktrace: true # Alternative source whitelist example: # include_stacktrace: ["source_a", "source_b"], # Format & include the query parameters with each query. Can be a # boolean to enable for all or a list of sources to enable. include_params: true # Alternative source whitelist example: # include_params:["source_a", "source_b"], # A list of table/source names to exclude excluded_sources: [ "schema_migrations", "oban_jobs", "oban_peers" ] } } ``` By default, transaction bookkeeping queries and schema migration checks are excluded, as well as queries to common background job tables. *** ### Plug/Phoenix [Section titled “Plug/Phoenix”](#plugphoenix) Captures telemetry events from HTTP requests processed by Plug and Phoenix. #### Default configuration [Section titled “Default configuration”](#default-configuration-1) By default, this module listens for the standard Phoenix endpoint telemetry event: * `phoenix.endpoint.stop` This is compatible with the default Phoenix configuration that adds telemetry via `Plug.Telemetry`: plug Plug.Telemetry, event\_prefix: \[:my, :prefix] #### Custom configuration [Section titled “Custom configuration”](#custom-configuration-1) You can customize the telemetry events to listen for by updating the insights\_config: ```elixir config :honeybadger, insights_config: %{ plug: %{ # Disable Plug/Phoenix telemetry events disabled: false, telemetry_events: [[:my, :prefix, :stop]] } } ``` *** ### LiveView [Section titled “LiveView”](#liveview) Captures telemetry events from Phoenix LiveView. #### Default configuration [Section titled “Default configuration”](#default-configuration-2) By default, this module listens for the following LiveView telemetry events: * `phoenix.live_view.mount.stop` * `phoenix.live_view.handle_params.stop` * `phoenix.live_view.handle_event.stop` * `phoenix.live_component.update.stop` * `phoenix.live_component.handle_event.stop` #### Custom configuration [Section titled “Custom configuration”](#custom-configuration-2) You can customize the telemetry events to listen for by updating the insights\_config: ```elixir config :honeybadger, insights_config: %{ live_view: %{ # Disable LiveView telemetry events disabled: false, telemetry_events: [ [:phoenix, :live_view, :mount, :stop], [:phoenix, :live_component, :handle_event, :stop], [:phoenix, :live_component, :update, :stop] [:phoenix, :live_view, :handle_event, :stop], [:phoenix, :live_view, :handle_params, :stop], [:phoenix, :live_view, :update, :stop] ] } } ``` *** ### Oban [Section titled “Oban”](#oban) Captures telemetry events from Oban job processing. #### Default configuration [Section titled “Default configuration”](#default-configuration-3) By default, this module listens for the following Oban telemetry events: * `oban.job.stop` * `oban.job.exception` #### Custom configuration [Section titled “Custom configuration”](#custom-configuration-3) You can customize the telemetry events to listen for by updating the insights\_config: ```elixir config :honeybadger, insights_config: %{ oban: %{ # Disable Oban telemetry events disabled: false, telemetry_events: [ [:oban, :job, :stop], [:oban, :job, :exception], [:oban, :engine, :start] ] } } ``` #### Job event context [Section titled “Job event context”](#job-event-context) We attempt to automatically inject `request_id` and any other event context into events emitted from a Job. The method for inheriting event context might not work in all cases, so you can explicitly add event context to a job by using the `add_event_context/1` function: ```elixir MyApp.Worker.new() |> Honeybadger.Insights.Oban.add_event_context() |> Oban.insert() ``` Ensure that the event context is available in the caller’s process dictionary before inserting into the job. *** ### Absinthe [Section titled “Absinthe”](#absinthe) Captures telemetry events from GraphQL operations executed via Absinthe. #### Default configuration [Section titled “Default configuration”](#default-configuration-4) By default, this module listens for the following Absinthe telemetry events: * `absinthe.execute.operation.stop` * `absinthe.execute.operation.exception` #### Custom configuration [Section titled “Custom configuration”](#custom-configuration-4) You can customize the telemetry events to listen for by updating the insights\_config: ```elixir config :honeybadger, insights_config: %{ absinthe: %{ # Disable Absinthe telemetry events disabled: false, telemetry_events: [ [:absinthe, :execute, :operation, :stop], [:absinthe, :execute, :operation, :exception], [:absinthe, :resolve, :field, :stop] ] } } ``` Note that adding field-level events like “absinthe.resolve.field.stop” can significantly increase the number of telemetry events generated. *** ### Finch [Section titled “Finch”](#finch) Captures telemetry events from HTTP requests made using Finch. #### Default configuration [Section titled “Default configuration”](#default-configuration-5) By default, this module listens for the standard Finch request telemetry event: * `finch.request.stop` #### Custom configuration [Section titled “Custom configuration”](#custom-configuration-5) You can customize the telemetry events to listen for by updating the insights\_config: ```elixir config :honeybadger, insights_config: %{ finch: %{ # Disable Finch telemetry events disabled: false, telemetry_events: ["finch.request.stop", "finch.request.exception"], # Include full URLs in telemetry events (default: false - only hostname is included) full_url: false } } ``` By default, only the hostname from URLs is captured for security and privacy reasons. If you need to capture the full URL including paths (but not query parameters), you can enable the `full_url` option. *** ### Tesla [Section titled “Tesla”](#tesla) Captures telemetry events from HTTP requests made using Tesla. #### Default configuration [Section titled “Default configuration”](#default-configuration-6) By default, this module listens for the standard Tesla request telemetry events: * `tesla.request.stop` * `tesla.request.exception` #### Custom configuration [Section titled “Custom configuration”](#custom-configuration-6) This module can be configured in the application config: ```elixir config :honeybadger, insights_config: %{ tesla: %{ # Disable Tesla telemetry events disabled: false, # Include full URLs in telemetry events (default: false - only hostname is included) full_url: false, # Custom telemetry event patterns to listen for (optional) telemetry_events: [ [:tesla, :request, :stop], [:tesla, :request, :exception] ] } } ``` *** ### Ash [Section titled “Ash”](#ash) Captures operations from the [Ash Framework](https://ash-hq.org/) using the `Ash.Tracer` behaviour. Unlike the other integrations which use telemetry events, the Ash integration implements a tracer. You need to add `Honeybadger.Insights.Ash` as a tracer in your Ash domain or resources. #### Setup [Section titled “Setup”](#setup) Add the tracer to your Ash domain: ```elixir use Ash.Domain, tracers: [Honeybadger.Insights.Ash] ``` Or per-resource: ```elixir use Ash.Resource, domain: YourDomain, tracers: [Honeybadger.Insights.Ash] ``` #### Default configuration [Section titled “Default configuration”](#default-configuration-7) By default, this module traces `:custom` and `:action` span types. #### Custom configuration [Section titled “Custom configuration”](#custom-configuration-7) You can customize which span types are traced via insights\_config: ```elixir config :honeybadger, insights_config: %{ ash: %{ trace_types: [:custom, :action, :query] } } ``` #### AshOban event context [Section titled “AshOban event context”](#ashoban-event-context) If you use [AshOban](https://hexdocs.pm/ash_oban) to run Ash actions as background jobs, you can pass the current Honeybadger event context to the job using the `extra_args` option in your trigger: ```elixir oban do triggers do trigger :my_trigger do action :my_action extra_args(&Honeybadger.Insights.Ash.AshOban.capture_event_context/1) end end end ``` The Honeybadger Oban integration will automatically restore the event context when the job runs, preserving request IDs and other context across async boundaries. ## Sending your own events [Section titled “Sending your own events”](#sending-your-own-events) Automatic instrumentation covers the libraries the package knows about. To send your own application events, see [Sending custom events](/lib/elixir/insights/sending-custom-events/). ## Sending logs from your infrastructure [Section titled “Sending logs from your infrastructure”](#sending-logs-from-your-infrastructure) Honeybadger isn’t just for errors and application data! You can use our [syslog](/guides/insights/integrations/systemd/), [Vector](/guides/insights/integrations/log-files/), or [PaaS integrations](/guides/insights/#adding-data-from-other-sources) to send additional data from your infrastructure to [Honeybadger Insights](/guides/insights/), where you can query, visualize, and analyze all of your production data in one place. # Event context > Add contextual data to Insights events in Elixir to improve debugging and understanding of application behavior. You can add custom metadata to the events sent to Honeybadger Insights by using the `event_context/1` function. This metadata will be included in each event call within the same process. Note: This will add the metadata to all events sent, so be careful not to include too much data. Try to keep it to simple key/value pairs. For example, you can add user ID information to all events (via plug): ```elixir defmodule MyAppWeb.Plug.UserContext do import Plug.Conn def init(opts), do: opts def call(conn, _opts) do user = get_session(conn, :user) Honeybadger.event_context(%{user_id: user.id}) conn end end ``` Event context is not automatically propagated to other processes. If you want to add context to events in a different process, you can use the `Honeybadger.event_context/0` function to get the current context and pass it to the `Honeybadger.event/1` function: ```elixir defmodule MyApp.MyGenServer do use GenServer def set(value) do GenServer.cast(__MODULE__, {:set, value, Honeybadger.event_context()}) end def handle_cast({:set, value, hb_context}, _state) do Honeybadger.event_context(hb_context) Honeybadger.event("set_value", %{value: value}) {:noreply, value} end end ``` ## Inheriting context [Section titled “Inheriting context”](#inheriting-context) If you know the parent process is alive and part of the process tree, you can use `Honeybadger.inherit_event_context/0` to inherit the context from the parent process. This method works best if you are running OTP 25+. ```elixir Task.async(fn -> Honeybadger.inherit_event_context() # Do some work here Honeybadger.event("work", %{did: "some_work"}) end) ``` Scenarios when inheriting context is useful include: * Direct process spawning (`spawn`, `spawn_link`) * `Task.async/1`, `Task.await/1`, etc. * Other scenarios where direct parent-child relationships are maintained When explicit passing is needed: * GenServer * Supervised processes * Processes started through other OTP abstractions # Filtering events > Filter Insights events in Elixir applications to reduce noise and focus on relevant data. You can filter out or customize events sent to Honeybadger Insights by using the `Honeybadger.EventFilter.Mixin` module. You can customize both the event built from telemetry data (`filter_telemetry_event/3`) and the event right before it is sent to Honeybadger (`filter_event/1`): ```elixir defmodule MyApp.MyFilter do use Honeybadger.EventFilter.Mixin # Drop analytics events by returning nil def filter_event(%{event_type: "analytics"} = _event), do: nil # Anonymize user data in login events def filter_event(%{event_type: "login"} = event) do event |> update_in([:data, :user_email], fn _ -> "[REDACTED]" end) |> put_in([:metadata, :filtered], true) end # Remove query field for a specific repo def filter_event(%{event_type: "my_app.repo.query"} = event) do Map.delete(event, :query) |> put_in([:metadata, :filtered], true) end # For telemetry events, you can customize while still applying default filtering def filter_telemetry_event(data, raw, event) do # First apply default filtering filtered_data = apply_default_telemetry_filtering(data) # Then apply custom logic case event do [:auth, :login, :start] -> Map.put(filtered_data, :security_filtered, true) _ -> filtered_data end end # Keep all other events as they are def filter_event(event), do: event end ``` Then configure the filter in your application’s configuration: ```elixir config :honeybadger, event_filter: MyApp.EventFilter ``` # Sampling events > Configure event sampling in Elixir to control Insights data volume while maintaining statistical accuracy. You can enable event sampling to reduce the number of events sent to Honeybadger. This is especially useful if you are hitting your daily event quota limit: ```elixir config :honeybadger, # Sample 50% of events insights_sample_rate: 50 ``` The `insights_sample_rate` option accepts a whole percentage value between 0 and 100, where 0 means no events will be sent and 100 means all events will be sent. The default is no sampling (100%). Events are sampled by hashing the `request_id` if available in the event payload, otherwise random sampling is used. This deterministic approach ensures that related events from the same request are consistently sampled together. ## Per-event sampling [Section titled “Per-event sampling”](#per-event-sampling) The sample rate is applied to all events sent to Honeybadger Insights, including automatic instrumentation events. You can also set the sample rate per event by adding the `sample_rate` key to the event metadata map: ```elixir Honeybadger.event("user_created", %{ user_id: user.id, _hb: %{sample_rate: 100} }) ``` The event sample rate can also be set within the `event_context/1` function. This can be handy if you want to set an overall sample rate for a process or ensure that specific instrumented events get sent: ```elixir # Set a higher sampling rate for this entire process Honeybadger.event_context(%{_hb: %{sample_rate: 100}}) # Now all events from this process, including automatic instrumentation, # will use the 100% sample rate Ecto.Repo.insert!(%MyApp.User{}) # This instrumented event will be sent ``` Remember that context is process-bound and applies to all events sent from the same process after the `event_context/1` call, until it’s changed or the process terminates. When setting sample rates below the global setting, be aware that this affects how events with the same `request_id` are sampled. Since sampling is deterministic based on the `request_id` hash, all events sharing the same `request_id` will either all be sampled or all be skipped together. This ensures consistency across related events. With that in mind, it’s recommended to default to the global sample rate and use per-event sampling for specific cases where you want to ensure events are sent regardless of the global setting, or you are setting the sample rate in the context where all events with the same `request_id` will also share the same sampling rate. # Sending custom events > Send custom events from Elixir applications to Honeybadger Insights for monitoring and analysis. You can send your own application events to [Honeybadger Insights](/guides/insights/). (For the events the package captures on its own, see [Automatic instrumentation](/lib/elixir/insights/automatic-instrumentation/).) Use the `Honeybadger.event/1` function to send event data to the events API. A `ts` field with the current timestamp will be added to the data if it isn’t provided. You can also use `Honeybadger.event/2`, which accepts a string as the first parameter and adds that value to the `event_type` field in the map before being sent to the API. ```elixir Honeybadger.event(%{ event_type: "user_created", user: user.id }) Honeybadger.event("project_deleted", %{ project: project.name }) ``` # Elixir integration guide > Install and configure Honeybadger error tracking and application monitoring for Elixir applications outside of Phoenix and Plug frameworks. **Typical installation time:** 5 minutes Hi there! You’ve found Honeybadger’s guide to **Elixir error tracking and performance monitoring**. If you use *Phoenix* or *Plug*, go check out the [Phoenix Integration Guide](../phoenix/). If not, then read on. This guide will teach you how to install the `honeybadger` Hex package in your Elixir project and use it to manually report errors to Honeybadger. You can also enable some [automatic logging and performance insights](/lib/elixir/insights/automatic-instrumentation/) (via telemetry) by setting the `insights_enabled` option to `true` in your configuration. On this page: ## Installing the package [Section titled “Installing the package”](#installing-the-package) Add the Honeybadger package to `deps/0` in your application’s `mix.exs`: ```elixir defp deps do [{:honeybadger, "~> 0.24"}] end ``` Then run: ```sh mix do deps.get, deps.compile ``` Finally, update your app’s `config.exs` file to include the Honeybadger configuration: ```elixir config :honeybadger, app: :my_app, api_key: "PROJECT_API_KEY", environment_name: config_env(), insights_enabled: true # Enable logging and performance insights ``` Tip Set `app` to your OTP application name (the `app` value in your `mix.exs`). Honeybadger uses this to highlight your app’s code in backtraces, making it easier to distinguish your code from library and framework code. Tip You can also configure your API key using the `HONEYBADGER_API_KEY` environment variable: ```sh export HONEYBADGER_API_KEY="PROJECT_API_KEY" ``` If you use this method, you can omit the `api_key` option from your configuration. See the [Configuration reference](/lib/elixir/reference/configuration/) for additional info. ## Testing your installation [Section titled “Testing your installation”](#testing-your-installation) Note Honeybadger does not report errors in `dev` and `test` environments by default. To enable reporting in development environments, temporarily add `exclude_envs: []` to your Honeybadger config. To test your installation, fire up `iex -S mix`, then run: ```elixir Honeybadger.notify("Hello Elixir!") ``` If Honeybadger is configured correctly, you should see a new error report in your Honeybadger project dashboard. ## Configuring Elixir’s logger [Section titled “Configuring Elixir’s logger”](#configuring-elixirs-logger) When configured, Honeybadger will report errors for any [SASL](http://www.erlang.org/doc/apps/sasl/error_logging.html)-compliant processes when they crash. Just set the `use_logger` option to `true` in your application’s `config.exs` and you’re good to go: ```elixir config :honeybadger, use_logger: true ``` ## Manually reporting errors [Section titled “Manually reporting errors”](#manually-reporting-errors) You can use the `Honeybadger.notify/2` function to manually report rescued exceptions: ```elixir try do # Buggy code goes here rescue exception -> Honeybadger.notify(exception, stacktrace: __STACKTRACE__) end ``` You can also pass a string message to the `notify` function (the second argument is optional): ```elixir Honeybadger.notify("Sign in failed", metadata: %{ user_id: current_user.id }) ``` See [Reporting Errors](/lib/elixir/errors/reporting-errors/) for more information. ## Reporting custom events [Section titled “Reporting custom events”](#reporting-custom-events) Use the `Honeybadger.event/1` and `Honeybadger.event/2` functions to send events to [Honeybadger Insights](/guides/insights/) for logging and performance monitoring: ```elixir Honeybadger.event(%{ event_type: "user_created", user: user.id }) # Honeybadger.event/2 is a shorthand that automatically adds the event_type # property to the event: Honeybadger.event("project_deleted", %{ project: project.name }) ``` See [Sending custom events](/lib/elixir/insights/sending-custom-events/) for more details. ## Sending logs from your infrastructure [Section titled “Sending logs from your infrastructure”](#sending-logs-from-your-infrastructure) Honeybadger isn’t just for errors and application data! You can use our [syslog](/guides/insights/integrations/systemd/), [Vector](/guides/insights/integrations/log-files/), or [PaaS integrations](/guides/insights/#adding-data-from-other-sources) to send additional data from your infrastructure to [Honeybadger Insights](/guides/insights/), where you can query, visualize, and analyze all of your production data in one place. ## Version requirements [Section titled “Version requirements”](#version-requirements) See [Supported Versions](/lib/elixir/reference/supported-versions/). # Phoenix and Plug integration guide > Install and configure Honeybadger application monitoring for Phoenix and Plug applications with automatic error reporting. **Typical installation time:** 5 minutes Hi there! You’ve found Honeybadger’s guide to **Phoenix error tracking and performance monitoring**. Once installed, Honeybadger will automatically report errors and performance insights from your Phoenix application. ## Installing the package [Section titled “Installing the package”](#installing-the-package) Add the Honeybadger package to `deps/0` in your application’s `mix.exs`: ```elixir defp deps do [{:honeybadger, "~> 0.24"}] end ``` Then run: ```sh mix do deps.get, deps.compile ``` Finally, update your app’s `config.exs` file to include the Honeybadger configuration: ```elixir config :honeybadger, app: :my_app, api_key: "PROJECT_API_KEY", environment_name: config_env(), insights_enabled: true # Enable logging and performance insights ``` Tip Set `app` to your OTP application name (the `app` value in your `mix.exs`). Honeybadger uses this to highlight your app’s code in backtraces, making it easier to distinguish your code from library and framework code. Tip You can also configure your API key using the `HONEYBADGER_API_KEY` environment variable: ```sh export HONEYBADGER_API_KEY="PROJECT_API_KEY" ``` If you use this method, you can omit the `api_key` option from your configuration. See the [Configuration reference](/lib/elixir/reference/configuration/) for additional info. ## Testing your installation [Section titled “Testing your installation”](#testing-your-installation) Note Honeybadger does not report errors in `dev` and `test` environments by default. To enable reporting in development environments, temporarily add `exclude_envs: []` to your Honeybadger config. To test your installation, fire up `iex -S mix`, then run: ```elixir Honeybadger.notify("Hello Elixir!") ``` If Honeybadger is configured correctly, you should see a new error report in your Honeybadger project dashboard. After you’ve tested your Honeybadger installation, you may want to configure one or more of the following integrations to automatically report errors. ## Enabling automatic error reporting [Section titled “Enabling automatic error reporting”](#enabling-automatic-error-reporting) The Honeybadger package can be used as a Plug alongside your Phoenix applications, as a logger backend, and/or as a standalone client for sprinkling in exception notifications where they are needed. The Honeybadger Plug adds a [Plug.ErrorHandler](https://github.com/elixir-lang/plug/blob/master/lib/plug/error_handler.ex) to your pipeline. Simply `use` the `Honeybadger.Plug` module inside of a Plug or Phoenix.Router and any crashes will be automatically reported to Honeybadger. It’s best to `use Honeybadger.Plug` **after the Router plugs** so that exceptions due to non-matching routes are not reported to Honeybadger. ### Phoenix example [Section titled “Phoenix example”](#phoenix-example) ```elixir defmodule MyappWeb.Router do use MyappWeb, :router use Honeybadger.Plug pipeline :browser do [...] end end ``` ### Plug example [Section titled “Plug example”](#plug-example) ```elixir defmodule MyPlugApp do use Plug.Router use Honeybadger.Plug [... the rest of your plug ...] end ``` ### Configuring Elixir’s logger [Section titled “Configuring Elixir’s logger”](#configuring-elixirs-logger) When configured, Honeybadger will report errors for any [SASL](http://www.erlang.org/doc/apps/sasl/error_logging.html)-compliant processes when they crash. Just set the `use_logger` option to `true` in your application’s `config.exs` and you’re good to go: ```elixir config :honeybadger, use_logger: true ``` ## Manually reporting errors [Section titled “Manually reporting errors”](#manually-reporting-errors) You can use the `Honeybadger.notify/2` function to manually report rescued exceptions: ```elixir try do # Buggy code goes here rescue exception -> Honeybadger.notify(exception, stacktrace: __STACKTRACE__) end ``` You can also pass a string message to the `notify` function (the second argument is optional): ```elixir Honeybadger.notify("Sign in failed", metadata: %{ user_id: current_user.id }) ``` See [Reporting Errors](/lib/elixir/errors/reporting-errors/) for more information. ## Reporting custom events [Section titled “Reporting custom events”](#reporting-custom-events) Use the `Honeybadger.event/1` and `Honeybadger.event/2` functions to send events to [Honeybadger Insights](/guides/insights/) for logging and performance monitoring: ```elixir Honeybadger.event(%{ event_type: "user_created", user: user.id }) # Honeybadger.event/2 is a shorthand that automatically adds the event_type # property to the event: Honeybadger.event("project_deleted", %{ project: project.name }) ``` See [Sending custom events](/lib/elixir/insights/sending-custom-events/) for more details. ## Sending logs from your infrastructure [Section titled “Sending logs from your infrastructure”](#sending-logs-from-your-infrastructure) Honeybadger isn’t just for errors and application data! You can use our [syslog](/guides/insights/integrations/systemd/), [Vector](/guides/insights/integrations/log-files/), or [PaaS integrations](/guides/insights/#adding-data-from-other-sources) to send additional data from your infrastructure to [Honeybadger Insights](/guides/insights/), where you can query, visualize, and analyze all of your production data in one place. ## Version requirements [Section titled “Version requirements”](#version-requirements) See [Supported Versions](/lib/elixir/reference/supported-versions/). # Configuration > Complete configuration reference for Honeybadger's Elixir library with all available options and settings. You can set configuration options in `config.exs`. It looks like this: ```elixir config :honeybadger, api_key: "PROJECT_API_KEY", environment_name: :prod ``` If you’d rather read, eg., `environment_name` from the OS environment, you can do like this: ```elixir config :honeybadger, environment_name: {:system, "HONEYBADGER_ENV"}, revision: {:system, "HEROKU_SLUG_COMMIT"} ``` *NOTE: This works only for the string options, and `environment_name`.* Here are all of the options you can pass in the keyword list: | Name | Description | Default | | -------------------------- | -------------------------------------------------------------------------------------------- | --------------------------------------------------------------- | | `app` | Name of your app’s OTP Application as an atom | `nil` | | `api_key` | Your application’s Honeybadger API key | `System.get_env("HONEYBADGER_API_KEY")` | | `environment_name` | (required) The name of the environment your app is running in. | `:prod` | | `exclude_errors` | Filters out errors from being sent to Honeybadger | `[]` | | `exclude_envs` | Environments that you want to disable Honeybadger notifications | `[:dev, :test]` | | `hostname` | Hostname of the system your application is running on | `:inet.gethostname` | | `origin` | URL for the Honeybadger API | `"https://api.honeybadger.io"` | | `project_root` | Directory root for where your application is running | `System.cwd/0` | | `revision` | The project’s git revision | `nil` | | `filter` | Module implementing `Honeybadger.Filter` to filter data before sending to Honeybadger.io | `Honeybadger.Filter.Default` | | `filter_keys` | A list of keywords (atoms) to filter. Only valid if `filter` is `Honeybadger.Filter.Default` | `[:password, :credit_card, :__changed__, :flash, :_csrf_token]` | | `filter_args` | If true, will remove function arguments in backtraces | `true` | | `filter_disable_url` | If true, will remove the request url | `false` | | `filter_disable_session` | If true, will remove the request session | `false` | | `filter_disable_params` | If true, will remove the request params | `false` | | `filter_disable_assigns` | If true, will remove the live\_view event assigns | `false` | | `fingerprint_adapter` | Implementation of FingerprintAdapter behaviour | | | `notice_filter` | Module implementing `Honeybadger.NoticeFilter`. If `nil`, no filtering is done. | `Honeybadger.NoticeFilter.Default` | | `sasl_logging_only` | If true, will notifiy for SASL errors but not Logger calls | `true` | | `use_logger` | Enable the Honeybadger Logger for handling errors outside of web requests | `true` | | `ignored_domains` | Add domains to ignore Error events in `Honeybadger.Logger`. | `[:cowboy]` | | `breadcrumbs_enabled` | Enable breadcrumb event tracking | `false` | | `ecto_repos` | Modules with implemented Ecto.Repo behaviour for tracking SQL breadcrumb events | `[]` | | `event_filter` | Module implementing `Honeybadger.EventFilter`. If `nil`, no filtering is done. | `Honeybadger.EventFilter.Default` | | `insights_enabled` | Enable sending automatic events to Honeybadger Insights | `false` | | `insights_config` | Specific library Configuration for Honeybadger Insights. | `%{}` | | `http_adapter` | Module implementing `Honeybadger.HttpAdapter` to send data to Honeybadger.io | Any available adapter (`Req`, `hackney`) | | `events_worker_enabled` | Enable sending events in a separate process | `true` | | `events_max_batch_retries` | Maximum number of retries for sending events | `3` | | `events_batch_size` | Maximum number of events to send in a single batch | `1000` | | `events_max_queue_size` | Maximum number of events to queue before dropping | `10000` | | `events_timeout` | Timeout in milliseconds for sending events | `5000` | | `events_throttle_wait` | Time in milliseconds to wait before retrying a failed batch | `60000` | ## HTTP adapters [Section titled “HTTP adapters”](#http-adapters) The HTTP client used to send data to Honeybadger can be customized. We will use either `Req` or `hackney` (in that order) by default if they are loaded. If you want to use a different HTTP client, you can set the `http_adapter` configuration option to any of our pre-built adapter modules. ```elixir config :honeybadger, # Without options http_adapter: Honeybadger.HTTPAdapter.Hackney # With options http_adapter: {Honeybadger.HTTPAdapter.Hackney, [...]} ``` You can also implement your own HTTP adapter to send data to Honeybadger. The adapter must implement the `Honeybadger.HttpAdapter` behaviour. # Supported Versions > View supported Elixir and Phoenix versions for Honeybadger's error tracking and application monitoring library. The support tables below are for the latest version of the Honeybadger package, which aims to support all maintained (non-EOL) versions of Elixir and supported frameworks. If you’re using an older version of Elixir or your framework, you may need to install an older version of the package. | Library | Supported Version | Notes | | ------- | ----------------- | ------------------------------------------------------------------------------------------------- | | Erlang | >= 26.0 | | | Elixir | >= 1.16 | | | Plug | >= 1.10 | | | Phoenix | >= 1.0 | This is an optional dependency and the version requirement applies only if you are using Phoenix. | # Frequently asked questions > Find answers to frequently asked questions about Honeybadger's Elixir library for error tracking and application monitoring. ## Why aren’t my errors being reported? [Section titled “Why aren’t my errors being reported?”](#why-arent-my-errors-being-reported) The most common reason for errors not being reported is that the app is in a development environment. See the [Environments](/lib/elixir/errors/environments/#development-environments) chapter in the **Error Tracking** guide for more information. The second most common reason is that the error being reported is covered by the [exclude\_errors list](/lib/elixir/errors/reducing-noise/). If neither of these is the issue, check out the [Troubleshooting guide](/lib/elixir/support/troubleshooting/#all-errors-are-not-reported). ## Why aren’t I getting notifications? [Section titled “Why aren’t I getting notifications?”](#why-arent-i-getting-notifications) By default we only send notifications the first time an exception happens, and when it re-occurs after being marked resolved. If an exception happens 100 times, but was never resolved you’ll only get 1 email about it. # Troubleshooting > Troubleshoot common issues with Honeybadger's Elixir error tracking and application monitoring library and resolve integration problems. Common issues/workarounds for [`honeybadger-elixir`](https://github.com/honeybadger-io/honeybadger-elixir) are documented here. If you don’t find a solution to your problem here or in our [support documentation](/lib/elixir/#getting-support), email and we’ll assist you! ## Before you start troubleshooting [Section titled “Before you start troubleshooting”](#before-you-start-troubleshooting) 1. Make sure you are on the latest version of [honeybadger-elixir](https://hexdocs.pm/honeybadger/). ### All errors are not reported [Section titled “All errors are not reported”](#all-errors-are-not-reported) If *no* errors are reported (even [manually via `Honeybadger.notify`](/lib/elixir/errors/reporting-errors/)): 1. [Is the `api_key` config option configured?](/lib/elixir/reference/configuration/) 2. [Are you in an excluded environment configured by `exclude_envs`?](/lib/elixir/errors/environments/#development-environments) ### Some errors are not reported [Section titled “Some errors are not reported”](#some-errors-are-not-reported) 1. [Is the error ignored via config?](/lib/elixir/errors/reducing-noise/) # Honeybadger for Go > Honeybadger monitors your Go applications for errors and exceptions so that you can fix them wicked fast. [![Go Reference](https://pkg.go.dev/badge/github.com/honeybadger-io/honeybadger-go.svg)](https://pkg.go.dev/github.com/honeybadger-io/honeybadger-go) Hi there! You’ve found Honeybadger’s guide to **Go error tracking**. Once installed, Honeybadger will automatically report errors from your Go application. ## How you should read the docs [Section titled “How you should read the docs”](#how-you-should-read-the-docs) * If you’re installing Honeybadger in an application that uses Go’s **net/http** package, check out the **[HTTP integration guide](/lib/go/integrations/http/)**. * For all other Go applications, start with the **[General integration guide](/lib/go/integrations/other/)**. * The **How-to guides** (in the left-hand navigation menu) are general guides on how to do things with the library, and should apply to all types of applications. * There is additional reference material in the **Package reference** section. ## Sample application [Section titled “Sample application”](#sample-application) If you’d like to see the library in action before you integrate it with your apps, check out our [sample application](https://github.com/honeybadger-io/crywolf-go). You can deploy the sample app to your Heroku account by clicking this button: [![Deploy](https://www.herokucdn.com/deploy/button.png)](https://heroku.com/deploy?template=https://github.com/honeybadger-io/crywolf-go) Don’t forget to destroy the Heroku app after you’re done so that you aren’t charged for usage. ## Getting support [Section titled “Getting support”](#getting-support) If you’re having trouble working with the package (such as you aren’t receiving error reports when you should be): 1. Upgrade to the latest package version if possible (you can find a list of changes in the [CHANGELOG](https://github.com/honeybadger-io/honeybadger-go/blob/master/CHANGELOG.md)) 2. If you believe you’ve found a bug, [submit an issue on GitHub](https://github.com/honeybadger-io/honeybadger-go/issues/) For all other problems, contact support for help: # Adding context to errors > Add context to Go error reports with custom metadata to improve debugging and error resolution. Honeybadger can display additional custom key/value metadata — or “context” — with each error report. Context is what you’re looking for if: * You want to record the current user’s id or email address at the time of an error * You need to send additional debugging information with an error * You have any other metadata you’d like to send with an error There are two ways to add context to errors in your code: [global](#global-context) and [local](#local-context). ## Global context [Section titled “Global context”](#global-context) Use [`honeybadger.SetContext`](https://pkg.go.dev/github.com/honeybadger-io/honeybadger-go#SetContext) to set context data that will be sent with any error that occurs: ```go honeybadger.SetContext(honeybadger.Context{ "user_id": 1, }) ``` For example, it’s often useful to record the current user’s ID when an error occurs in a web app. To do that, use `SetContext` to set the user id on each request. If an error occurs, the id will be reported with it. **Note:** This method is currently shared across goroutines, and therefore may not be optimal for use in highly concurrent use cases, such as HTTP requests. See [issue #35](https://github.com/honeybadger-io/honeybadger-go/issues/35). ### Clearing global context [Section titled “Clearing global context”](#clearing-global-context) To clear all context data that was previously set with `SetContext`: ```go honeybadger.ClearContext() ``` ## Local context [Section titled “Local context”](#local-context) You can also add context to a single error report using [`Context`](https://pkg.go.dev/github.com/honeybadger-io/honeybadger-go#Context) as an optional argument to `honeybadger.Notify`: ```go honeybadger.Notify(err, honeybadger.Context{"user_id": 2}) ``` Local context is useful when you want to add context that’s specific to a particular error, without affecting global context. ## Special context keys [Section titled “Special context keys”](#special-context-keys) While you can add any key/value data to context, a few keys have special meaning in Honeybadger: | Key | Description | | ------------ | ----------------------------------------------------------------------------------------------------- | | `user_id` | The `String` user ID used by Honeybadger to aggregate user data across occurrences on the error page. | | `user_email` | Same as `user_id`, but for email addresses | ## Limits [Section titled “Limits”](#limits) Honeybadger uses the following limits to ensure the service operates smoothly for everyone: * Nested objects have a max depth of 20 * Context values have a max size of 64Kb When an error notification includes context data that exceed these limits, the context data will be truncated, and the notification will still be processed. # Customizing error grouping > Customize how Honeybadger groups Go errors using error classes and fingerprints. Honeybadger uses the error’s class name to group similar errors together. This works well for most cases, but you may want to customize grouping when: * Your error classes are generic (such as `errors.errorString`) * You want to group related errors together regardless of their class * You want to separate errors that have the same class but different causes ## Overriding the error class [Section titled “Overriding the error class”](#overriding-the-error-class) If your error classes are often generic, you can improve grouping by overriding the default class name with something more specific using [`ErrorClass`](https://pkg.go.dev/github.com/honeybadger-io/honeybadger-go#ErrorClass): ```go honeybadger.Notify(err, honeybadger.ErrorClass{"DatabaseConnectionError"}) ``` All errors with the same error class will be grouped together. ## Using custom fingerprints [Section titled “Using custom fingerprints”](#using-custom-fingerprints) To override grouping entirely, you can send a custom [`Fingerprint`](https://pkg.go.dev/github.com/honeybadger-io/honeybadger-go#Fingerprint). All errors with the same fingerprint will be grouped together, regardless of error class: ```go honeybadger.Notify(err, honeybadger.Fingerprint{"checkout-payment-failed"}) ``` Fingerprints are useful when you want complete control over how errors are grouped. For example, you might want to group all payment-related errors together regardless of the underlying error type. ## Combining with other options [Section titled “Combining with other options”](#combining-with-other-options) You can combine error class or fingerprint with other notification options: ```go honeybadger.Notify(err, honeybadger.ErrorClass{"PaymentError"}, honeybadger.Context{"order_id": 12345}, honeybadger.Tags{"payment", "checkout"}, ) ``` ## Advanced: Using BeforeNotify for dynamic grouping [Section titled “Advanced: Using BeforeNotify for dynamic grouping”](#advanced-using-beforenotify-for-dynamic-grouping) For more complex grouping logic, you can use `BeforeNotify` to dynamically set the fingerprint based on the error. One common use case is grouping `errors.errorString` errors by their message instead of class: ```go honeybadger.BeforeNotify( func(notice *honeybadger.Notice) error { if notice.ErrorClass == "errors.errorString" { notice.Fingerprint = notice.Message } return nil } ) ``` Note that in this example, the backtrace is ignored. If you want to group by message *and* backtrace, you could append data from `notice.Backtrace` to the fingerprint string. An alternate approach would be to override `notice.ErrorClass` with a more specific class name that may be inferred from the message. # Reducing noise > Filter and modify Go error notifications before they are sent to Honeybadger using BeforeNotify callbacks. Sometimes you may want to modify the data sent to Honeybadger right before an error notification is sent, or skip the notification entirely. The `honeybadger.BeforeNotify` function lets you add callbacks to do this. ## Skipping notifications [Section titled “Skipping notifications”](#skipping-notifications) To skip certain errors from being reported, return an error from your `BeforeNotify` callback: ```go honeybadger.BeforeNotify( func(notice *honeybadger.Notice) error { if notice.ErrorClass == "SkippedError" { return fmt.Errorf("Skipping this notification") } // Return nil to send notification for all other classes. return nil } ) ``` When your callback returns an error, the notification is not sent to Honeybadger. ## Modifying notifications [Section titled “Modifying notifications”](#modifying-notifications) You can also modify the notice before it’s sent. For example, to change the error class for all errors: ```go honeybadger.BeforeNotify( func(notice *honeybadger.Notice) error { // Errors in Honeybadger will always have the class name "GenericError". notice.ErrorClass = "GenericError" return nil } ) ``` ## Multiple callbacks [Section titled “Multiple callbacks”](#multiple-callbacks) You can register multiple `BeforeNotify` callbacks. They will be executed in the order they were registered. If any callback returns an error, the notification is skipped. ## Notice fields [Section titled “Notice fields”](#notice-fields) The [`Notice`](https://pkg.go.dev/github.com/honeybadger-io/honeybadger-go#Notice) struct passed to your callback contains these fields you can inspect or modify: | Field | Type | Description | | ------------ | ---------- | -------------------- | | ErrorClass | string | Error type name | | ErrorMessage | string | Error message | | Fingerprint | string | Grouping fingerprint | | Tags | \[]string | Error tags | | URL | string | Request URL | | Context | Context | Custom context data | | Params | Params | URL/form parameters | | CGIData | CGIData | HTTP headers | | Backtrace | \[]\*Frame | Stack trace | | Env | string | Environment name | | Hostname | string | Server hostname | See the [Go package documentation](https://pkg.go.dev/github.com/honeybadger-io/honeybadger-go) for complete type definitions. ## Disabling notifications entirely [Section titled “Disabling notifications entirely”](#disabling-notifications-entirely) For development and testing, you may want to disable all error reporting. Use `NewNullBackend` to create a backend which swallows all errors: ```go honeybadger.Configure(honeybadger.Configuration{Backend: honeybadger.NewNullBackend()}) ``` This is useful to prevent sending unnecessary errors during development or in test environments. # Reporting errors > Manually report errors from Go applications to Honeybadger using the Notify function. Honeybadger reports unhandled panics automatically when you use `honeybadger.Handler` or `honeybadger.Monitor()`. In all other cases, use `honeybadger.Notify` to send errors to Honeybadger. ## Using honeybadger.Notify [Section titled “Using honeybadger.Notify”](#using-honeybadgernotify) If you’ve handled a panic in your code, but would still like to report the error to Honeybadger, use `honeybadger.Notify`: ```go if err != nil { honeybadger.Notify(err) } ``` ## Adding context to notifications [Section titled “Adding context to notifications”](#adding-context-to-notifications) You can add local context using an optional second argument with [`Context`](https://pkg.go.dev/github.com/honeybadger-io/honeybadger-go#Context): ```go honeybadger.Notify(err, honeybadger.Context{"user_id": 2}) ``` See [Adding context to errors](/lib/go/errors/context/) for more details. ## Customizing error grouping [Section titled “Customizing error grouping”](#customizing-error-grouping) Honeybadger uses the error’s class name to group similar errors together. If your error classes are often generic (such as `errors.errorString`), you can improve grouping by overriding the default with [`ErrorClass`](https://pkg.go.dev/github.com/honeybadger-io/honeybadger-go#ErrorClass): ```go honeybadger.Notify(err, honeybadger.ErrorClass{"CustomClassName"}) ``` To override grouping entirely, you can send a custom [`Fingerprint`](https://pkg.go.dev/github.com/honeybadger-io/honeybadger-go#Fingerprint). All errors with the same fingerprint will be grouped together: ```go honeybadger.Notify(err, honeybadger.Fingerprint{"A unique string"}) ``` See [Customizing error grouping](/lib/go/errors/customizing-error-grouping/) for more details. ## Adding tags [Section titled “Adding tags”](#adding-tags) To tag errors in Honeybadger using [`Tags`](https://pkg.go.dev/github.com/honeybadger-io/honeybadger-go#Tags): ```go honeybadger.Notify(err, honeybadger.Tags{"timeout", "http"}) ``` See [Tagging errors](/lib/go/errors/tagging-errors/) for more details. ## Combining options [Section titled “Combining options”](#combining-options) You can combine multiple options in a single `Notify` call: ```go honeybadger.Notify(err, honeybadger.Context{"user_id": 2}, honeybadger.Tags{"timeout", "http"}, honeybadger.ErrorClass{"TimeoutError"}, ) ``` ## Including HTTP request data [Section titled “Including HTTP request data”](#including-http-request-data) When reporting errors from HTTP handlers, you can pass the request directly to include URL, parameters, and headers automatically: ```go honeybadger.Notify(err, r) // r is *http.Request ``` For more control, you can pass specific request data using [`Params`](https://pkg.go.dev/github.com/honeybadger-io/honeybadger-go#Params) and [`CGIData`](https://pkg.go.dev/github.com/honeybadger-io/honeybadger-go#CGIData): ```go // Include URL parameters honeybadger.Notify(err, honeybadger.Params(r.URL.Query())) // Include form data r.ParseForm() honeybadger.Notify(err, honeybadger.Params(r.Form)) // Include HTTP headers as CGI data honeybadger.Notify(err, honeybadger.CGIData{ "REQUEST_METHOD": r.Method, "HTTP_USER_AGENT": r.UserAgent(), "REMOTE_ADDR": r.RemoteAddr, }) // Include the request URL honeybadger.Notify(err, r.URL) ``` **Note:** When using `honeybadger.Handler`, request data is captured automatically. See the [HTTP integration guide](/lib/go/integrations/http/) for details. # Tagging errors > Add tags to Go error reports in Honeybadger to organize and filter errors. Tags allow you to categorize and filter errors in Honeybadger. You can use tags to: * Group errors by feature area (e.g., “checkout”, “auth”, “api”) * Mark errors by severity or priority * Filter errors in the Honeybadger dashboard ## Adding tags to errors [Section titled “Adding tags to errors”](#adding-tags-to-errors) To tag errors when reporting them to Honeybadger, use `honeybadger.Tags`: ```go honeybadger.Notify(err, honeybadger.Tags{"timeout", "http"}) ``` You can add multiple tags as separate strings in the slice. ## Combining tags with other options [Section titled “Combining tags with other options”](#combining-tags-with-other-options) Tags can be combined with context and other notification options: ```go honeybadger.Notify(err, honeybadger.Tags{"checkout", "payment"}, honeybadger.Context{"order_id": 12345}, ) ``` See the [Go package documentation](https://pkg.go.dev/github.com/honeybadger-io/honeybadger-go) for more details. # Insights overview > Stream Go application logs and custom events into Honeybadger Insights, then query everything with BadgerQL. [Insights](/guides/insights/) lets you observe what your Go application does in production. The Honeybadger Go package ships handlers for the standard `slog` package and for `zerolog`. Wire one in and every log line becomes a structured event in Insights, fields and all. From there, you can attach per-request fields to a derived logger, send custom events for moments that don’t fit a log shape, and use [BadgerQL](/guides/insights/badgerql/) to ask questions across the whole event stream. Any field you send is queryable as soon as it arrives, with no schema to define ahead of time. ## Wire up structured logging [Section titled “Wire up structured logging”](#wire-up-structured-logging) Construct an `slog` logger backed by the Honeybadger handler. The handler accepts a custom event type, which is the BadgerQL `event_type` field you will filter on later: Build an Insights logger ```go import ( "log/slog" "github.com/honeybadger-io/honeybadger-go" hbslog "github.com/honeybadger-io/honeybadger-go/slog" ) hbClient := honeybadger.New(honeybadger.Configuration{APIKey: "..."}) insightsLogger := slog.New( hbslog.New(hbClient).WithEventType("http_request"), ).With("service", "checkouts", "commit", commit) ``` `service` and `commit` ride on every event from this logger, so you can filter by service across a fleet or split metrics by release. Keep this logger separate from your application’s main `slog` logger. Stdout and Insights serve different purposes, and routing every log line through Honeybadger inflates your event volume with noise. Stash the request-scoped derivative on context (below) so handlers emit through it deliberately. [Capturing logs](/lib/go/insights/capturing-logs/)slog and zerolog setup options. [Sending custom events](/lib/go/insights/sending-events/)The full honeybadger.Event API. ## Add per-request context [Section titled “Add per-request context”](#add-per-request-context) `slog`’s `.With()` returns a new logger with extra attributes attached to every subsequent log call. Use that to derive a request-scoped logger inside HTTP middleware. Attach only attributes that make sense for *every* request here, typically the request ID: Per-request logger in middleware ```go func InsightsMiddleware(insightsLogger *slog.Logger) func(http.Handler) http.Handler { return func(next http.Handler) http.Handler { return http.HandlerFunc(func(w http.ResponseWriter, r *http.Request) { start := time.Now() wrapped := &responseWriter{ResponseWriter: w, status: 200} requestLogger := insightsLogger.With( "request_id", r.Header.Get("X-Request-Id"), ) r = r.WithContext(context.WithValue(r.Context(), loggerKey, requestLogger)) next.ServeHTTP(wrapped, r) requestLogger.LogAttrs(r.Context(), slog.LevelInfo, "request", slog.String("method", r.Method), slog.String("path", r.URL.Path), slog.Int("status", wrapped.status), slog.Int64("duration", time.Since(start).Microseconds()), ) }) } } ``` Every request now produces one `http_request` event with `method`, `path`, `status`, `duration` (microseconds), and `request_id`. Slowest endpoints by p95: Slowest endpoints ```badgerql filter event_type::str == "http_request" | stats percentile(95, duration::float) as p95_us by path::str | sort p95_us desc | limit 5 | only path, toHumanString(p95_us, "microseconds") as p95 ``` | path | p95 | | -------------------- | ----- | | /checkouts/authorize | 412ms | | /reports/generate | 287ms | | /search | 138ms | | /accounts/upgrade | 96ms | | /users/me | 41ms | ## Record application events [Section titled “Record application events”](#record-application-events) For application events recorded from inside a handler (a payment authorized, a subscription upgrading, a feature toggle flipping), emit them through a further-derived logger pulled from context. Handler-specific attributes attached via `.With()` ride along with `request_id` and anything else the middleware put on the request logger: Send a custom payment event ```go func authorizeCheckout(w http.ResponseWriter, r *http.Request) { logger := r.Context().Value(loggerKey).(*slog.Logger). With("checkout_variant", r.URL.Query().Get("variant")) // ... logger.LogAttrs(r.Context(), slog.LevelInfo, "payment authorized", slog.String("event_type", "payment.authorized"), slog.String("payment_provider", payment.Provider), slog.Float64("amount", checkout.Total), slog.String("currency", checkout.Currency), slog.String("authorization_id", payment.AuthorizationID), ) } ``` This query breaks down the amounts collected by variant and provider: Payments by variant and provider ```badgerql filter event_type::str == "payment.authorized" | stats count() as authorizations, sum(amount::float) as authorized_amount by checkout_variant::str, payment_provider::str | sort authorized_amount desc ``` | authorizations | authorized\_amount | checkout\_variant | payment\_provider | | -------------- | ------------------ | ----------------- | ----------------- | | 413 | 34108.00 | new | stripe | | 218 | 18722.00 | new | paypal | | 418 | 32167.00 | control | stripe | | 220 | 13639.00 | control | paypal | # Capturing logs > Send structured logs from Go applications to Honeybadger Insights using slog or zerolog. Honeybadger provides handlers for popular Go logging libraries that send structured logs directly to Honeybadger Insights as events. ## Supported libraries [Section titled “Supported libraries”](#supported-libraries) * [slog](#slog) - Go’s standard structured logging package (Go 1.21+) * [zerolog](#zerolog) - High-performance JSON logger *** ## slog [Section titled “slog”](#slog) The slog handler sends logs from Go’s standard `log/slog` package to Honeybadger Insights. **Requires Go 1.21+** ### Quick start [Section titled “Quick start”](#quick-start) ```go import ( "log/slog" "github.com/honeybadger-io/honeybadger-go" hbslog "github.com/honeybadger-io/honeybadger-go/slog" ) func main() { client := honeybadger.New(honeybadger.Configuration{ APIKey: "PROJECT_API_KEY", }) logger := slog.New(hbslog.New(client)) logger.Info("app started", "version", "1.0.0") } ``` This produces an event in Honeybadger Insights: ```json { "event_type": "log", "level": "INFO", "message": "app started", "version": "1.0.0" } ``` ### Event types [Section titled “Event types”](#event-types) The default event type is `log`. Set a custom event type for all logs using `WithEventType`: ```go audit := slog.New(hbslog.New(client).WithEventType("audit")) audit.Info("user logged in", "user_id", 42) ``` Set the event type per log call with the `event_type` attribute: ```go logger.Info("user signup", "event_type", "user_lifecycle", "user_id", 123) logger.Info("payment processed", "event_type", "payment", "amount", 99.99) ``` ### Attributes and groups [Section titled “Attributes and groups”](#attributes-and-groups) Use `WithAttrs` to add attributes to all logs, and `WithGroup` to nest attributes: ```go handler := hbslog.New(client). WithAttrs([]slog.Attr{slog.String("service", "api")}). WithGroup("http") logger := slog.New(handler) logger.Info("request handled", "status", 200, "method", "POST") ``` This produces: ```json { "event_type": "log", "level": "INFO", "message": "request handled", "service": "api", "http": { "status": 200, "method": "POST" } } ``` ### Log level filtering [Section titled “Log level filtering”](#log-level-filtering) Control which logs are sent to Honeybadger: ```go // Only send WARN and above handler := hbslog.New(client).WithLevel(slog.LevelWarn) logger := slog.New(handler) logger.Info("This is ignored") logger.Warn("This is sent") ``` Use `slog.LevelVar` for dynamic level changes at runtime: ```go levelVar := new(slog.LevelVar) levelVar.Set(slog.LevelInfo) handler := hbslog.New(client).WithLevel(levelVar) logger := slog.New(handler) levelVar.Set(slog.LevelDebug) // Now debug logs will be sent ``` *** ## zerolog [Section titled “zerolog”](#zerolog) The zerolog adapter sends logs from the `rs/zerolog` package to Honeybadger Insights. ### Quick start [Section titled “Quick start”](#quick-start-1) ```go import ( "github.com/rs/zerolog" "github.com/honeybadger-io/honeybadger-go" hbzerolog "github.com/honeybadger-io/honeybadger-go/zerolog" ) func main() { client := honeybadger.New(honeybadger.Configuration{ APIKey: "PROJECT_API_KEY", }) writer := hbzerolog.New(client) logger := zerolog.New(writer).With().Timestamp().Logger() logger.Info().Msg("hello") } ``` ### Options [Section titled “Options”](#options) #### WithEventType [Section titled “WithEventType”](#witheventtype) Sets the default event type for all logs (default: `"log"`). Override per-log by including an `event_type` field: ```go writer := hbzerolog.New(client, hbzerolog.WithEventType("app_log")) ``` #### WithKeys [Section titled “WithKeys”](#withkeys) Customize field names if your zerolog uses non-standard keys. The writer remaps the time field to `ts` for Honeybadger: ```go writer := hbzerolog.New( client, hbzerolog.WithEventType("app_log"), hbzerolog.WithKeys("timestamp", "severity"), // defaults: "time", "level" ) ``` # Event context > Add contextual data to Insights events in Go to improve debugging and understanding of application behavior. You can add custom metadata to the events sent to Honeybadger Insights by using the `SetEventContext` function. This metadata will be merged into all events sent via `honeybadger.Event()`. ## Setting event context [Section titled “Setting event context”](#setting-event-context) Use `honeybadger.SetEventContext()` to set context data that will be included with all events: ```go honeybadger.SetEventContext(honeybadger.Context{ "user_id": 123, "account": "acme", }) ``` Event data passed directly to `Event()` takes precedence over event context if there are conflicting keys. ## Clearing event context [Section titled “Clearing event context”](#clearing-event-context) To clear all event context data that was previously set: ```go honeybadger.ClearEventContext() ``` ## Example usage [Section titled “Example usage”](#example-usage) A common pattern is to set event context early in a request lifecycle: ```go func handleRequest(w http.ResponseWriter, r *http.Request) { user := getCurrentUser(r) honeybadger.SetEventContext(honeybadger.Context{ "user_id": user.ID, "account_id": user.AccountID, }) // All events sent during this request will include user context honeybadger.Event("page_view", map[string]any{ "path": r.URL.Path, }) } ``` **Note:** Event context is stored globally and shared across goroutines. For highly concurrent applications, consider passing context data directly to `Event()` instead. # Filtering events > Filter Insights events in Go applications to reduce noise and focus on relevant data. You can filter out or customize events sent to Honeybadger Insights by using the `honeybadger.BeforeEvent()` function. This allows you to modify event data or skip events entirely before they are sent. ## Modifying events [Section titled “Modifying events”](#modifying-events) To modify or augment event data before it’s sent, add a callback that modifies the event map and returns `nil`: ```go honeybadger.BeforeEvent( func(event map[string]any) error { event["environment"] = "production" return nil } ) ``` ## Dropping events [Section titled “Dropping events”](#dropping-events) To skip events from being sent, return `honeybadger.ErrEventDropped`: ```go honeybadger.BeforeEvent( func(event map[string]any) error { if event["event_type"] == "debug_event" { return honeybadger.ErrEventDropped } return nil } ) ``` ## Multiple callbacks [Section titled “Multiple callbacks”](#multiple-callbacks) You can register multiple `BeforeEvent` callbacks. They will be executed in the order they were registered. If any callback returns `ErrEventDropped`, the event is skipped. ## Example: Filtering sensitive data [Section titled “Example: Filtering sensitive data”](#example-filtering-sensitive-data) A common use case is to filter sensitive data from events: ```go honeybadger.BeforeEvent( func(event map[string]any) error { // Remove sensitive fields delete(event, "password") delete(event, "credit_card") // Anonymize email addresses if email, ok := event["email"].(string); ok { event["email"] = anonymizeEmail(email) } return nil } ) ``` ## Example: Dropping high-volume events [Section titled “Example: Dropping high-volume events”](#example-dropping-high-volume-events) You might want to drop certain high-volume events to reduce costs: ```go honeybadger.BeforeEvent( func(event map[string]any) error { // Drop health check events if event["event_type"] == "health_check" { return honeybadger.ErrEventDropped } // Drop events from internal services if source, ok := event["source"].(string); ok { if source == "internal-monitoring" { return honeybadger.ErrEventDropped } } return nil } ) ``` # Sending custom events > Send custom events to Honeybadger Insights for tracking application behavior and metrics in Go. Honeybadger’s Go package can be used to send events to [Honeybadger Insights](/guides/insights/). ## Sending custom events [Section titled “Sending custom events”](#sending-custom-events) Use `honeybadger.Event()` to send custom events: ```go honeybadger.Event("user_login", map[string]any{ "user_id": 123, "email": "user@example.com", }) ``` The first argument is the event type, and the second is a map of event data. Events are batched and sent asynchronously for optimal performance. ## Configuration [Section titled “Configuration”](#configuration) You can configure batching, retries, and throttling behavior. See [Configuration](/lib/go/reference/configuration/) for details on the following options: | Option | Default | Description | | ----------------------- | ---------- | ----------------------------------- | | `EventsBatchSize` | 1000 | Maximum events per batch | | `EventsTimeout` | 30 seconds | Request timeout | | `EventsMaxQueueSize` | 100000 | Maximum events to queue | | `EventsMaxRetries` | 3 | Maximum retry attempts | | `EventsThrottleWait` | 60 seconds | Wait time before retrying | | `EventsDropLogInterval` | 60 seconds | Interval for logging dropped events | # HTTP integration guide > Install and configure Honeybadger for Go applications using net/http with automatic panic reporting. **Typical installation time:** 5 minutes Hi there! You’ve found Honeybadger’s guide to **Go error tracking** for applications using the `net/http` package. Once installed, Honeybadger will automatically report panics from your HTTP handlers. ## Installing the package [Section titled “Installing the package”](#installing-the-package) To install, grab the package from GitHub: ```sh go get github.com/honeybadger-io/honeybadger-go ``` Then add an import to your application code: ```go import "github.com/honeybadger-io/honeybadger-go" ``` ## Configuring your API key [Section titled “Configuring your API key”](#configuring-your-api-key) Configure your API key using `honeybadger.Configure`: ```go honeybadger.Configure(honeybadger.Configuration{APIKey: "PROJECT_API_KEY"}) ``` You can also configure Honeybadger via the `HONEYBADGER_API_KEY` environment variable. See [Configuration](/lib/go/reference/configuration/) for more options. ## Enabling automatic panic reporting [Section titled “Enabling automatic panic reporting”](#enabling-automatic-panic-reporting) To automatically report panics which happen during an HTTP request, wrap your `http.Handler` function with [`honeybadger.Handler`](https://pkg.go.dev/github.com/honeybadger-io/honeybadger-go#Handler): ```go log.Fatal(http.ListenAndServe(":8080", honeybadger.Handler(handler))) ``` Request data such as cookies and params will automatically be reported with errors which happen inside `honeybadger.Handler`. Make sure you recover from panics after Honeybadger’s Handler has been executed to ensure all panics are reported. ## What data is captured [Section titled “What data is captured”](#what-data-is-captured) When a panic occurs inside `honeybadger.Handler`, the following request data is automatically included in the error report: * Request URL and method * URL query parameters * Form data (if parsed) * HTTP headers (as CGI variables) * Cookies For manually reported errors, pass the request to include this data: ```go func myHandler(w http.ResponseWriter, r *http.Request) { if err := doSomething(); err != nil { honeybadger.Notify(err, r) } } ``` See [Reporting errors](/lib/go/errors/reporting-errors/) for more options. ## Testing your installation [Section titled “Testing your installation”](#testing-your-installation) To verify that your installation is working, you can trigger a test panic in one of your HTTP handlers: ```go func testHandler(w http.ResponseWriter, r *http.Request) { panic("Testing Honeybadger!") } ``` Visit the route that triggers this handler, then check your Honeybadger dashboard for the error. ## Next steps [Section titled “Next steps”](#next-steps) * Learn how to [report errors manually](/lib/go/errors/reporting-errors/) * Add [context to your errors](/lib/go/errors/context/) * Explore [configuration options](/lib/go/reference/configuration/) # Other Go applications > Install and configure Honeybadger for Go applications with automatic panic monitoring and manual error reporting. **Typical installation time:** 5 minutes Hi there! You’ve found Honeybadger’s guide to **Go error tracking** for standalone applications, CLI tools, workers, and other non-HTTP Go programs. Once installed, Honeybadger will report panics and errors from your application. ## Installing the package [Section titled “Installing the package”](#installing-the-package) To install, grab the package from GitHub: ```sh go get github.com/honeybadger-io/honeybadger-go ``` Then add an import to your application code: ```go import "github.com/honeybadger-io/honeybadger-go" ``` ## Configuring your API key [Section titled “Configuring your API key”](#configuring-your-api-key) Configure your API key using `honeybadger.Configure`: ```go honeybadger.Configure(honeybadger.Configuration{APIKey: "PROJECT_API_KEY"}) ``` You can also configure Honeybadger via the `HONEYBADGER_API_KEY` environment variable. See [Configuration](/lib/go/reference/configuration/) for more options. ## Enabling automatic panic reporting [Section titled “Enabling automatic panic reporting”](#enabling-automatic-panic-reporting) To report all unhandled panics which happen in your application, add the following to `main()`: ```go func main() { defer honeybadger.Monitor() // application code... } ``` **Important:** `honeybadger.Monitor()` will re-panic after it reports the error, so make sure that it is only called once before recovering from the panic (or allowing the process to crash). You can also monitor specific functions: ```go func risky() { defer honeybadger.Monitor() // risky business logic... } ``` ## Manually reporting errors [Section titled “Manually reporting errors”](#manually-reporting-errors) To report an error manually, use `honeybadger.Notify`: ```go if err != nil { honeybadger.Notify(err) } ``` See [Reporting errors](/lib/go/errors/reporting-errors/) for more details. ## Testing your installation [Section titled “Testing your installation”](#testing-your-installation) To verify that your installation is working, you can add a test panic: ```go func main() { defer honeybadger.Monitor() panic("Testing Honeybadger!") } ``` Run your application, then check your Honeybadger dashboard for the error. ## Next steps [Section titled “Next steps”](#next-steps) * Learn how to [report errors manually](/lib/go/errors/reporting-errors/) * Add [context to your errors](/lib/go/errors/context/) * Explore [configuration options](/lib/go/reference/configuration/) # Configuration > Complete configuration reference for Honeybadger's Go library with all available options and settings. You can configure Honeybadger using the `honeybadger.Configure` method: ```go honeybadger.Configure(honeybadger.Configuration{ APIKey: "PROJECT_API_KEY", Env: "production", }) ``` You can also configure most options via environment variables. ## Configuration options [Section titled “Configuration options”](#configuration-options) | Name | Type | Default | Example | Environment variable | | --------------------- | --------------------- | ------------------------------ | ------------------------------------ | ---------------------------------------------------- | | APIKey | `string` | `""` | `"badger01"` | `HONEYBADGER_API_KEY` | | Root | `string` | The current working directory | `"/path/to/project"` | `HONEYBADGER_ROOT` | | Env | `string` | `""` | `"production"` | `HONEYBADGER_ENV` | | Hostname | `string` | The hostname of current server | `"badger01"` | `HONEYBADGER_HOSTNAME` | | Endpoint | `string` | `"https://api.honeybadger.io"` | `"https://honeybadger.example.com/"` | `HONEYBADGER_ENDPOINT` | | Sync | `bool` | `false` | `true` | `HONEYBADGER_SYNC` | | Timeout | `time.Duration` | 3 seconds | `10 * time.Second` | `HONEYBADGER_TIMEOUT` (nanoseconds) | | Logger | `honeybadger.Logger` | Logs to stderr | `CustomLogger{}` | n/a | | Backend | `honeybadger.Backend` | HTTP backend | `CustomBackend{}` | n/a | | EventsBatchSize | `int` | 1000 | `500` | `HONEYBADGER_EVENTS_BATCH_SIZE` | | EventsTimeout | `time.Duration` | 30 seconds | `10 * time.Second` | `HONEYBADGER_EVENTS_TIMEOUT` (nanoseconds) | | EventsMaxQueueSize | `int` | 100000 | `50000` | `HONEYBADGER_EVENTS_MAX_QUEUE_SIZE` | | EventsMaxRetries | `int` | 3 | `5` | `HONEYBADGER_EVENTS_MAX_RETRIES` | | EventsThrottleWait | `time.Duration` | 60 seconds | `30 * time.Second` | `HONEYBADGER_EVENTS_THROTTLE_WAIT` (nanoseconds) | | EventsDropLogInterval | `time.Duration` | 60 seconds | `30 * time.Second` | `HONEYBADGER_EVENTS_DROP_LOG_INTERVAL` (nanoseconds) | ## Configuration via environment variables [Section titled “Configuration via environment variables”](#configuration-via-environment-variables) The following environment variables are supported: * `HONEYBADGER_API_KEY` - Your Honeybadger API key * `HONEYBADGER_ENV` - The environment name (e.g., “production”, “staging”) * `HONEYBADGER_ROOT` - The project root directory * `HONEYBADGER_HOSTNAME` - The server hostname * `HONEYBADGER_ENDPOINT` - Custom API endpoint URL * `HONEYBADGER_SYNC` - Set to “true” for synchronous error reporting * `HONEYBADGER_TIMEOUT` - Request timeout in nanoseconds * `HONEYBADGER_EVENTS_BATCH_SIZE` - Maximum events per batch * `HONEYBADGER_EVENTS_TIMEOUT` - Events request timeout in nanoseconds * `HONEYBADGER_EVENTS_MAX_QUEUE_SIZE` - Maximum events to queue * `HONEYBADGER_EVENTS_MAX_RETRIES` - Maximum retry attempts for events * `HONEYBADGER_EVENTS_THROTTLE_WAIT` - Wait time before retrying in nanoseconds * `HONEYBADGER_EVENTS_DROP_LOG_INTERVAL` - Interval for logging dropped events in nanoseconds ## Sync mode [Section titled “Sync mode”](#sync-mode) By default, notices are sent via a separate worker goroutine. This is ideal for long-running applications as it keeps Honeybadger from blocking during execution. However, this can be a problem for short-running applications (lambdas, for example) as the program might terminate before all messages are processed. To combat this, you can configure Honeybadger to work in “Sync” mode which blocks until notices are sent when `honeybadger.Notify` is executed: ```go honeybadger.Configure(honeybadger.Configuration{Sync: true}) ``` Alternatively, if you want asynchronous behavior but need to ensure notices are sent before your program exits, you can call `honeybadger.Flush`: ```go honeybadger.Notify("I errored.") honeybadger.Flush() ``` ## Custom logger [Section titled “Custom logger”](#custom-logger) You can provide a custom logger by implementing the `honeybadger.Logger` interface: ```go honeybadger.Configure(honeybadger.Configuration{ Logger: myCustomLogger, }) ``` ## Custom backend [Section titled “Custom backend”](#custom-backend) For testing or custom integrations, you can provide a custom backend: ```go honeybadger.Configure(honeybadger.Configuration{ Backend: myCustomBackend, }) ``` To disable error reporting entirely (useful for development), use the null backend: ```go honeybadger.Configure(honeybadger.Configuration{ Backend: honeybadger.NewNullBackend(), }) ``` ## Creating a new client [Section titled “Creating a new client”](#creating-a-new-client) In the same way that the log library provides a predefined “standard” logger, honeybadger defines a standard client which may be accessed directly via `honeybadger`. A new client may also be created by calling `honeybadger.New`: ```go hb := honeybadger.New(honeybadger.Configuration{APIKey: "some other api key"}) hb.Notify("This error was reported by an alternate client.") ``` # Supported versions > Go versions supported by the Honeybadger Go library. This library supports the last two major Go releases, consistent with the Go team’s [release policy](https://go.dev/doc/devel/release): * Go 1.25.x * Go 1.24.x Older versions may work but are not officially supported or tested. # Honeybadger for Java > Honeybadger monitors your Java applications for errors and exceptions so that you can fix them wicked fast. **Typical installation time:** \~10 minutes Hi there! You’ve found Honeybadger’s guide to **Java exception and error tracking**. Once installed, Honeybadger will automatically report errors from your Java application. ## Getting started [Section titled “Getting started”](#getting-started) [Source Code](https://github.com/honeybadger-io/honeybadger-java) • [Maven](https://search.maven.org/#search%7Cga%7C1%7Cg%3A%22io.honeybadger%22) Honeybadger works out of the box with many popular Java frameworks. Installation is just a matter of including the jar library and setting your API key. In this section, we’ll cover the basics. More advanced installations are covered later. ### 1. Install the jar [Section titled “1. Install the jar”](#1-install-the-jar) The first step is to add the honeybadger jar to your dependency manager (Maven, SBT, Gradle, Ivy, etc). In the case of Maven, you would add it as so: ```xml io.honeybadger honeybadger-java LATEST ``` In the case of SBT: ```plaintext libraryDependencies += "io.honeybadger" % "honeybadger-java" % "]1,)" ``` For other dependency managers an example is provided on the [Maven Central site](https://search.maven.org/#search%7Cgav%7C1%7Cg%3A%22io.honeybadger%22%20AND%20a%3A%22honeybadger-java%22). If you are not using a dependency manager, download the jar directly and add it to your classpath. ### 2. Install a slf4j compatible logging library or binding in your project [Section titled “2. Install a slf4j compatible logging library or binding in your project”](#2-install-a-slf4j-compatible-logging-library-or-binding-in-your-project) *Note*: If you are using [Spring Boot](http://projects.spring.io/spring-boot/) or the [Play Framework](https://www.playframework.com/), a slf4j compatible logger is installed by default. All dependencies needed for running are included in the distributed JAR with one exception - slf4j-api. We expect that you are using some logging library and that you have imported the sl4j-api in order to provide a common interface for the logger to imported libraries. Almost every logging library provides a means for it to be compatible with the slf4j API. These are two good candidates if you aren’t sure about which one to choose: * [Logback](http://logback.qos.ch/) * [log4j2](http://logging.apache.org/log4j/2.x/log4j-slf4j-impl/index.html) ### 3. Set your API key and configuration parameters [Section titled “3. Set your API key and configuration parameters”](#3-set-your-api-key-and-configuration-parameters) Next, you’ll set the API key and some configuration parameters for this project. #### Stand-alone usage [Section titled “Stand-alone usage”](#stand-alone-usage) If you want to send all unhandled errors to Honeybadger and have them logged to slf4j via the error log level, you will need to set the correct system properties (or provide a [ConfigContext](https://github.com/honeybadger-io/honeybadger-java/tree/master/honeybadger-java/src/main/java/io/honeybadger/reporter/config/ConfigContext.java)) and add a single line to the thread in which you want to register the error handler. A typical stand-alone implementation may look like: ```java import io.honeybadger.reporter.HoneybadgerUncaughtExceptionHandler; public class MyApp { public static void main(String argv[]) { HoneybadgerUncaughtExceptionHandler.registerAsUncaughtExceptionHandler(); // The rest of the application goes here } } ``` You would invoke it with the `-Dhoneybadger.api_key=` system parameter and any other configuration values via system parameters it would load with the correct state. It would then register itself as the default error handler. #### Servlet usage [Section titled “Servlet usage”](#servlet-usage) A servlet based implementation may look like: In your web.xml file: ```xml HoneybadgerFilter io.honeybadger.reporter.servlet.HoneybadgerFilter honeybadger.api_key PROJECT_API_KEY honeybadger.excluded_sys_props bonecp.password,bonecp.username honeybadger.excluded_exception_classes org.apache.catalina.connector.ClientAbortException honeybadger.display_feedback_form false HoneybadgerFilter /* ``` Note If you have other code executing in your servlet-based application that doesn’t go through the servlet interface, you will want to register an exception handler for it in order to report errors to Honeybadger. See the *Stand-alone Usage* section. #### Play Framework usage [Section titled “Play Framework usage”](#play-framework-usage) This library has been tested against Play 2.4.2. After adding Hondeybadger as a dependency to your dependency manager as explained in the [Install the jar section](#1-install-the-jar), you can enable Honeybadger as an error handler by adding the following lines to your conf/application.conf file: ```plaintext honeybadger.api_key = [Your project API key] # You can add any of the Honeybadger configuration parameters here directly # honeybadger.excluded_exception_classes = com.myorg.AnnoyingException play.http.errorHandler = io.honeybadger.reporter.play.HoneybadgerErrorHandler ``` This will allow the library to wrap the default error handler implementation and pass around Honeybadger error ids instead of the default Play error ids. #### Spring Framework usage [Section titled “Spring Framework usage”](#spring-framework-usage) This library has been tested against Spring 4.2.2 using Spring Boot. After adding Honeybadger as a dependency to your dependency manager as explained in the [Install the jar section](#1-install-the-jar), you can enable Honeybadger as an error handler by adding the `honeybadger.api_key` configuration parameter to your [Spring configuration](http://docs.spring.io/spring-boot/docs/current/reference/html/boot-features-external-config.html). Spring allows for many different vectors of configuration and it is beyond the scope of this document to describe all of them. For example, if you were using a file-based application configuration, you would need to add your Honeybadger configuration parameters as follows: ```plaintext ENV = production honeybadger.api_key = [Your project API key] honeybadger.excluded_exception_classes = com.myorg.AnnoyingException ``` *Note*: Spring doesn’t support the concept of a single environment name. Rather, it supports [a pattern of using multiple profiles](http://docs.spring.io/spring-boot/docs/current/reference/html/boot-features-profiles.html) to determine the runtime configuration. This pattern doesn’t map nicely to Honeybadger’s configuration, so you will need to define `ENV` or `JAVA_ENV` within your configuration in order for it to map properly to Honeybadger’s way of doing things. ## Configuration [Section titled “Configuration”](#configuration) ### Advanced configuration [Section titled “Advanced configuration”](#advanced-configuration) There are a few ways to configure the Honeybadger library. Each one of the ways is implemented as a [ConfigContext](https://github.com/honeybadger-io/honeybadger-java/tree/master/honeybadger-java/src/main/java/io/honeybadger/reporter/config/ConfigContext.java) that can be passed in the constructor of the [HoneybadgerReporter](https://github.com/honeybadger-io/honeybadger-java/tree/master/honeybadger-java/src/main/java/io/honeybadger/reporter/HoneybadgerReporter.java) class. The implementations available are: * [DefaultsConfigContext](https://github.com/honeybadger-io/honeybadger-java/tree/master/honeybadger-java/src/main/java/io/honeybadger/reporter/config/DefaultsConfigContext.java) - This configuration context provides defaults that can be read by other context implementations. * [MapConfigContext](https://github.com/honeybadger-io/honeybadger-java/tree/master/honeybadger-java/src/main/java/io/honeybadger/reporter/config/MapConfigContext.java) - This reads configuration from a Map that is supplied to its constructor. * [PlayConfigContext](https://github.com/honeybadger-io/honeybadger-java/tree/master/honeybadger-java/src/main/java/io/honeybadger/reporter/config/PlayConfigContext.java) - This reads configuration from the Play Framework’s internal configuration mechanism. * [ServletFilterConfigContext](https://github.com/honeybadger-io/honeybadger-java/tree/master/honeybadger-java/src/main/java/io/honeybadger/reporter/config/ServletFilterConfigContext.java) - This reads configuration from a servlet filter configuration. * [SpringConfigContext](https://github.com/honeybadger-io/honeybadger-java/tree/master/honeybadger-java/src/main/java/io/honeybadger/reporter/config/SpringConfigContext.java) - This reads configuration from the Spring framework’s internal configuration mechanism. * [StandardConfigContext](https://github.com/honeybadger-io/honeybadger-java/tree/master/honeybadger-java/src/main/java/io/honeybadger/reporter/config/StandardConfigContext.java) - This reads configuration from the system parameters, environment variables and defaults and is **the default configuration provider**. * [SystemSettingsConfigContext](https://github.com/honeybadger-io/honeybadger-java/tree/master/honeybadger-java/src/main/java/io/honeybadger/reporter/config/SystemSettingsConfigContext.java) - This reads configuration purely from system settings. #### Configuring with environment variables or system properties (12-factor style) [Section titled “Configuring with environment variables or system properties (12-factor style)”](#configuring-with-environment-variables-or-system-properties-12-factor-style) All configuration options can also be read from environment variables or [Java system properties](https://docs.oracle.com/javase/tutorial/essential/environment/sysprop.html) when using the default [StandardConfigContext](https://github.com/honeybadger-io/honeybadger-java/tree/master/honeybadger-java/src/main/java/io/honeybadger/reporter/config/StandardConfigContext.java). Framework specific configuration contexts use of environment variables or system properties depends on the framework’s implementation. ### Configuration options [Section titled “Configuration options”](#configuration-options) \| Option Details | Description | | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | -------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | --- | --- | | **CORE** | | | | | **Name**: `ENV` or `JAVA_ENV`\ **Type**: String\ **Required**: No\ **Default**: `unknown`\ **Sample Value**: `production` | String sent to Honeybadger indicating running environment (eg development, test, staging, production, etc). | | **Name**: `honeybadger.api_key` or `HONEYBADGER_API_KEY`\ **Type**: String\ **Required**: Yes\ **Default**: N/A\ **Sample Value**: `29facd41` | The API key found in the settings tab in the Honeybadger UI. | | **Name**: `honeybadger.application_package`\ **Type**: String\ **Required**: No\ **Default**: N/A\ **Sample Value**: `my.app.package` | Java application package name used to indicate to Honeybadger what stacktraces are within the calling application’s code base. | | **Name**: `honeybadger.excluded_exception_classes`\ **Type**: CSV\ **Required**: No\ **Default**: N/A\ **Sample Value**: `co.foo.Exception`,\ `com.myorg.AnnoyingException` | CSV of Java classes in which errors are never sent to Honeybadger. This is useful for errors that are bubbled up from underlying frameworks or application servers like Tomcat. If you are using Tomcat, you may want to include `org.apache.catalina.connector.ClientAbortException`. | | **Name**: `honeybadger.excluded_sys_props`\ **Type**: CSV\ **Required**: No\ **Default**: `honeybadger.api_key`,\ `honeybadger.read_api_key`,\ `honeybadger.excluded_sys_props`,\ `honeybadger.url`\ **Sample Value**: `bonecp.password`,`bonecp.username` | CSV of Java system properties to exclude from being logged to Honeybadger. This is useful for excluding authentication information. Default values are automatically added. | | **Name**: `honeybadger.excluded_params`\ **Type**: CSV\ **Required**: No\ **Default**: N/A\ **Sample Value**: `auth_token`,\ `session_data`,\ `credit_card_number` | CSV of HTTP GET/POST query parameter values that will be excluded from the data sent to Honeybadger. This is useful for excluding authentication information, parameters that are too long or sensitive. | | **Name**: `honeybadger.maximum_retry_attempts`\ **Type**: Integer\ **Required**: No\ **Default**: 3\ **Sample Value:** 3 (must be >= 0) | Number of times HoneybadgerReporter will retry delivering an error report if the first attempt fails. (If set to 3, retries up to 3 times before giving up; if set to 0, tries once and gives up). | |   | | | | | **FEEDBACK\_FORM** | | | | | **Name**: `honeybadger.display_feedback_form`\ **Type**: Boolean\ **Required**: No\ **Default**: `true`\ **Sample Value**: `false` | Displays the feedback form or JSON output when an error is thrown via a servlet call. | | **Name**: `honeybadger.feedback_form_template_path`\ **Type**: String\ **Required**: No\ **Default**: `templates/feedback-form.mustache`\ **Sample Value**: `templates/my-company.mustache` | Path within the class path to the mustache template that is displayed when an error occurs in a servlet request. | |   | | | | | **NETWORK** | | | | | **Name**: `http.proxyHost`\ **Type**: String\ **Required**: No\ **Default**: N/A\ **Sample Value**: `localhost` | Standard Java system property for specifying the host to proxy all HTTP traffic through. | | **Name**: `http.proxyPort`\ **Type**: Integer\ **Required**: No\ **Default**: N/A\ **Sample Value**: `8888` | Standard Java system property for specifying the port to proxy all HTTP traffic through. | | **Name**: `honeybadger.socket_timeout`\ **Type**: Integer\ **Required**: No\ **Default**: N/A\ **Sample Value**: `60000` | Duration in milliseconds the HTTP socket can be open. | | **Name**: `honeybadger.connect_timeout`\ **Type**: Integer\ **Required**: No\ **Default**: N/A\ **Sample Value**: `60000` | Duration in milliseconds the HTTP socket is allowed to be in the connecting phase. | |   | | | | | **DEVELOPMENT** | | | | | **Name**: `honeybadger.read_api_key` or `HONEYBADGER_READ_API_KEY`\ **Type**: String\ **Required**: When testing\ **Default**: N/A\ **Sample Value**: `qjcp6c7Nv9yR-bsvGZ77` | API key used to access the Read API. | | **Name**: `honeybadger.url`\ **Type**: String\ **Required**: No\ **Default**: `https://api.honeybadger.io`\ **Sample Value**: `https://other.hbapi.com` | URL to the Honeybadger API endpoint. You may want to access it without TLS in order to test with a proxy utility. | ## Custom error pages [Section titled “Custom error pages”](#custom-error-pages) The Honeybadger library has a few parameters that it looks for whenever it renders an error page. These can be used to display extra information about the error, or to ask the user for information about how they triggered the error. Most of the parameters just link to a resource file that can provide translations for the strings displayed to the user. | Parameter | Description | | ------------------------------------- | -------------------- | | `honeybadger.feedback.error_title` | Title of page | | `honeybadger.feedback.thanks` | Thank you message | | `honeybadger.feedback.heading` | Prompt for feedback | | `honeybadger.feedback.labels.name` | Explanation query | | `honeybadger.feedback.labels.phone` | Phone number label | | `honeybadger.feedback.labels.email` | Email label | | `honeybadger.feedback.labels.comment` | Comments label | | `honeybadger.feedback.submit` | Submit button label | | `honeybadger.link` | HB link label | | `honeybadger.powered_by` | Powered by HB text | | `action` | Form POST URI | | `error_id` | Honeybadger Error ID | | `error_msg` | Error message | The default template is setup to collect user feedback and to suppress the display of the error message. This behavior can be changed by placing a new [mustache template](https://mustache.github.io/) in your classpath and specifying its path via the `honeybadger.feedback_form_template_path` configuration option. ## Collecting user feedback (ServletFilter) [Section titled “Collecting user feedback (ServletFilter)”](#collecting-user-feedback-servletfilter) When an error is sent to Honeybadger, an HTML form can be generated so users can fill out relevant information that led up to that error. Feedback responses are displayed inline in the comments section on the fault detail page. This behavior is enabled by default. To disable it set the configuration option `honeybadger.display_feedback_form` to `false`. ## Using tags [Section titled “Using tags”](#using-tags) This version of honeybadger-java supports sending tags, but it requires invoking a new overload of ```plaintext NoticeReporter.reportError(Throwable error, Object request, String message, Iterable tags); ``` The existing error handler/filter implementations for Play, Spring, and Servlets do not currently invoke this variant. Those implementations can be overridden to customize the tagging behavior for your application. ## Supported JVM [Section titled “Supported JVM”](#supported-jvm) | JVM | Supported Version | | ---------------- | ---------------------------- | | Oracle (Java SE) | 1.7, 1.8, 9, \[10, 11, 12]\* | | OpenJDK JDK/JRE | 1.7, 1.8, 9, 10, 11, 12 | *Limitations*: We don’t currently test on Oracle’s commercially licensed VMs, due to new licensing rules. Accordingly, Oracle JDK after version 9 is supported on a best-effort basis only. If you discover a defect specific to their commercially-licensed VM, please [submit an issue](https://github.com/honeybadger-io/honeybadger-java/issues/new). ## Supported frameworks [Section titled “Supported frameworks”](#supported-frameworks) | Framework | Version | Notes | | ---------------- | ------- | ----------------------------------------------------------------------------------------------------------------- | | Servlet API | 4.0.1 | | | Play Framework | 2.7.2 | We still call one deprecated API. See [Issue #110](https://github.com/honeybadger-io/honeybadger-java/issues/110) | | Spring Framework | 5.1.7 | | The Play Framework Spring are supported natively (install/configure the library and your done). For the Servlet API, you will need to configure a [servlet filter](https://github.com/honeybadger-io/honeybadger-java/tree/master/honeybadger-java/src/main/java/io/honeybadger/reporter/servlet/HoneybadgerFilter.java) and enable it in your application. As for manual invocation of the API, you will need to configure your application to directly call the [reporter class](https://github.com/honeybadger-io/honeybadger-java/tree/master/honeybadger-java/src/main/java/io/honeybadger/reporter/HoneybadgerReporter.java). You can find more information about this in the stand-alone usage section. # Honeybadger for Node.js and JavaScript > Complete guide to Honeybadger's JavaScript error tracking and application monitoring platform for browser and Node.js applications. Hi there! You’ve found Honeybadger’s docs on **Universal JavaScript exception tracking**. In these guides we’re going to discuss [`honeybadger.js`](https://github.com/honeybadger-io/honeybadger-js) and how to use it to track exceptions in your **Client-side JavaScript and Node.js applications**. ## How you should read the docs [Section titled “How you should read the docs”](#how-you-should-read-the-docs) * For **client-side** JavaScript, start with the [Browser Integration Guide](/lib/javascript/integration/browser/). * For **server-side** JavaScript, start with the [Node.js Integration Guide](/lib/javascript/integration/node/). * The **How-To Guides** (in the left-hand navigation menu) are general guides on how to do things with the library, and should apply to all types of applications. ## Getting support [Section titled “Getting support”](#getting-support) If you’re having trouble working with the library (such as you aren’t receiving error reports when you should be): 1. Upgrade to the latest version if possible (you can find a list of bugfixes and other changes in the [CHANGELOG](https://github.com/honeybadger-io/honeybadger-js/blob/master/CHANGELOG.md)) 2. Check out our [Frequently Asked Questions](/lib/javascript/support/faq/) 3. Run through the [Troubleshooting guide](/lib/javascript/support/troubleshooting/) 4. If you believe you’ve found a bug, [submit an issue on GitHub](https://github.com/honeybadger-io/honeybadger-js/issues/) For all other problems, contact support for help: # Capturing events with breadcrumbs > Add breadcrumbs to JavaScript error reports to track events and user actions leading up to errors. **Breadcrumbs** are events that happen right before an error occurs. Honeybadger captures [many types of breadcrumbs](#automatic-breadcrumbs) automatically, such as click events, console logs, and Ajax requests. You can enhance your ability to rapidly understand and fix your errors by capturing additional breadcrumbs throughout your application. ## Capturing breadcrumbs [Section titled “Capturing breadcrumbs”](#capturing-breadcrumbs) To capture a breadcrumb anywhere in your application: ```js Honeybadger.addBreadcrumb("Sent Email", { metadata: { user_id: user.id, body: body }, }); ``` The first argument (`message`) is the only required data. In the UI, `message` is front and center in your breadcrumbs list, so we prefer a more terse description accompanied by rich metadata. Here are the supported options when adding breadcrumbs: | Option name | Description | | ----------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ | | `metadata` | A (*optional*) `Object` that contains any contextual data to help debugging. Must be a single-level object with simple primitives (strings, numbers, booleans) as values. | | `category` | An (*optional*) `string` key used to group specific types of events. We primarily use this key to display a corresponding icon, however, you can use it for your own categorization if you like. | ### Categories [Section titled “Categories”](#categories) A Breadcrumb category is a top level property. It’s main purpose is to allow for display differences (icons & styling) in the UI. You may give a breadcrumb any category you wish. Unknown categories will default to the “custom” styling. Here are the current categories and a brief description of how you might categorize certain activity: | Category | Description | | -------- | ------------------------------------------- | | custom | Any other kind of breadcrumb | | error | A thrown error | | query | Access or Updates to any data or file store | | job | Queueing or Working via a job system | | request | Outbound / inbound requests | | render | Any output or serialization via templates | | log | Any messages logged | | notice | A Honeybadger Notice | ## Automatic breadcrumbs [Section titled “Automatic breadcrumbs”](#automatic-breadcrumbs) Honeybadger captures the following breadcrumbs automatically by instrumenting browser features: * Clicks * Console logs * Errors * History/location changes * Network requests (XHR and fetch) ## Enabling/disabling breadcrumbs [Section titled “Enabling/disabling breadcrumbs”](#enablingdisabling-breadcrumbs) Breadcrumbs are enabled by default. To disable breadcrumbs in your project: ```js Honeybadger.configure({ // ... breadcrumbsEnabled: false, }); ``` You can also enable/disable specific types of breadcrumbs: ```js Honeybadger.configure({ breadcrumbsEnabled: { dom: true, network: true, navigation: true, console: true, }, }); ``` *Note: This configuration applies only on the first call to `Honeybadger.configure`.* # Capturing cross-domain script errors > Capture errors from cross-domain scripts in JavaScript applications with proper CORS configuration. Honeybadger ignores cross-domain script errors by default because they contain no useful information. You can fix this by loading your scripts with [CORS](https://developer.mozilla.org/en-US/docs/Web/HTTP/CORS). To enable CORS on your cross-domain scripts, add the CORS header to your web-server: ```plaintext Access-Control-Allow-Origin: * ``` Then add the [`crossorigin`](https://developer.mozilla.org/en-US/docs/Web/HTML/CORS_settings_attributes) attribute to your script tag: ```plaintext ``` Note Errors that happen in development and test environments are not reported by default. To always report errors or to change the defaults, see [Environments and Versions](/lib/javascript/errors/environments-and-versions/#development-environments). Here’s a video walkthrough of a basic, global installation: [![Using Honeybadger with JavaScript](https://embed-ssl.wistia.com/deliveries/0881945df2b2413bf15aba6fc853a7b477218048.jpg?image_play_button=true\&image_play_button_color=7b796ae0\&image_crop_resized=150x84)](https://honeybadger.wistia.com/medias/8wkvbipxxj) ### Non-blocking loading [Section titled “Non-blocking loading”](#non-blocking-loading) The default CDN installation above loads `honeybadger.min.js` synchronously so that Honeybadger’s `window.onerror` handler is in place before any other scripts run. This ensures automatic error catching works for all errors, but it means the script is render-blocking. If page load performance is a concern, you can load the script with the `defer` attribute: ```html ``` The `defer` attribute makes the CDN script download without blocking render and execute after the HTML is parsed. Since `defer` only applies to external scripts, the inline configure call uses a `DOMContentLoaded` listener to ensure it runs after the deferred script has executed. **Trade-offs to be aware of:** * **If you only use manual `Honeybadger.notify()` calls** (i.e., `enableUncaught` and `enableUnhandledRejection` are both `false`), then `defer` can be used safely as long as your `notify()` calls also run after the notifier has loaded — for example, in deferred or bundled application scripts. * **If you rely on automatic error catching** (the default), any uncaught errors or unhandled promise rejections that occur *before* the deferred script executes will not be captured. In practice, this is a small window — deferred scripts run after the DOM is parsed but before the `DOMContentLoaded` event. As an alternative, [bundling Honeybadger with npm](#installing-via-npmyarn) eliminates the extra network request entirely and gives you full control over load timing. ### Installing via NPM/YARN [Section titled “Installing via NPM/YARN”](#installing-via-npmyarn) ```plaintext # npm npm install @honeybadger-io/js --save # yarn yarn add @honeybadger-io/js ``` You can include *honeybadger.js* from the `node_modules` directory. #### Bundling with ESM (esbuild), CommonJS (Browserify/Webpack), etc. [Section titled “Bundling with ESM (esbuild), CommonJS (Browserify/Webpack), etc.”](#bundling-with-esm-esbuild-commonjs-browserifywebpack-etc) ```sh // ES module import Honeybadger from '@honeybadger-io/js'; // CommonJS var Honeybadger = require("path/to/honeybadger"); Honeybadger.configure({ apiKey: 'PROJECT_API_KEY', environment: 'production', revision: 'git SHA/project version' }); ``` * See an [example browserify + honeybadger.js project](https://github.com/honeybadger-io/honeybadger-js/tree/master/examples/browserify). * See an [example webpack + honeybadger.js project](https://github.com/honeybadger-io/honeybadger-js/tree/master/examples/webpack). #### RequireJS (AMD) [Section titled “RequireJS (AMD)”](#requirejs-amd) ```sh requirejs(["path/to/honeybadger"], function(Honeybadger) { Honeybadger.configure({ apiKey: 'PROJECT_API_KEY', environment: 'production', revision: 'git SHA/project version' }); }); ``` * See an [example requirejs + honeybadger.js project](https://github.com/honeybadger-io/honeybadger-js/tree/master/examples/requirejs). ## Reporting errors [Section titled “Reporting errors”](#reporting-errors) By default Honeybadger will report all uncaught exceptions automatically using our `window.onerror` handler. You can also manually notify Honeybadger of errors and other events in your application code: ```javascript try { // ...error producing code... } catch (error) { Honeybadger.notify(error); } ``` ## Identifying users [Section titled “Identifying users”](#identifying-users) Honeybadger can track what users have encountered each error. To identify the current user in error reports, add a user identifier and/or email address with `Honeybadger.context`: ```javascript Honeybadger.setContext({ user_id: 123, user_email: "user@example.com", }); ``` ## Tracking deploys [Section titled “Tracking deploys”](#tracking-deploys) Honeybadger can also keep track of application deployments, and link errors to the version which the error occurred in. Here’s a simple `curl` script to record a deployment: ```sh HONEYBADGER_ENV="production" \ HONEYBADGER_REVISION="$(git rev-parse HEAD)" \ HONEYBADGER_REPOSITORY="$(git config --get remote.origin.url)" \ HONEYBADGER_API_KEY="Your project API key" \ && curl -g "https://api.honeybadger.io/v1/deploys?deploy[environment]=$HONEYBADGER_ENV&deploy[local_username]=$USER&deploy[revision]=$HONEYBADGER_REVISION&deploy[repository]=$HONEYBADGER_REPOSITORY&api_key=$HONEYBADGER_API_KEY" ``` Be sure that the same revision is also configured in the *honeybadger.js* library. Read more about deploy tracking in the [API docs](/api/deployments/). ### Tracking deploys from Netlify [Section titled “Tracking deploys from Netlify”](#tracking-deploys-from-netlify) If you are deploying your site to Netlify, you can notify Honeybadger of deployments via Netlify’s webhooks. Go to the **Deploy notifications** section of the **Build & deploy** tab for your site settings, and choose to add an Outgoing webhook notification. Choose `Deploy succeeded` as the event to listen for, and use this format for your URL: `https://api.honeybadger.io/v1/deploys/netlify?api_key=YOUR_HONEYBADGER_API_KEY_HERE` The environment that will be reported to Honeybadger defaults to the Netlify environment that was deployed, but you can override that with `&environment=CUSTOM_ENV` in the webhook URL, if you like. ## Source map support [Section titled “Source map support”](#source-map-support) Honeybadger can automatically un-minify your code if you provide a source map along with your minified JavaScript files. See our [Source Map Guide](/lib/javascript/errors/using-source-maps/) for details. ## Collect user feedback [Section titled “Collect user feedback”](#collect-user-feedback) When an error occurs, a form can be shown to gather feedback from your users. Read more about this feature [here](/lib/javascript/errors/collecting-user-feedback/). # Chrome Extension integration guide > Honeybadger monitors your Chrome extensions for errors and exceptions so that you can fix them wicked fast. **Typical installation time:** 5 minutes Hi there! You’ve found Honeybadger’s guide to **JavaScript error and exception tracking for your chrome extensions**. Once installed, Honeybadger will automatically report errors from your chrome extension. ## Installation [Section titled “Installation”](#installation) Code in Chrome extensions can run in different execution contexts, such as background scripts, content scripts, and popup or options pages. To monitor errors in all these contexts, you need to include the Honeybadger.js library in each of them. Download the minified version of honeybadger.js to your source code from Honeybadger’s CDN (i.e. ) and save under in your extension’s source code (i.e. `/vendor`). ### Options and popup pages [Section titled “Options and popup pages”](#options-and-popup-pages) For the html (`options` or `popup`) pages, place the following code between the `` tags of your page: ```html ``` ### Background scripts [Section titled “Background scripts”](#background-scripts) For background scripts, add the following code at the top of your background script: ```javascript importScripts(chrome.runtime.getURL("vendor/honeybadger.ext.min.js")); Honeybadger.configure({ apiKey: "PROJECT_API_KEY", environment: "production", revision: "git SHA/project version", }); ``` ### Content scripts [Section titled “Content scripts”](#content-scripts) Finally, for content scripts, the manifest file should also be updated to include the Honeybadger library: ```json { "content_scripts": [ { "matches": [""], "js": ["vendor/honeybadger.ext.min.js", "content-script.js"] } ] } ``` Then, inside the `content-script.js` file, configure Honeybadger: ```javascript Honeybadger.configure({ apiKey: "PROJECT_API_KEY", environment: "production", revision: "git SHA/project version", }); ``` Note Errors that happen in development and test environments are not reported by default. To always report errors or to change the defaults, see [Environments and Versions](/lib/javascript/errors/environments-and-versions/#development-environments). See an [example chrome extension + honeybadger.js project](https://github.com/honeybadger-io/honeybadger-js/tree/master/packages/js/examples/chrome-extension). ## Reporting errors [Section titled “Reporting errors”](#reporting-errors) By default Honeybadger will report all uncaught exceptions automatically using our `window.onerror` handler. You can also manually notify Honeybadger of errors and other events in your application code: ```javascript try { // ...error producing code... } catch (error) { Honeybadger.notify(error); } ``` ## Identifying users [Section titled “Identifying users”](#identifying-users) Honeybadger can track what users have encountered each error. To identify the current user in error reports, add a user identifier and/or email address with `Honeybadger.context`: ```javascript Honeybadger.setContext({ user_id: 123, user_email: "user@example.com", }); ``` ## Tracking deploys [Section titled “Tracking deploys”](#tracking-deploys) Honeybadger can also keep track of application deployments, and link errors to the version which the error occurred in. Here’s a simple `curl` script to record a deployment: ```sh HONEYBADGER_ENV="production" \ HONEYBADGER_REVISION="$(git rev-parse HEAD)" \ HONEYBADGER_REPOSITORY="$(git config --get remote.origin.url)" \ HONEYBADGER_API_KEY="Your project API key" \ && curl -g "https://api.honeybadger.io/v1/deploys?deploy[environment]=$HONEYBADGER_ENV&deploy[local_username]=$USER&deploy[revision]=$HONEYBADGER_REVISION&deploy[repository]=$HONEYBADGER_REPOSITORY&api_key=$HONEYBADGER_API_KEY" ``` Be sure that the same revision is also configured in the *honeybadger.js* library. Read more about deploy tracking in the [API docs](/api/deployments/). ## Source map support [Section titled “Source map support”](#source-map-support) Honeybadger can automatically un-minify your code if you provide a source map along with your minified JavaScript files. See our [Source Map Guide](/lib/javascript/errors/using-source-maps/) for details. ## Limitations [Section titled “Limitations”](#limitations) Google’s recent extension review policies forced us to remove the feature to [Collect User Feedback](/lib/javascript/errors/collecting-user-feedback/) in Chrome Extensions. If you are already using Honeybadger in your chrome extensions, please note that Google may reject your extension when you update it. In that case, please download a new build build from our [CDN](https://js.honeybadger.io/v6.16/honeybadger.ext.min.js) and replace the existing build in your extension. If you are using the Collect User Feedback feature in your extension and would like to have it in the future, please let us know! # Ember integration guide > Honeybadger monitors your Ember applications for errors and exceptions so that you can fix them wicked fast. **Typical installation time:** 5 minutes Hi there! You’ve found Honeybadger’s guide to **Ember error and exception tracking**. Once installed, Honeybadger will automatically report errors from your Ember application. ## Installation [Section titled “Installation”](#installation) First, install *honeybadger.js*: ```plaintext # npm npm add @honeybadger-io/js --save # yarn yarn add @honeybadger-io/js ``` Then, configure Ember’s [`onerror`](https://guides.emberjs.com/release/configuring-ember/debugging/#toc_miscellaneous) handler to report errors to Honeybadger: ```js // Import honeybadger.js import * as Honeybadger from "@honeybadger-io/js"; // Configure honeybadger.js Honeybadger.configure({ apiKey: "PROJECT_API_KEY", environment: "production", revision: "git SHA/project version", }); // Configure Ember's onerror handler Ember.onerror = function (error) { Honeybadger.notify(error); }; ``` Note Errors that happen in development and test environments are not reported by default. To always report errors or to change the defaults, see [Environments and Versions](/lib/javascript/errors/environments-and-versions/#development-environments). ## Reporting errors [Section titled “Reporting errors”](#reporting-errors) In addition to Ember’s `onerror` handler, Honeybadger will report all uncaught exceptions automatically using our `window.onerror` handler. To disable uncaught error reporting: ```js Honeybadger.configure({ enableUncaught: false }); ``` You can also manually notify Honeybadger of errors and other events in your application code: ```javascript try { // ...error producing code... } catch (error) { Honeybadger.notify(error); } ``` See the [Reporting Errors How-to Guide](/lib/javascript/errors/reporting-errors/) for more info. ## Identifying users [Section titled “Identifying users”](#identifying-users) Honeybadger can track what users have encountered each error. To identify the current user in error reports, add a user identifier and/or email address with `Honeybadger.context`: ```javascript Honeybadger.setContext({ user_id: 123, user_email: "user@example.com", }); ``` ## Tracking deploys [Section titled “Tracking deploys”](#tracking-deploys) As with vanilla JavaScript applications, you can notify Honeybadger when you’ve deployed a new build. Honeybadger will associate an error report with a specific revision number (matching the ‘revision’ field in your *honeybadger.js* configuration). Here’s a simple `curl` script to record a deployment: ```sh HONEYBADGER_ENV="production" \ HONEYBADGER_REVISION="$(git rev-parse HEAD)" \ HONEYBADGER_REPOSITORY="$(git config --get remote.origin.url)" \ HONEYBADGER_API_KEY="Your project API key" \ && curl -g "https://api.honeybadger.io/v1/deploys?deploy[environment]=$HONEYBADGER_ENV&deploy[local_username]=$USER&deploy[revision]=$HONEYBADGER_REVISION&deploy[repository]=$HONEYBADGER_REPOSITORY&api_key=$HONEYBADGER_API_KEY" ``` Be sure that the same revision is also configured in the *honeybadger.js* library. Read more about deploy tracking in the [API docs](/api/deployments). ### Tracking deploys from Netlify [Section titled “Tracking deploys from Netlify”](#tracking-deploys-from-netlify) If you are deploying your site to Netlify, you can notify Honeybadger of deployments via Netlify’s webhooks. Go to the **Deploy notifications** section of the **Build & deploy** tab for your site settings, and choose to add an Outgoing webhook notification. Choose `Deploy succeeded` as the event to listen for, and use this format for your URL: `https://api.honeybadger.io/v1/deploys/netlify?api_key=YOUR_HONEYBADGER_API_KEY_HERE` The environment that will be reported to Honeybadger defaults to the Netlify environment that was deployed, but you can override that with `&environment=CUSTOM_ENV` in the webhook URL, if you like. ## Source map support [Section titled “Source map support”](#source-map-support) Honeybadger can automatically un-minify your code if you provide a source map along with your minified JavaScript files. See our [Source Map Guide](/lib/javascript/errors/using-source-maps/) for details. ## Collect user feedback [Section titled “Collect user feedback”](#collect-user-feedback) When an error occurs, a form can be shown to gather feedback from your users. Read more about this feature [here](/lib/javascript/errors/collecting-user-feedback/). # Next.js integration guide > Honeybadger monitors your Next.js applications for errors and exceptions so that you can fix them wicked fast. **Typical installation time:** 7 minutes Hi there! You’ve found Honeybadger’s guide to **Next.js error and exception tracking**. Once installed, Honeybadger will automatically report errors from your Next.js application. The `@honeybadger-io/nextjs` package utilizes the packages `@honeybadger-io/js`, `@honeybadger-io/react` and `@honeybadger-io/webpack` under the hood to provide a simplified integration package for Next.js applications. You can always refer to these packages’ documentation for more information and advanced configuration. ## Features [Section titled “Features”](#features) * App Router support (added with Next.js 13) * Automatic reporting of uncaught exceptions (see [Limitations](#limitations)) * Breadcrumbs * Source map upload to Honeybadger * CLI command to generate Honeybadger configuration files for Next.js runtimes ## Installation [Section titled “Installation”](#installation) Add `@honeybadger-io/nextjs` and `@honeybadger-io/react` as dependencies. ```plaintext # npm npm add @honeybadger-io/react @honeybadger-io/nextjs --save # yarn yarn add @honeybadger-io/react @honeybadger-io/nextjs ``` ## Configuration [Section titled “Configuration”](#configuration) Note Honeybadger needs a configuration file for each Next.js runtime. Additionally, some more configuration in `next.config.js` is required to setup the runtime and upload source maps to Honeybadger. Even though you can configure each file separately, we recommend to use Honeybadger’s environment variables to set configuration values once: `NEXT_PUBLIC_HONEYBADGER_API_KEY` (Honeybadger API key), `NEXT_PUBLIC_HONEYBADGER_REVISION` (Revision of current deployment) and `NEXT_PUBLIC_HONEYBADGER_ASSETS_URL` (URL to your public assets). Run the following command, which generates configuration files in your project root for each Next.js runtime: ```plaintext npx honeybadger-copy-config-files ``` The following files will added to your project: * `honeybadger.server.config.js` - Configuration file for Next.js server runtime * `honeybadger.client.config.js` - Configuration file for Next.js client runtime * `honeybadger.edge.config.js` - Configuration file for Next.js Edge runtime * `pages/_error.[js|tsx]` - Next.js Pages Router custom error component - if *pages* folder exists * `app/error.[js|tsx]` - Next.js App Router custom error component - if *app* folder exists * `app/global-error.[js|tsx]` - Next.js App Router global error component - if *app* folder exists **Note**: The `honeybadger.edge.config.js` file is necessary if you deploy your Next.js application to Vercel and use [Vercel Edge Functions](https://vercel.com/features/edge-functions). If not, you can safely remove this file. **Note**: The script will create backups of any existing files. In your `next.config.js`: ```javascript const { setupHoneybadger } = require("@honeybadger-io/nextjs"); const moduleExports = { // ... Your existing module.exports object goes here }; // Showing default values const honeybadgerNextJsConfig = { // Disable source map upload (optional) disableSourceMapUpload: false, // Hide debug messages (optional) silent: true, // More information available at @honeybadger-io/webpack: https://github.com/honeybadger-io/honeybadger-js/tree/master/packages/webpack webpackPluginOptions: { // Required if you want to upload source maps to Honeybadger apiKey: process.env.NEXT_PUBLIC_HONEYBADGER_API_KEY, // Required if you want to upload source maps to Honeybadger assetsUrl: process.env.NEXT_PUBLIC_HONEYBADGER_ASSETS_URL, revision: process.env.NEXT_PUBLIC_HONEYBADGER_REVISION, endpoint: "https://api.honeybadger.io/v1/source_maps", ignoreErrors: false, retries: 3, workerCount: 5, deploy: { environment: process.env.NEXT_PUBLIC_VERCEL_ENV || process.env.VERCEL_ENV || process.env.NODE_ENV, repository: "https://url.to.git.repository", localUsername: "username", }, }, }; module.exports = setupHoneybadger(moduleExports, honeybadgerNextJsConfig); ``` **Note**: If you want to upload source maps to Honeybadger, ensure that `disableSourceMapUpload` is set to `false` and that `apiKey` and `assetsUrl` properties are set in `webpackPluginOptions`. **Note**: The value of `assetsUrl` should be the URL to your domain suffixed with `_next`. For example if you app is deployed on Vercel and has the domain `my-app.vercel.app`, the value of `assetsUrl` should be `https://my-app.vercel.app/_next`. Optionally, you can use Honeybadger’s Error Boundary component to collect additional React contextual information for errors that occur in your React components. Simply wrap the `Component` prop in your `_app.js` file: ```jsx import { Honeybadger, HoneybadgerErrorBoundary } from "@honeybadger-io/react"; function MyApp({ Component, pageProps }) { return ( ); } export default MyApp; ``` You can read more about Error Boundaries in the [React documentation](https://reactjs.org/docs/error-boundaries.html). Note Errors that happen in development and test environments are not reported by default. To always report errors or to change the defaults, see [Environments and Versions](/lib/javascript/errors/environments-and-versions/#development-environments). ## Insights instrumentation [Section titled “Insights instrumentation”](#insights-instrumentation) Enable Insights HTTP instrumentation in your Honeybadger config files to record a `request.handled` event for each inbound request. Export the config object so API and edge handlers can reuse it: honeybadger.server.config.js ```javascript import Honeybadger from "@honeybadger-io/js"; export const config = { apiKey: process.env.NEXT_PUBLIC_HONEYBADGER_API_KEY, environment: process.env.NEXT_PUBLIC_VERCEL_ENV || process.env.VERCEL_ENV || process.env.NODE_ENV, revision: process.env.NEXT_PUBLIC_HONEYBADGER_REVISION, insights: { enabled: true, http: true }, }; Honeybadger.configure(config); ``` Do the same in `honeybadger.edge.config.js` when you use the Edge runtime. Wrap App Router route handlers, Pages Router API routes, middleware, and edge handlers with `withHoneybadger` from `@honeybadger-io/nextjs`. When Insights HTTP is enabled, each request emits `request.handled` with method, path, status, duration, `request_id`, and `correlation_id`. Pass config explicitly for API and edge handlers Webpack config-file auto-injection only reaches pages such as `_app`, `_document`, `_error`, and the App Router `main-app` entry. It does **not** reach API routes (`pages/api/*`, `app/api/*`) or edge middleware. Pass your exported config as the second argument to `withHoneybadger` in those files. The argument is ignored if Honeybadger is already configured, so it is safe to pass everywhere. App Router route handler: ```typescript import { NextResponse } from "next/server"; import { withHoneybadger } from "@honeybadger-io/nextjs"; import { config } from "../../../honeybadger.server.config"; export const GET = withHoneybadger(async () => { return NextResponse.json({ message: "hello" }); }, config); ``` Pages Router API route: ```javascript import { withHoneybadger } from "@honeybadger-io/nextjs"; import { config } from "../../honeybadger.server.config"; export default withHoneybadger((req, res) => { res.status(200).json({ message: "hello" }); }, config); ``` Edge route (import from `honeybadger.edge.config.js`): ```typescript import { NextResponse } from "next/server"; import { withHoneybadger } from "@honeybadger-io/nextjs"; import { config } from "../../../honeybadger.edge.config"; export const runtime = "edge"; export const GET = withHoneybadger(async () => { return NextResponse.json({ message: "hello from the edge" }); }, config); ``` Middleware (also runs on the edge runtime — pass edge config explicitly): ```typescript import { NextResponse } from "next/server"; import type { NextRequest } from "next/server"; import { withHoneybadger } from "@honeybadger-io/nextjs"; import { config } from "./honeybadger.edge.config"; export const middleware = withHoneybadger((request: NextRequest) => { return NextResponse.next(); }, config); ``` On the Node.js runtime, `request_id` and `correlation_id` are seeded onto the event context, so programmatic `Honeybadger.event(...)` calls during the request inherit them. On the **edge** runtime, those IDs are included on the `request.handled` event itself, but programmatic events do not inherit them (the edge build uses a shared global store that cannot safely isolate concurrent requests). For the full Insights configuration surface (including console logs, filtering, and sampling), see [Automatic instrumentation](/lib/javascript/insights/automatic-instrumentation/). ## Reporting errors [Section titled “Reporting errors”](#reporting-errors) The above configuration will automatically report errors to Honeybadger in most cases (see [Limitations](#limitations)), but you can also report errors manually: ```javascript import { Honeybadger } from "@honeybadger-io/react"; Honeybadger.notify(error); ``` ## Identifying users [Section titled “Identifying users”](#identifying-users) Honeybadger can track which users have encountered each error. To identify the current user in error reports, add a user identifier and/or email address with `Honeybadger.setContext`: ```javascript import { Honeybadger } from "@honeybadger-io/react"; Honeybadger.setContext({ user_id: 123, user_email: "user@example.com", }); ``` ## Sending additional context [Section titled “Sending additional context”](#sending-additional-context) Sometimes additional application state may be helpful for diagnosing errors. You can arbitrarily specify additional key/value pairs when you invoke `setContext`. ```javascript import { Honeybadger } from "@honeybadger-io/react"; Honeybadger.setContext({ active_organization: 55, custom_configuration: false, }); ``` ## Clearing context [Section titled “Clearing context”](#clearing-context) If your user logs out or if your context changes during the React component lifetime, you can set new values as appropriate by invoking `setContext` again. Additionally, if needed, you can clear the context by invoking `clear`: ```javascript import { Honeybadger } from "@honeybadger-io/react"; // Set the context to {} Honeybadger.clear(); ``` ## Advanced usage [Section titled “Advanced usage”](#advanced-usage) `@honeybadger-io/nextjs` is built on [@honeybadger-io/js](https://github.com/honeybadger-io/honeybadger-js/tree/master/packages/js) and [@honeybadger-io/react](https://github.com/honeybadger-io/honeybadger-js/tree/master/packages/react). See the [Honeybadger JavaScript integration documentation](/lib/javascript/) for additional customization options, as well as the dedicated [React integration guide](/lib/javascript/integration/react/). ## Source map upload and tracking deploys [Section titled “Source map upload and tracking deploys”](#source-map-upload-and-tracking-deploys) Honeybadger can automatically un-minify your code if you provide a source map along with your minified JavaScript files. See our [Source Map Guide](/lib/javascript/errors/using-source-maps/) for details. Fill in the values under `webpackPluginOptions` in your `next.config.js` file to upload source maps to Honeybadger. You can notify Honeybadger when you’ve deployed a new build. Honeybadger will associate an error report with a specific revision number (matching the `revision` field in the configuration passed to `Honeybadger.configure`, found in one of your honeybadger.\[server|client|edge].config.js files). Set deploy information in your Honeybadger’s Next.js configuration under the `webpackPluginOptions.deploy` key. For more information, see [@honeybadger-io/webpack](https://github.com/honeybadger-io/honeybadger-js/tree/master/packages/webpack) documentation. ## Collect User Feedback [Section titled “Collect User Feedback”](#collect-user-feedback) When an error occurs, a form can be shown to gather feedback from your users. Honeybadger can automatically show the form by setting the `showUserFeedbackFormOnError` prop to `true`: ```javascript ``` Read more about this feature [here](/lib/javascript/errors/collecting-user-feedback/). ## Limitations [Section titled “Limitations”](#limitations) The following limitations are known to exist and will be tackled in future releases: * [Issue link](https://github.com/honeybadger-io/honeybadger-js/issues/1055): A custom error component is used to report uncaught exceptions to Honeybadger. This is necessary because Next.js does not provide a way to hook into the error handler. This is not a catch-all errors solution. If you are using the *Pages Router*, there are some caveats to this approach, as reported [here](https://nextjs.org/docs/advanced-features/custom-error-page#caveats). This is a limitation of Next.js, not Honeybadger’s Next.js integration. Errors thrown in middlewares or API routes will not be reported to Honeybadger, since when they reach the error component, the response status code is 404 and no error information is available. Additionally, there is an open [issue](https://github.com/vercel/next.js/issues/45535) about 404 being reported with Next.js apps deployed on Vercel, when they should be reported as 500. If you are using the *App Router*, these limitations do not apply, because errors thrown in middlewares or API routes do not reach the custom error component but are caught by the global `window.onerror` handler. However, some other server errors (i.e. from data fetching methods) will be reported with minimal information, since Next.js will send a [generic error message](https://nextjs.org/docs/app/building-your-application/routing/error-handling#handling-server-errors) to this component for better security. ## Sample applications [Section titled “Sample applications”](#sample-applications) Two sample applications are available in the [*examples*](https://github.com/honeybadger-io/honeybadger-js/tree/master/packages/nextjs/examples) folder. Follow the README instructions to run them. # Node.js integration guide > Honeybadger monitors your Node.js applications for errors and exceptions so that you can fix them wicked fast. **Typical installation time:** 3 minutes Hi there! You’ve found Honeybadger’s guide to **Node.js error and exception tracking**. Once installed, Honeybadger will automatically report errors from your Node.js application. Heads up! Between callbacks, promises, event emitters, and timers, error-handling in Node.js is a complex and difficult field, but we’re here to help! Our Node.js library tries to catch as many different kinds of errors as possible with minimal configuration; if you encounter problems setting it up or find any gaps, feel free to [open an issue](https://github.com/honeybadger-io/honeybadger-js/issues/new). ## Installation [Section titled “Installation”](#installation) First, install the npm package: ```sh npm install @honeybadger-io/js --save ``` Then, require the honeybadger module and configure your API key: ```javascript const Honeybadger = require("@honeybadger-io/js"); Honeybadger.configure({ apiKey: "[ YOUR API KEY HERE ]", }); ``` By default Honeybadger will be notified automatically of all unhandled errors which crash your node processes. Many applications catch errors, however, so you may want to set up some additional framework integrations. ## Framework integrations [Section titled “Framework integrations”](#framework-integrations) ### Express and Express-style frameworks [Section titled “Express and Express-style frameworks”](#express-and-express-style-frameworks) Errors which happen in [Express](http://expressjs.com/) or [Connect](https://github.com/senchalabs/connect#readme) apps can be automatically reported to Honeybadger by installing our middleware. The `requestHandler` middleware must be added before your other app middleware, while the `errorHandler` must be added after all app middleware and routes, but before any custom error handling middleware: ```javascript app.use(Honeybadger.requestHandler); // Use *before* all other app middleware. // Any other middleware and routes app.use(myMiddleware); app.get("/", (req, res) => {...}); app.use(Honeybadger.errorHandler); // Use *after* all other app middleware // Your custom error handling middleware app.use(myErrorMiddleware); ``` You can follow a similar pattern for most frameworks which use Express-style middleware: #### Restify [Section titled “Restify”](#restify) ```js const server = restify.createServer(); server.use(Honeybadger.requestHandler); // Other middleware and routes... server.on("restifyError", Honeybadger.errorHandler); ``` #### Sails.js [Section titled “Sails.js”](#sailsjs) For Sails.js, use `Honeybadger.errorHandler` to report errors from within your [custom `serverError` response](https://sailsjs.com/documentation/concepts/extending-sails/custom-responses). ```js const Honeybadger = require("@honeybadger-io/js"); module.exports = function serverError(optionalData) { if (_.isError(optionalData)) { Honeybadger.errorHandler(optionalData, this.req); return res.status(500).send(optionalData.stack); } }; ``` You should also add the `Honeybadger.requestHandler` at the start of your middleware chain so asynchronous context can be correctly tracked between requests: ```js // in config/http.js module.exports.http = { middleware: { order: [ "honeybadgerContext", // other middleware... ], honeybadgerContext: Honeybadger.requestHandler, }, }; ``` ### Non-Express-style frameworks [Section titled “Non-Express-style frameworks”](#non-express-style-frameworks) For frameworks that don’t use Express-style middleware, Honeybadger will still capture unhandled exceptions automatically, but you may need to add a few lines of code to capture other kinds of errors and use the context feature properly. Fastify has a dedicated plugin (below). For other frameworks, see [Tracking Context](#tracking-context). #### Fastify [Section titled “Fastify”](#fastify) Use the dedicated Fastify plugin. It is not exported from the main `@honeybadger-io/js` entry — import it from the deep path below. Install the optional peer package `fastify-plugin` (>= 4); `fastify` (>= 4) is also an optional peer. ```js const Honeybadger = require("@honeybadger-io/js"); const { fastifyPlugin } = require("@honeybadger-io/js/dist/server/fastify"); fastify.register(fastifyPlugin(Honeybadger)); fastify.setErrorHandler((err, req, reply) => Honeybadger.withRequest(req, () => { Honeybadger.notify(err); reply.send({ message: "error" }); }), ); ``` Do **not** register `Honeybadger.requestHandler` as a Fastify `preHandler` — that Express middleware expects a Node `ServerResponse` EventEmitter and is not compatible with Fastify’s reply object. The plugin isolates each request with `withRequest` and, when Insights HTTP instrumentation is enabled, emits `request.handled` events. See [Automatic instrumentation](/lib/javascript/insights/automatic-instrumentation/) for the full Insights setup. ### AWS Lambda [Section titled “AWS Lambda”](#aws-lambda) To automatically report errors which happen in your [AWS Lambda](https://aws.amazon.com/lambda/) functions, wrap your Lambda handlers in `Honeybadger.lambdaHandler()`: ```javascript async function myHandler(event, context) { // ... } exports.handler = Honeybadger.lambdaHandler(myHandler); ``` Check out our [example AWS Lambda project](https://github.com/honeybadger-io/honeybadger-js/tree/master/examples/aws-lambda) for a list of handlers with different settings. ##### Timeout warning [Section titled “Timeout warning”](#timeout-warning) If your Lambda function hits its [time limit](https://docs.aws.amazon.com/lambda/latest/dg/gettingstarted-limits.html#w329aad109b7b9), it will get killed by AWS Lambda without completing. Honeybadger can notify you when your function is about time out. By default, this will be when there are only 50 milliseconds left to reach the limit. You can override this with the `timeoutWarningThresholdMs` setting: ```javascript Honeybadger.configure({ timeoutWarningThresholdMs: 1000, }); ``` You can disable the timeout warning with the `reportTimeoutWarning` setting: ```javascript Honeybadger.configure({ reportTimeoutWarning: false, }); ``` To manually report errors in a serverless environment, use `Honeybadger.notifyAsync`. Read more below. ## Manually reporting errors [Section titled “Manually reporting errors”](#manually-reporting-errors) Honeybadger reports unhandled exceptions by default. You can also manually notify Honeybadger of errors and other events in your application code: ```javascript try { // ...error producing code... } catch (error) { Honeybadger.notify(error); } ``` `Honeybadger.notify` implements a *fire-and-forget* approach, which means that you can call the function and continue execution in your application code without waiting for the error to be reported. This is OK for most applications, but in some environments this can cause problems when the execution environment could be terminated before the report is sent to Honeybadger. For this reason, you may use `Honeybadger.notifyAsync` which is a promise-based implementation of `notify` and will resolve only after the report is sent: ```javascript async function doSomething() { try { // ...error producing code... } catch (error) { await Honeybadger.notifyAsync(error); } } ``` See the [full documentation](/lib/javascript/) for more options. ## Tracking context [Section titled “Tracking context”](#tracking-context) You can add contextual information to your error reports to make debugging easier: ```javascript Honeybadger.setContext({ query: searchQuery, }); ``` When an error is captured (manually or automatically), the context will be sent along in the error report and displayed in the Context section of the Honeybadger UI. Important In apps like web servers that handle multiple requests at the same time, you need to properly isolate each request’s context. For middleware-based frameworks like Express, this is done automatically when you use the `requestHandler` middleware. For other frameworks, you’ll need to wrap your request and error handlers in `Honeybadger.withRequest()` method and pass in the request object. Here are examples in some popular frameworks: ### AdonisJS [Section titled “AdonisJS”](#adonisjs) For AdonisJS, you’ll need to do three (easy) steps: * Create a middleware that wraps your request handlers with `withRequest()`). You can generate a middleware with `adonis make:middleware HoneybadgerContext` (v4) or `node ace make:middleware HoneybadgerContext` (v5): app/Middleware/HoneybadgerContext.js ```js // Adonis v5: app/Middleware/HoneybadgerContext.ts class HoneybadgerContext { async handle({ request, response }, next) { await Honeybadger.withRequest(request, next); } } ``` * Register the middleware: ```js // Adonis v4: in start/kernel.js const globalMiddleware = ["App/Middleware/HoneybadgerContext"]; // Adonis v5: in start/kernel.ts Server.middleware.register([() => import("App/Middleware/HoneybadgerContext")]); ``` * In your exception handler’s `report()` method, make sure to use `withRequest()`. (On Adonis v4, you may need to generate an exception handler with `adonis make:ehandler`): app/Exceptions/Handler.js ```js // Adonis v5: app/Exceptions/Handler.ts class ExceptionHandler extends BaseExceptionHandler { // ... async report(error, { request }) { Honeybadger.withRequest(request, () => Honeybadger.notify(error)); } } ``` ### Hapi [Section titled “Hapi”](#hapi) In Hapi, you’ll need to wrap your request handlers in `withRequest`, as well as add an `onPreResponse` extension to report errors. ```javascript server.route({ method: 'POST', path: '/search', handler: async (request, h) => Honeybadger.withRequest(request, () => { Honeybadger.setContext({ query: request.payload.searchQuery }); return ...; }) }); server.ext('onPreResponse', (request, h) => Honeybadger.withRequest(request, () => { if (!request.response.isBoom) { return h.continue; } Honeybadger.notify(request.response); return h.continue; })); ``` ## Identifying users [Section titled “Identifying users”](#identifying-users) Honeybadger can track what users have encountered each error. To identify the current user in error reports, add a user identifier and/or email address with `Honeybadger.setContext`: ```javascript Honeybadger.setContext({ user_id: 123, user_email: "user@example.com", }); ``` We’ll surface this info in a special “Affected Users” section in the Honeybadger UI. ## Tracking deploys [Section titled “Tracking deploys”](#tracking-deploys) Honeybadger can also keep track of application deployments, and link errors to the version which the error occurred in. Here’s a simple `curl` script to record a deployment: ```sh HONEYBADGER_ENV="production" \ HONEYBADGER_REVISION="$(git rev-parse HEAD)" \ HONEYBADGER_REPOSITORY="$(git config --get remote.origin.url)" \ HONEYBADGER_API_KEY="Your project API key" \ && curl -g "https://api.honeybadger.io/v1/deploys?deploy[environment]=$HONEYBADGER_ENV&deploy[local_username]=$USER&deploy[revision]=$HONEYBADGER_REVISION&deploy[repository]=$HONEYBADGER_REPOSITORY&api_key=$HONEYBADGER_API_KEY" ``` Be sure that the same revision is also configured in the honeybadger.js library. Read more about deploy tracking in the [API docs](/api/deployments/). ## Uncaught exceptions [Section titled “Uncaught exceptions”](#uncaught-exceptions) Honeybadger’s default uncaught exception handler logs the error and exits the process after notifying Honeybadger of the uncaught exception. You can change the default handler by replacing the `afterUncaught` config callback with a new handler function. Honeybadger will still be notified before your handler is invoked. Note that it’s important to exit the process cleanly if you replace the handler; see [Warning: using ‘uncaughtException’ correctly](https://nodejs.org/api/process.html#process_warning_using_uncaughtexception_correctly) for additional information. ### Examples [Section titled “Examples”](#examples) ```javascript Honeybadger.configure({ afterUncaught: (err) => { doSomethingWith(err); process.exit(1); }, }); ``` ### Disable Honeybadger’s uncaught error handler [Section titled “Disable Honeybadger’s uncaught error handler”](#disable-honeybadgers-uncaught-error-handler) To disable Honeybadger’s handler entirely (restoring Node’s default behavior for uncaught exceptions), use the `enableUncaught` option when calling `Honeybadger.configure`: ```javascript Honeybadger.configure({ apiKey: '[ YOUR API KEY HERE ]' enableUncaught: false }); ``` ## Source map support [Section titled “Source map support”](#source-map-support) Honeybadger can automatically un-minify your code if you provide a source map along with your minified JavaScript files. See our [Source Map Guide](/lib/javascript/errors/using-source-maps/) for details. Honeybadger also supports Node’s [experimental `--source-map-support` flag](https://nodejs.org/dist/latest-v14.x/docs/api/cli.html#cli_enable_source_maps) as of **version 14+**. If you run `node` with `--source-map-support` (and are generating source maps in your build), your stack traces should be automatically translated *before* they are sent to Honeybadger. ## Sample application [Section titled “Sample application”](#sample-application) If you’d like to see the library in action before you integrate it with your apps, check out our [sample Node.js/Express application](https://github.com/honeybadger-io/crywolf-node). You can deploy the sample app to your Heroku account by clicking this button: [![Deploy](https://www.herokucdn.com/deploy/button.png)](https://heroku.com/deploy?template=https://github.com/honeybadger-io/crywolf-node) Don’t forget to destroy the Heroku app after you’re done so that you aren’t charged for usage. The code for the sample app is [available on Github](https://github.com/honeybadger-io/crywolf-node), in case you’d like to read through it, or run it locally. # React integration guide > Honeybadger monitors your React applications for errors and exceptions so that you can fix them wicked fast. **Typical installation time:** 5 minutes Hi there! You’ve found Honeybadger’s guide to **React error and exception tracking**. Once installed, Honeybadger will automatically report errors from your React application. ## Installation [Section titled “Installation”](#installation) Add *@honeybadger-io/react* as a dependency. ```plaintext # npm npm add @honeybadger-io/js @honeybadger-io/react --save # yarn yarn add @honeybadger-io/js @honeybadger-io/react ``` In your main.js: ```javascript import React from "react"; import ReactDOM from "react-dom"; import "./index.css"; import App from "./App"; import { Honeybadger, HoneybadgerErrorBoundary } from "@honeybadger-io/react"; const config = { apiKey: "PROJECT_API_KEY", environment: "production", revision: "git SHA/project version", }; const honeybadger = Honeybadger.configure(config); ReactDOM.render( , document.getElementById("root"), ); ``` Note Errors that happen in development and test environments are not reported by default. To always report errors or to change the defaults, see [Environments and Versions](/lib/javascript/errors/environments-and-versions/#development-environments). ### `HoneyBadgerErrorBoundary` props [Section titled “HoneyBadgerErrorBoundary props”](#honeybadgererrorboundary-props) * `honeybadger` The Honeybadger config object. * `children` Your root `` component. * `ErrorComponent` (optional — default: “DefaultErrorComponent”) The component that will be rendered in `ErrorBoundary` children’s place when an error is thrown during React rendering. The default value for this prop is the `DefaultErrorComponent`. #### DefaultErrorComponent [Section titled “DefaultErrorComponent”](#defaulterrorcomponent) ```jsx class DefaultErrorComponent extends Component { render() { return (
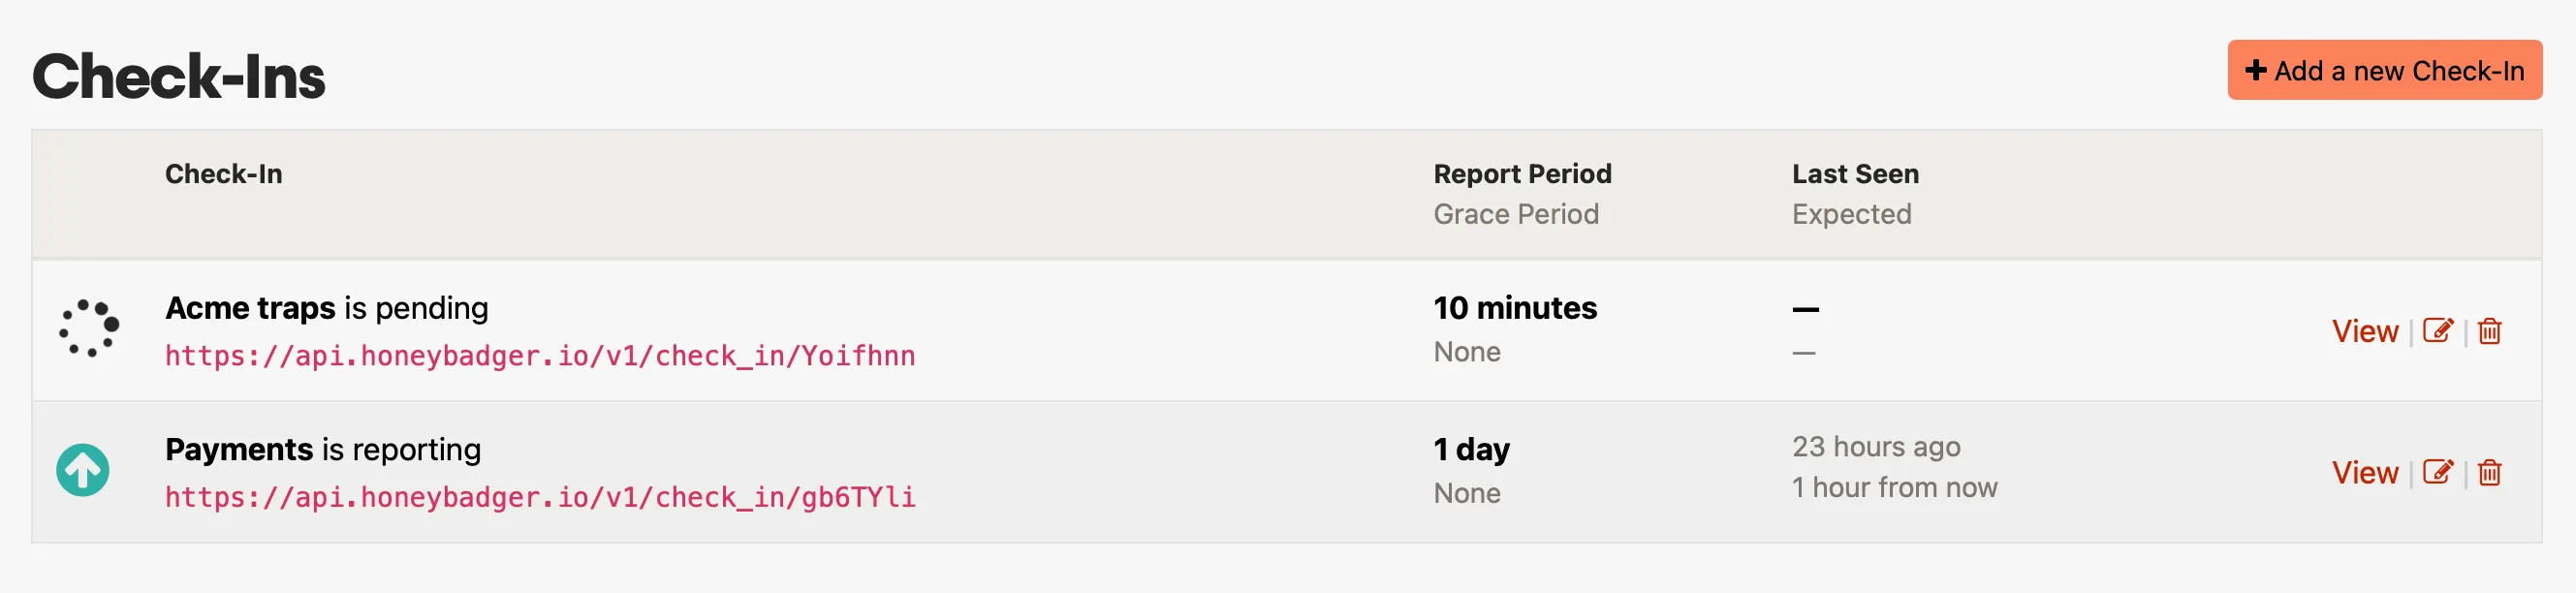
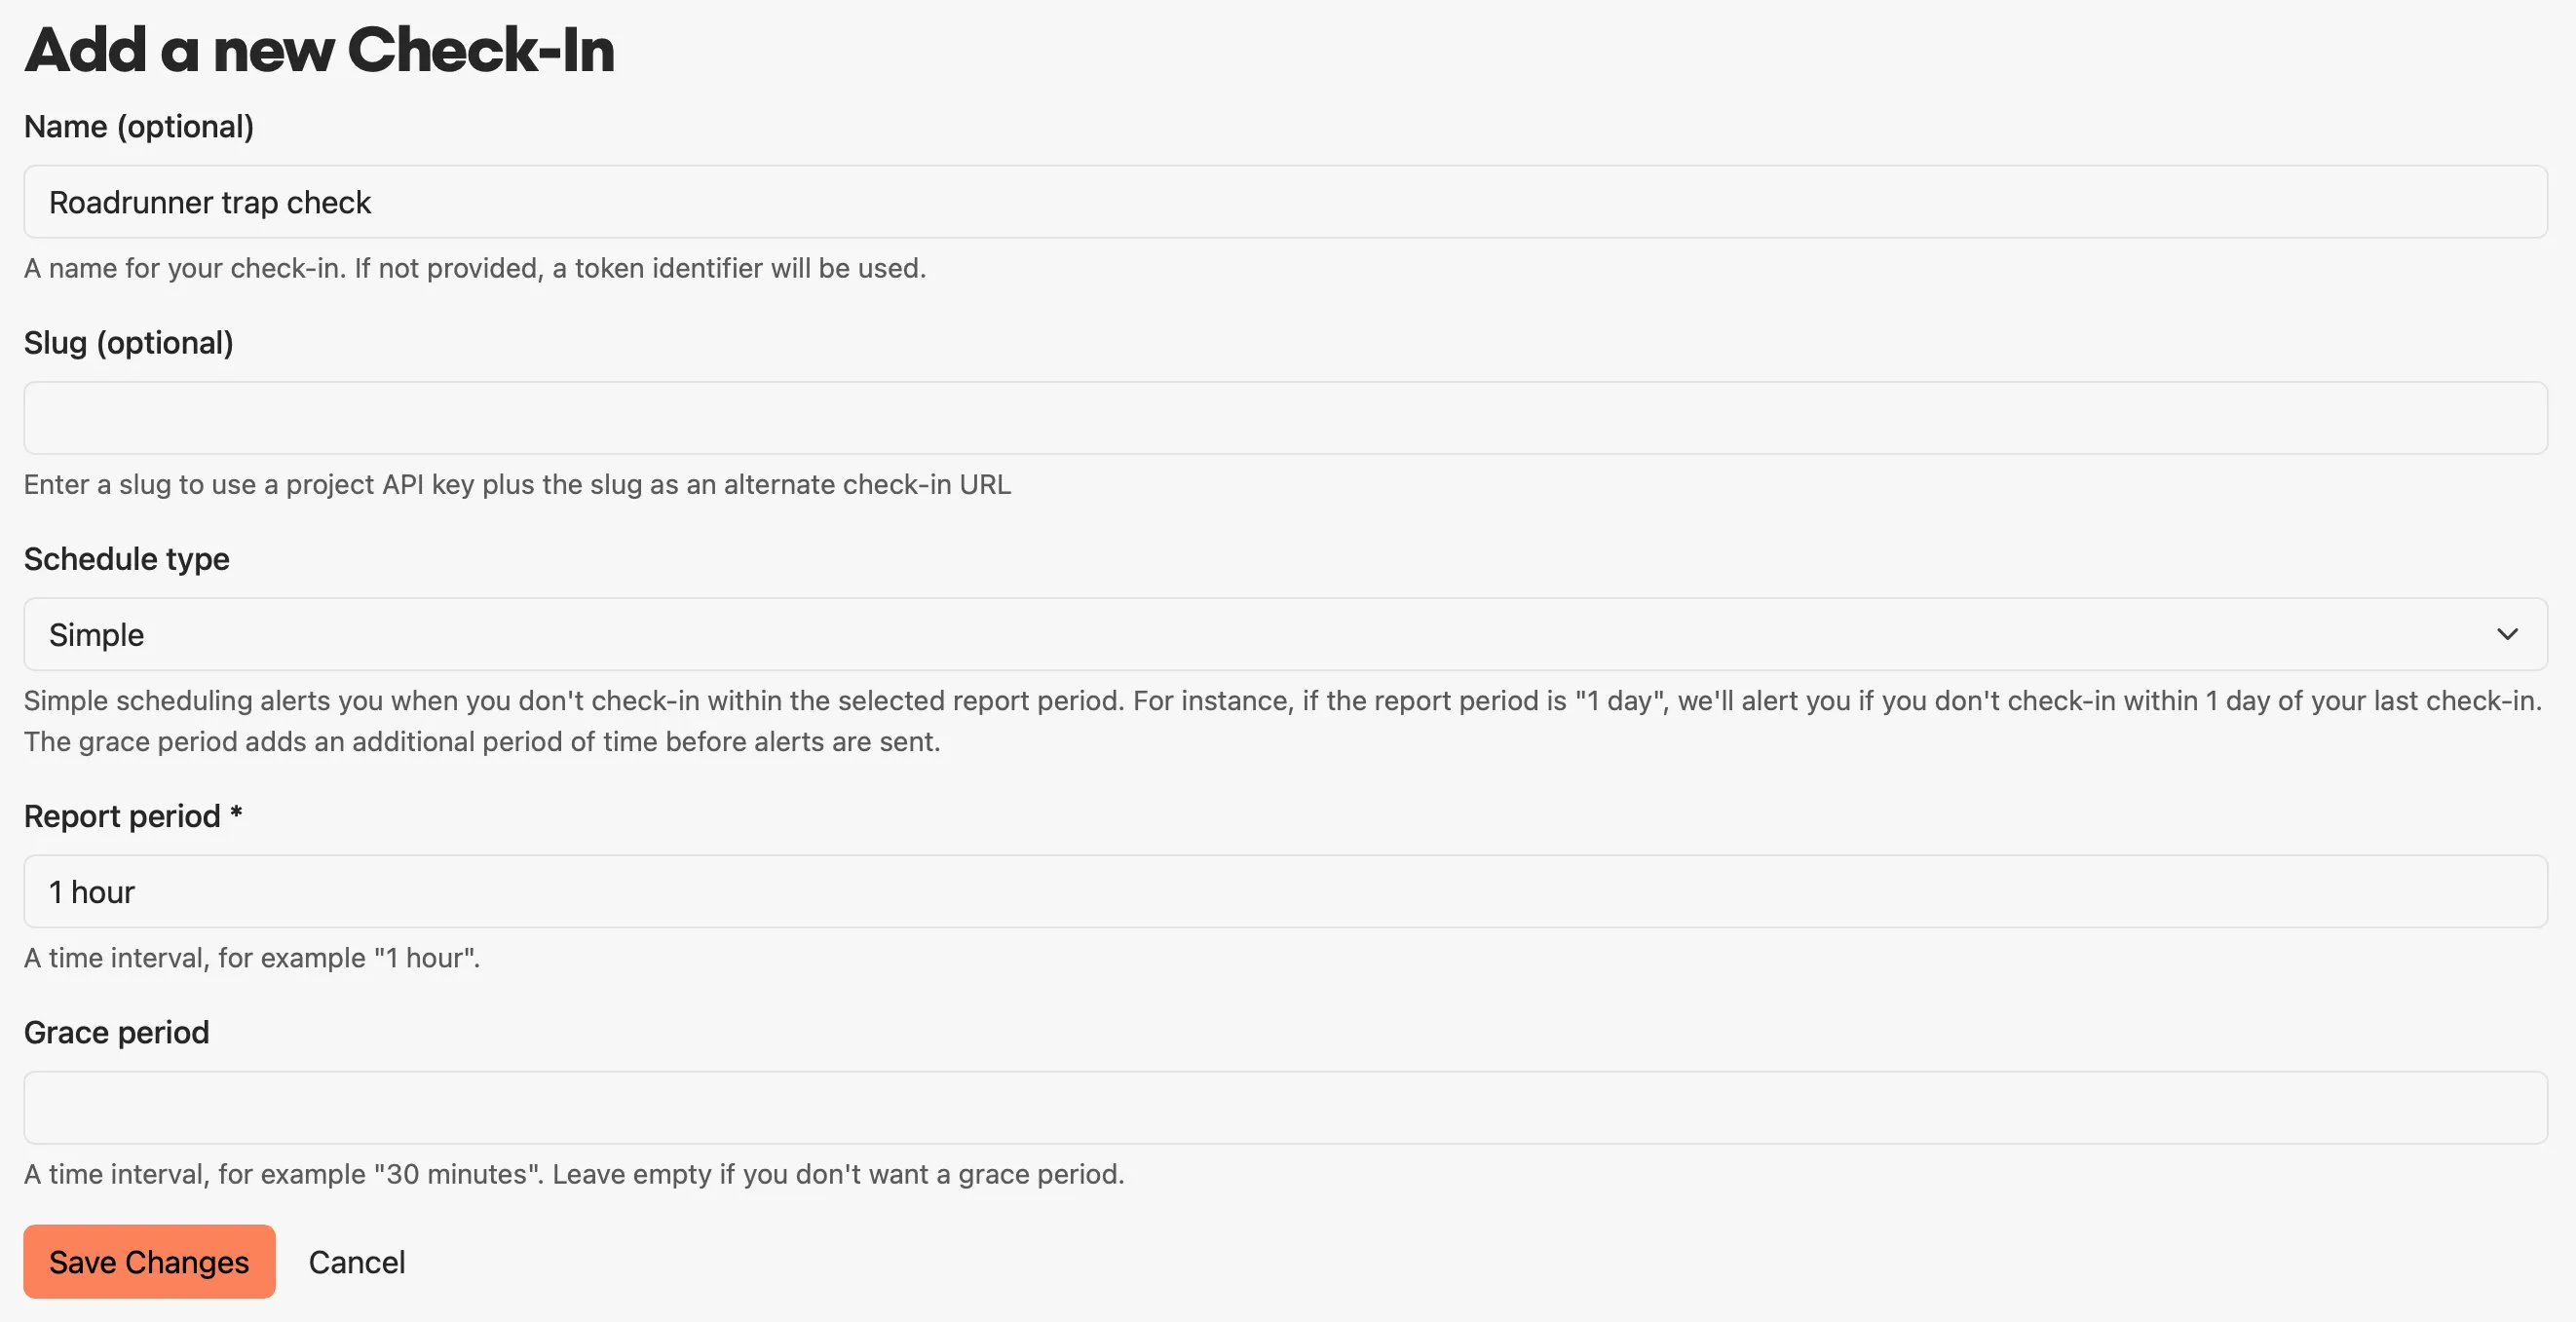
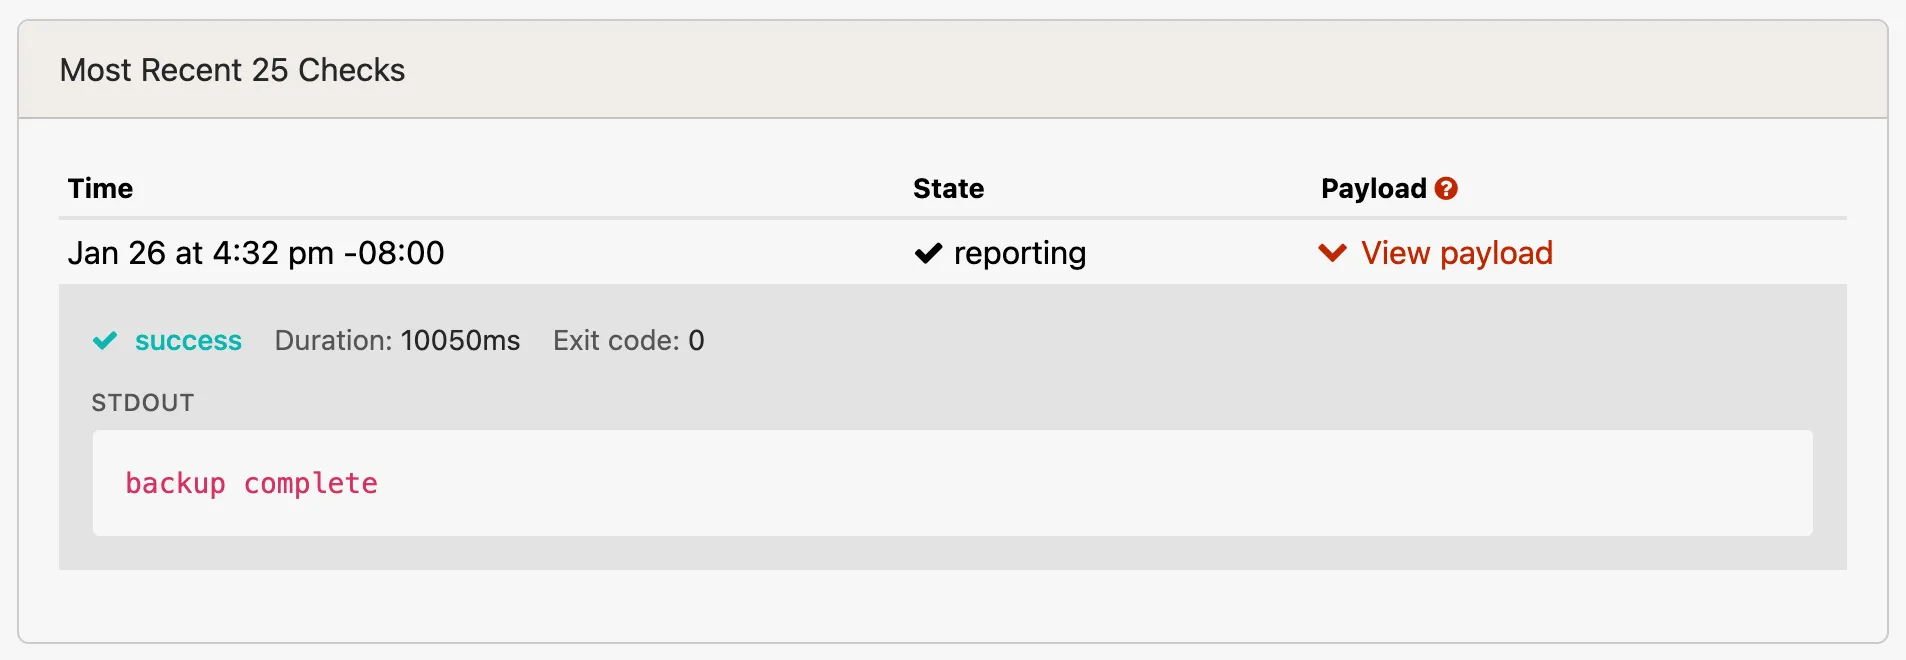
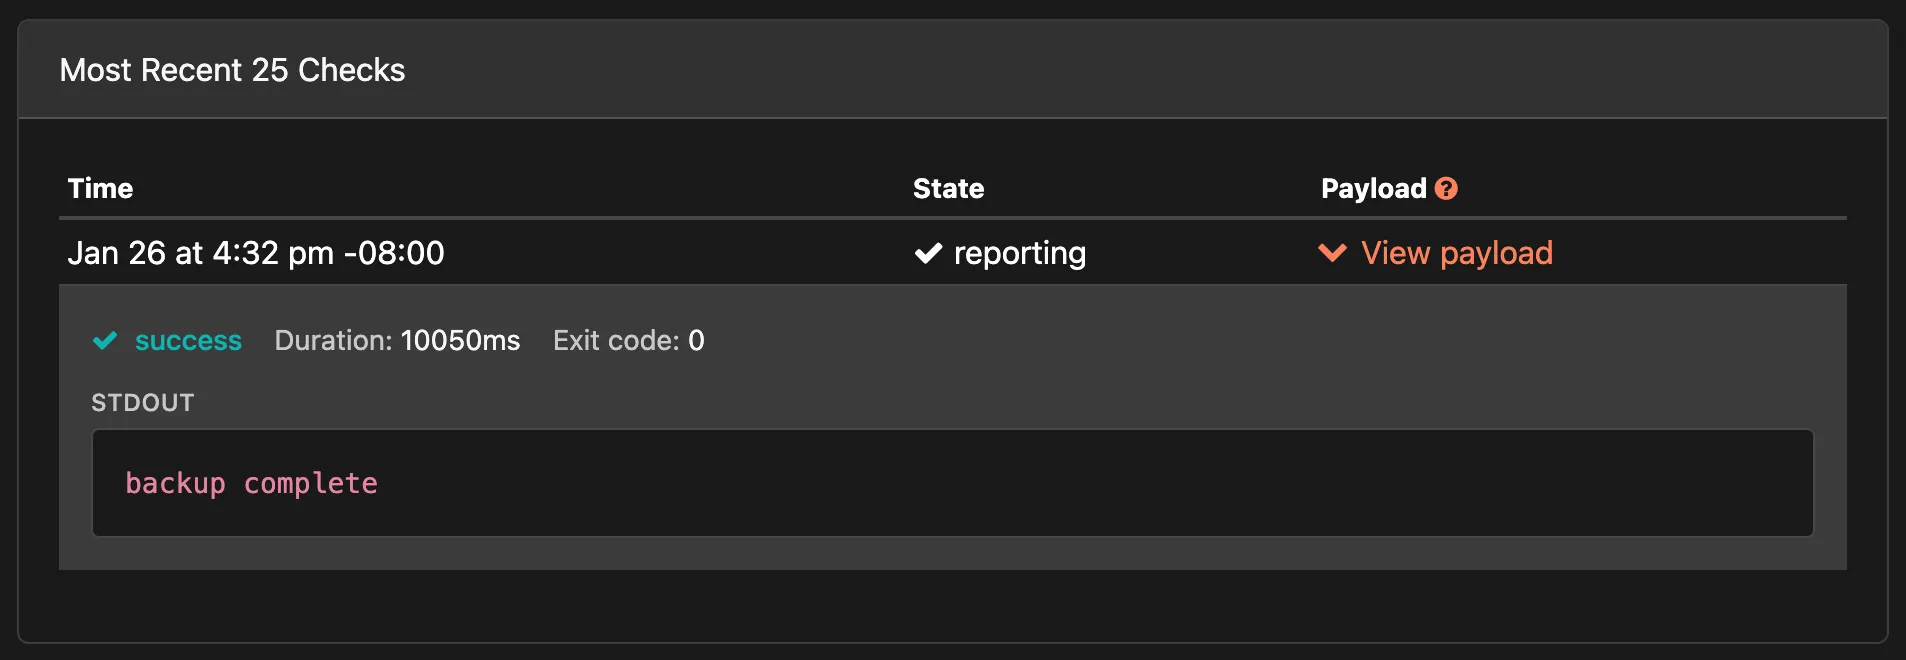
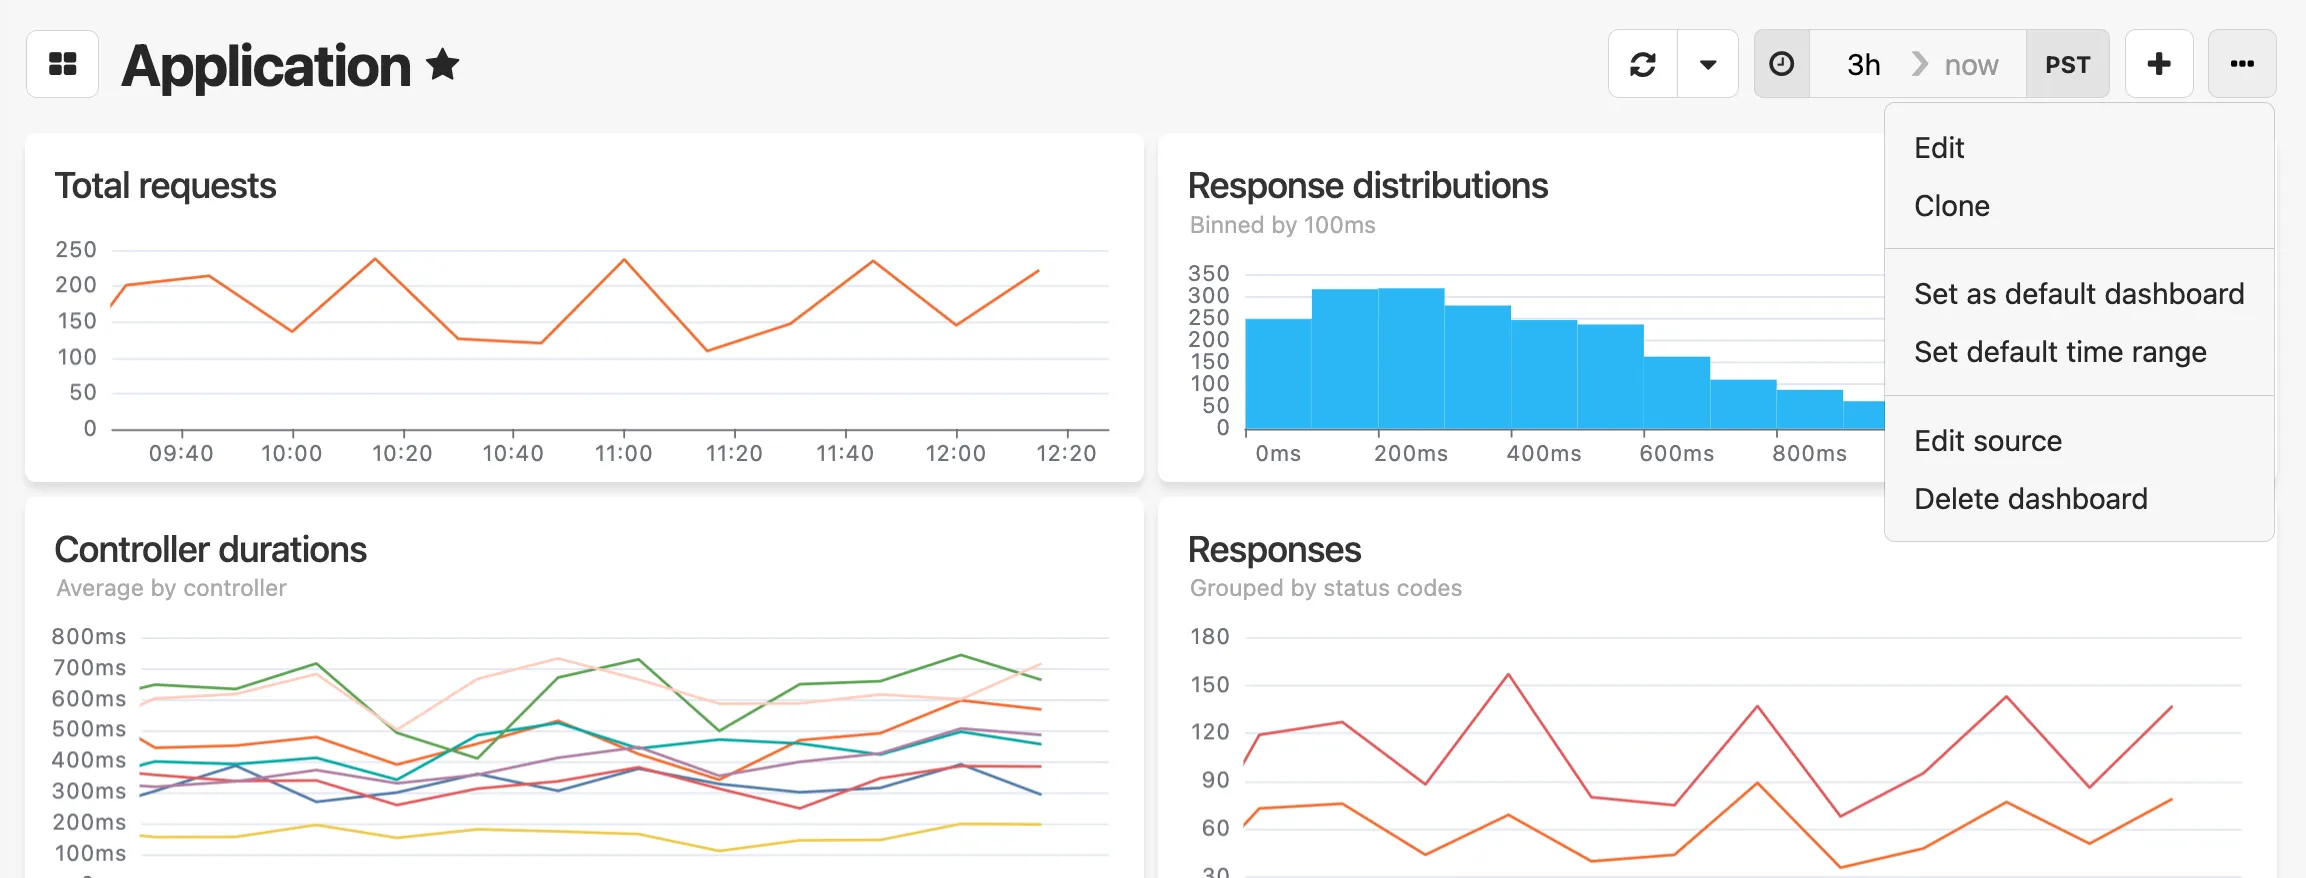
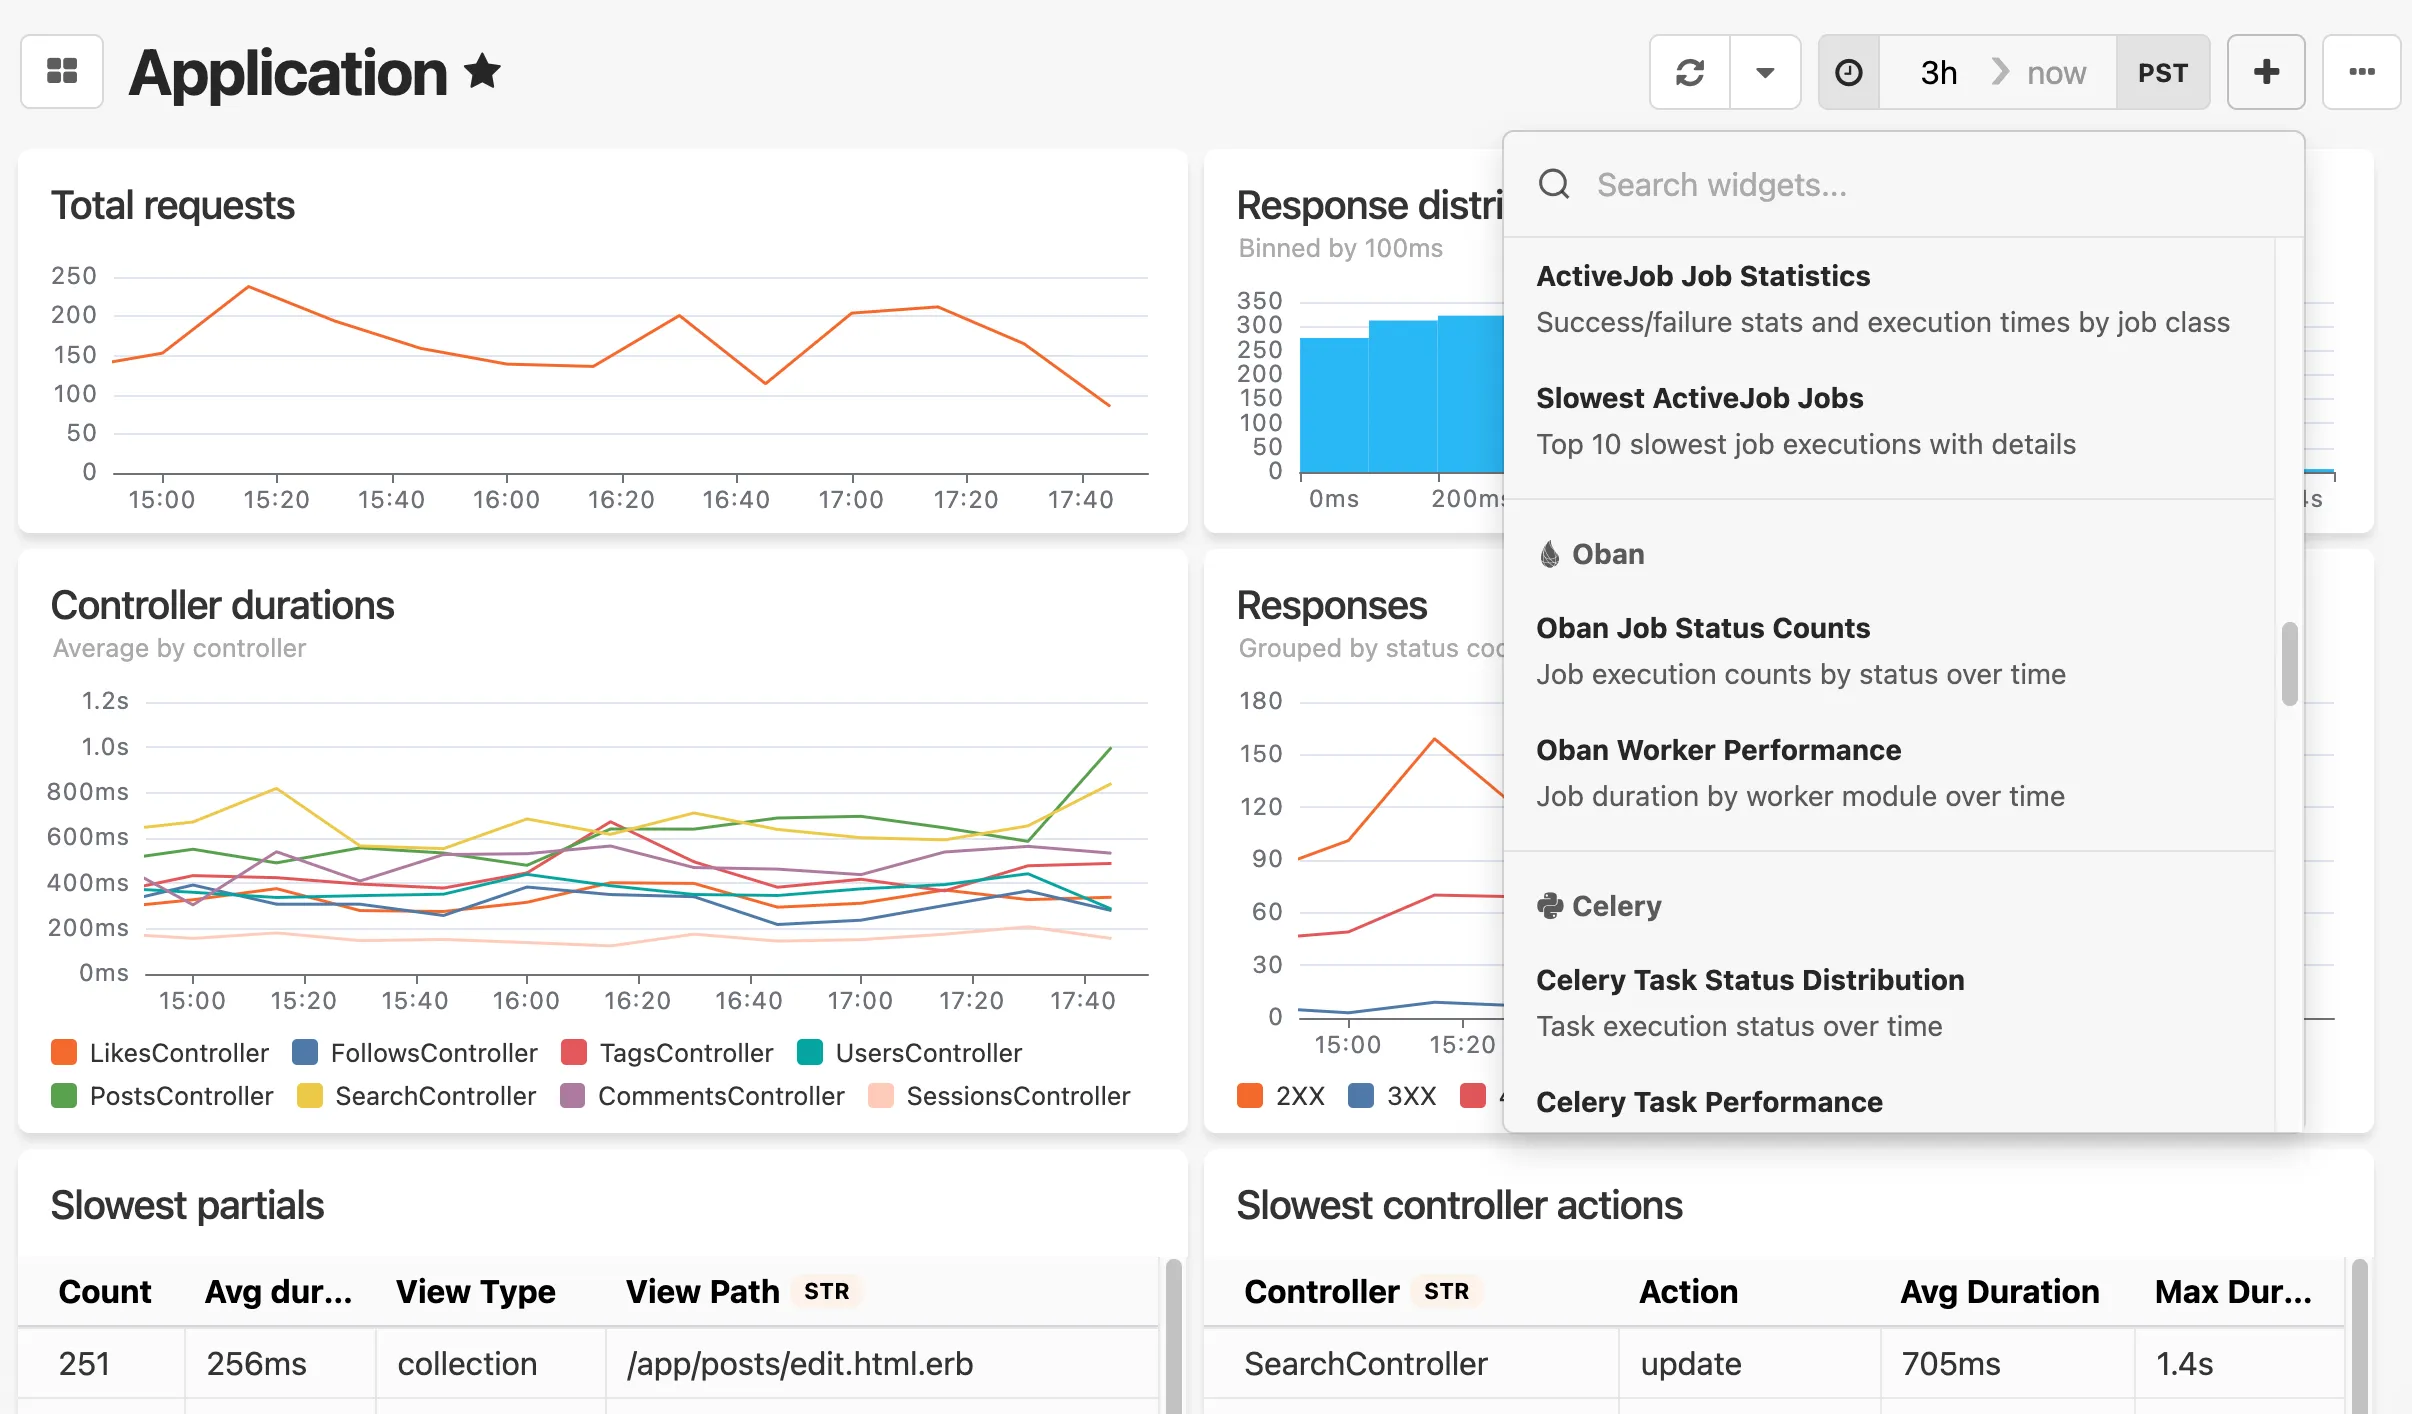
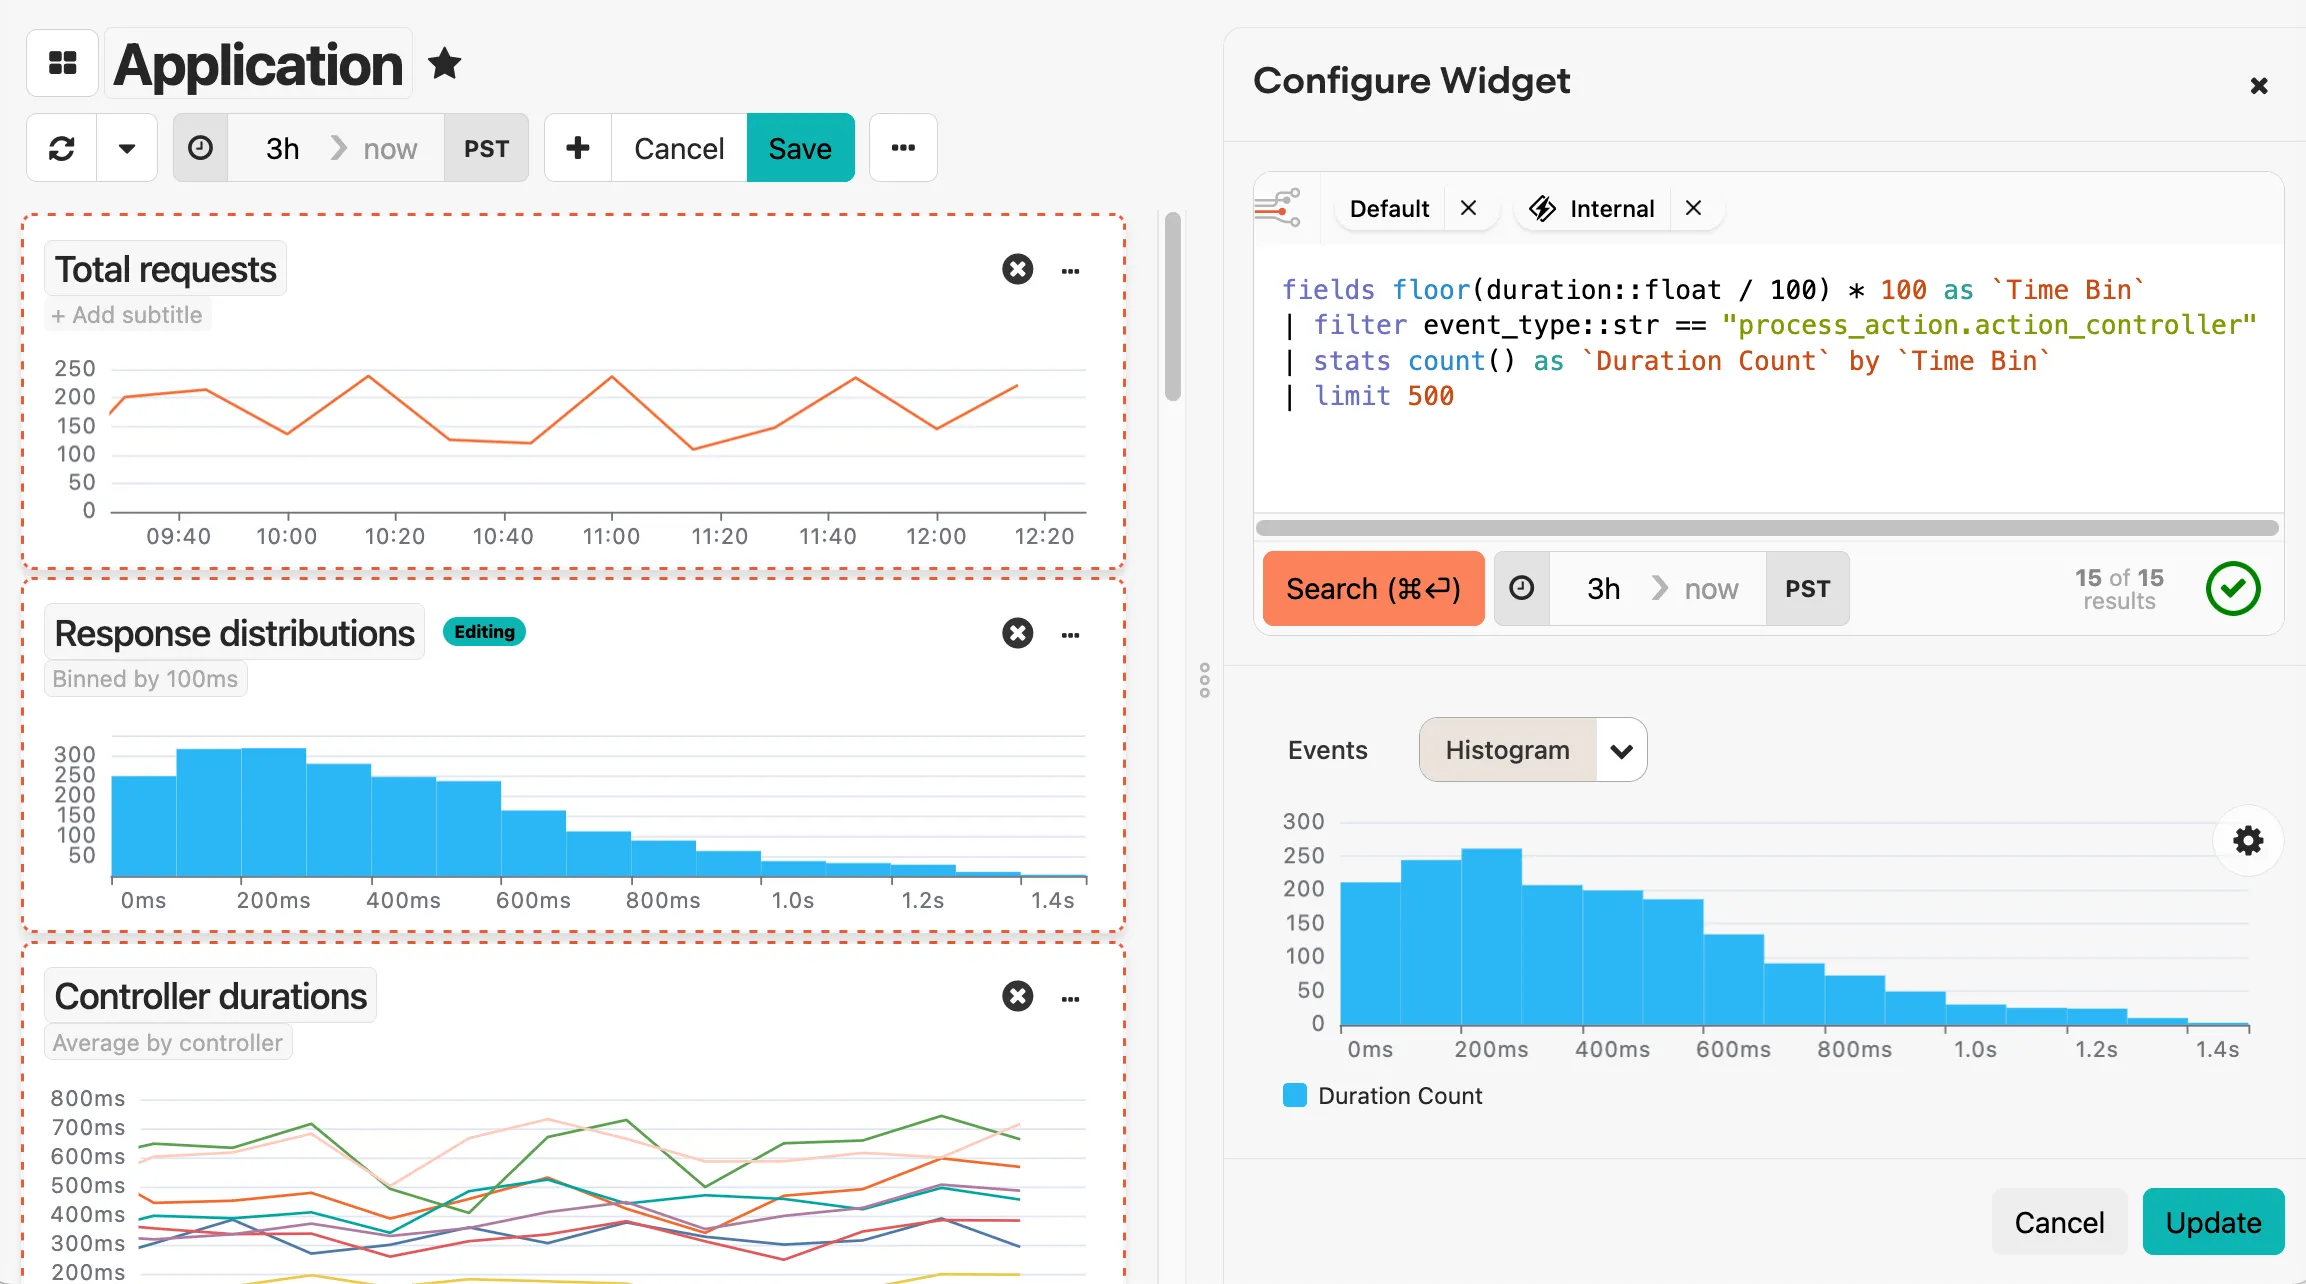
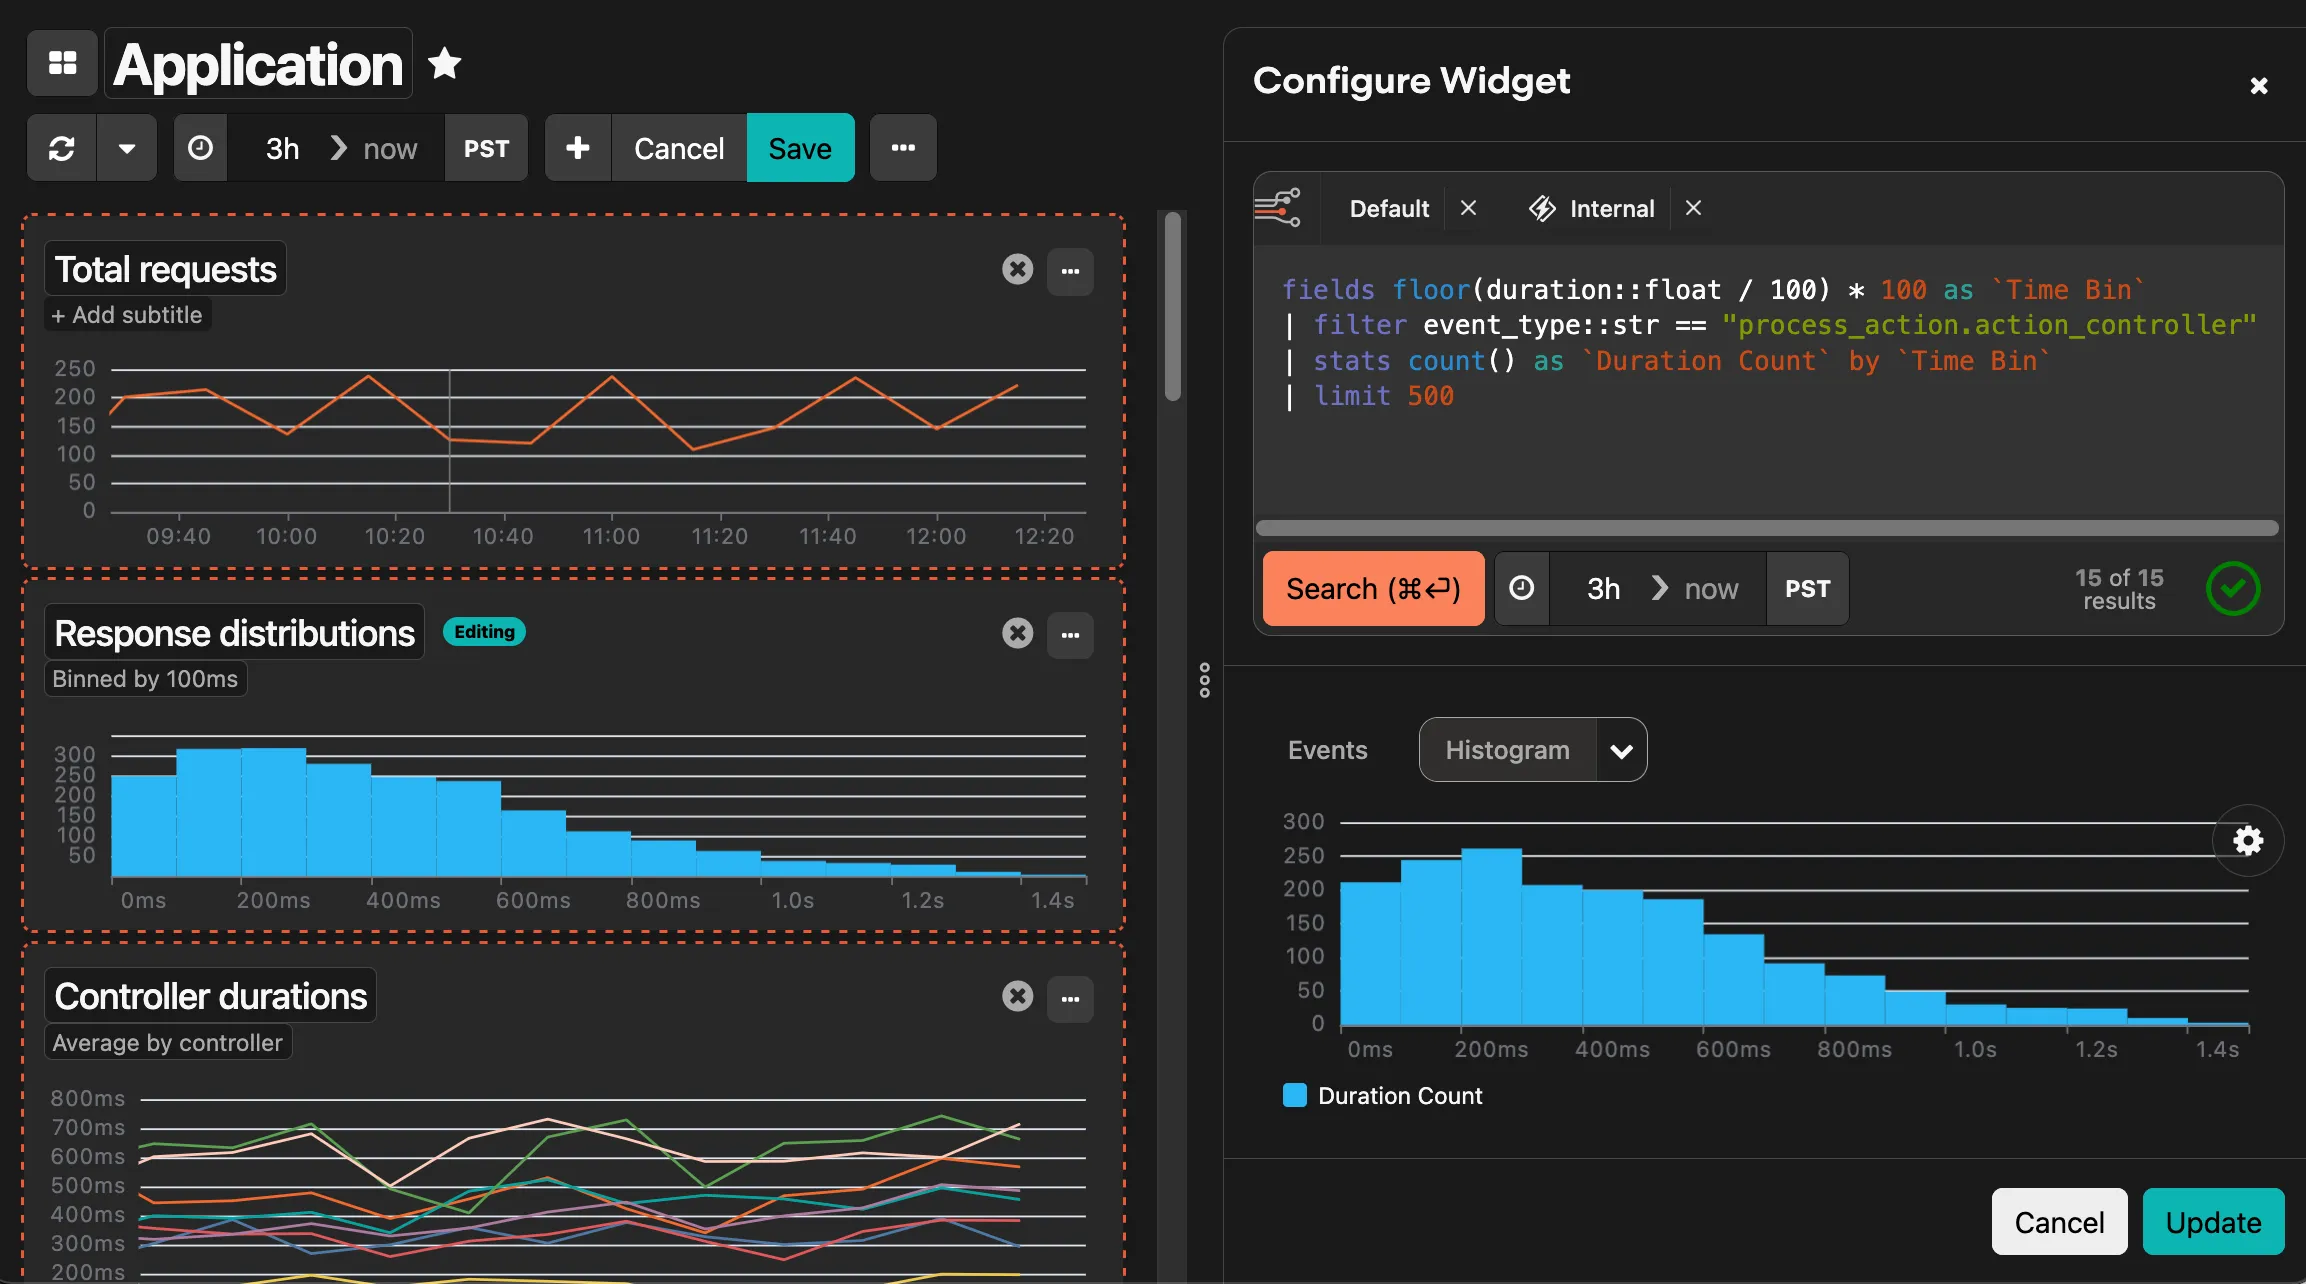
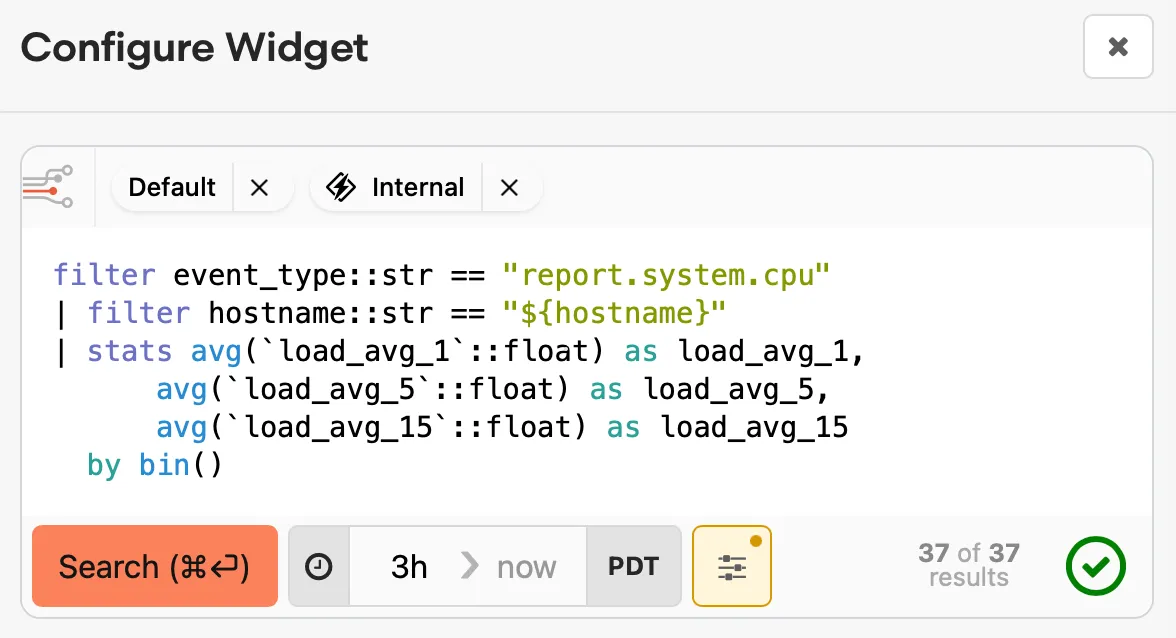
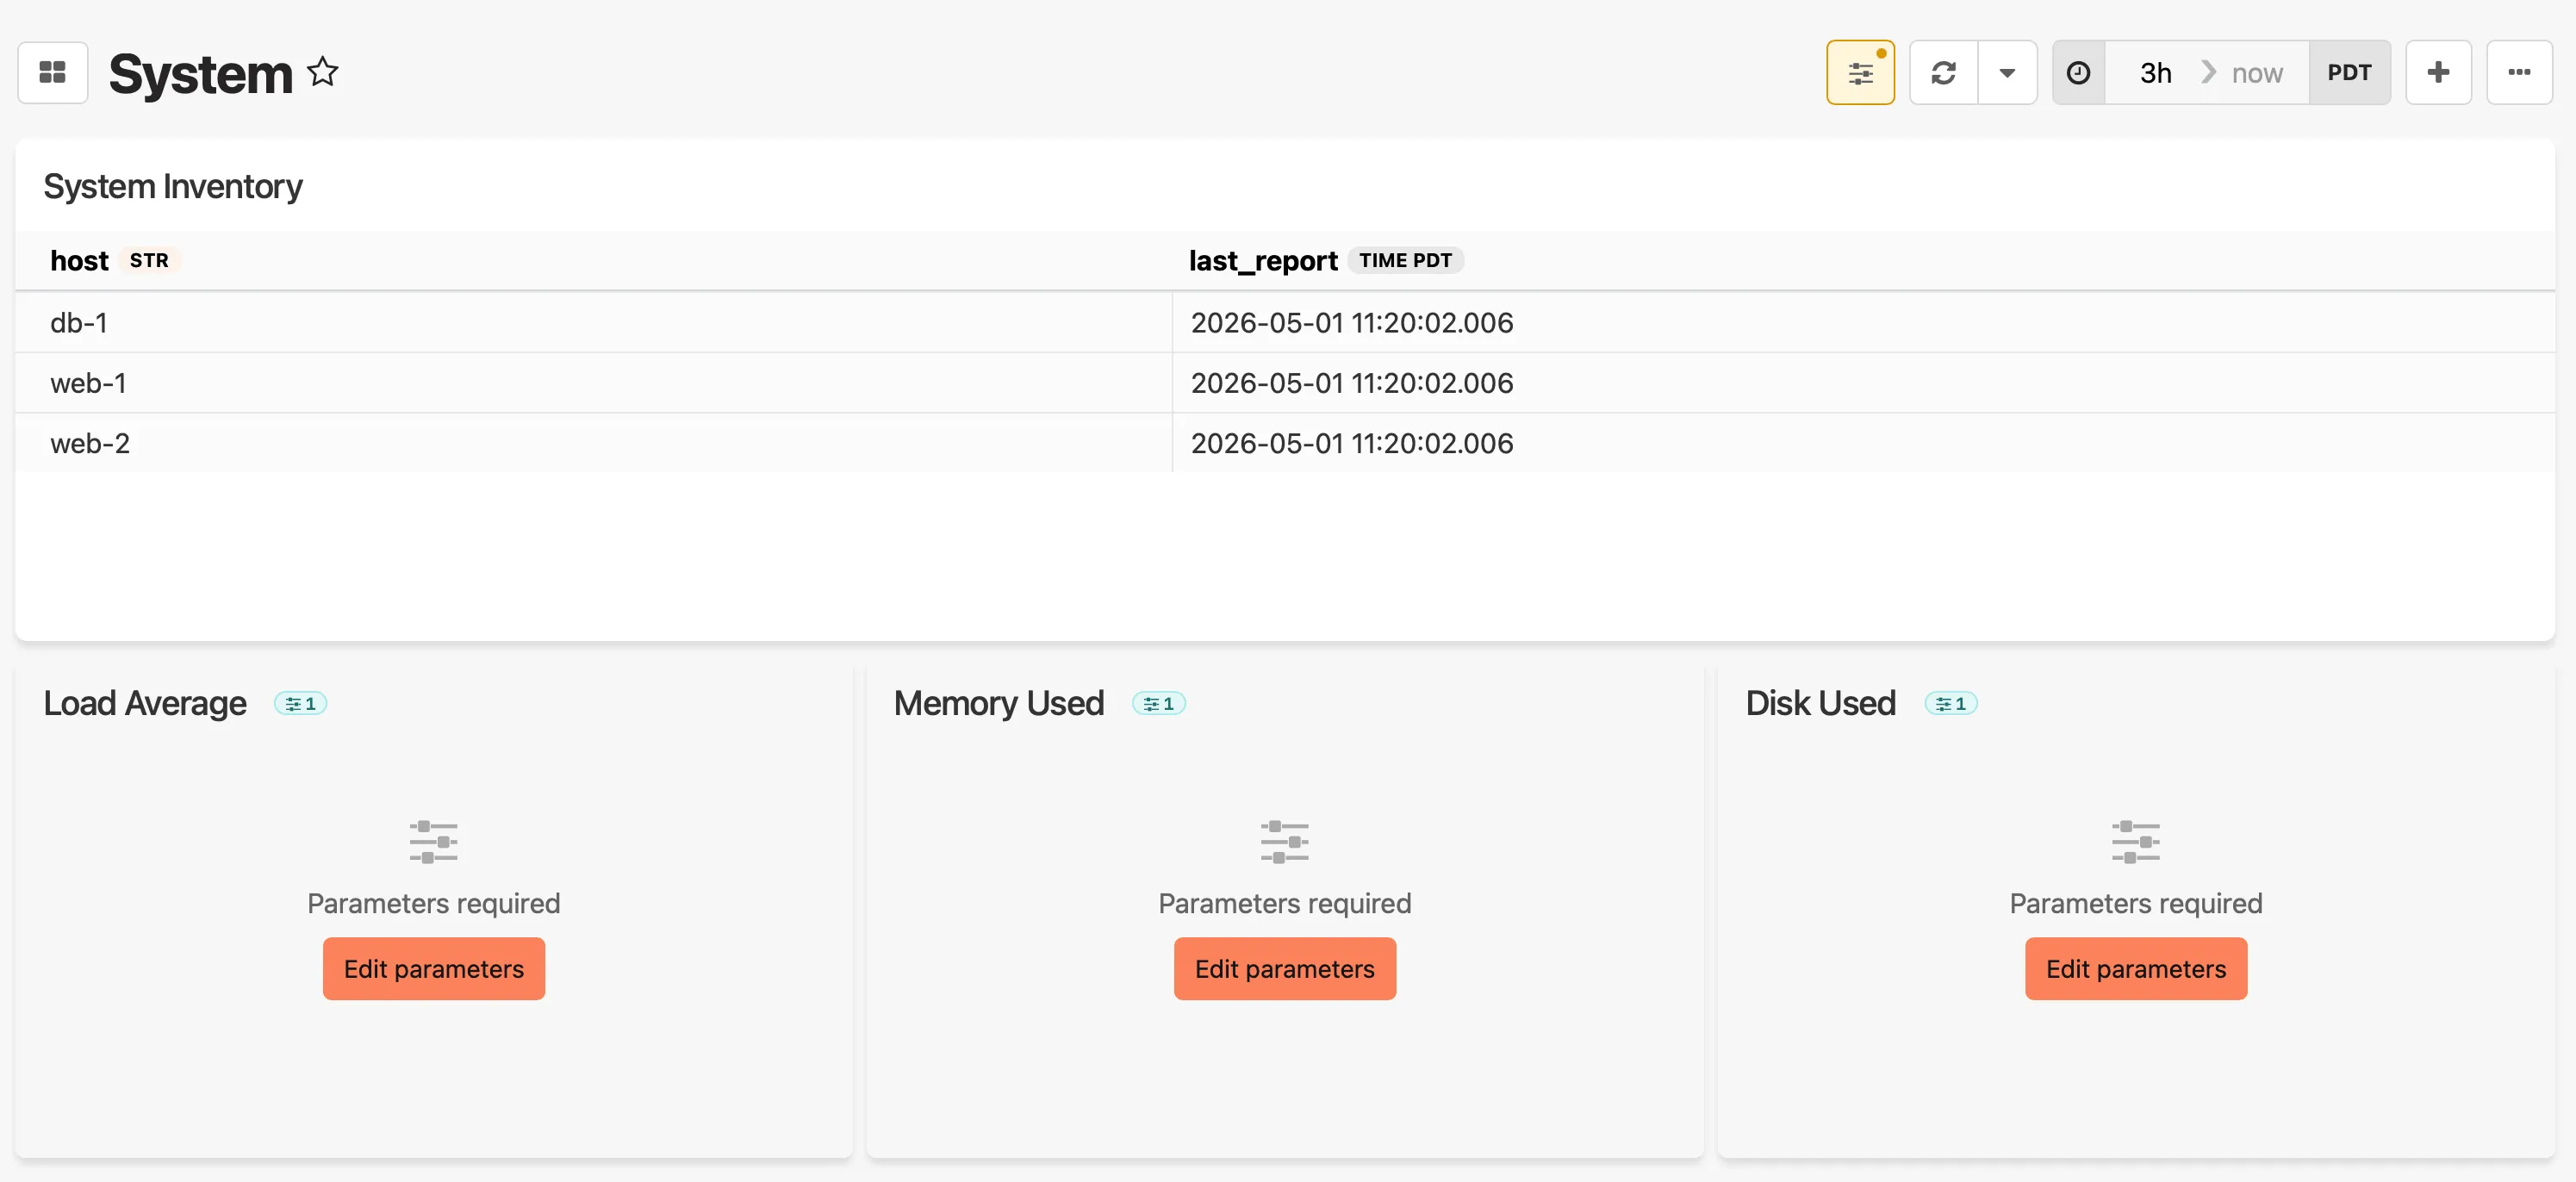
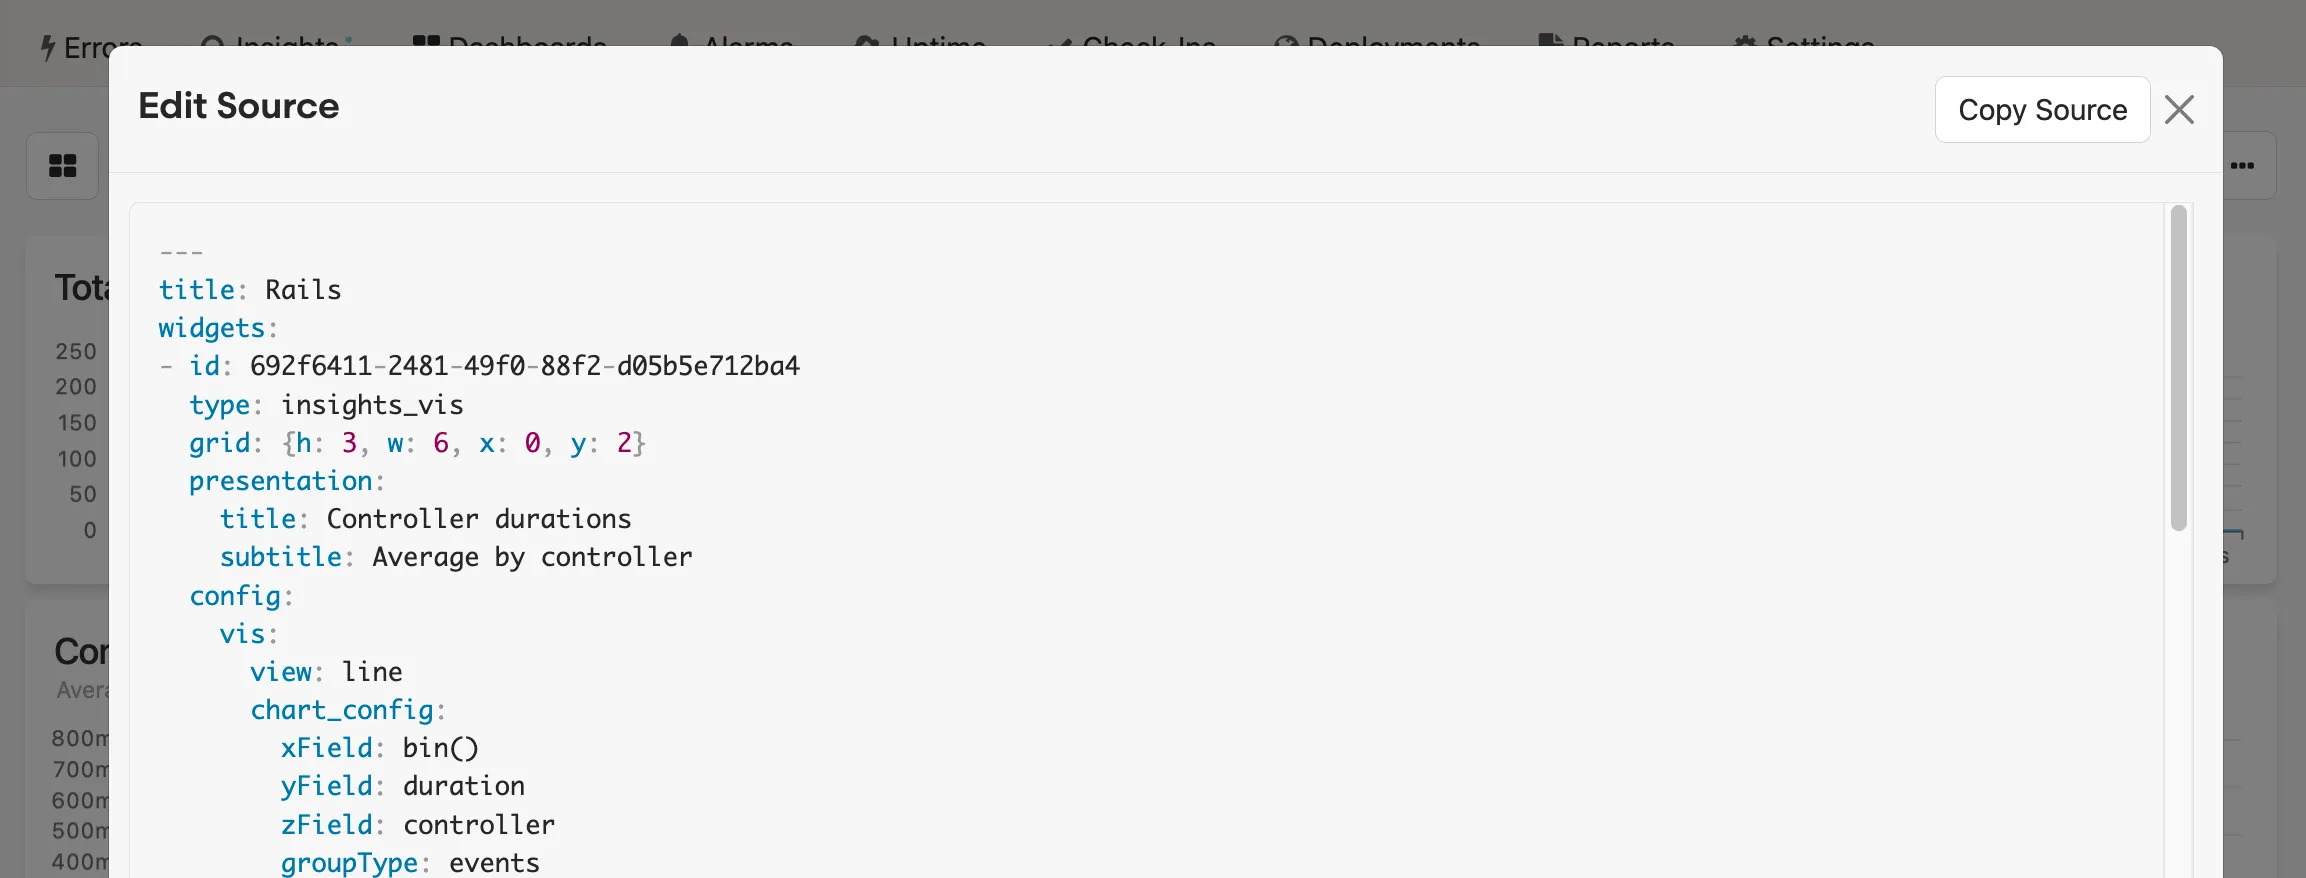
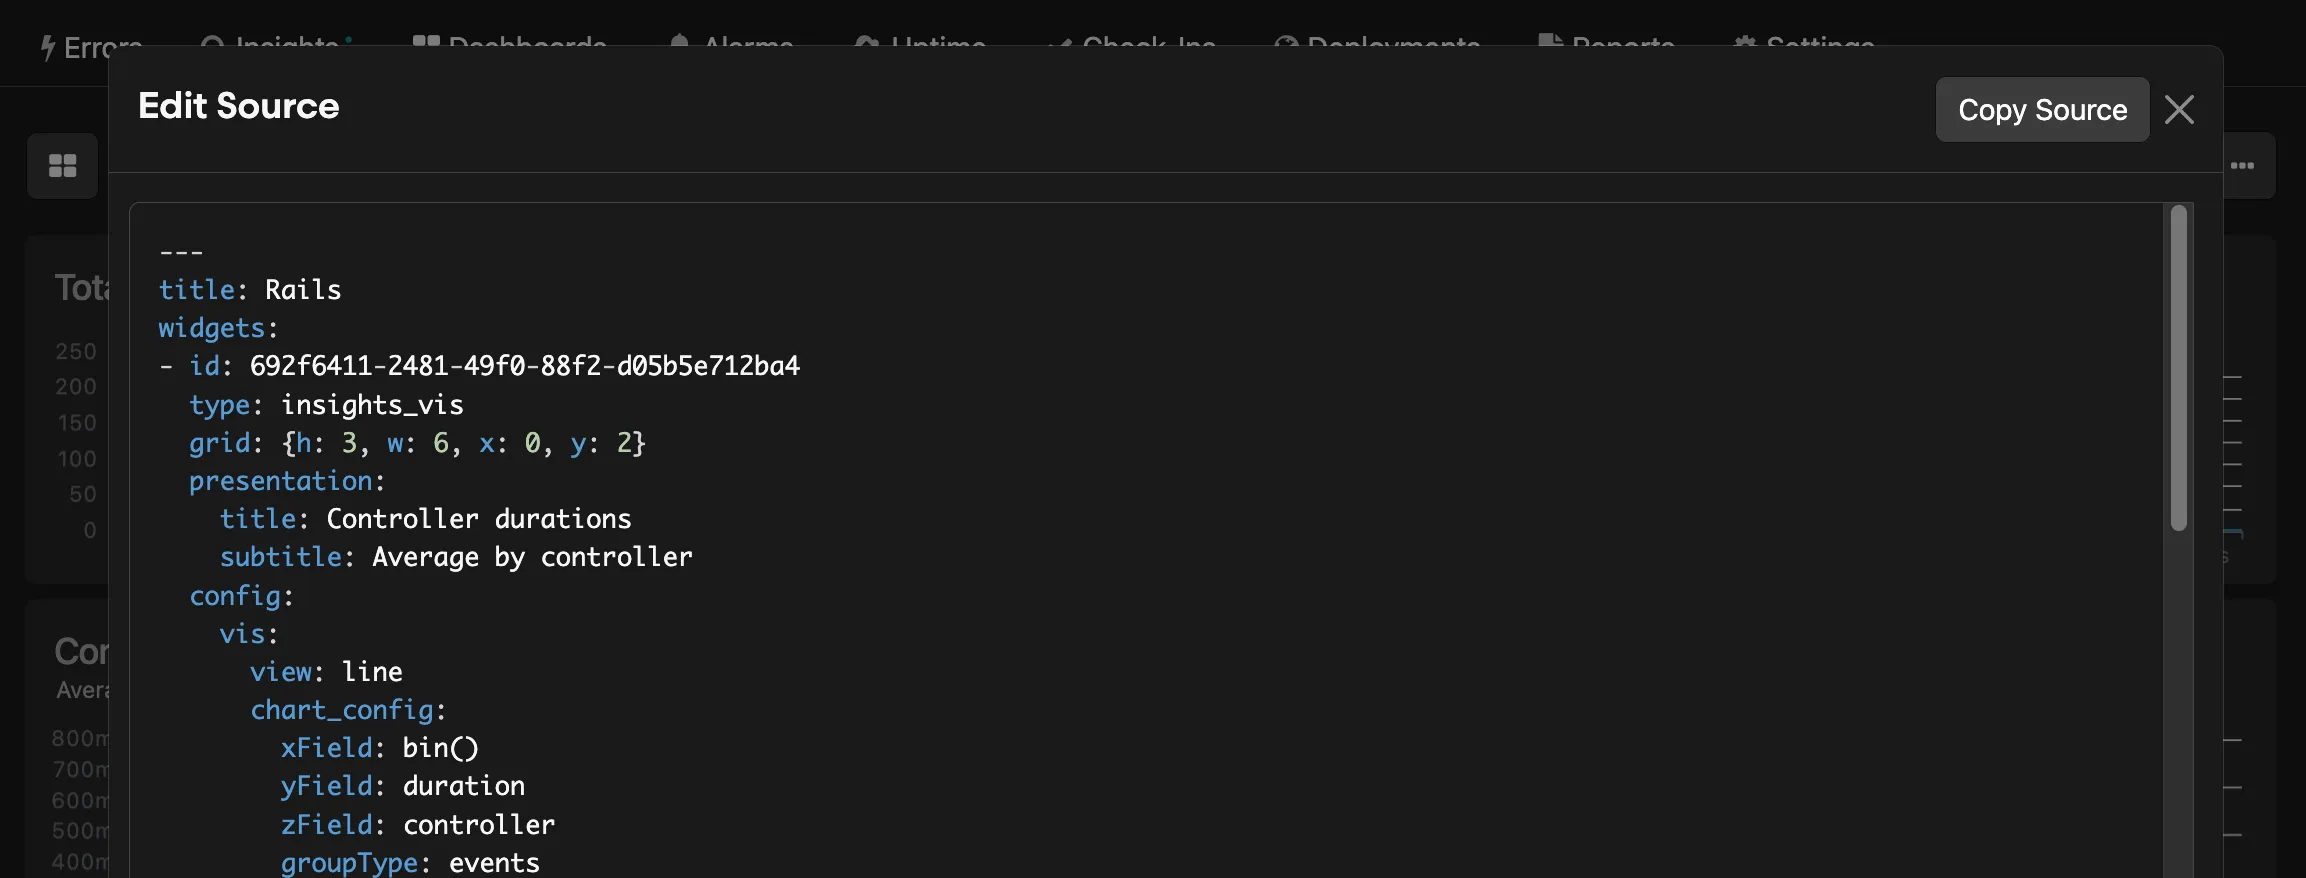
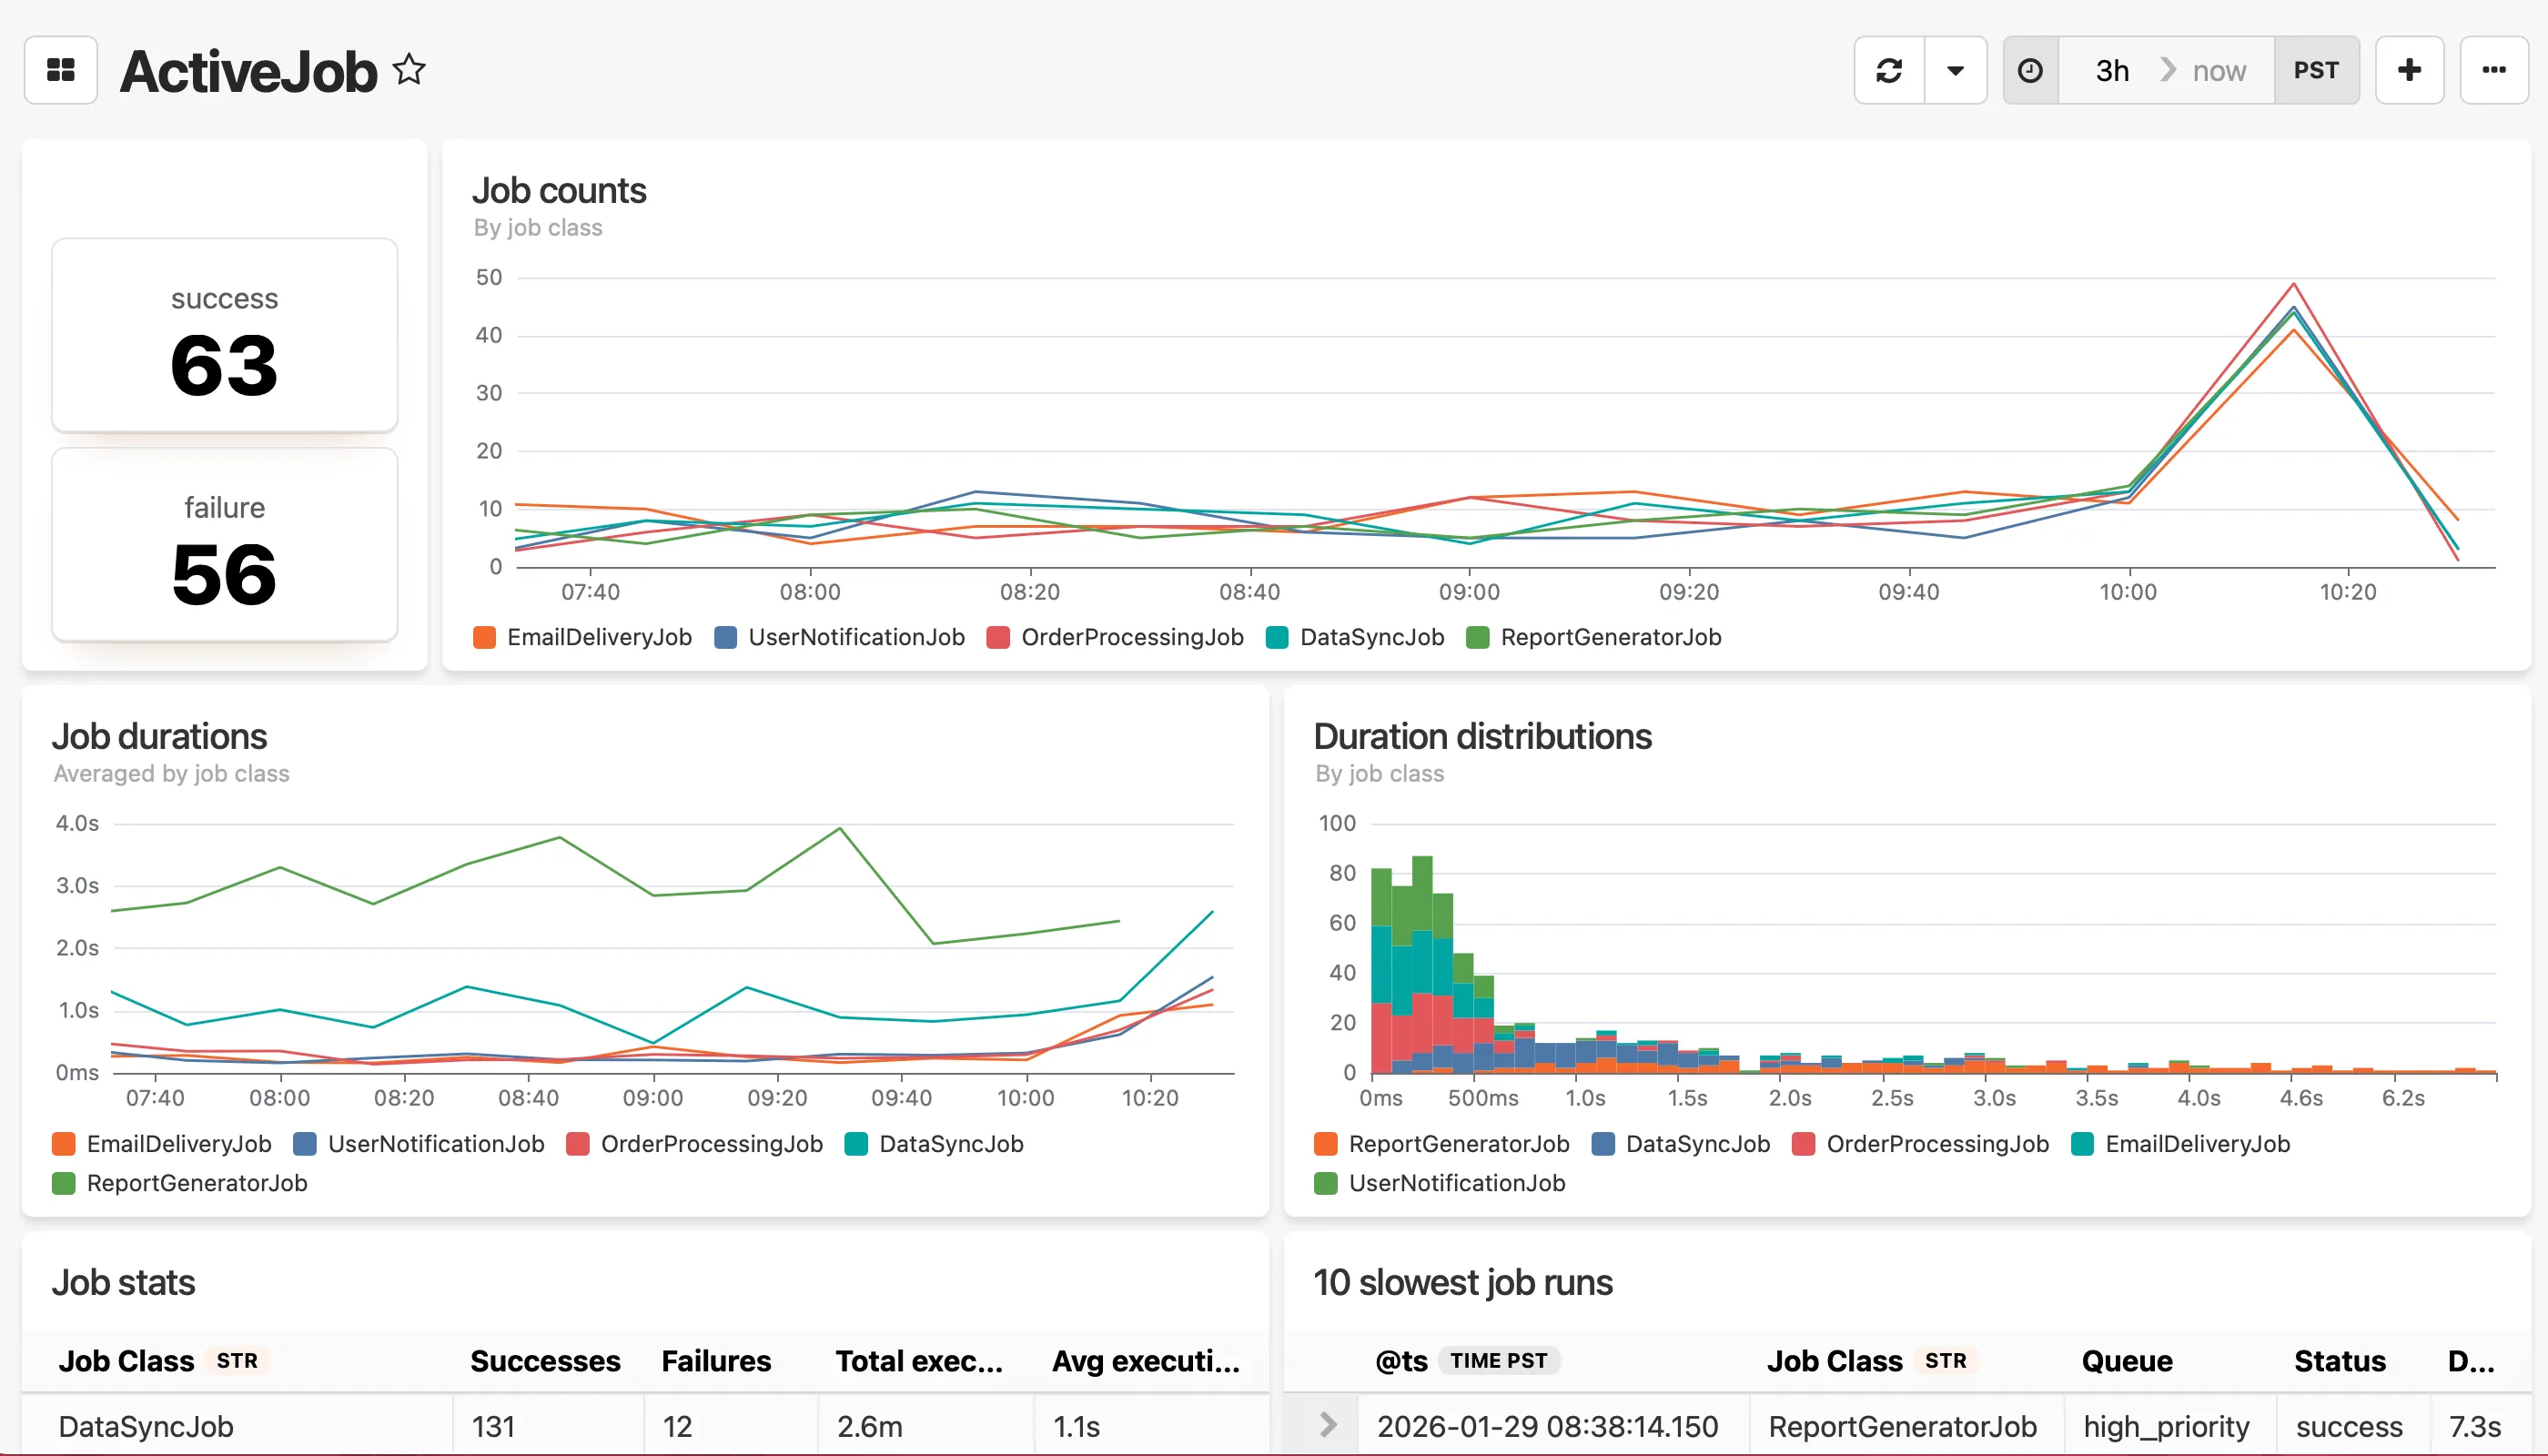
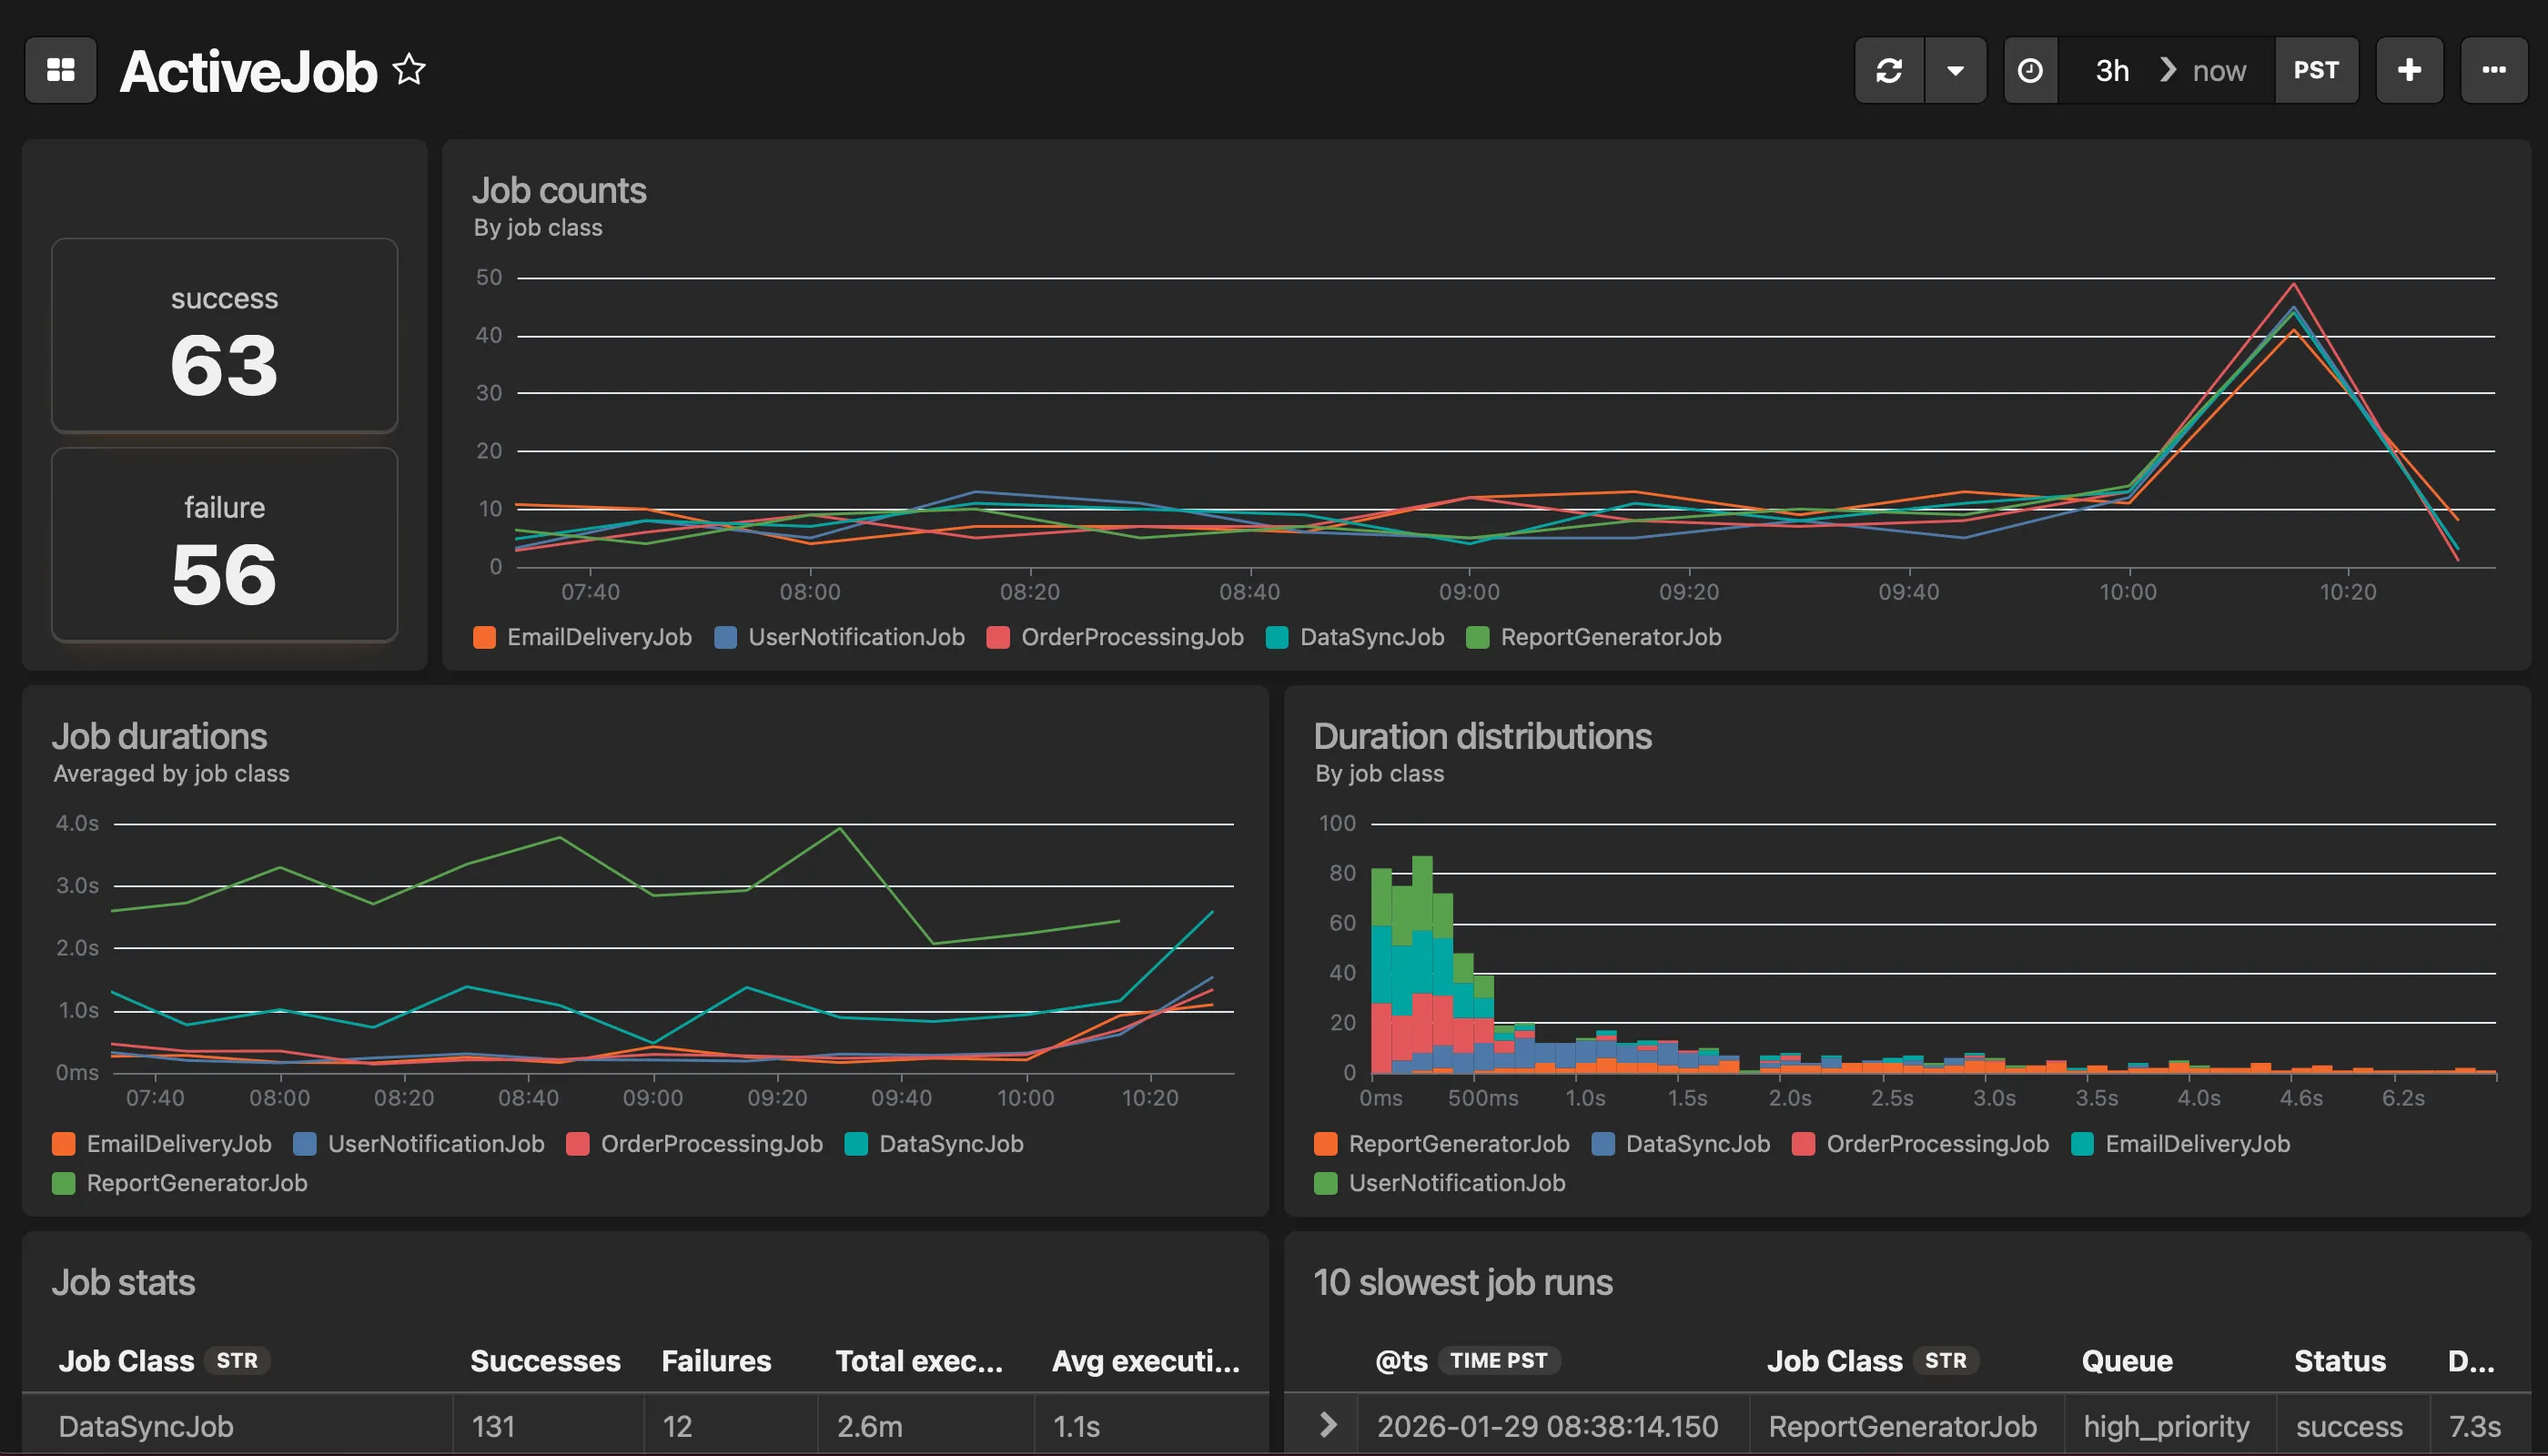
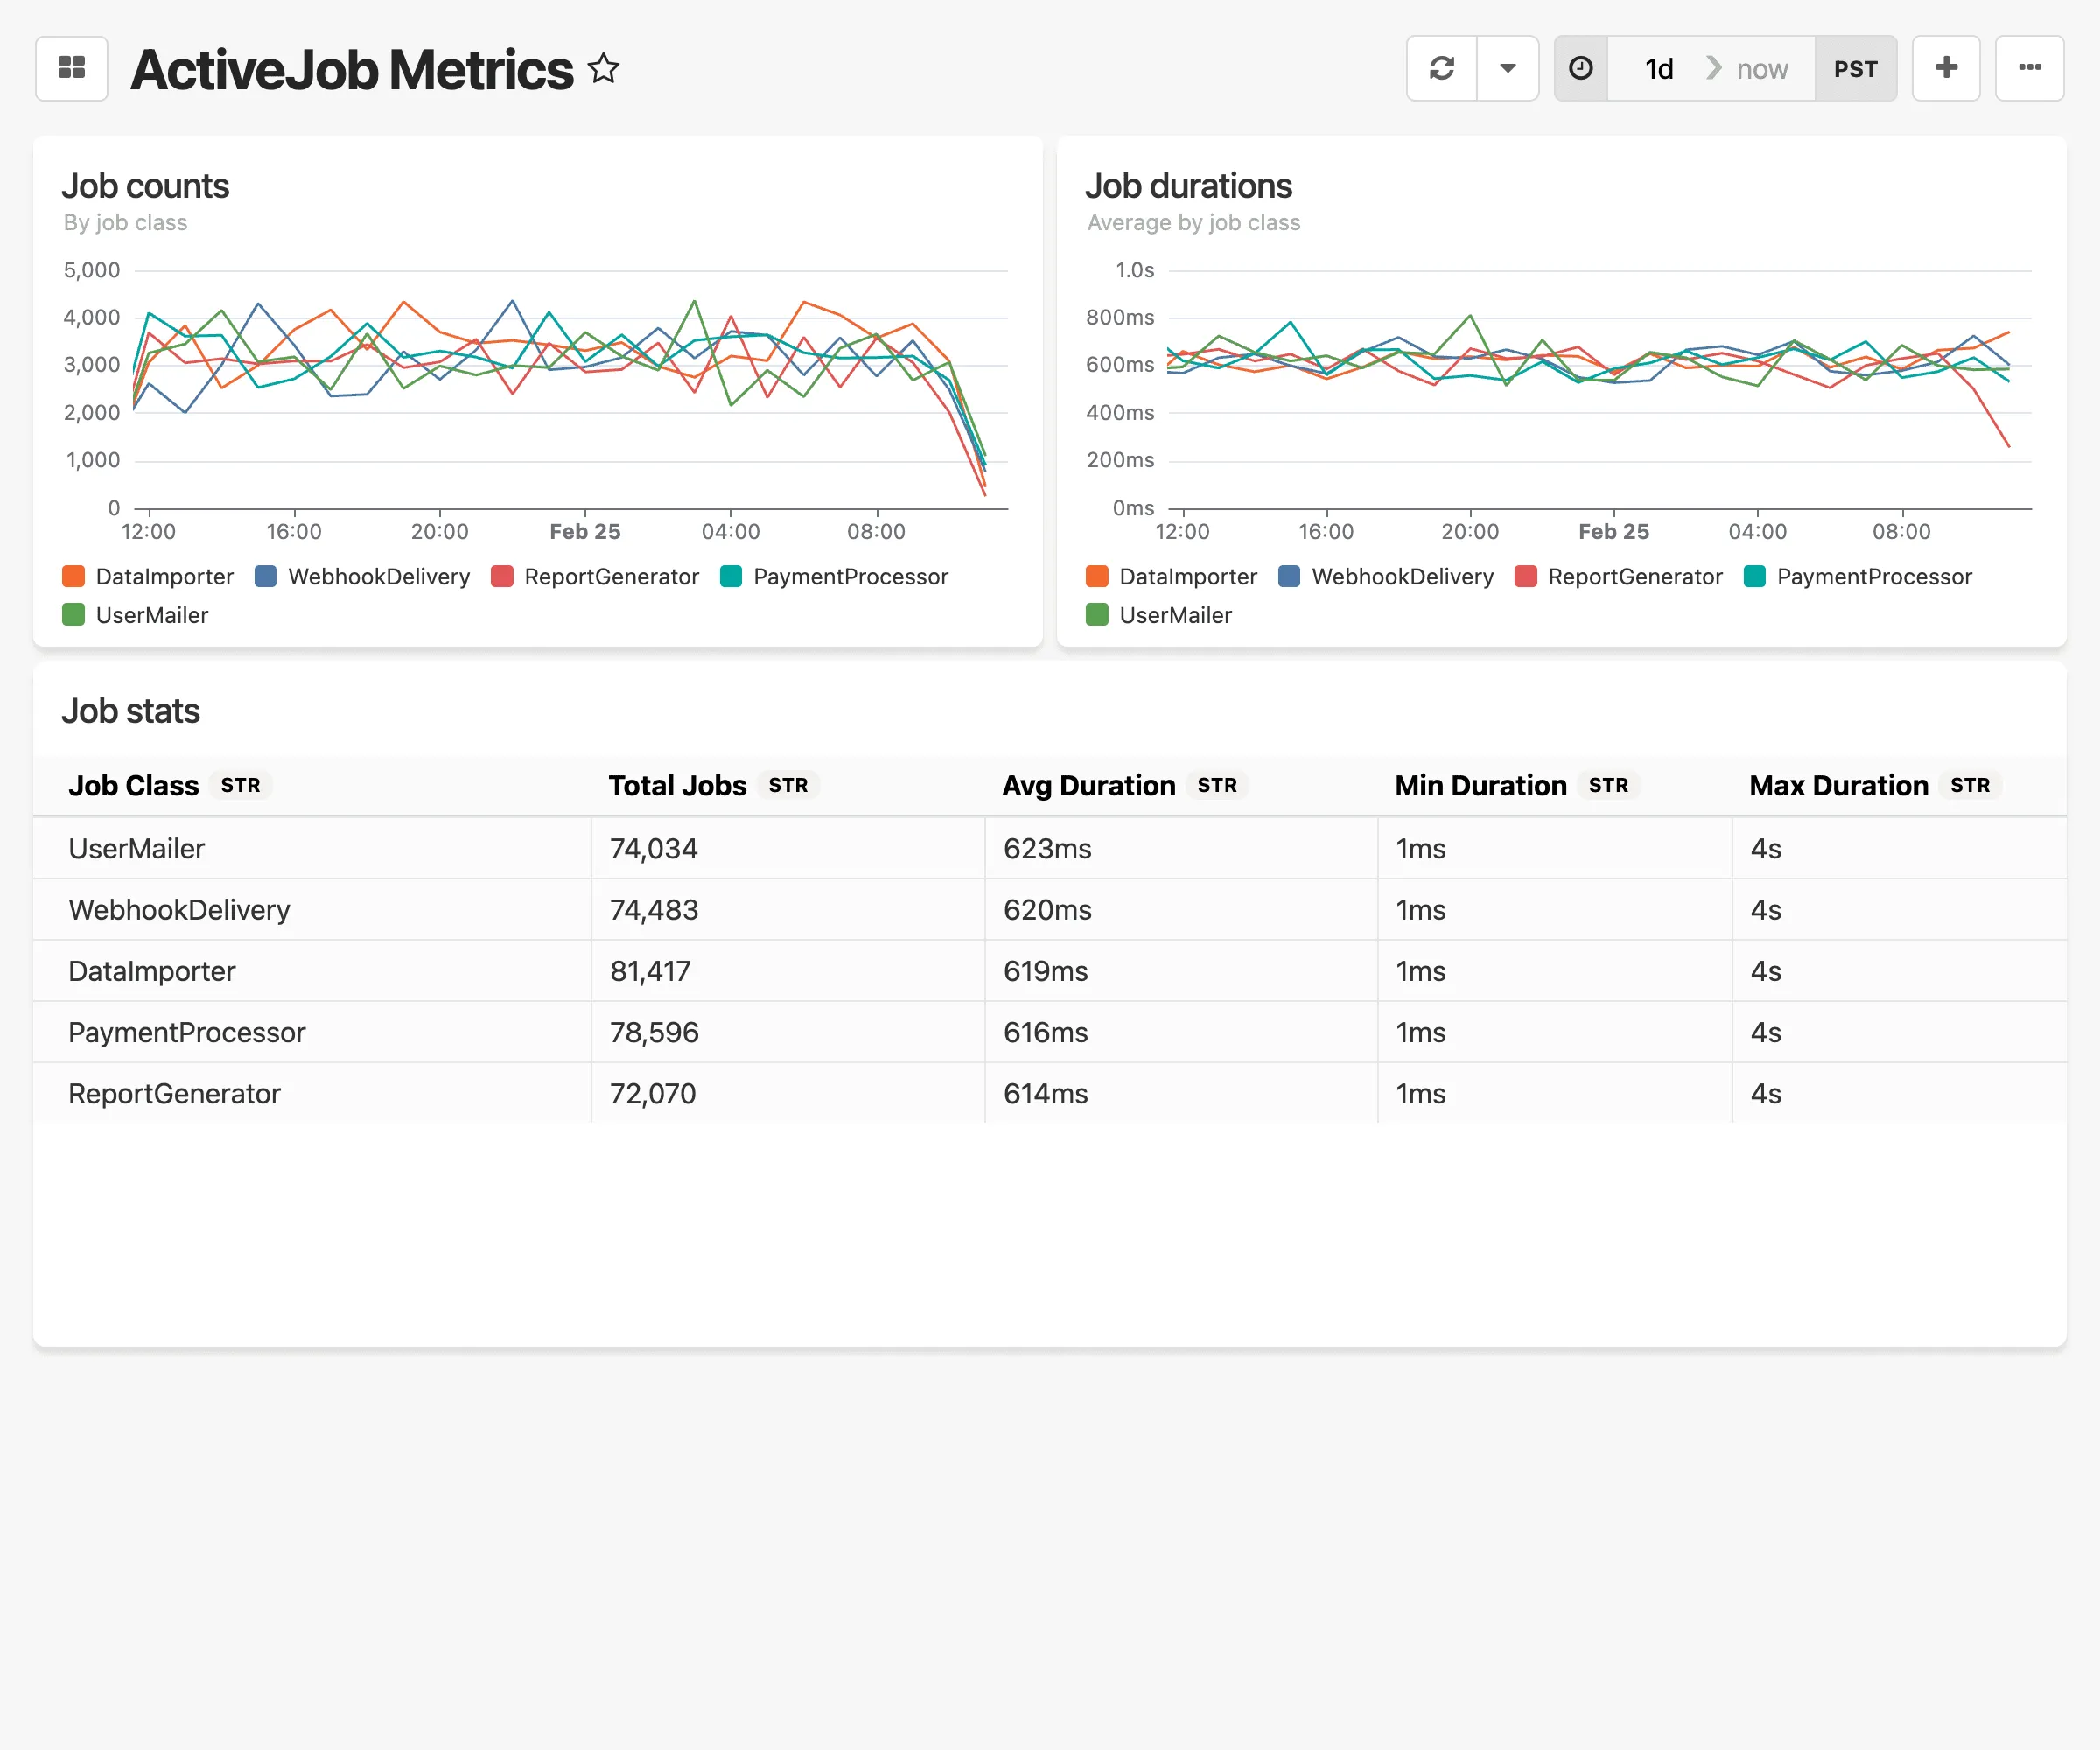
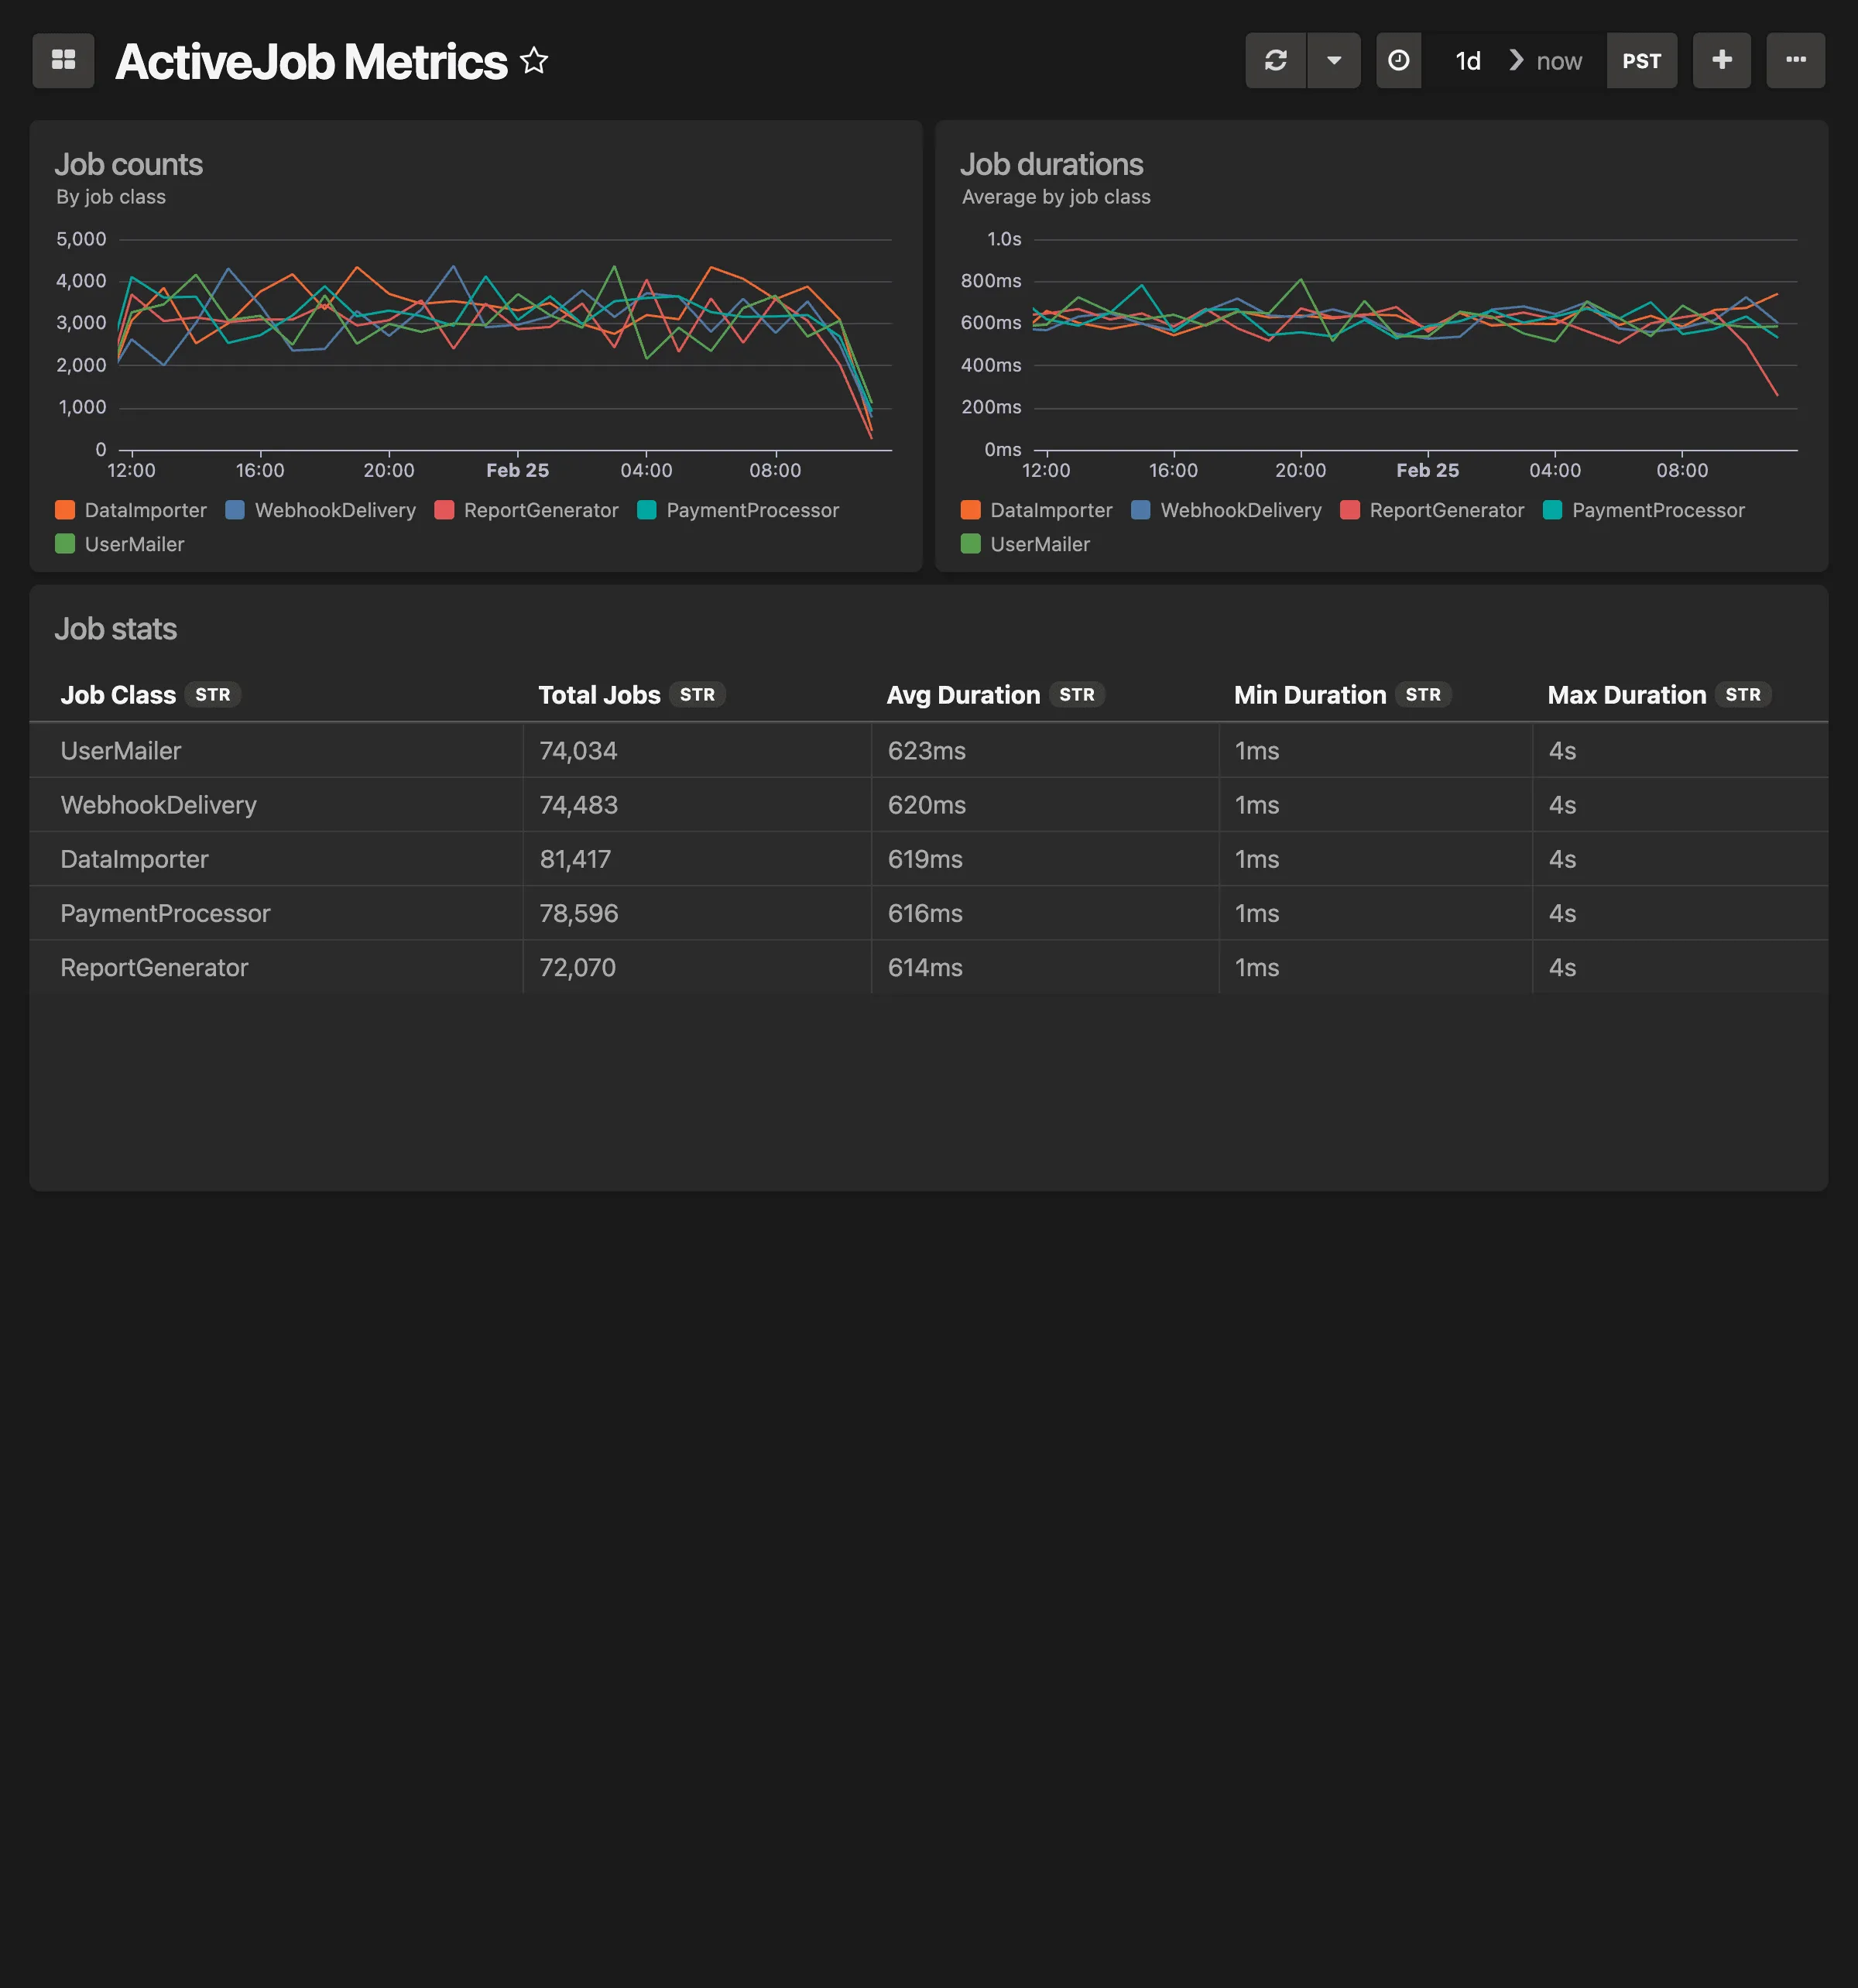
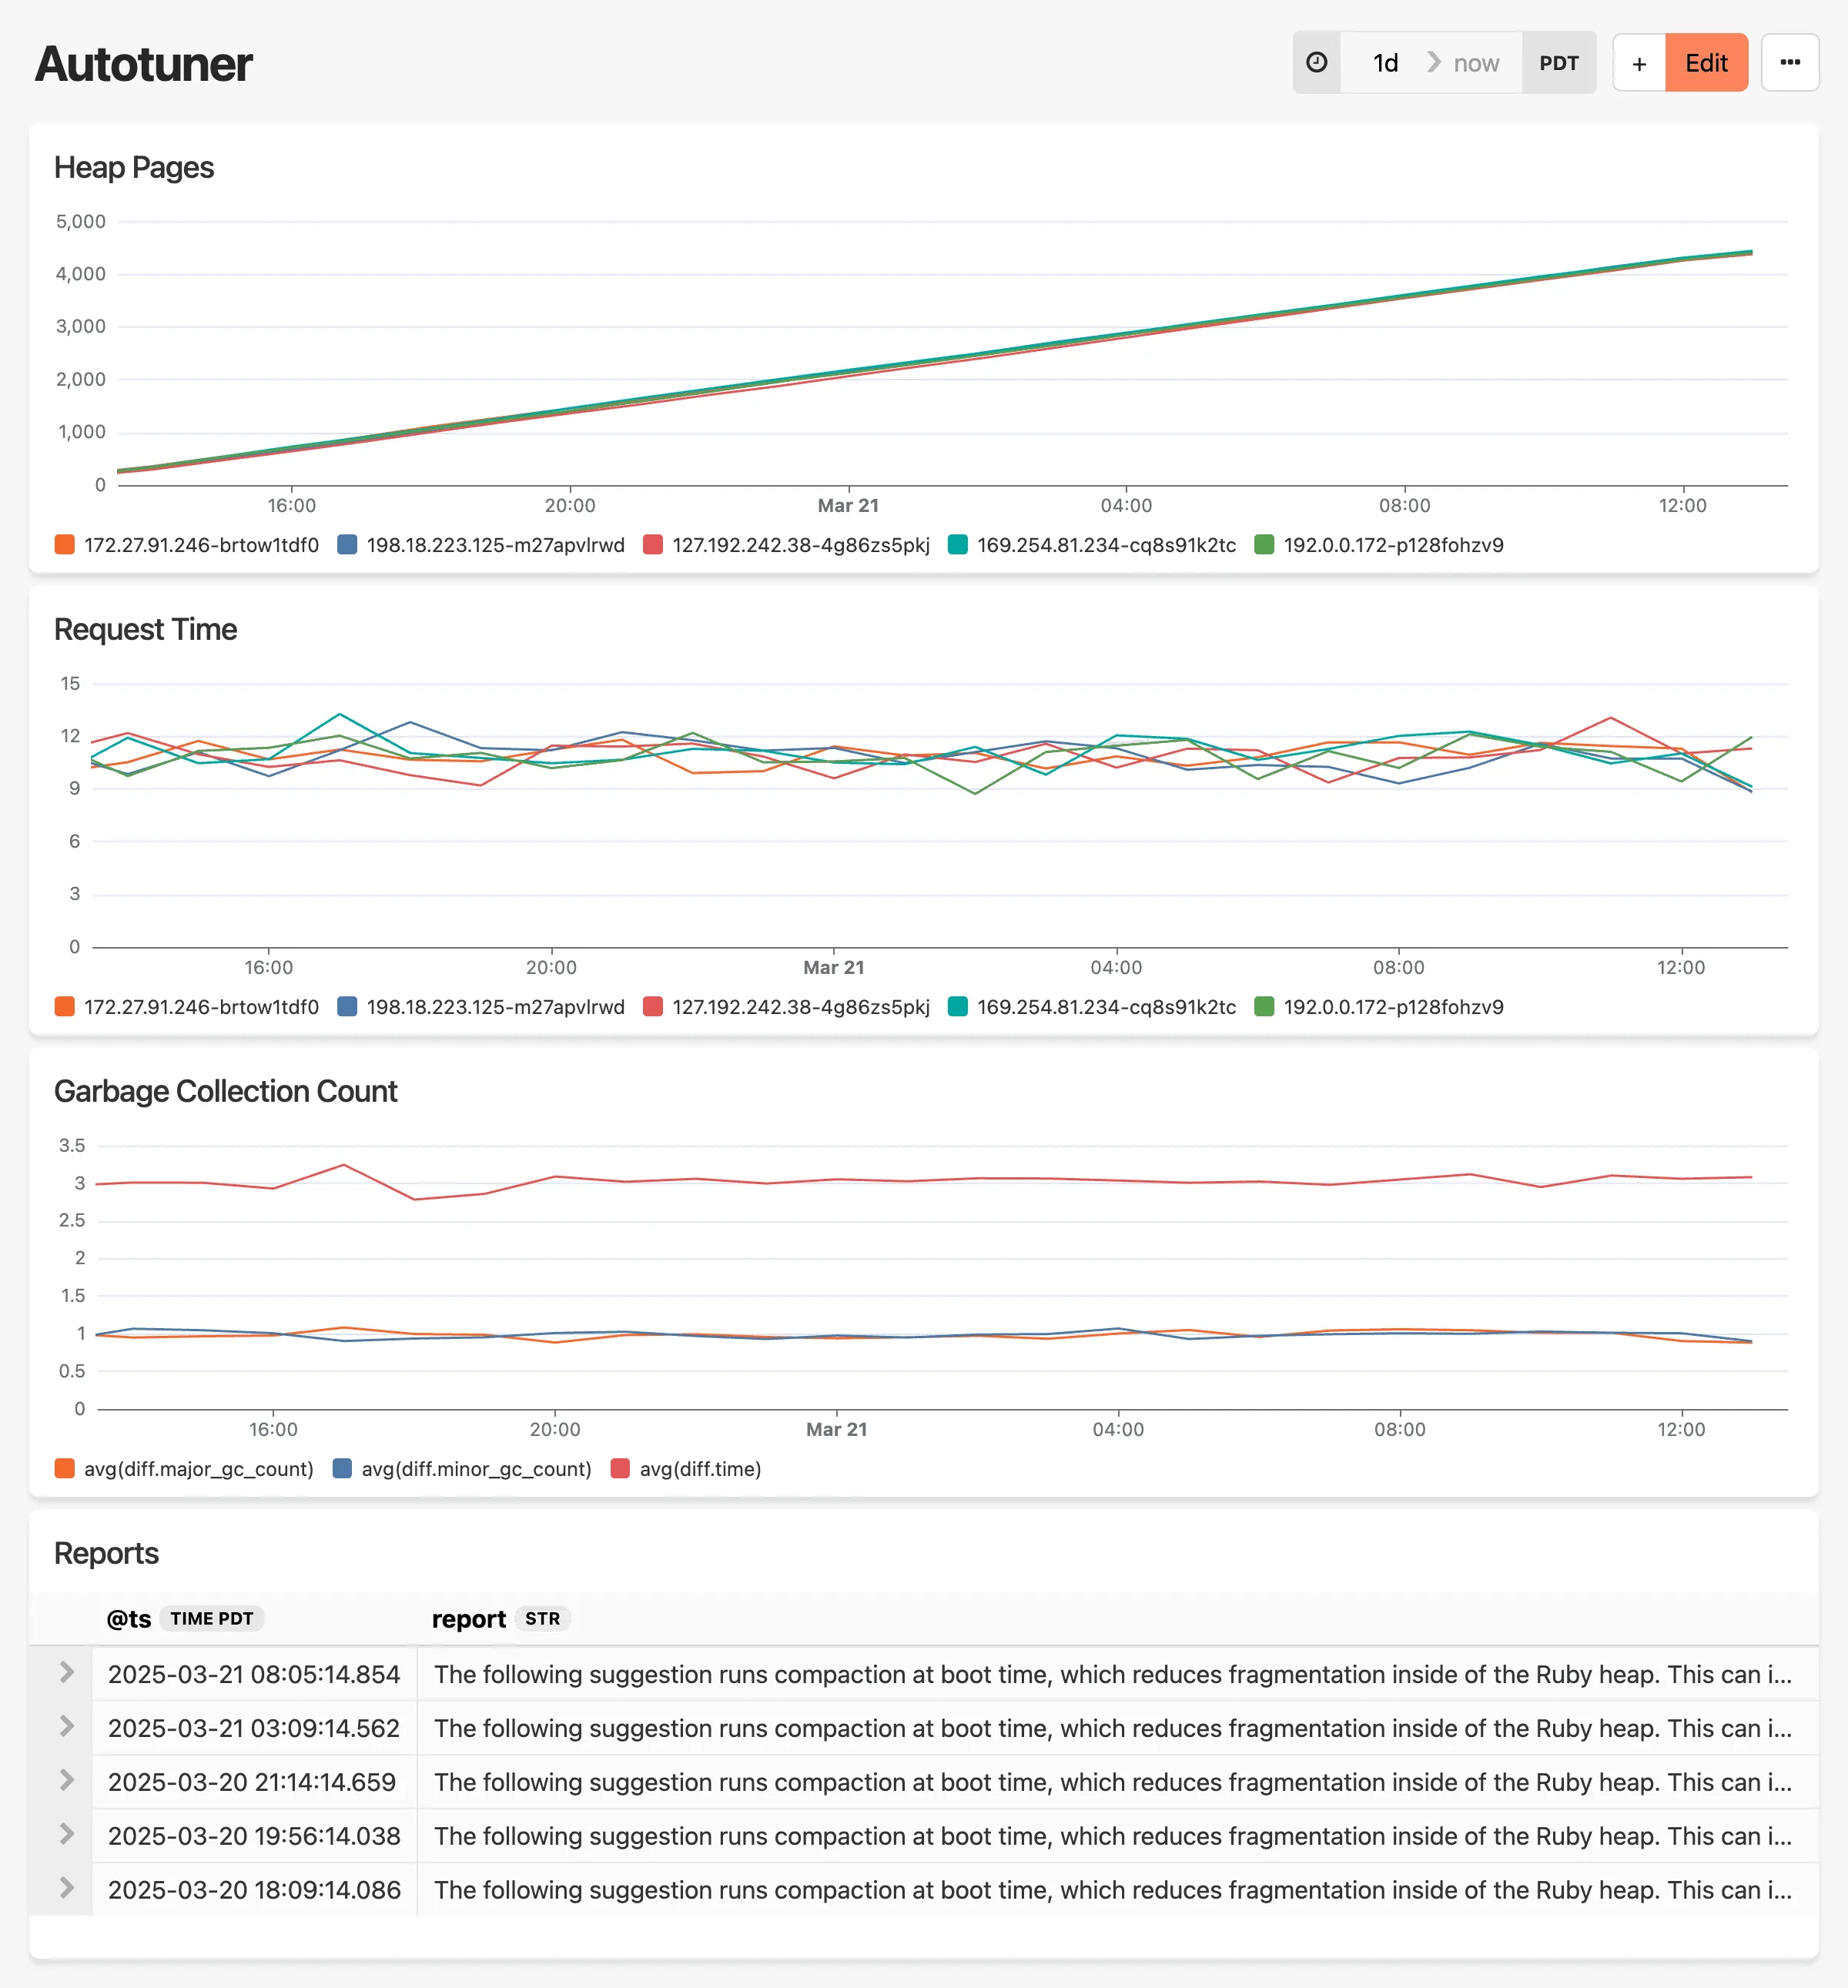
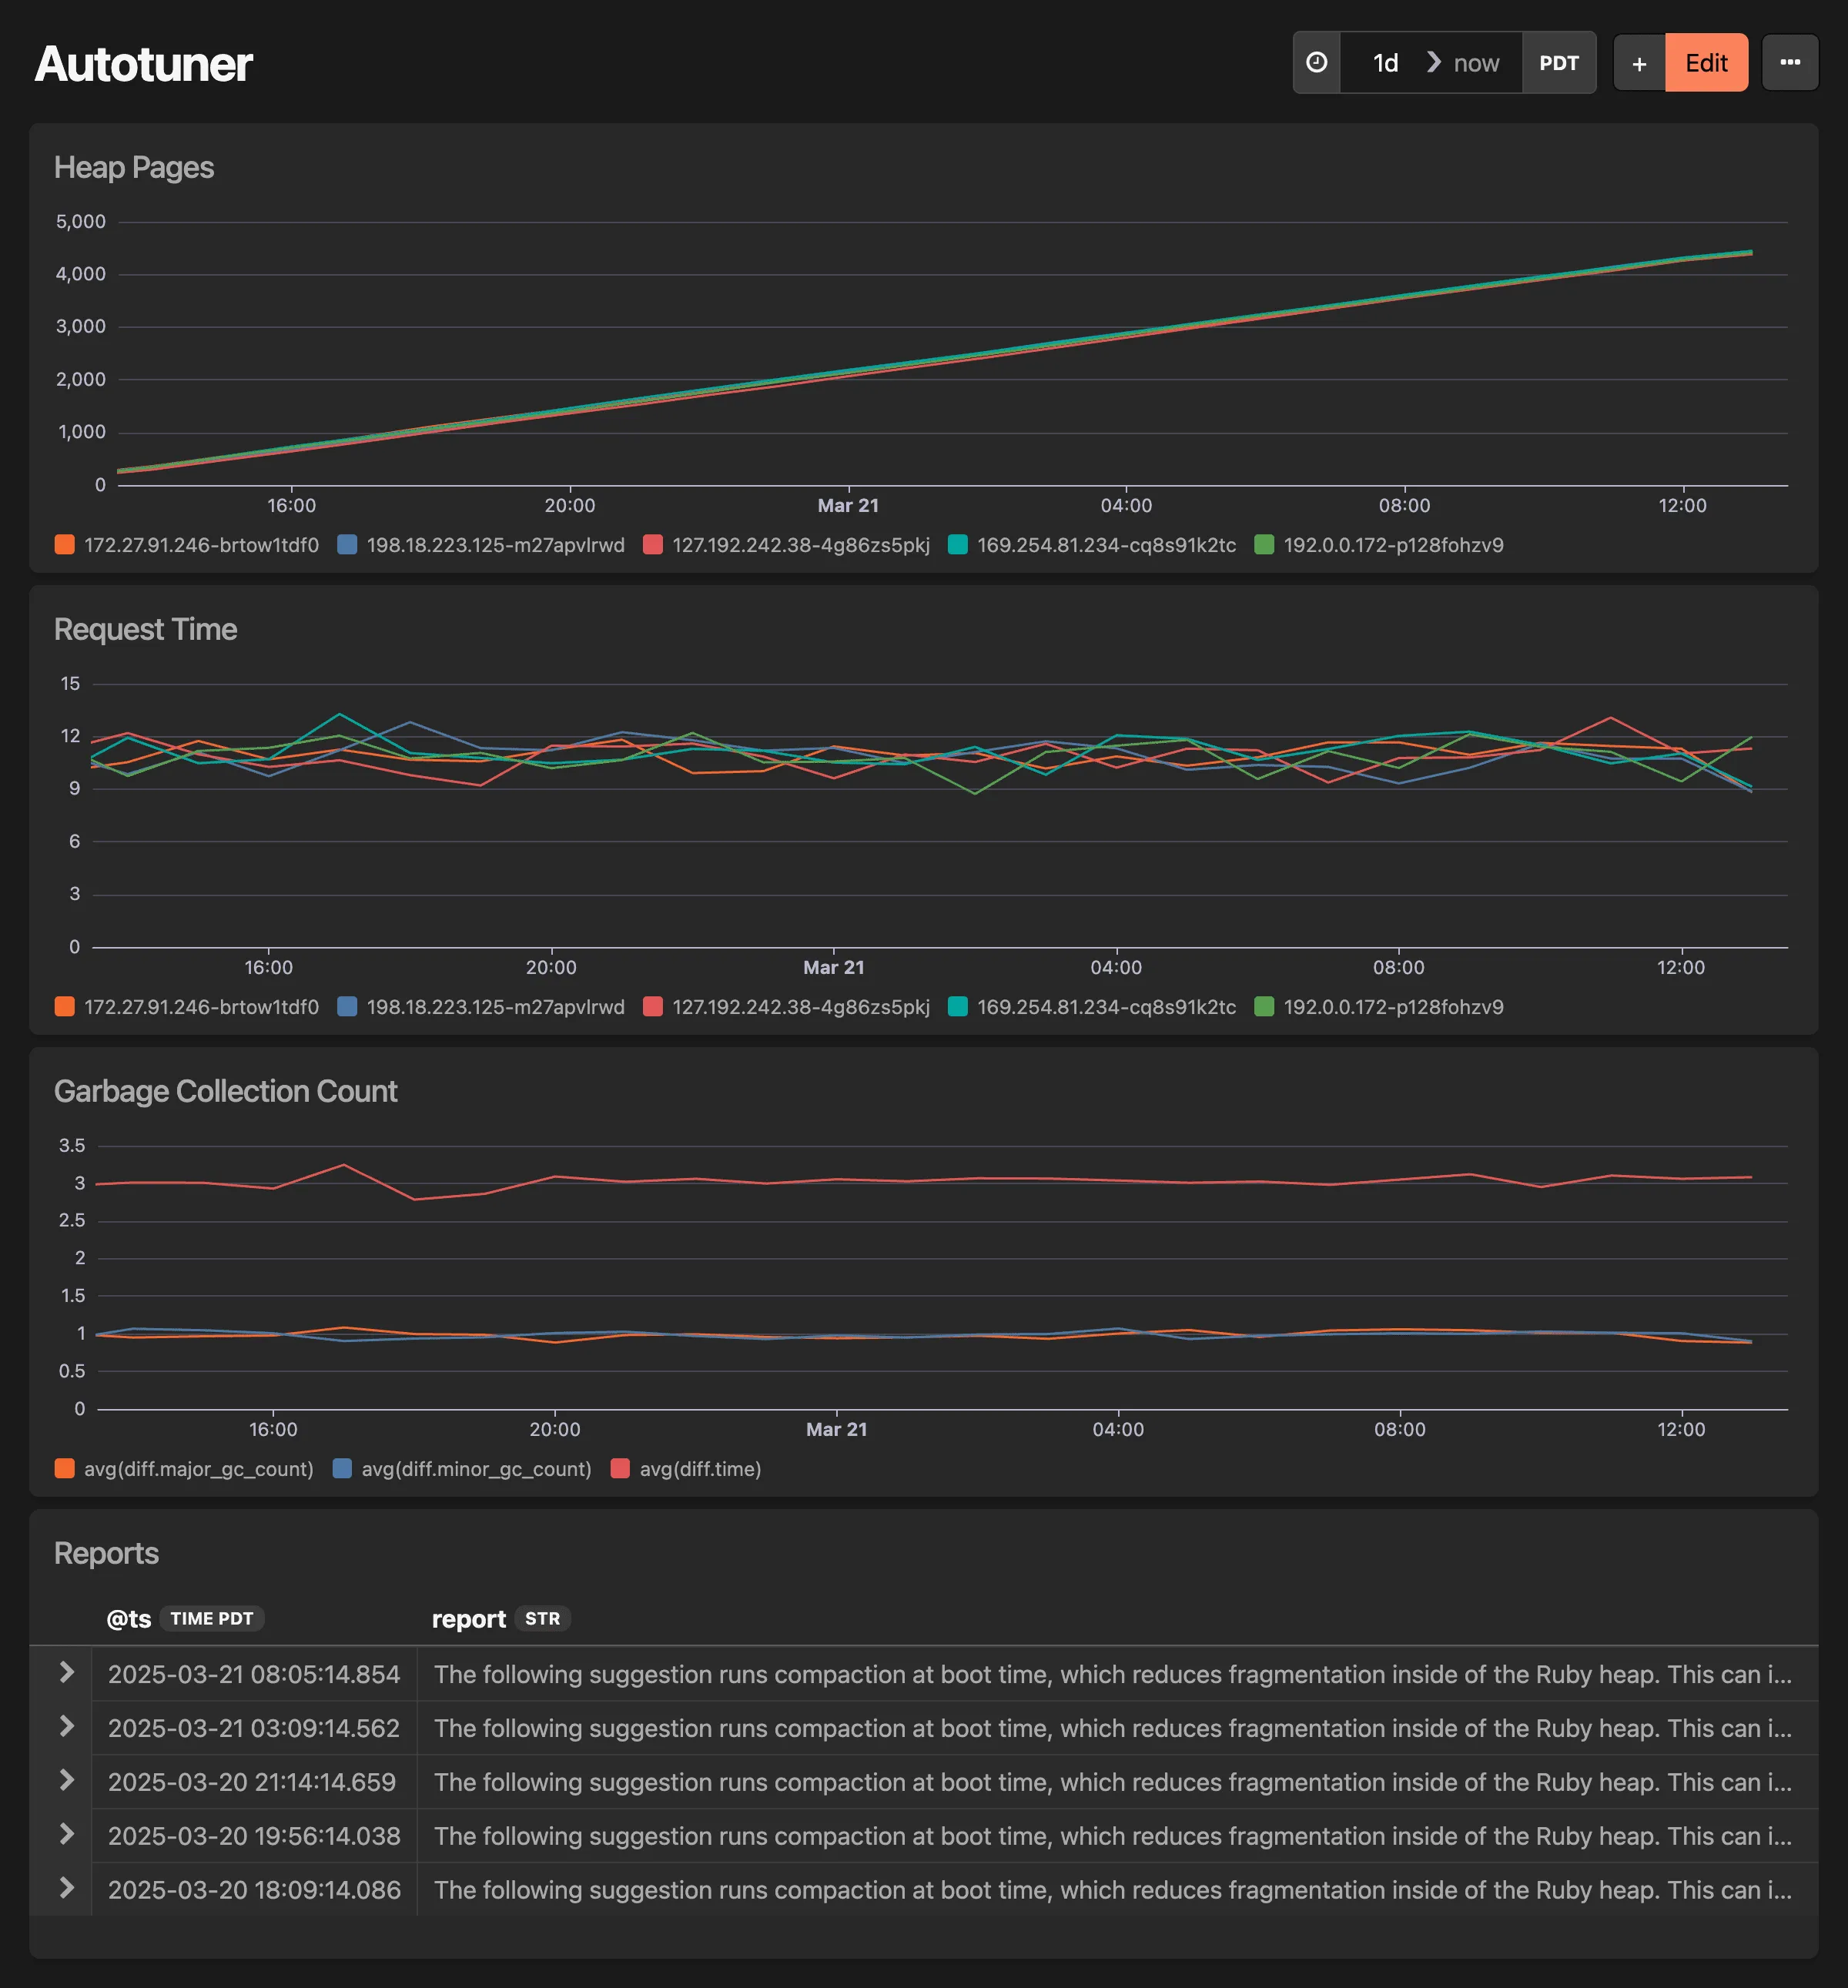
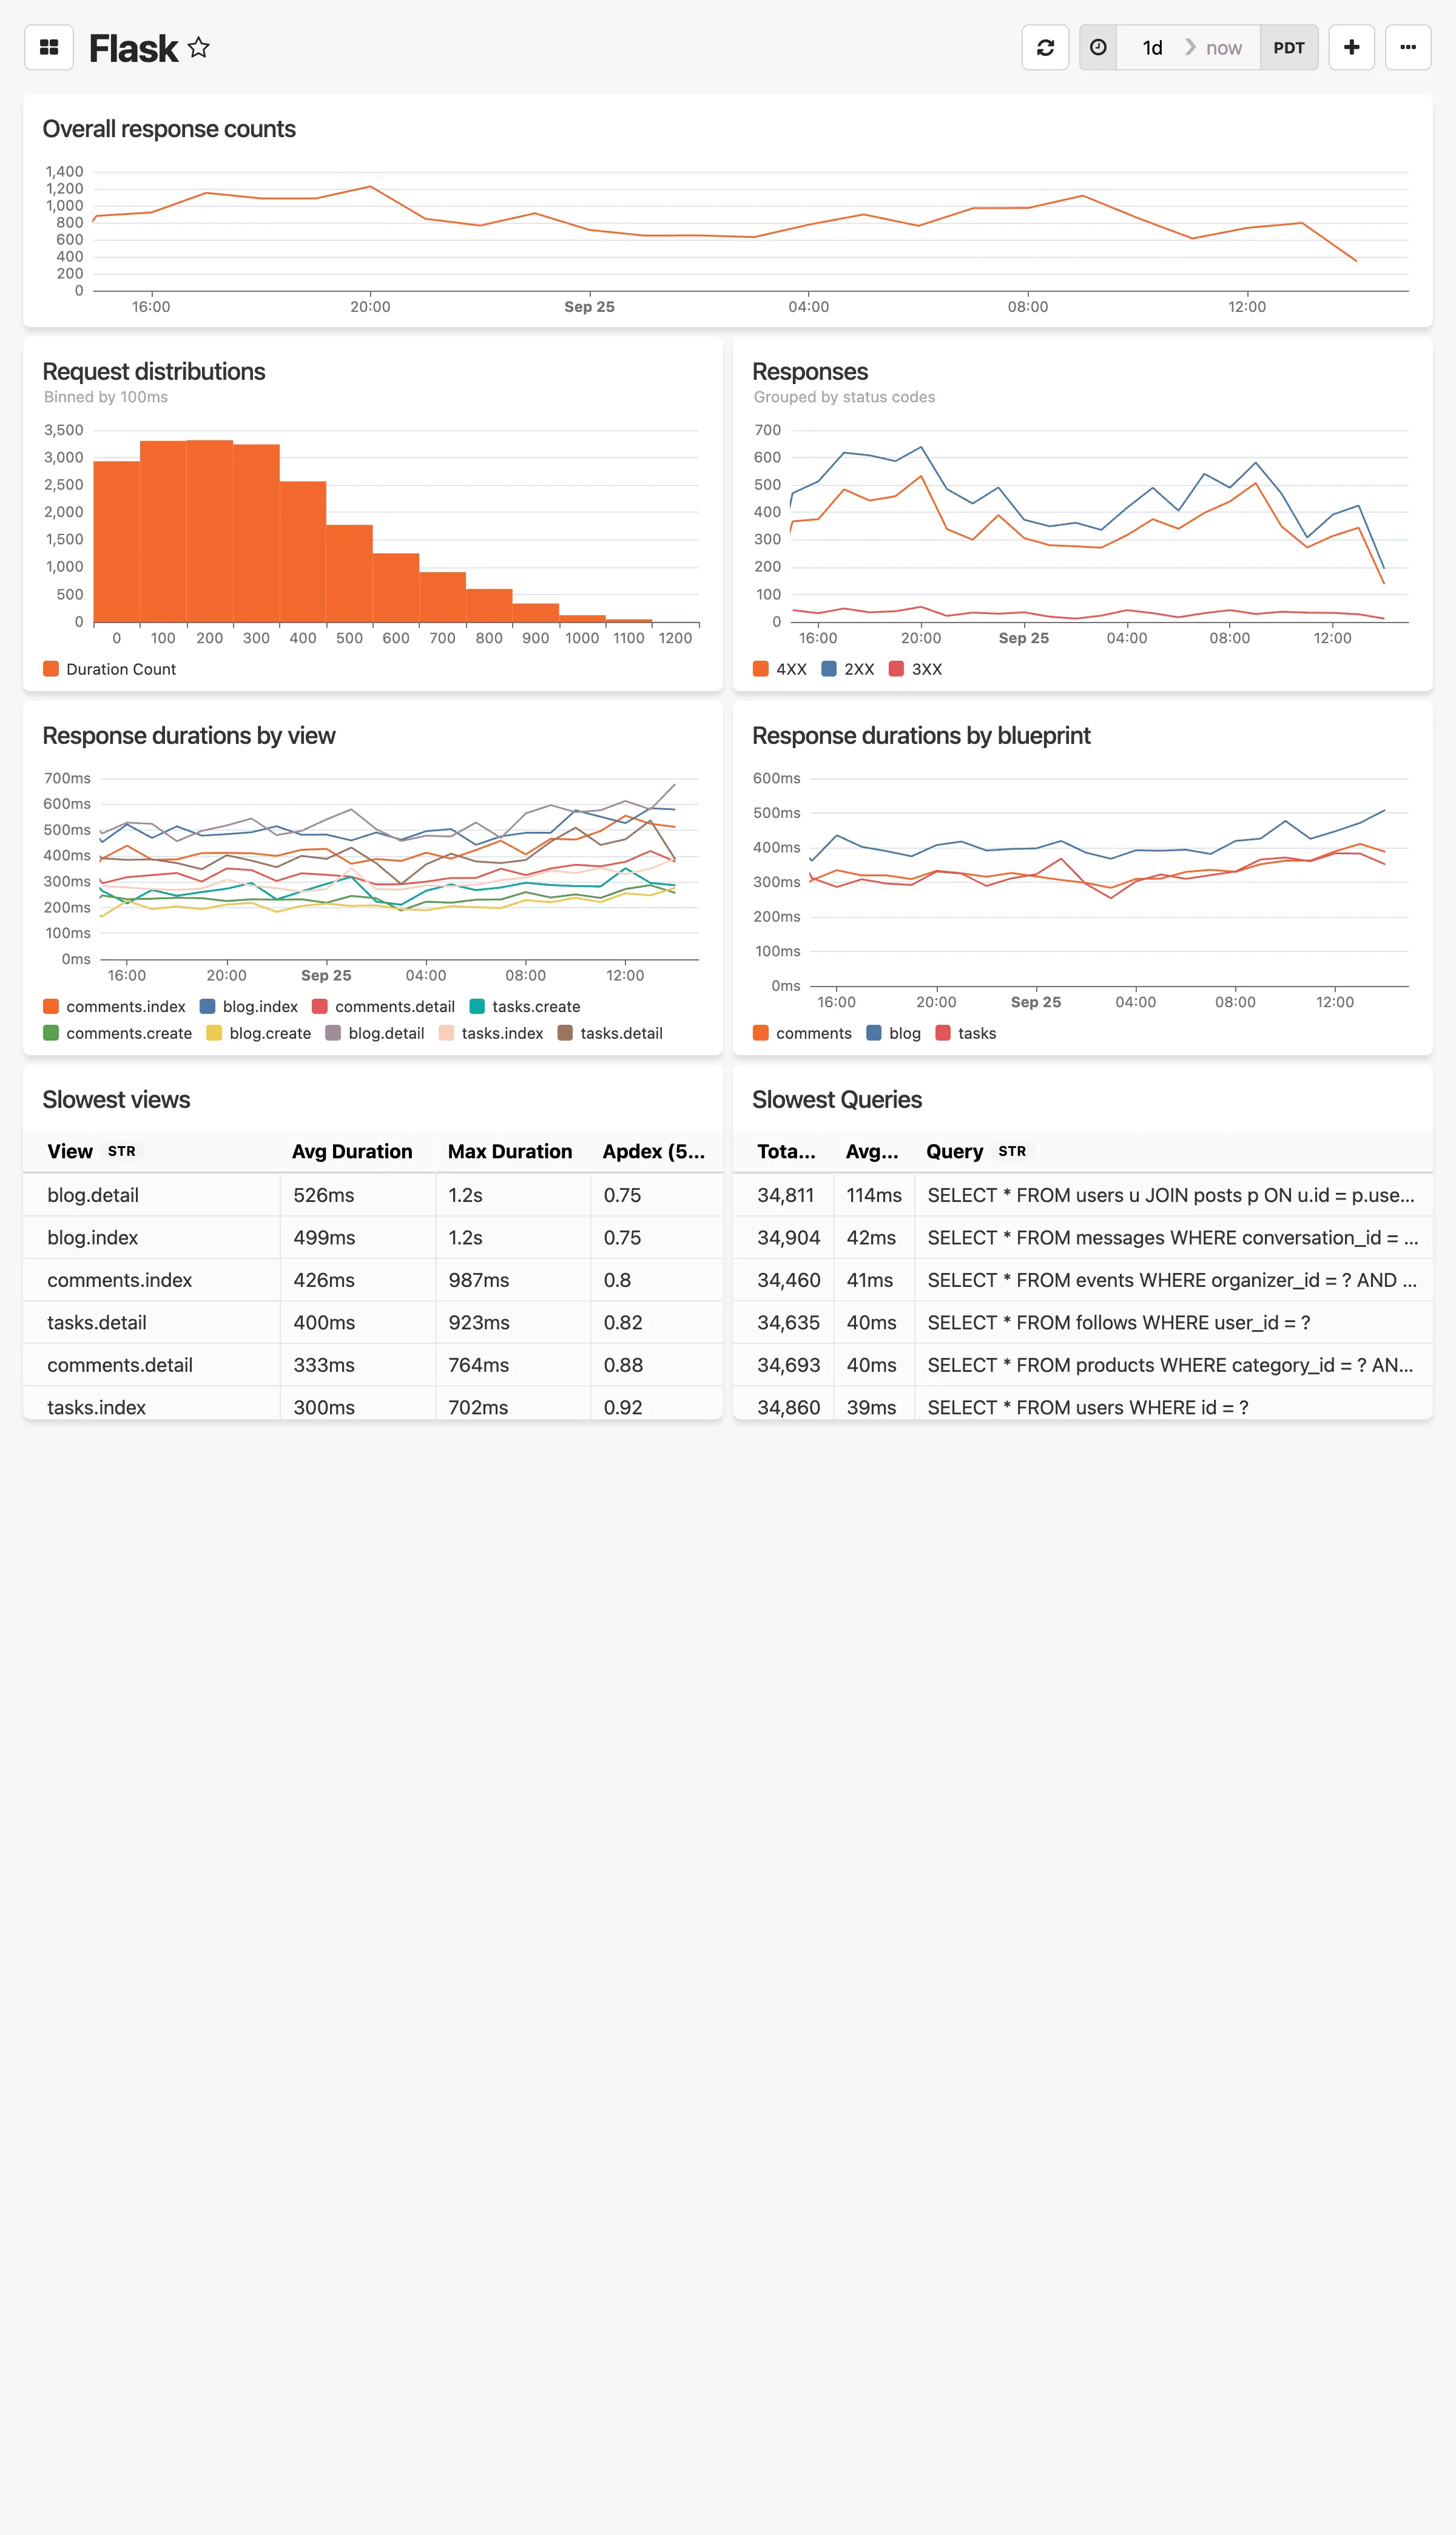
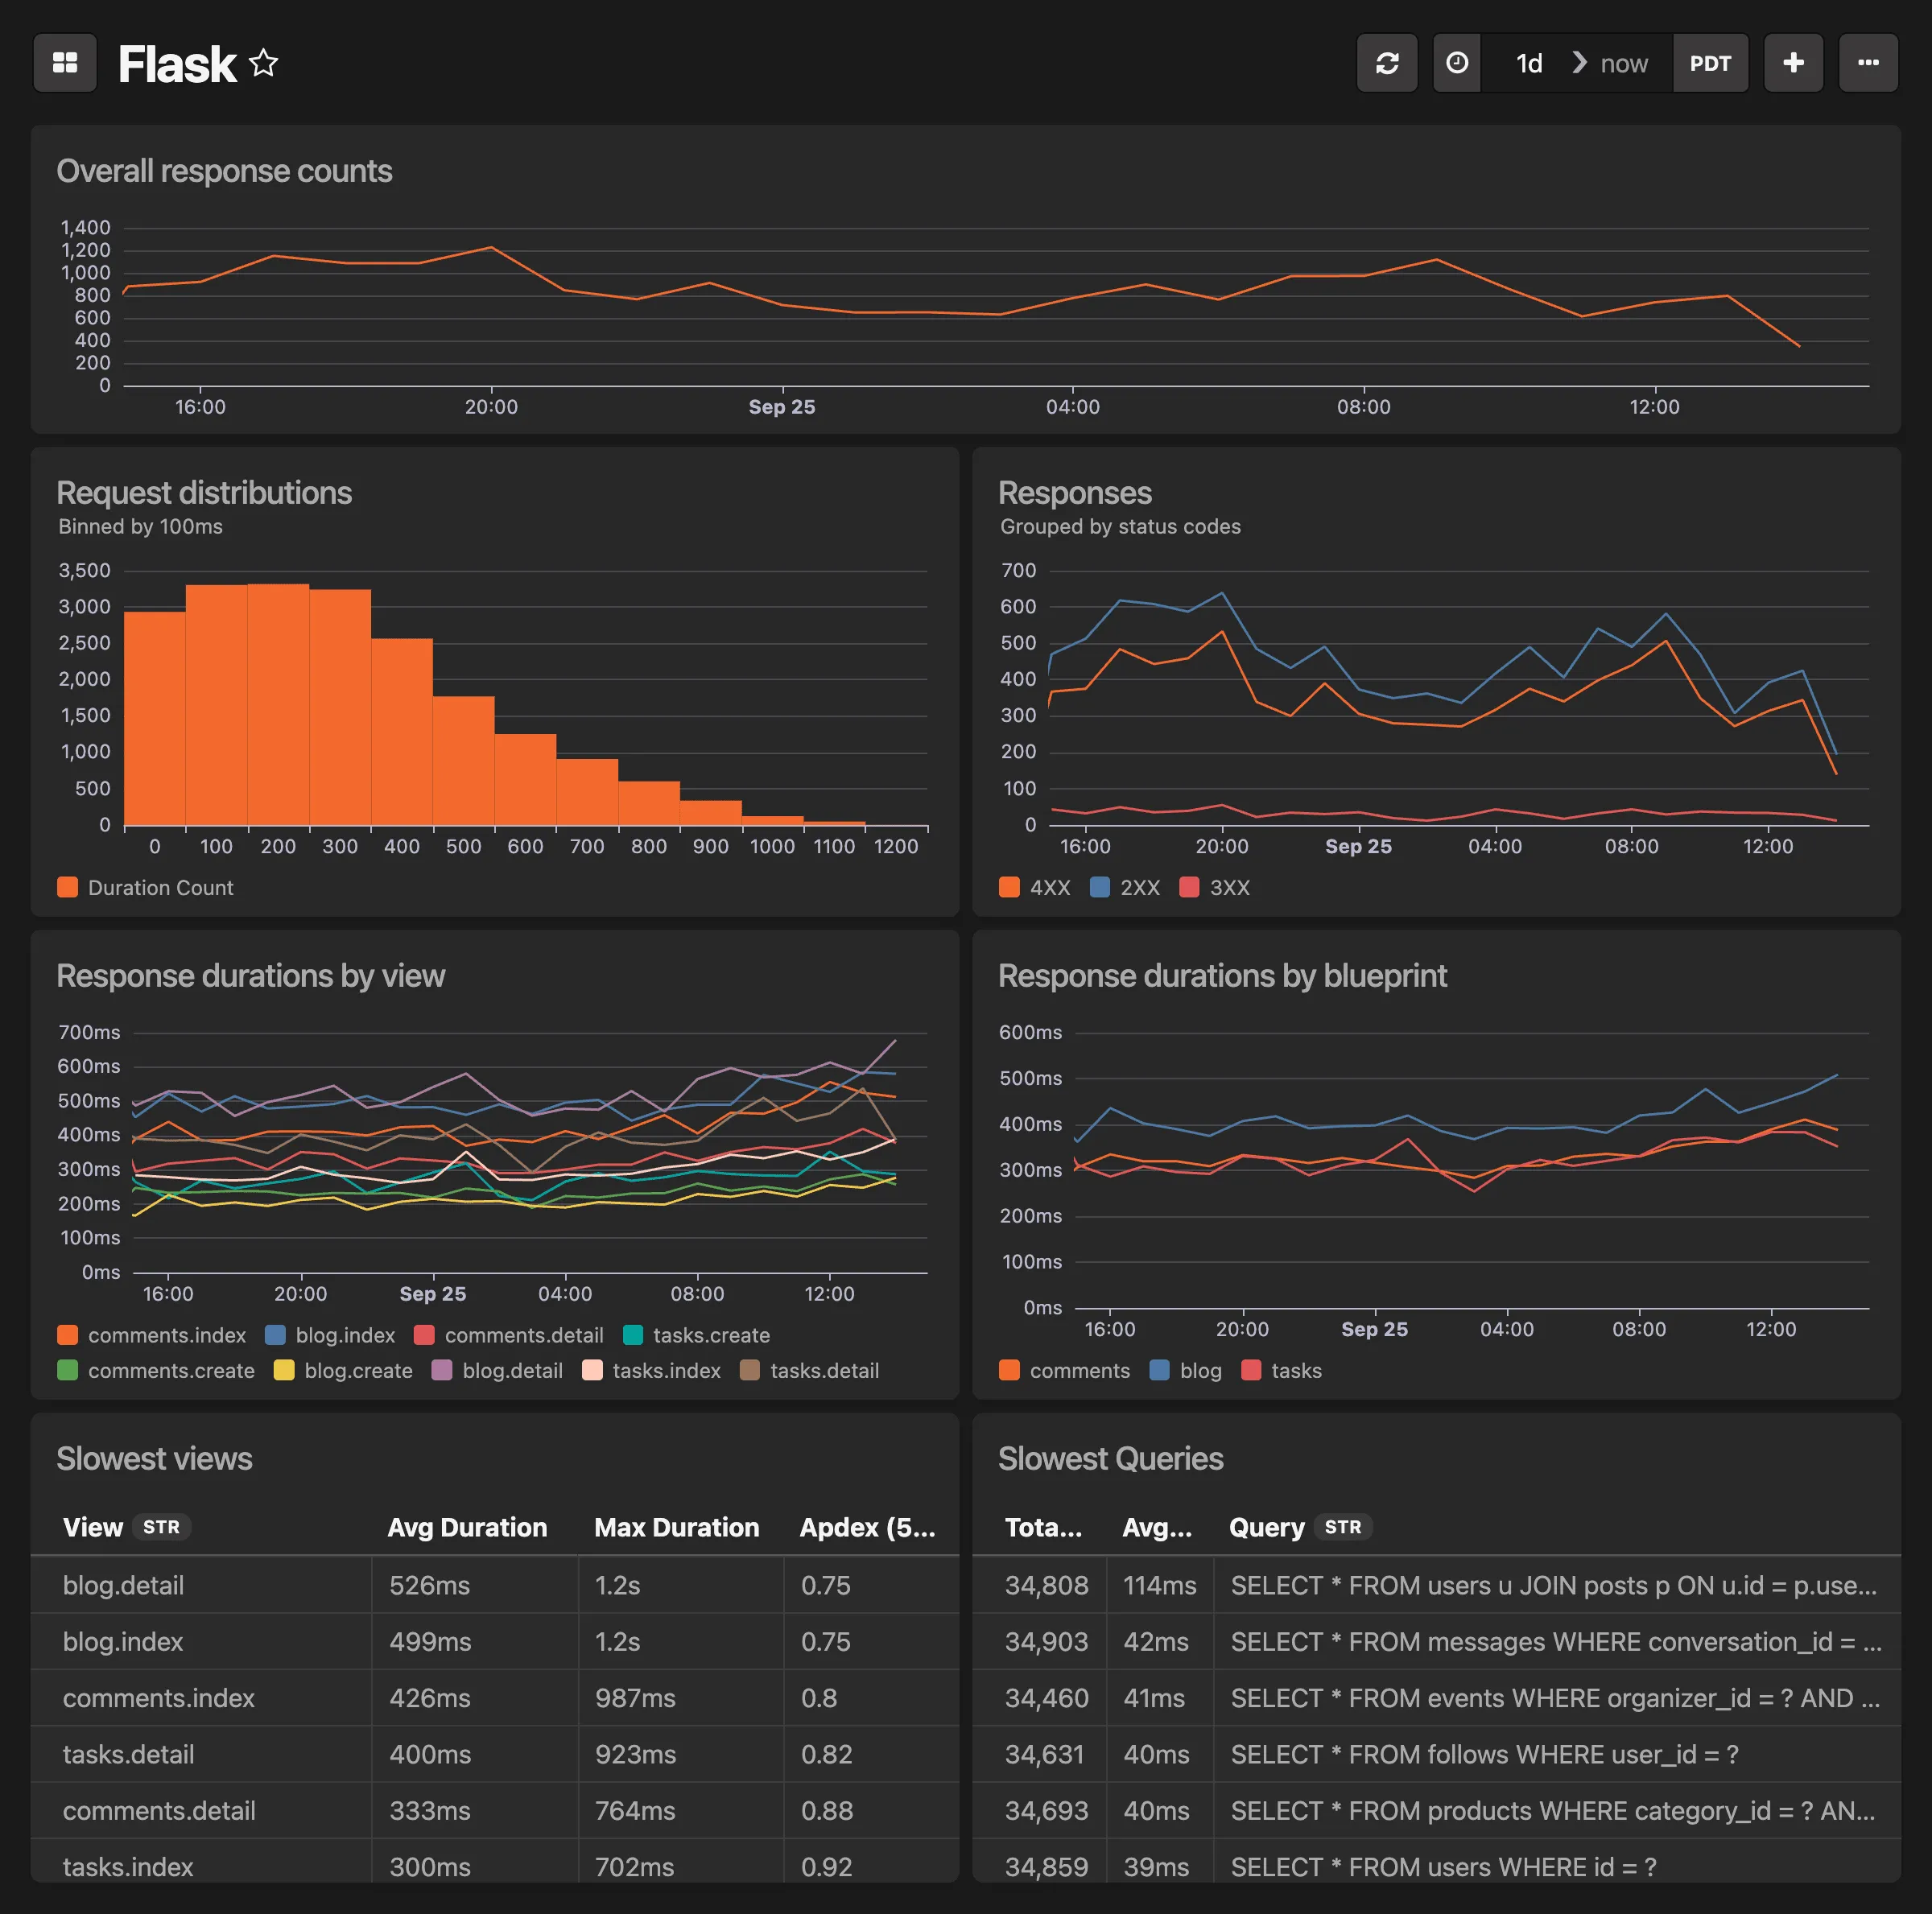
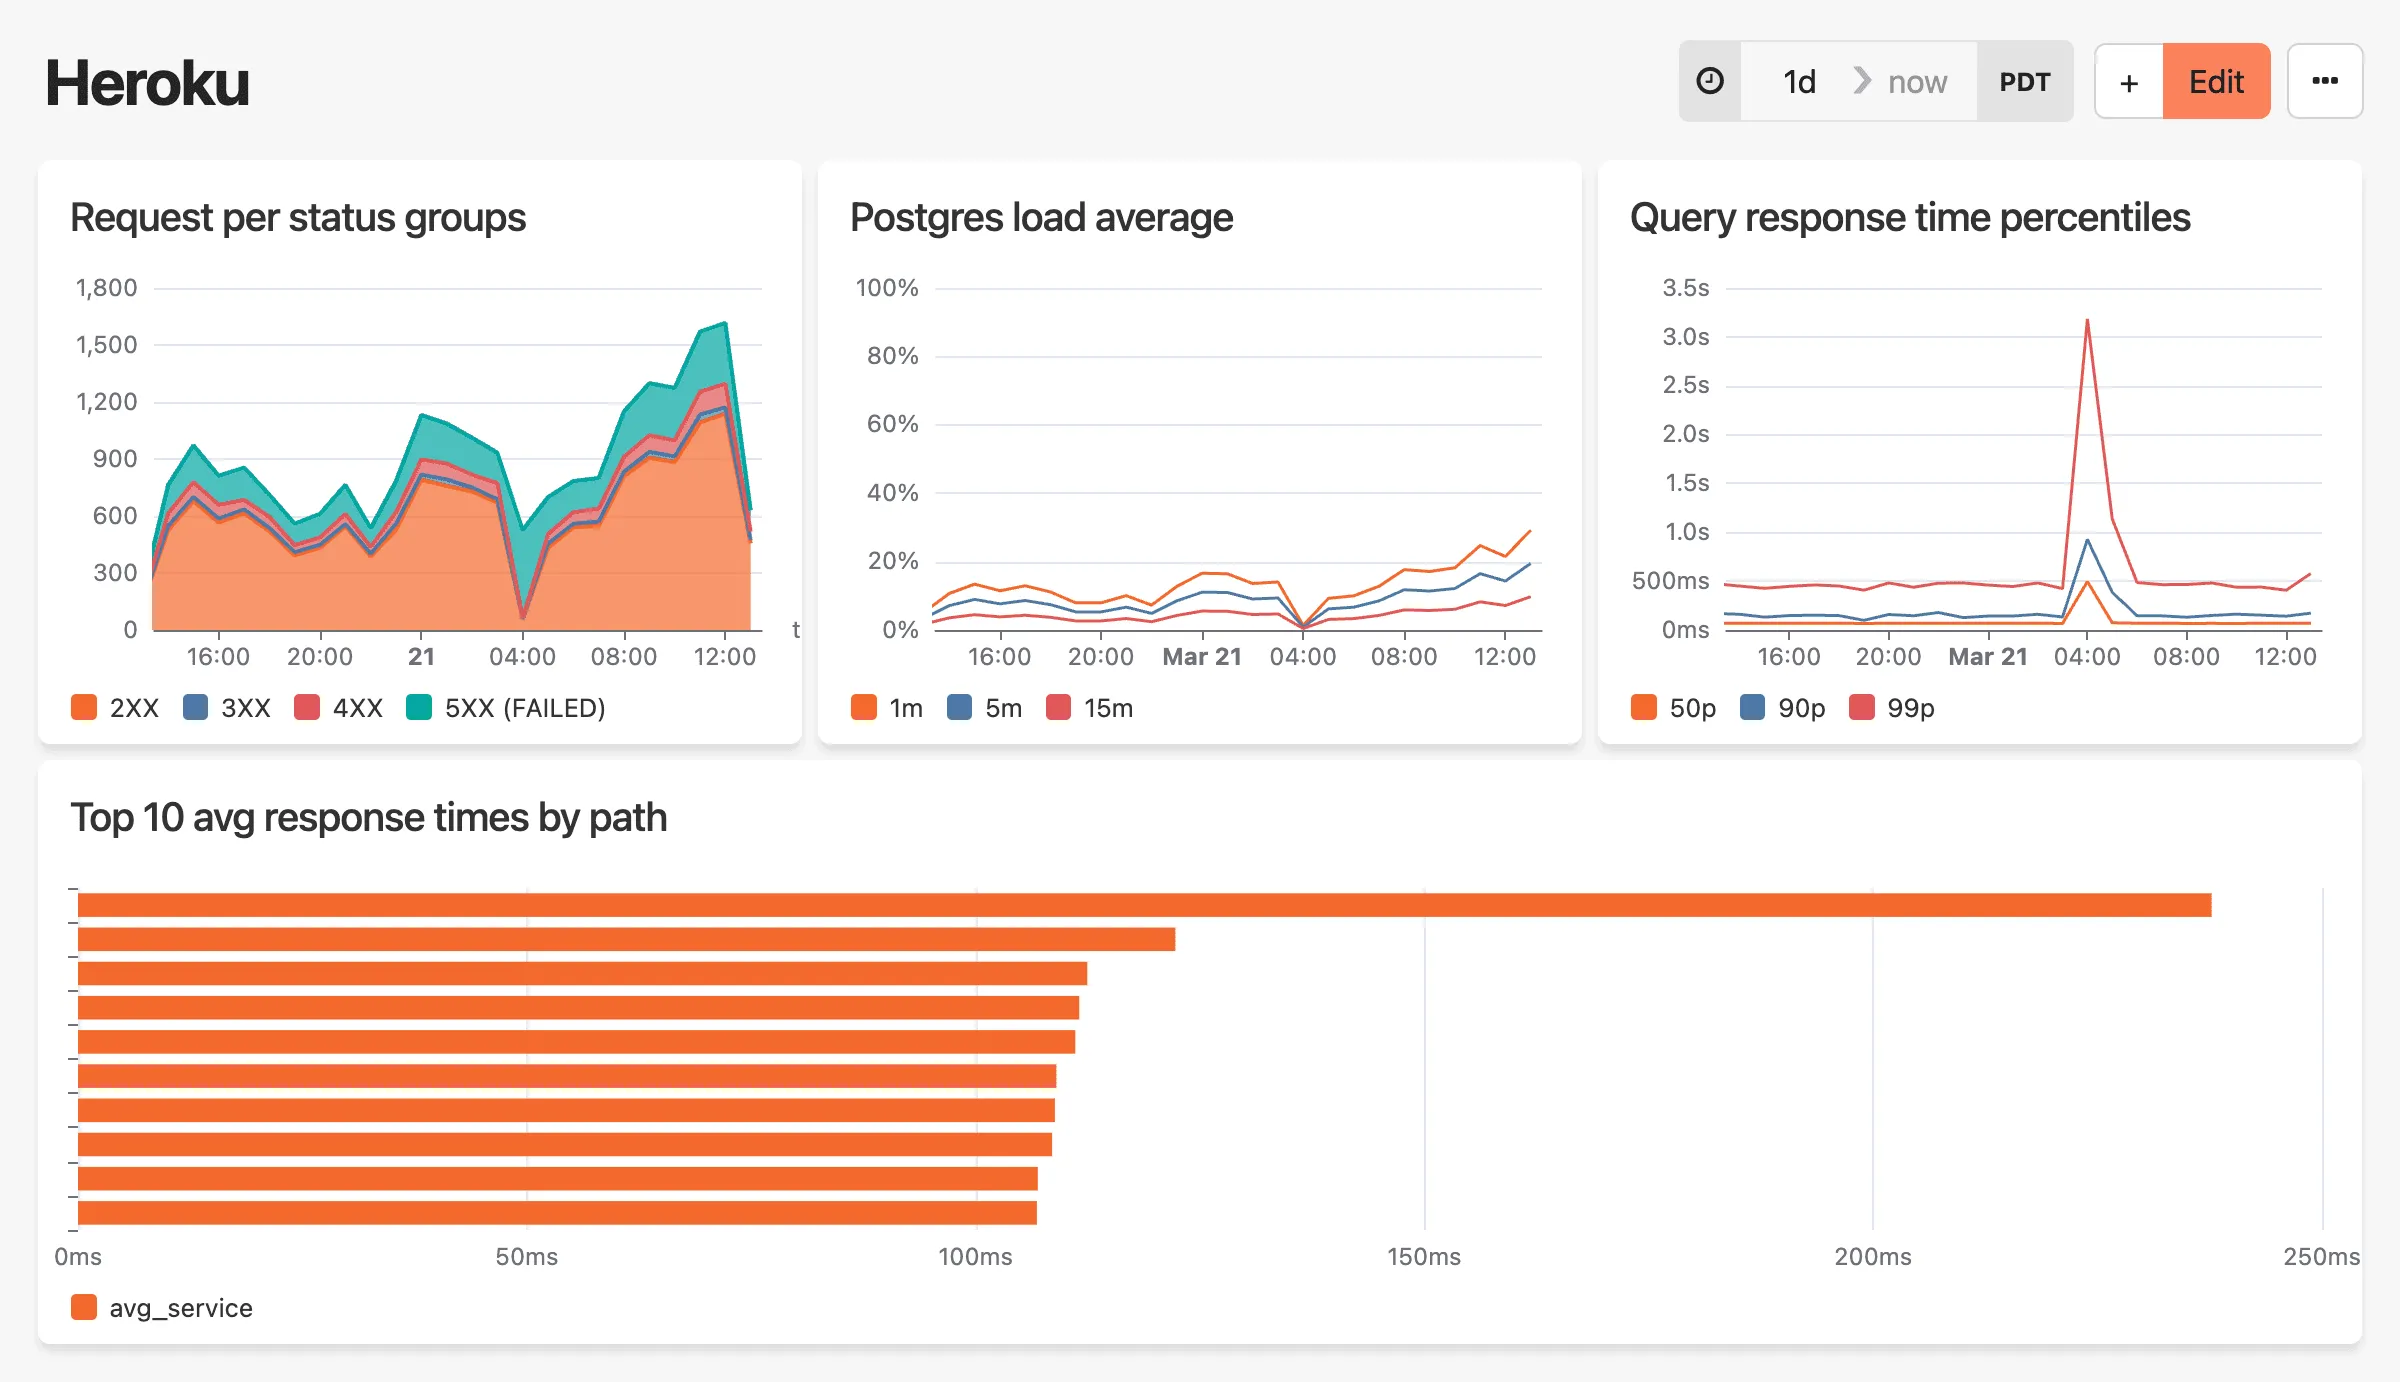
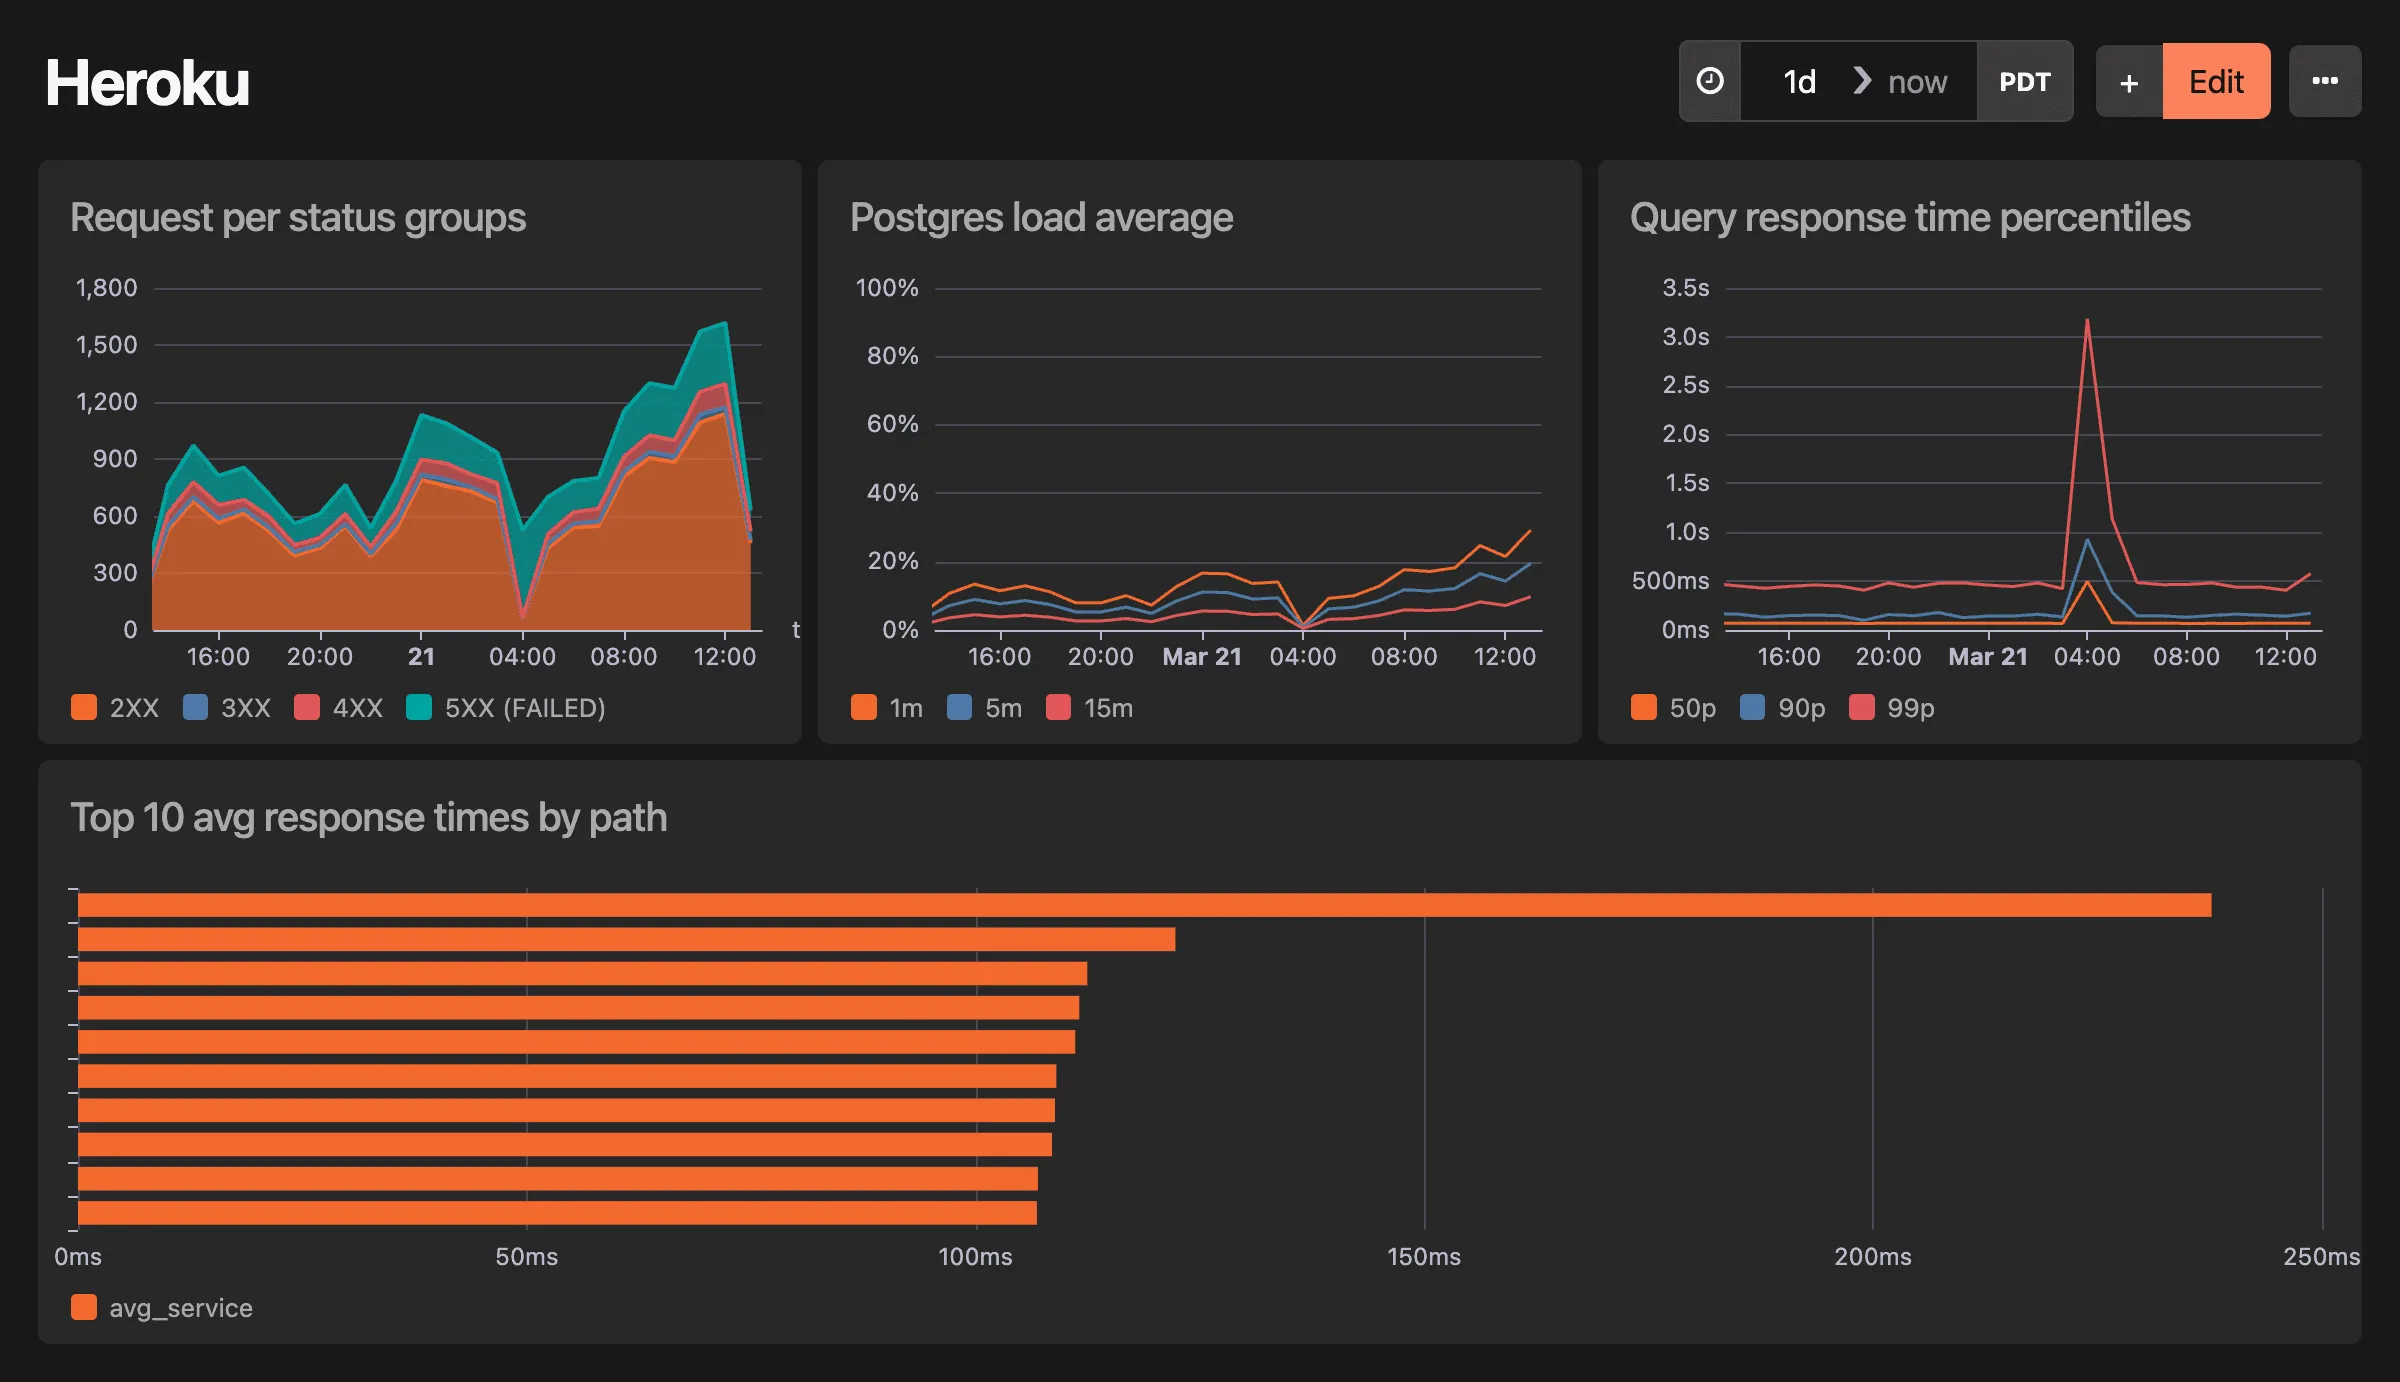
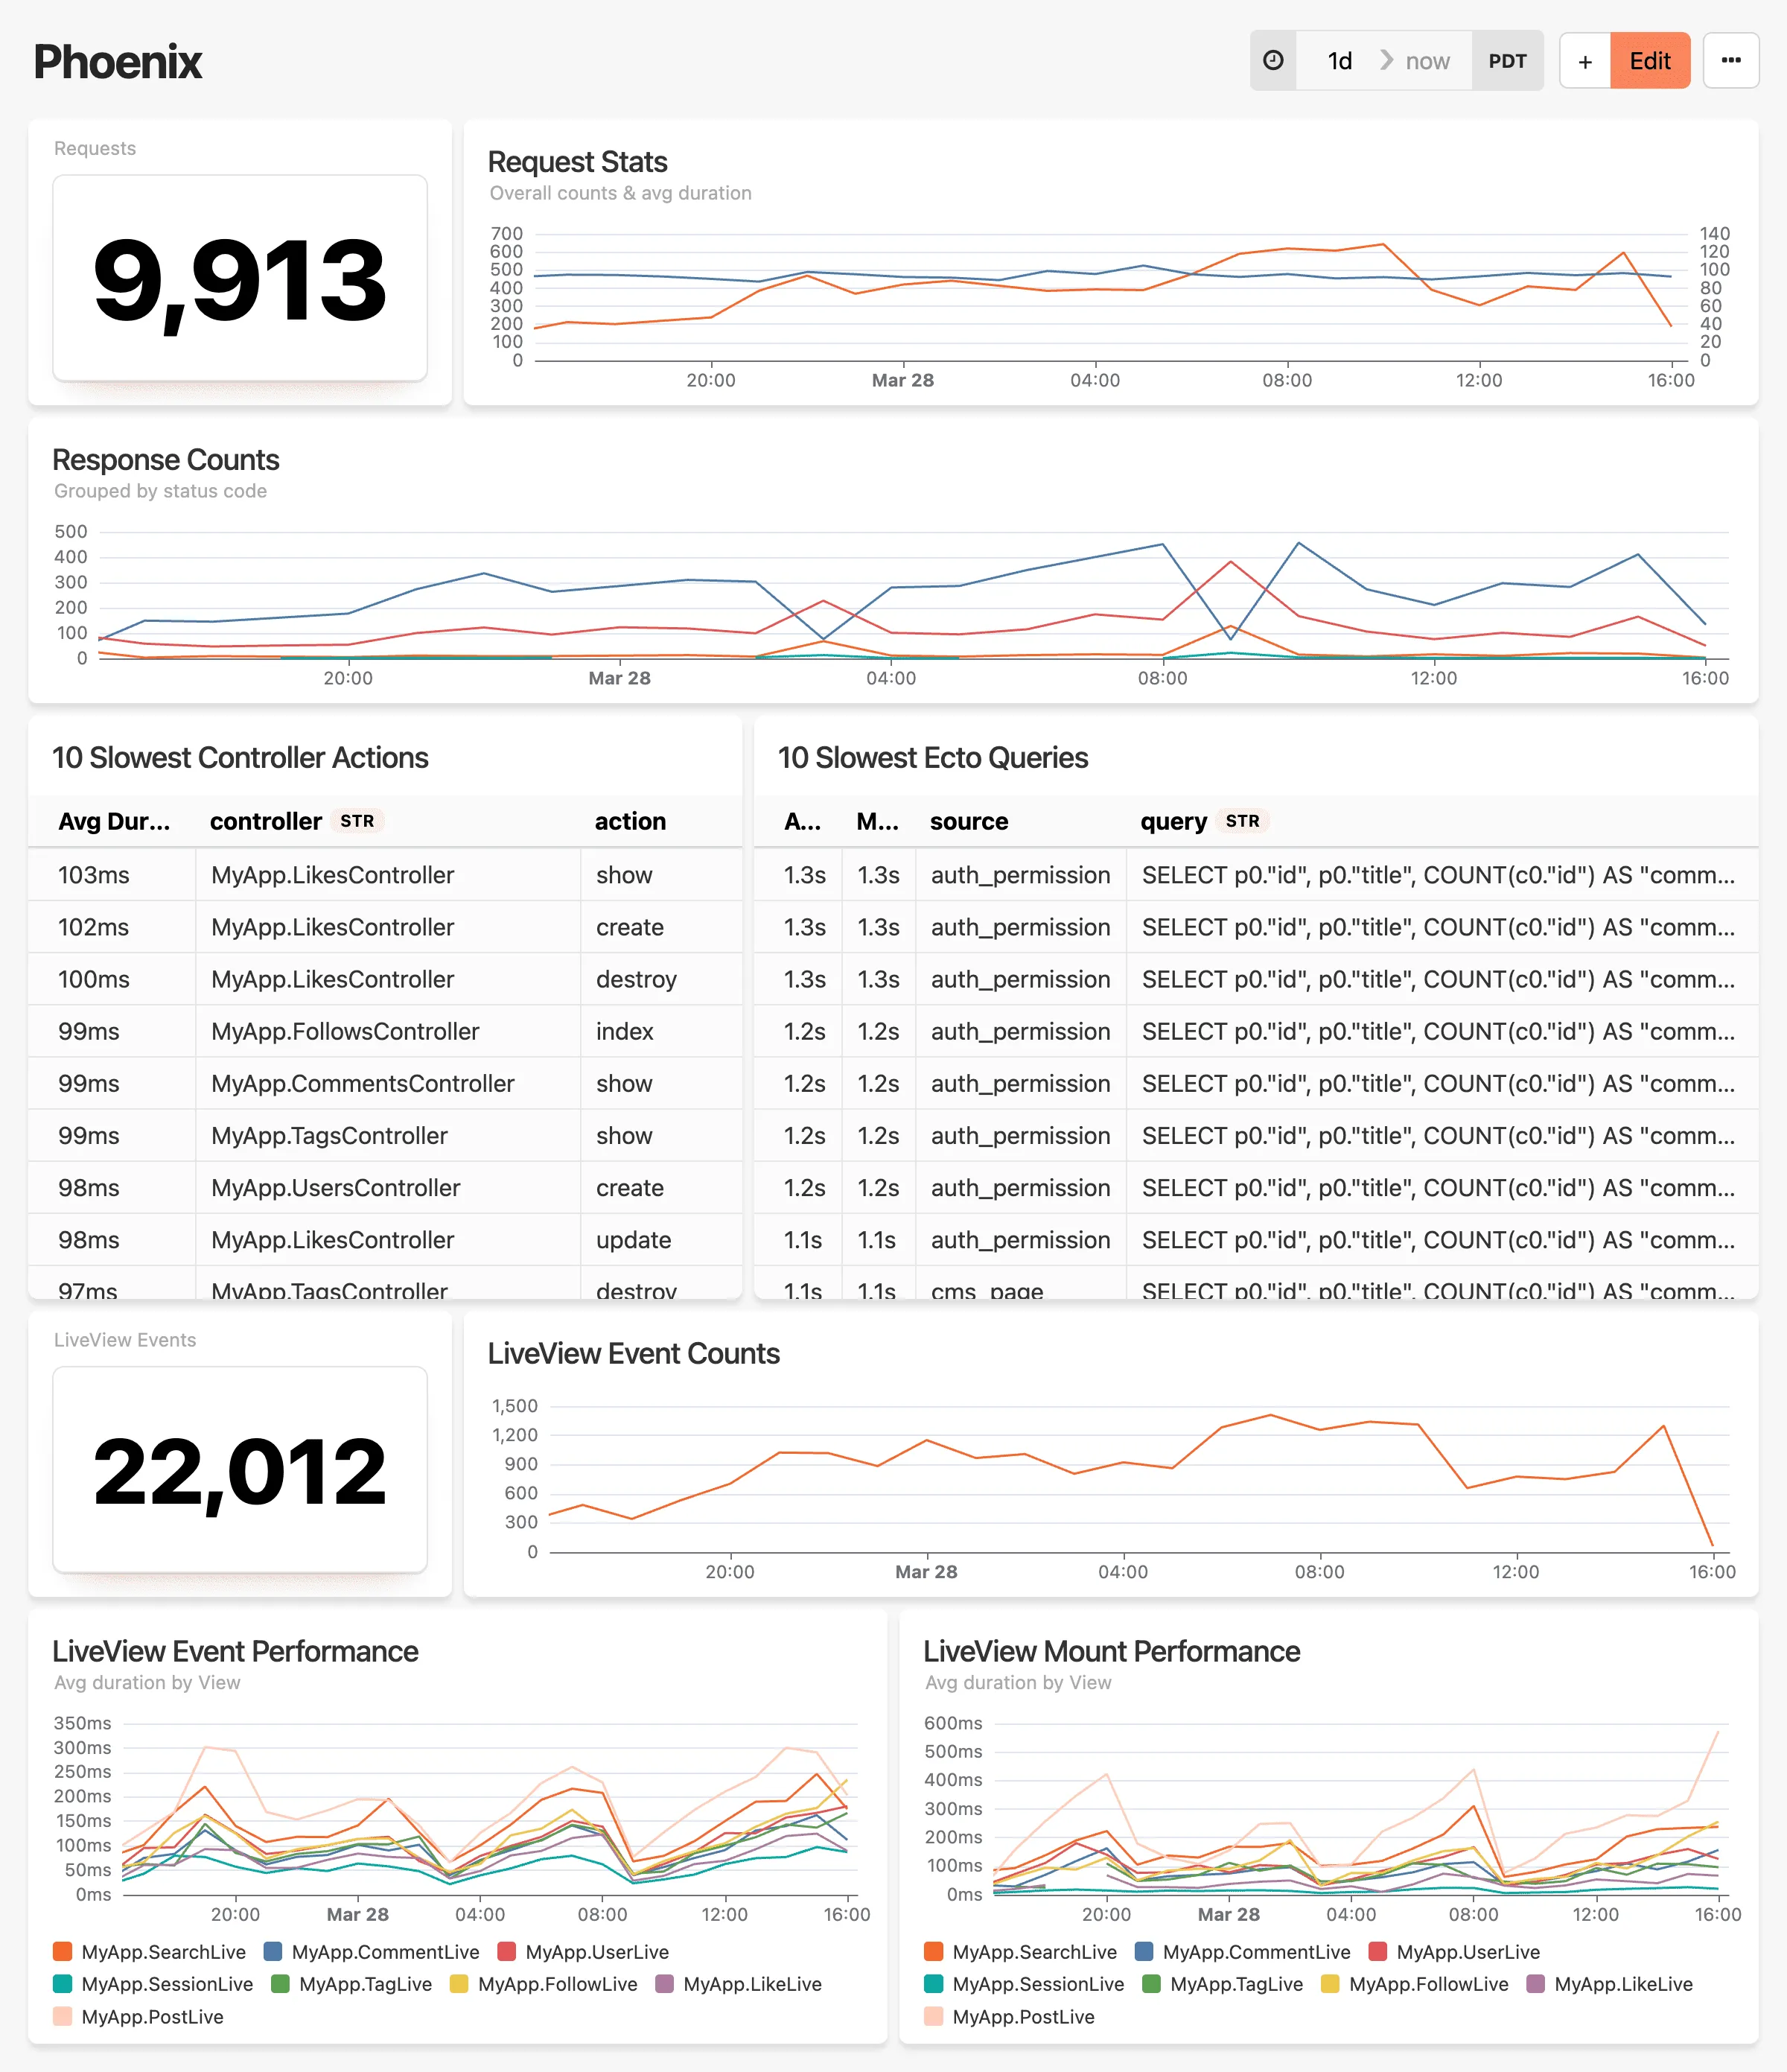
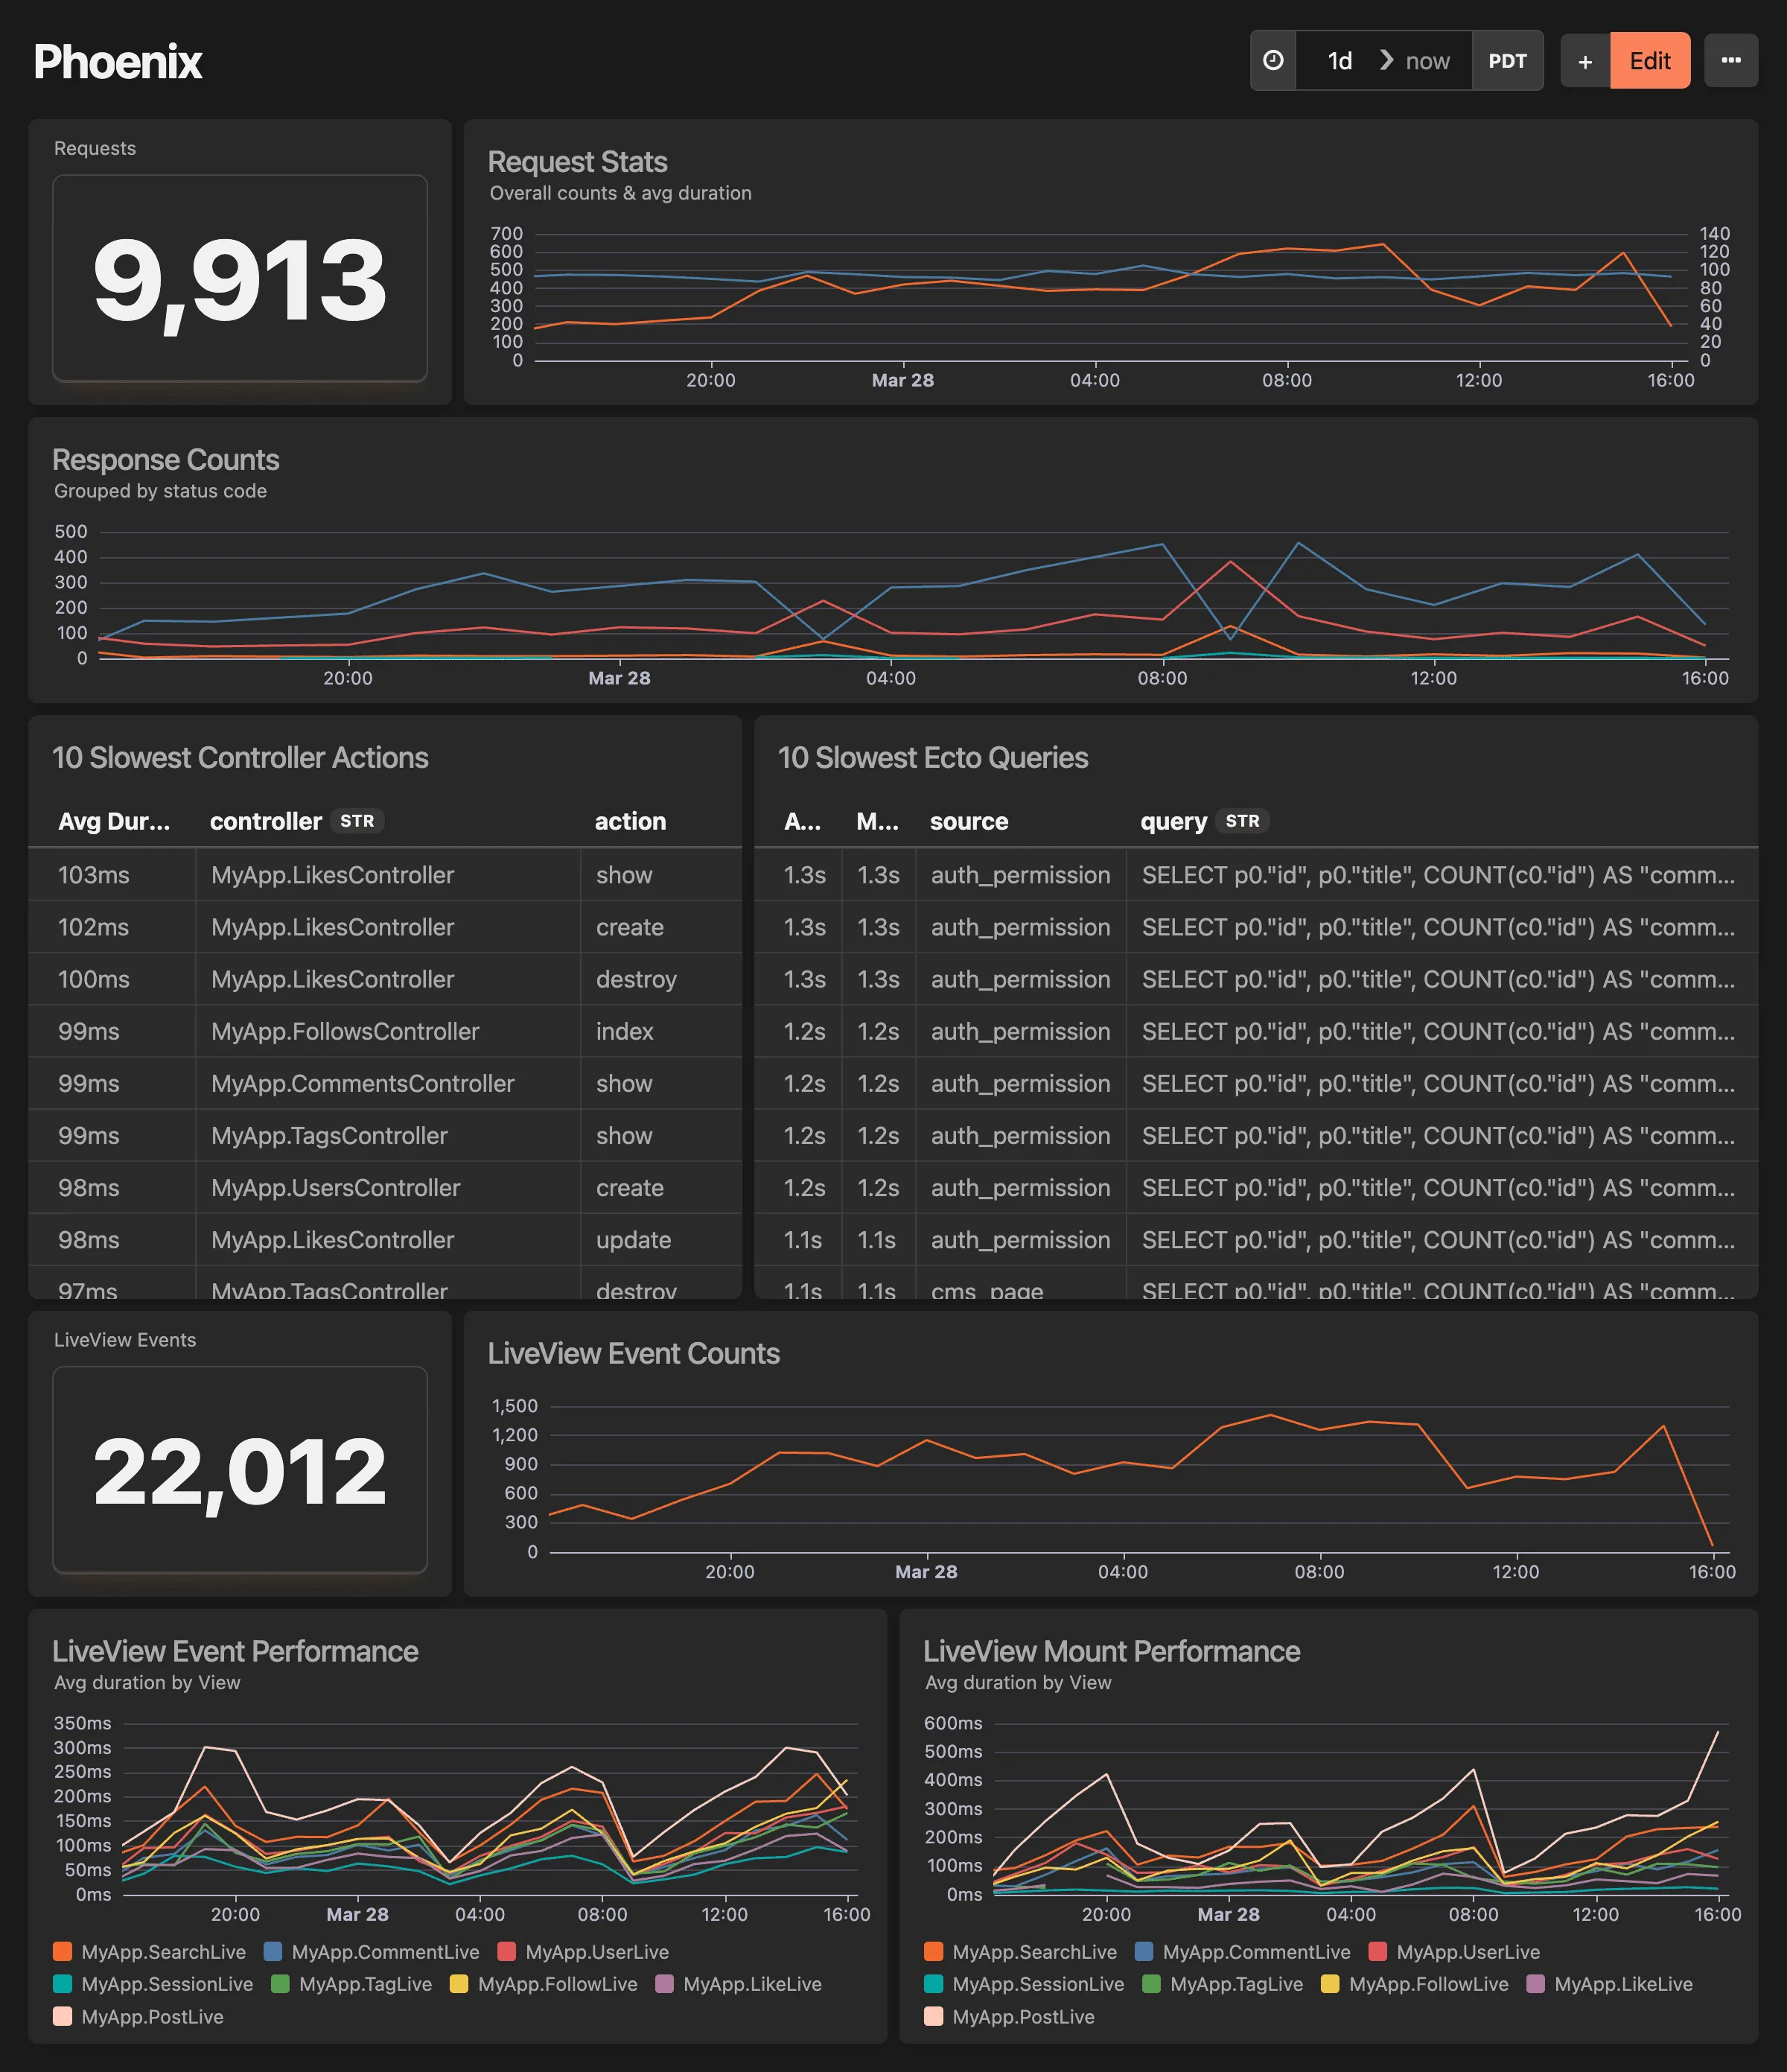
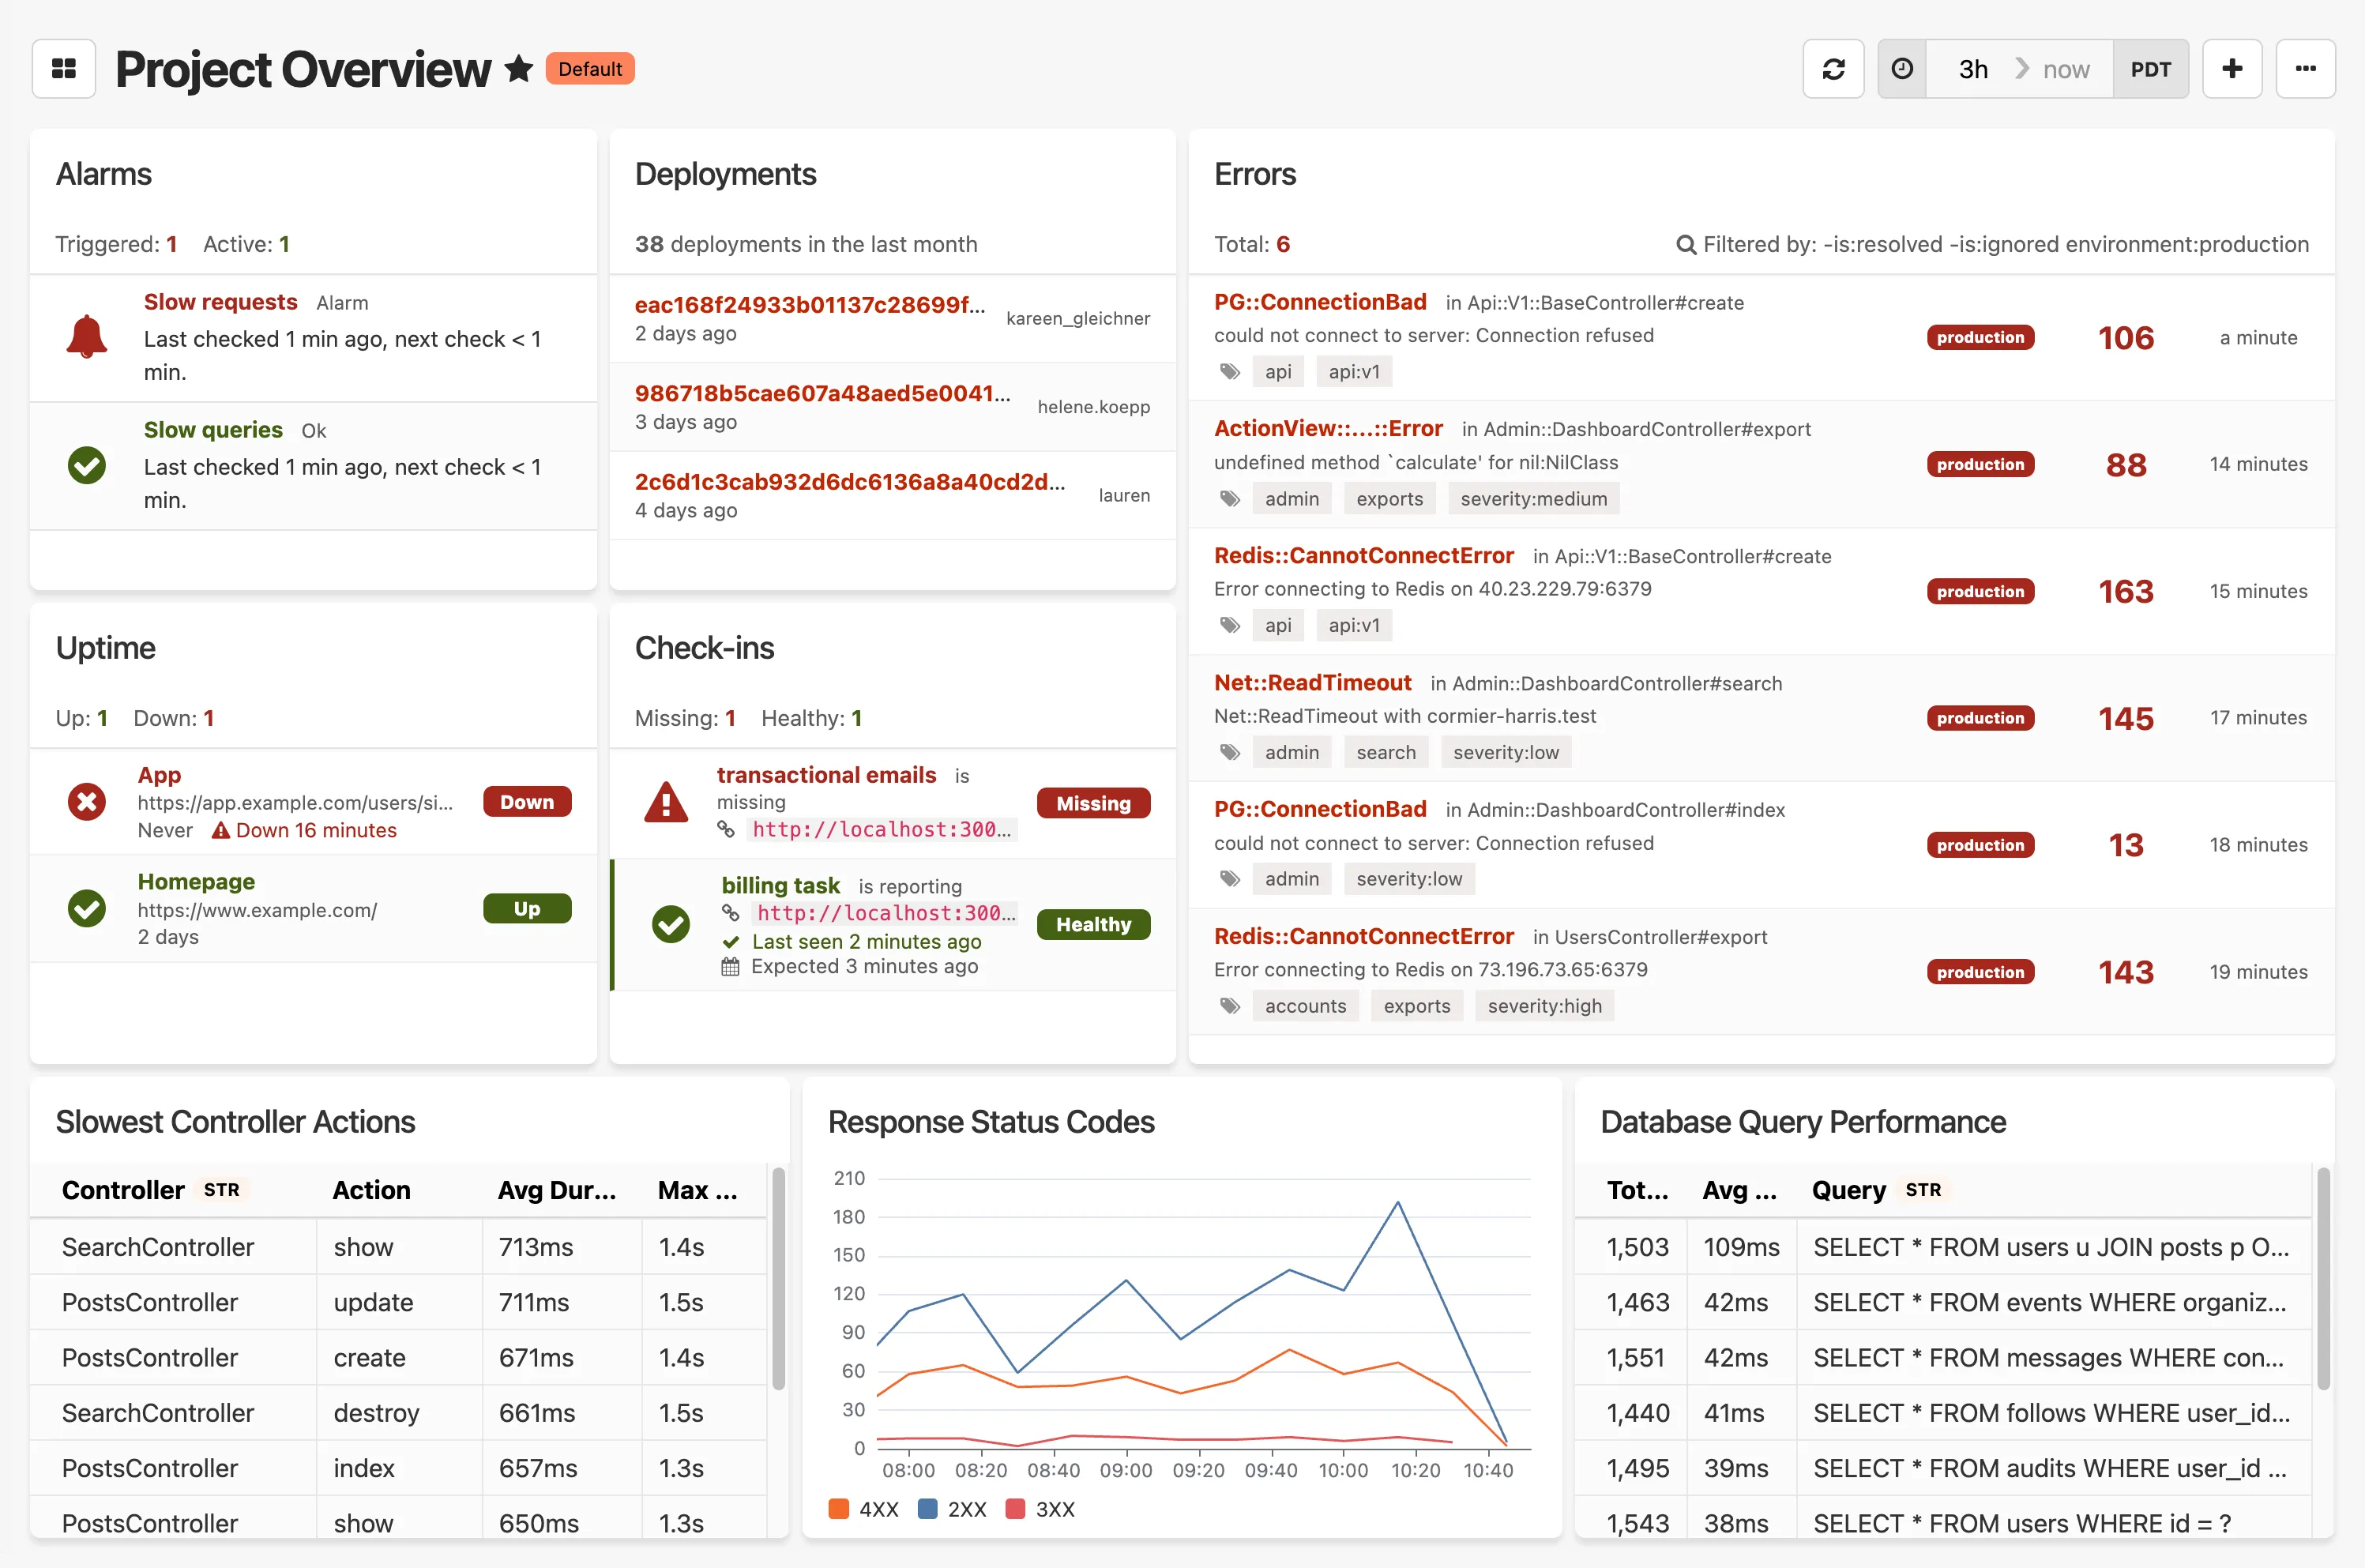
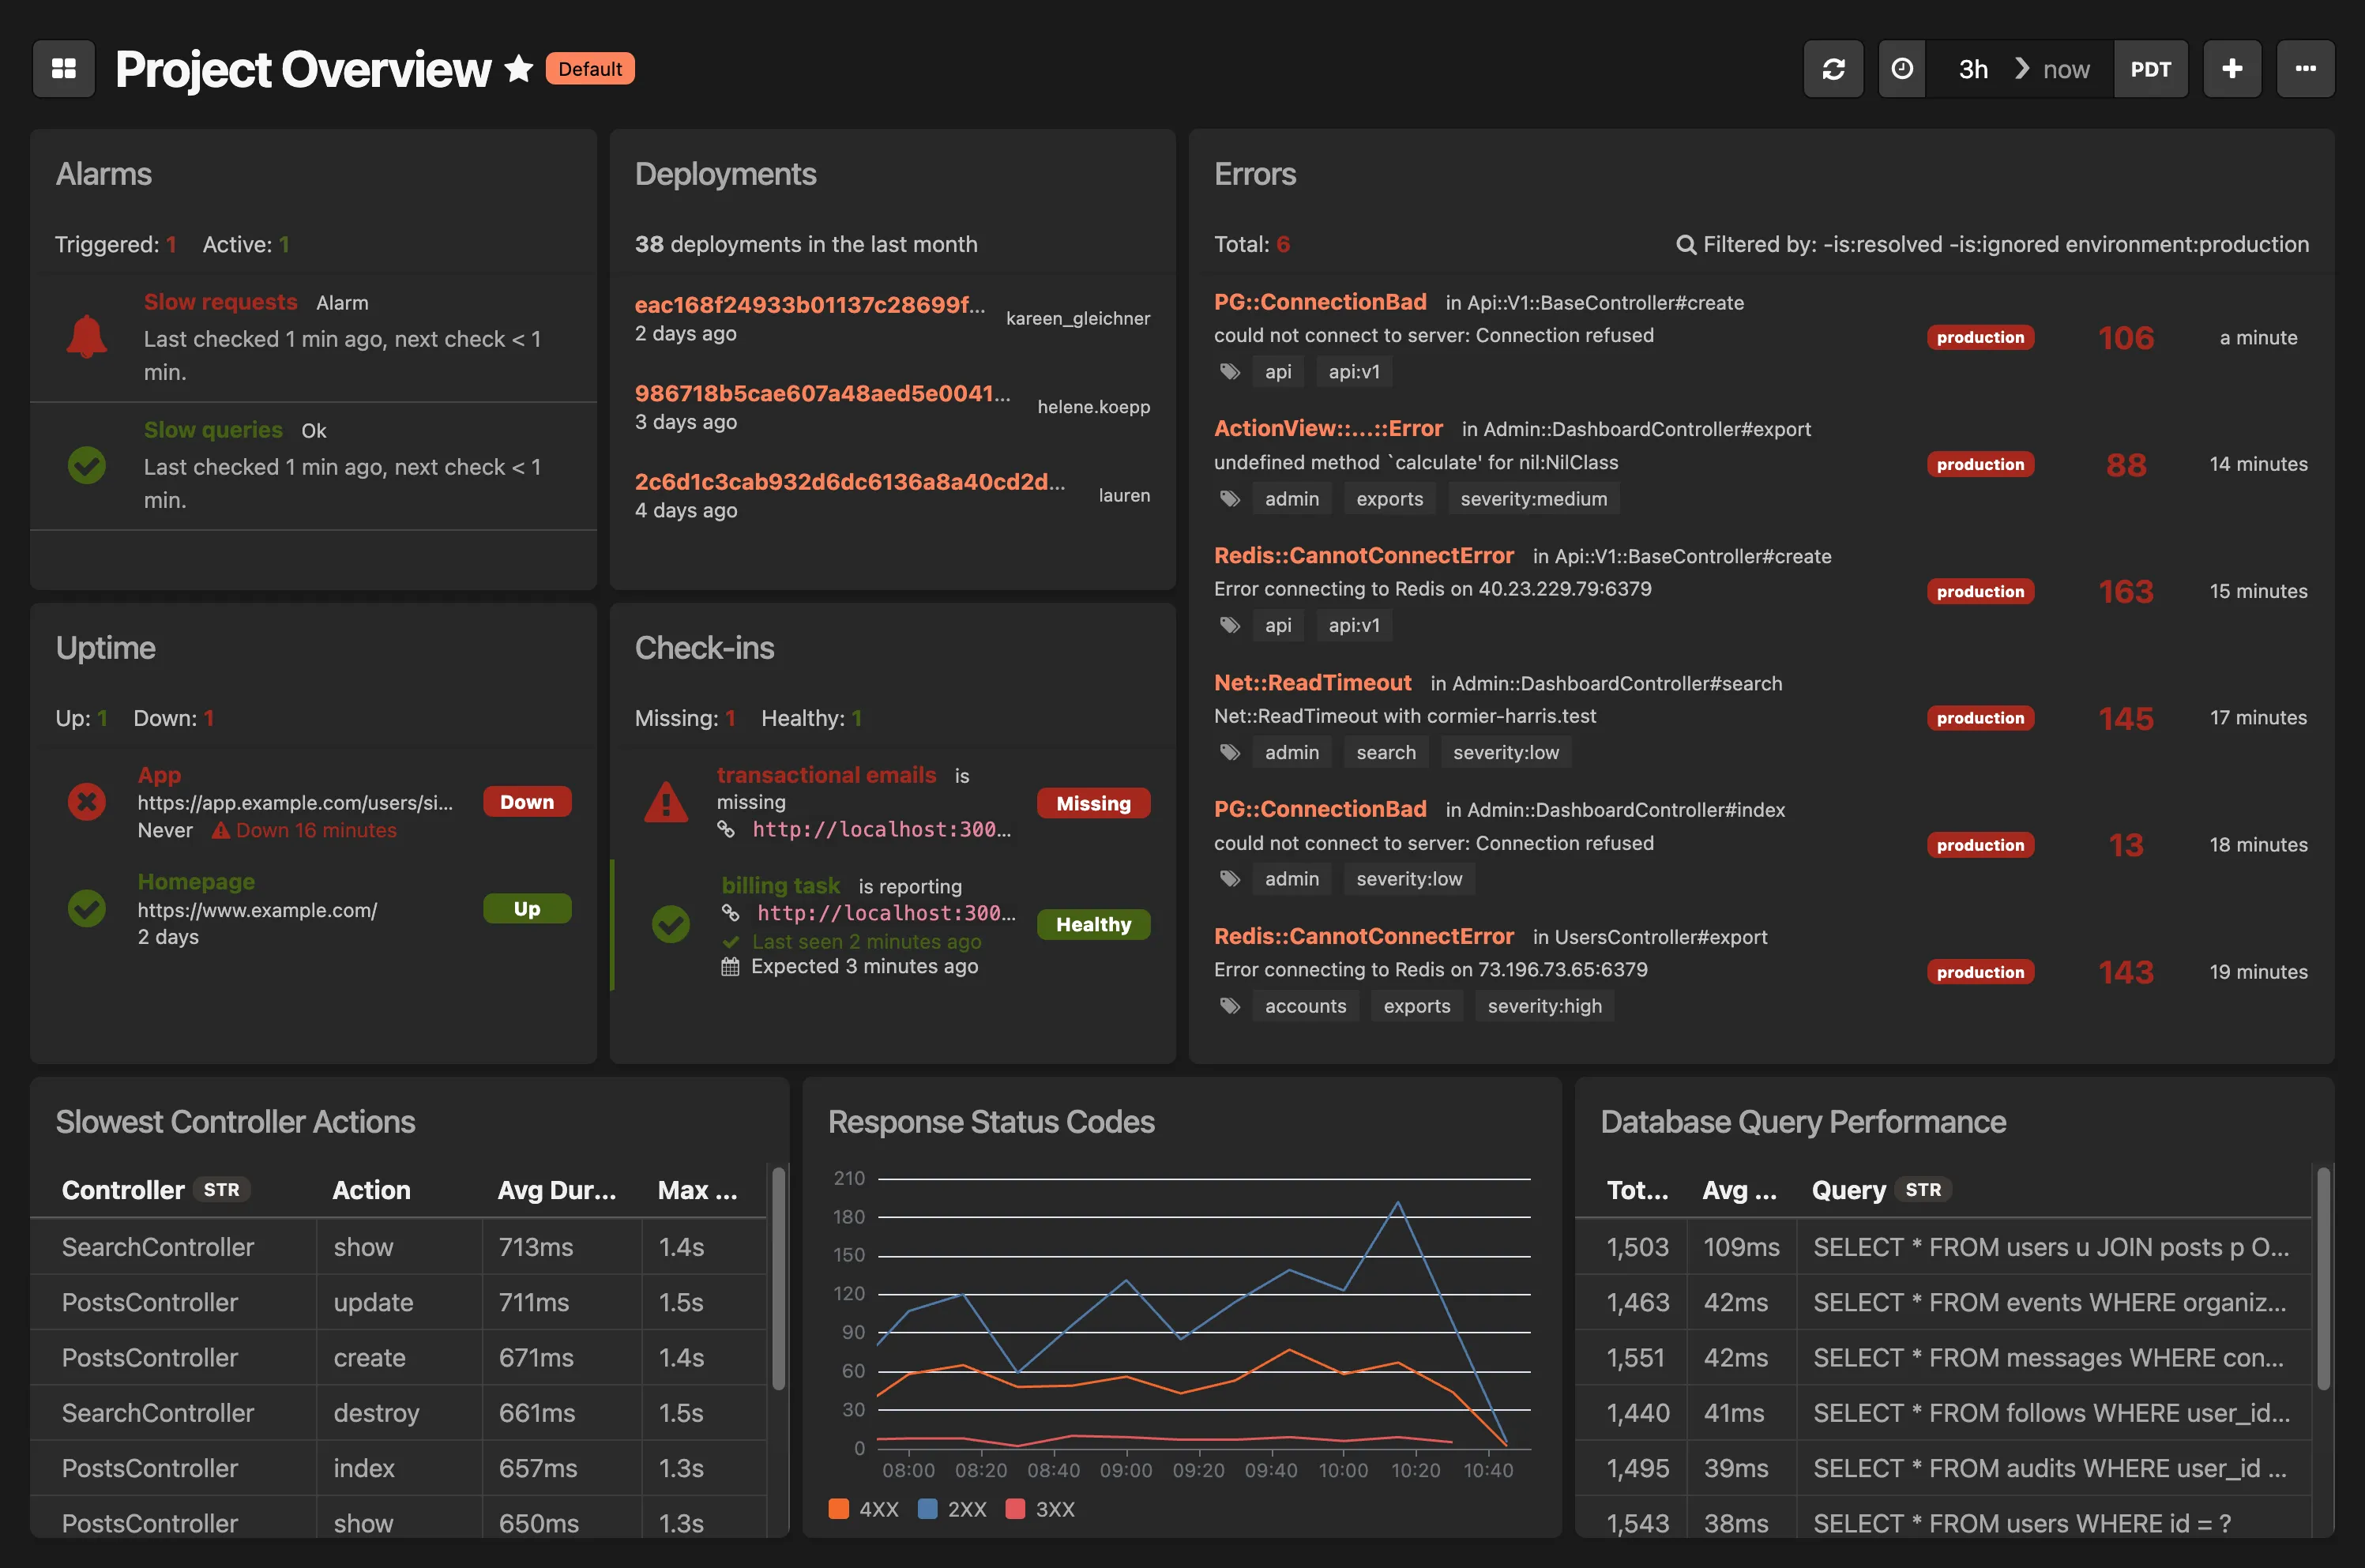
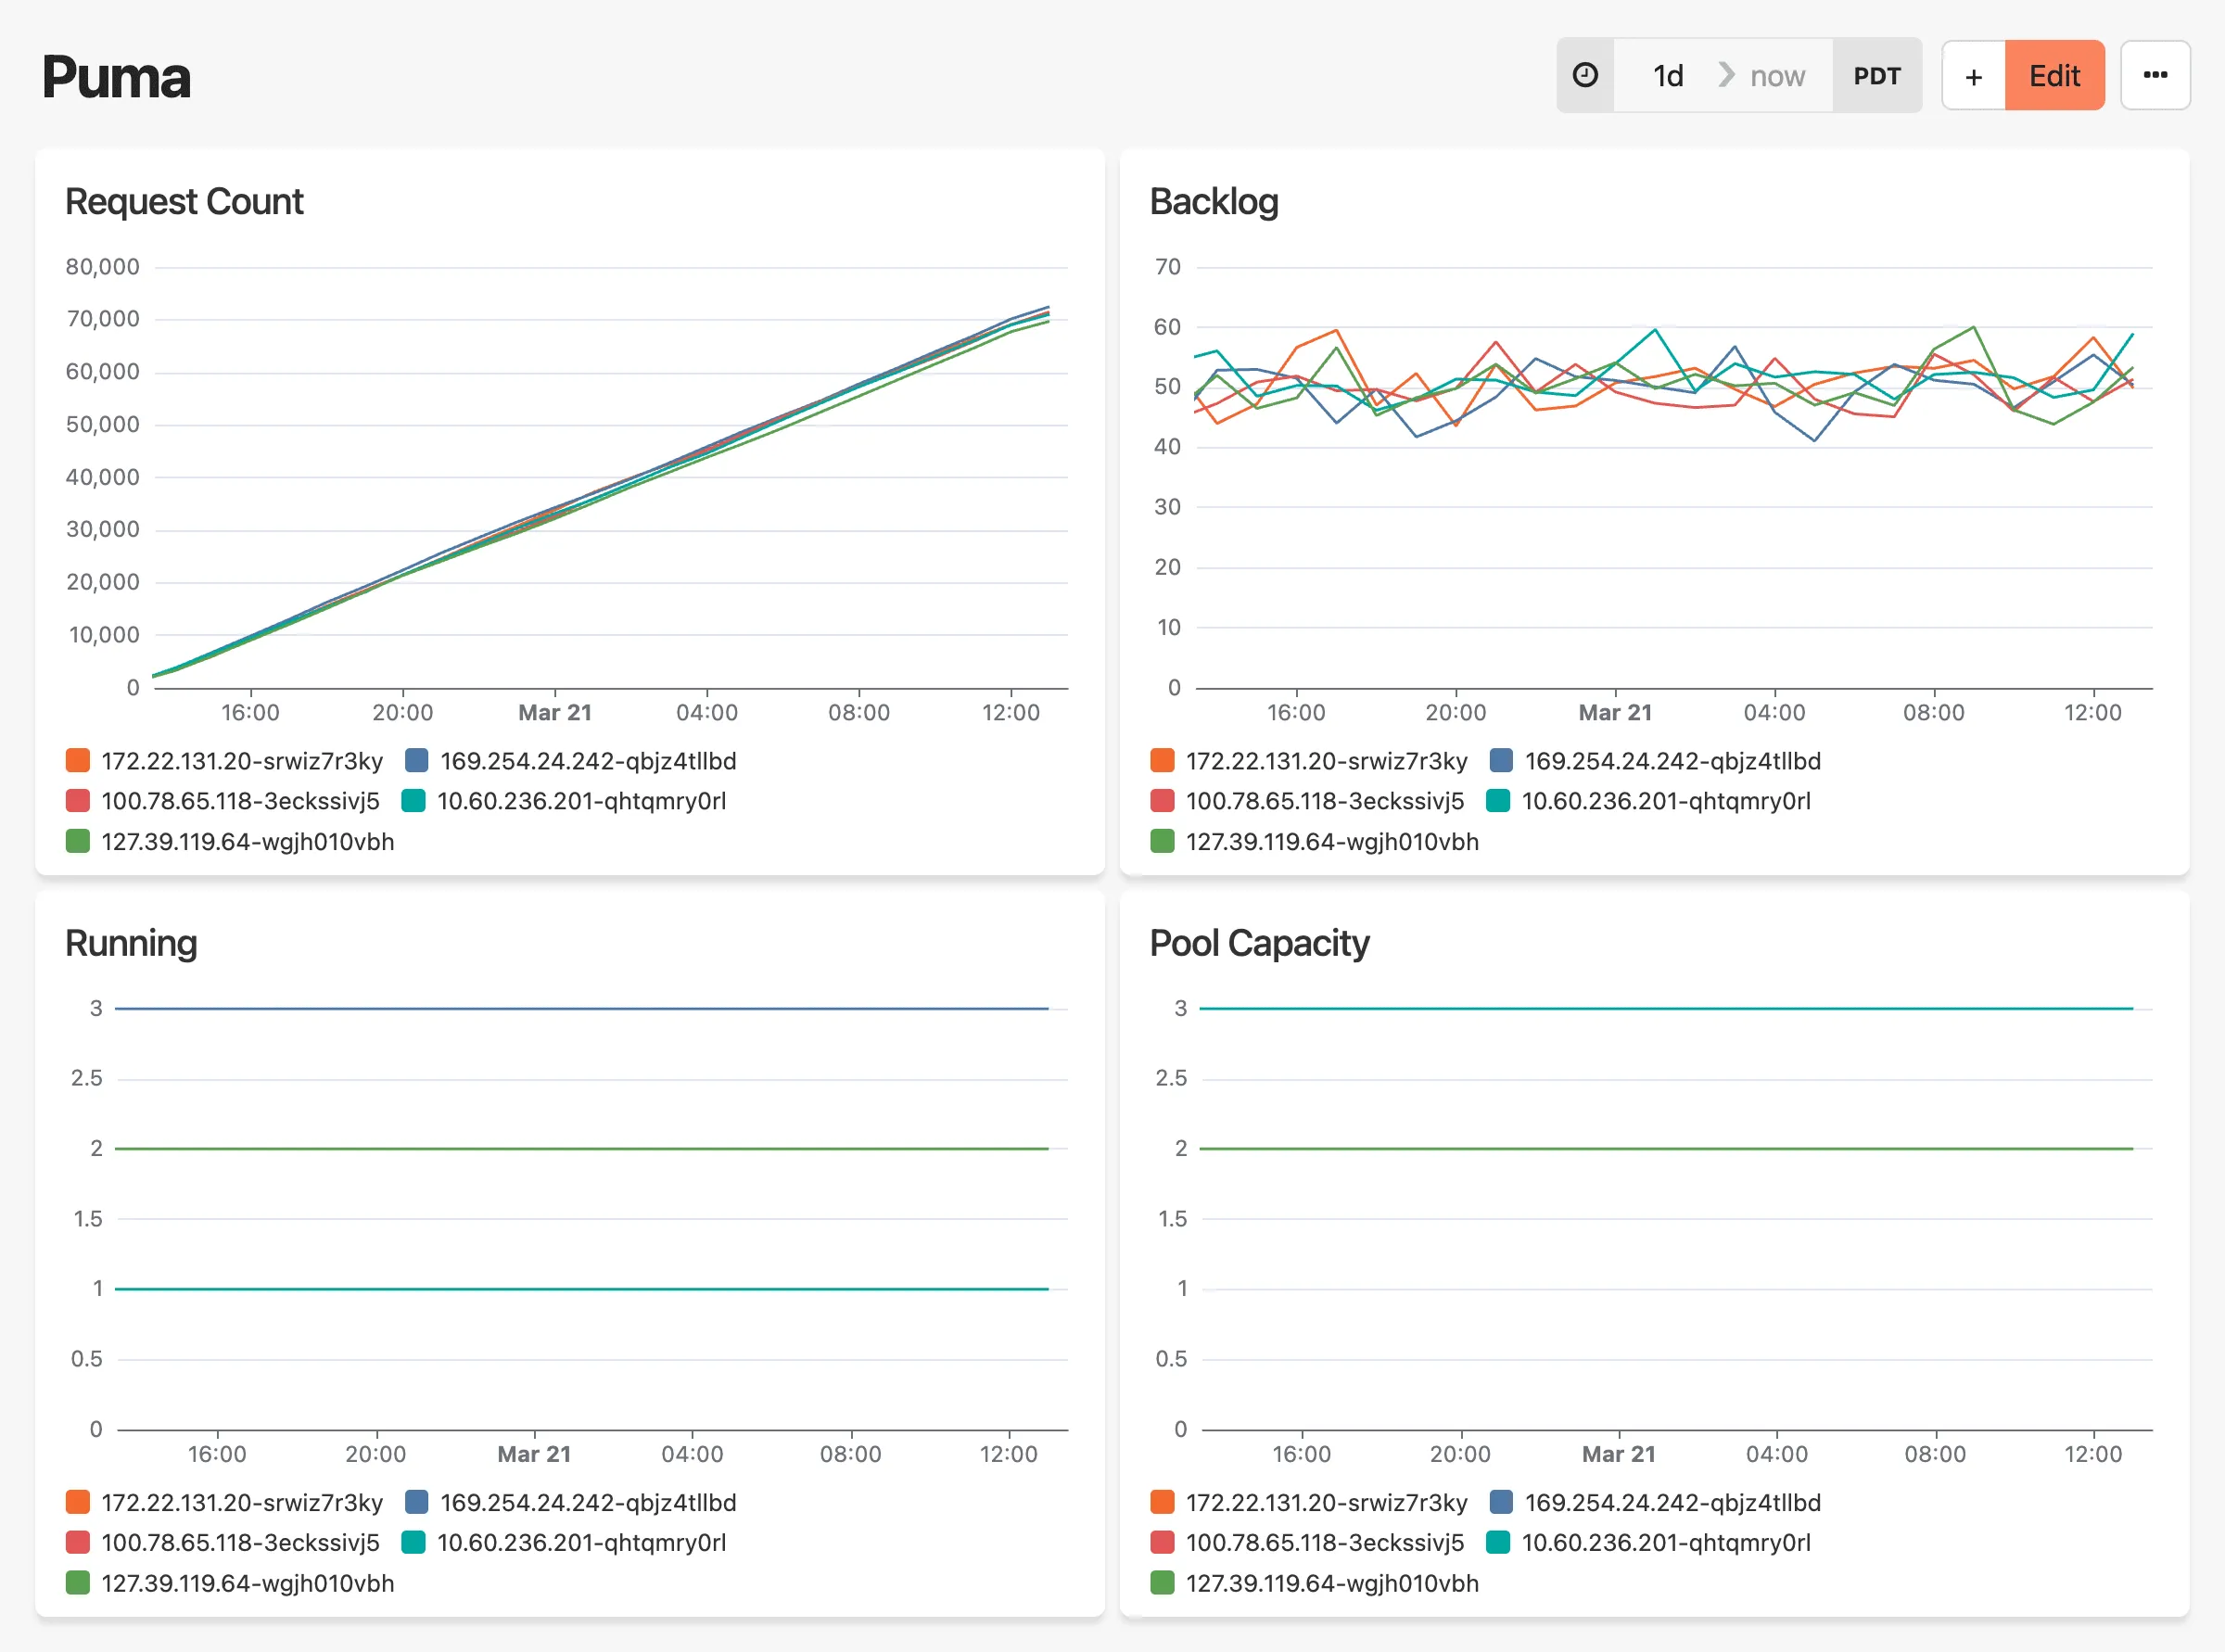
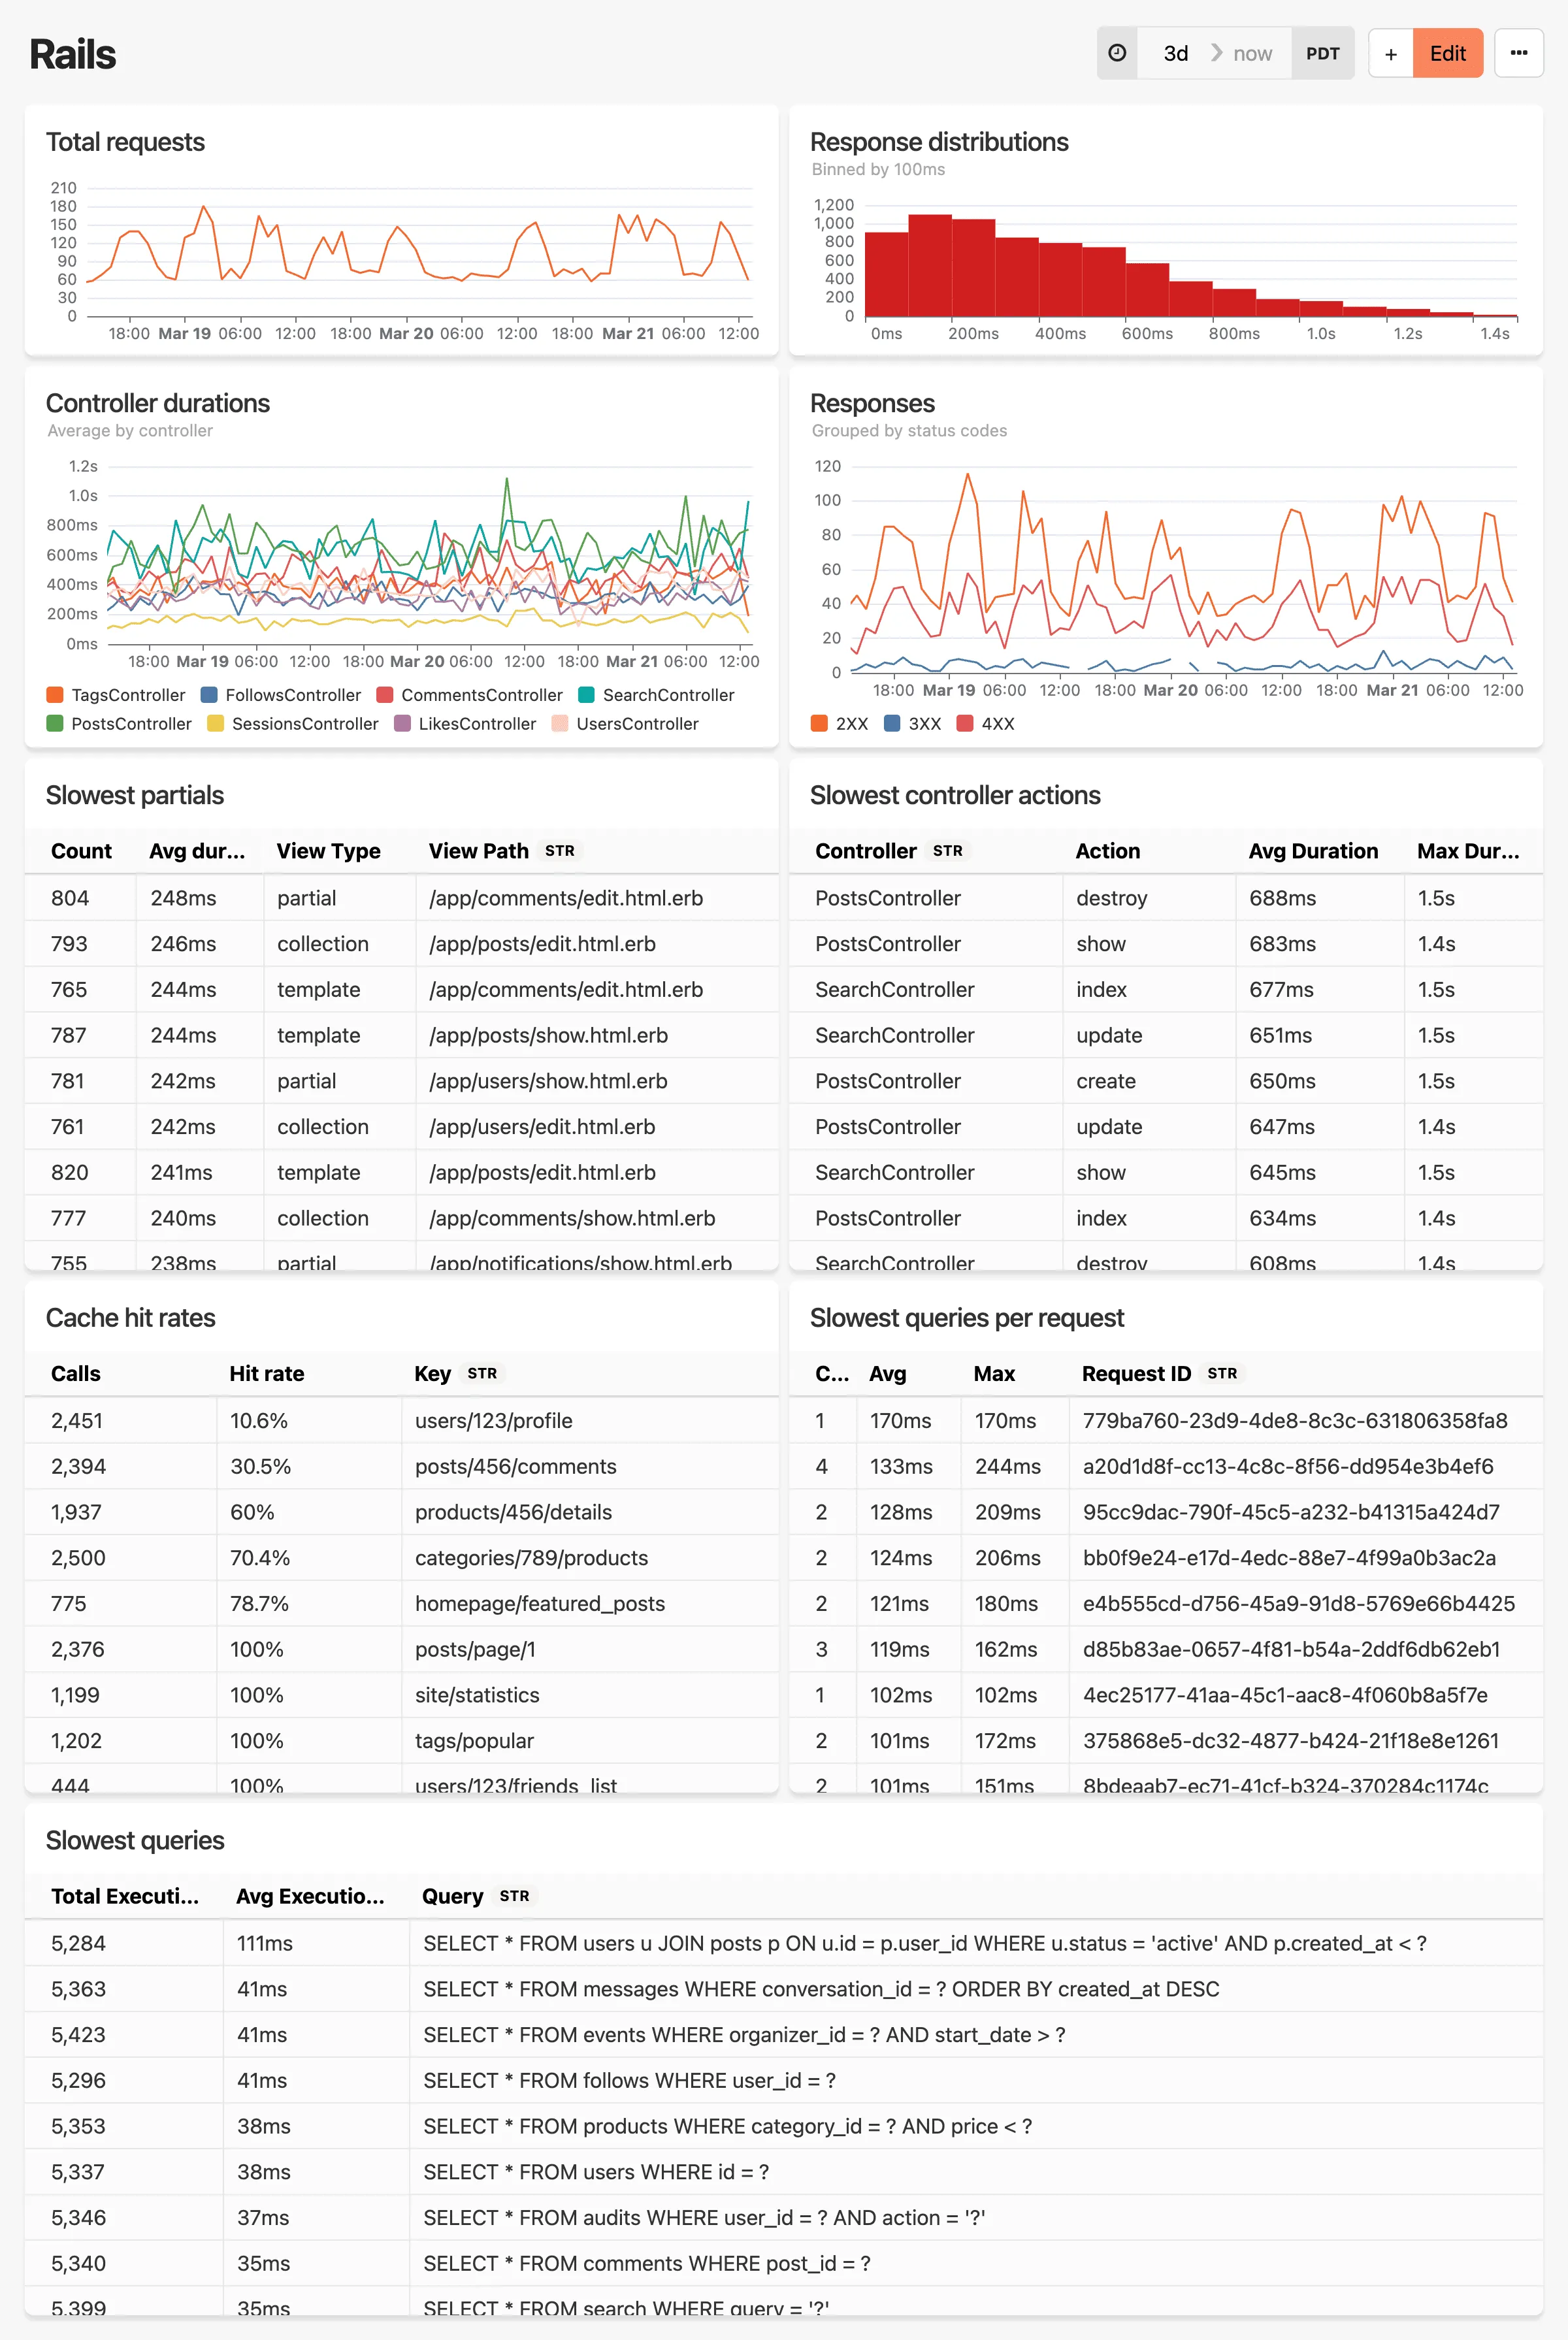
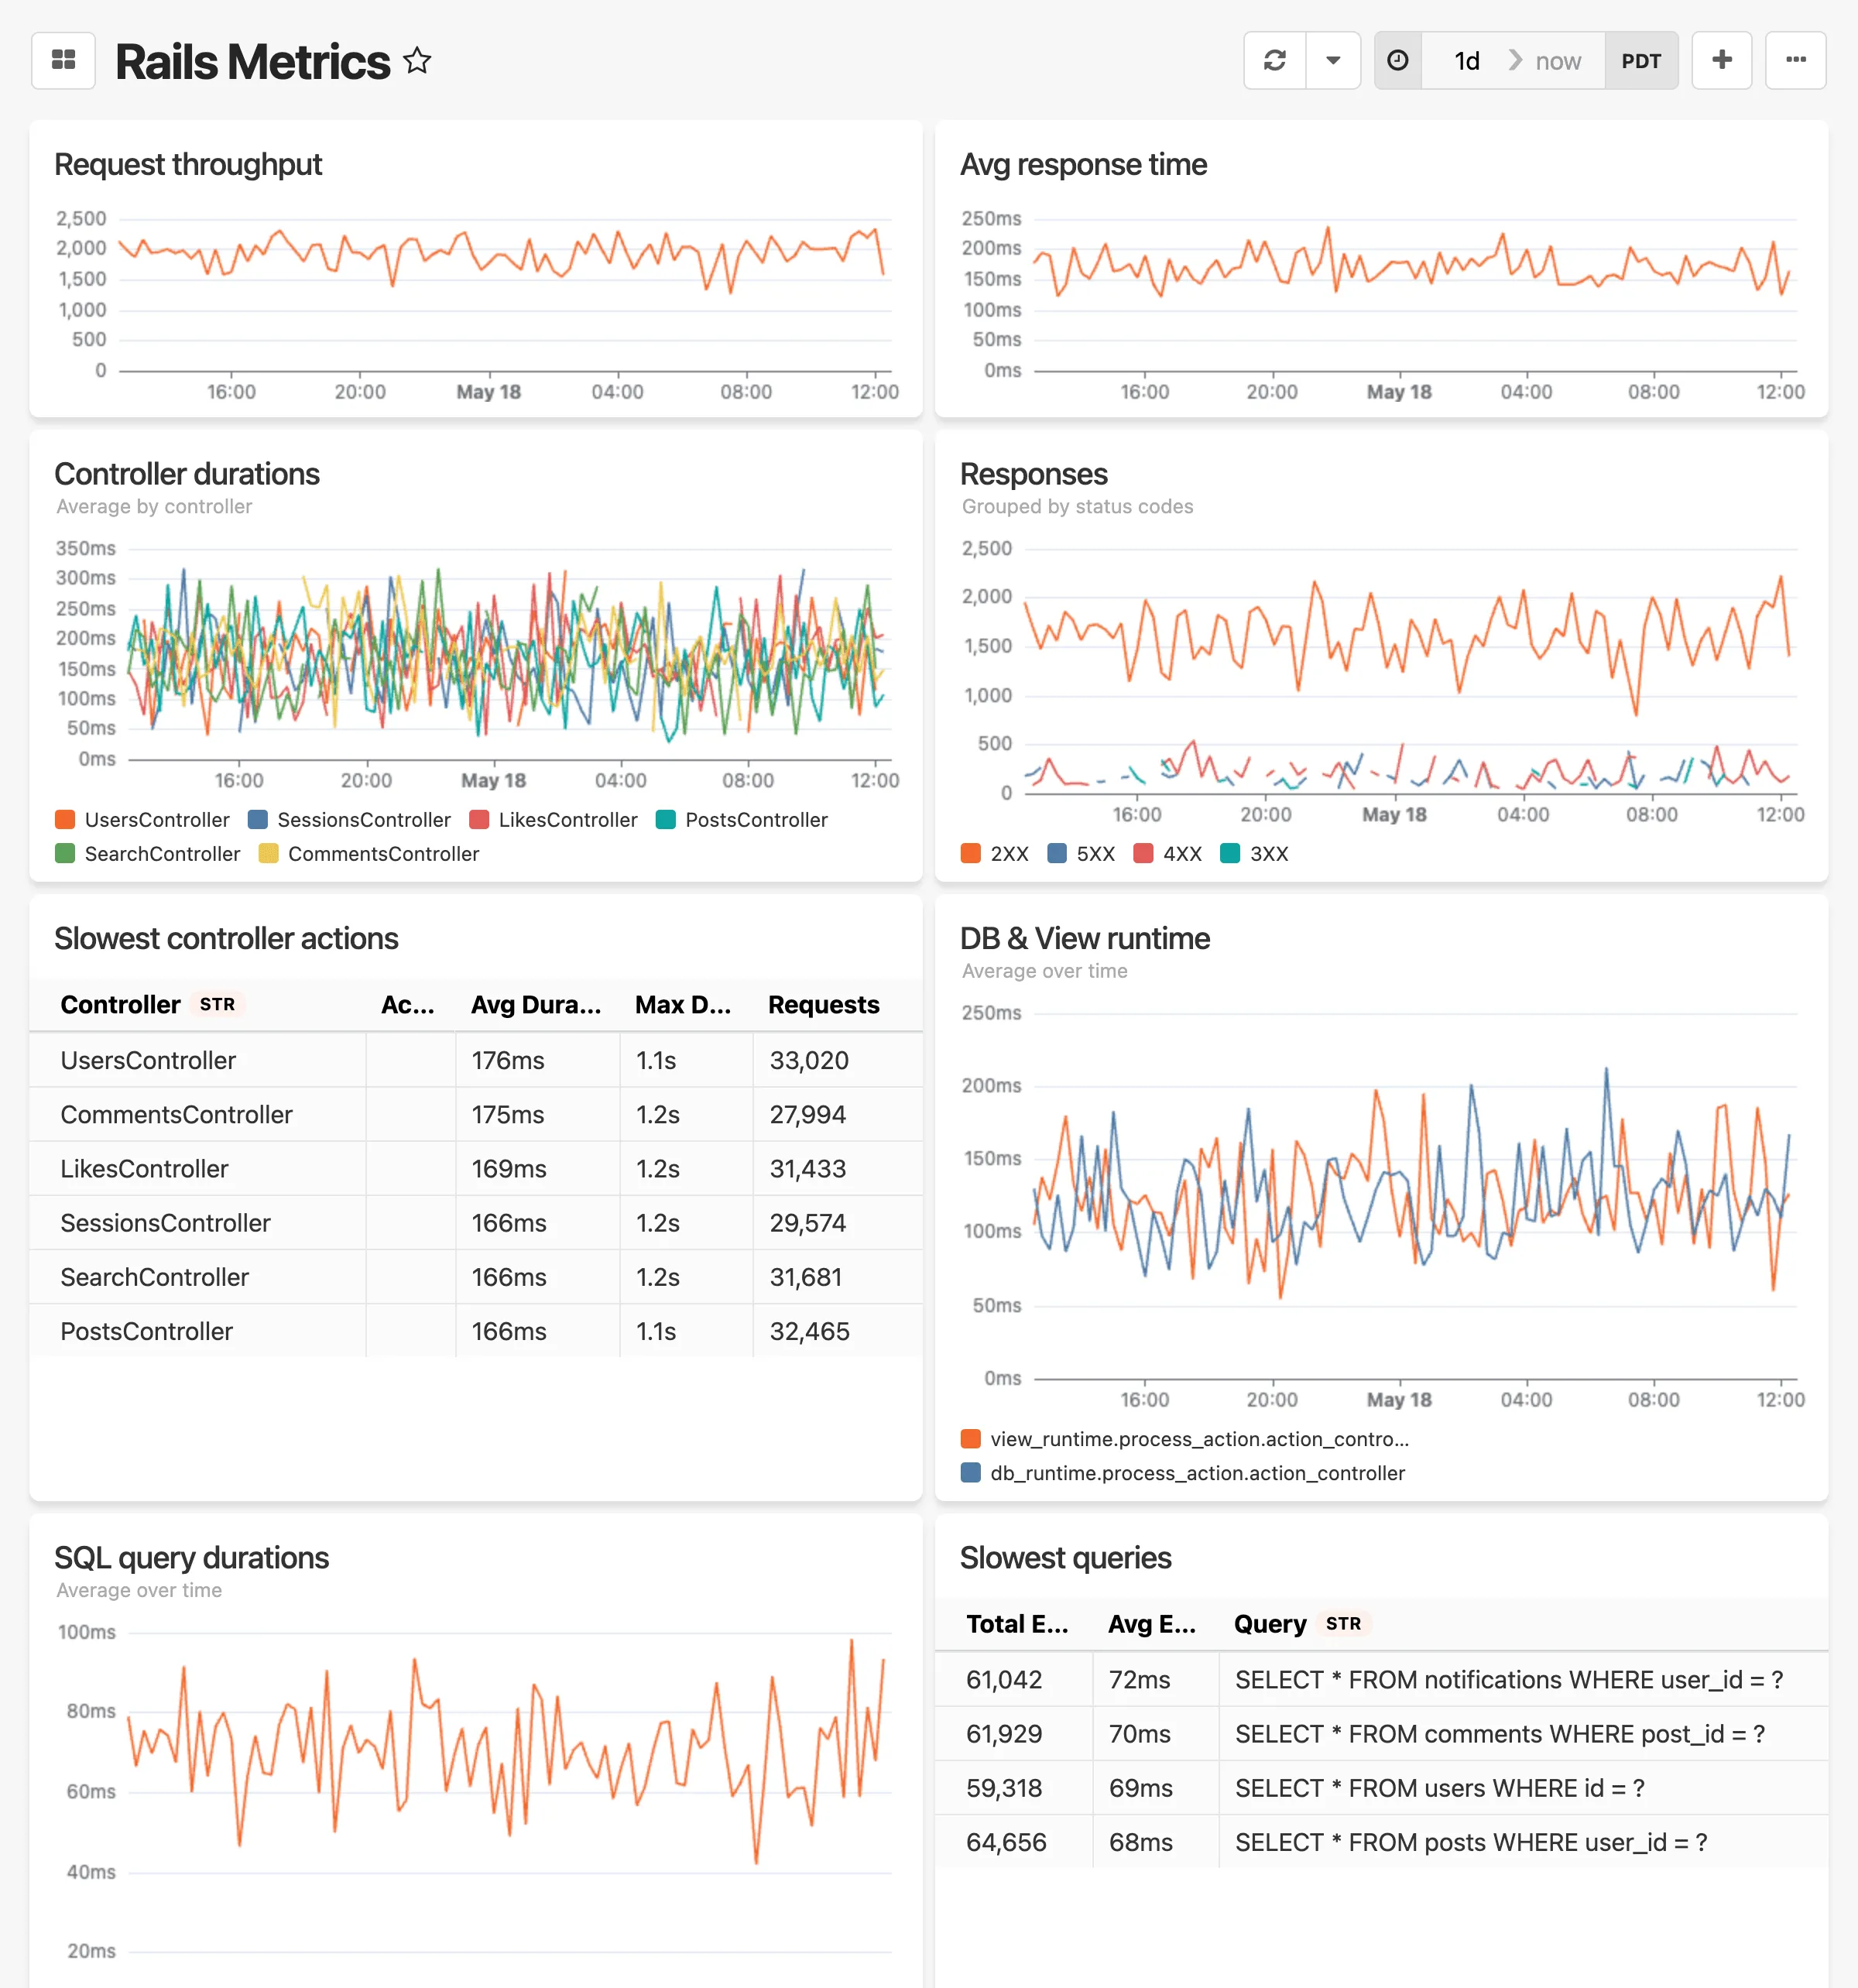
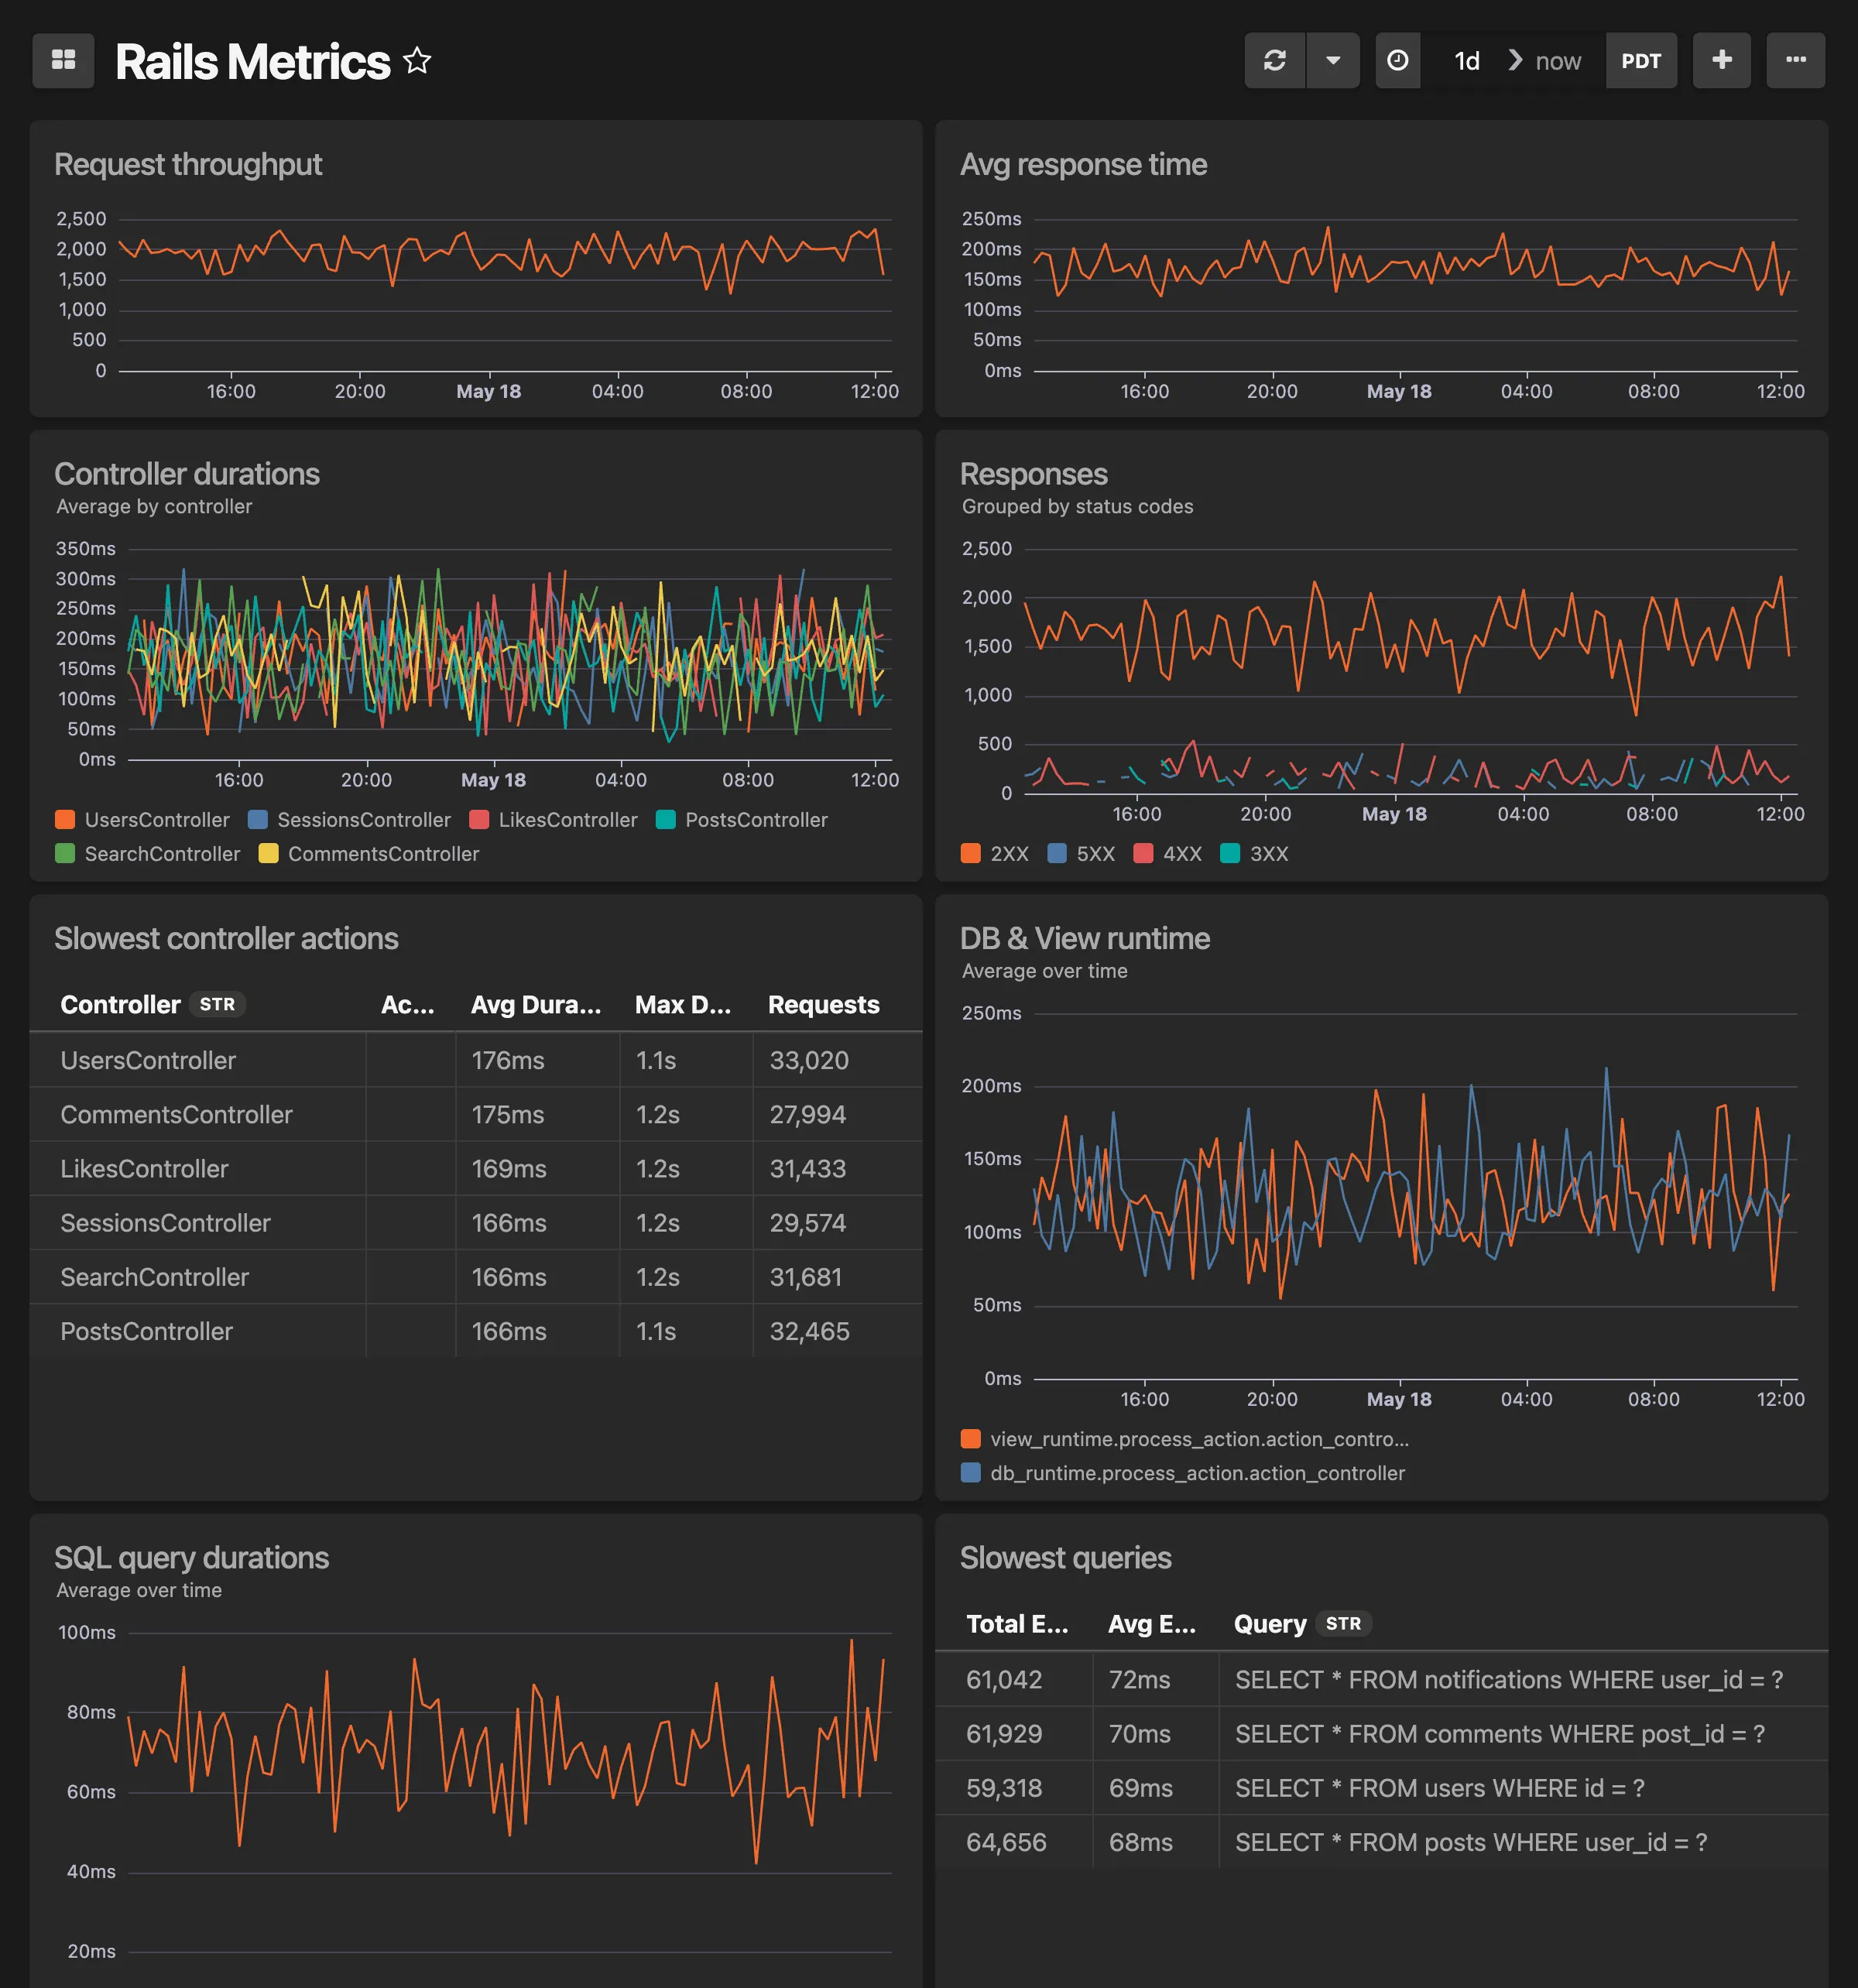
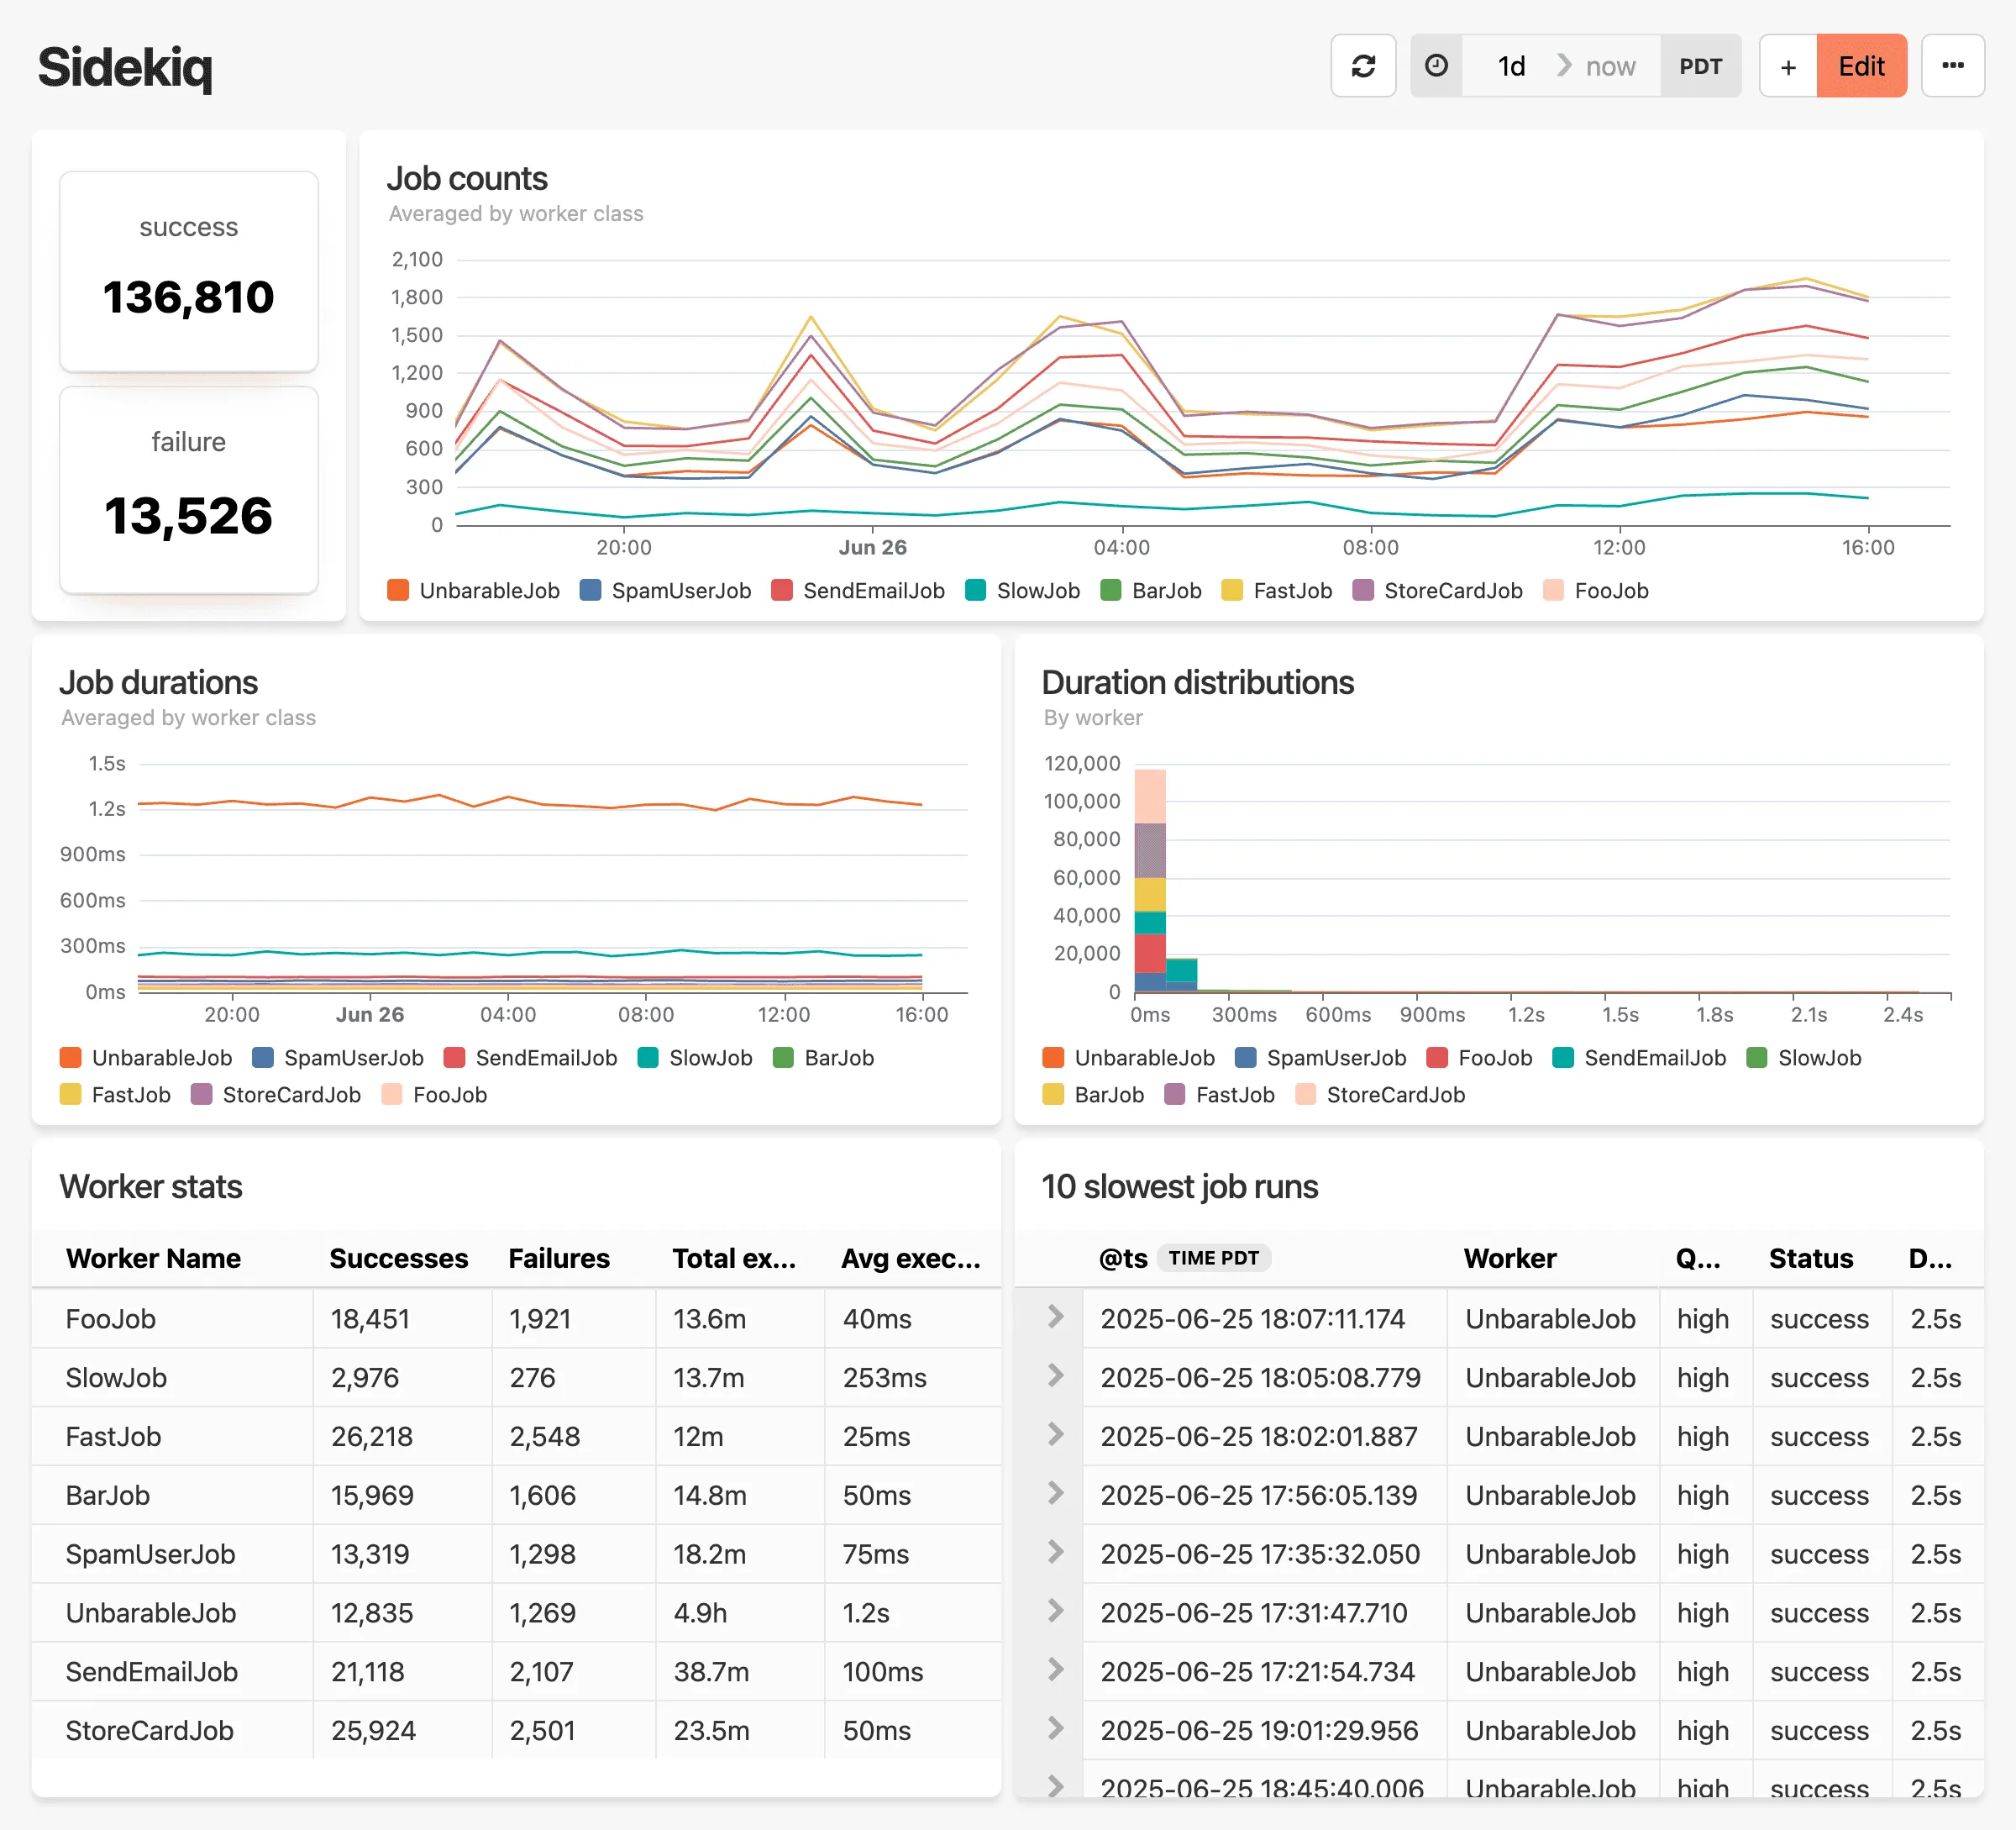
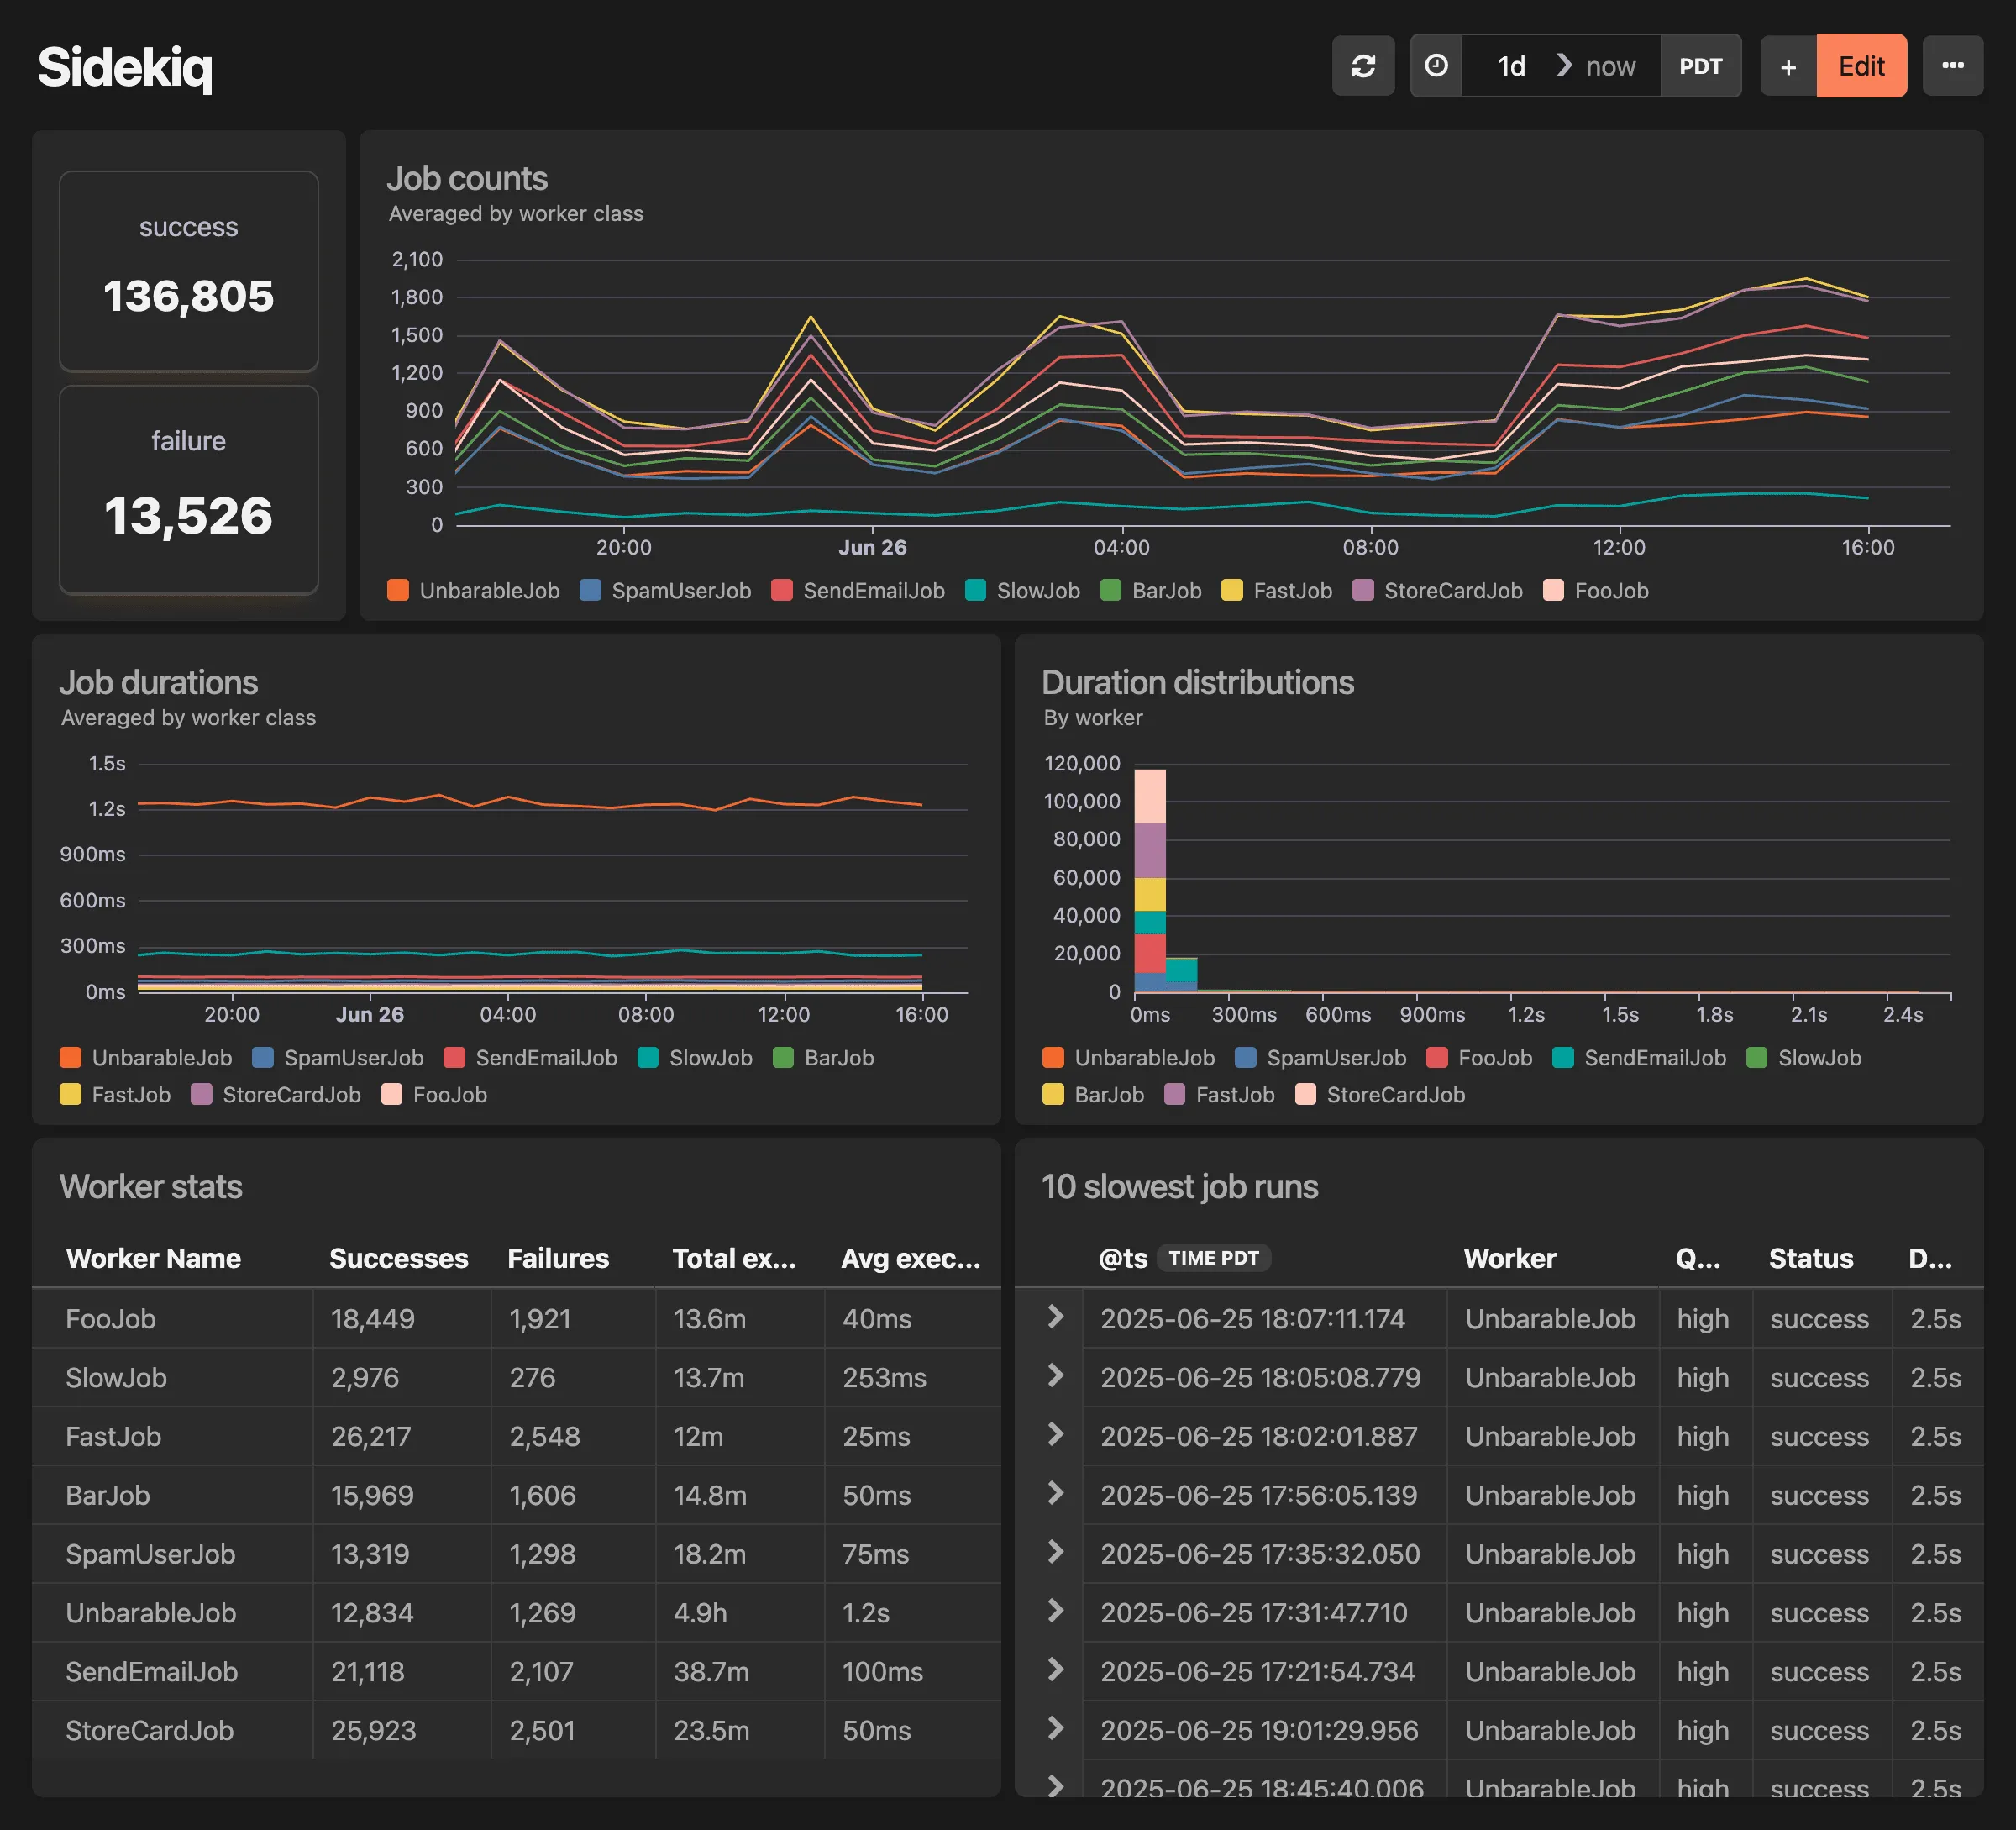
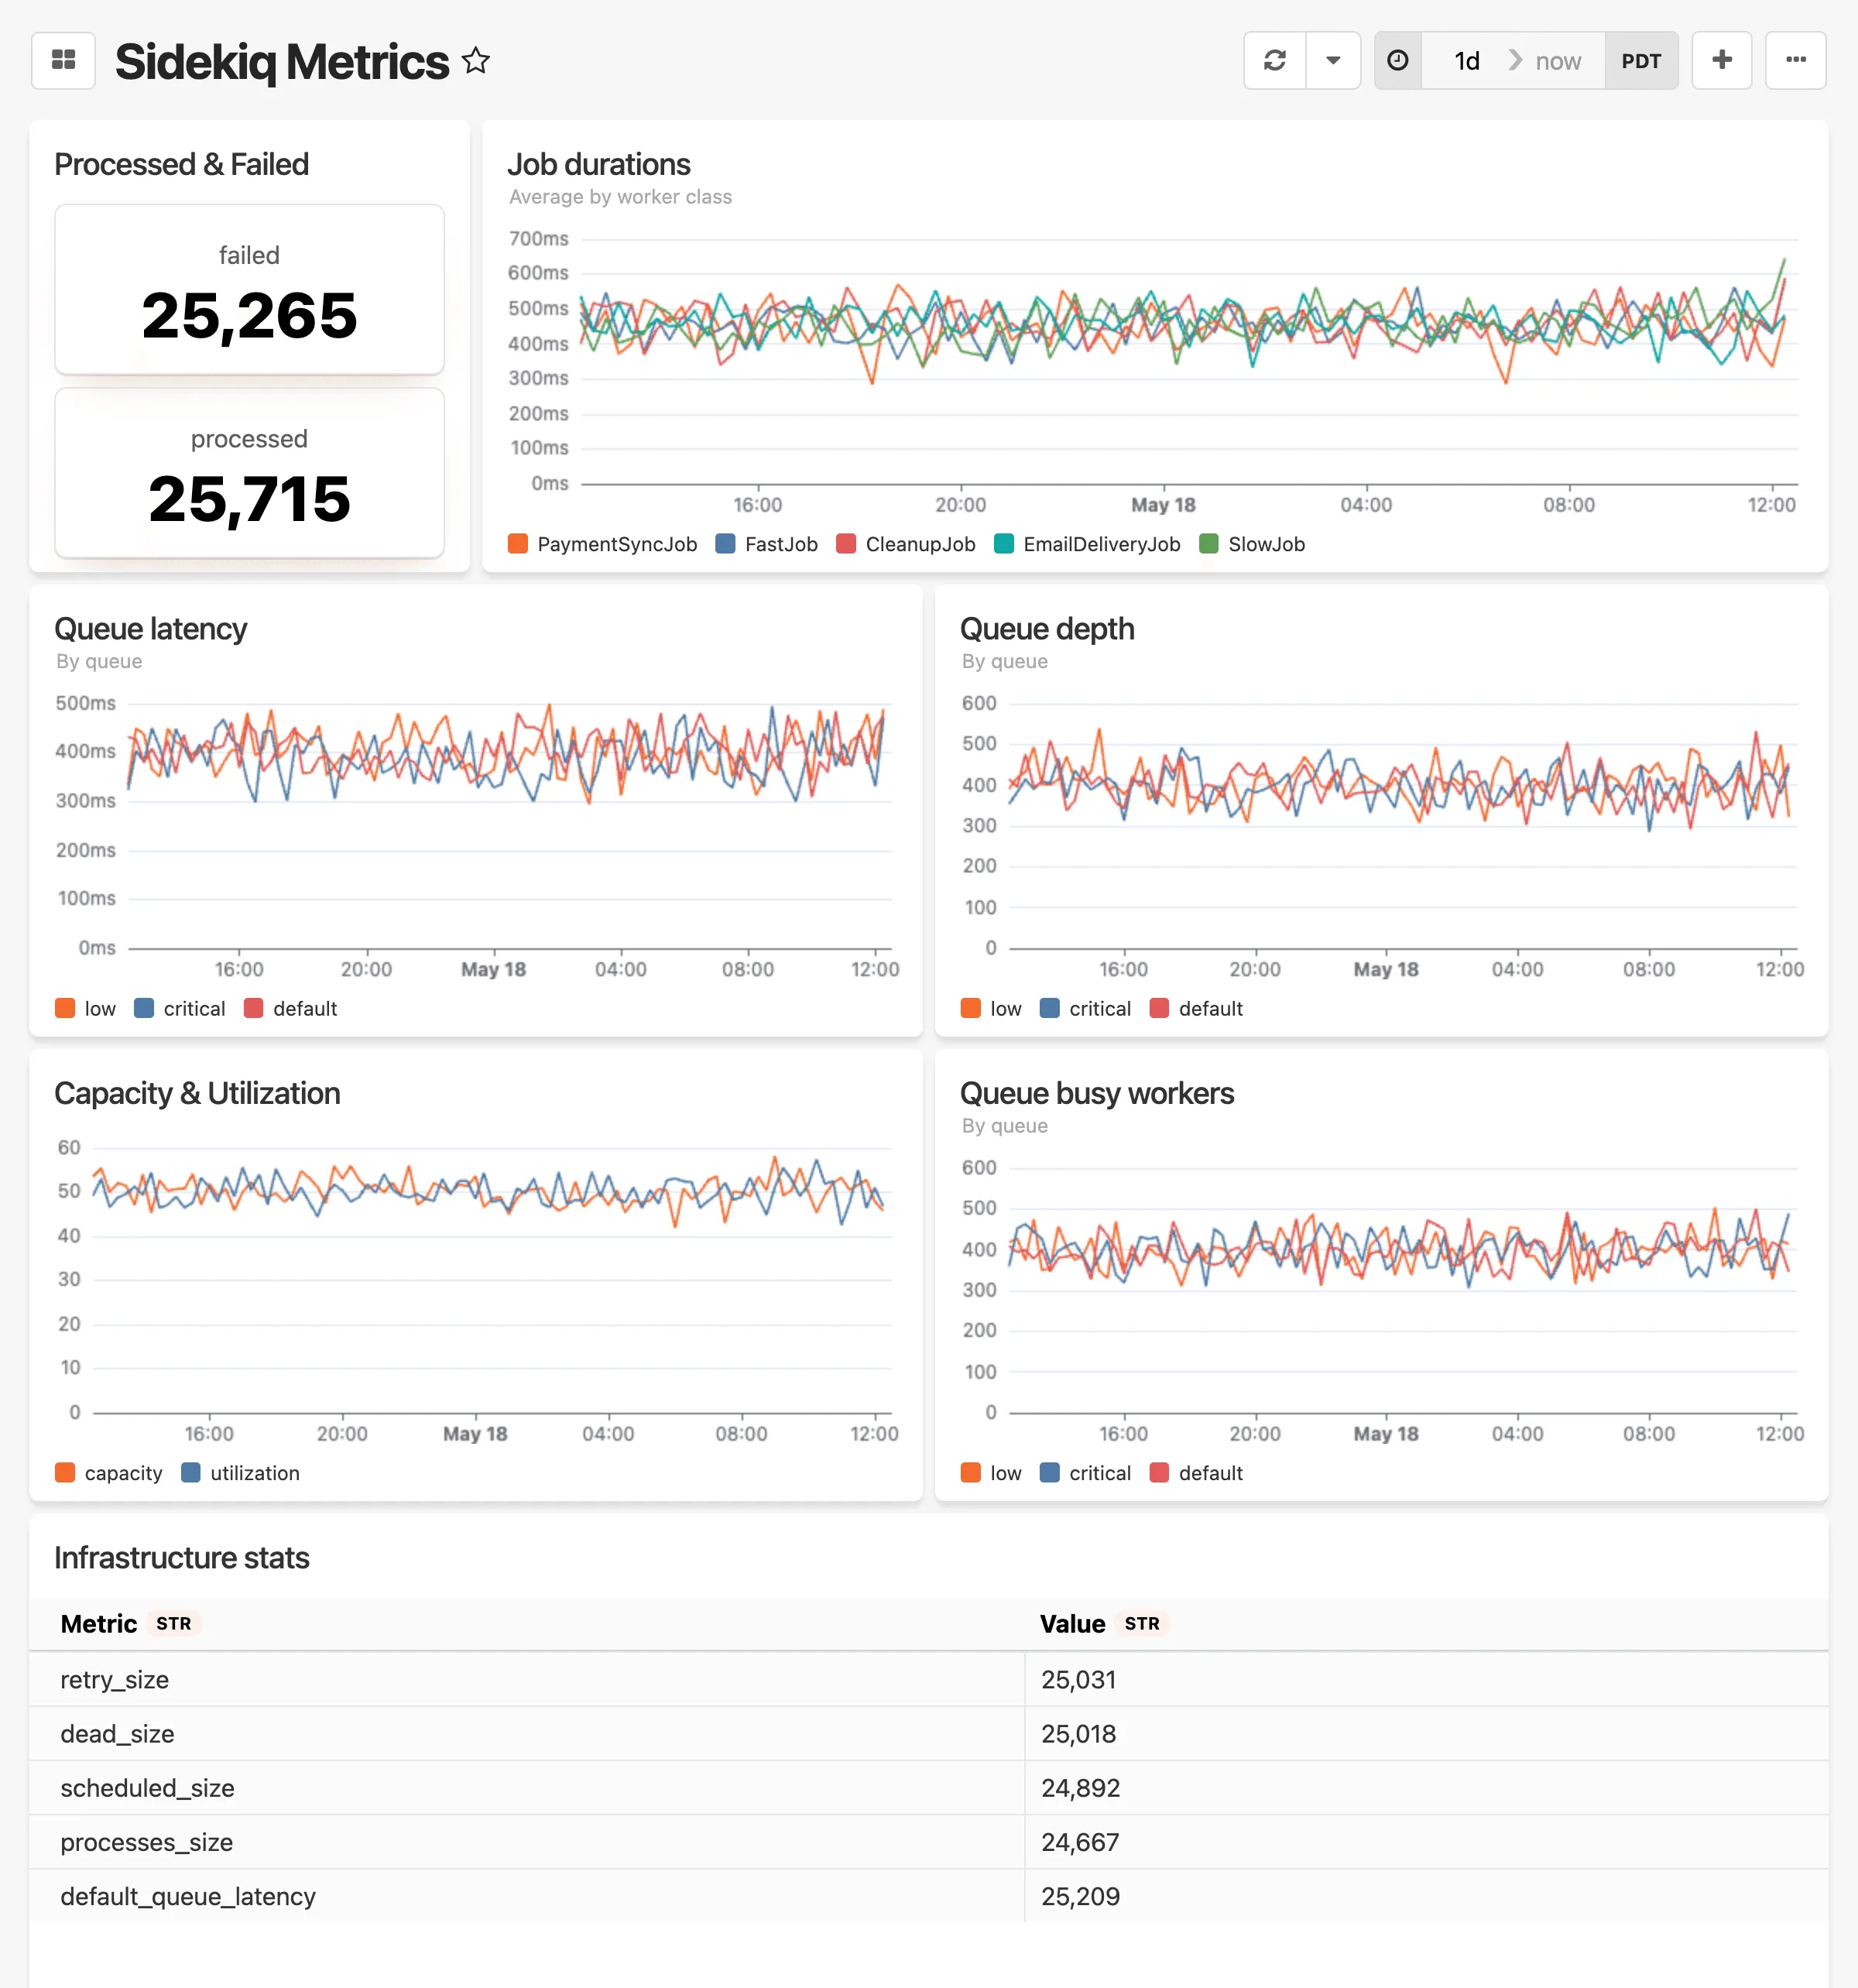
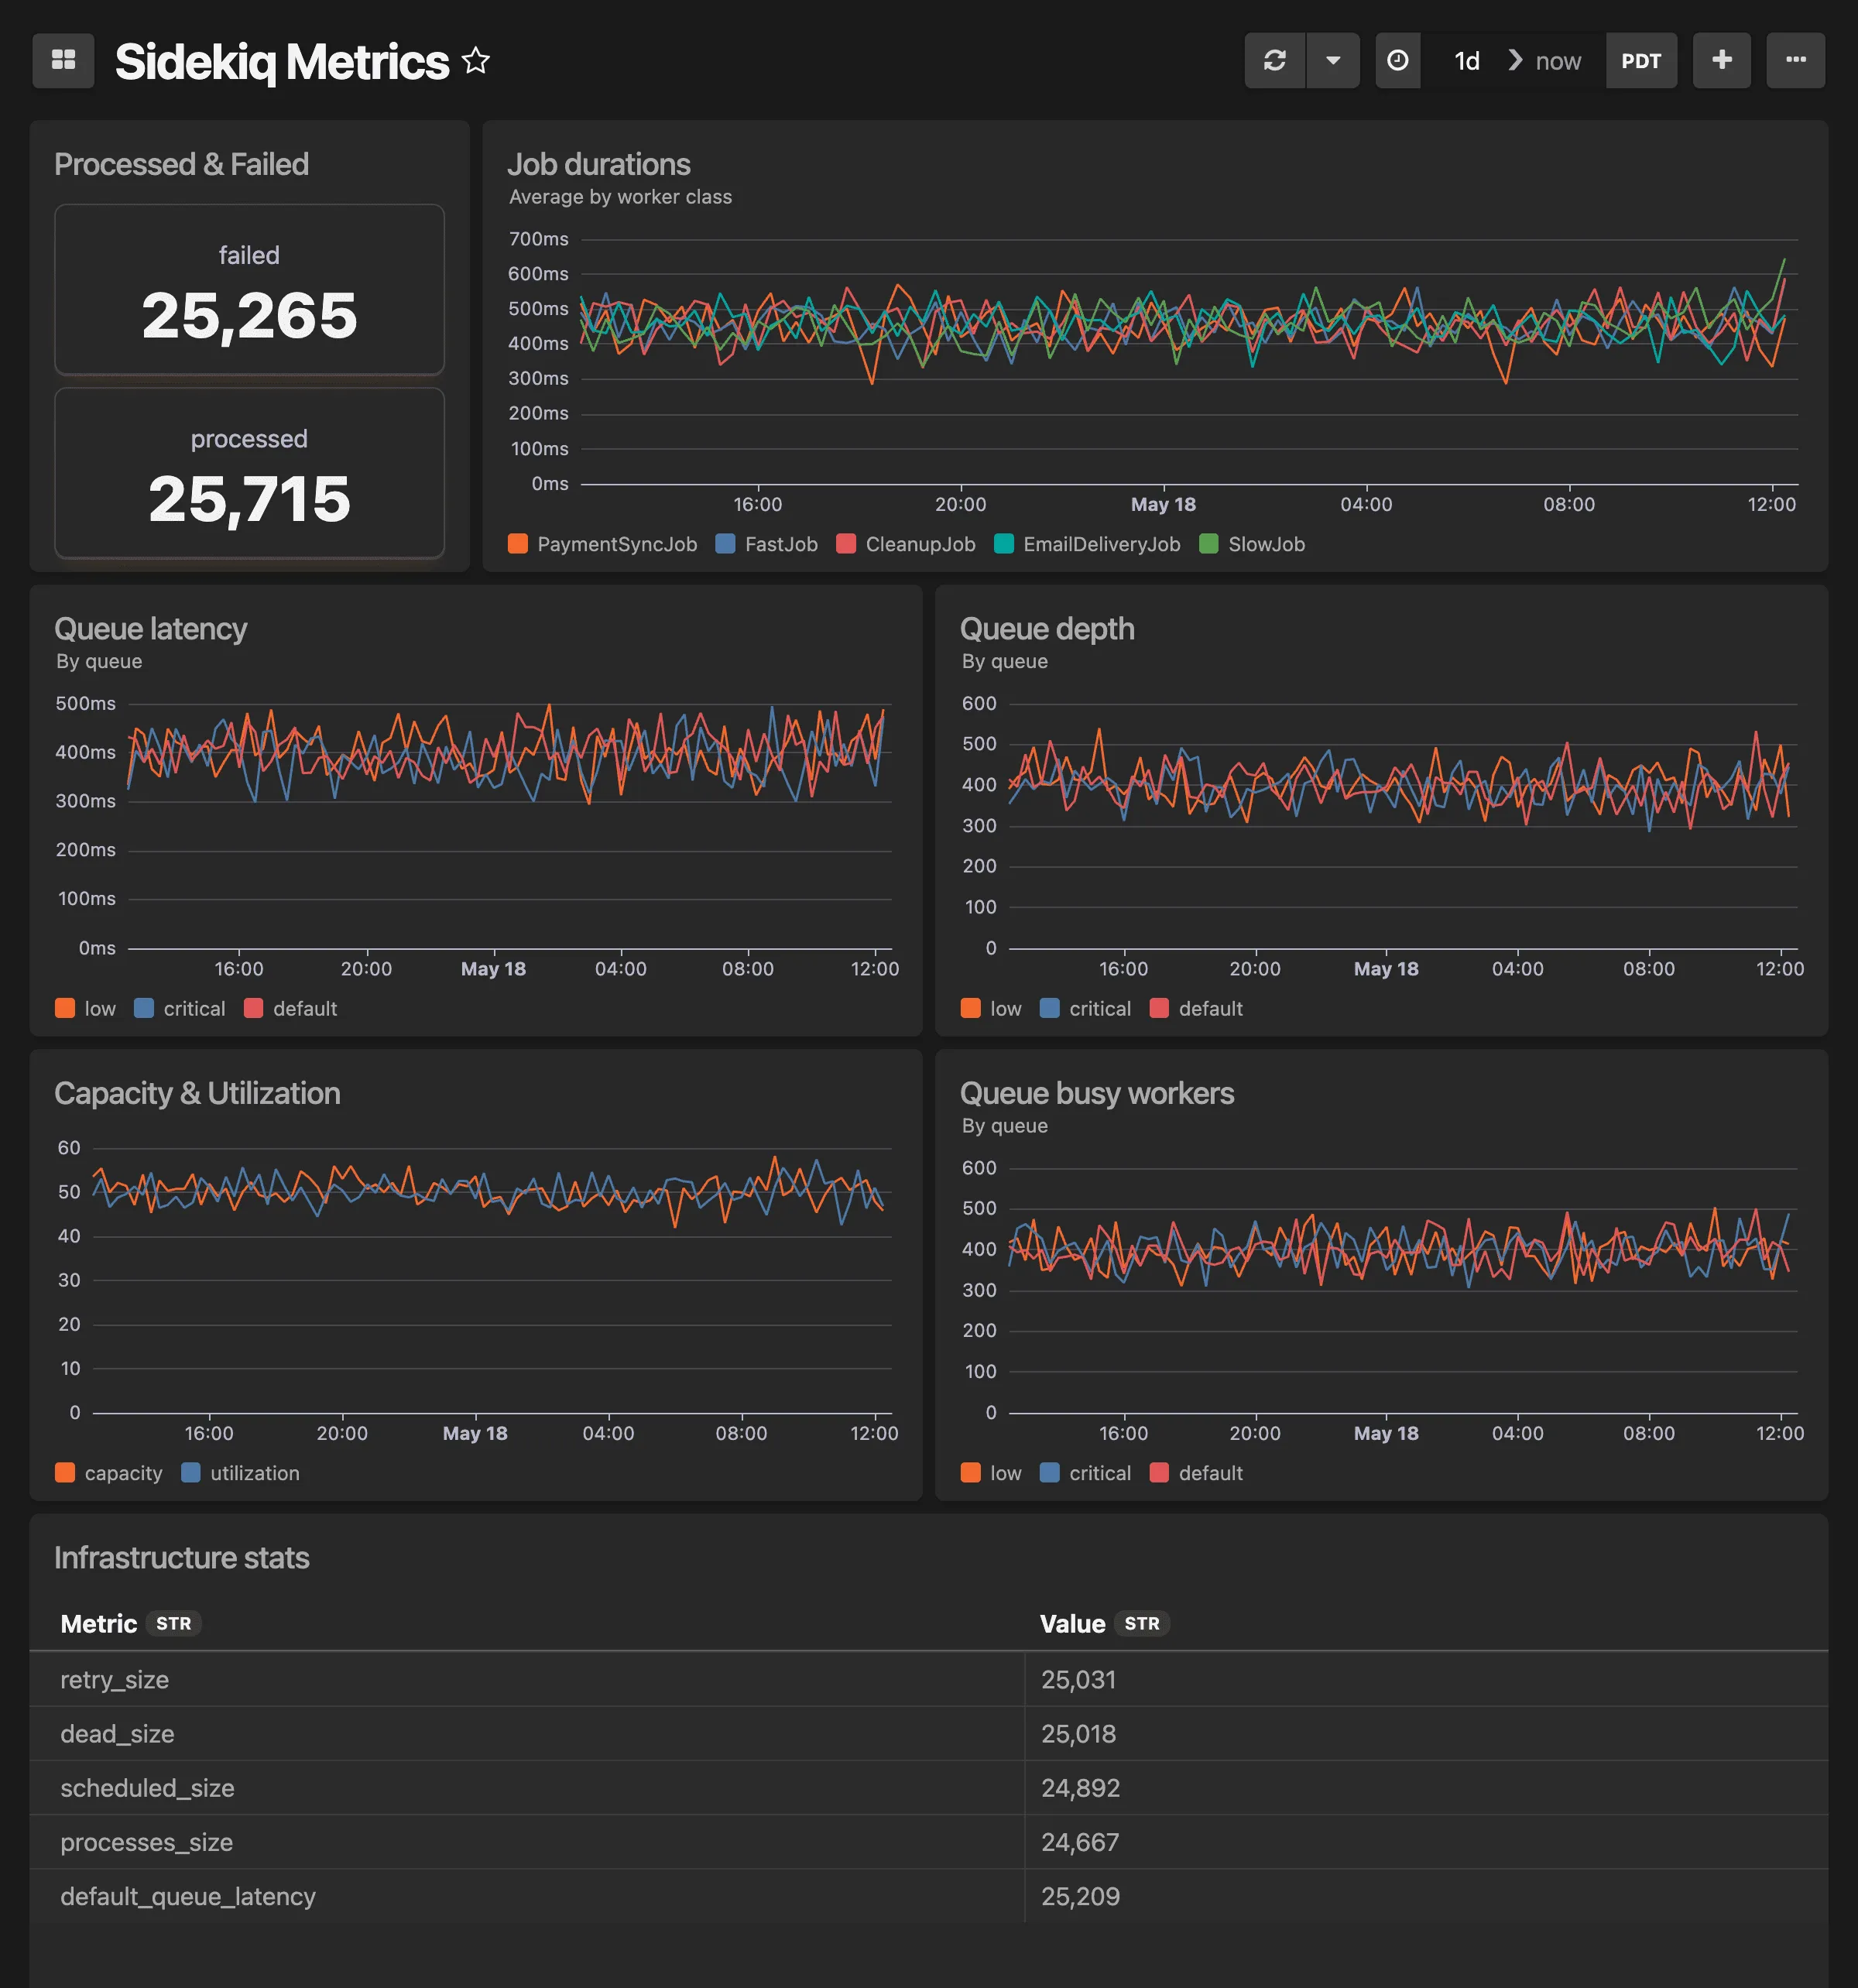
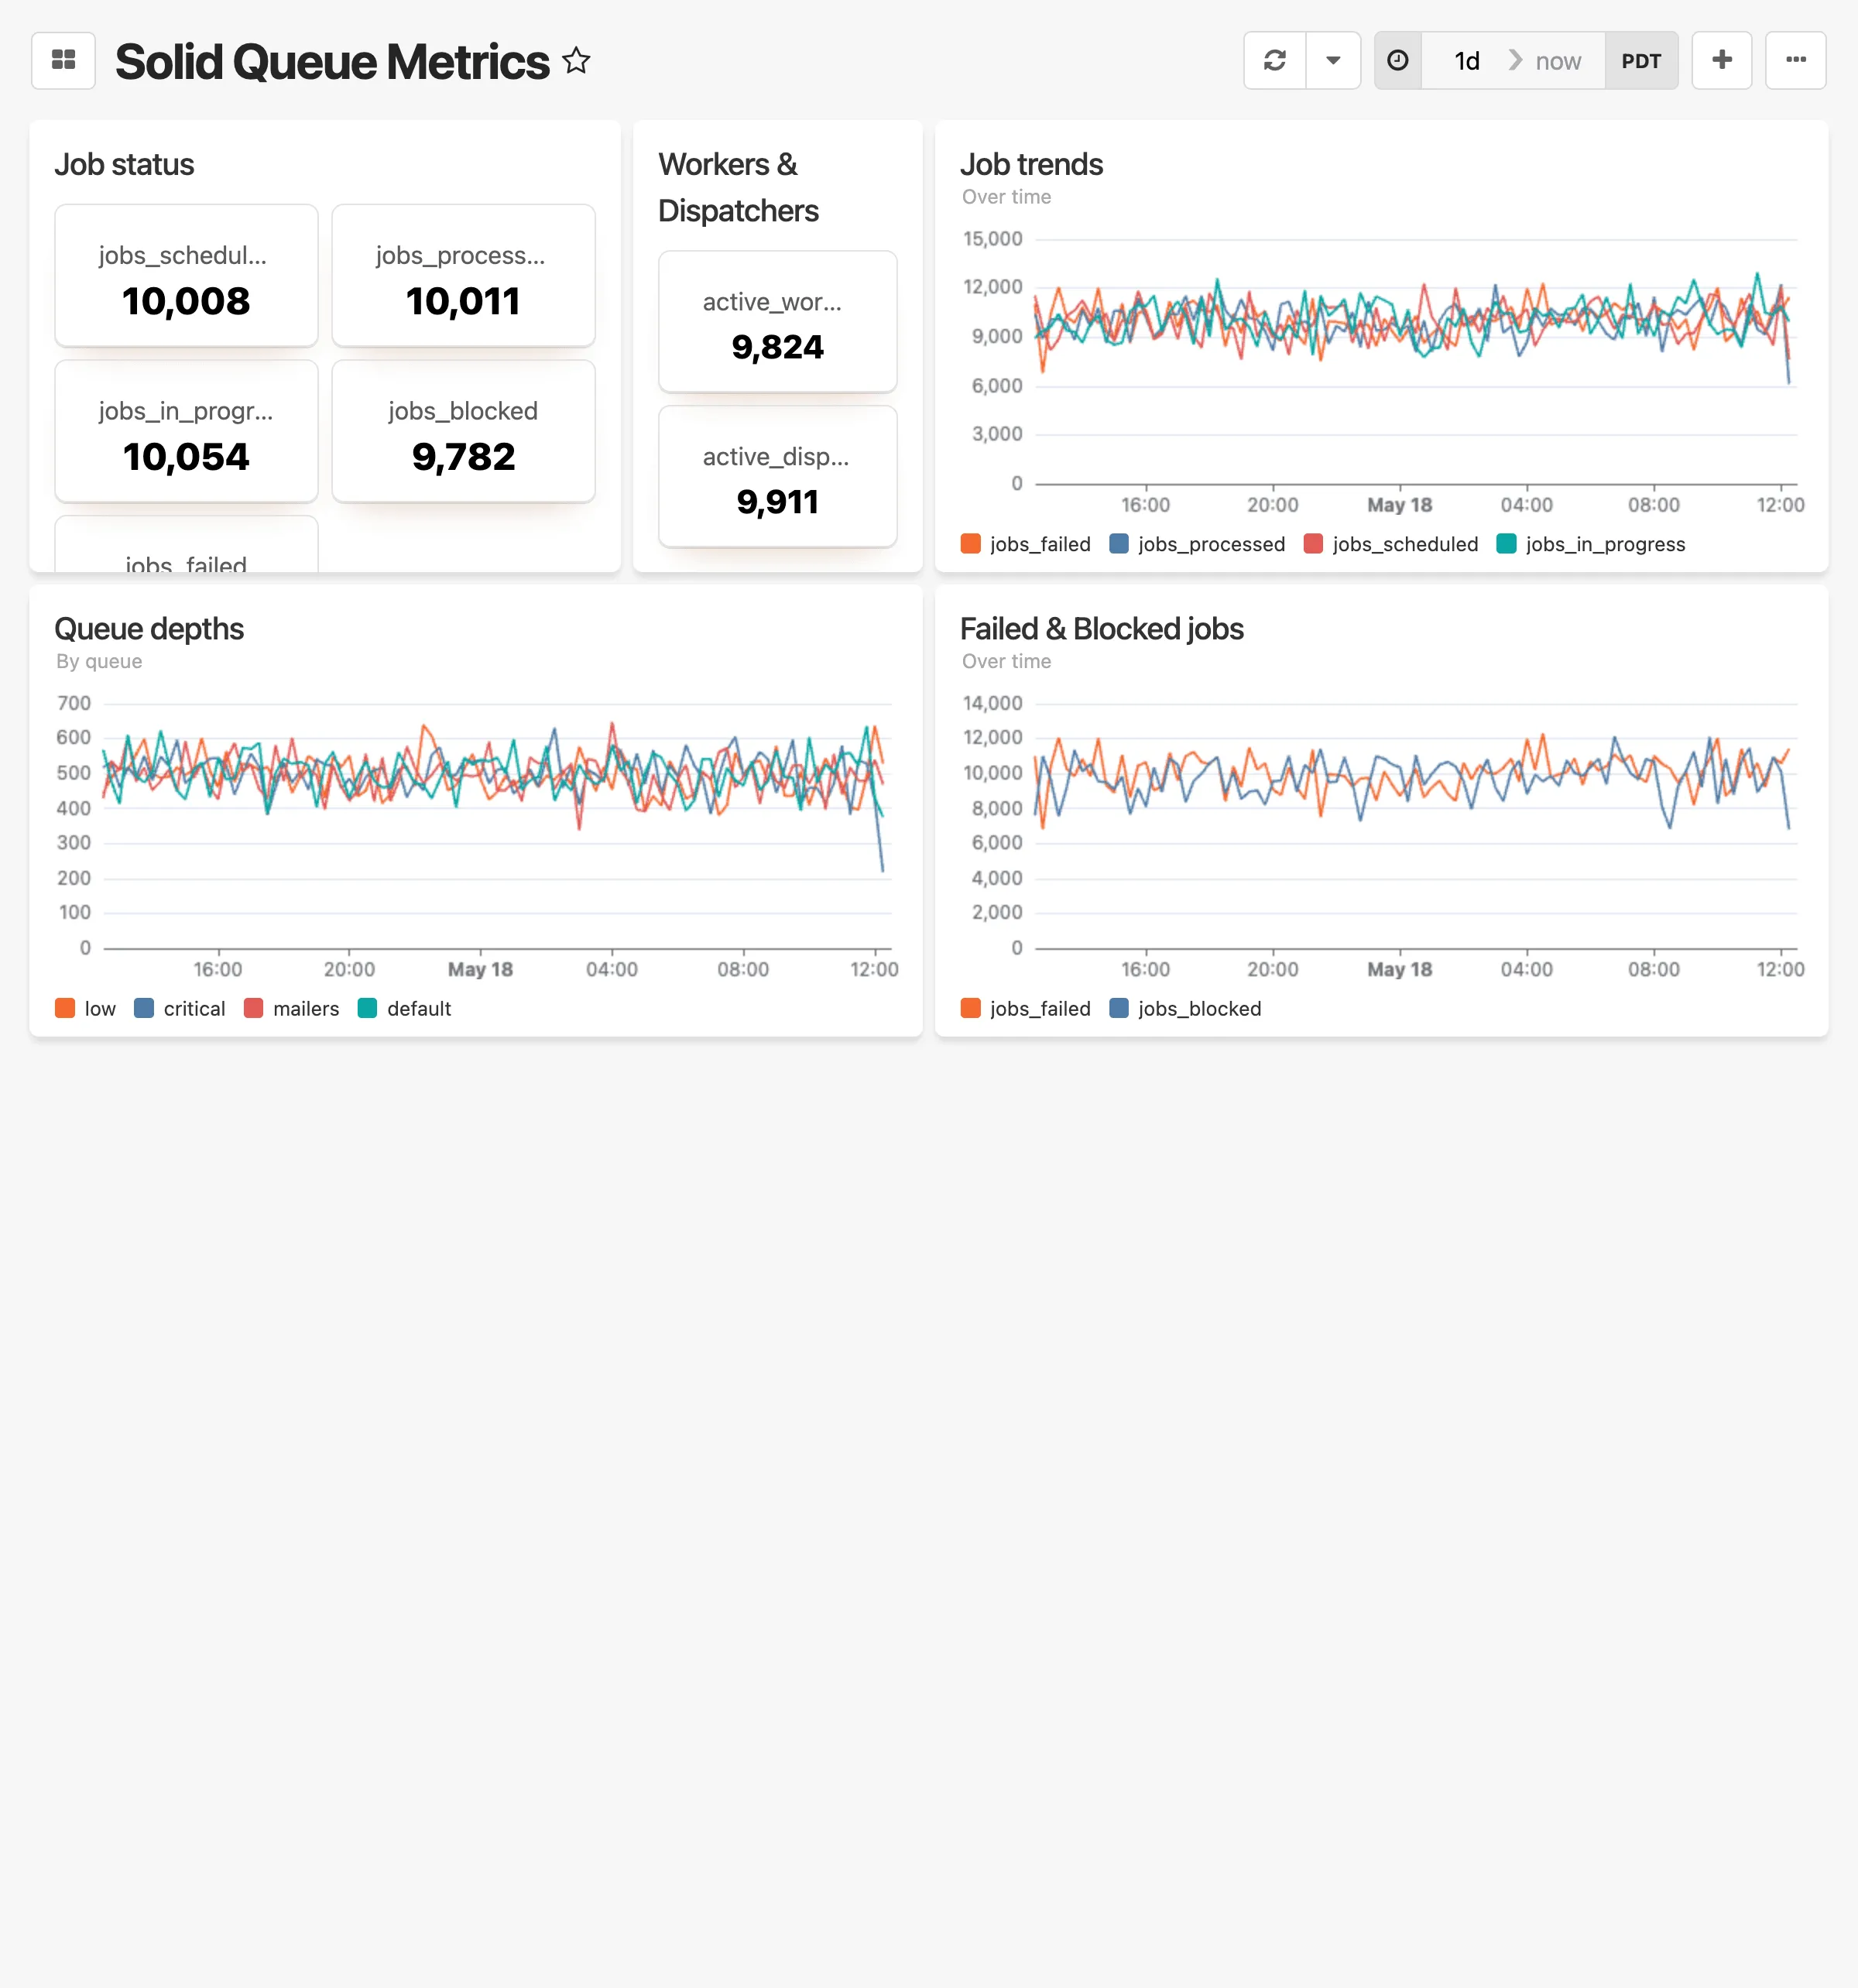
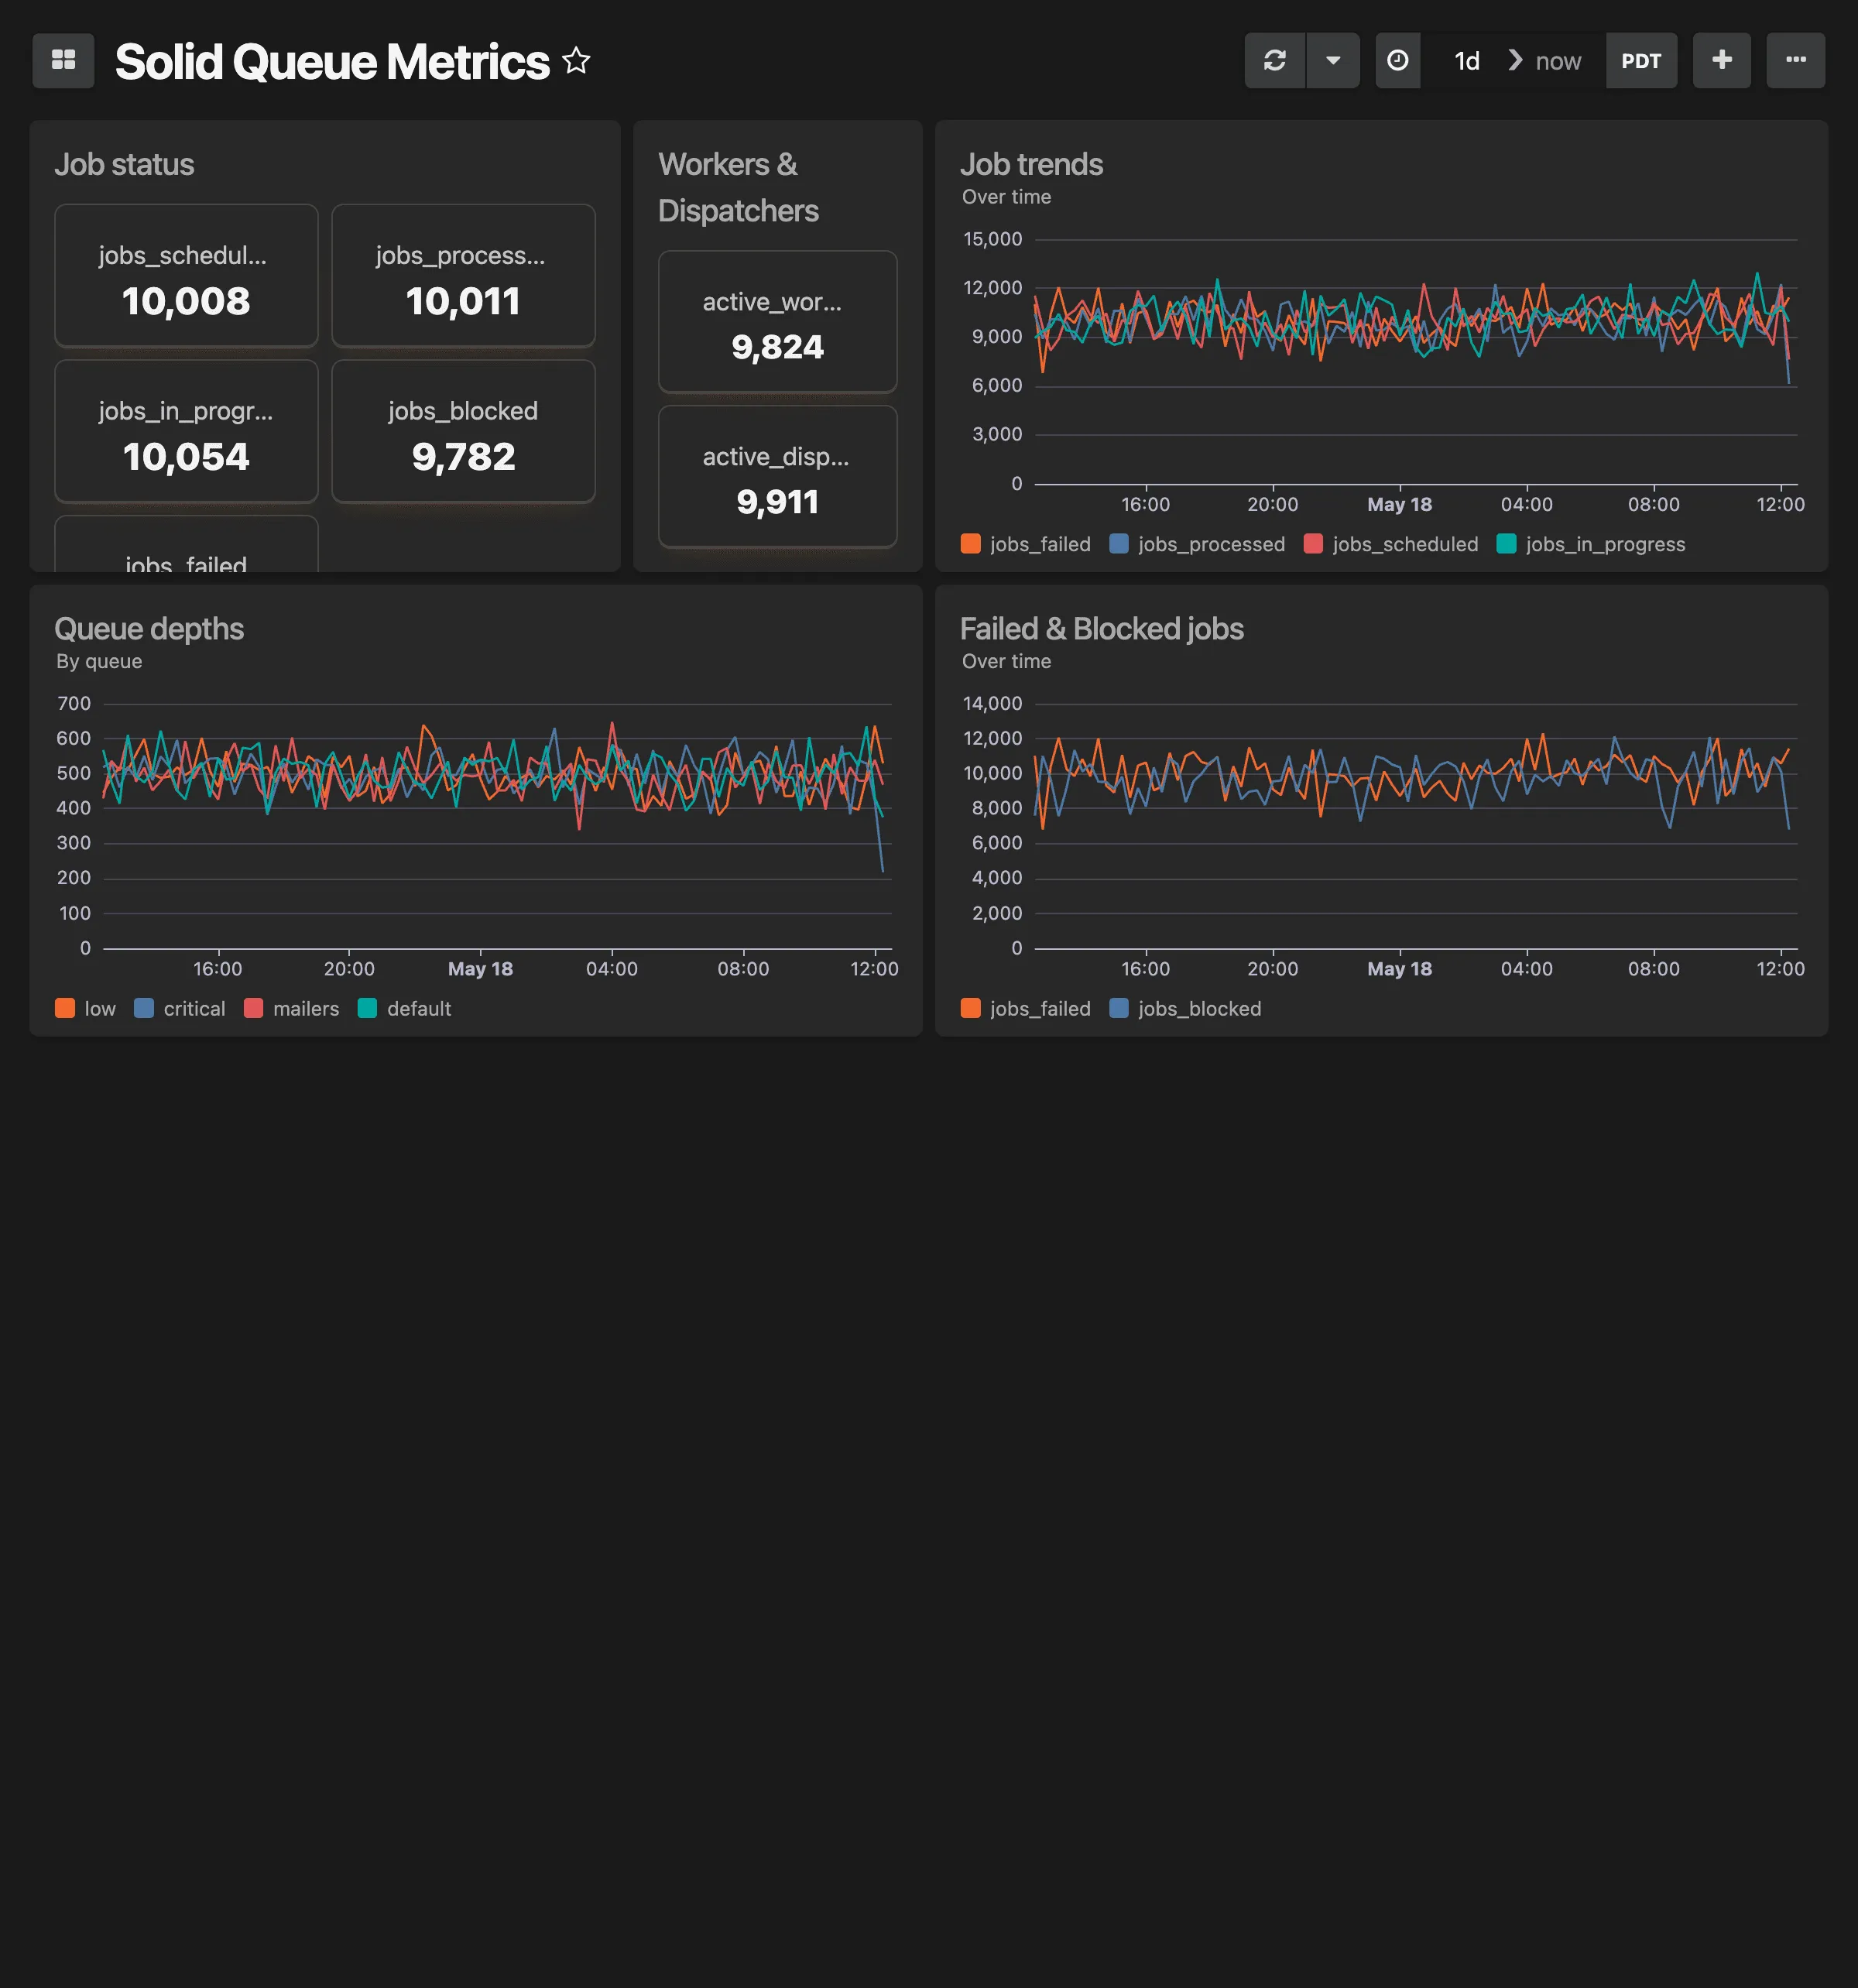



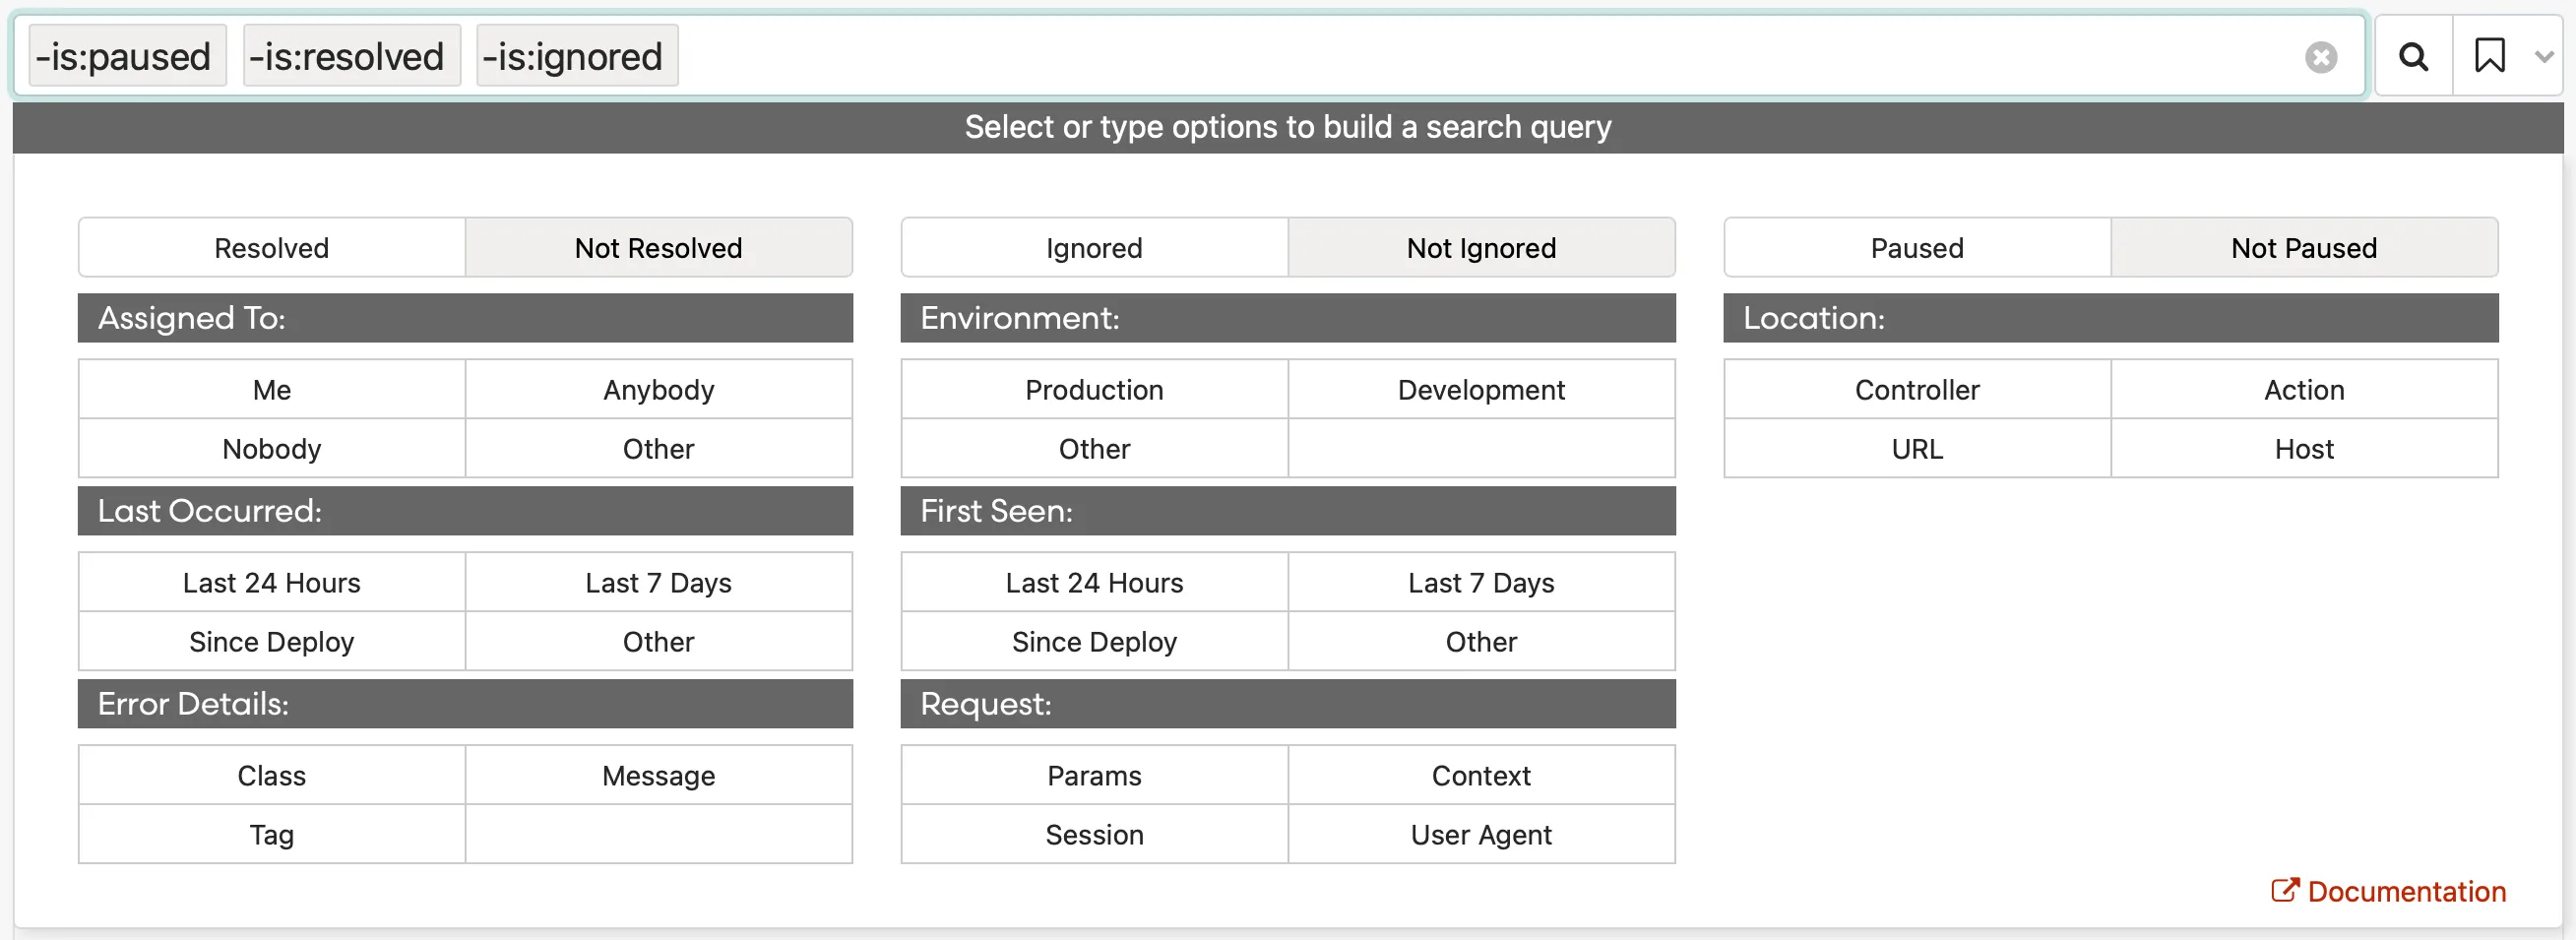

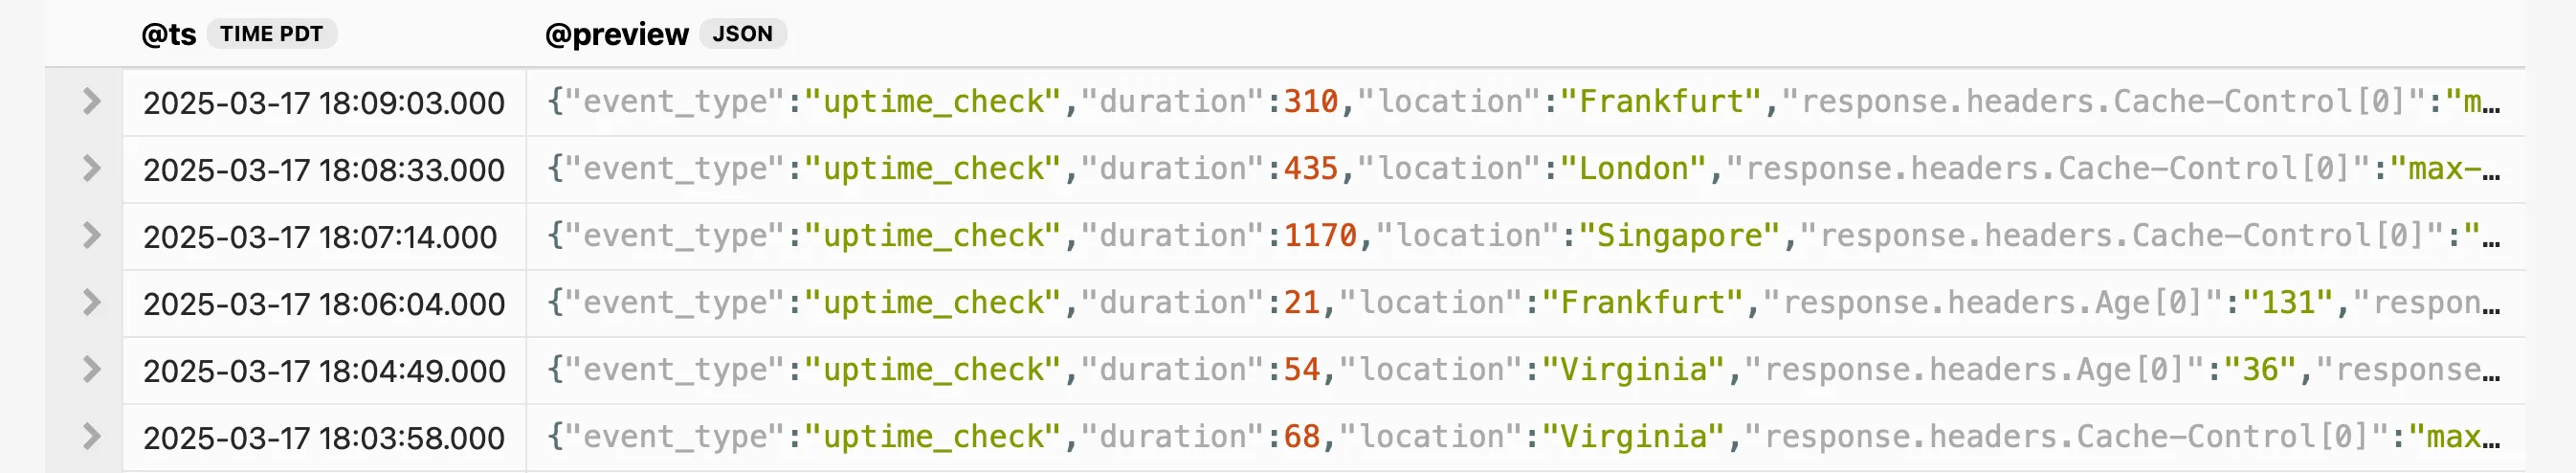
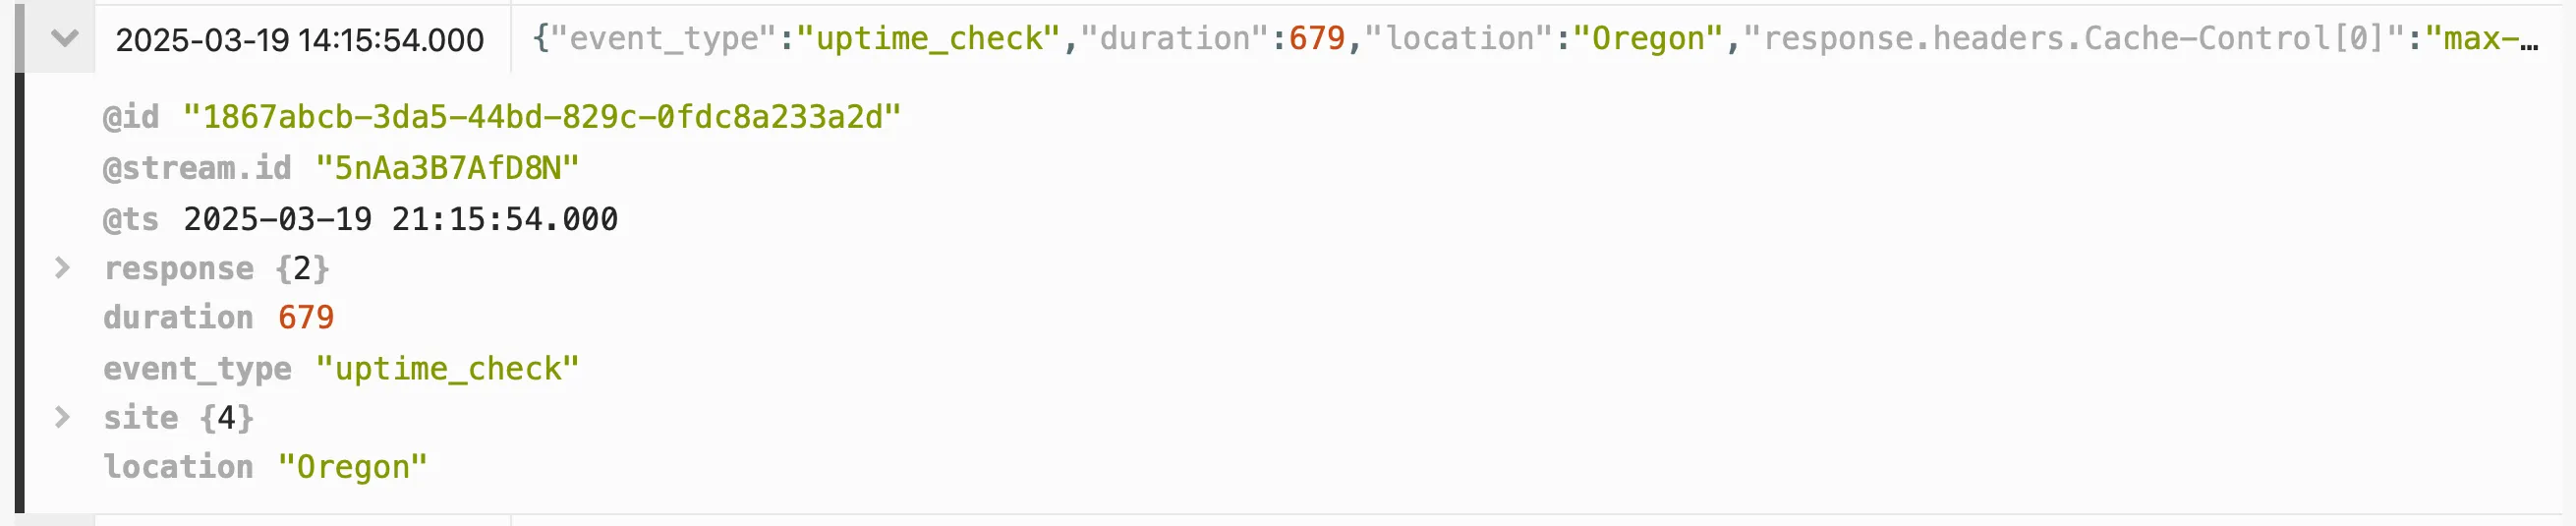
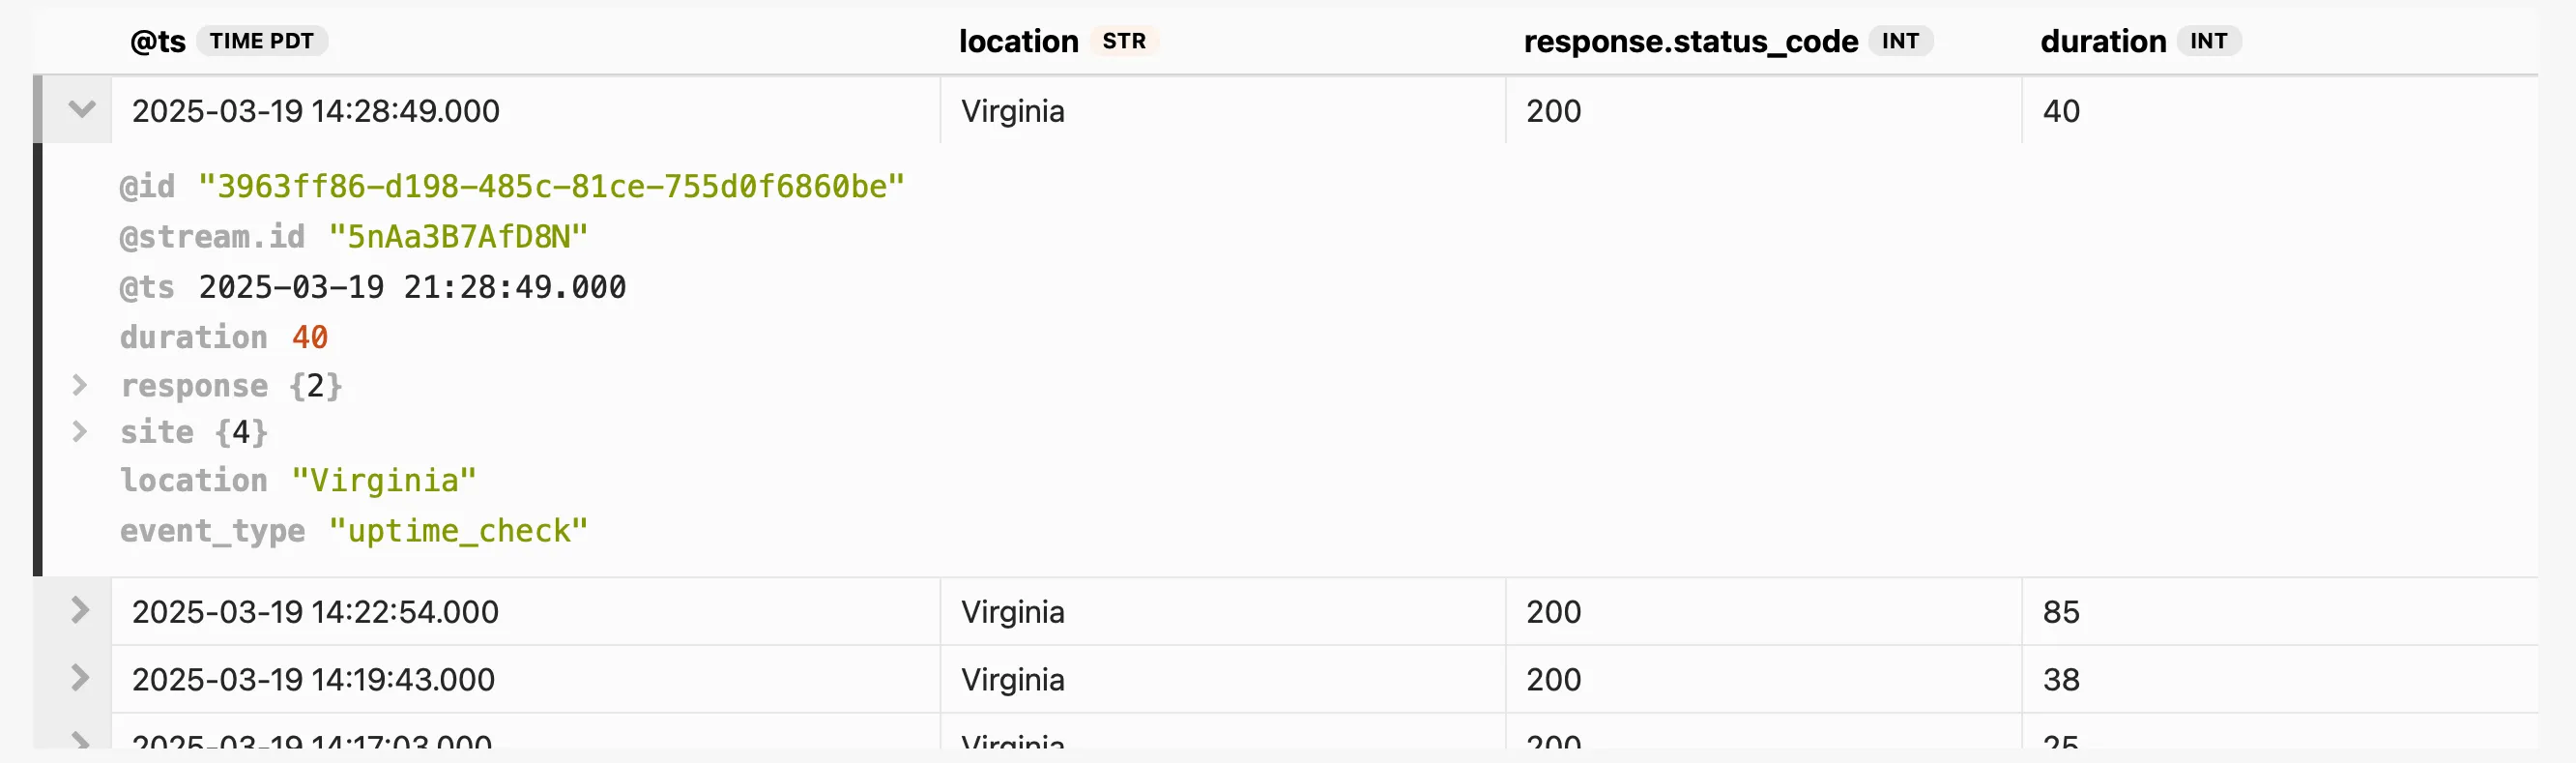
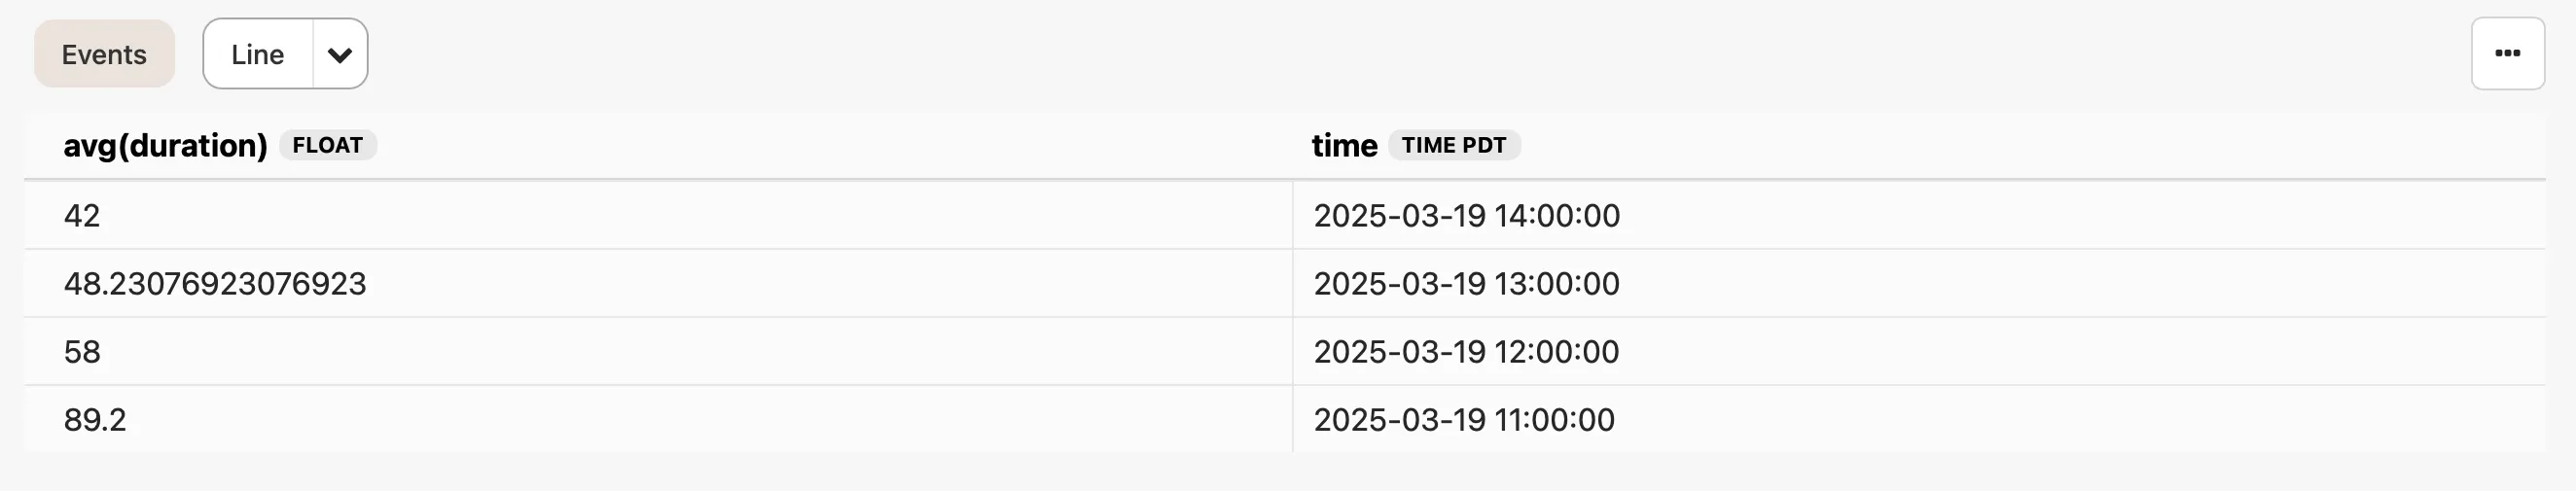
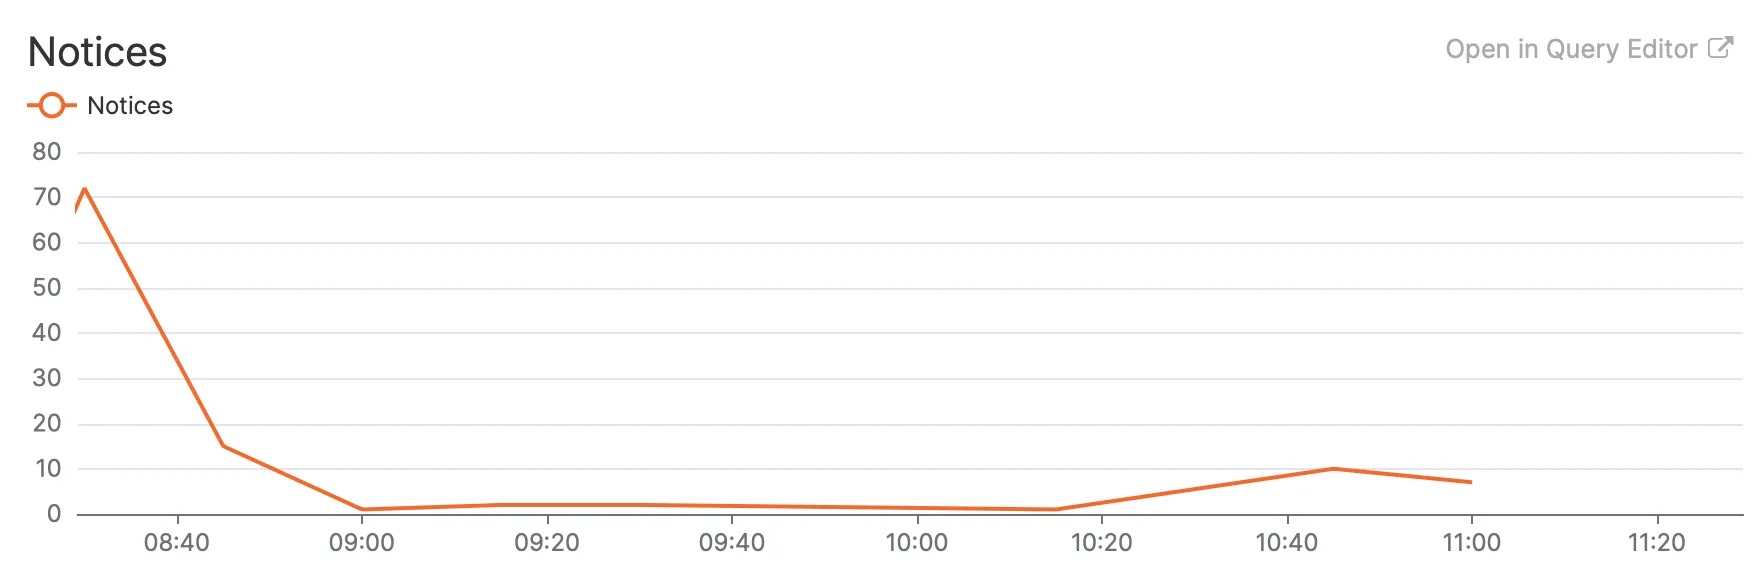
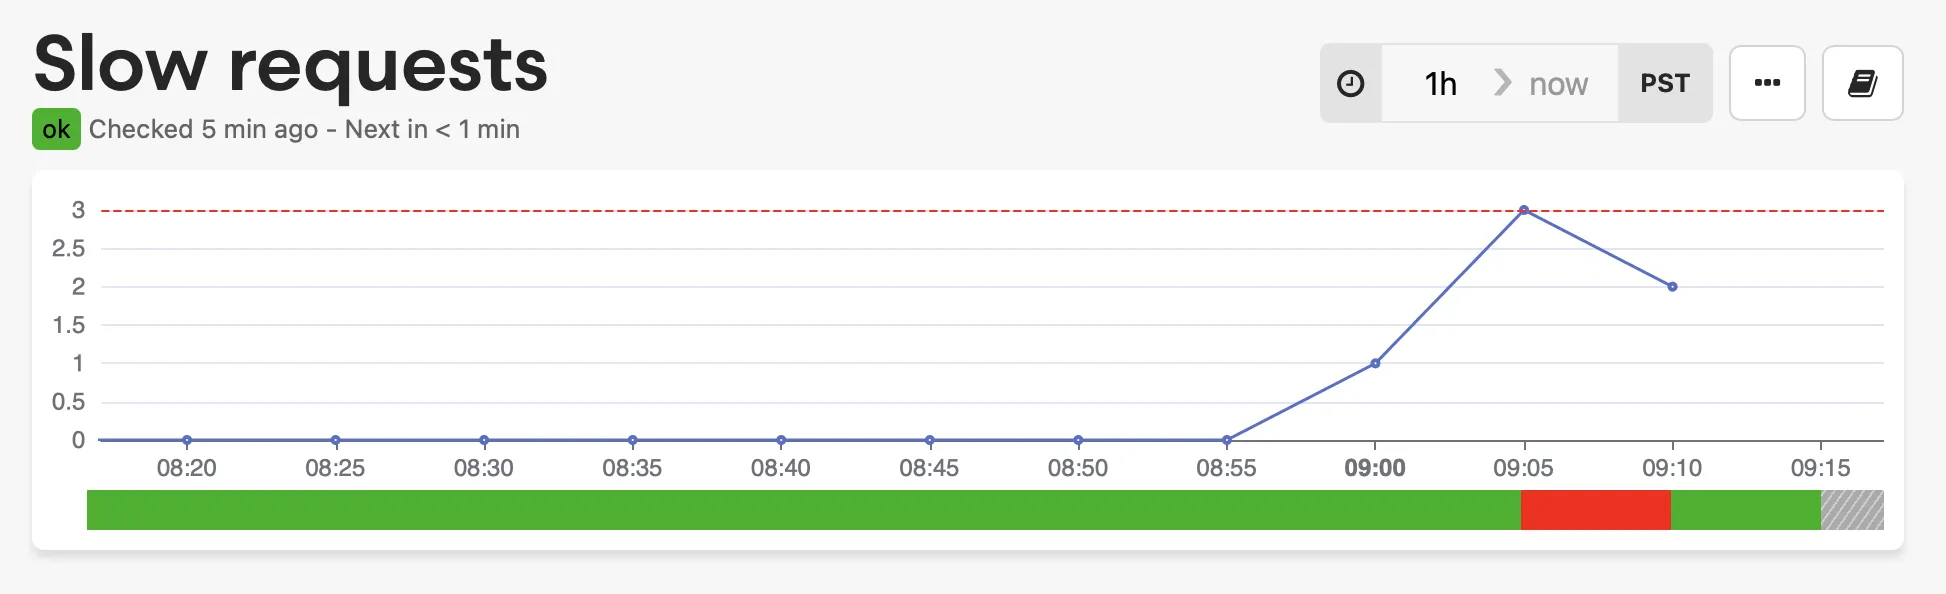
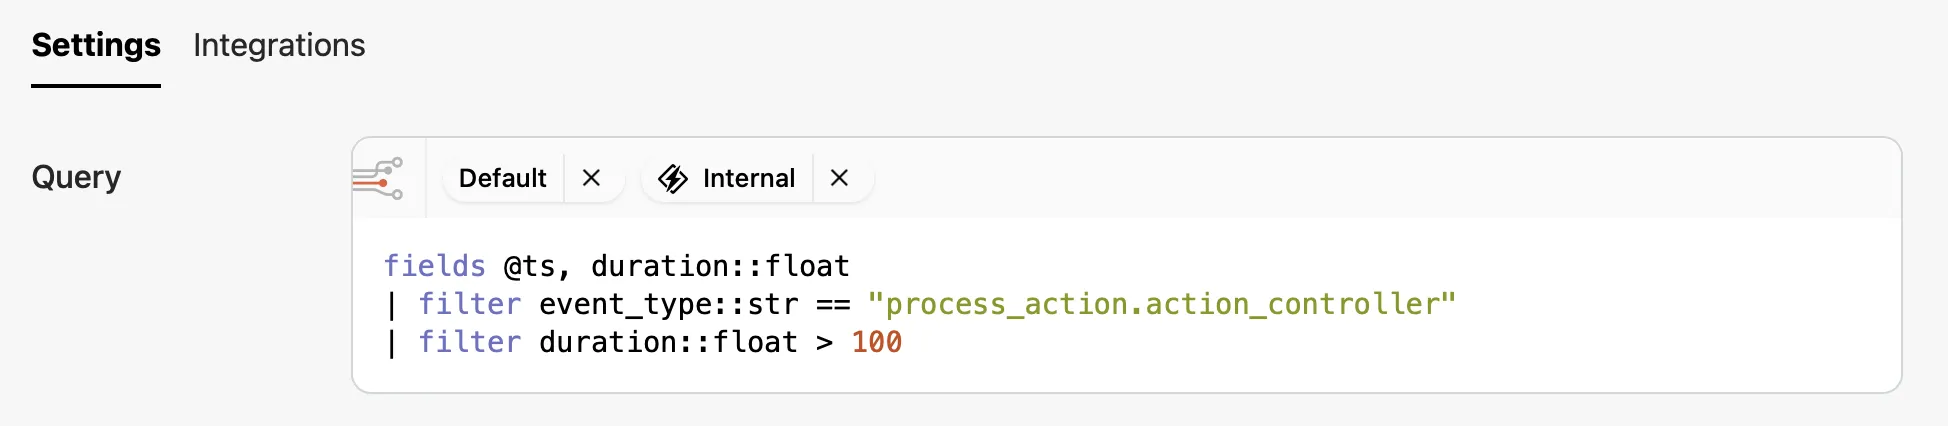


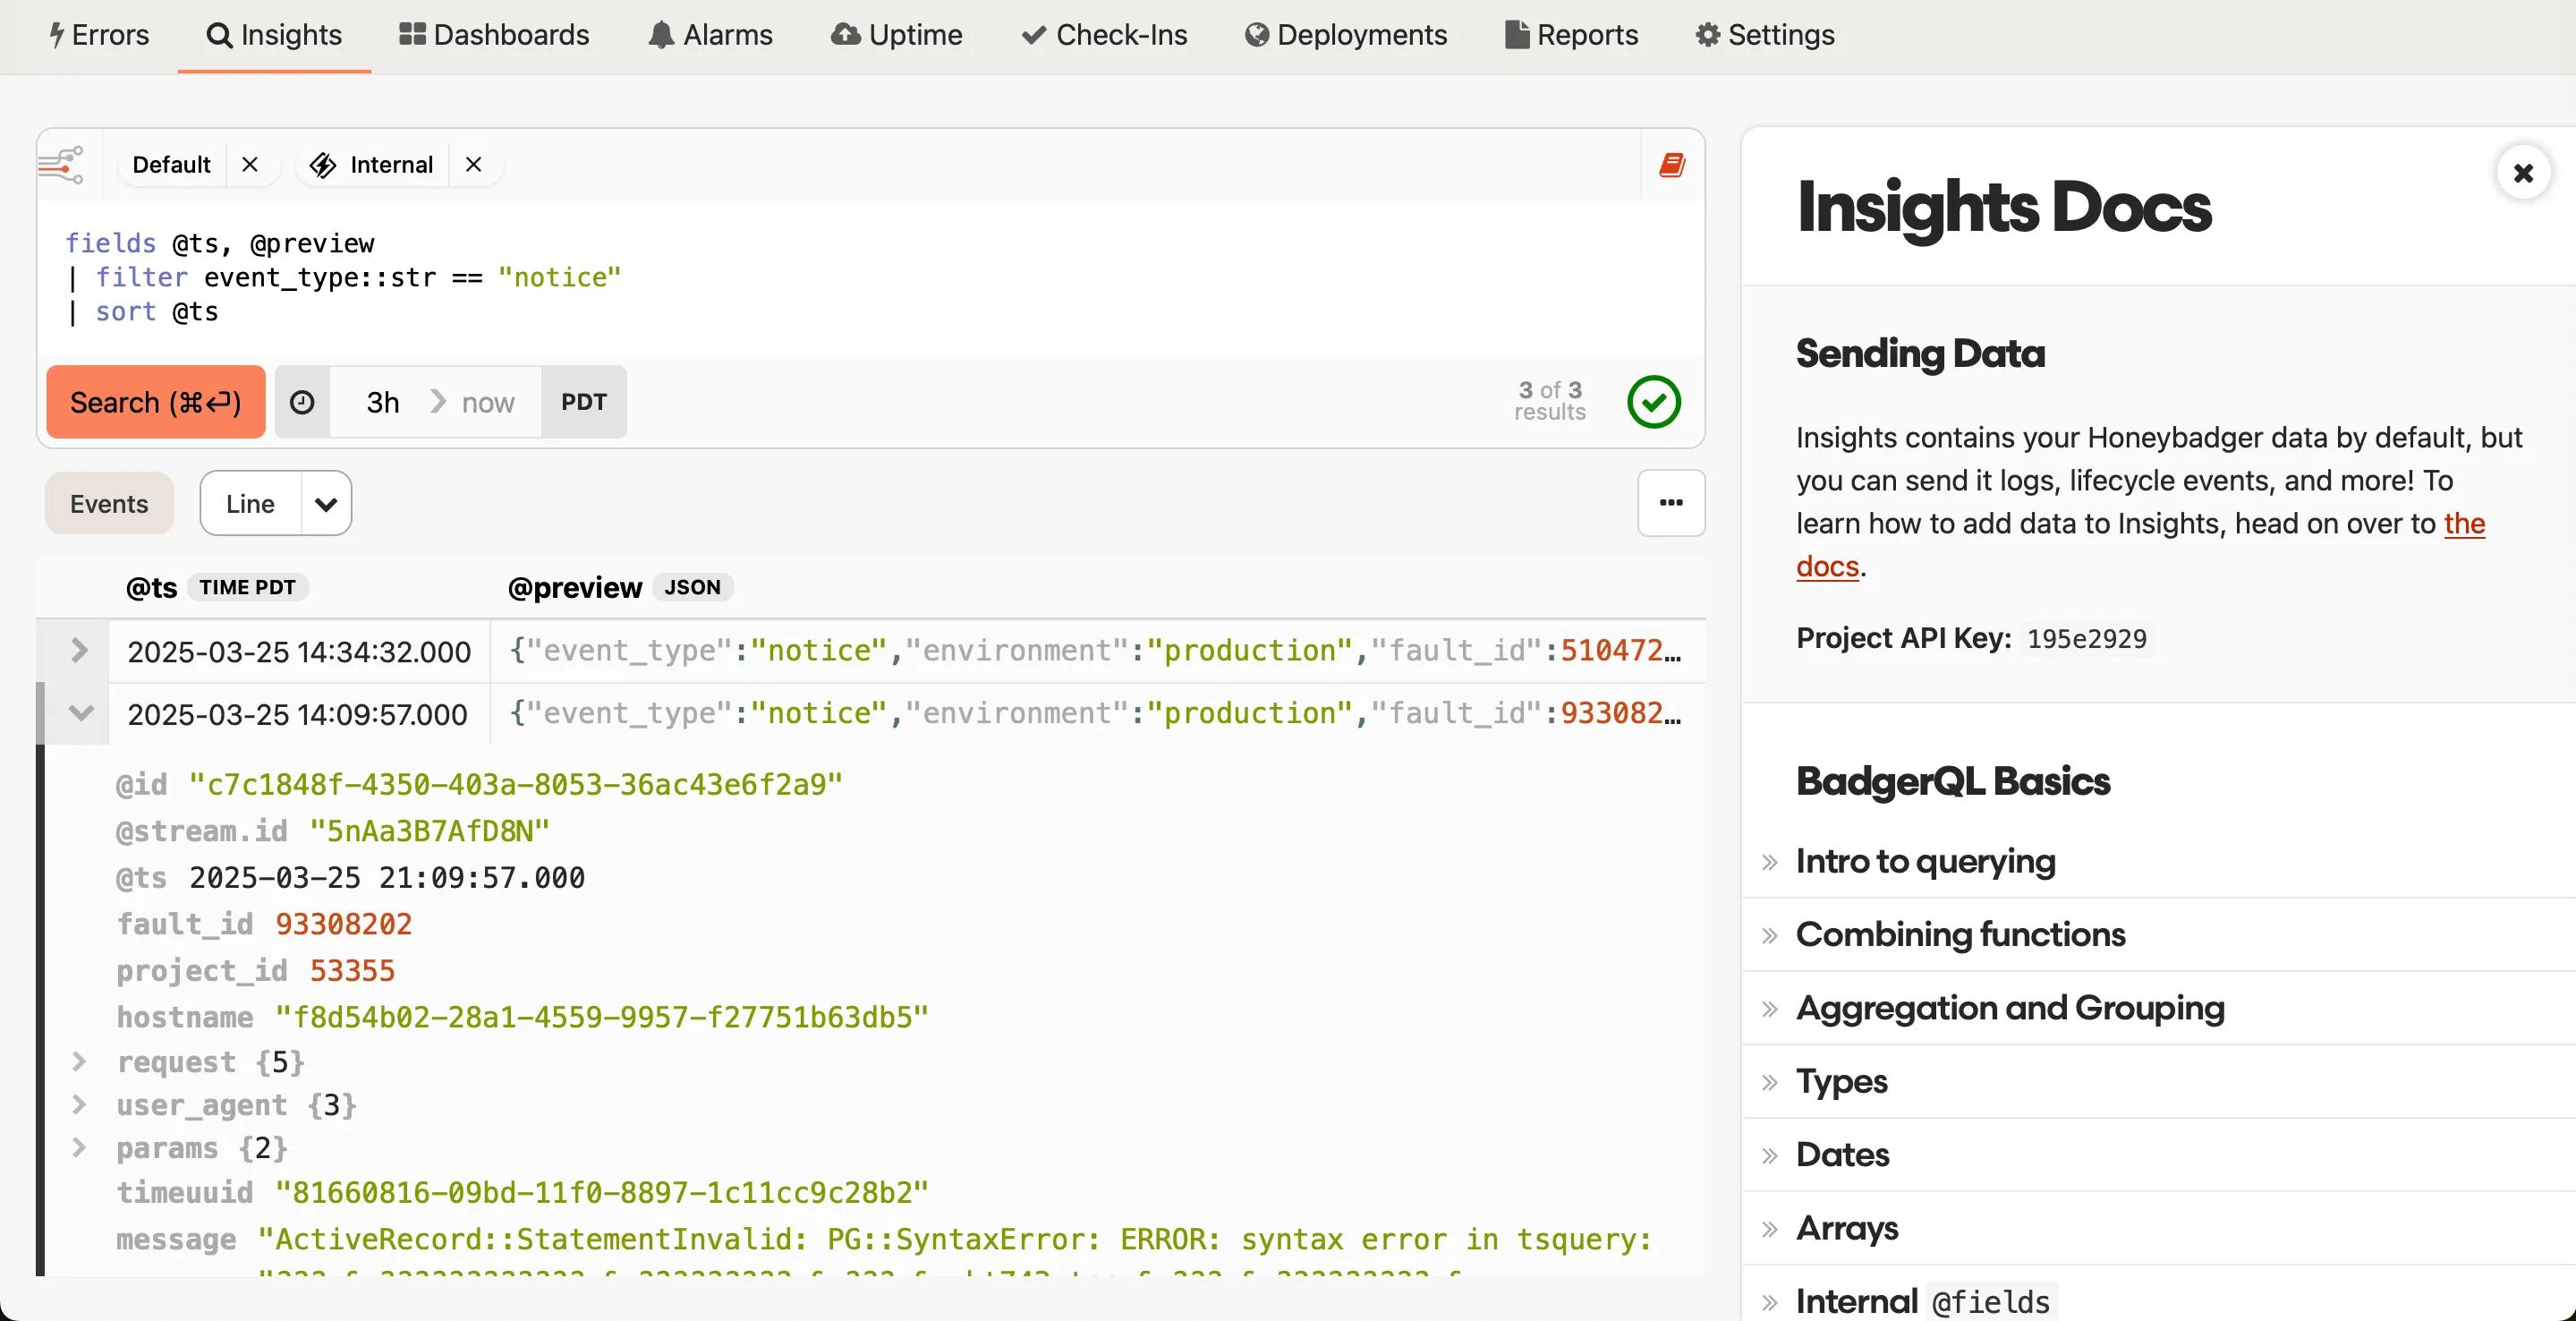
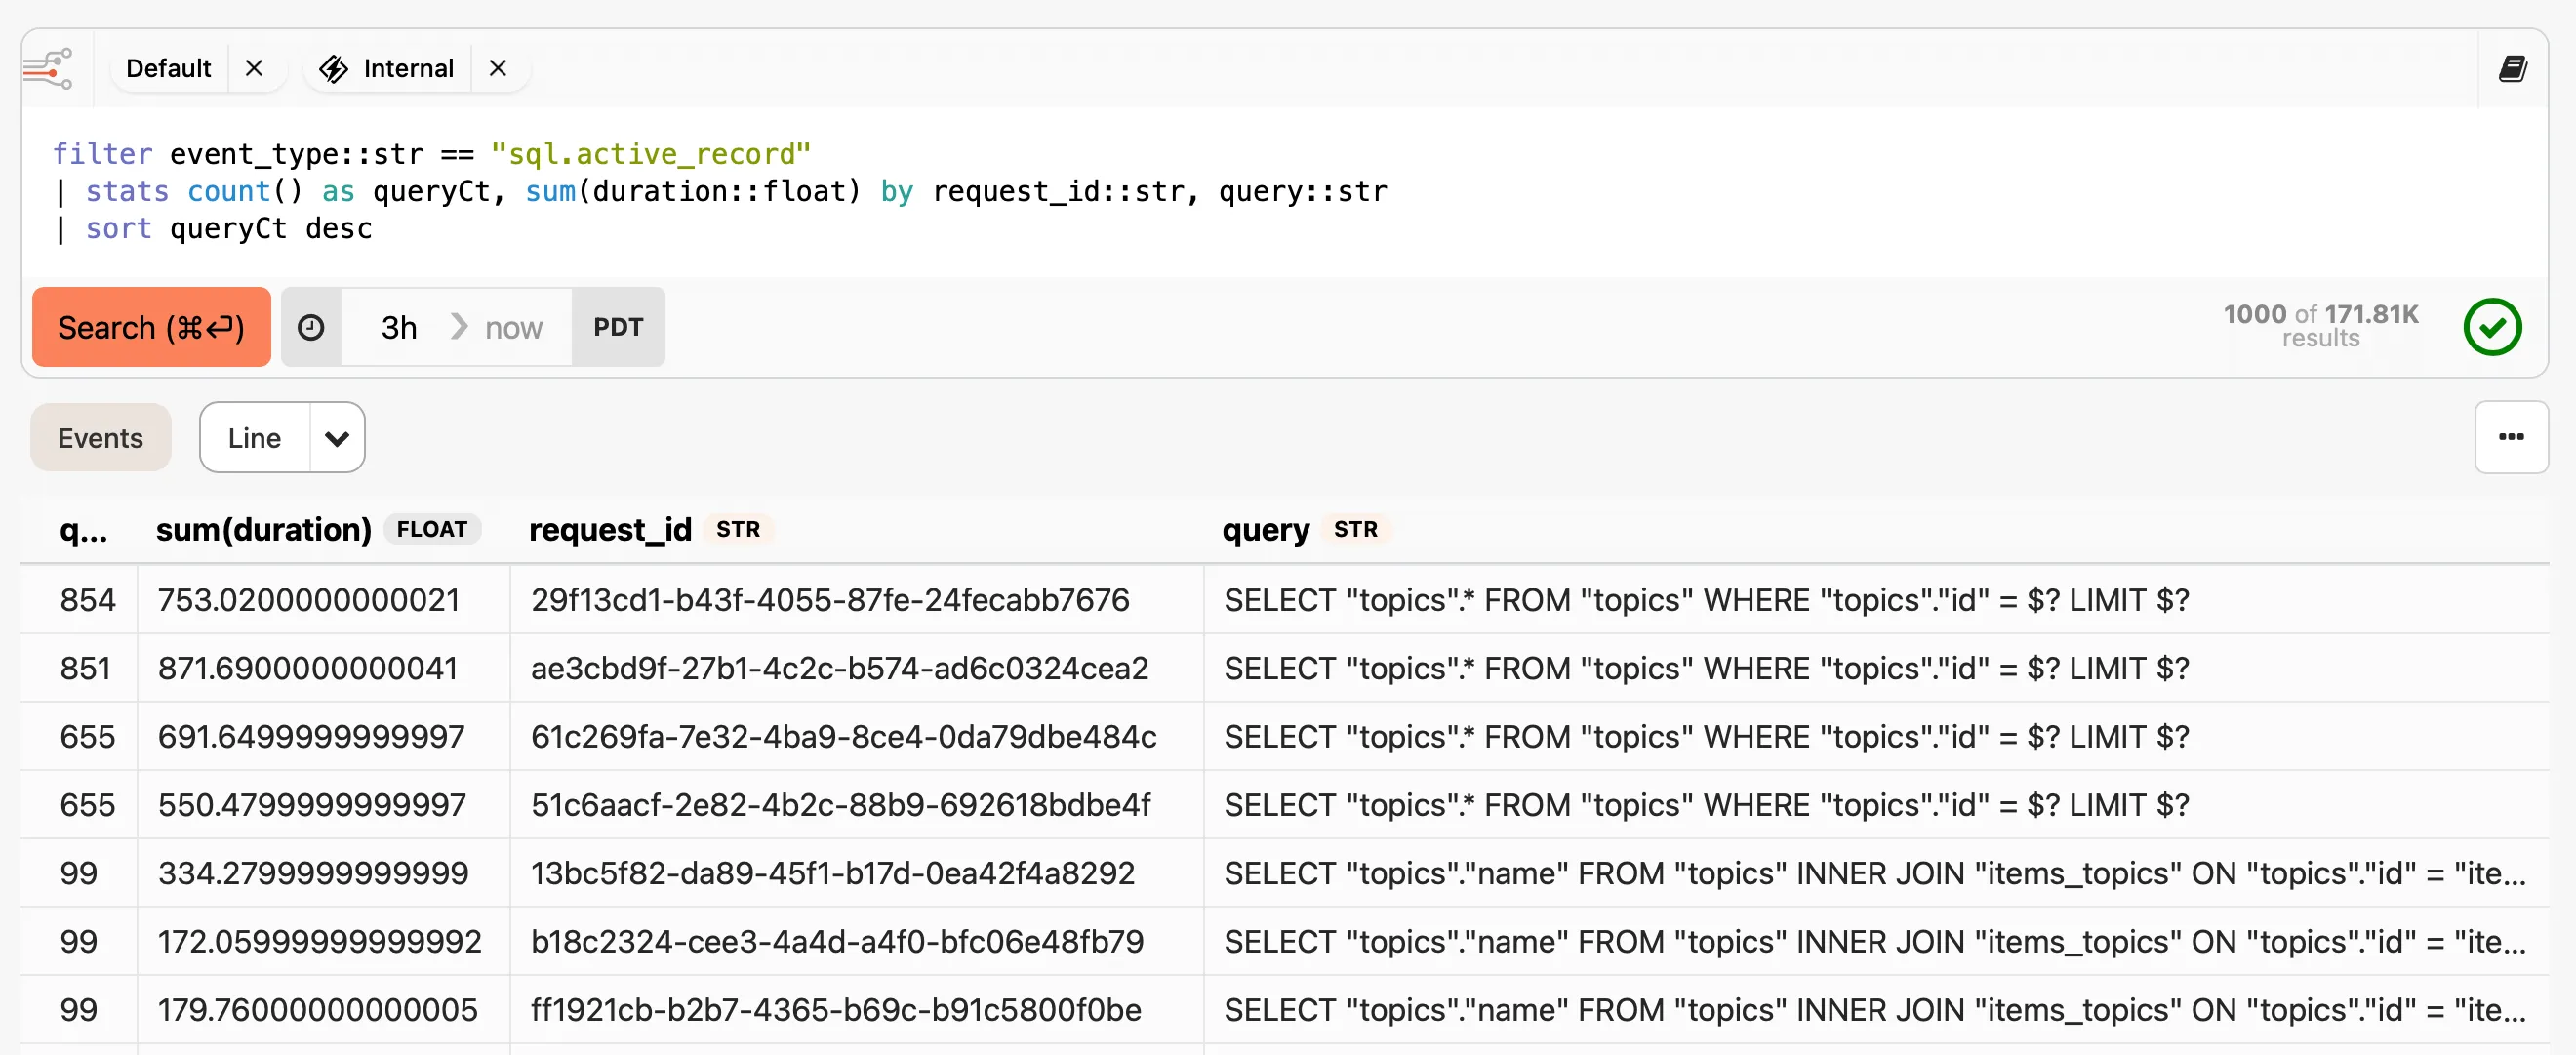
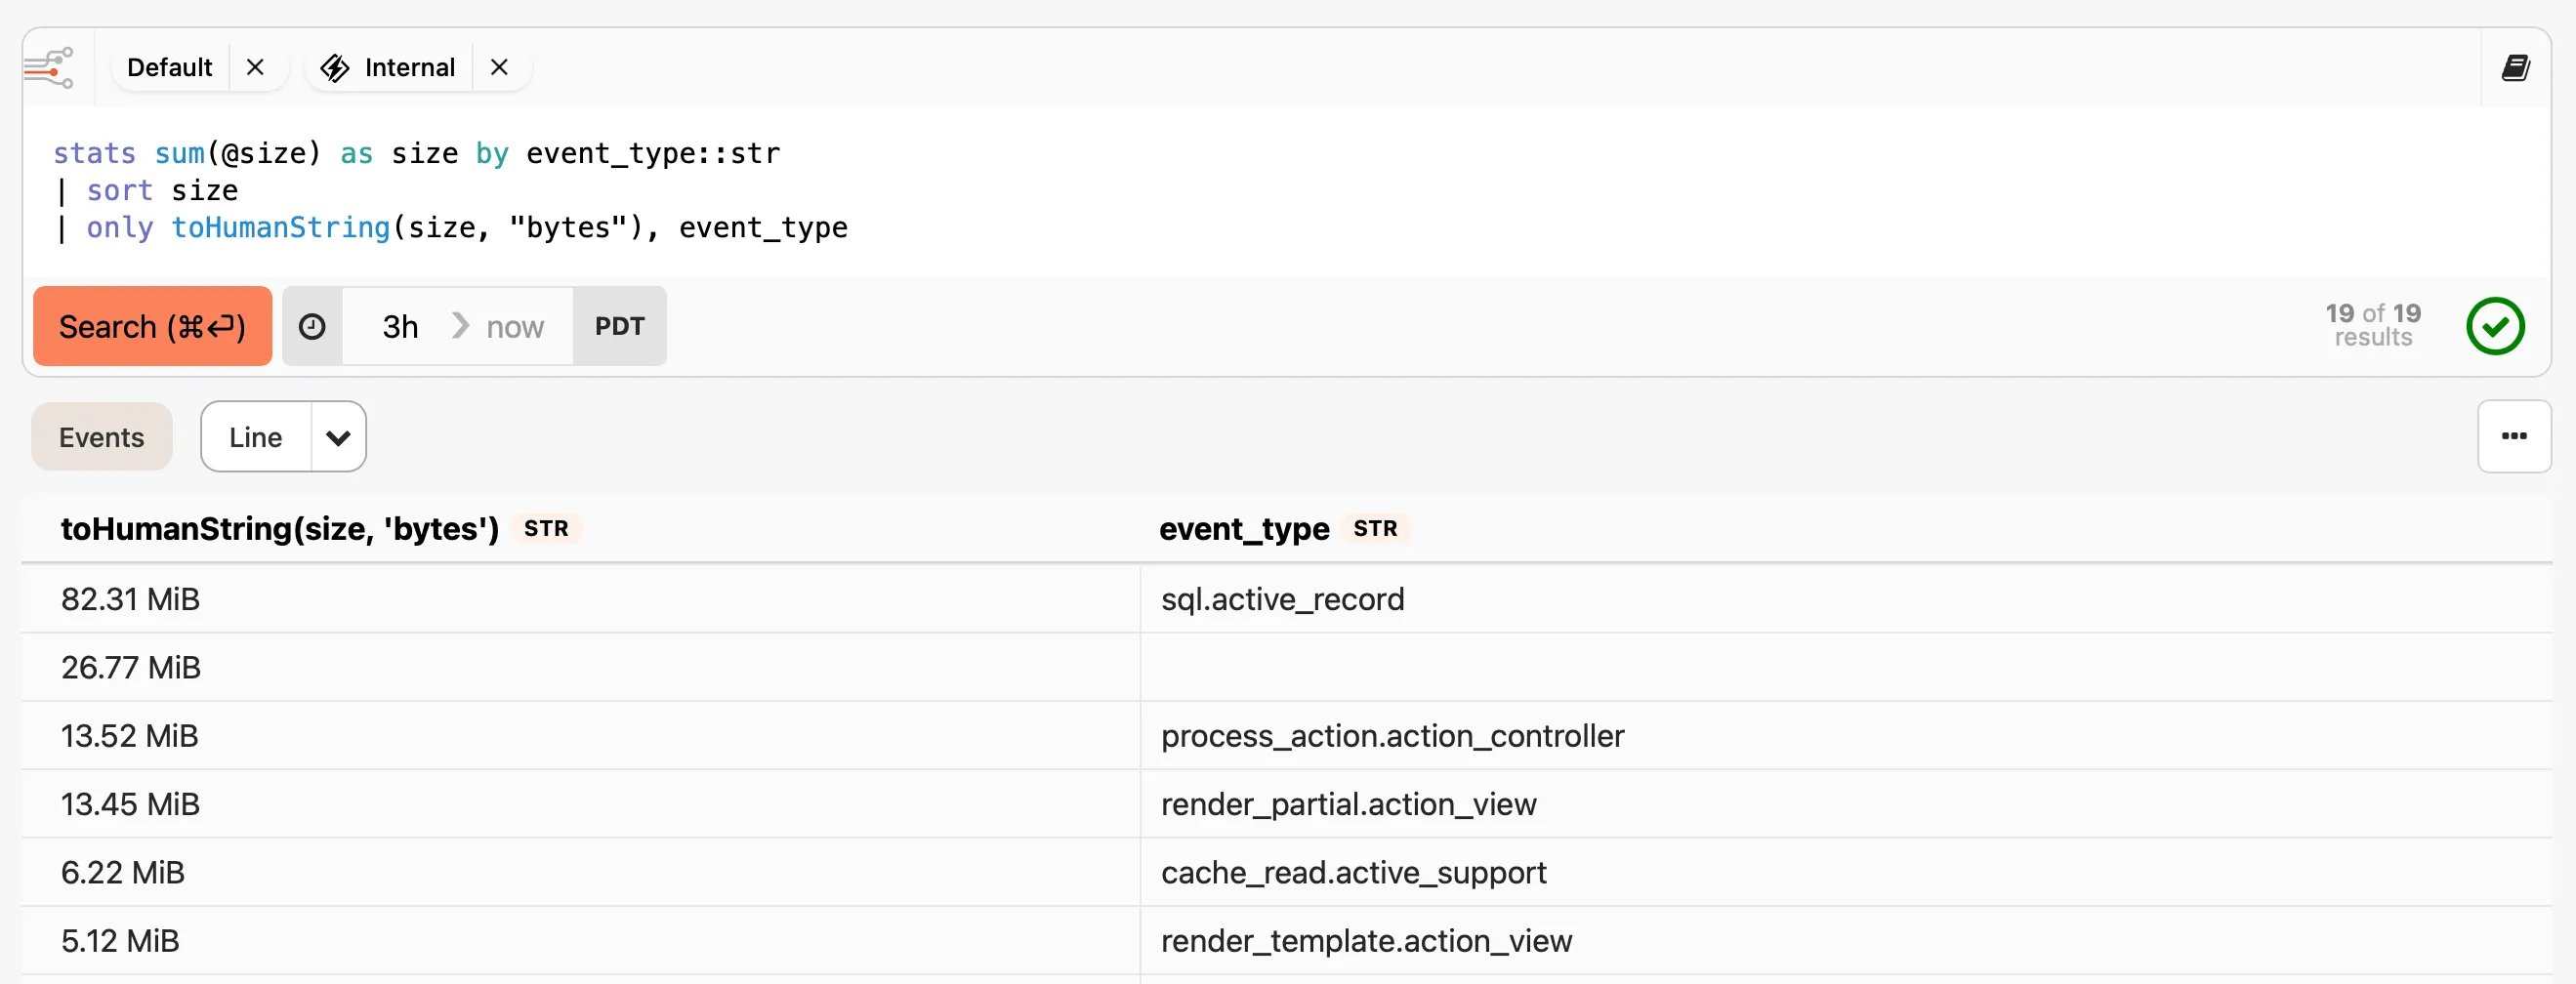
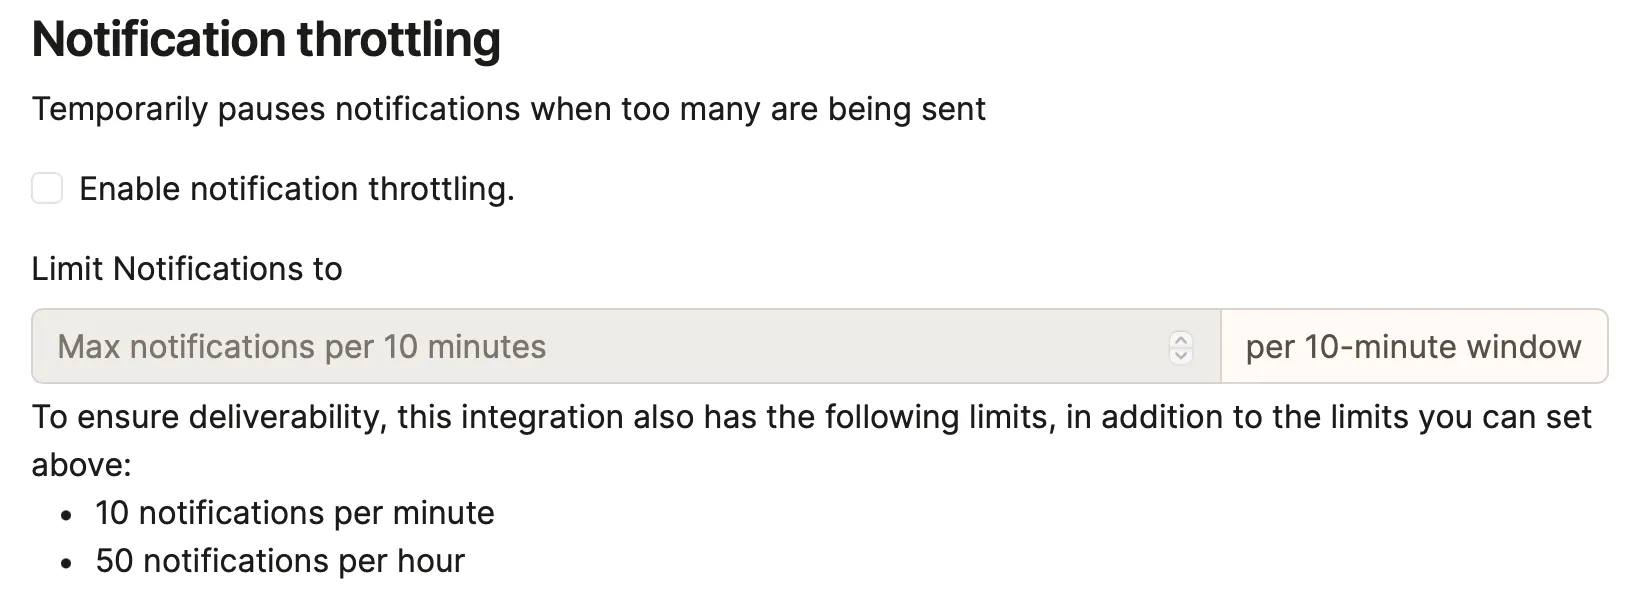






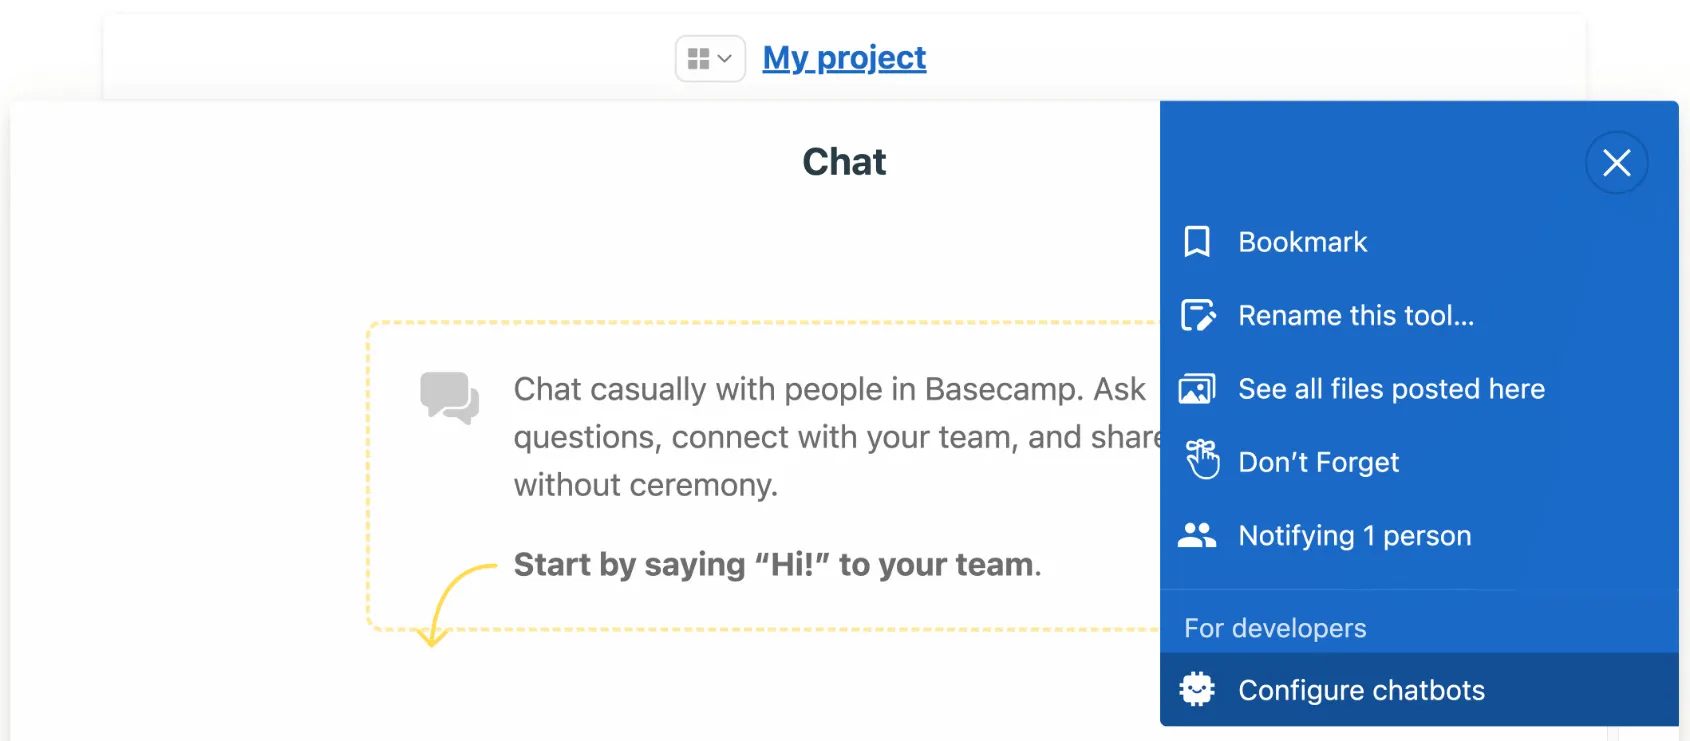
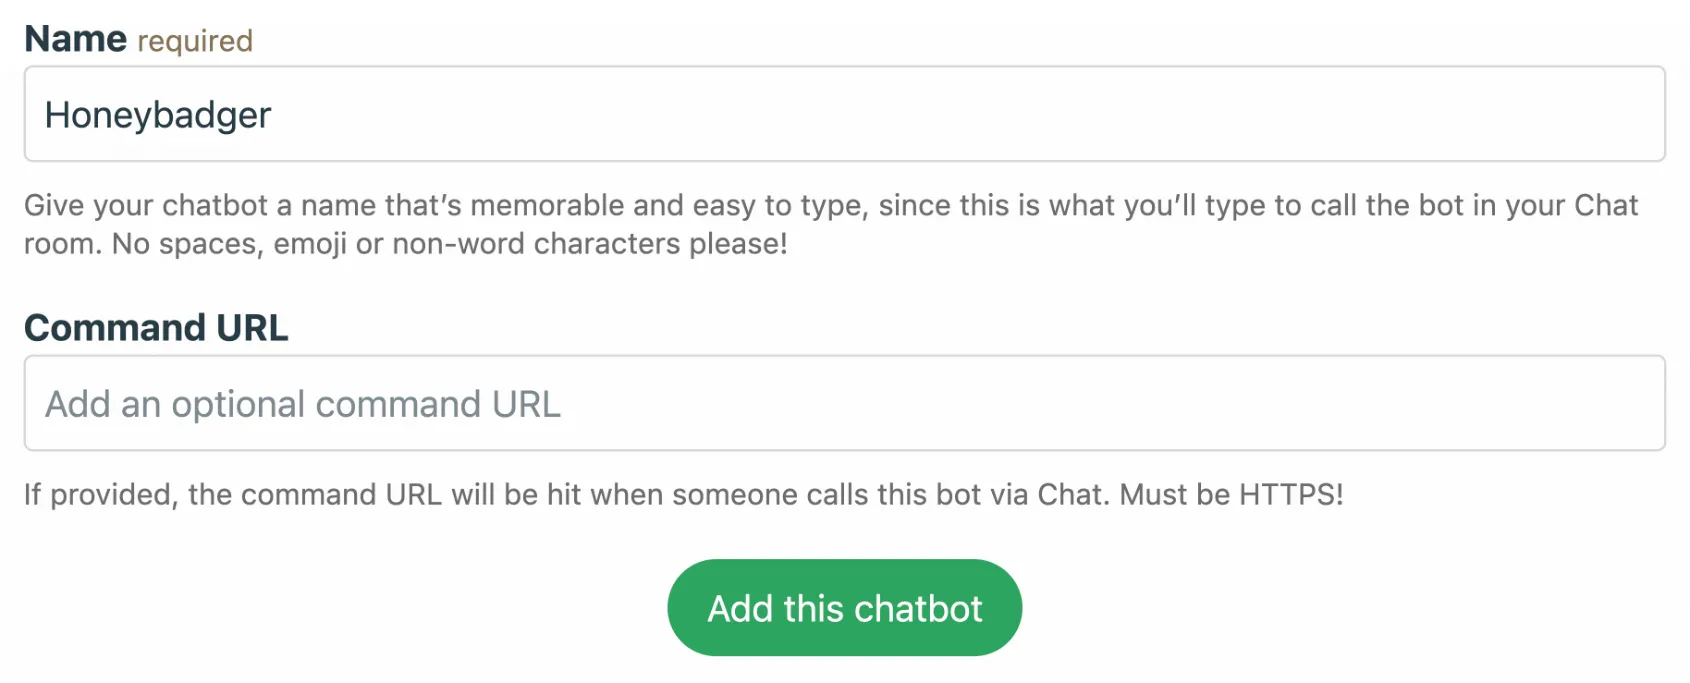
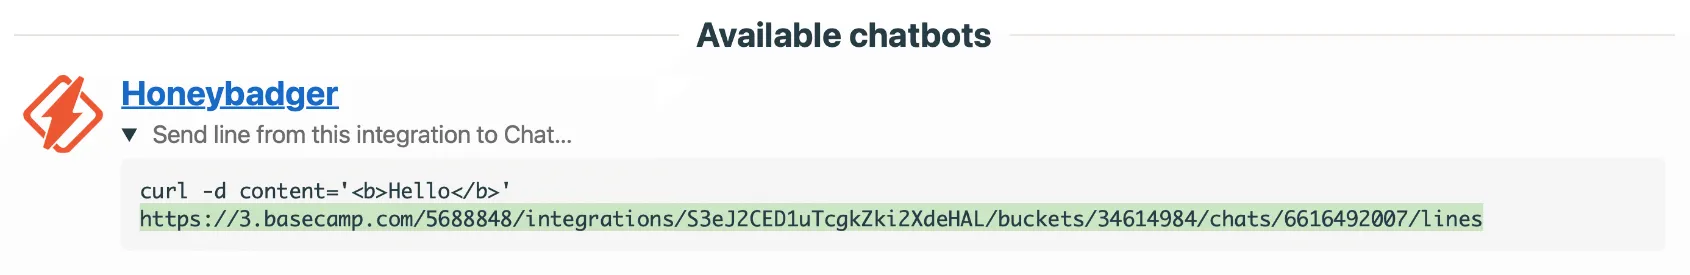



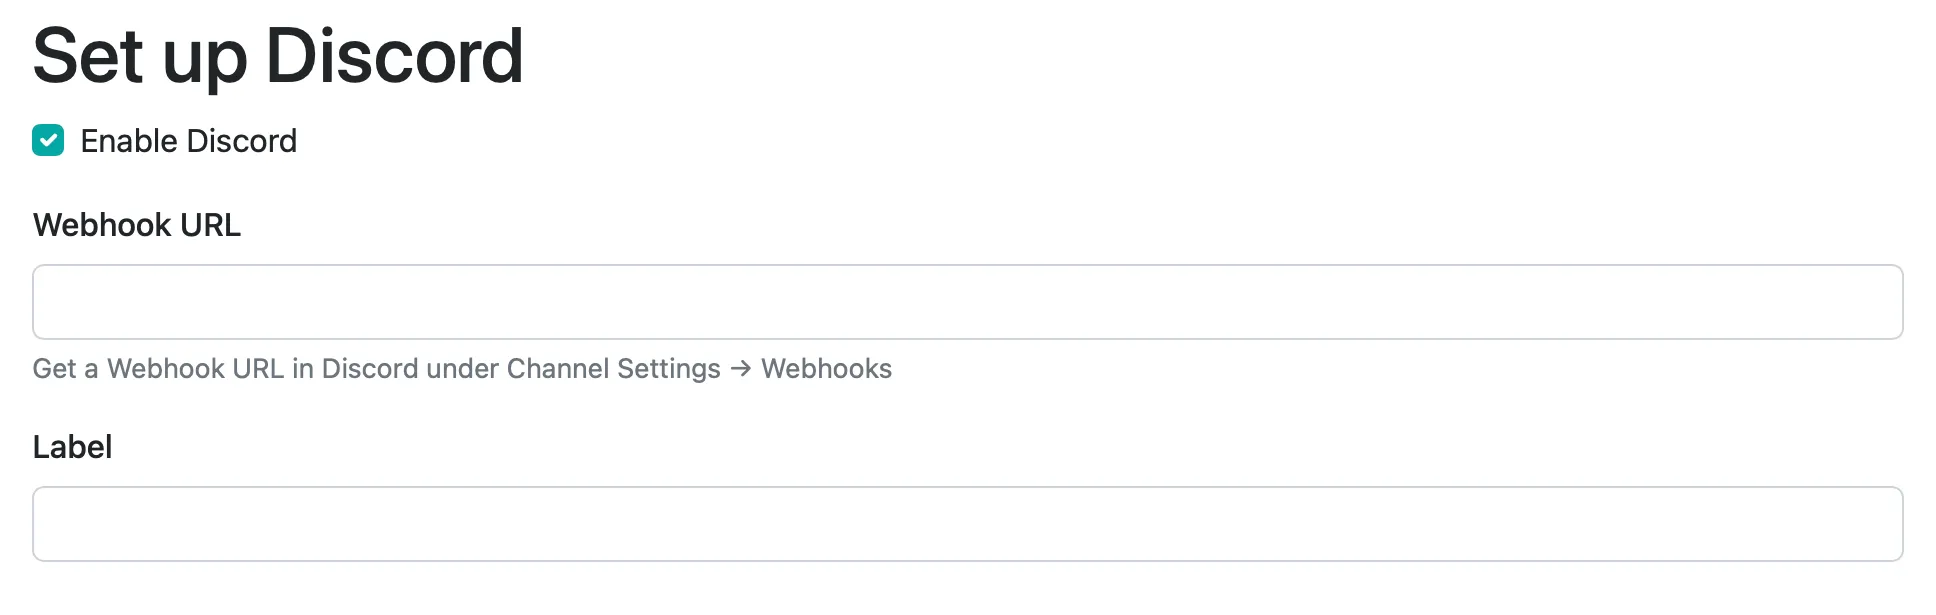




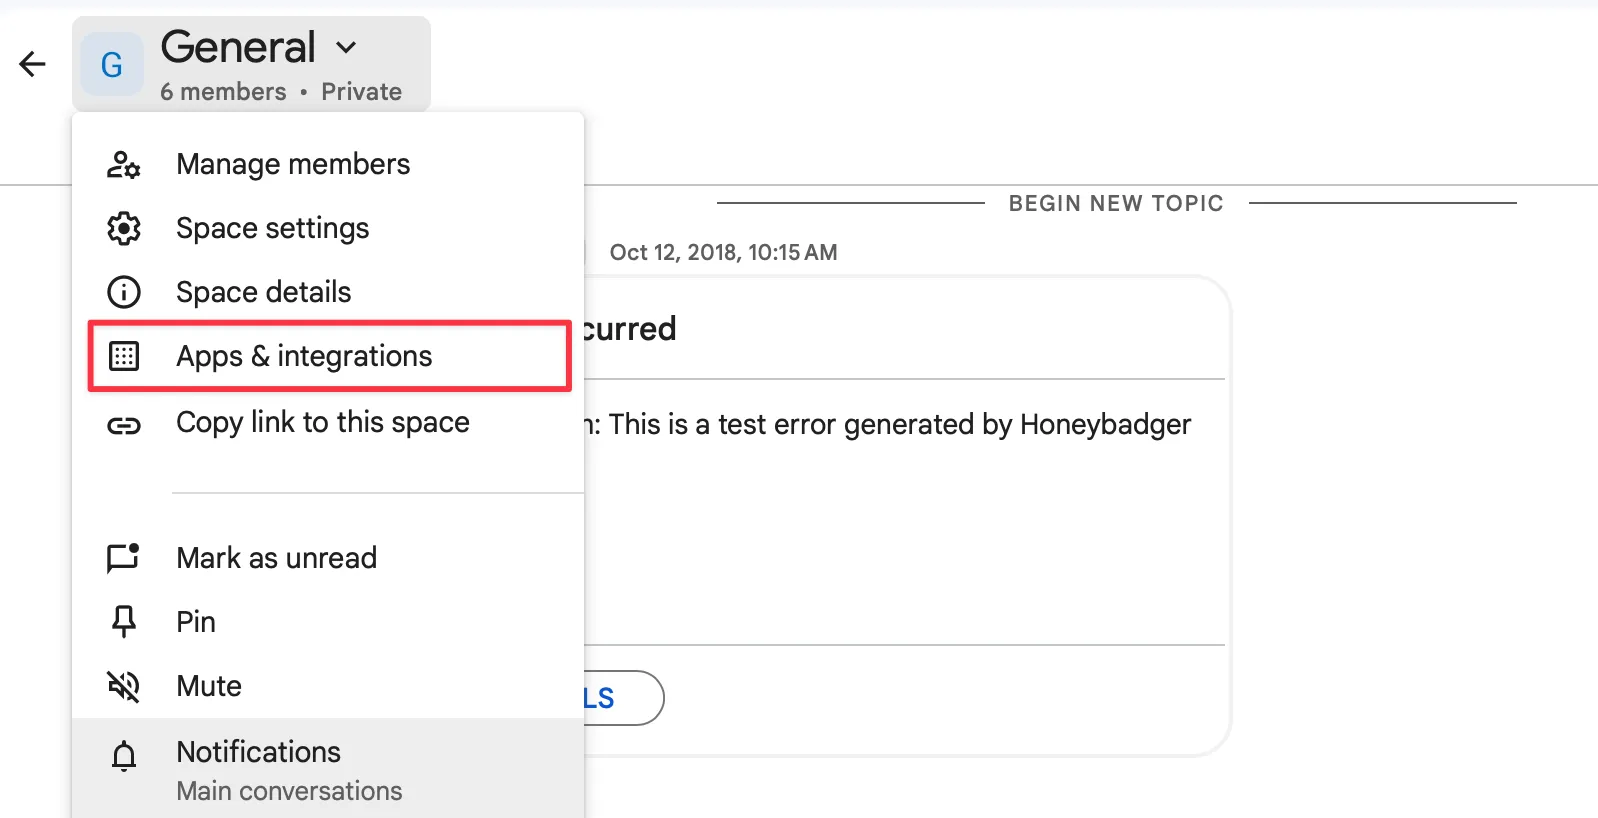

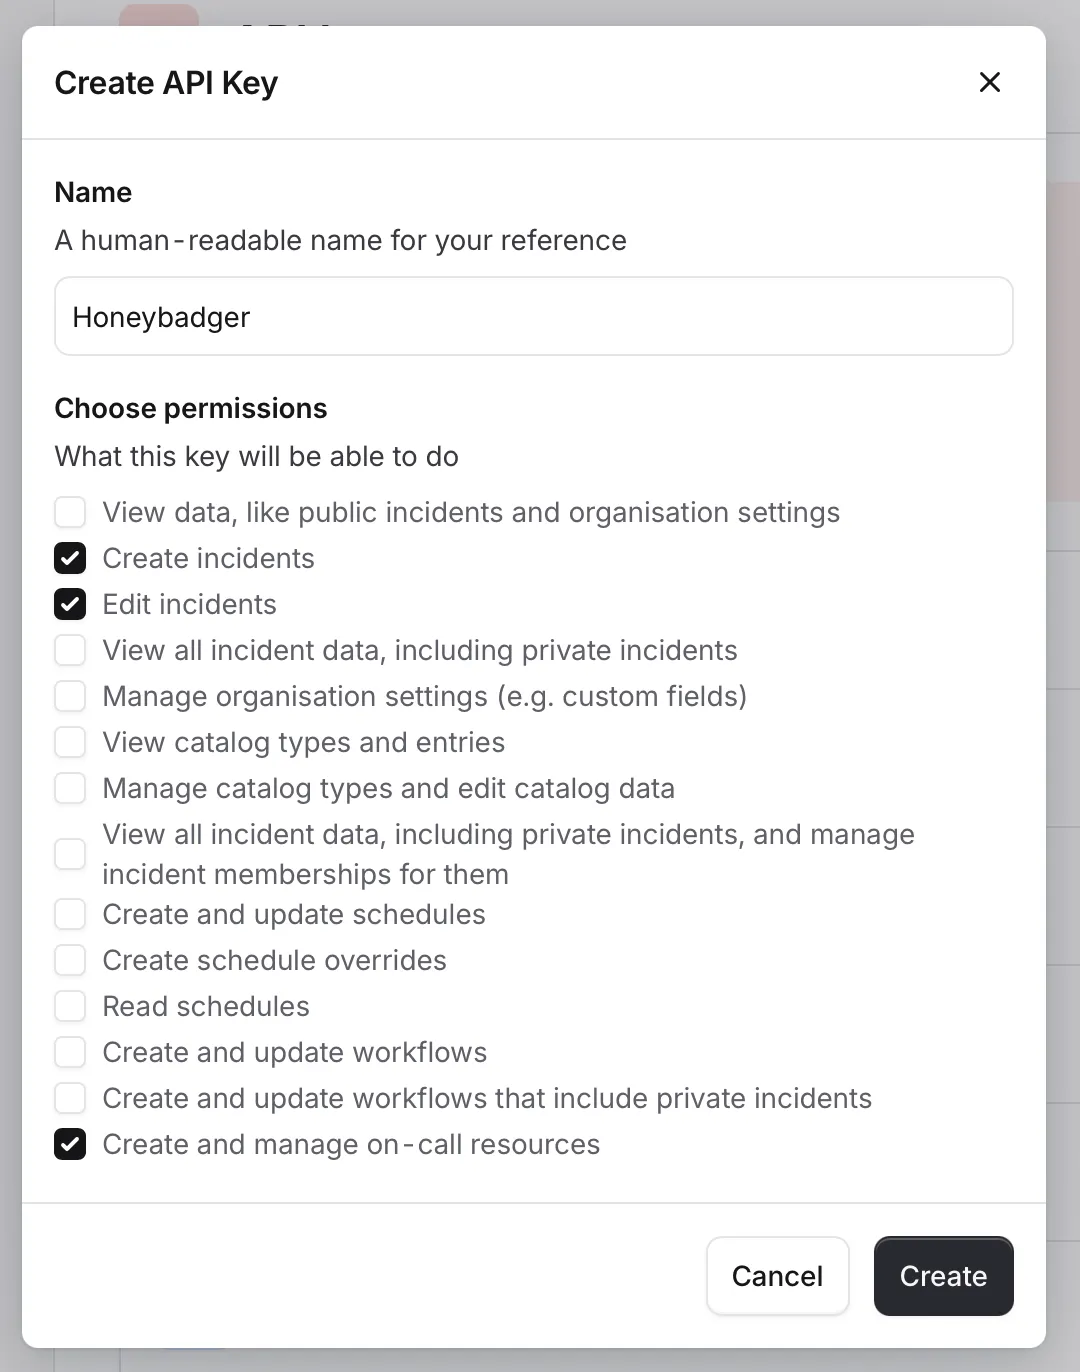













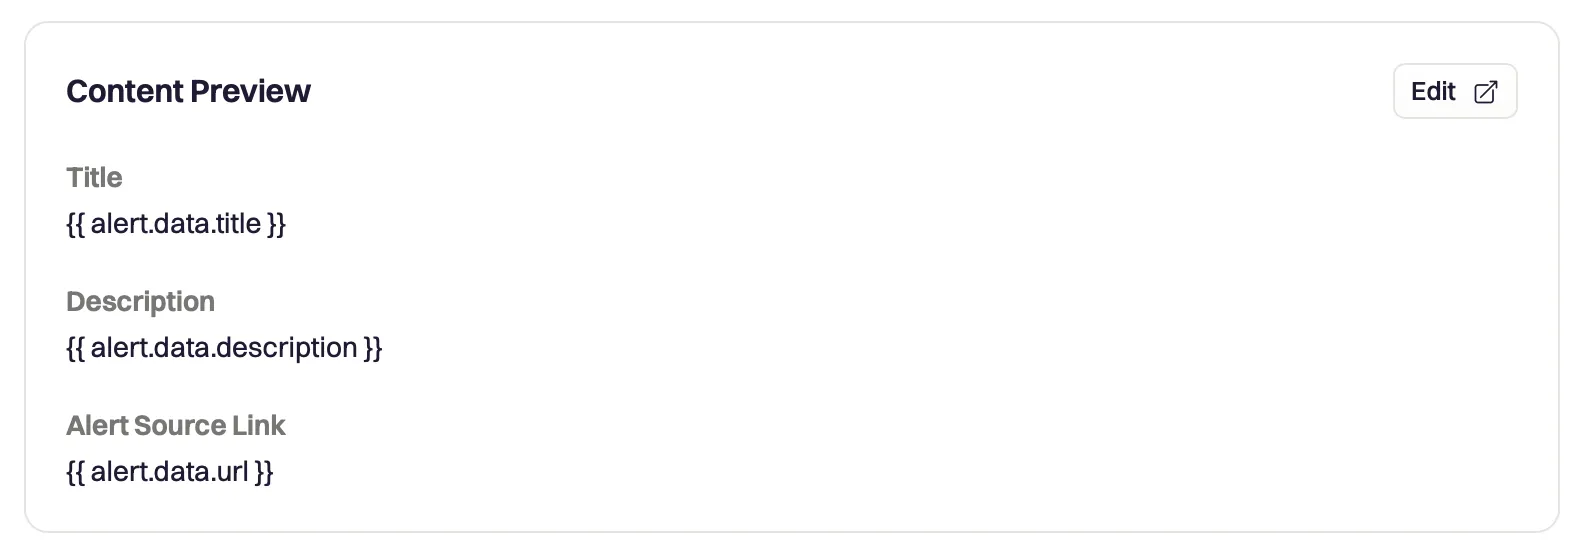

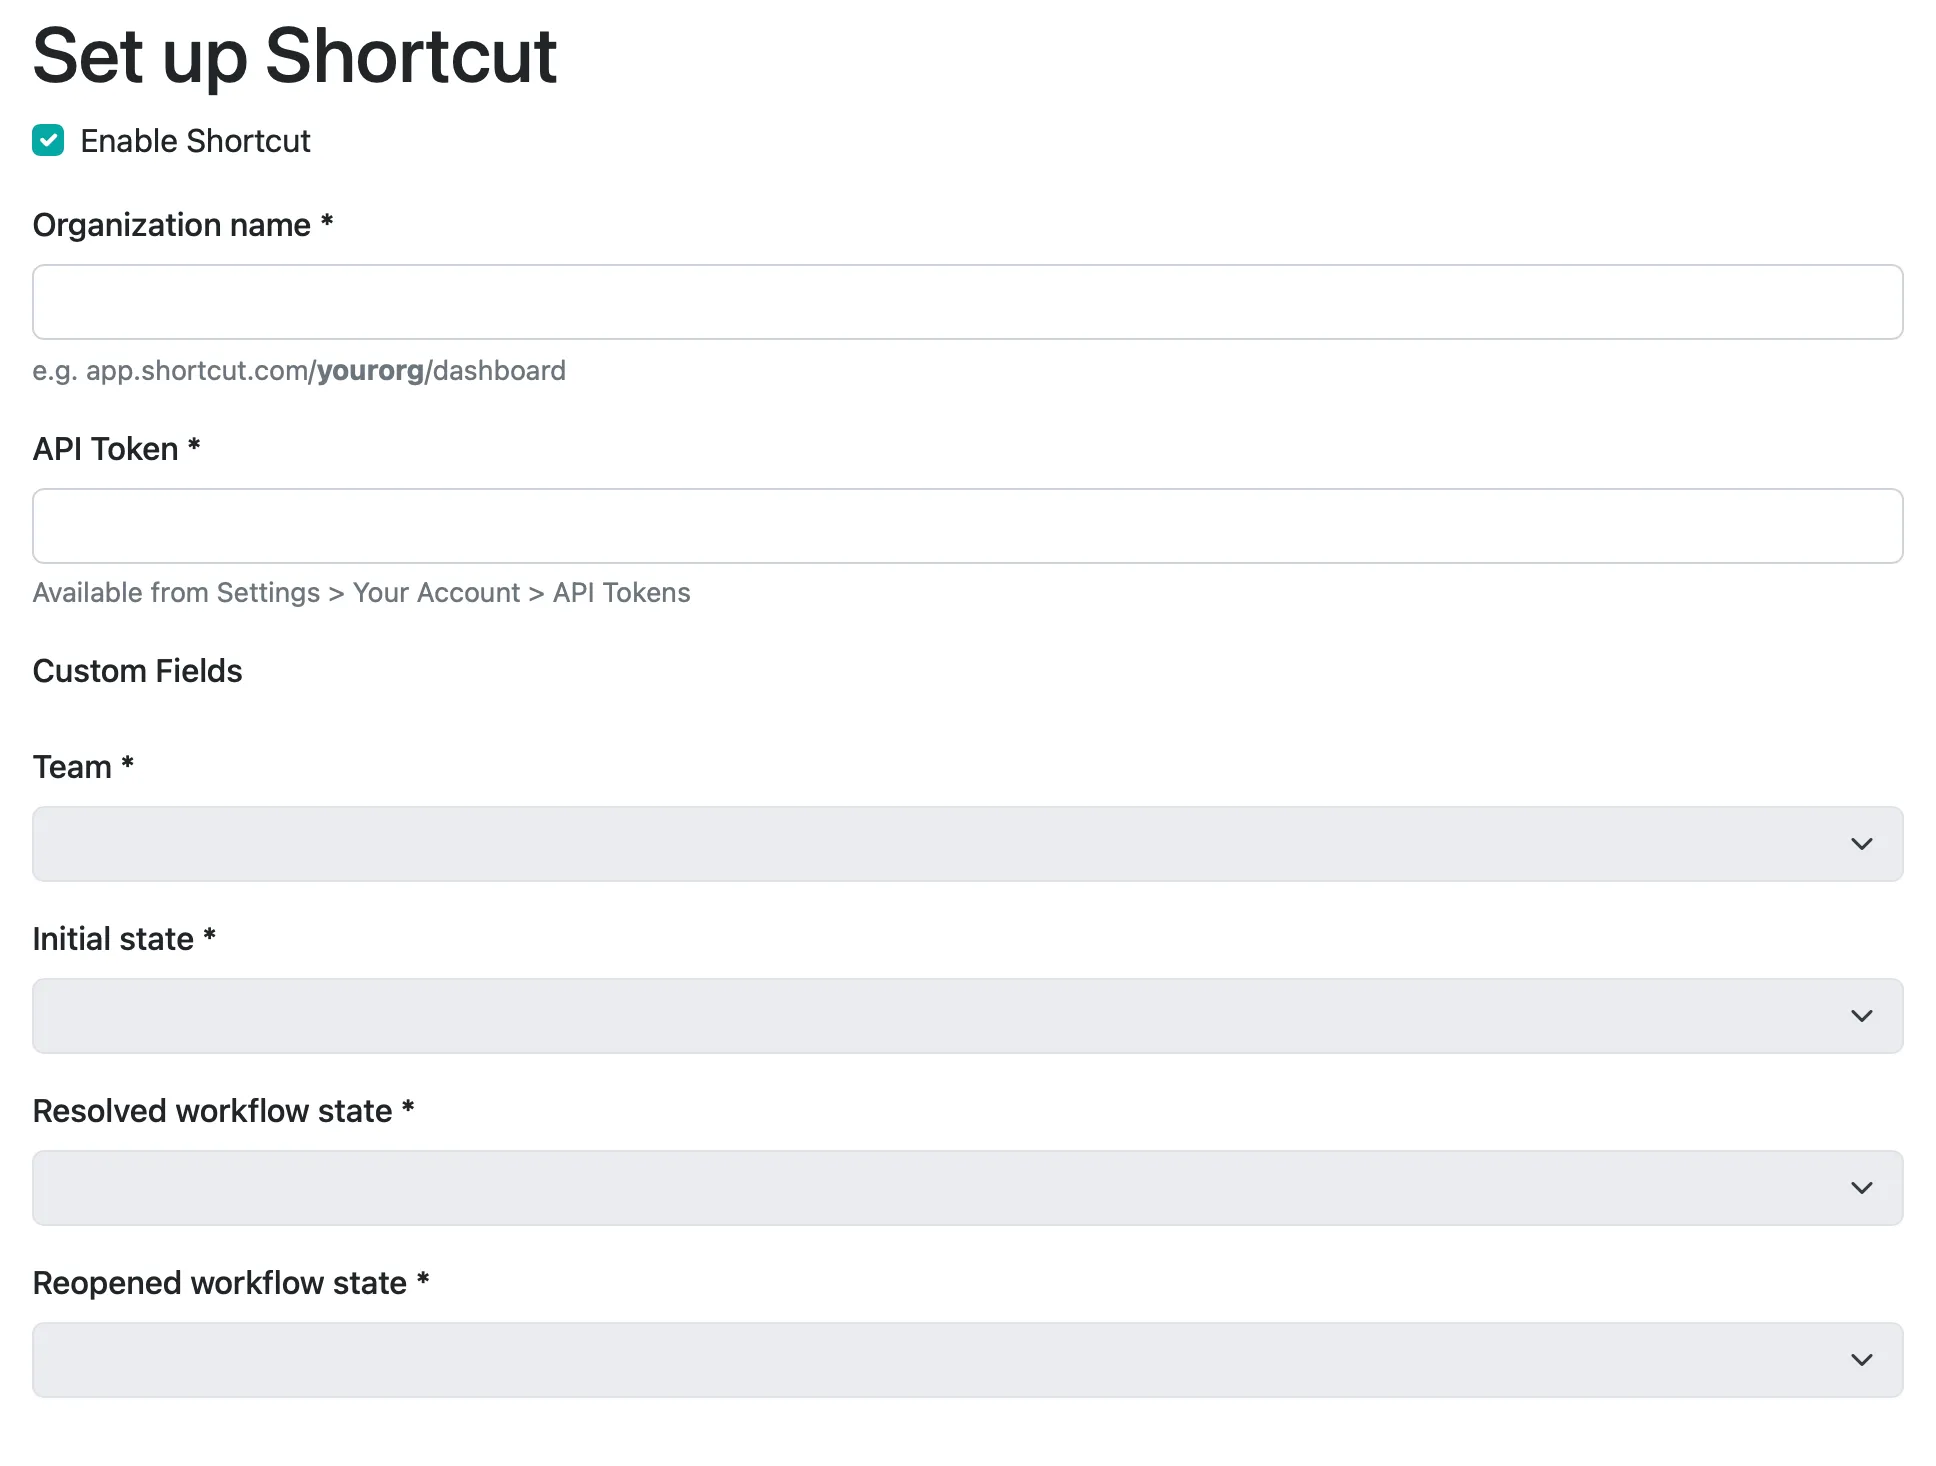

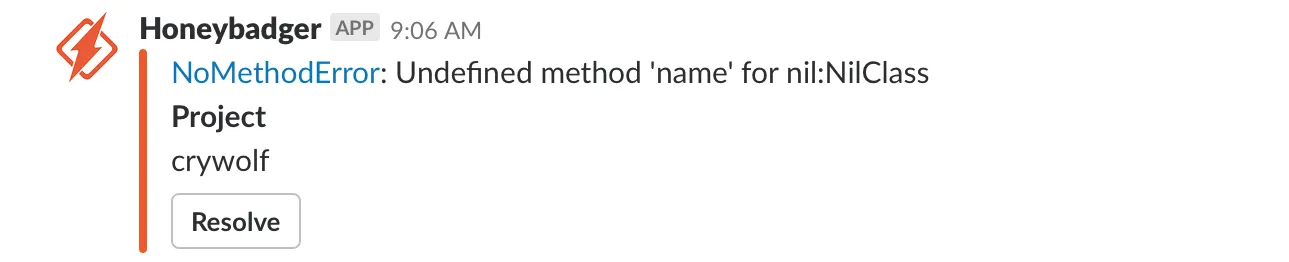




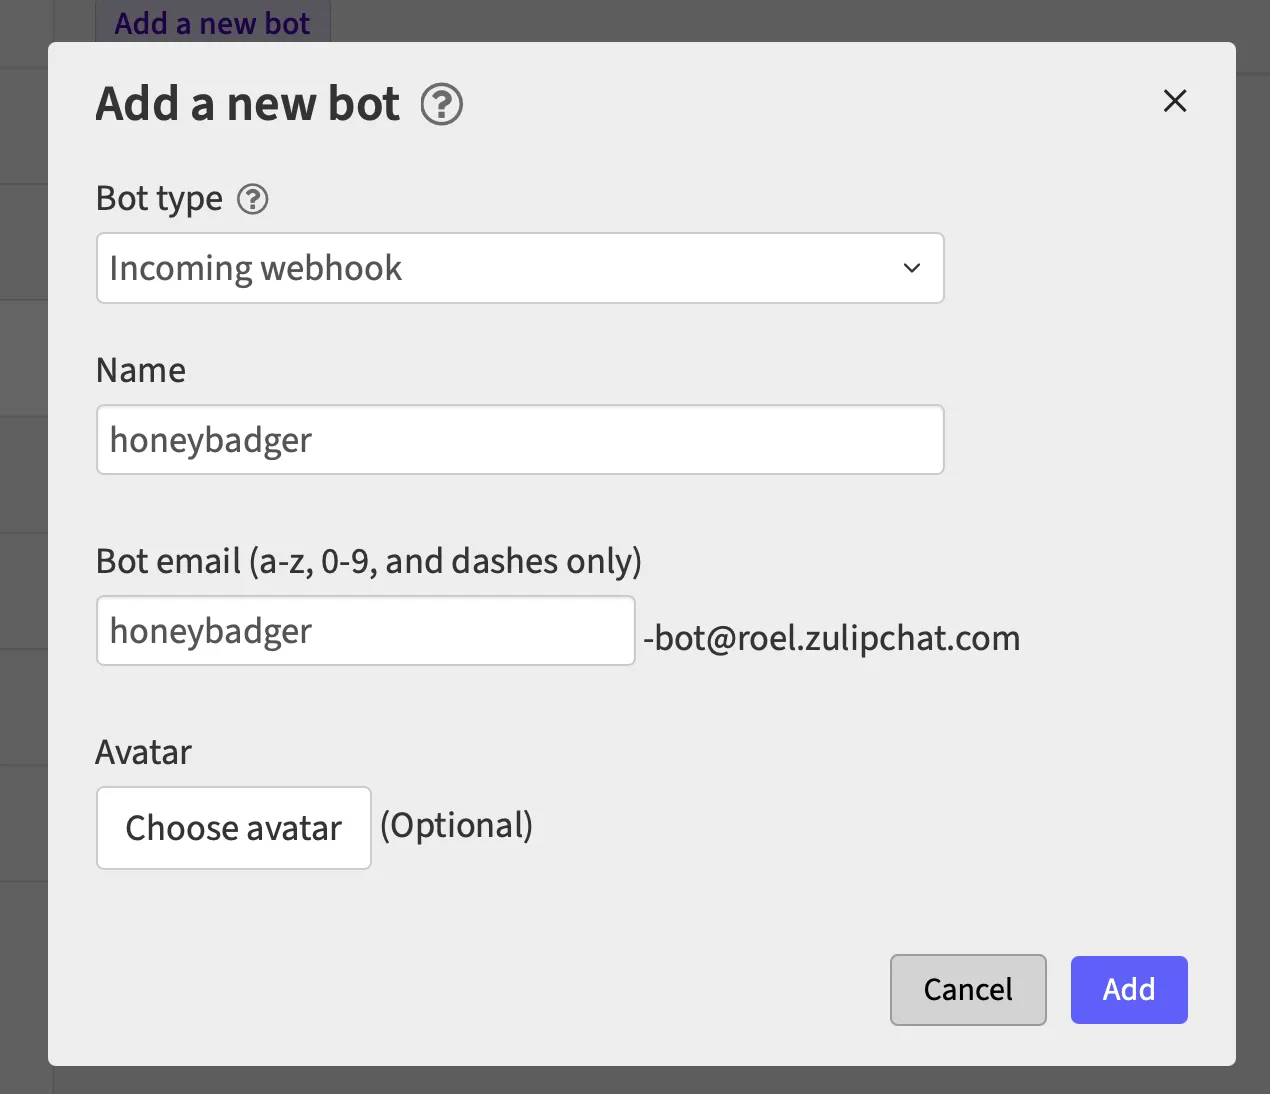



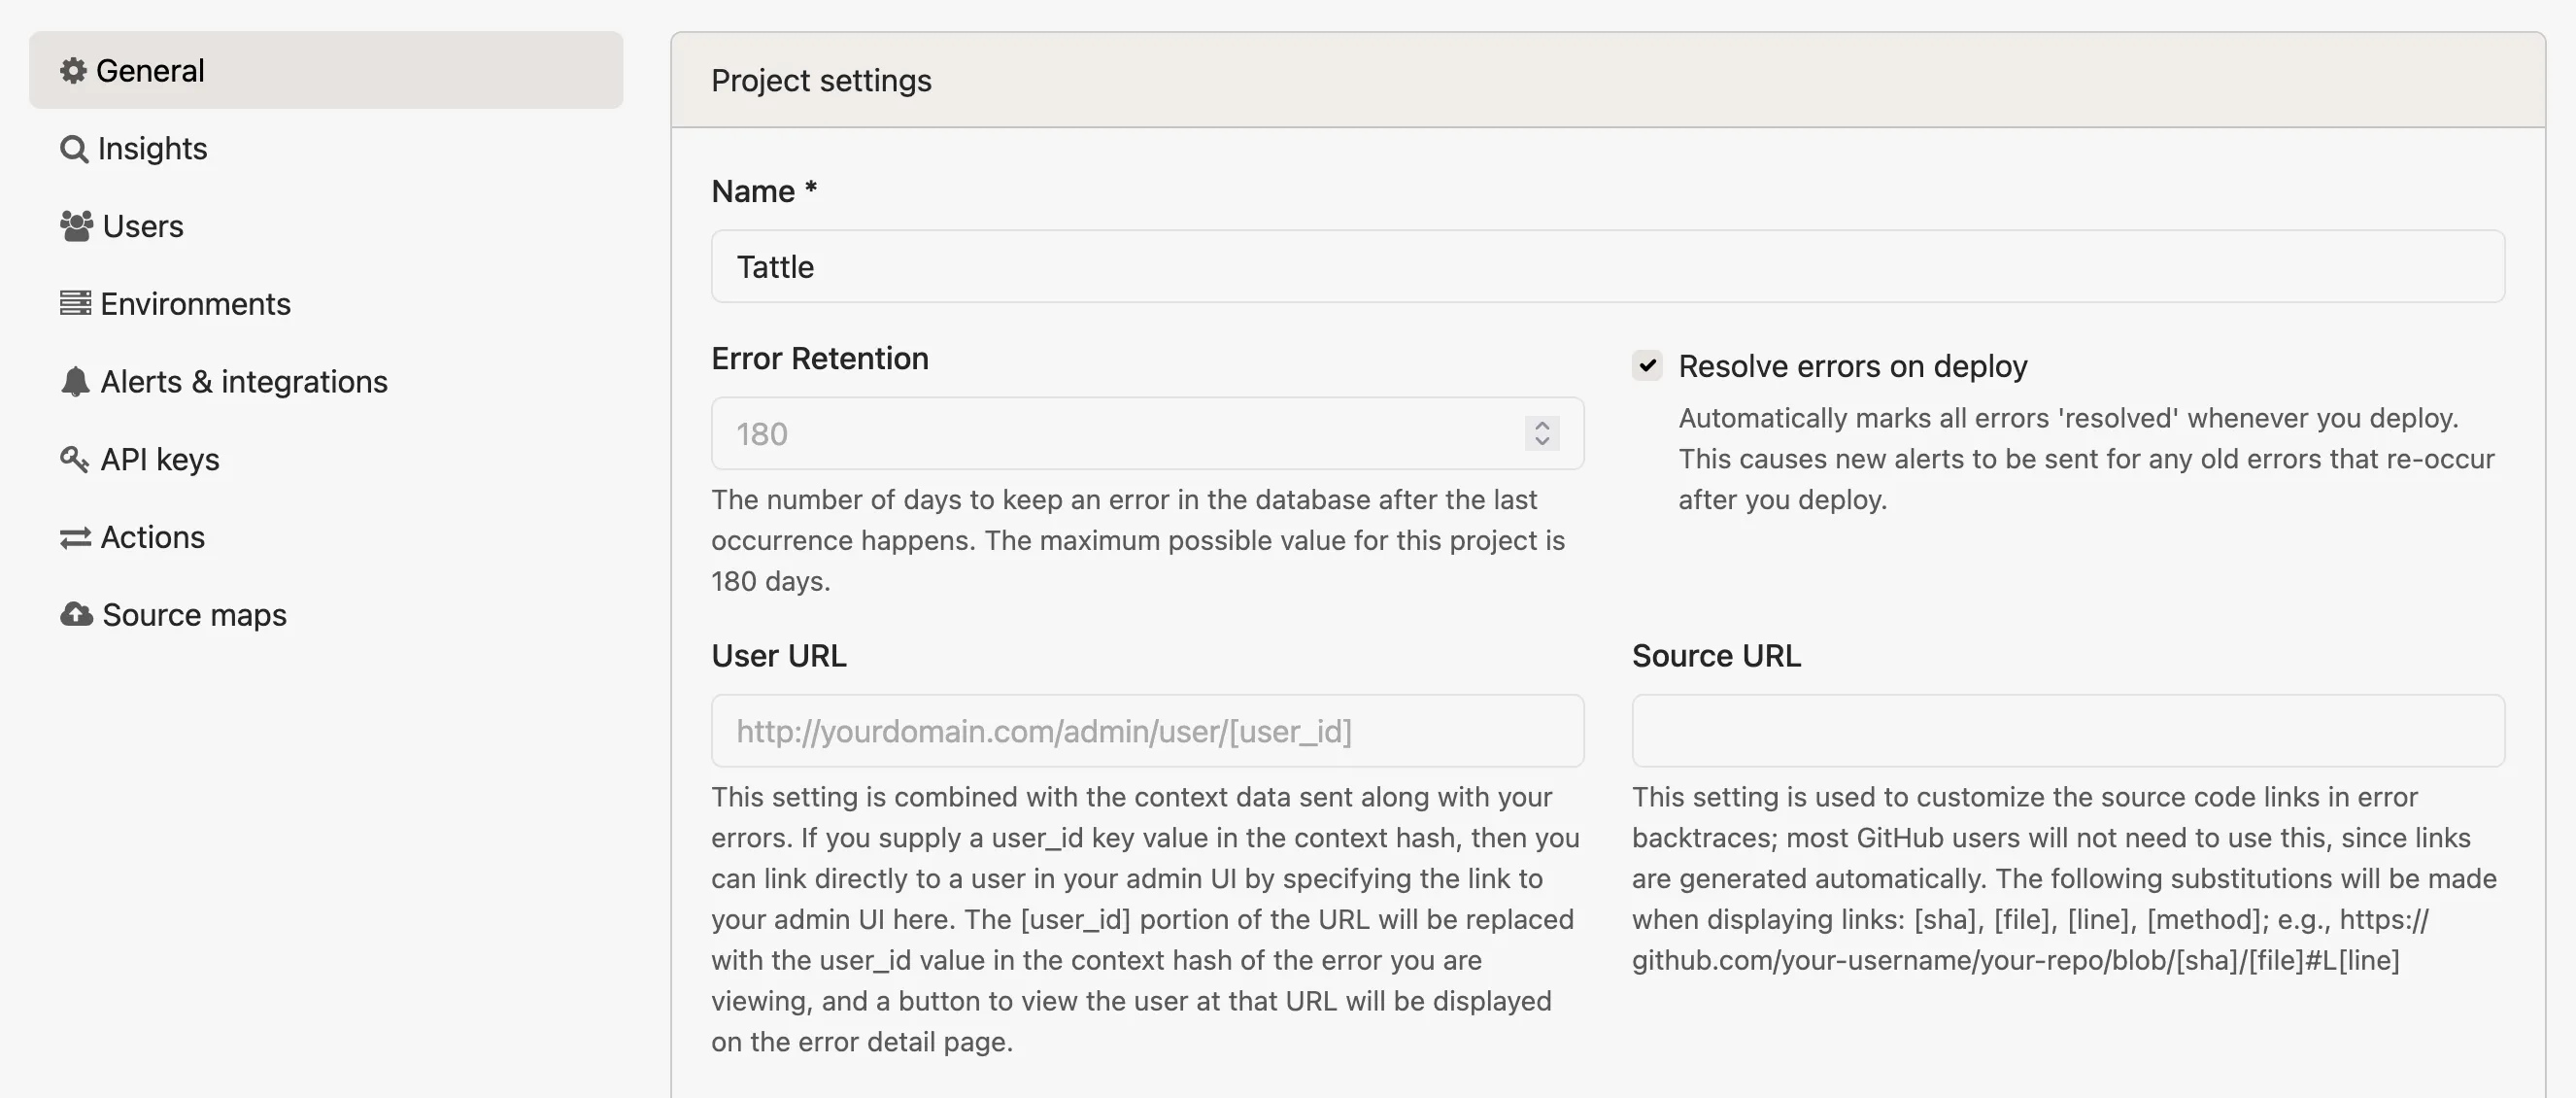
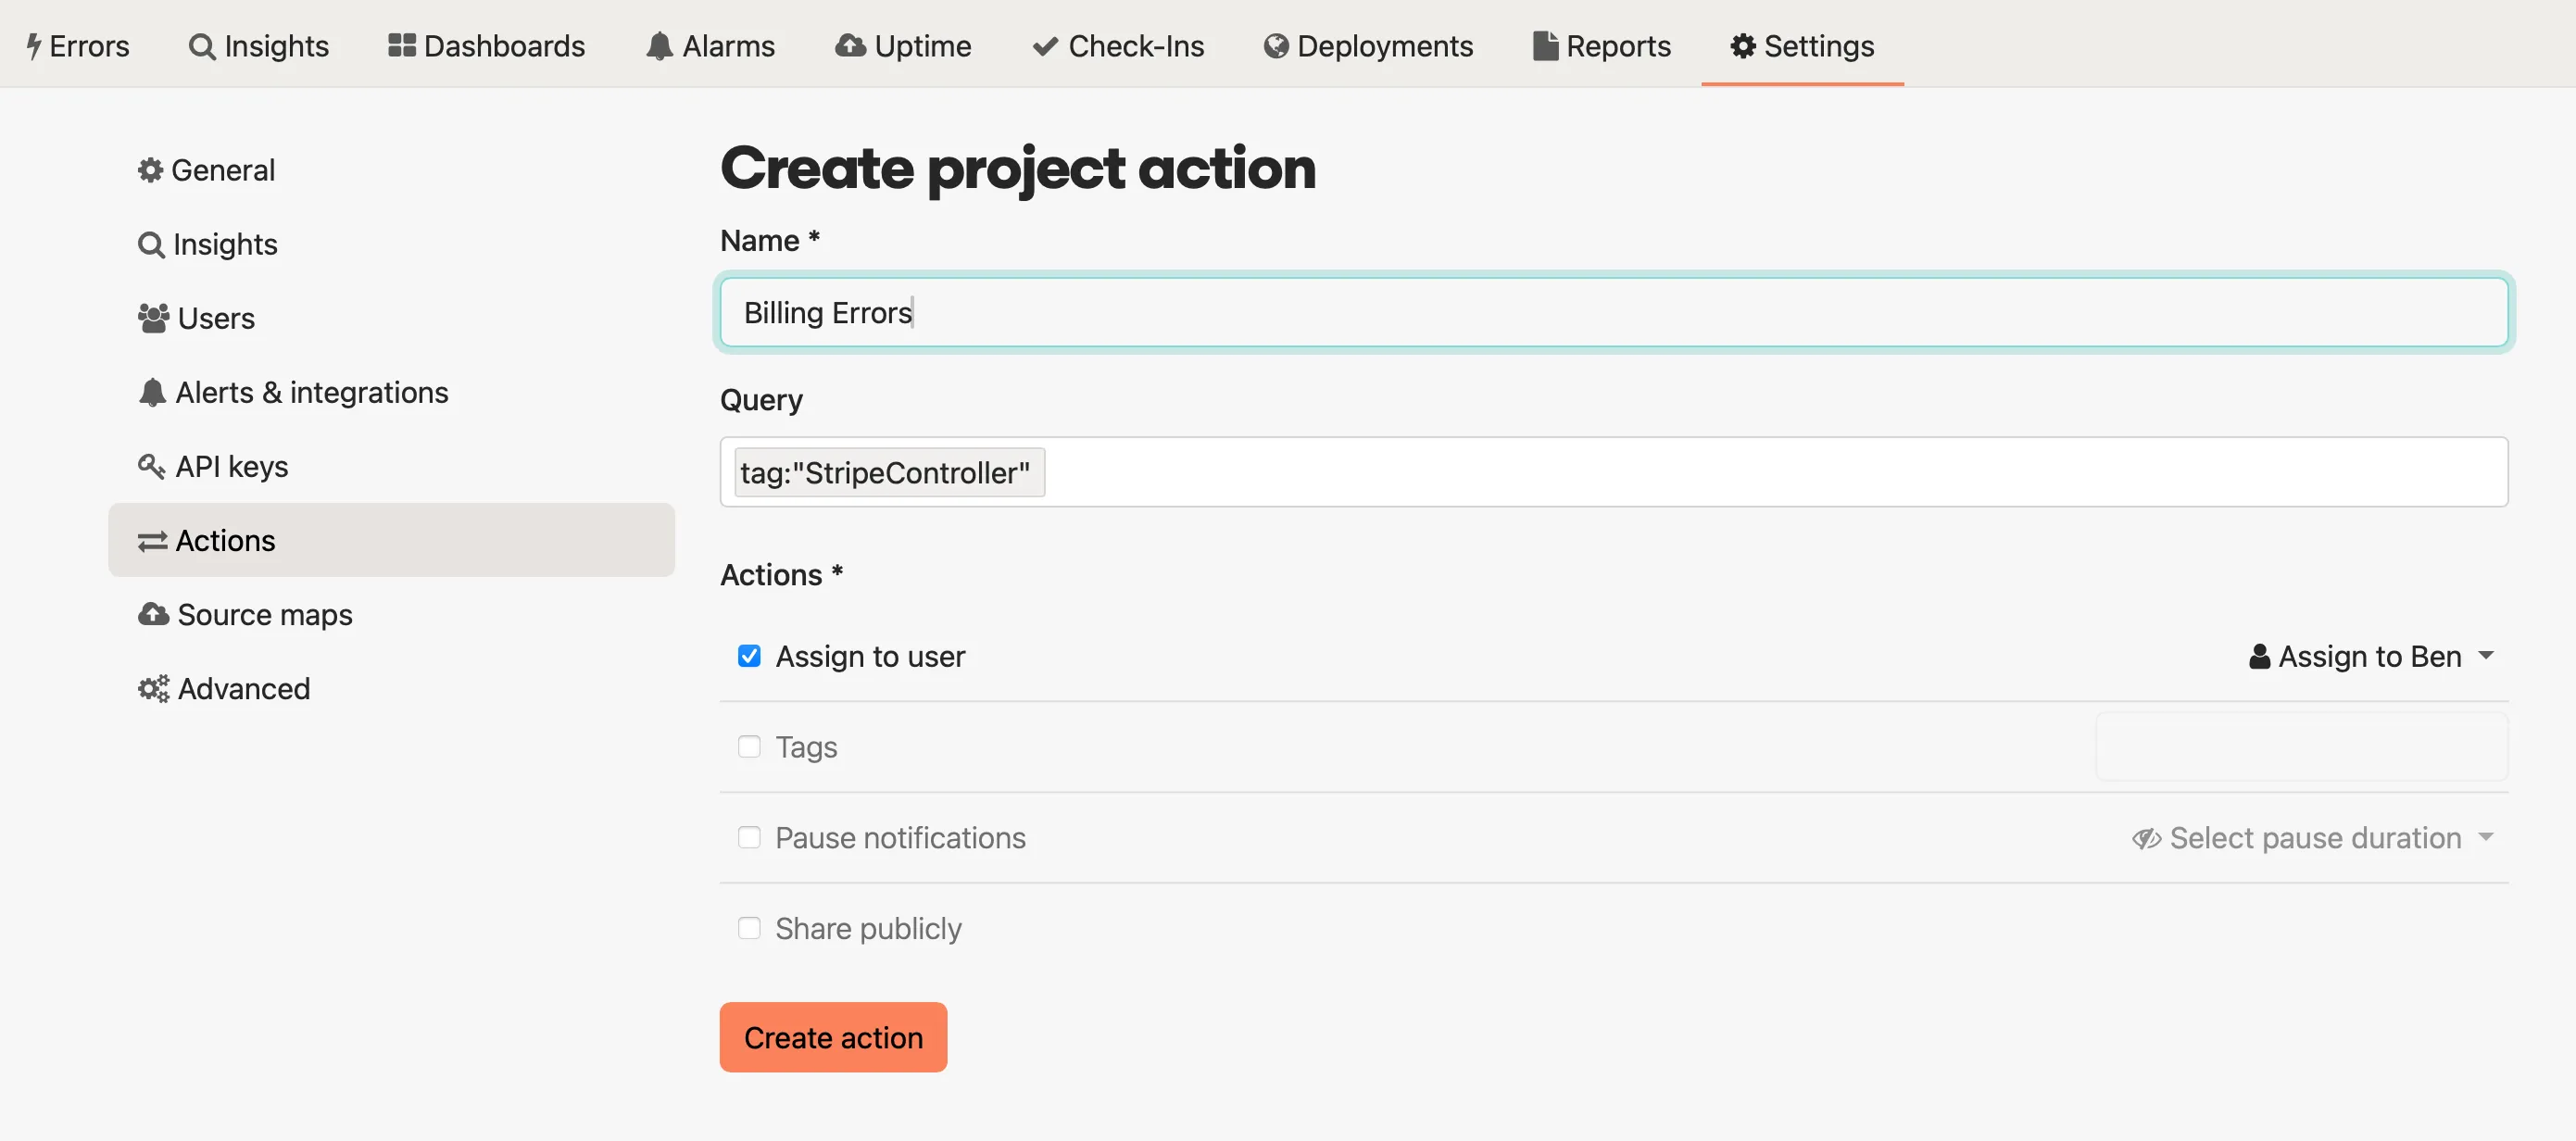
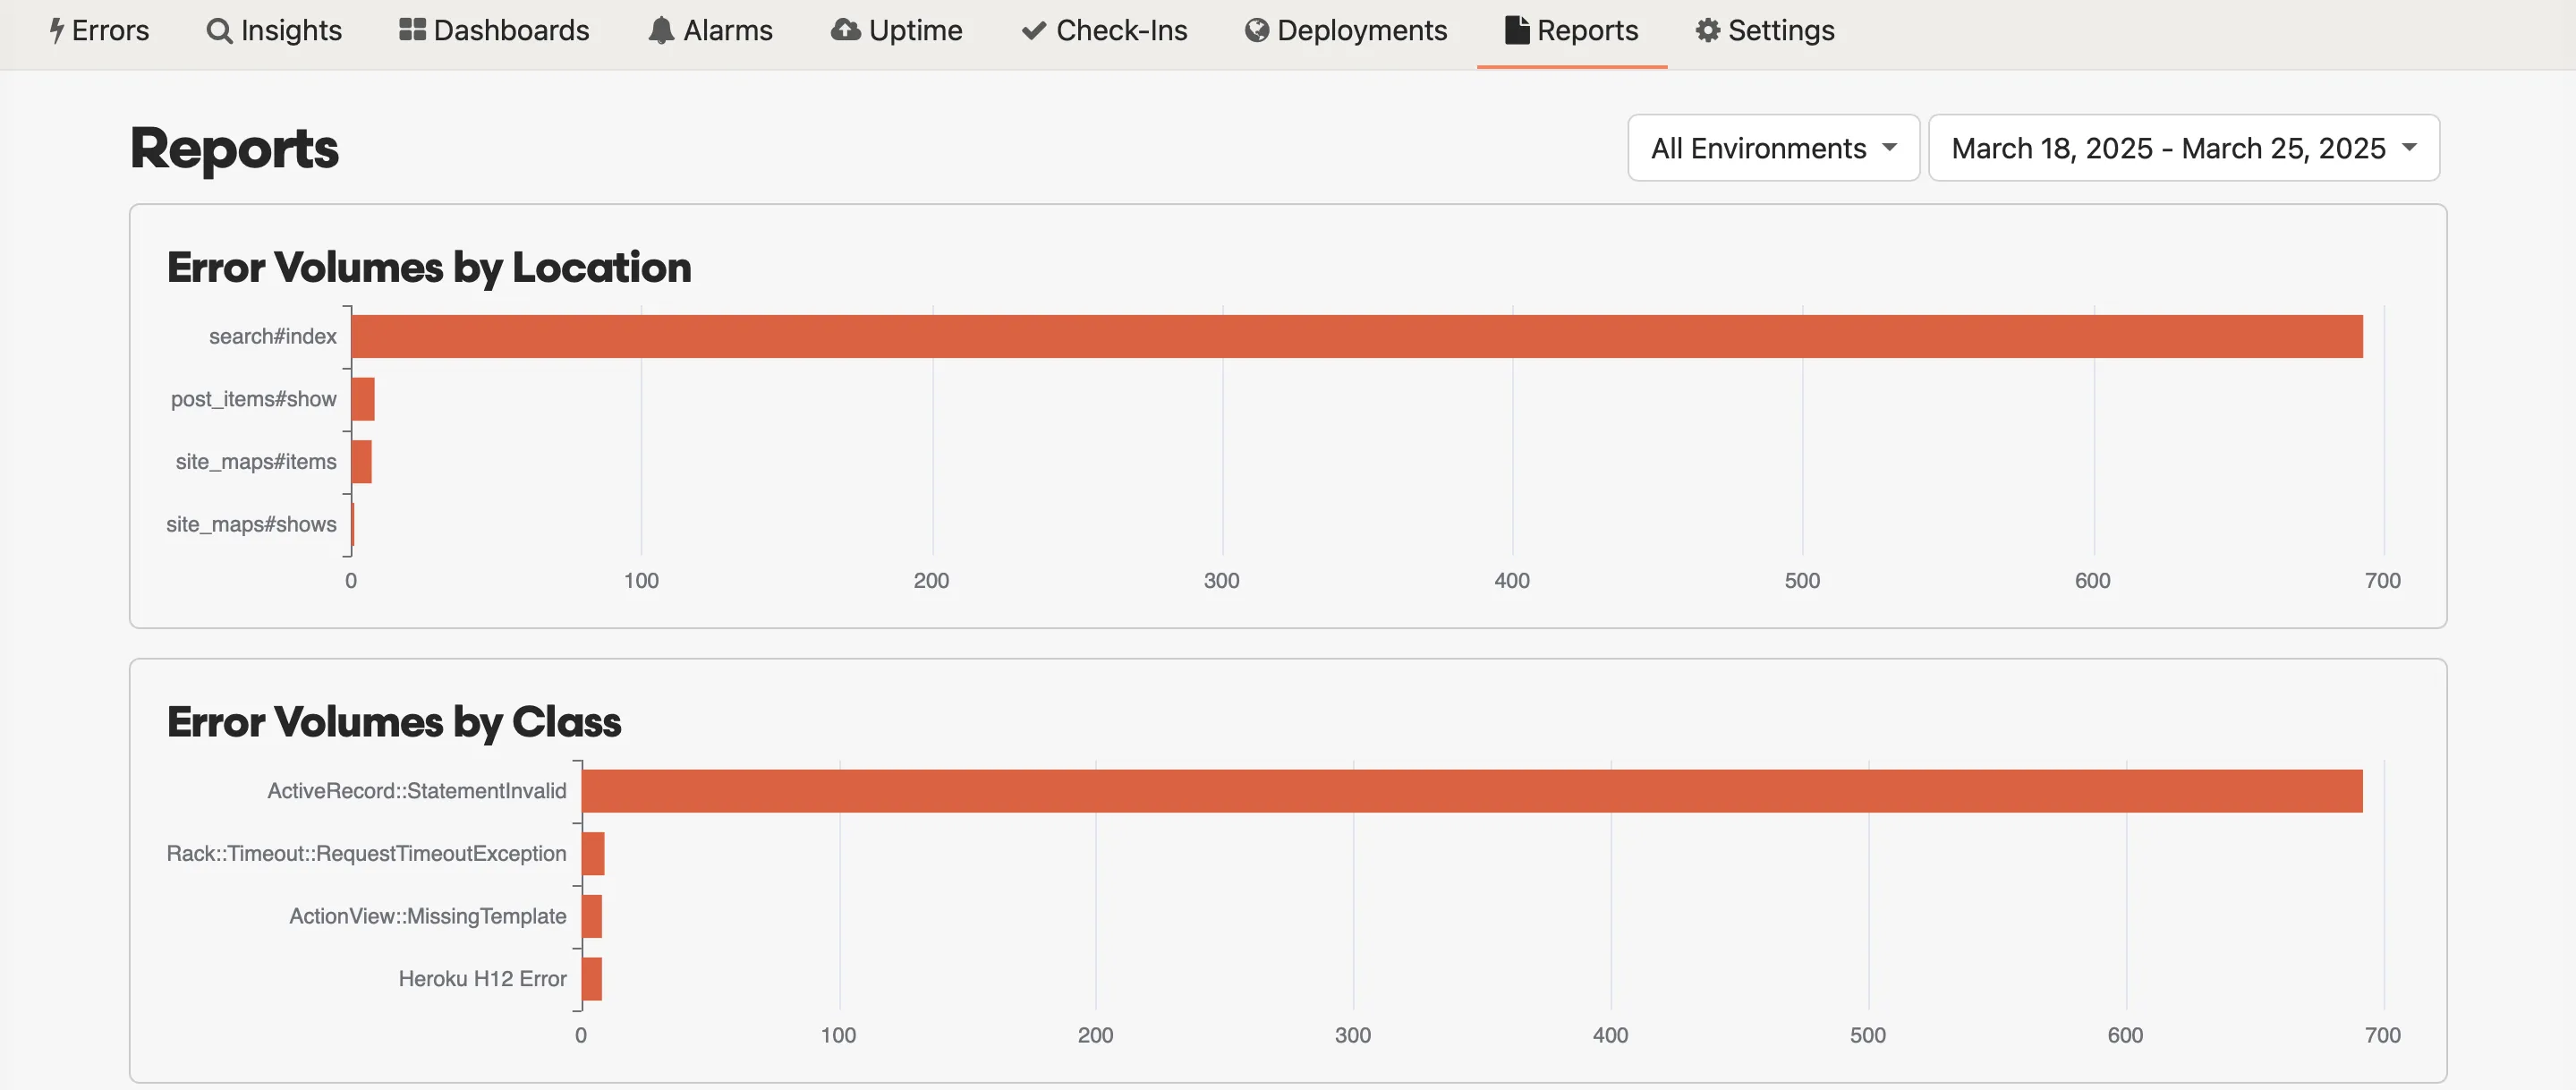

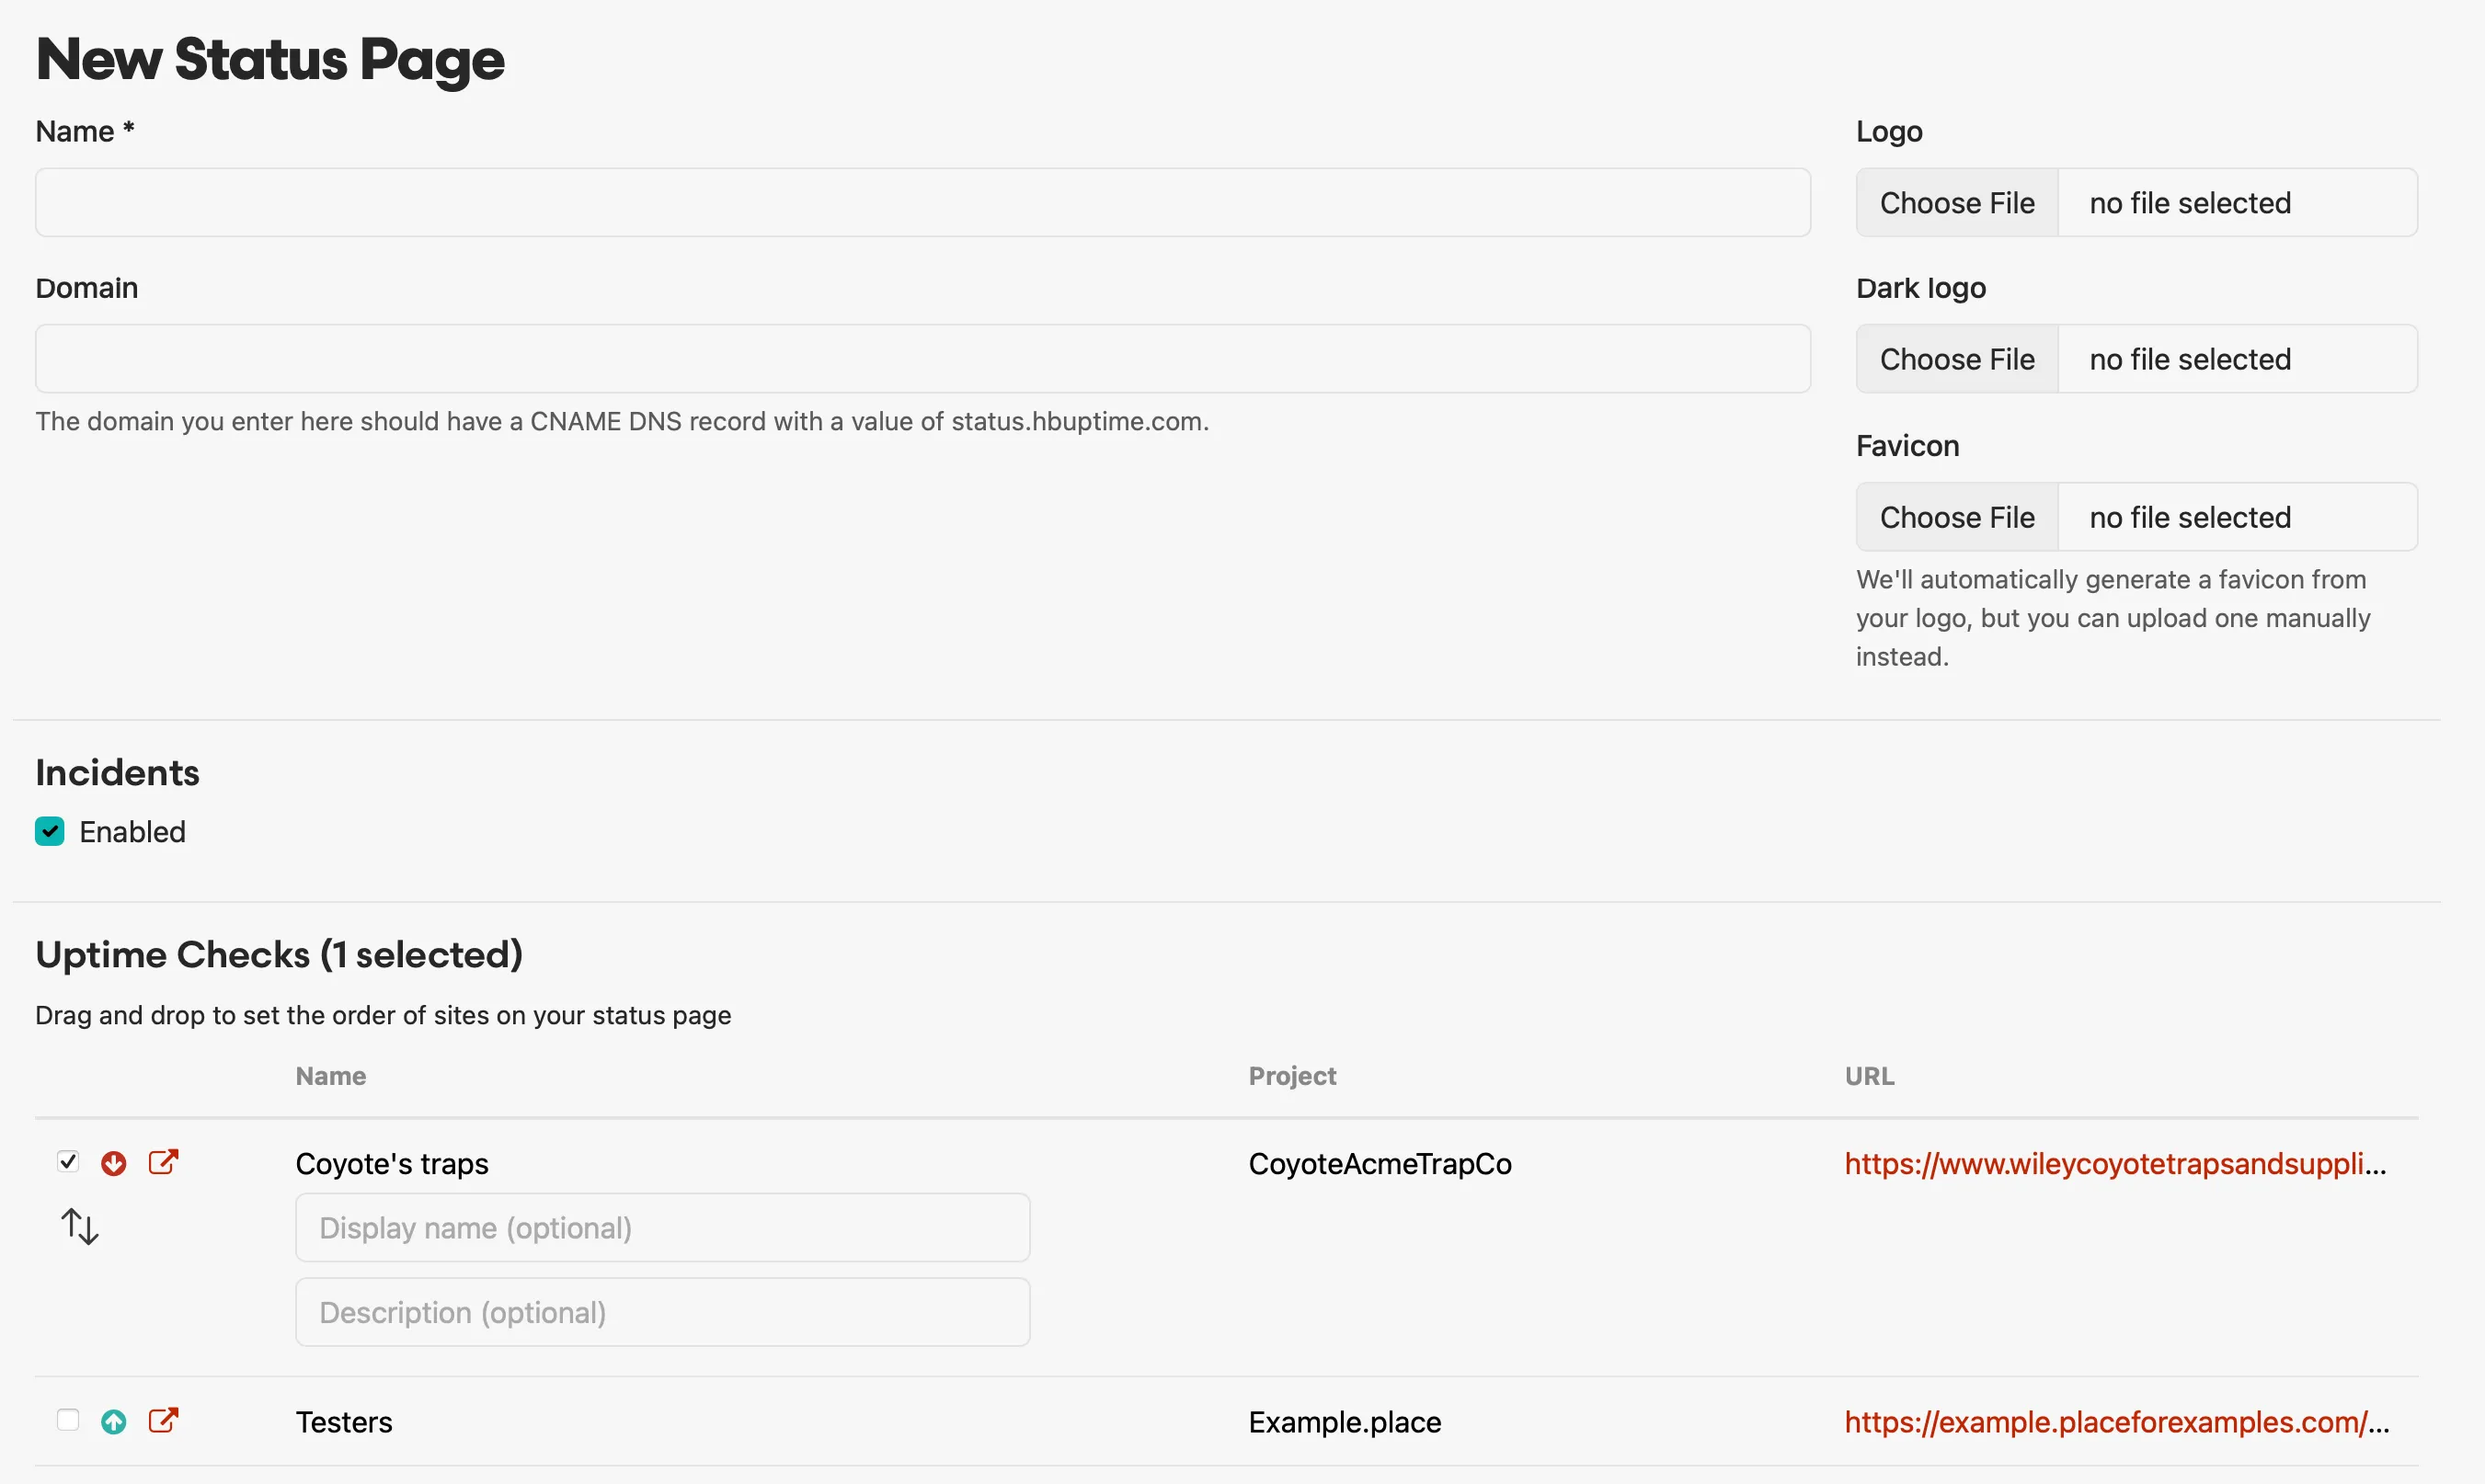
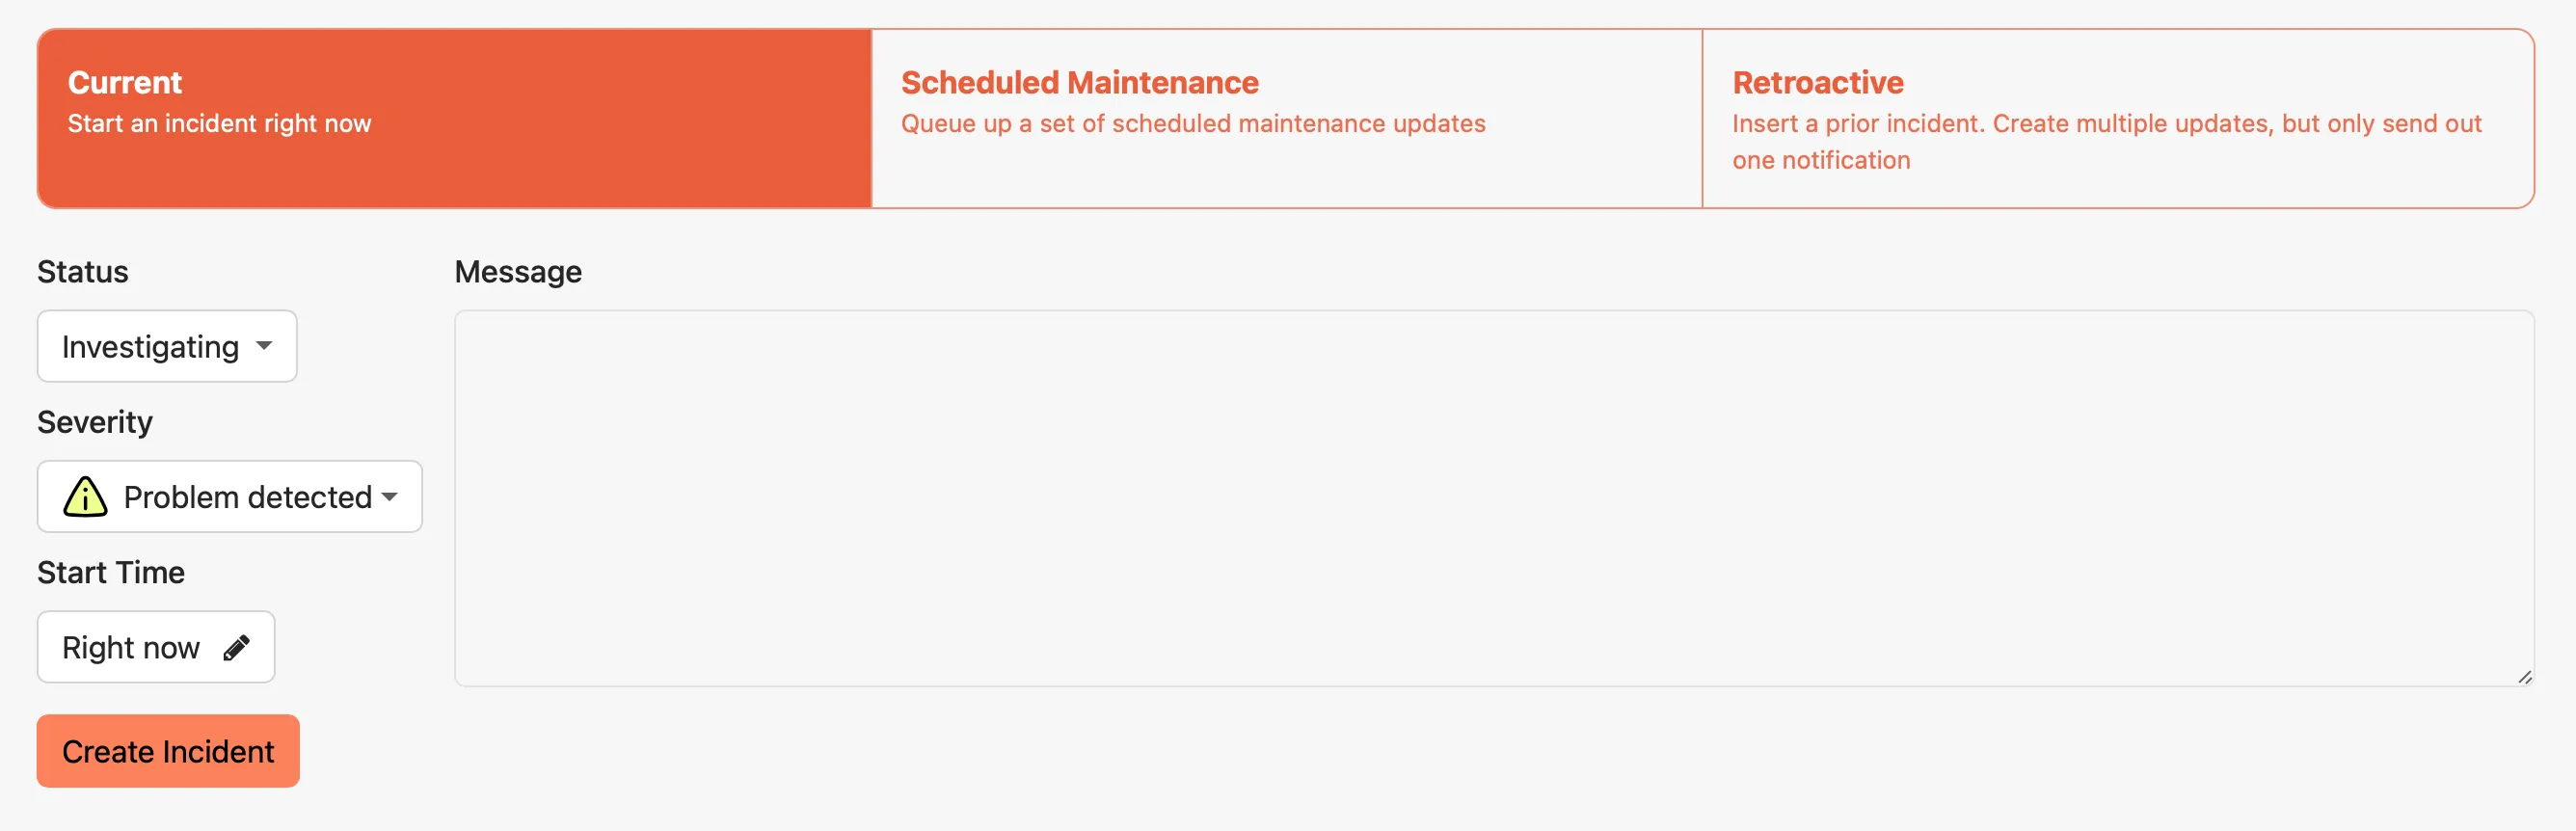
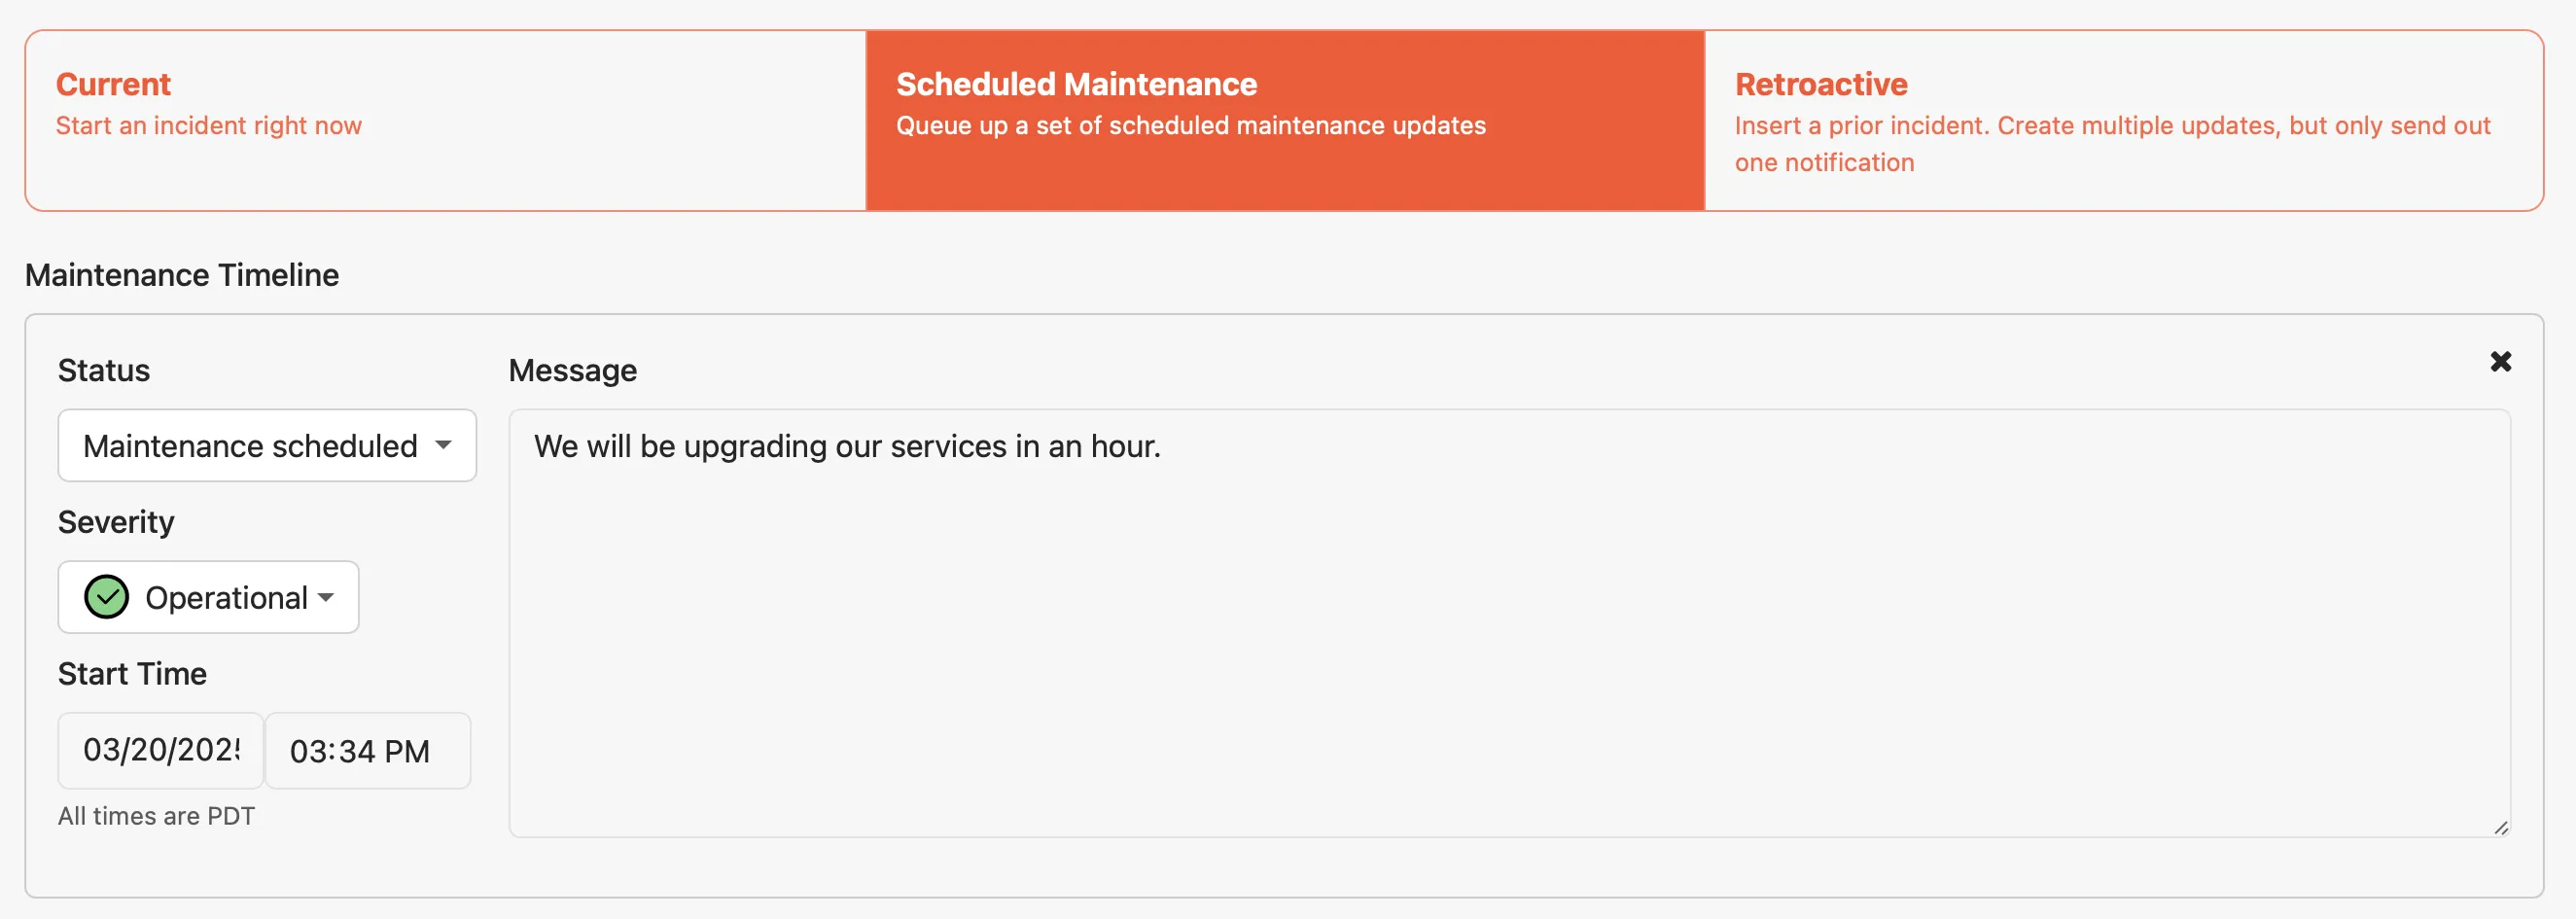
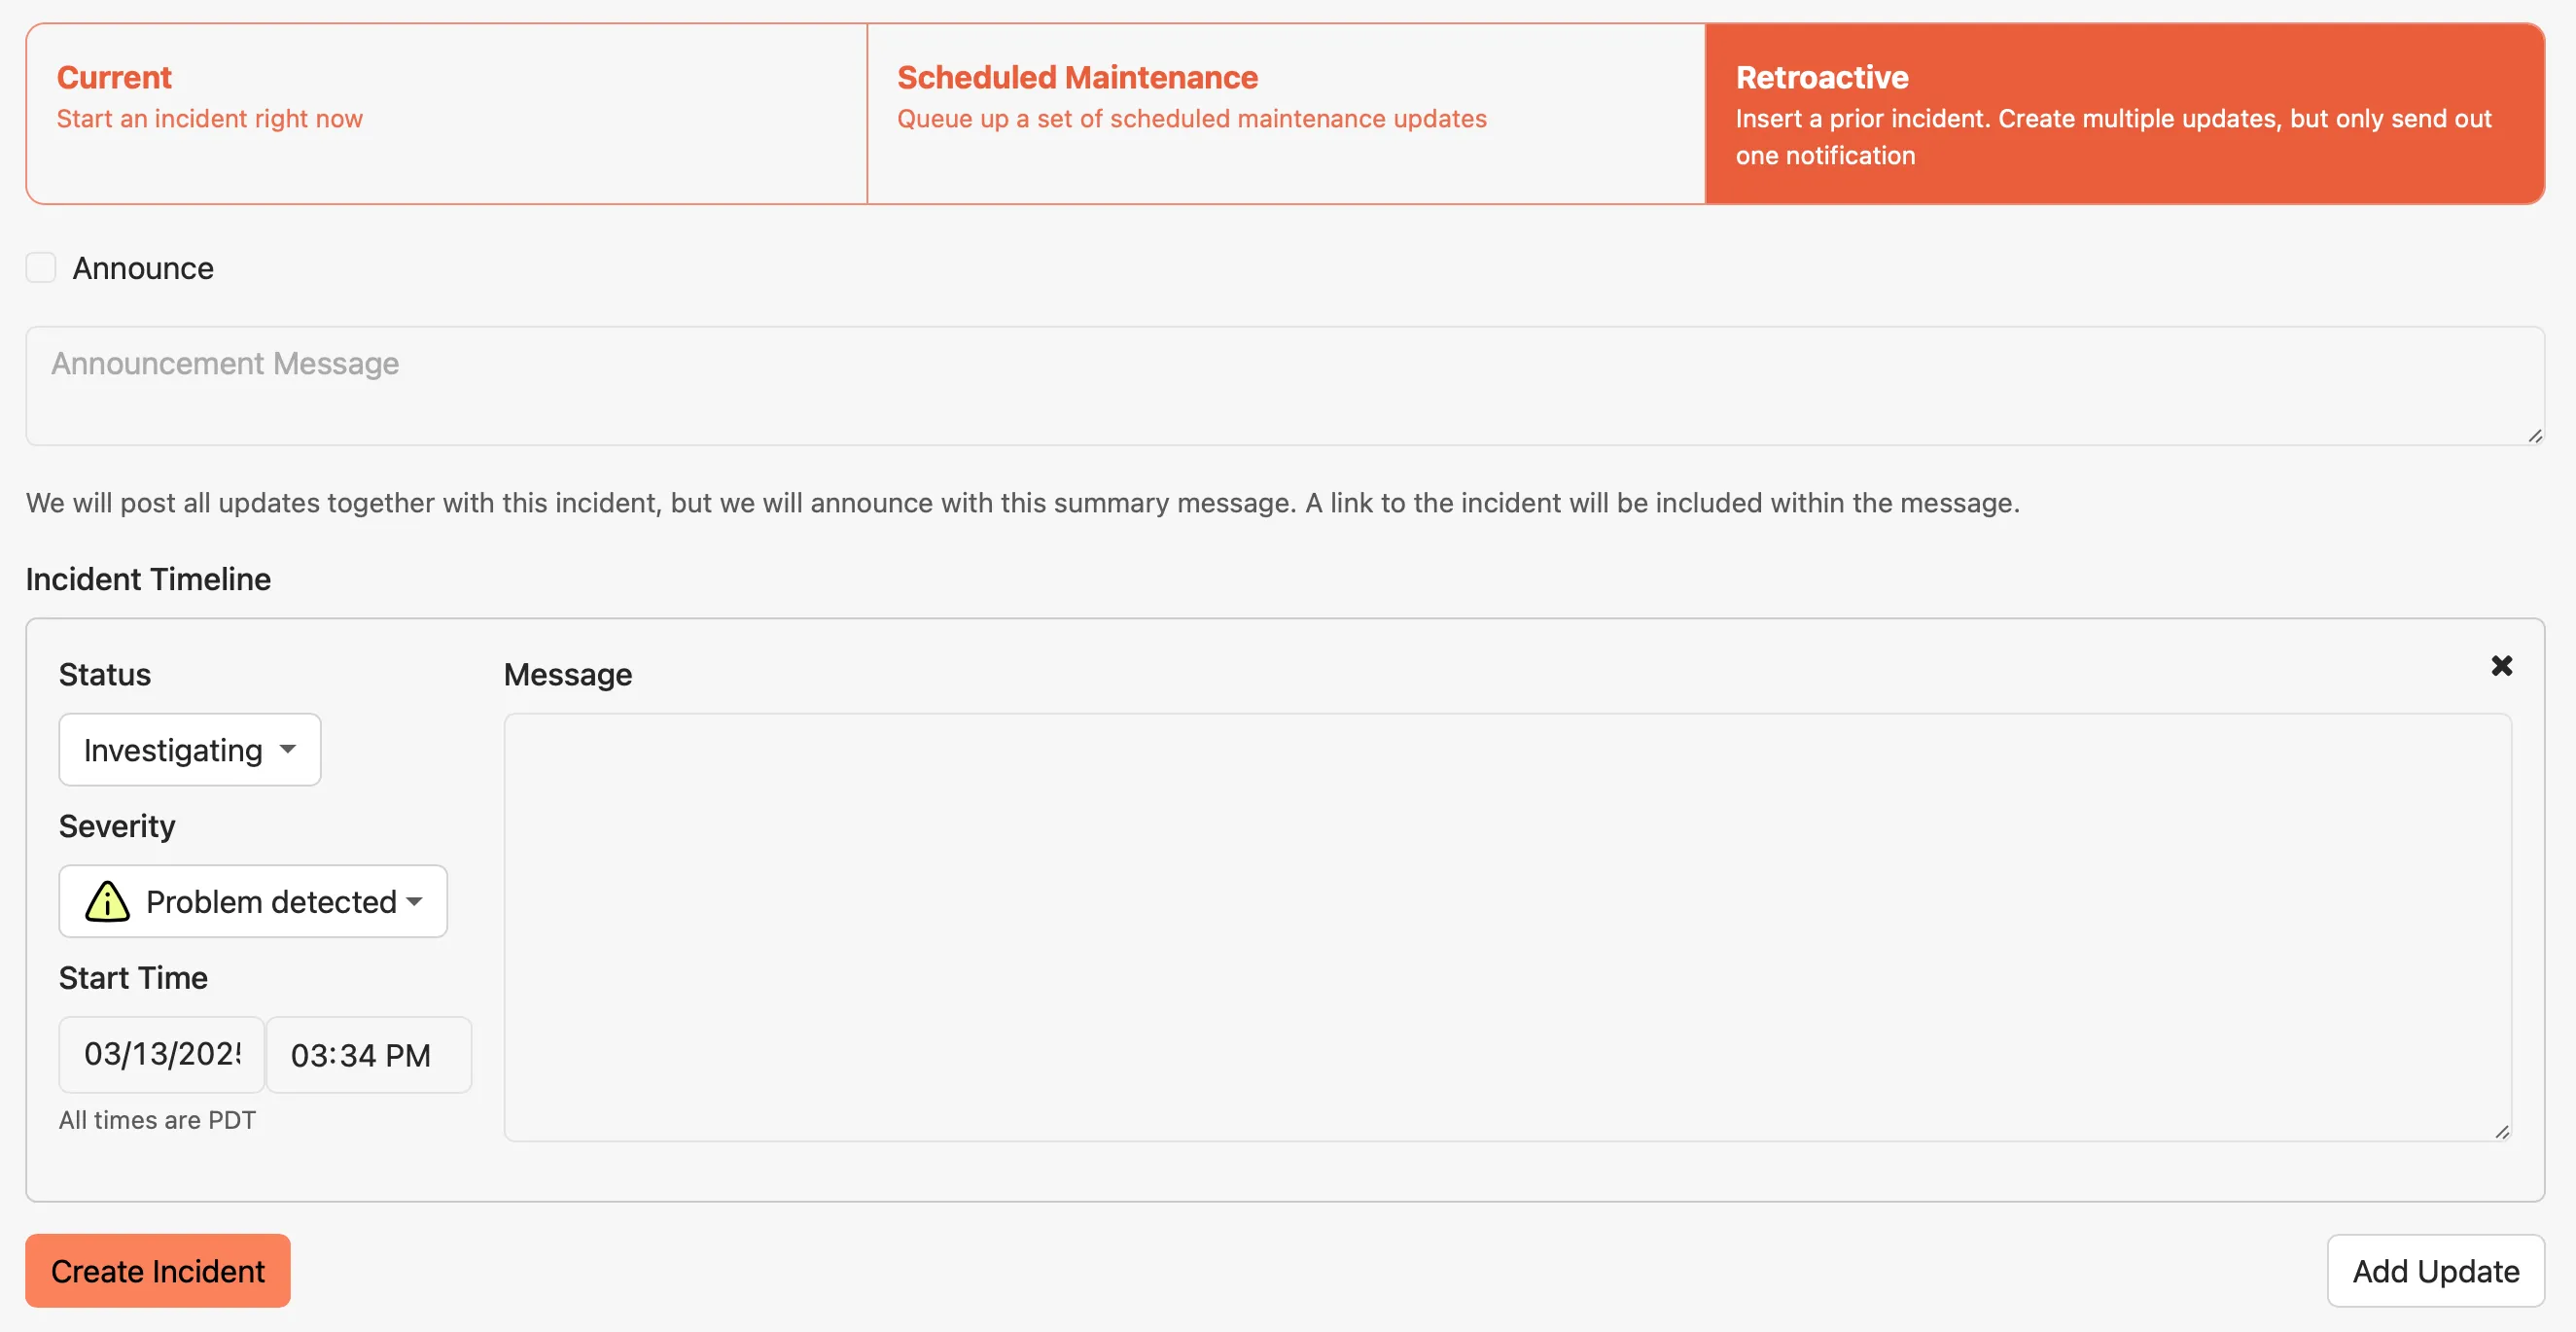
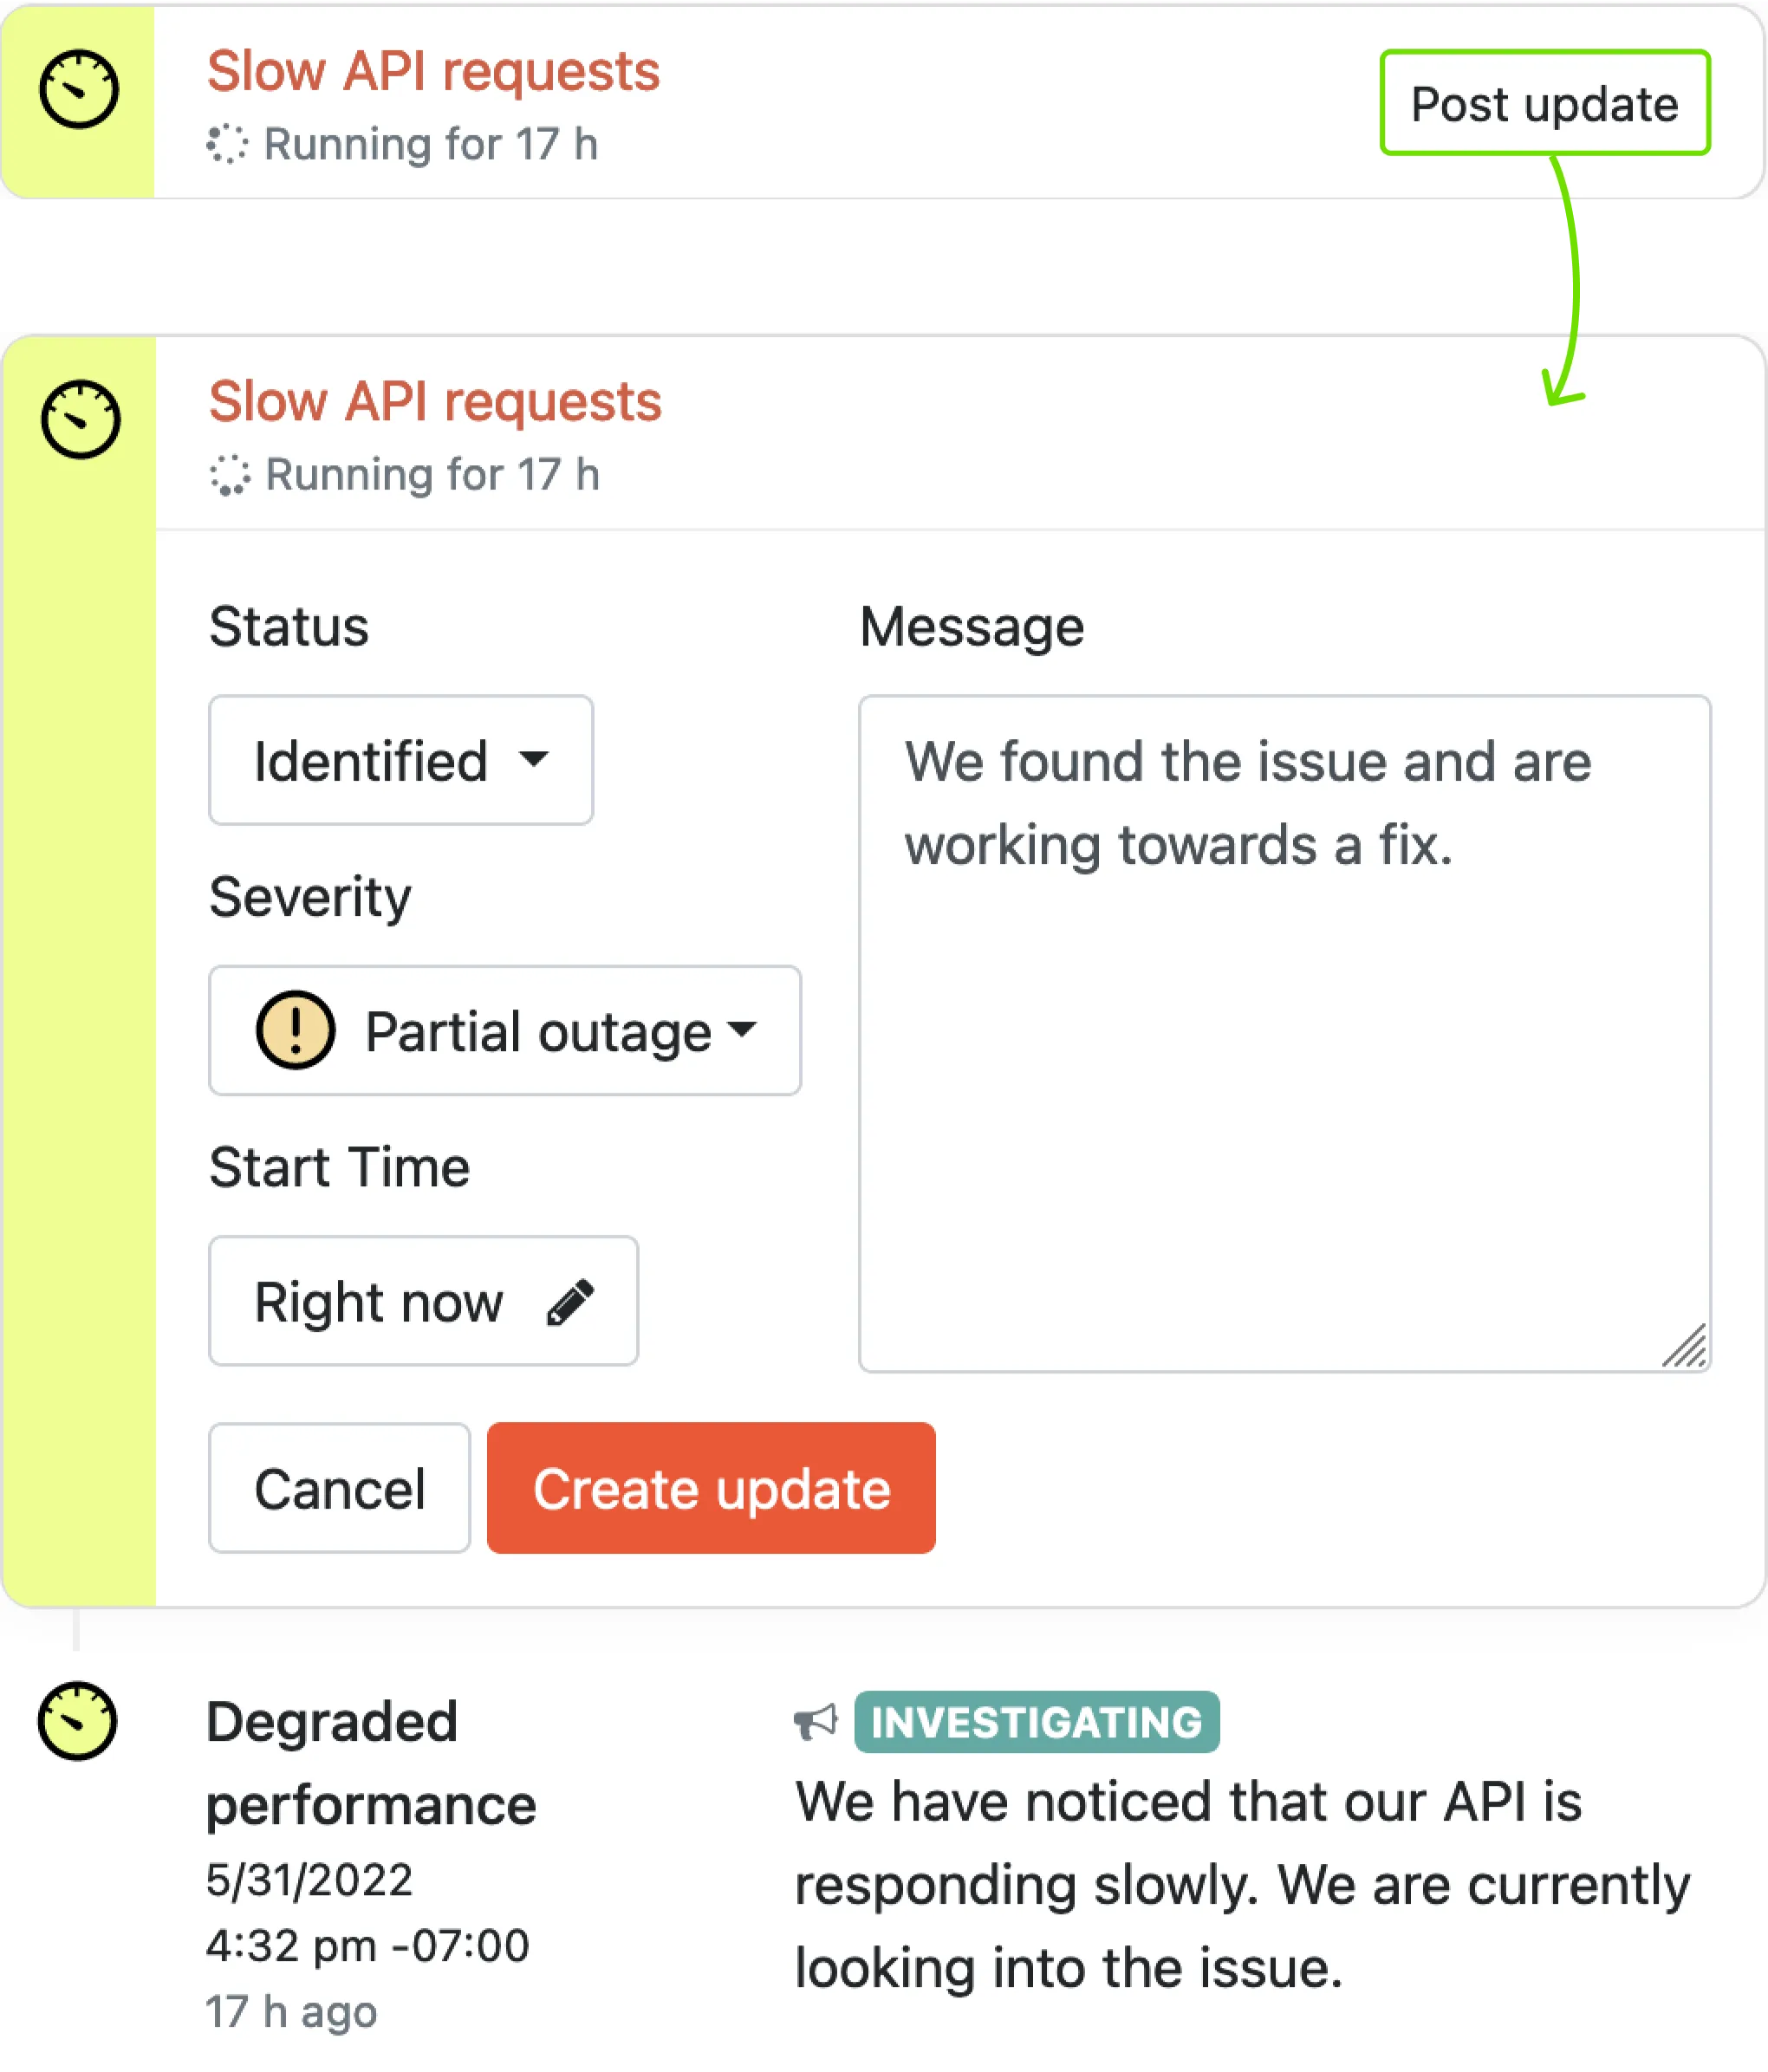
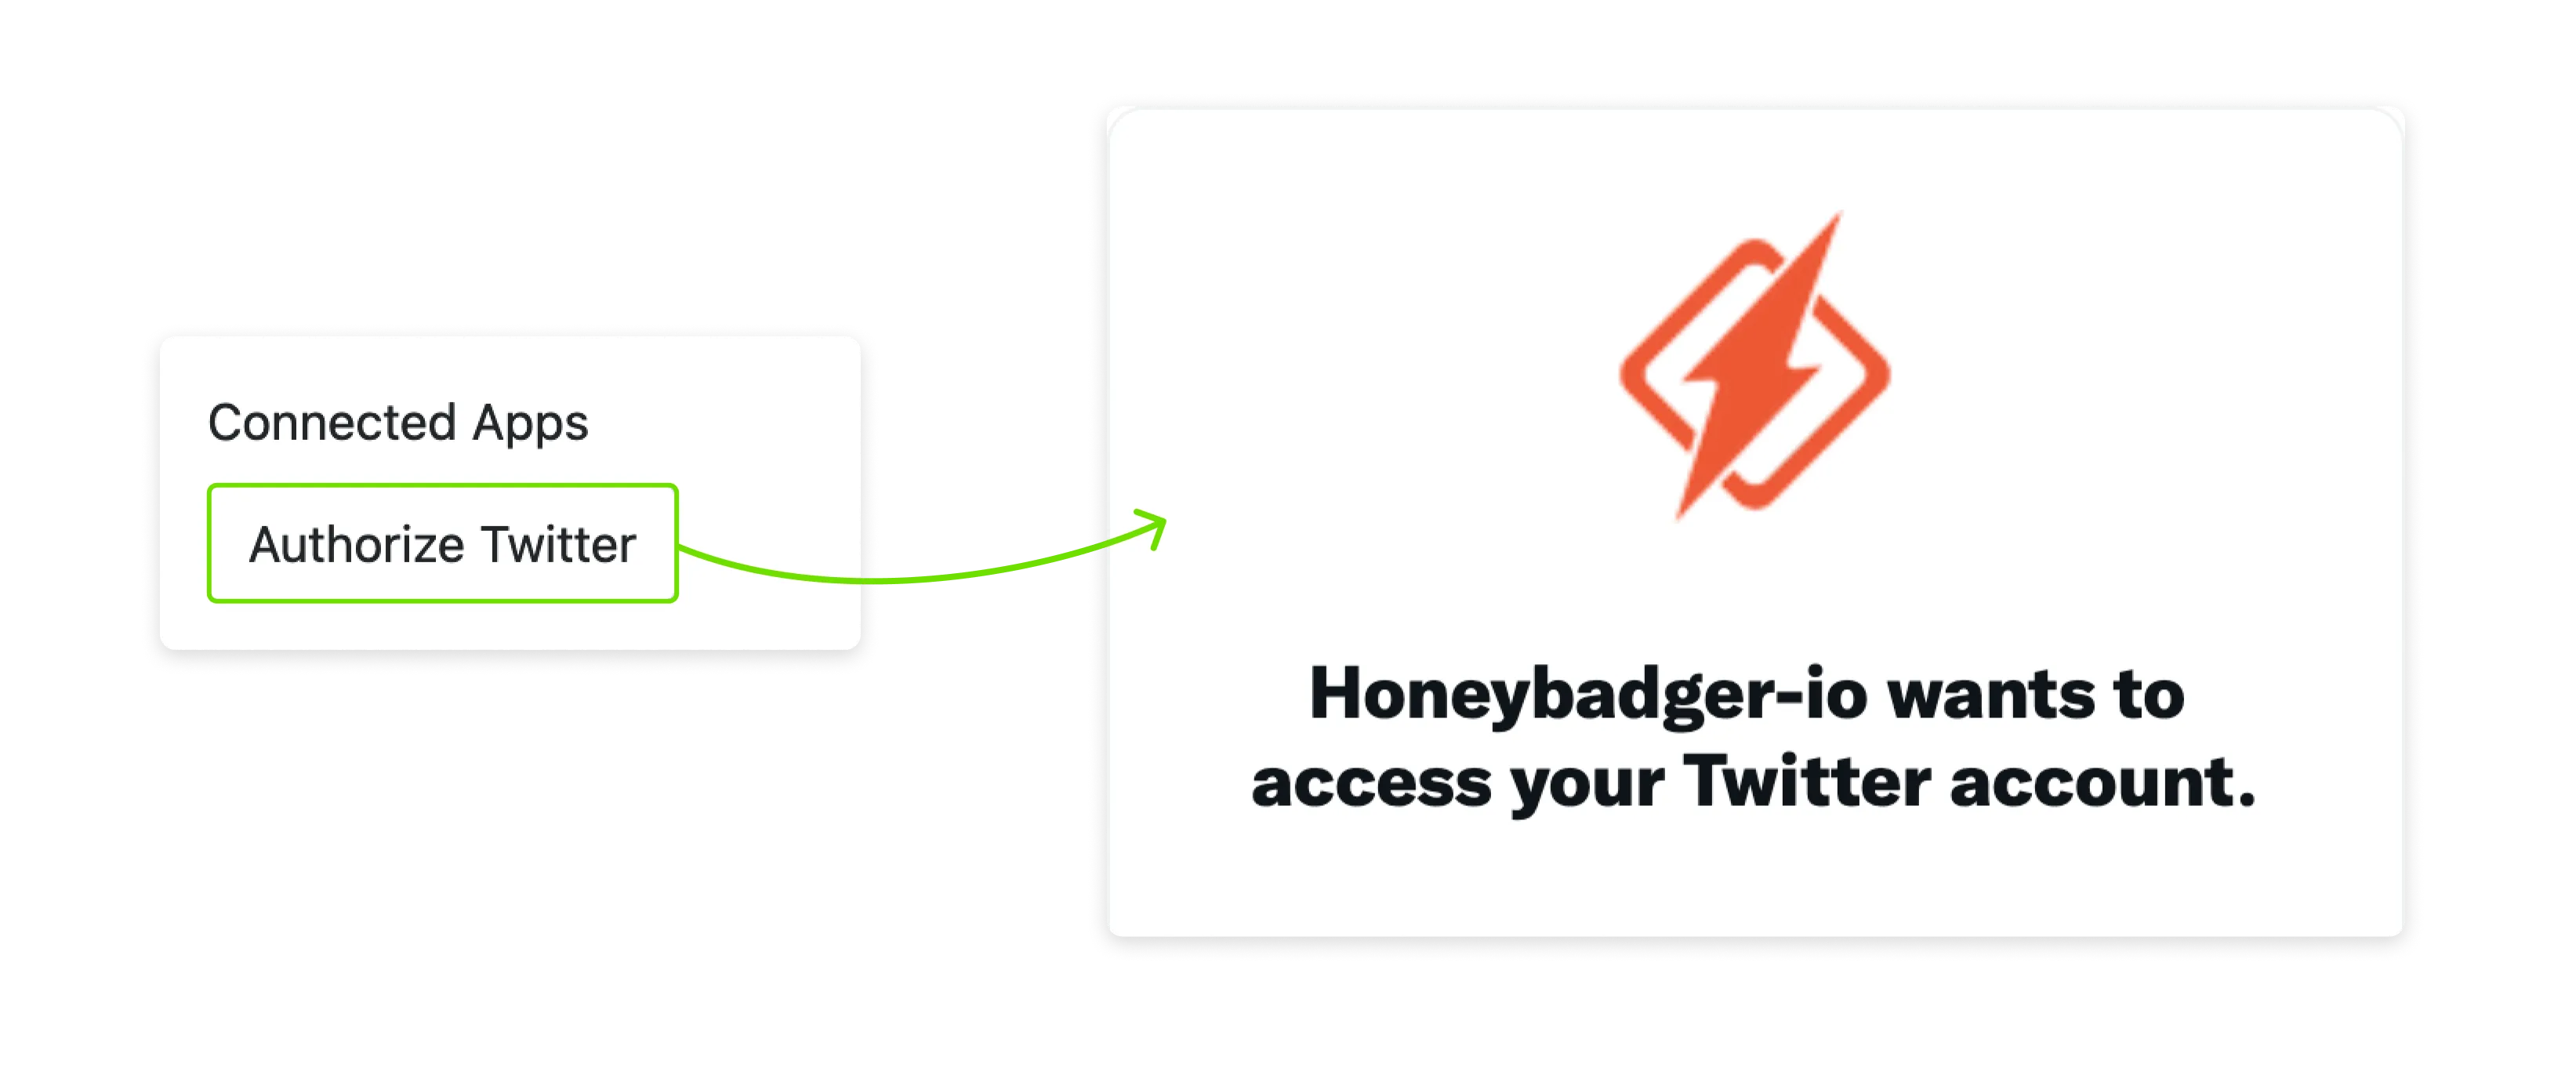
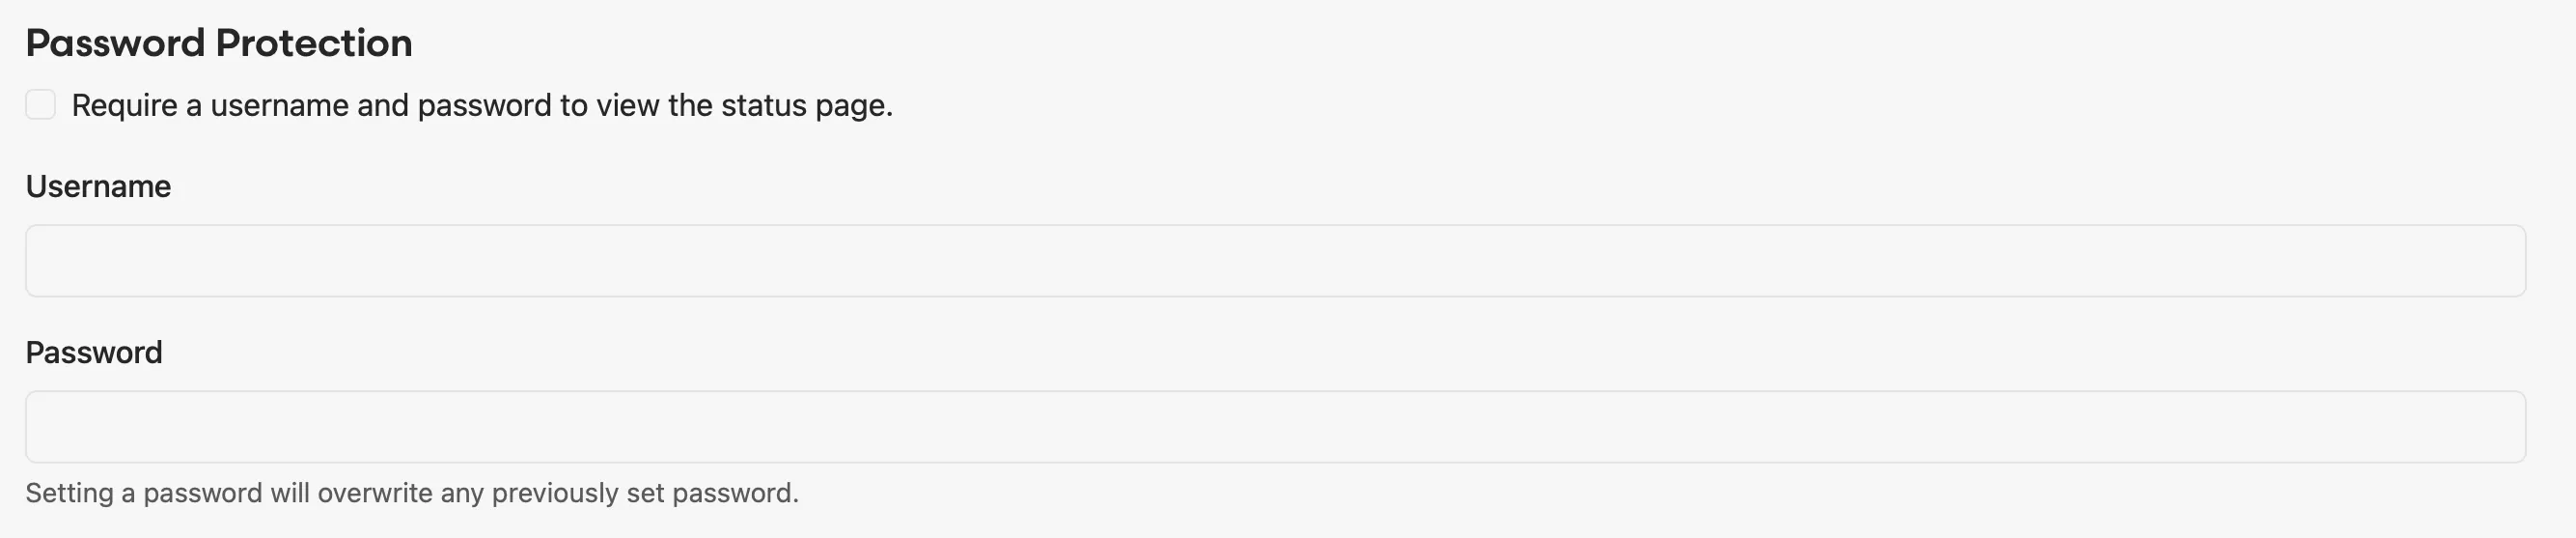
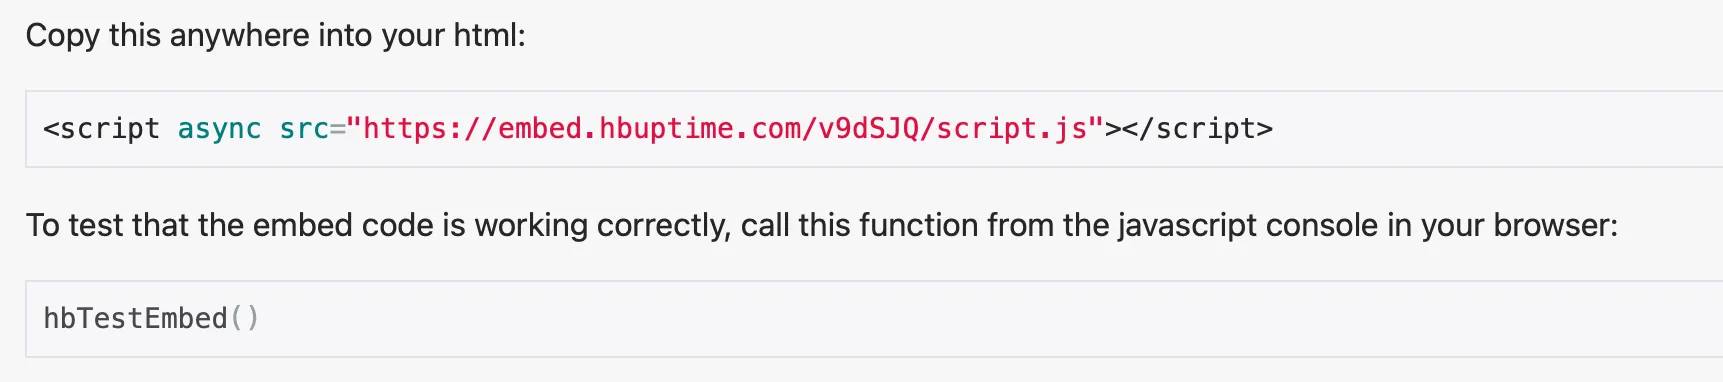
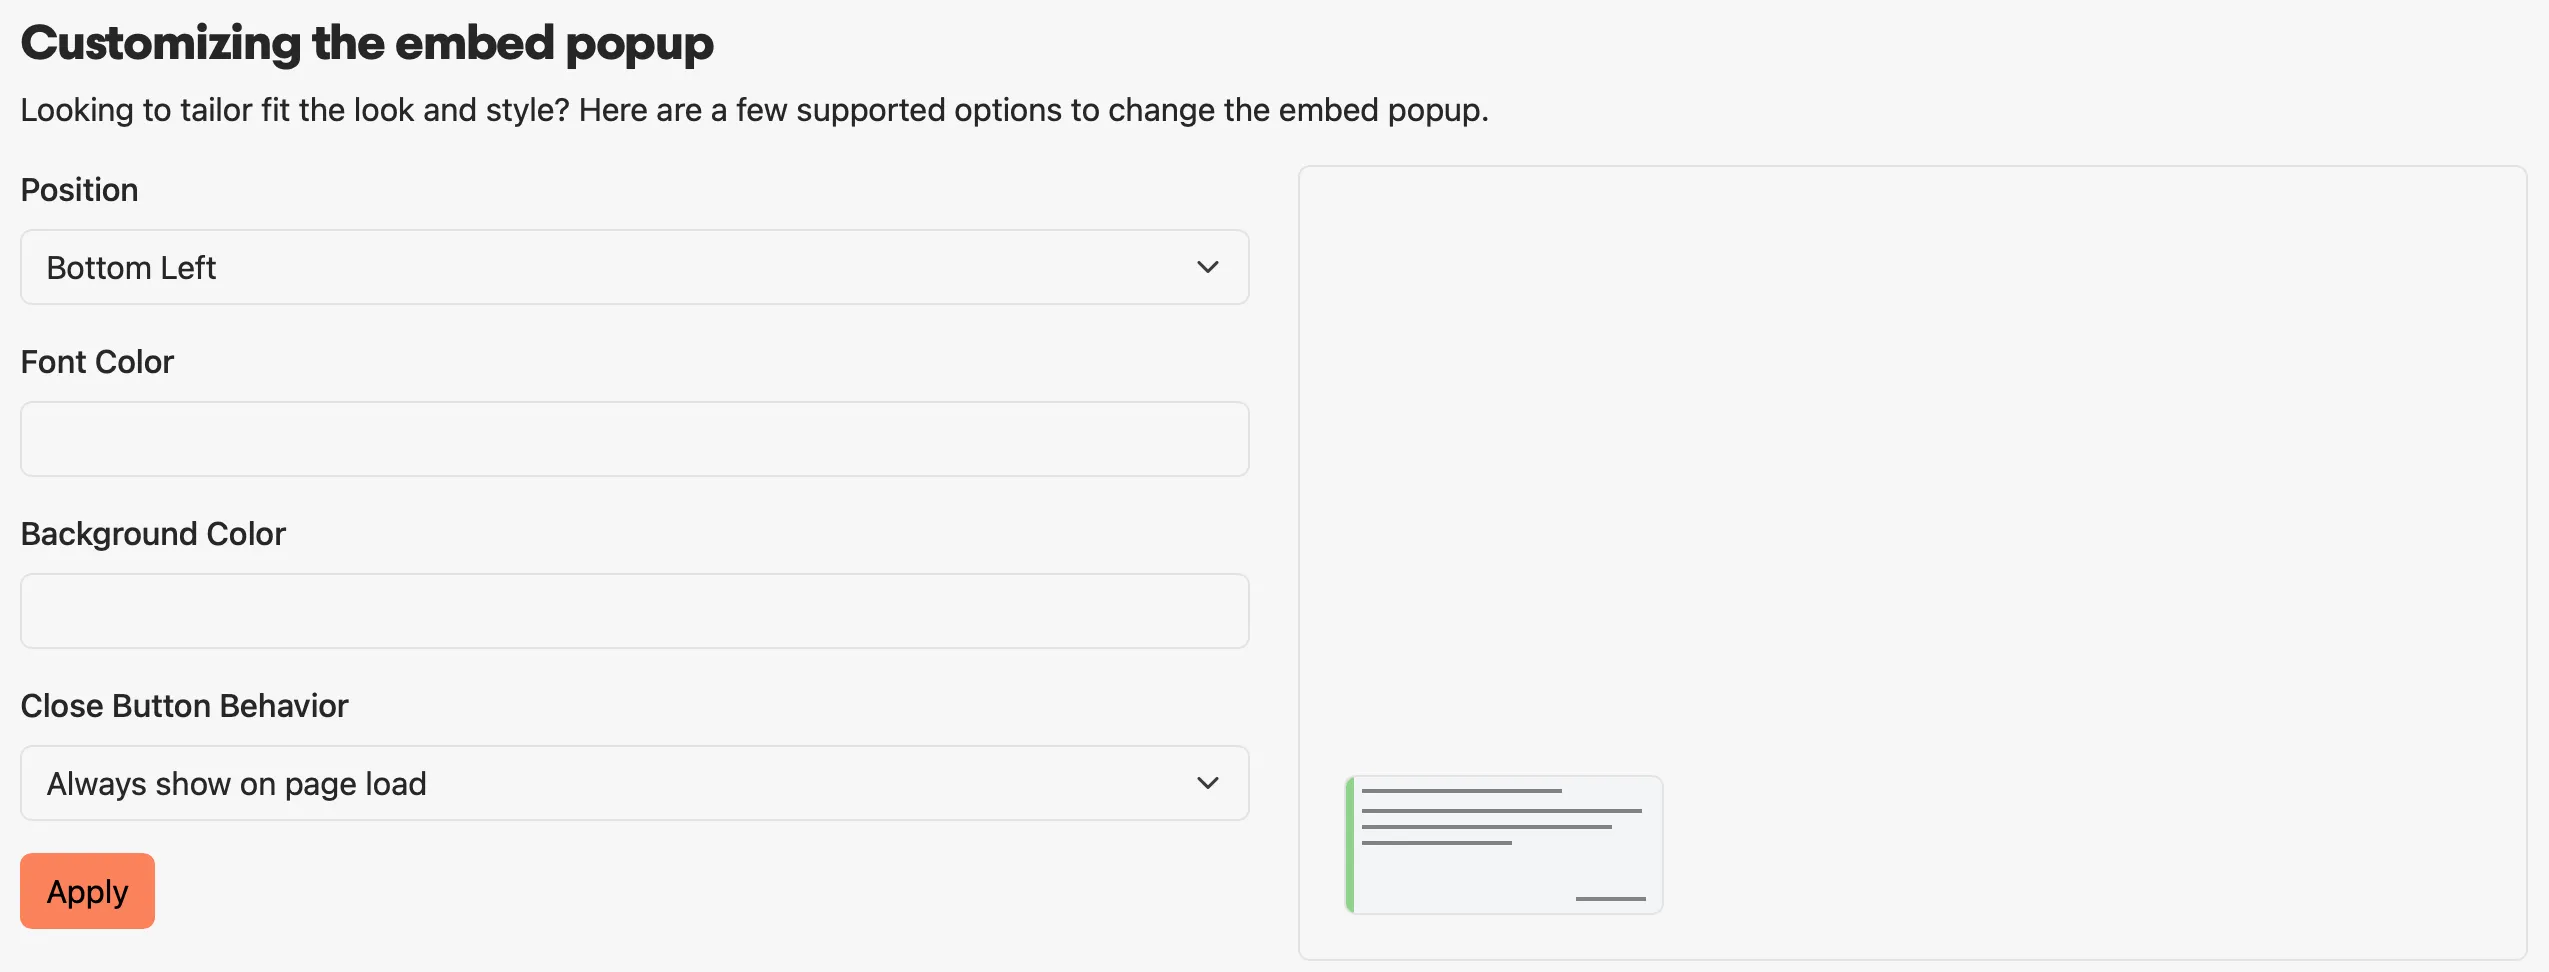
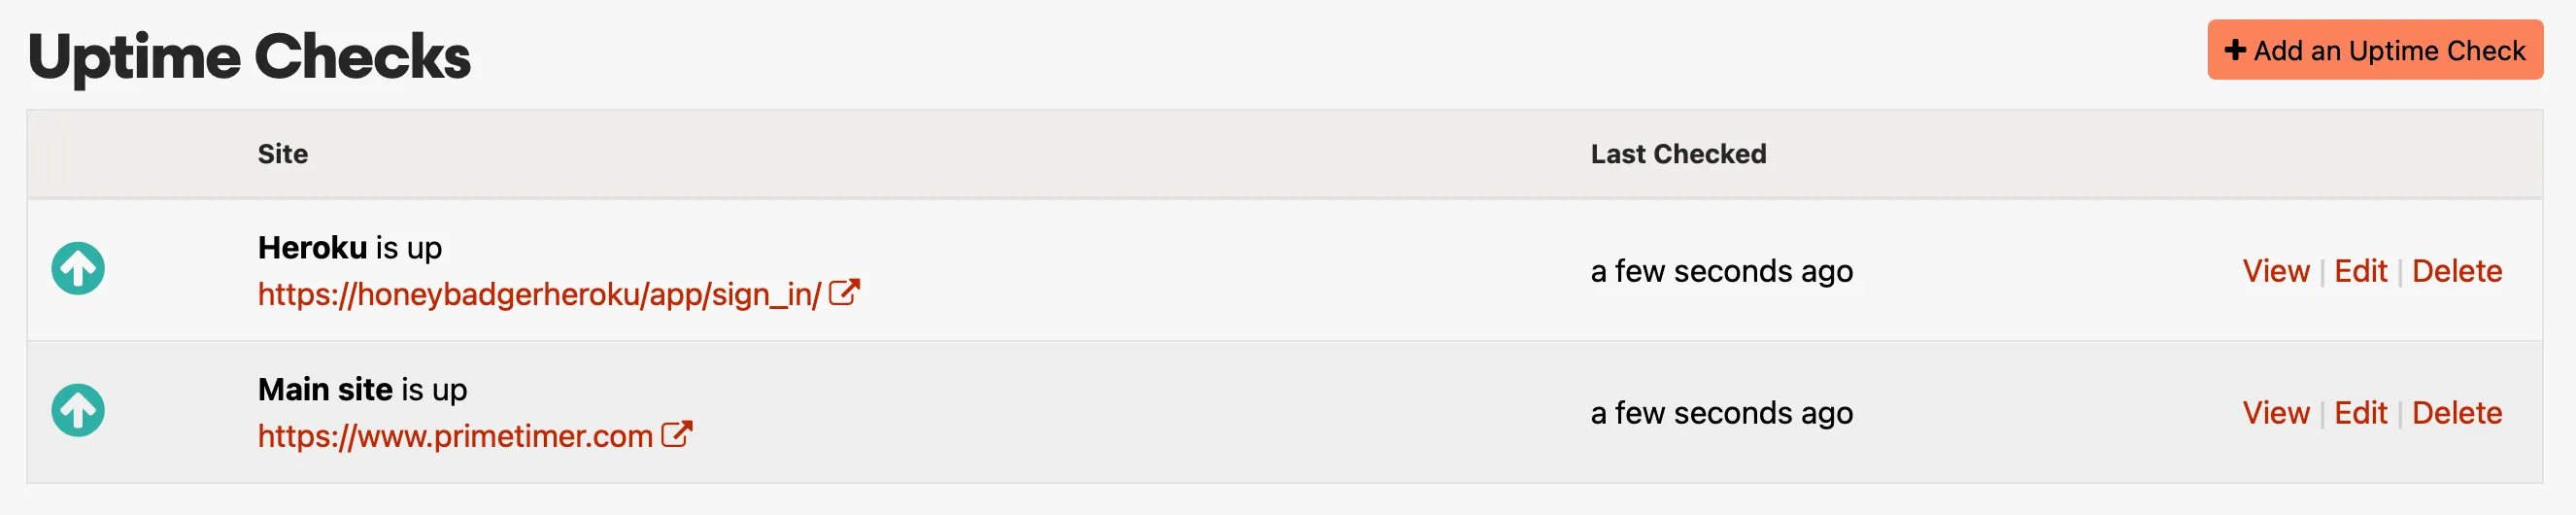
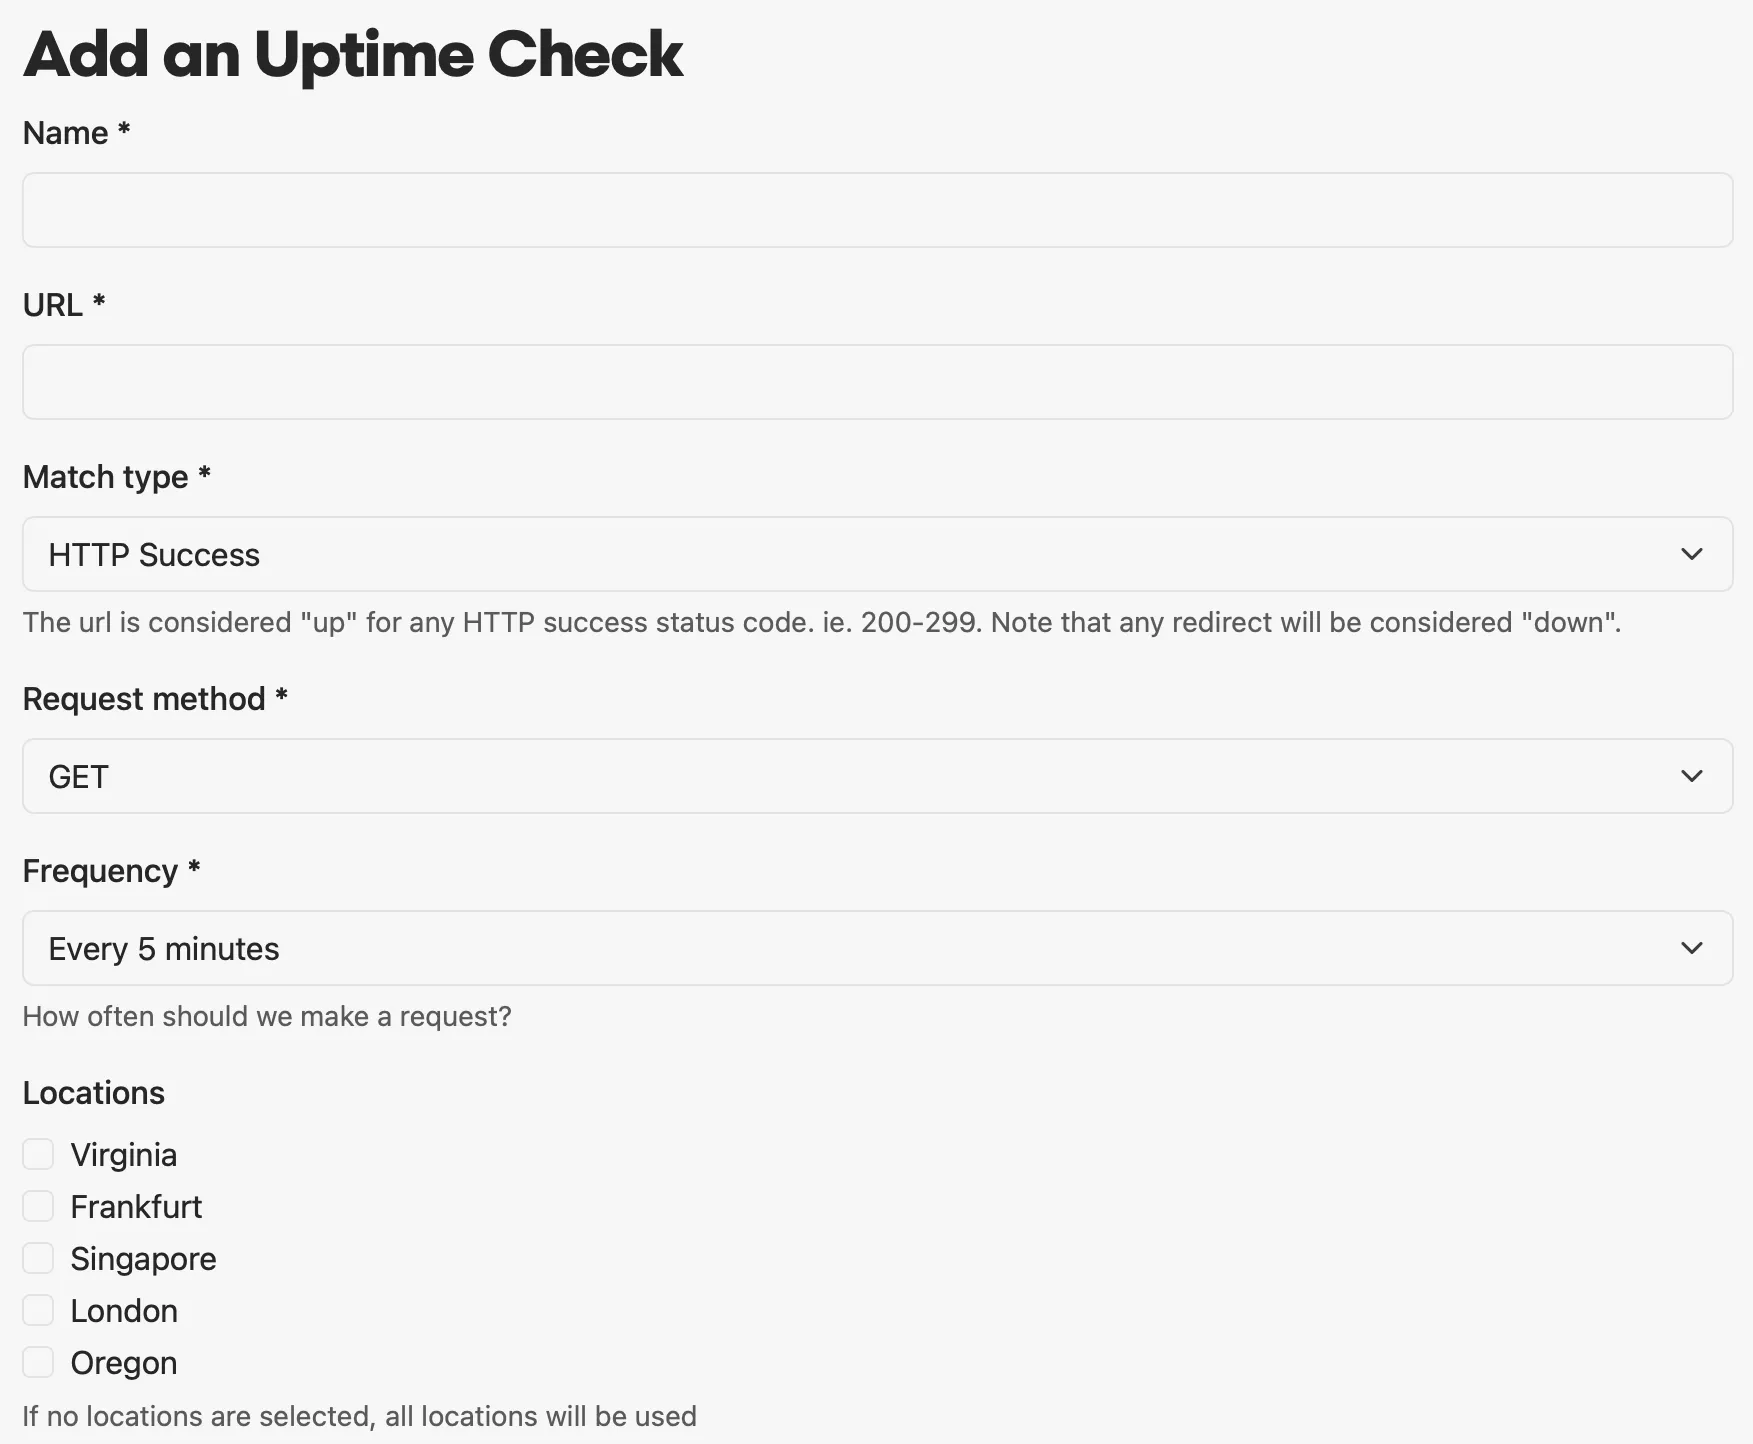
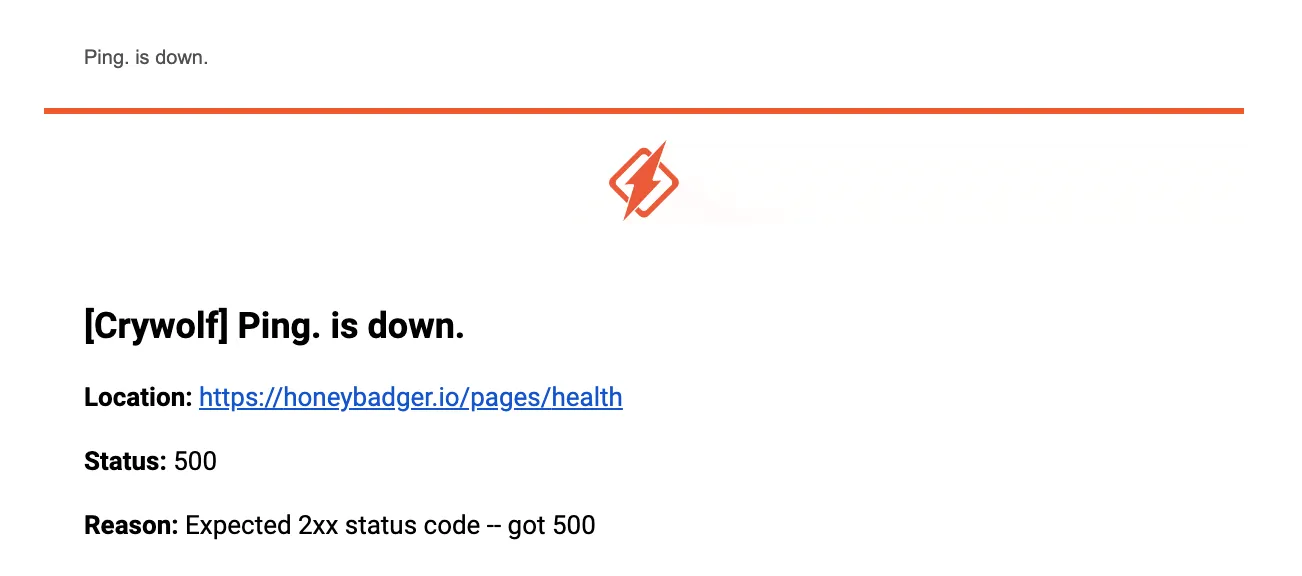
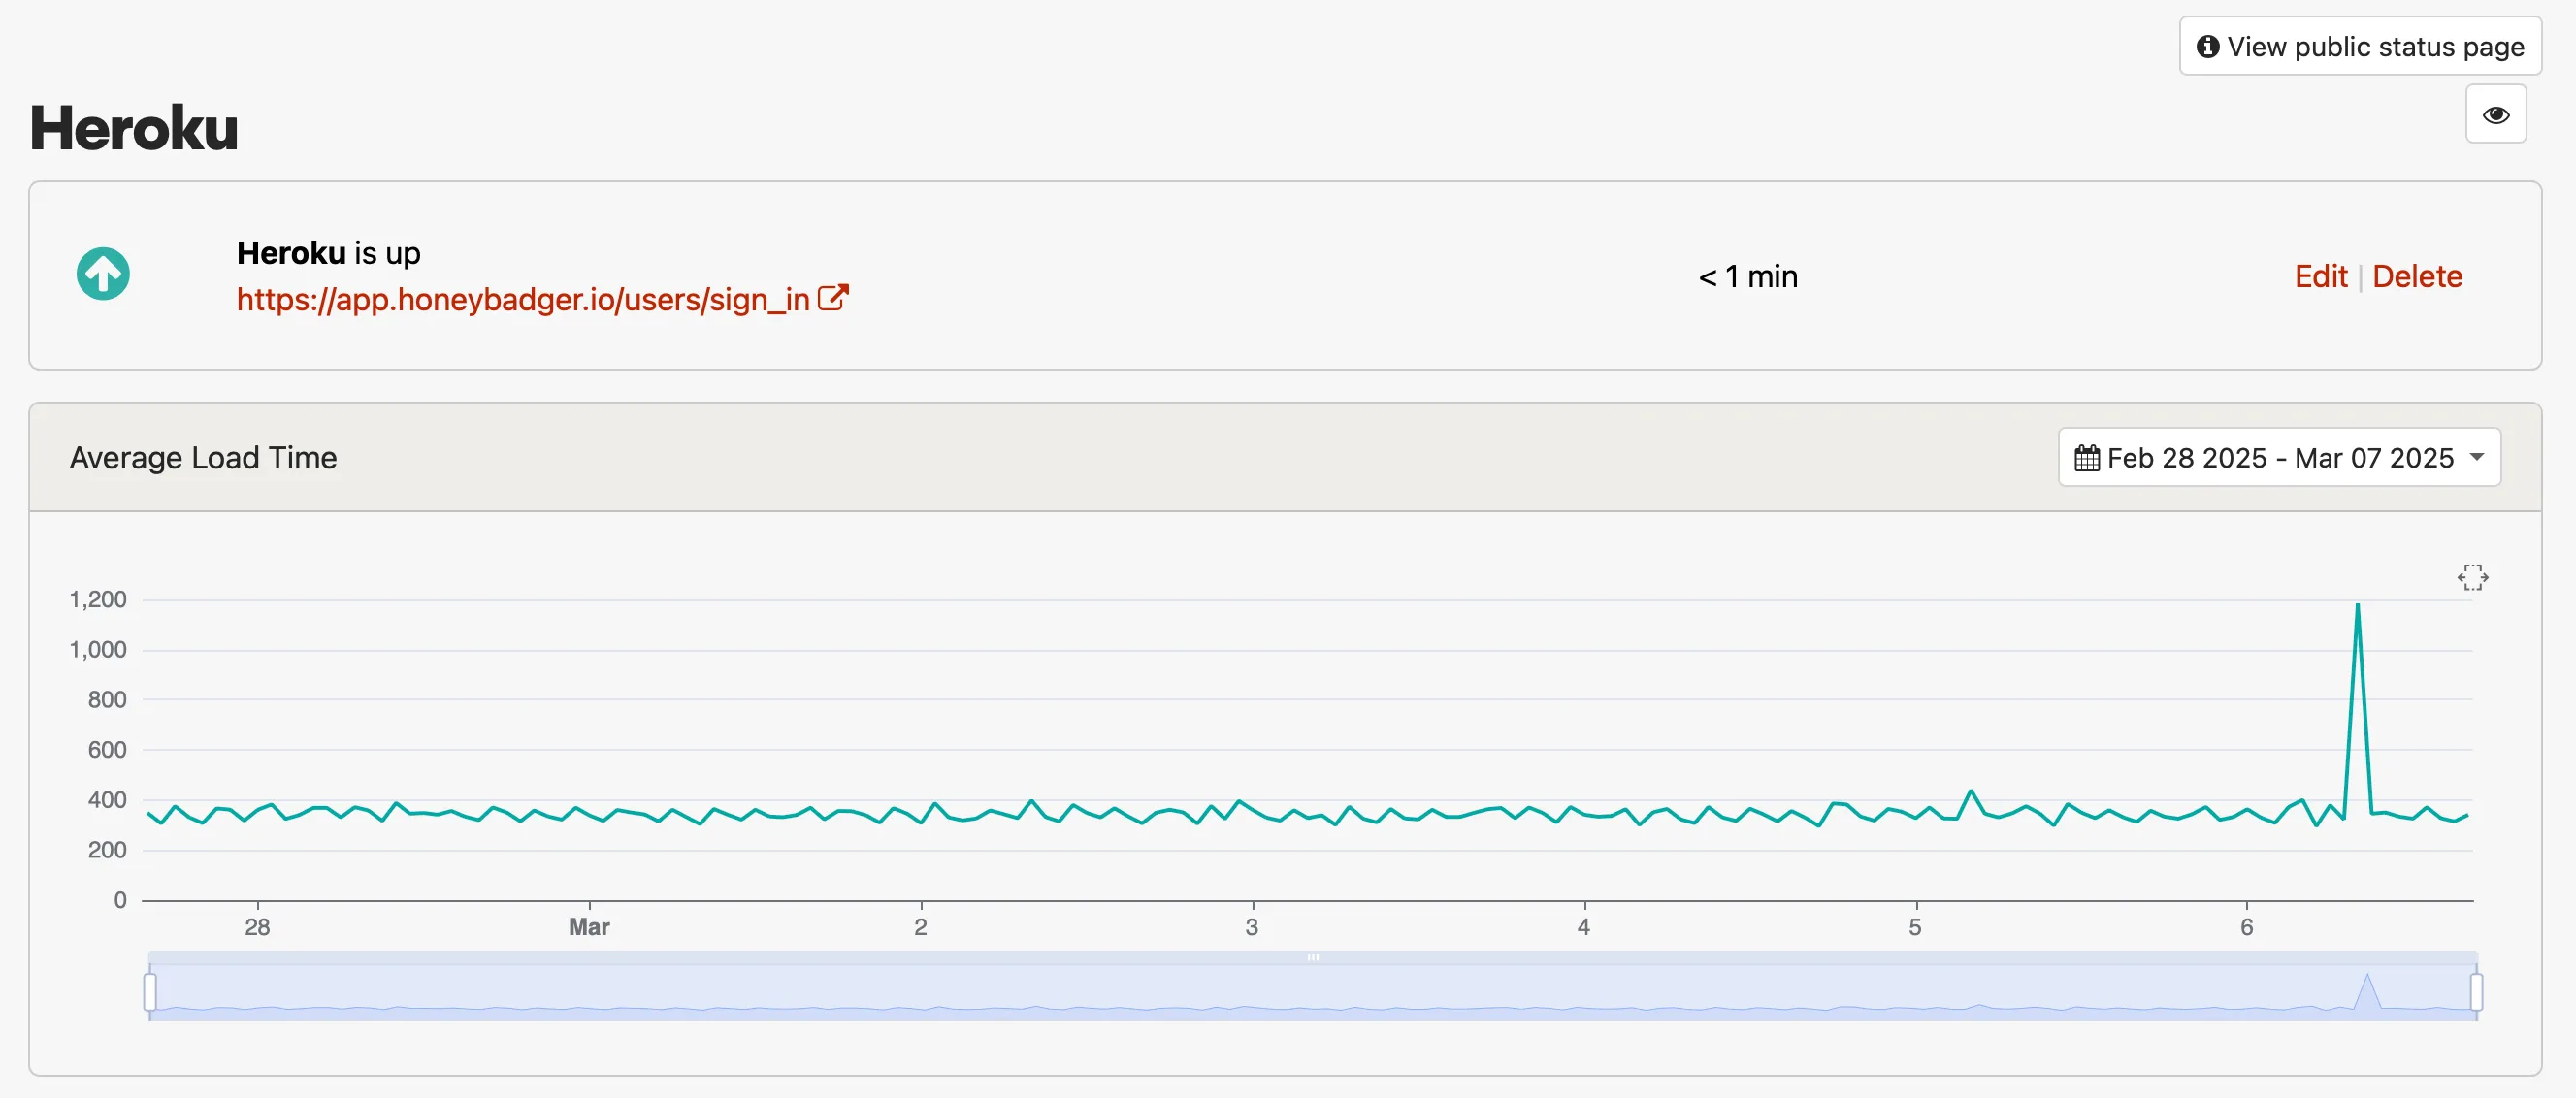
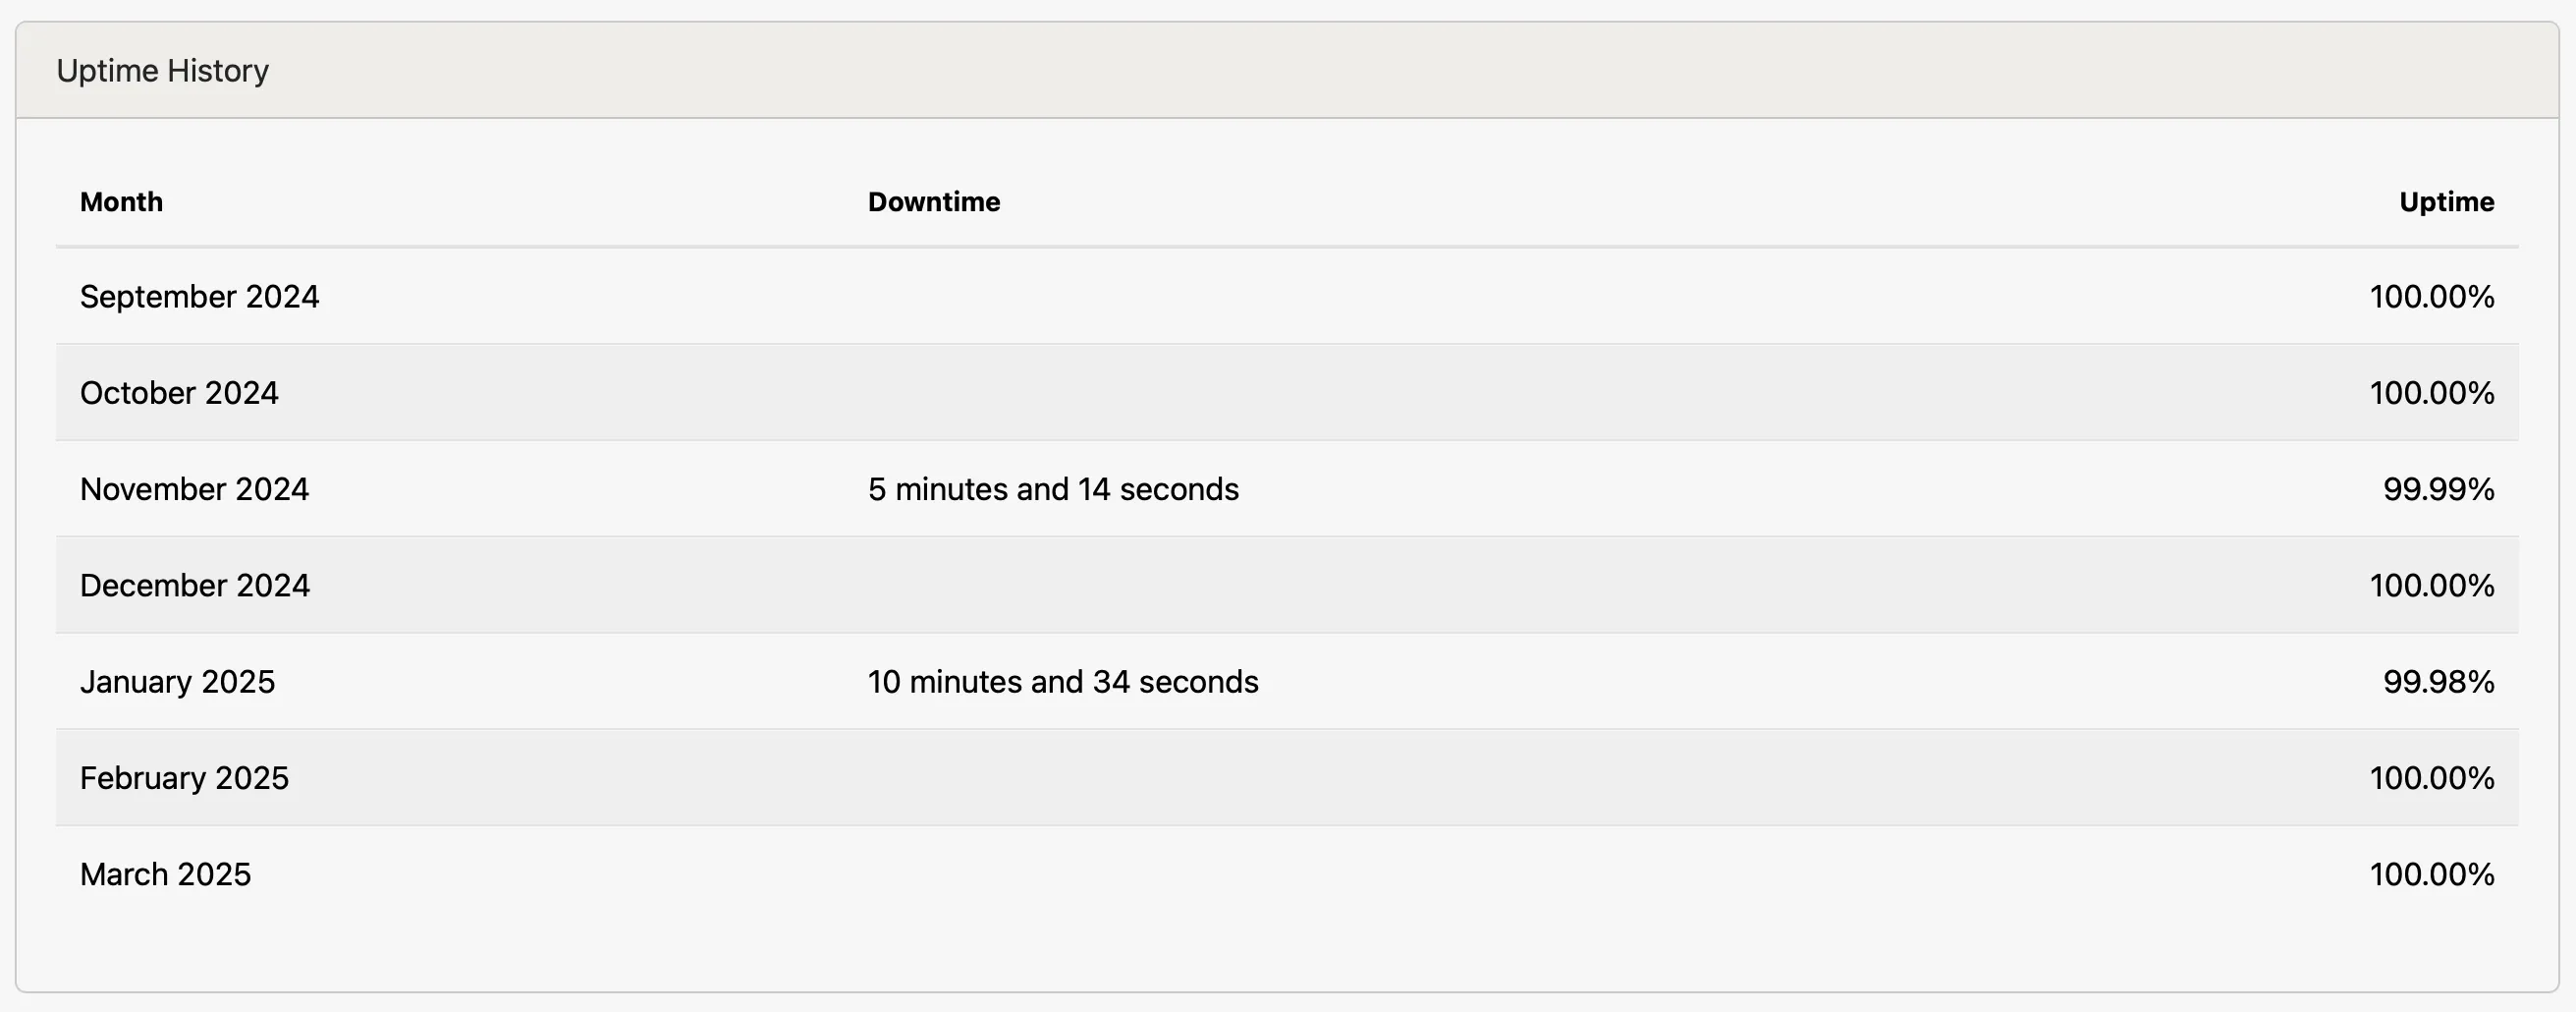
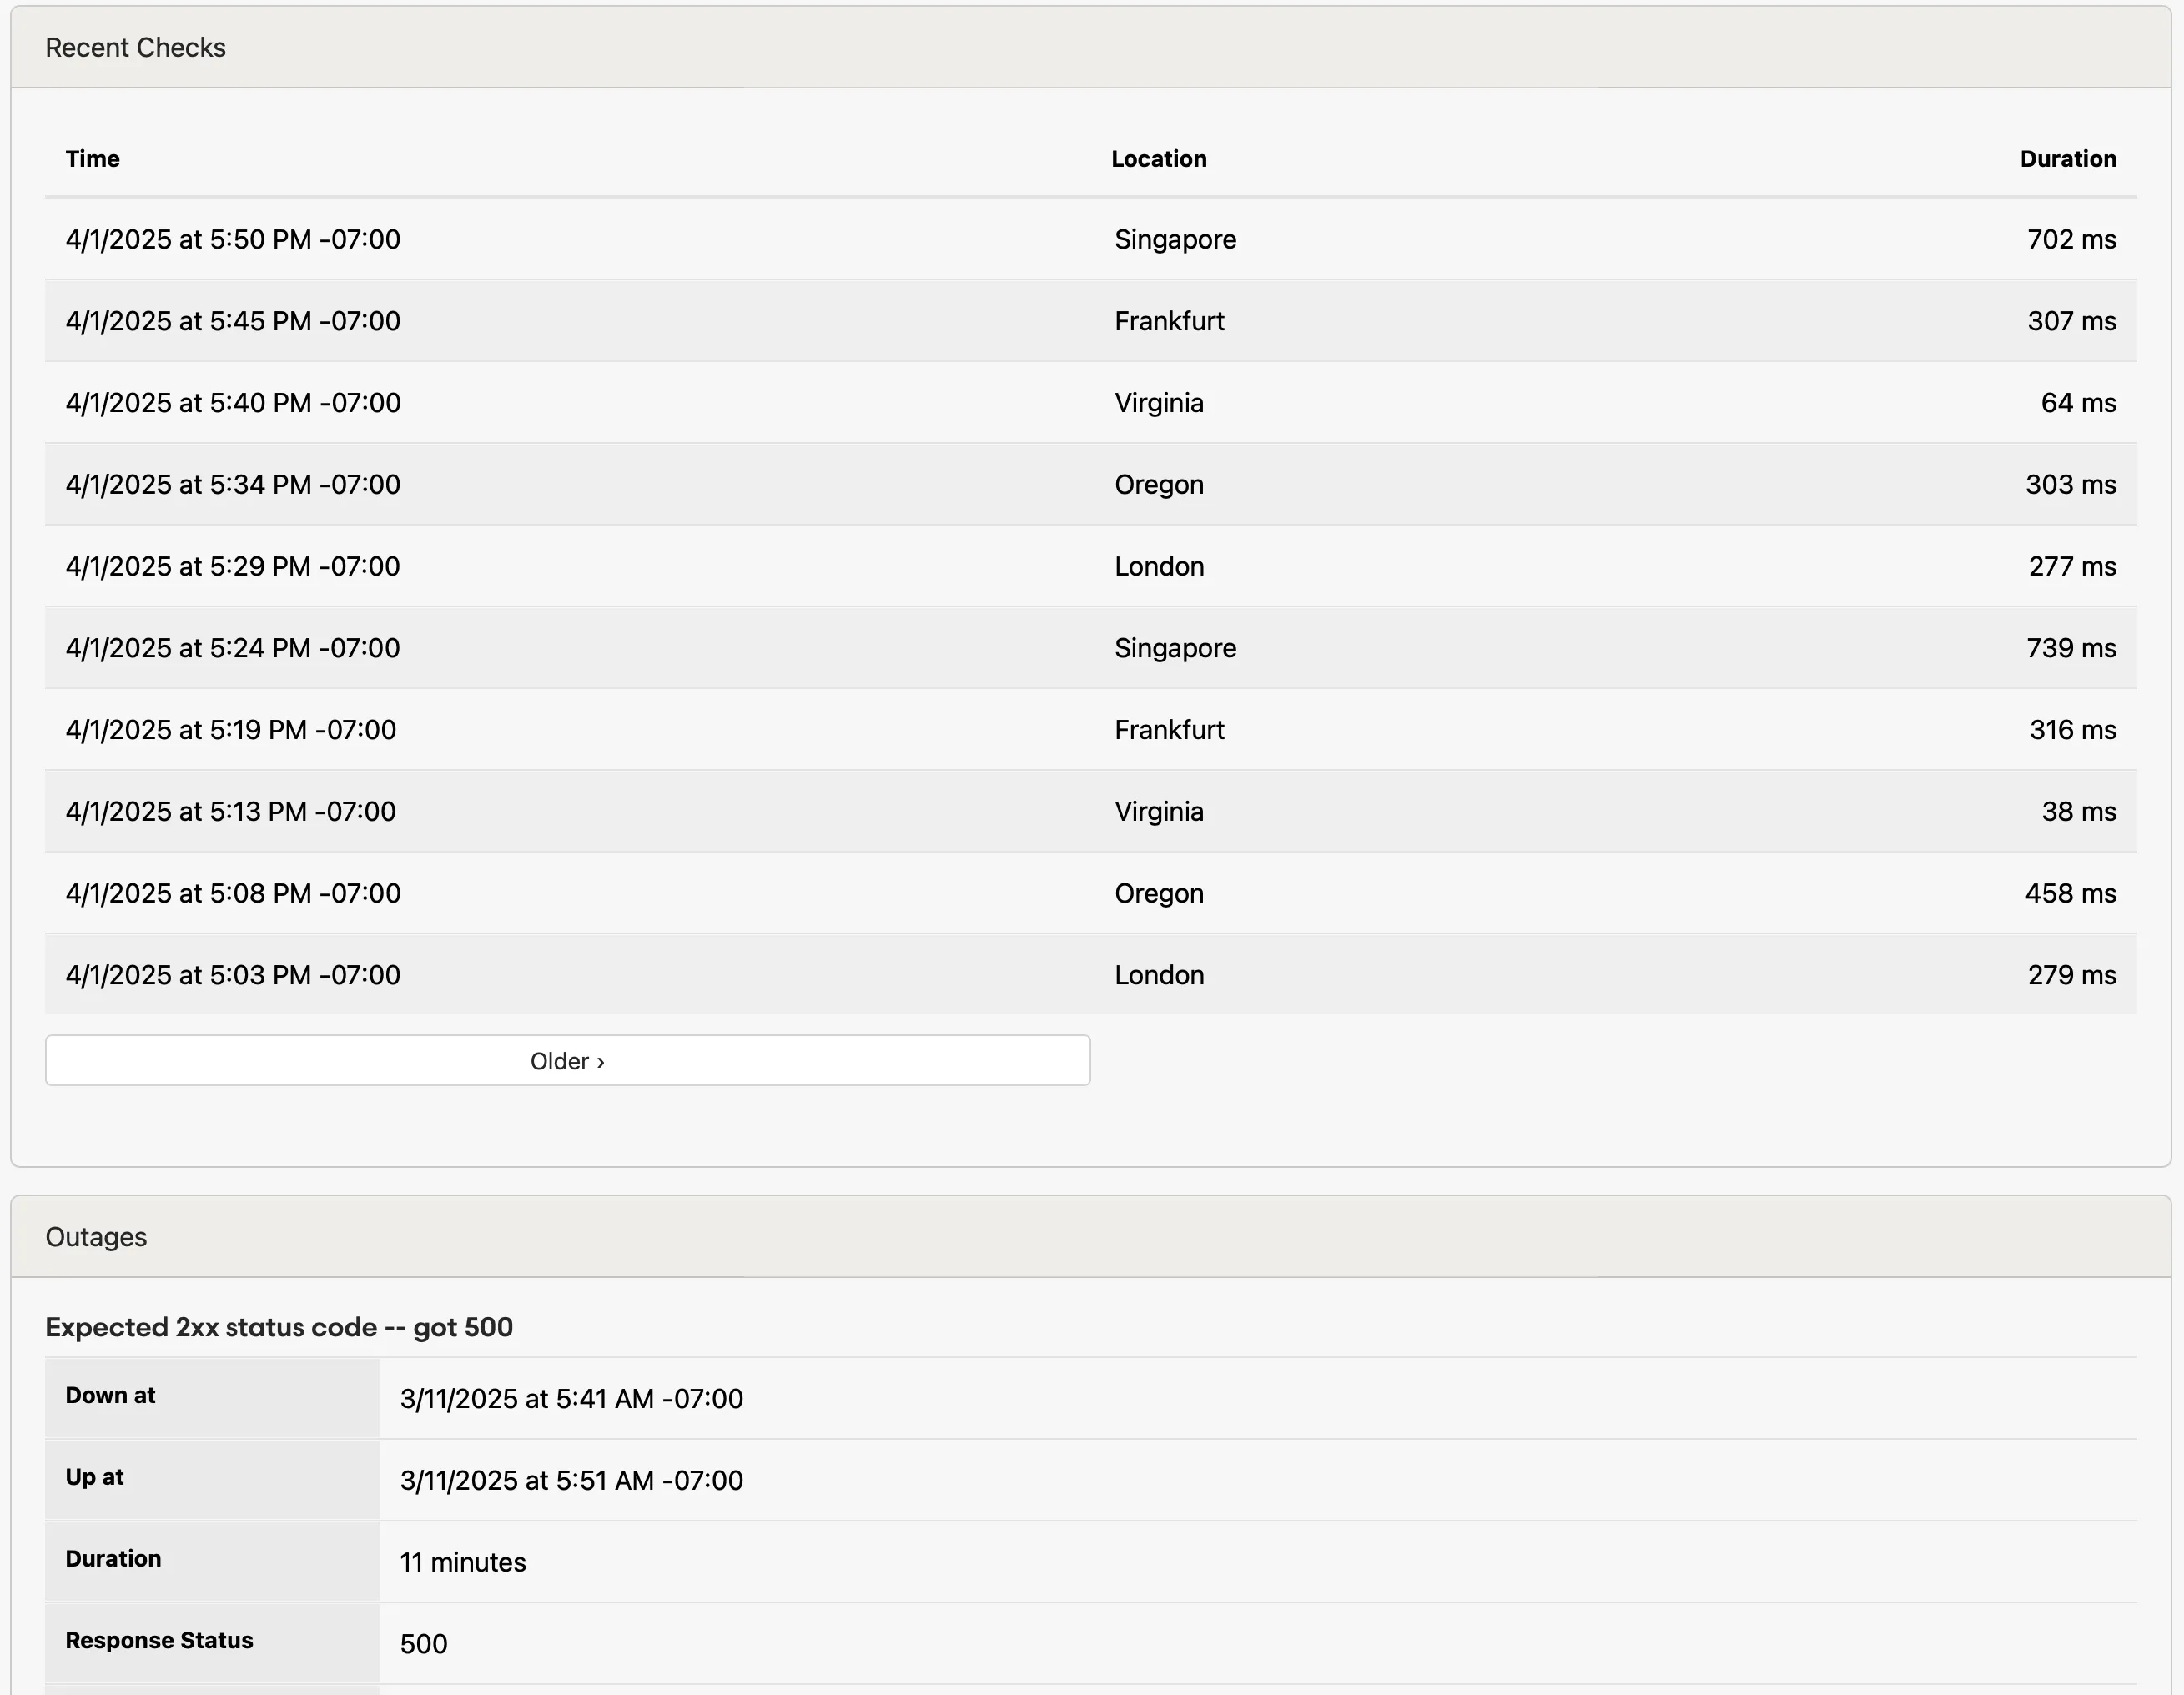
An Error Occurred
{this.error}
{this.info}
); } } ``` ## Reporting errors [Section titled “Reporting errors”](#reporting-errors) Using the example configuration above, you’ll install *@honeybadger-io/react* as React’s error handler. Additionally, by default, an error handler for all JavaScript errors will be attached to the `window.onerror` handler for JavaScript errors that may originate from React components or other JavaScript on the page. Because React doesn’t intercept all errors that may occur within a React component, errors that bubble up to the `window.onerror` handler may be missing some React component contextual information, but the stack trace will be available. If, for some reason, you do not wish to install Honeybadger’s error handler on the global `window.onerror` handler, you may add `{ enableUncaught: false }` to the configuration you’re passing to `Honeybadger.configure`. You may also manually report errors by directly invoking the [honeybadger.js](https://github.com/honeybadger-io/honeybadger-js/tree/master/packages/js) API. ```javascript honeybadger.notify(error); ``` See the [full documentation](/lib/javascript/) for more options. Note React handles exceptions slightly differently in development mode than in production. As a result, in development mode only, the error boundary component you create will capture the error and add React context, but React will essentially re-throw the error and it will bubble up to the window\.onerror handler (without the React context data). This behavior will not occur when your React application is built for production. ## Identifying users [Section titled “Identifying users”](#identifying-users) Honeybadger can track which users have encountered each error. To identify the current user in error reports, add a user identifier and/or email address with `honeybadger.setContext`: ```javascript honeybadger.setContext({ user_id: 123, user_email: "user@example.com", }); ``` ## Sending additional context [Section titled “Sending additional context”](#sending-additional-context) Sometimes additional application state may be helpful for diagnosing errors. You can arbitrarily specify additional key/value pairs when you invoke `setContext`. ```javascript honeybadger.setContext({ active_organization: 55, custom_configuration: false, }); ``` ## Clearing context [Section titled “Clearing context”](#clearing-context) If your user logs out or if your context changes during the React component lifetime, you can set new values as appropriate by invoking `setContext` again. Additionally, if needed, you can clear the context by invoking `clear`: ```javascript // Set the context to {} honeybadger.clear(); ``` ## Advanced usage [Section titled “Advanced usage”](#advanced-usage) *@honeybadger-io/react* is built on [honeybadger.js](https://github.com/honeybadger-io/honeybadger-js). See the [Honeybadger JavaScript integration documentation](/lib/javascript/) for additional customization options. ## Tracking deploys [Section titled “Tracking deploys”](#tracking-deploys) As with vanilla JavaScript applications, you can notify Honeybadger when you’ve deployed a new build. Honeybadger will associate an error report with a specific revision number (matching the ‘revision’ field in the configuration passed to `Honeybadger.configure`). Here’s a simple `curl` script to record a deployment: ```sh HONEYBADGER_ENV="production" \ HONEYBADGER_REVISION="$(git rev-parse HEAD)" \ HONEYBADGER_REPOSITORY="$(git config --get remote.origin.url)" \ HONEYBADGER_API_KEY="Your project API key" \ && curl -g "https://api.honeybadger.io/v1/deploys?deploy[environment]=$HONEYBADGER_ENV&deploy[local_username]=$USER&deploy[revision]=$HONEYBADGER_REVISION&deploy[repository]=$HONEYBADGER_REPOSITORY&api_key=$HONEYBADGER_API_KEY" ``` Be sure that the same revision is also configured in the *@honeybadger-io/react* library. Read more about deploy tracking in the [API docs](/api/deployments/). ### Tracking deploys from Netlify [Section titled “Tracking deploys from Netlify”](#tracking-deploys-from-netlify) If you are deploying your site to Netlify, you can notify Honeybadger of deployments via Netlify’s webhooks. Go to the **Deploy notifications** section of the **Build & deploy** tab for your site settings, and choose to add an Outgoing webhook notification. Choose `Deploy succeeded` as the event to listen for, and use this format for your URL: `https://api.honeybadger.io/v1/deploys/netlify?api_key=YOUR_HONEYBADGER_API_KEY_HERE` The environment that will be reported to Honeybadger defaults to the Netlify environment that was deployed, but you can override that with `&environment=CUSTOM_ENV` in the webhook URL, if you like. ## Source map support [Section titled “Source map support”](#source-map-support) Honeybadger can automatically un-minify your code if you provide a source map along with your minified JavaScript files. See our [Source Map Guide](/lib/javascript/errors/using-source-maps/) for details. ## Collect user feedback [Section titled “Collect user feedback”](#collect-user-feedback) When an error occurs, a form can be shown to gather feedback from your users. Honeybadger can automatically show the form by setting the `showUserFeedbackFormOnError` prop to `true`: ```javascript ``` Read more about this feature [here](/lib/javascript/errors/collecting-user-feedback/). ## Sample application [Section titled “Sample application”](#sample-application) A minimal implementation is included in the [*example*](https://github.com/honeybadger-io/honeybadger-js/tree/master/packages/react/example) folder in the *@honeybadger-io/react* repository. To run it from the command line, enter the following commands in your shell: ```bash cd example yarn install REACT_APP_HONEYBADGER_API_KEY=yourkey yarn start ``` Observe the command-line output to determine the appropriate URL to connect to in your browser (usually `http://localhost:3000/`). # Honeybadger for React Native > Honeybadger monitors your React Native applications for errors and exceptions so that you can fix them wicked fast. Note This documentation is for version **6** or later. If you are using an earlier version, please see the [v5 documentation](/lib/javascript/integration/react-native-v5/). Hi there! You’ve found Honeybadger’s guide to **React Native exception and error tracking**. Once installed, Honeybadger will automatically report errors from your React Native application. ## Installation [Section titled “Installation”](#installation) From the root directory of your React Native project, add *@honeybadger-io/react-native* as a dependency: ```shell npm install "@honeybadger-io/react-native" cd ios && pod install ``` The iOS step is required to properly add the library to the Xcode project through CocoaPods. Android doesn’t require a separate step. Add the following to your **App.js** file to initialize the Honeybadger library. ```js import Honeybadger from "@honeybadger-io/react-native"; export default function App() { Honeybadger.configure({ apiKey: "[ YOUR API KEY HERE ]", }); // ... } ``` You can log into your [Honeybadger](https://app.honeybadger.io/) account to obtain your API key. See the [Configuration Reference](/lib/javascript/reference/configuration/) for a full list of config options. Note Errors that happen in development and test environments are not reported by default. To always report errors or to change the defaults, see [Environments and Versions](/lib/javascript/errors/environments-and-versions/#development-environments). ## Reporting errors [Section titled “Reporting errors”](#reporting-errors) Uncaught iOS, Android, and JavaScript errors will be automatically reported to Honeybadger by default. You may also manually report errors by directly invoking the [honeybadger.js](https://github.com/honeybadger-io/honeybadger-js/tree/master/packages/js) API. ```javascript Honeybadger.notify(error); ``` See the [full documentation](/lib/javascript/errors/reporting-errors/) for more options. ## Identifying users [Section titled “Identifying users”](#identifying-users) Honeybadger can track which users have encountered each error. To identify the current user in error reports, add a user identifier and/or email address with `Honeybadger.setContext`: ```javascript Honeybadger.setContext({ user_id: 123, user_email: "user@example.com", }); ``` ## Sending additional context [Section titled “Sending additional context”](#sending-additional-context) Sometimes additional application state may be helpful for diagnosing errors. You can arbitrarily specify additional key/value pairs when you invoke `setContext`. ```javascript Honeybadger.setContext({ active_organization: 55, custom_configuration: false, }); ``` ## Clearing context [Section titled “Clearing context”](#clearing-context) If your user logs out or if your context changes during the React component lifetime, you can set new values as appropriate by invoking `setContext` again. Additionally, if needed, you can clear the context by invoking `clear`: ```javascript // Set the context to {} Honeybadger.clear(); ``` ## Advanced usage [Section titled “Advanced usage”](#advanced-usage) *@honeybadger-io/react-native* is built on [honeybadger.js](https://github.com/honeybadger-io/honeybadger-js). See the [Honeybadger JavaScript integration documentation](/lib/javascript/) for additional customization options. ## Source map support [Section titled “Source map support”](#source-map-support) To generate and upload source maps to Honeybadger, use the following command: ```shell npx honeybadger-upload-sourcemaps --apiKey --revision ``` The `--apiKey` param is your Honeybadger API key for the project. The `--revision` param should match the revision param of the `Honeybadger.init` call inside your application. This is done so that reported errors are correctly matched up against the generated source maps. As of version 0.70, React Native uses Hermes as the default JavaScript engine. The source maps tool assumes that your project uses Hermes. If you are building against an earlier version of React Native, or are explicitly not using Hermes, add the `--no-hermes` flag to the source maps tool, like so: ```shell npx honeybadger-upload-sourcemaps --no-hermes --apiKey --revision ``` If your React Native project uses Expo, include the `--expo` param. ```shell npx honeybadger-upload-sourcemaps --apiKey --revision --expo ``` If you just want to generate the source maps without uploading them to Honeybadger, you can use the `--skip-upload` flag. ```shell npx honeybadger-upload-sourcemaps --skip-upload --apiKey --revision ``` ## Sample applications [Section titled “Sample applications”](#sample-applications) The [*examples*](https://github.com/honeybadger-io/honeybadger-js/tree/master/packages/react-native/examples) folder contains two minimal React Native projects, demonstrating the use of the Honeybadger library. See the [README](https://github.com/honeybadger-io/honeybadger-js/tree/master/packages/react-native#example-projects) for details. # Honeybadger for React Native version <=5 > Honeybadger monitors your React Native applications for errors and exceptions so that you can fix them wicked fast. Note This documentation is for **version 5** or earlier. If you are using a more recent version, please see the [latest documentation](/lib/javascript/integration/react-native/). ## Installation [Section titled “Installation”](#installation) From the root directory of your React Native project: ```shell npm install "@honeybadger-io/react-native" cd ios && pod install ``` The above will download the Honeybadger React Native library and add it as a dependency of your project. The iOS step is required to properly add the library to the Xcode project through CocoaPods. Android doesn’t require a separate step. ## Initialization [Section titled “Initialization”](#initialization) Add the following to your **App.js** file to initialize the Honeybadger library. ```js import Honeybadger from "@honeybadger-io/react-native"; export default function App() { Honeybadger.configure("PROJECT_API_KEY"); // ... } ``` You can log into your [Honeybadger](https://honeybadger.io) account to obtain your API key. ## Configuration [Section titled “Configuration”](#configuration) The configure method takes additional configuration options. | Name | Type | Required | Default | Example | | ------------ | ------- | -------- | ------- | -------------------- | | apiKey | String | YES | `""` | `"hb-api-key-1234"` | | reportErrors | Boolean | NO | true | | | revision | String | NO | `""` | `"8afb34a"` | | projectRoot | String | NO | `""` | `"/path/to/project"` | ```js Honeybadger.configure("hb-api-key-1234", "8afb34a", "/path/to/project"); ``` The **reportErrors** parameter determines if errors are to be sent to Honeybadger. This is set to **true** by default. In certain environments, say, during development, it could be useful to set **reportErrors** to **false** to prevent errors from being posted to your Honeybadger account. ## Usage examples [Section titled “Usage examples”](#usage-examples) iOS, Android, and JavaScript errors will be automatically handled by the Honeybadger React Native library, by default. But you can also use the following API to customize error handling in your application. ### Honeybadger.notify(error, additionalData) [Section titled “Honeybadger.notify(error, additionalData)”](#honeybadgernotifyerror-additionaldata) You can use the **notify** method to send any kind of error, exception, object, String, etc. If sending an error or exception, the Honeybadger React Native library will attempt to extract a stack trace and any relevant information that might be useful. You can also optionally provide **additionalData** to the **notify** method, as either a string or an object, to include any relevant information. ### Honeybadger.setContext(context) [Section titled “Honeybadger.setContext(context)”](#honeybadgersetcontextcontext) If you have data that you would like to include whenever an error or an exception occurs, you can provide that data using the **setContext** method. Provide an object as an argument. You can call **setContext** as many times as needed. New context data will be merged with any previously-set context data. ```js Honeybadger.setContext({ user_id: "123abc", more: "some additional data", }); ``` ### Honeybadger.resetContext() [Section titled “Honeybadger.resetContext()”](#honeybadgerresetcontext) If you’ve used **Honeybadger.setContext()** to store context data, you can use **Honeybadger.resetContext()** to clear that data. ### Honeybadger.setLogLevel(logLevel) [Section titled “Honeybadger.setLogLevel(logLevel)”](#honeybadgersetloglevelloglevel) Sets the logging level for the Honeybadger library. ```js Honeybadger.setLogLevel("debug"); ``` The following values are accepted: | Value | Meaning | | --------- | ---------------------------------------- | | “debug” | Everything will be logged to console. | | “warning” | Only warnings will be logged to console. | | “error” | Only errors will be logged to console. | The default logging level is “warning”. # Stimulus integration guide > Honeybadger monitors your Stimulus applications for errors and exceptions so that you can fix them wicked fast. **Typical installation time:** 5 minutes Hi there! You’ve found Honeybadger’s guide to **Stimulus error and exception tracking**. Once installed, Honeybadger will automatically report errors from your Stimulus application. ## Installation [Section titled “Installation”](#installation) First, install *honeybadger.js*: ```plaintext # npm npm add @honeybadger-io/js --save # yarn yarn add @honeybadger-io/js ``` Then, configure Stimulus to report errors to Honeybadger: ```js // In a Rails app this code typically resides in app/javascript/packs/application.js // In a non-Rails app, usually src/application.js // Import honeybadger.js import { Application } from "stimulus"; import * as Honeybadger from "@honeybadger-io/js"; // Configure honeybadger.js Honeybadger.configure({ apiKey: "PROJECT_API_KEY", environment: "production", revision: "git SHA/project version", }); // Start Stimulus application const application = Application.start(); // Set up error handler application.handleError = (error, message, detail) => { console.warn(message, detail); Honeybadger.notify(error); }; // Perform your other Stimulus setup here ``` Note Errors that happen in development and test environments are not reported by default. To always report errors or to change the defaults, see [Environments and Versions](/lib/javascript/errors/environments-and-versions/#development-environments). ## Reporting errors [Section titled “Reporting errors”](#reporting-errors) Honeybadger also reports all uncaught exceptions outside of Stimulus controllers using our `window.onerror` handler. To disable uncaught error reporting: ```js Honeybadger.configure({ enableUncaught: false }); ``` You can also manually notify Honeybadger of errors and other events in your application code: ```javascript try { // ...error producing code... } catch (error) { Honeybadger.notify(error); } ``` See the [Reporting Errors How-to Guide](/lib/javascript/errors/reporting-errors/) for more info. ## Identifying users [Section titled “Identifying users”](#identifying-users) Honeybadger can track what users have encountered each error. To identify the current user in error reports, add a user identifier and/or email address with `Honeybadger.context`: ```javascript Honeybadger.setContext({ user_id: 123, user_email: "user@example.com", }); ``` ## Tracking deploys [Section titled “Tracking deploys”](#tracking-deploys) As with vanilla JavaScript applications, you can notify Honeybadger when you’ve deployed a new build. Honeybadger will associate an error report with a specific revision number (matching the ‘revision’ field in your *honeybadger.js* configuration). Here’s a simple `curl` script to record a deployment: ```sh HONEYBADGER_ENV="production" \ HONEYBADGER_REVISION="$(git rev-parse HEAD)" \ HONEYBADGER_REPOSITORY="$(git config --get remote.origin.url)" \ HONEYBADGER_API_KEY="Your project API key" \ && curl -g "https://api.honeybadger.io/v1/deploys?deploy[environment]=$HONEYBADGER_ENV&deploy[local_username]=$USER&deploy[revision]=$HONEYBADGER_REVISION&deploy[repository]=$HONEYBADGER_REPOSITORY&api_key=$HONEYBADGER_API_KEY" ``` Be sure that the same revision is also configured in the *honeybadger.js* library. Read more about deploy tracking in the [API docs](/api/deployments). ### Tracking deploys from Netlify [Section titled “Tracking deploys from Netlify”](#tracking-deploys-from-netlify) If you are deploying your site to Netlify, you can notify Honeybadger of deployments via Netlify’s webhooks. Go to the **Deploy notifications** section of the **Build & deploy** tab for your site settings, and choose to add an Outgoing webhook notification. Choose `Deploy succeeded` as the event to listen for, and use this format for your URL: `https://api.honeybadger.io/v1/deploys/netlify?api_key=YOUR_HONEYBADGER_API_KEY_HERE` The environment that will be reported to Honeybadger defaults to the Netlify environment that was deployed, but you can override that with `&environment=CUSTOM_ENV` in the webhook URL, if you like. ## Source map support [Section titled “Source map support”](#source-map-support) Honeybadger can automatically un-minify your code if you provide a source map along with your minified JavaScript files. See our [Source Map Guide](/lib/javascript/errors/using-source-maps/) for details. ## Collect user feedback [Section titled “Collect user feedback”](#collect-user-feedback) When an error occurs, a form can be shown to gather feedback from your users. Read more about this feature [here](/lib/javascript/errors/collecting-user-feedback/). # Vue.js 2.x integration guide > Honeybadger monitors your Vue.js applications for errors and exceptions so that you can fix them wicked fast. **Typical installation time:** 5 minutes Hi there! You’ve found Honeybadger’s guide to **Vue.js 2.x error and exception tracking**. Once installed, Honeybadger will automatically report errors from your Vue.js application. ## Installation [Section titled “Installation”](#installation) Add *@honeybadger-io/js* and *@honeybadger-io/vue* as dependencies and configure. ```plaintext # npm npm add @honeybadger-io/js @honeybadger-io/vue --save # yarn yarn add @honeybadger-io/js @honeybadger-io/vue ``` In your main.js: ```javascript import Vue from "vue"; import HoneybadgerVue from "@honeybadger-io/vue"; const config = { apiKey: "PROJECT_API_KEY", environment: "production", revision: "git SHA/project version", }; Vue.use(HoneybadgerVue, config); ``` Note Errors that happen in development and test environments are not reported by default. To always report errors or to change the defaults, see [Environments and Versions](/lib/javascript/errors/environments-and-versions/#development-environments). ## Reporting errors [Section titled “Reporting errors”](#reporting-errors) Using the example configuration above, you’ll install *@honeybadger-ui/vue* as Vue’s error handler. Depending on the Vue version you’re using, the errors that Vue propagates through its own error handler may vary. Generally, rendering errors are passed in *Vue 2.0.0* and above, errors in component lifecycle hooks are handled in *Vue 2.2.0* and above, and errors in Vue custom event handlers will be passed through to `errorHandler` in *Vue 2.4.0* and above. Additionally, by default, an error handler for all JavaScript errors will be attached to the `window.onerror` handler for JavaScript errors that may originate from Vue components or other JavaScript on the page. Because Vue doesn’t intercept all errors that may occur within a Vue component, errors that bubble up to the `window.onerror` handler may be missing some Vue component contextual information, but the stack trace will be available. If, for some reason, you do not wish to install Honeybadger’s error handler on the global `window.onerror` handler, you may add `{ enableUncaught: false }` to the configuration when you’re registering `HoneybadgerVue`. You may also manually report errors by directly invoking the [honeybadger.js](https://github.com/honeybadger-io/honeybadger-js) API. ```javascript Vue.$honeybadger.notify(error); ``` See the [full documentation](/lib/javascript/) for more options. ## Identifying users [Section titled “Identifying users”](#identifying-users) Honeybadger can track which users have encountered each error. To identify the current user in error reports, add a user identifier and/or email address with `Vue.$honeybadger.setContext`: ```javascript Vue.$honeybadger.setContext({ user_id: 123, user_email: "user@example.com", }); ``` ## Sending additional context [Section titled “Sending additional context”](#sending-additional-context) Sometimes additional application state may be helpful for diagnosing errors. You can arbitrarily specify additional key/value pairs when you invoke `setContext`. ```javascript Vue.$honeybadger.setContext({ active_organization: 55, custom_configuration: false, }); ``` ## Clearing context [Section titled “Clearing context”](#clearing-context) If your user logs out or if your context changes during the Vue component lifetime, you can set new values as appropriate by invoking `setContext` again. Additionally, if needed, you can clear the context by invoking `clear`: ```javascript // Set the context to {} Vue.$honeybadger.clear(); ``` ## Advanced usage [Section titled “Advanced usage”](#advanced-usage) *@honeybadger-io/vue* is built on [honeybadger.js](https://github.com/honeybadger-io/honeybadger-js). Most configuration options can be passed in to the `config` object you pass when registering the `HoneybadgerVue` component with your Vue app instance. As of this release, there are no Vue-specific configuration options, but that may change as we learn more about Vue users’ unique needs. In general, configuration and context options supported by the JavaScript version of the library should work as is, aside from needing to reference `Vue.$honeybadger` instead of a global `Honeybadger` variable. See the [Honeybadger JavaScript integration documentation](/lib/javascript/) for additional customization options. ## Tracking deploys [Section titled “Tracking deploys”](#tracking-deploys) As with vanilla JavaScript applications, you can notify Honeybadger when you’ve deployed a new build. Honeybadger will associate an error report with a specific revision number (matching the `revision` field in the configuration when registering the `HoneybadgerVue` component). Here’s a simple `curl` script to record a deployment: ```sh HONEYBADGER_ENV="production" \ HONEYBADGER_REVISION="$(git rev-parse HEAD)" \ HONEYBADGER_REPOSITORY="$(git config --get remote.origin.url)" \ HONEYBADGER_API_KEY="Your project API key" \ && curl -g "https://api.honeybadger.io/v1/deploys?deploy[environment]=$HONEYBADGER_ENV&deploy[local_username]=$USER&deploy[revision]=$HONEYBADGER_REVISION&deploy[repository]=$HONEYBADGER_REPOSITORY&api_key=$HONEYBADGER_API_KEY" ``` Be sure that the same revision is also configured in the *@honeybadger-io/vue* library. Read more about deploy tracking in the [API docs](/api/deployments/). ### Tracking deploys from Netlify [Section titled “Tracking deploys from Netlify”](#tracking-deploys-from-netlify) If you are deploying your site to Netlify, you can notify Honeybadger of deployments via Netlify’s webhooks. Go to the **Deploy notifications** section of the **Build & deploy** tab for your site settings, and choose to add an Outgoing webhook notification. Choose `Deploy succeeded` as the event to listen for, and use this format for your URL: `https://api.honeybadger.io/v1/deploys/netlify?api_key=YOUR_HONEYBADGER_API_KEY_HERE` The environment that will be reported to Honeybadger defaults to the Netlify environment that was deployed, but you can override that with `&environment=CUSTOM_ENV` in the webhook URL, if you like. ## Source map support [Section titled “Source map support”](#source-map-support) Honeybadger can automatically un-minify your code if you provide a source map along with your minified JavaScript files. See our [Source Map Guide](/lib/javascript/errors/using-source-maps/) for details. ## Collect user feedback [Section titled “Collect user feedback”](#collect-user-feedback) When an error occurs, a form can be shown to gather feedback from your users. Read more about this feature [here](/lib/javascript/errors/collecting-user-feedback/). ## Sample applications [Section titled “Sample applications”](#sample-applications) Two sample applications are included in the `examples/` folder in the honeybadger-vue repository, one for vue 2.x and one for vue 3.x. You can follow the README.md inside each app to run them. # Vue.js 3.x integration guide > Honeybadger monitors your Vue.js applications for errors and exceptions so that you can fix them wicked fast. **Typical installation time:** 5 minutes Hi there! You’ve found Honeybadger’s guide to **Vue.js 3.x error and exception tracking**. Once installed, Honeybadger will automatically report errors from your Vue.js application. ## Installation [Section titled “Installation”](#installation) Add *@honeybadger-io/js* and *@honeybadger-io/vue* as dependencies and configure. ```shell # npm npm add @honeybadger-io/js @honeybadger-io/vue --save # yarn yarn add @honeybadger-io/js @honeybadger-io/vue ``` In your main.js (or main.ts): ```javascript import HoneybadgerVue from "@honeybadger-io/vue"; import { createApp } from "vue"; import App from "./App"; //your root component const app = createApp(App); const config = { apiKey: "PROJECT_API_KEY", environment: "production", revision: "git SHA/project version", }; app.use(HoneybadgerVue, config); app.mount("#app"); ``` Note Errors that happen in development and test environments are not reported by default. To always report errors or to change the defaults, see [Environments and Versions](/lib/javascript/errors/environments-and-versions/#development-environments). ## Using Vite for development [Section titled “Using Vite for development”](#using-vite-for-development) If you are using Vite for local development, you may get CORS errors in your browser console. To work around that, you can apply the following in your vite.config.js (or vite.config.ts): ```javascript export default defineConfig({ // ... server: { cors: false, }, }); ``` ## Reporting errors [Section titled “Reporting errors”](#reporting-errors) Using the example configuration above, you’ll install *@honeybadger-io/vue* as Vue’s error handler. By default, an error handler for all JavaScript errors will be attached to the `window.onerror` handler for JavaScript errors that may originate from Vue components or other JavaScript on the page. Because Vue doesn’t intercept all errors that may occur within a Vue component, errors that bubble up to the `window.onerror` handler may be missing some Vue component contextual information, but the stack trace will be available. If, for some reason, you do not wish to install Honeybadger’s error handler on the global `window.onerror` handler, you may add `{ enableUncaught: false }` to the configuration when you’re registering `HoneybadgerVue`. You may also manually report errors by directly invoking the [honeybadger.js](https://github.com/honeybadger-io/honeybadger-js) API. ### Composition API [Section titled “Composition API”](#composition-api) To access the Honeybadger instance when using the Composition API, use the `useHoneybadger` function: ```javascript ``` ### Options API [Section titled “Options API”](#options-api) To access the Honeybadger instance when using the Options API, use `this.$honeybadger`: ```javascript // inside a component this.$honeybadger.notify(error); ``` See the [full documentation](/lib/javascript/) for more options on how to call `notify()`. ## Identifying users [Section titled “Identifying users”](#identifying-users) Honeybadger can track which users have encountered each error. To identify the current user in error reports, add a user identifier and/or email address with `$honeybadger.setContext`: ```javascript // inside a component this.$honeybadger.setContext({ user_id: 123, user_email: "user@example.com", }); ``` ## Sending additional context [Section titled “Sending additional context”](#sending-additional-context) Sometimes additional application state may be helpful for diagnosing errors. You can arbitrarily specify additional key/value pairs when you invoke `setContext`. ```javascript // inside a component this.$honeybadger.setContext({ active_organization: 55, custom_configuration: false, }); ``` ## Clearing context [Section titled “Clearing context”](#clearing-context) If your user logs out or if your context changes during the Vue component lifetime, you can set new values as appropriate by invoking `setContext` again. Additionally, if needed, you can clear the context by invoking `clear`: ```javascript // inside a component this.$honeybadger.clear(); ``` ## Advanced usage [Section titled “Advanced usage”](#advanced-usage) *@honeybadger-io/vue* is built on [honeybadger.js](https://github.com/honeybadger-io/honeybadger-js). Most configuration options can be passed in to the `config` object you pass when registering the `HoneybadgerVue` component with your Vue app instance. As of this release, there are no Vue-specific configuration options, but that may change as we learn more about Vue users’ unique needs. In general, configuration and context options supported by the JavaScript version of the library should work as is, aside from needing to reference `this.$honeybadger` (or `app.$honeybadger` if you have access to your vue `app` instance) instead of a global `Honeybadger` variable. See the [Honeybadger JavaScript integration documentation](/lib/javascript/) for additional customization options. ## Tracking deploys [Section titled “Tracking deploys”](#tracking-deploys) As with vanilla JavaScript applications, you can notify Honeybadger when you’ve deployed a new build. Honeybadger will associate an error report with a specific revision number (matching the `revision` field in the configuration when registering the Honeybadger component). Here’s a simple `curl` script to record a deployment: ```sh HONEYBADGER_ENV="production" \ HONEYBADGER_REVISION="$(git rev-parse HEAD)" \ HONEYBADGER_REPOSITORY="$(git config --get remote.origin.url)" \ HONEYBADGER_API_KEY="Your project API key" \ && curl -g "https://api.honeybadger.io/v1/deploys?deploy[environment]=$HONEYBADGER_ENV&deploy[local_username]=$USER&deploy[revision]=$HONEYBADGER_REVISION&deploy[repository]=$HONEYBADGER_REPOSITORY&api_key=$HONEYBADGER_API_KEY" ``` Be sure that the same revision is also configured in the *@honeybadger-io/vue* library. Read more about deploy tracking in the [API docs](/api/deployments). ### Tracking deploys from Netlify [Section titled “Tracking deploys from Netlify”](#tracking-deploys-from-netlify) If you are deploying your site to Netlify, you can notify Honeybadger of deployments via Netlify’s webhooks. Go to the **Deploy notifications** section of the **Build & deploy** tab for your site settings, and choose to add an Outgoing webhook notification. Choose `Deploy succeeded` as the event to listen for, and use this format for your URL: `https://api.honeybadger.io/v1/deploys/netlify?api_key=YOUR_HONEYBADGER_API_KEY_HERE` The environment that will be reported to Honeybadger defaults to the Netlify environment that was deployed, but you can override that with `&environment=CUSTOM_ENV` in the webhook URL, if you like. ## Source map support [Section titled “Source map support”](#source-map-support) Honeybadger can automatically un-minify your code if you provide a source map along with your minified JavaScript files. See our [Source Map Guide](/lib/javascript/errors/using-source-maps/) for details. ## Collect user feedback [Section titled “Collect user feedback”](#collect-user-feedback) When an error occurs, a form can be shown to gather feedback from your users. Read more about this feature [here](/lib/javascript/errors/collecting-user-feedback/). ## Sample applications [Section titled “Sample applications”](#sample-applications) Two sample applications are included in the `examples/` folder in the honeybadger-vue repository, one for vue 2.x and one for vue 3.x. You can follow the README.md inside each app to run them. To create your own standalone Vue application, simply follow the [Quick Start](https://vuejs.org/guide/quick-start.html#with-build-tools) guide in Vue.js documentation. Remember to install Honeybadger Vue: ```bash npm add @honeybadger-io/js @honeybadger-io/vue ``` Then, in your `main.js`, you can follow the pattern in the source code in `examples/vue3/src/main.js`: ```javascript import { createApp } from "vue"; import App from "./App"; import router from "./router"; import HoneyBadgerVue from "@honeybadger-io/vue"; const app = createApp(App); app.use(HoneyBadgerVue, { apiKey: "your_api_key" }); app.use(router).mount("#app"); ``` # Configuration > Complete configuration reference for Honeybadger's JavaScript library with all available options and settings. ## Configuration file (server-side only) [Section titled “Configuration file (server-side only)”](#configuration-file-server-side-only) When using the JavaScript client in a Node.js environment, you can configure Honeybadger using a configuration file in your project’s root directory, such as `honeybadger.config.js` or `honeybadger.config.ts`. The configuration file should export an object with the configuration. An example configuration file is shown below: honeybadger.config.js ```javascript module.exports = { apiKey: process.env.HONEYBADGER_API_KEY, environment: process.env.NODE_ENV, revision: process.env.HONEYBADGER_REVISION, // etc. }; ``` ## Configuration options [Section titled “Configuration options”](#configuration-options) All of the available configuration options are shown below: ```javascript Honeybadger.configure({ // Honeybadger API key (required) apiKey: "", // The revision of the current deploy revision: "", // Project root projectRoot: "http://my-app.com", // Environment environment: "production", // Defaults to the server's hostname in Node.js hostname: "badger01", // Environments which will not report data developmentEnvironments: ["dev", "development", "test"], // Override `developmentEnvironments` to explicitly enable/disable error reporting // reportData: true, // Key values to filter from request data. Matches are partial, so "password" // and "password_confirmation" will both be filtered filters: ["creditcard", "password"], // Tags to apply to every reported error. Accepts an array of strings or a // comma-separated string. See "Tagging errors". tags: [], // Component (optional) component: "", // Action (optional) action: "", // Should unhandled errors be reported? // This option uses `window.onerror` in browsers and `uncaughtException` in Node.js enableUncaught: true, // Executed after an uncaught exception is reported in Node.js. // See "Uncaught exceptions" in the Node.js integration guide. // afterUncaught: (error) => {}, // Should unhandled Promise rejections be reported? enableUnhandledRejection: true, // Enable breadcrumbs collection breadcrumbsEnabled: true, // Insights instrumentation (off by default). `enabled` is the master switch; // `console` and `http` are ignored unless `enabled` is true. insights: { enabled: false, // Forward console logs to Honeybadger Insights console: false, // Emit request.handled events for inbound HTTP requests (server integrations) http: false, }, // Event delivery controls for Insights events: { // How often to flush buffered events, in seconds dispatchIntervalSeconds: 10, // Flush when this many events are buffered bulkThreshold: 500, // Percentage of events to send (0–100) sampleRatePercentage: 100, }, // Deprecated: use `insights.enabled` and `insights.console` instead. // Setting `eventsEnabled: true` auto-enables both (not `insights.http`) and // logs a deprecation warning. Explicit `insights` values win over the shim. // eventsEnabled: false, // Collector Host // If you are using our EU stack, this should be set to "https://eu-api.honeybadger.io". endpoint: "https://api.honeybadger.io", // The maximum number of breadcrumbs to include with error reports maxBreadcrumbs: 40, // The maximum depth allowed in deeply-nested objects maxObjectDepth: 8, // The logger to use. Should behave like `console` logger: console, // Output Honeybadger debug messages to the logger debug: false, }); ``` The following additional options are available in **browser environments**: ```javascript Honeybadger.configure({ // Send notifications asynchronously async: true, // Endpoint to submit user feedback for errors. See "Collecting User Feedback". // If you are using our EU stack, this should be set to "https://eu-api.honeybadger.io/v2/feedback". userFeedbackEndpoint: "https://api.honeybadger.io/v2/feedback", // Limit the maximum number of errors the client will send to Honeybadger // after page load. Default is unlimited (undefined) maxErrors: 20, // Ignore errors that originate from browser extensions (chrome-extension://, // moz-extension://, safari-extension://, safari-web-extension://). // Errors filtered by this option do not count against `maxErrors`. ignoreBrowserExtensionErrors: false, // Enable breadcrumbs collection breadcrumbsEnabled: true, // You can also selectively configure these types of breadcrumbs: // breadcrumbsEnabled: { // dom: true, // network: true, // navigation: true, // console: true // } // Element attributes to prefer when naming elements in click breadcrumbs. // See "Naming elements in click breadcrumbs" below. breadcrumbsSelectorAttributes: ["data-hb-name"], }); ``` The following additional options are available in **serverless environments** (currently AWS Lambda): ```javascript Honeybadger.configure({ // Report a warning to Honeybadger when a Lambda function is about to reach // its configured time limit reportTimeoutWarning: true, // How close (in milliseconds) the function must get to the Lambda time // limit before the timeout warning is reported timeoutWarningThresholdMs: 50, }); ``` See [Timeout warning](/lib/javascript/integration/node/#timeout-warning) in the Node.js integration guide for details. ### Naming elements in click breadcrumbs [Section titled “Naming elements in click breadcrumbs”](#naming-elements-in-click-breadcrumbs) When you click an element, Honeybadger records a `ui.click` breadcrumb containing a CSS selector for that element. By default the selector is built from each element’s tag, id, and classes, which can be hard to read in apps that use utility CSS frameworks such as Tailwind: ```plaintext body > div#root > main > div.flex.min-h-screen.flex-col.font-sans.antialiased > ... ``` To make these breadcrumbs legible, add a `data-hb-name` attribute to the elements you care about. When a clicked element — or one of its ancestors — has the attribute, its value replaces that element’s selector segment, and the nearest named ancestor anchors the selector, so everything above it is dropped. Given this markup: ```html

Acme Corp

``` Clicking the heading records the selector `deal-card > h3.text-left.font-semibold` instead of the full chain from ``. Use `breadcrumbsSelectorAttributes` to reuse attributes you already have, such as the test IDs from your test suite. The first attribute in the list that is present on an element wins: ```javascript Honeybadger.configure({ breadcrumbsSelectorAttributes: ["data-hb-name", "data-testid"], }); ``` Set the option to `[]` to disable this behavior and always build selectors from tags, ids, and classes. ## Configuring with environment variables [Section titled “Configuring with environment variables”](#configuring-with-environment-variables) Unlike some of our other client libraries, *honeybadger.js* does **not** automatically read configuration from environment variables; to use environment variables, you must configure Honeybadger like this: ```javascript Honeybadger.configure({ apiKey: process.env.HONEYBADGER_API_KEY, environment: process.env.NODE_ENV, revision: process.env.HONEYBADGER_REVISION, // etc. }); ``` Note that `process.env` may not be available outside of Node.js by default (it depends on your JavaScript build system). For example, [in Webpack you need to use `environmentPlugin`](https://webpack.js.org/plugins/environment-plugin/) to make `process.env` keys available in source files. ## `beforeEvent` handlers [Section titled “beforeEvent handlers”](#beforeevent-handlers) `beforeEvent` handlers run before each Insights event is sent to Honeybadger. Handlers may be synchronous or asynchronous. Return `false` (or a promise that resolves to `false`) to skip the event, or mutate the payload in place to change what is sent. See [Filtering events](/lib/javascript/insights/filtering-events/). ```javascript Honeybadger.beforeEvent((event) => { if (event.event_type === "request.handled" && event.path === "/health") { return false; } }); ``` ## `beforeNotify` handlers [Section titled “beforeNotify handlers”](#beforenotify-handlers) `beforeNotify` handlers run before each notice (error report) is sent to Honeybadger. There are two cases this might be useful: 1. Filtering out unwanted error reports by returning `false` from a handler 2. Sanitizing or enhancing notice data before being sent to Honeybadger ### Usage examples [Section titled “Usage examples”](#usage-examples) Sanitizing notice data: ```javascript Honeybadger.beforeNotify((notice) => { if (/creditCard/.test(notice.url)) { notice.url = "[FILTERED]"; } }); ``` Adding additional context to notice data: ```javascript Honeybadger.beforeNotify((notice) => { notice.context.session_id = MyApp.sessionId; }); ``` Adding additional context to notice data from an async source: ```javascript Honeybadger.beforeNotify(async (notice) => { notice.context.state = await MyApp.getState(); }); ``` Skipping a notice: ```javascript Honeybadger.beforeNotify((notice) => { if (/third-party-domain/.test(notice.stack)) { return false; } }); ``` ## `afterNotify` handlers [Section titled “afterNotify handlers”](#afternotify-handlers) `afterNotify` handlers run *after* each notice (error report) is sent to Honeybadger. Here are two cases where this is useful: 1. Displaying the ID of the Honeybadger notice to users 2. Handling errors if the Honeybadger API rejects the notice ### Usage examples [Section titled “Usage examples”](#usage-examples-1) Log a URL to the error report in Honeybadger: ```javascript Honeybadger.afterNotify((err, notice) => { if (err) { return console.log(`Honeybadger notification failed: ${err}`); } console.log( `Honeybadger notice: https://app.honeybadger.io/notice/${notice.id}`, ); }); ``` An `afterNotify` handler can also be attached to a single error report: ```javascript Honeybadger.notify("testing", { afterNotify: (err, notice) => console.log(err || notice.id), }); ``` ### Notice properties [Section titled “Notice properties”](#notice-properties) The following notice properties are available in `notice` objects: * `notice.stack` - The stack trace (read only) * `notice.backtrace` - The parsed backtrace object * `notice.name` - The exception class name * `notice.message` - The error message * `notice.url` - The current url * `notice.projectRoot` - The root url * `notice.environment` - Name of the environment. example: “production” * `notice.component` - Similar to a rails controller name. example: “users” * `notice.action` - Similar to a rails action name. example: “create” * `notice.fingerprint` - A unique fingerprint, used to customize grouping of errors in Honeybadger * `notice.context` - The context object * `notice.tags` - A string comma-separated list of tags * `notice.params` - An object of request parameters * `notice.session` - An object of request session key/values * `notice.headers` - An object of request headers * `notice.cookies` - An object of cookie key/values. May also be sent as a string in the document.cookie “foo=bar;bar=baz” format. The following additional notice properties are available in `afterNotify` handlers: * `notice.id` - The UUID of the error in Honeybadger # Supported versions > View supported browsers and Node.js versions for Honeybadger's JavaScript error tracking and application monitoring library. ## Browser [Section titled “Browser”](#browser) * [`@honeybadger-io/js`](https://github.com/honeybadger-io/honeybadger-js/tree/master/packages/js) works in **all modern browsers** and is tested back to the following versions: | Chrome | Edge | Firefox | Safari | | ------ | ---- | ------- | ------ | | 49.0 | 15.0 | 58.0 | 12.1 | * [`@honeybadger-io/webpack`](https://github.com/honeybadger-io/honeybadger-js/tree/master/packages/webpack) supports Webpack **v3+**. * [`@honeybadger-io/rollup-plugin`](https://github.com/honeybadger-io/honeybadger-js/tree/master/packages/rollup-plugin) supports Rollup **v3+**. ## Node.js [Section titled “Node.js”](#nodejs) * [`@honeybadger-io/js`](https://github.com/honeybadger-io/honeybadger-js/tree/master/packages/js) supports all [currently maintained Node.js releases](https://nodejs.org/en/about/releases/). # Frequently asked questions > Find answers to frequently asked questions about Honeybadger's JavaScript error tracking and application monitoring library. ## How do I ignore certain errors? [Section titled “How do I ignore certain errors?”](#how-do-i-ignore-certain-errors) Return `false` to a `Honeybadger.beforeNotify` handler: ```js Honeybadger.beforeNotify(function (notice) { if (/third-party-domain/.test(notice.stack)) { return false; } }); ``` For more information, see [Reducing Noise](/lib/javascript/errors/reducing-noise/). ## Why aren’t my Source Maps working? [Section titled “Why aren’t my Source Maps working?”](#why-arent-my-source-maps-working) Check out the [Troubleshooting](/lib/javascript/support/troubleshooting/#source-map-is-not-working) section. # Troubleshooting > Troubleshoot common issues with Honeybadger's JavaScript library and resolve integration problems. Common issues/workarounds for [`honeybadger.js`](https://github.com/honeybadger-io/honeybadger-js) are documented here. If you don’t find a solution to your problem here or in our [support documentation](/lib/javascript/#getting-support), email and we’ll assist you! ## Before you start troubleshooting [Section titled “Before you start troubleshooting”](#before-you-start-troubleshooting) 1. Make sure you are on the latest version of [*honeybadger.js*](https://github.com/honeybadger-io/honeybadger-js) 2. Enable the [`debug` config option](/lib/javascript/reference/configuration/) ## All errors are not reported [Section titled “All errors are not reported”](#all-errors-are-not-reported) If *no* errors are reported (even manually via `Honeybadger.notify`): 1. Is the [`apiKey` config option](/lib/javascript/reference/configuration/) configured? 2. Is the error ignored in a [`beforeNotify` callback](/lib/javascript/errors/reducing-noise/)? ## Uncaught errors are not reported [Section titled “Uncaught errors are not reported”](#uncaught-errors-are-not-reported) If you can report errors using `Honeybadger.notify`, but uncaught errors are not automatically reported: 1. Is the [`enableUncaught` config option](/lib/javascript/reference/configuration/#configuration-options) enabled? It must be enabled for uncaught errors to be reported. It is enabled by default. 2. Is Honeybadger’s `window.onerror` callback installed? Check `window.onerror` in the console and make sure it originates in honeybadger.js or honeybadger.min.js (or wherever you are hosting our JavaScript). If it doesn’t, it’s possible some 3rd-party code is overriding our callback. 3. If the error originates in a file hosted on a different domain, is CORs enabled? If you host your assets on a CDN (or if the domain is different from where your HTML is served) you may need to enable CORS on your asset domain for the `window.onerror` errors to be reported. See for more info. If this is the issue, you should see logs similar to this: ```plaintext [Log] [Honeybadger] Ignoring cross-domain script error. ``` 4. Does your application or framework handle errors internally? If you’re using a framework, search the documentation for “error handling”. For example, Ember provides its own `Ember.onerror` callback which you must configure in order for uncaught errors to be reported: ```js Ember.onerror = function (error) { Honeybadger.notify(error); }; ``` ## Errors are reported twice [Section titled “Errors are reported twice”](#errors-are-reported-twice) 1. If it’s a React app, are you running in dev mode? React’s [Strict Mode](https://reactjs.org/docs/strict-mode.html#detecting-unexpected-side-effects) may cause double rendering, causing Honeybadger to report multiple errors. This shouldn’t be a problem in your production build. For more info, see [github.com/honeybadger-io/honeybadger-react#247](https://github.com/honeybadger-io/honeybadger-react/issues/247) ## Source map is not working [Section titled “Source map is not working”](#source-map-is-not-working) Note These steps are supplemental to the **Source Maps Debug Tool**. If you haven’t checked it out yet, start there first! You can find it by visiting *Project Settings → Source Maps → Debug Tool* in your Honeybadger project (if you don’t see the “Source Maps” tab, you may need to go to *Project Settings → Edit* and change the language to “Client-side JavaScript”, “Node.js”, etc.). ### Did the error happen *before* the source map was uploaded? [Section titled “Did the error happen before the source map was uploaded?”](#did-the-error-happen-before-the-source-map-was-uploaded) Honeybadger **does not** apply source maps to errors that have already occurred. If the error in question first occurred before the source map was uploaded, that’s likely the problem—look for a newer version of the error. You may also want to delete the old error in the Honeybadger UI to avoid confusion. ### Did the build process modify the output *after* it generated your source map? [Section titled “Did the build process modify the output after it generated your source map?”](#did-the-build-process-modify-the-output-after-it-generated-your-source-map) If a source map is available but translation is not working, **make sure that your build process did not add extra lines/comments to the top of your minified JavaScript file**, which could throw off the mapping information. For example, line 1 column 123 would become line 2 column 123, which would not translate. Likewise, **ensure that your build process or CDN does not minify the file twice.** Some CDN providers (such as Cloudflare) can auto-minify your JavaScript files after you upload them—such options should be disabled. ### If you are hosting your source map [Section titled “If you are hosting your source map”](#if-you-are-hosting-your-source-map) In some cases a few minified errors may get through before we have the chance to download and process your hosted source map. If your source map is not being applied to your errors after the first few minutes: 1. Is your minified file publicly accessible? Try downloading it with `curl`: ```sh curl https://www.example.com/assets/application.min.js ``` 2. Does the [`minified_url`](https://docs.honeybadger.io/lib/javascript/errors/using-source-maps/#uploading-your-source-map) point to the correct URL? If you are using [@honeybadger-io/webpack](https://github.com/honeybadger-io/honeybadger-js/tree/master/packages/webpack) or [@honeybadger-io/rollup-plugin](https://github.com/honeybadger-io/honeybadger-js/tree/master/packages/rollup), this parameter is built using the [`assetsUrl`](https://github.com/honeybadger-io/honeybadger-js/tree/master/packages/webpack#plugin-parameters) parameter. 3. Does your minified file have [the `sourceMappingURL` comment](/lib/javascript/errors/using-source-maps/#hosting-your-source-map)? 4. Is your Source Map file publicly accessible? Try downloading it with `curl`: ```sh curl https://www.example.com/assets/application.min.js.map ``` 5. If using [Authentication](/lib/javascript/errors/using-source-maps/#authentication), is the `Honeybadger-Token` header validated correctly? Try downloading with `curl`: ```sh curl -H"Honeybadger-Token: token" https://www.example.com/assets/application.min.js.map ``` ### If you are uploading your source map [Section titled “If you are uploading your source map”](#if-you-are-uploading-your-source-map) 1. Navigate to **Project Settings** -> **Source Maps** -> **Uploaded Source Maps**, then: 2. Does the **Minified URL** for your source map match the minified URL in your JavaScript stack trace? The URLs must match exactly, with the exception of [wildcards](/api/reporting-source-maps/#wildcards) and query strings (which are ignored). 3. Does the **revision** match the `revision` key in the **Application Environment** section of the error page? If it doesn’t, [make sure the `revision` of your uploaded source map is the same as the `revision` configured in `honeybadger.js`](/lib/javascript/errors/using-source-maps/#versioning-your-project). 4. Was the source map uploaded **before** the first error for that revision occurred? Source mappings are cached, meaning that uploading the source map after the error occurred has no effect. The only way to get a new mapping in this case is to deploy a new revision, making sure the source map upload completes before the code is live. 5. If your build process includes compression, make sure your source map files are not compressed (such as with gzip compression) when you upload them. 6. Can you parse your source map as JSON? Source map files must be valid JSON. ## Error in `beforeNotify` handler [Section titled “Error in beforeNotify handler”](#error-in-beforenotify-handler) If you’re using *honeybadger.js* < 1.0.4, upgrade to a more recent version. [1.0.4 fixed a bug in `beforeNotify`](https://github.com/honeybadger-io/honeybadger-js/blob/master/CHANGELOG.md#104---2019-06-12) which prevented some properties from being available on the notice object (which would most likely result in `ReferenceError` in certain use cases). # Upgrading to @honeybadger-io/js v3.0 > Upgrade guide for migrating to Honeybadger JavaScript library v3 with breaking changes and new features. The new [@honeybadger-io/js](https://www.npmjs.com/package/@honeybadger-io/js) package is a universal/isomorphic JavaScript package combining the deprecated [honeybadger-js for browsers](https://www.npmjs.com/package/honeybadger-js) and the [honeybadger for Node.js](https://www.npmjs.com/package/honeybadger) NPM packages. **Moving forward, development for both platforms will happen on @honeybadger-io/js** ([source code on GitHub](https://github.com/honeybadger-io/honeybadger-js)). The new API is mostly the same as the old packages, with a few small changes. ## Upgrading from honeybadger-js v2.x (client-side) [Section titled “Upgrading from honeybadger-js v2.x (client-side)”](#upgrading-from-honeybadger-js-v2x-client-side) If you currently use the [honeybadger-js](https://www.npmjs.com/package/honeybadger-js) package, this section is for you. The changes between *honeybadger-js* and *@honeybadger-io/js* are minimal. First, replace the old package with the new one: ```sh npm uninstall honeybadger-js npm install @honeybadger-io/js ``` Next, replace any `require`/`import` statements that reference “honeybadger-js”: ```js const Honeybadger = require("@honeybadger-io/js"); // Or: // import Honeybadger from '@honeybadger-io/js'; Honeybadger.configure({ apiKey: "project api key", environment: "production", revision: "git SHA/project version", }); ``` Finally, review this list of changes: * Previously deprecated snake case config options such as `api_key`, `project_root`, etc. are no longer supported. Use `apiKey`, `projectRoot` instead. * Stack traces are now parsed client-side; `notice.stack` is now read-only in [`beforeNotify` handlers](/lib/javascript/reference/configuration/#beforenotify-handlers), and a new `notice.backtrace` object has been added. * The `max_depth` config option is now `maxObjectDepth` * The `host` and `port` config options are now `endpoint` * `onerror` is now `enableUncaught` * The `onunhandledrejection` config option is now `enableUnhandledRejection` * The `ignorePatterns` config option has been removed. Use a [`beforeNotify` handler](/lib/javascript/reference/configuration/#beforenotify-handlers) instead: ```js const ignorePatterns = [/NoisyError/i, /unwanted error message/i]; Honeybadger.beforeNotify(function (notice) { if (ignorePatterns.some((p) => p.test(notice.message))) { return false; } }); ``` * `Honeybadger.wrap` [has been removed](https://github.com/honeybadger-io/honeybadger-js/pull/506). If you used this functionality, you can recreate it like so: ```js Honeybadger.wrap = function (func) { try { func.apply(this, arguments); } catch (error) { Honeybadger.notify(error); throw error; } }; ``` See [configuration](/lib/javascript/reference/configuration/) for an up-to-date list of available config options. Feel free to [email support](mailto:support@honeybadger.io?subject=honeybadger-js%20v3%20upgrade) if you run into issues not mentioned here. ### CDN users [Section titled “CDN users”](#cdn-users) If you use the CDN instead of the NPM package, replace your current script tag with the **v3.0** script tag: ```html ``` ## Upgrading from honeybadger 1.x (Node.js) [Section titled “Upgrading from honeybadger 1.x (Node.js)”](#upgrading-from-honeybadger-1x-nodejs) If you currently use the [honeybadger](https://www.npmjs.com/package/honeybadger) package, this section is for you. First, replace the old package with the new one: ```sh npm uninstall honeybadger npm install @honeybadger-io/js ``` Next, replace any `require` statements that reference “honeybadger-js”: ```js const Honeybadger = require("@honeybadger-io/js"); Honeybadger.configure({ apiKey: "project api key", environment: "production", revision: "git SHA/project version", }); ``` Finally, review this list of changes: * Environment variables are no longer configured by default; you must explicitly call `Honeybadger.configure`, i.e.: ```js Honeybadger.configure({ apiKey: process.env.HONEYBADGER_API_KEY, environment: process.env.HONEYBADGER_ENVIRONMENT, }); ``` * [`Honeybadger.logger`](https://github.com/honeybadger-io/honeybadger-node#configuring-the-default-logger) is now the [`logger` config option](/lib/javascript/reference/configuration/#configuration-options). * [`Honeybadger.onUncaughtException`](https://github.com/honeybadger-io/honeybadger-node#honeybadgeronuncaughtexception-configure-the-uncaught-exception-handler) is now the [`afterUncaught` config option](/lib/javascript/reference/configuration/#configuration-options). * [Events](https://github.com/honeybadger-io/honeybadger-node#events) are no longer emitted. Use [`beforeNotify` and `afterNotify` handlers instead](/lib/javascript/reference/configuration/#beforenotify-handlers). See [configuration](/lib/javascript/reference/configuration/) for an up-to-date list of available config options. Feel free to [email support](mailto:support@honeybadger.io?subject=honeybadger-js%20v3%20upgrade) if you run into issues not mentioned here. # Unofficial client libraries > Are you using a language or framework that we don't officially support yet? You still have a few options! Are you using a language or framework that we don’t officially support yet? You still have a few options: * Try one of our [community packages](#community-packages) * Report errors using our [exceptions API](/api/reporting-exceptions/) ## Community packages [Section titled “Community packages”](#community-packages) Here are some unofficial client libraries that were created by the Honeybadger community. We can’t guarantee that they’re up to date or that they’ll work for you, but we’re happy to link to them here. To add your project, [send us an email](mailto:support@honeybadger.io). ### MakerKit (Next.js) [Section titled “MakerKit (Next.js)”](#makerkit-nextjs) [MakerKit](https://makerkit.dev/) is a Next.js SaaS starter kit that gives you a full B2B application foundation so you can ship a SaaS product fast instead of building infrastructure from scratch. See the following integration guides for instructions: * [Next.js Supabase](https://makerkit.dev/docs/next-supabase-turbo/monitoring/honeybadger) * [Next.js Drizzle](https://makerkit.dev/docs/nextjs-drizzle/monitoring/honeybadger) * [Next.js Prisma](https://makerkit.dev/docs/nextjs-prisma/monitoring/honeybadger) See our [official Next.js integration guide](/lib/javascript/integration/nextjs/) for further reference. ### Go (golang) [Section titled “Go (golang)”](#go-golang) * [agonzalezro/goneybadger (Go)](https://github.com/agonzalezro/goneybadger) * [DavidHuie/gobadger (Go)](https://github.com/DavidHuie/gobadger) * [remind101/pkg (Go)](https://github.com/remind101/pkg/tree/master/reporter/hb2) ### Java [Section titled “Java”](#java) * [styleseek/honeybadger-java (Java)](https://github.com/styleseek/honeybadger-java) * [dekobon/honeybadger-jvm-client-v2 (Java)](https://github.com/dekobon/honeybadger-jvm-client-v2) * [Workable/honeybadger-java (Java)](https://github.com/Workable/honeybadger-java) ### Elixir/Erlang [Section titled “Elixir/Erlang”](#elixirerlang) * [barsoom/content\_translator (Elixir)](https://github.com/barsoom/content_translator/blob/master/lib/error_reporting_backend.ex) * [fyler/lager\_honeybadger\_backend (Erlang)](https://github.com/fyler/lager_honeybadger_backend) ### Scala [Section titled “Scala”](#scala) * [alno’s gist (Scala)](https://gist.github.com/alno/fd2eadfd776bad03ee3d) ### C\# [Section titled “C#”](#c) * [webnuts/Honeybadger.ErrorReporter (C#)](https://github.com/webnuts/Honeybadger.ErrorReporter) # Honeybadger for PHP > Documentation for Honeybadger's PHP error tracking library. Hi there! You’ve found Honeybadger’s docs on **PHP exception tracking**. In these guides we’re going to discuss [`honeybadger-php`](https://github.com/honeybadger-io/honeybadger-php) and how to use it to track exceptions in your PHP applications. ## How you should read the docs [Section titled “How you should read the docs”](#how-you-should-read-the-docs) * If you’re installing Honeybadger in your **Laravel** application for the first time, check out the **[Laravel Integration Guide](/lib/php/integration/laravel/)**. If you use a different framework, start with the **[General Integration Guide](/lib/php/integration/other/)** instead. * The **How-To Guides** (in the left-hand navigation menu) are general guides on how to do things with the library, and should apply to all types of applications. * There is a wealth of additional knowledge about Honeybadger in the **Library Reference** and **Support** sections. ## Getting support [Section titled “Getting support”](#getting-support) If you’re having trouble working with the library (such as you aren’t receiving error reports when you should be): 1. Upgrade to the latest version if possible (you can find a list of bugfixes and other changes in the [CHANGELOG](https://github.com/honeybadger-io/honeybadger-php/blob/master/CHANGELOG.md)) 2. Check out our [Frequently Asked Questions](/lib/php/support/faq/) 3. Run through the [Troubleshooting guide](/lib/php/support/troubleshooting/) 4. If you believe you’ve found a bug, [submit an issue on GitHub](https://github.com/honeybadger-io/honeybadger-php/issues/) For all other problems, contact support for help: # Capturing events with breadcrumbs > Learn how to use breadcrumbs to track events leading up to errors. When your application encounters an error, it’s often helpful to know what events occurred leading up to that. Honeybadger lets you do that with *breadcrumbs*. Breadcrumbs are records of events that happened within your application — external API calls, job dispatches, database queries, or anything that you think might be relevant. When we capture an error, we display these breadcrumbs in your dashboard to provide extra debugging information. ![Breadcrumbs](/_astro/php_breadcrumbs.BVlDCoST_Zrpw27.webp) Use [context](/lib/php/errors/customizing-error-reports/#custom-metadata-context) to record request-global data like the current user ID; use breadcrumbs to record specific events within the request and their custom metadata. ## Automatic breadcrumbs [Section titled “Automatic breadcrumbs”](#automatic-breadcrumbs) If you’re using Laravel or Lumen, Honeybadger can automatically capture breadcrumbs from your app. By default, we’ll record: * [Log events](https://laravel.com/docs/logging) * [View renders](https://laravel.com/docs/views) * [Email dispatches](https://laravel.com/docs/mail) * [Job dispatches](https://laravel.com/docs/queues) * [Notification dispatches](https://laravel.com/docs/notifications) * [Database queries](https://laravel.com/docs/queries) * [Redis commands](https://laravel.com/docs/redis) * Incoming requests You can customise this with the `breadcrumbs` option in your `config/honeybadger.php`: ```php 'breadcrumbs' => [ 'enabled' => true, 'automatic' => [ Breadcrumbs\DatabaseQueryExecuted::class, Breadcrumbs\DatabaseTransactionStarted::class, Breadcrumbs\DatabaseTransactionCommitted::class, Breadcrumbs\DatabaseTransactionRolledBack::class, Breadcrumbs\CacheHit::class, Breadcrumbs\CacheMiss::class, Breadcrumbs\JobQueued::class, Breadcrumbs\MailSending::class, Breadcrumbs\MailSent::class, Breadcrumbs\MessageLogged::class, Breadcrumbs\NotificationSending::class, Breadcrumbs\NotificationSent::class, Breadcrumbs\NotificationFailed::class, Breadcrumbs\RedisCommandExecuted::class, Breadcrumbs\RouteMatched::class, Breadcrumbs\ViewRendered::class, ], ], ``` The `breadcrumbs.automatic` key contains the list of the events Honeybadger tracks by default. You can disable a specific event by removing or commenting out the appropriate line. ## Custom breadcrumbs [Section titled “Custom breadcrumbs”](#custom-breadcrumbs) You can also record breadcrumb events manually. This can be helpful if you aren’t using a supported framework, or there are additional events in your application that Honeybadger doesn’t recognize. To add a breadcrumb, use `$honeybadger->addBreadcrumb($message, $metadata, $category)`: ```php $honeybadger = Honeybadger\Honeybadger::new(['api_key' => 'PROJECT_API_KEY']); $honeybadger->addBreadcrumb("Notification sent", ['user_id' => $user->id, 'type' => 'welcome']); $honeybadger->addBreadcrumb("Payment webhook received", ['service' => 'Stripe'], 'webhooks'); // If you're using Laravel or Lumen, you can also use the Facade or service container app('honeybadger')->addBreadcrumb("Notification sent", ['user_id' => $user->id, 'type' => 'welcome']); Honeybadger::addBreadcrumb("Notification sent", ['user_id' => $user->id, 'type' => 'welcome'], 'notifications'); ``` ![Custom breadcrumbs](/_astro/php_custom_breadcrumbs.DbCe_AYo_Z1ac1iu.webp) The `addBreadcrumb()` method has one required parameter, `message`. The message should be a terse summary of the event, which we’ll display prominently in the UI for each breadcrumb. You can also provide: * `metadata`, a key-value array of contextual data about the event. The metadata should be a single-level array with simple primitives as values (strings, integers, floats, or booleans). * `category`, a string key used to classify and group events. See [Categories](#categories) for more details. For each event, the Honeybadger client will automatically add a timestamp, so you don’t need to include that yourself. ## Categories [Section titled “Categories”](#categories) A `category` is a top level property of a breadcrumb. Categories are helpful so events can be presented differently on your project dashboard; for instance, `error` breadcrumbs are styled with a red “error” icon. Feel free to give a breadcrumb any category you wish. Any categories we don’t recognize will use the default ‘custom’ styling. Here are the recognized categories and a description of how you might categorize certain activity: | Category | Description | | -------- | ------------------------------------------- | | custom | Any other kind of breadcrumb | | error | A thrown error | | query | Access or Updates to any data or file store | | job | Queueing or Working via a job system | | request | Outbound / inbound requests | | render | Any output or serialization via templates | | log | Any messages logged | | notice | A Honeybadger Notice | ## Disabling breadcrumbs [Section titled “Disabling breadcrumbs”](#disabling-breadcrumbs) To turn off collection of breadcrumbs, use the `breadcrumbs.enabled` configuration option: ```php $honeybadger = \Honeybadger\Honeybadger::new([ 'api_key' => 'PROJECT_API_KEY', 'breadcrumbs' => [ 'enabled' => false, ], ]); ``` When you do this, the Honeybadger client will stop any automatic collection of breadcrumbs and the `addBreadcrumb()` method will do nothing. ## Limits [Section titled “Limits”](#limits) We use the following limits on breadcrumbs to ensure the service operates smoothly for everyone: * We only store & transmit the last 40 breadcrumb events for any error. * Metadata can only hold scalar values (no objects, arrays or PHP resources) * String values have a maximum size of 64Kb # Capturing function call arguments > Configure PHP to include function arguments in error backtraces. Sometimes it’s helpful to see what arguments a function was called with, so you can replicate the issue and figure out the cause of the error. By default, Honeybadger will automatically include function arguments when rendering the backtrace on your dashboard. However, on some versions of PHP, you may need to enable this. PHP 7.4 and later comes with the [zend.exception\_ignore\_args](https://www.php.net/manual/en/ini.core.php#ini.zend.exception-ignore-args) setting in the `php.ini` file. This setting is designed to protect you from accidentally divulging sensitive information to the outside world. When this setting is set to “On”, function arguments won’t be included in traces. If you expose your stack traces to outside users, you may want to keep this as “On”. However, if your traces are only sent to your logs and trusted services like Honeybadger, it’s typically safe to set this to “Off”. If you’d like Honeybadger to capture function arguments, you’ll need to set this to “Off”. To do this: * Locate your ini file by running `php --ini`. * Open the ini file and change the value of `zend.exception_ignore_args` to “Off” ```ini ; Allows to include or exclude arguments from stack traces generated for exceptions ; Default: Off ; In production, it is recommended to turn this setting on to prohibit the output ; of sensitive information in stack traces zend.exception_ignore_args = Off ``` # Collecting user feedback > Learn how to display error IDs and collect user feedback on Laravel error pages. We don’t want our users to be interrupted by errors, but sometimes it does happen. Honeybadger helps you work with your users to fix errors by linking user requests to error occurrences and allowing users to leave relevant feedback on errors. If you’re using Laravel, the `honeybadger-io/honeybadger-laravel` package comes with a few handy Blade directives to make your error pages more proactive. ## Prerequisites [Section titled “Prerequisites”](#prerequisites) First off, you’ll need to [publish Laravel’s inbuilt error pages](https://laravel.com/docs/errors#custom-http-error-pages) or create your own. Then you can add our directives to the Blade template. If you’re using Laravel’s error views, the default base template is `minimal.blade.php`. Note that if you’re on development, you’ll only see [the Ignition error page](https://github.com/facade/ignition). To see the production error views, set `APP_DEBUG` in your `.env` file to `false`. ## Displaying the error ID [Section titled “Displaying the error ID”](#displaying-the-error-id) Whenever you send an error to Honeybadger, we return a unique UUID for that occurrence. You can easily jump to the error details at any time by visiting [https://app.honeybadger.io/notice/{the-error-uuid}](https://app.honeybadger.io/notice/%7Bthe-error-uuid%7D). You can also set the UUID to be automatically displayed on error pages, to serve as a reference. To do this, use the `@honeybadgerError` directive in your Blade error template: ```php
@yield('code')
@yield('message')
@honeybadgerError
``` You can place the directive anywhere you wish on your page, and we’ll replace it with ```plaintext Error ID: {the error ID} ``` If you wish to style the error view or customize the text, you can also pass `class` or `text` arguments to the directive: ```php @honeybadgerError(["class" => "uppercase text-gray-500", "text" => "Your error ID is: "]) ``` ## Displaying a feedback form [Section titled “Displaying a feedback form”](#displaying-a-feedback-form) ![Feedback Form on Laravel](/_astro/laravel_feedback_form.DkSH_Raw_1W5xvN.webp) Honeybadger comes with an HTML form so users can provide additional helpful information about what led up to that error. Feedback responses are displayed inline in the Comments section on the error detail page. To include the feedback form on your error page, use the `@honeybadgerFeedback` directive. You can change the text displayed in the form via the [Laravel localization system](https://laravel.com/docs/localization). Here’s an example: resources/lang/vendor/honeybadger/en/feedback.php ```php return [ 'thanks' => 'Thanks for the feedback!', 'heading' => 'Care to help us fix this?', 'explanation' => 'Any information you can provide will help our technical team get to the bottom of this issue.', 'labels' => [ 'name' => 'Your name', 'phone' => 'Your phone number', 'email' => 'Your email address', 'comment' => 'Comment (required)', ], 'submit' => 'Send', ]; ``` ## Advanced customization [Section titled “Advanced customization”](#advanced-customization) We’ve optimized the error ID and feedback form so they render well in the default Laravel error template (`minimal.blade.php`), but your setup might be different from that. In that case, you can publish the corresponding views and customize them as you like: ```bash php artisan vendor:publish --tag honeybadger-views ``` The views will be published to `resources/views/vendor/honeybadger`, where you can customize them as you wish, and Laravel will load your customized version. # Customizing error grouping > Learn how to customize how errors are grouped in Honeybadger. Honeybadger groups similar exceptions together using rules which we’ve found to work the best in most cases. The default information we use to group errors is: 1. The file name, method name, and line number of the error’s location 2. The class name of the error 3. The component/controller name We use this information to construct a “fingerprint” of the exception. Exceptions with the same fingerprint are treated as the same error in Honeybadger. You can customize the grouping for each exception by changing the error class name, component, or stack trace—or by sending a custom fingerprint. The `fingerprint` option can be used to override the fingerprint for an exception reported with the `notify()` method: ```php $honeybadger->notify(exception, $request, ['fingerprint' => 'a unique string']) ``` # Customizing error reports > Learn how to customize error reports with metadata and request information. Honeybadger has several ways to customize the data reported with each error to add custom metadata and request information. ## Custom metadata (context) [Section titled “Custom metadata (context)”](#custom-metadata-context) Honeybadger can display additional custom key/value metadata — or “context” — with each error report. Context data can be anything, but a few keys have a special meaning in Honeybadger. Use `$honeybadger->context();` to add global context to error reports: ```php $honeybadger->context('user_id', 123); // Add multiple context items: $honeybadger->context([ 'user_id' => 123, 'user_email' => 'homer@simpsons.com', ]); ``` *** While you can add any key/value data to context, a few keys have special meaning in Honeybadger: | Option | Description | | ------------ | ----------------------------------------------------------------------------------------------------- | | `user_id` | The `String` user ID used by Honeybadger to aggregate user data across occurrences on the error page. | | `user_email` | Same as `user_id`, but for email addresses | ## Sending request information [Section titled “Sending request information”](#sending-request-information) Honeybadger automatically includes request information for error reports in Laravel/Lumen. In other frameworks which rely on Symphony’s HttpFoundation component, you can include request information when reporting exceptions: ```php $honeybadger->notify($error, $request); ``` # Environments > Configure environments in Honeybadger for PHP applications. Honeybadger groups errors by the environment they belong to. You don’t have to set an environment, but it can be useful if you’re running your app in different locations, such as “production” and “staging”. To set the environment in Honeybadger, add the `environment_name` setting to your [configuration](/lib/php/reference/configuration/): ```php [ 'environment_name' => 'production', ] ``` Honeybadger reports errors in all environments that also have an API key configured. # Filtering sensitive data > Learn how to filter sensitive data from error reports. When Honeybadger includes request or environment data in error reports, you may want to exclude sensitive keys. We try to provide sane defaults, but you should always review the data you’re reporting to make sure you aren’t leaking sensitive information. There are two types of potentially sensitive data in Honeybadger: [Request Parameters](#request-parameters) and [Environment Keys](#environment-keys). ## Request parameters [Section titled “Request parameters”](#request-parameters) You can filter sensitive request parameters using the [`request['filter']` configuration option](/lib/php/reference/configuration/). The value should be an array of keys to filter. Honeybadger filters the following keys by default: ```php [ 'request' => [ 'filter' => [ 'password', 'password_confirmation' ], ], ] ``` ## Environment keys [Section titled “Environment keys”](#environment-keys) Honeybadger maintains a [whitelist of environment keys](/lib/php/reference/configuration/#environment-whitelist), so you don’t usually have to worry about leaking sensitive configuration such as API keys or passwords to 3rd-party services. If you *do* need to filter some of the default keys, Honeybadger has you covered with the `environment['filter']` configuration option. You can also add additional keys to the whitelist with the `environment['include']` option, if you’re sure you always want to report them: ```php [ 'environment' => [ // Environment keys to filter before the payload sent to Honeybadger 'filter' => [], // Additional environment keys to include 'include' => [], ], ] ``` # Reducing noise > Learn how to ignore exceptions and reduce alert fatigue in your php applications. Sometimes there are errors that you would rather not send to Honeybadger because they are not actionable or are handled internally. In Honeybadger, you can [ignore exceptions by type](#ignoring-exceptions-by-type) using the built-in `excluded_exceptions` configuration option, as well as the `$dontReport` option in [Laravel](#laravel). You can also disable error reporting in all or some environments. ## Ignoring exceptions by type [Section titled “Ignoring exceptions by type”](#ignoring-exceptions-by-type) There may be some types of exceptions which you never want to report. To ignore them, use the `excluded_exceptions` [configuration option](/lib/php/reference/configuration/): ```php [ 'excluded_exceptions' => [ SomeException::class, AnotherException::class, ], ] ``` ### Laravel [Section titled “Laravel”](#laravel) If you’re using [Laravel](/lib/php/integration/laravel/), Honeybadger respects the `$dontReport` property of Laravel’s [exception handler](https://laravel.com/docs/5.6/errors/#the-exception-handler) when automatically reporting exceptions during web requests. This means that any exceptions which are ignored by Laravel will also be ignored by Honeybadger. You may add other exception types to this array as needed: app/Exceptions/Handler.php ```php /** * A list of the exception types that should not be reported. * * @var array */ protected $dontReport = [ \Illuminate\Auth\AuthenticationException::class, \Illuminate\Auth\Access\AuthorizationException::class, \Symfony\Component\HttpKernel\Exception\HttpException::class, \Illuminate\Database\Eloquent\ModelNotFoundException::class, \Illuminate\Validation\ValidationException::class, ]; ``` Keep in mind that Honeybadger will still report exceptions on this list if they are reported *outside* of Laravel’s exception handler, such as when [reporting handled exceptions](/lib/php/errors/reporting-errors#reporting-handled-exceptions/). ## Ignoring exceptions programmatically [Section titled “Ignoring exceptions programmatically”](#ignoring-exceptions-programmatically) You can use the `beforeNotify` callback to ignore exceptions programmatically. This callback is called before an exception is sent to Honeybadger. If the callback returns `false`, the exception will not be reported. For example, you can ignore exceptions based on the exception message: ```php $honeybadger->beforeNotify(function (&$notice) { if (strpos($notice['error']['message'], 'Ignore this exception') !== false) { return false; } }); ``` Or, you may modify the fingerprint of the exception to group it with other similar exceptions: ```php $honeybadger->beforeNotify(function (&$notice) { $notice['error']['fingerprint'] = 'MyFingerprint'; }); ``` **Note**: You can register multiple `beforeNotify` callbacks. If any of them return `false`, the exception will not be reported. ### Notice properties [Section titled “Notice properties”](#notice-properties) The `$notice` parameter is an associative array that contains the following keys: * `breadcrumbs` * `enabled`: Indicates if breadcrumbs are enabled, fetched from the configuration * `trail`: The breadcrumb trail converted to an array of associative arrays, each containing: * `message`: The message of the breadcrumb * `category`: The category of the breadcrumb * `metadata`: An associative array of metadata for the breadcrumb * `timestamp`: The timestamp of the breadcrumb * `error` * `class`: The type of the exception. * `message`: The exception message. * `backtrace`: The backtrace of the exception. * `causes`: The previous exceptions in the backtrace. * `fingerprint`: A grouping identifier for the error, if provided. * `tags`: Tags associated with the error, wrapped in an array. * `request` * `cgi_data`: CGI data from the environment, or an empty object if not available. * `params`: Request parameters, or an empty object if not available. * `session`: Session data, or an empty object if not available. * `url`: The request URL. * `context`: Context data or an empty object if not available. * `component`: The component name, either from additional parameters or context. * `action`: The action name, either from additional parameters or context. * `server` * `pid`: The process ID. * `version`: The application version. * `hostname`: The hostname of the server. * `project_root`: The root directory of the project. * `environment_name`: The name of the environment. ## Disabling error reporting [Section titled “Disabling error reporting”](#disabling-error-reporting) You can disable error reporting completely by setting the `report_data` config option to false. For example, the default Laravel config has this as: ```php 'report_data' => ! in_array(env('APP_ENV'), ['local', 'testing']), ``` This means exceptions won’t be reported to Honeybadger in `local` and `testing` environments. If you want to change that, you can easily add or remove environments or set `report_data` to `true`. # Reporting errors > Learn how to report errors to Honeybadger in PHP applications. Honeybadger reports uncaught exceptions automatically. In all other cases, use `$honeybadger->notify()` and `$honeybadger->customNotification()` to send errors to Honeybadger. ## Reporting unhandled exceptions [Section titled “Reporting unhandled exceptions”](#reporting-unhandled-exceptions) By default, `honeybadger-php` registers global error and exception handlers which automatically report all unhandled exceptions to Honeybadger. These handlers can be disabled via the following [configuration options](/lib/php/reference/configuration/#default-configuration): ```php [ 'handlers' => [ // Enable global exception handler 'exception' => true, // Enable global error handler 'error' => true, ] ] ``` ## Reporting handled exceptions [Section titled “Reporting handled exceptions”](#reporting-handled-exceptions) To catch an exception and notify Honeybadger without re-throwing: ```php try { throw new Exception('Whoops!'); } catch (Exception $e) { $honeybadger->notify($e); } ``` You can call `$honeybadger->notify()` anywhere in your code where you have an `Exception` to report. ### Including request data [Section titled “Including request data”](#including-request-data) You can optionally include a `\Symfony\Component\HttpFoundation\Request::class` request as the second argument to `$honeybadger->notify()`: ```php $honeybadger->notify($e, $app->request()); ``` When the request is included, HTTP information such as params, headers, and session data will be sent to Honeybadger. ## Sending custom notifications [Section titled “Sending custom notifications”](#sending-custom-notifications) To notify Honeybadger of other types of errors: ```php $honeybadger->customNotification([ 'title' => 'Special Error', 'message' => 'Special Error: a special error has occurred', ]); ``` ### Options [Section titled “Options”](#options) | Option Name | Description | | ----------- | ------------------------------------------------- | | title | The title of the error (normally the class name). | | message | The error message. | # Tracking deploys > Learn how to use Honeybadger to track deployments in your PHP application. Honeybadger can keep track of application deployments, and link errors to the version which the error occurred in. Here’s a simple `curl` script to record a deployment: ```sh HONEYBADGER_ENV="production" \ HONEYBADGER_REVISION="$(git rev-parse HEAD)" \ HONEYBADGER_REPOSITORY="$(git config --get remote.origin.url)" \ HONEYBADGER_API_KEY="Your project API key" \ && curl -g "https://api.honeybadger.io/v1/deploys?deploy[environment]=$HONEYBADGER_ENV&deploy[local_username]=$USER&deploy[revision]=$HONEYBADGER_REVISION&deploy[repository]=$HONEYBADGER_REPOSITORY&api_key=$HONEYBADGER_API_KEY" ``` Be sure that the same revision is also configured in the honeybadger-js library. Read more about deploy tracking in the [API docs](/api/deployments/). If you are using our EU stack, you should use `eu-api.honeybadger.io` instead of `api.honeybadger.io` for the `curl` command. ### Tracking deploys from Laravel Forge [Section titled “Tracking deploys from Laravel Forge”](#tracking-deploys-from-laravel-forge) If you are deploying your site with [Laravel Forge](https://forge.laravel.com), you can notify Honeybadger of deployments via Deployment Notifications. Use this format for your webhook URL: `https://api.honeybadger.io/v1/deploys/forge?api_key=YOUR_HONEYBADGER_API_KEY_HERE&environment=production` If you are using our EU stack, you should use `eu-api.honeybadger.io` instead of `api.honeybadger.io` in the webhook URL. ### Deploying with GitHub Actions [Section titled “Deploying with GitHub Actions”](#deploying-with-github-actions) If your CI/CD pipeline is hosted with GitHub Actions, you can use the [Honeybadger Deploy Action](https://github.com/marketplace/actions/honeybadger-deploy-action) to notify our API about deployments. # Configuring check-ins > Configure Check-Ins for PHP and Laravel applications. Note For Laravel specific integration information, see the [Laravel](/lib/php/integration/laravel/#check-ins) page. For Lumen specific information, see the [Lumen](/lib/php/integration/lumen/) page. Honeybadger’s PHP and Laravel packages allow configuring [Check-Ins](https://www.honeybadger.io/check-ins) via the `checkins` configuration key. Create, update or even remove check-ins for your project(s) by defining them in your configuration file. If you are using Laravel or Lumen, this should be in your `config/honeybadger.php` file. ```php 'api_key' => env('HONEYBADGER_API_KEY'), 'personal_auth_token' => env('HONEYBADGER_PERSONAL_AUTH_TOKEN'), 'checkins' => [ [ 'schedule_type' => 'simple', 'name' => 'Hourly clean up', 'slug' => 'hourly-clean-up', 'grace_period' => '5 minutes', 'report_period' => '1 hour' ], [ 'schedule_type' => 'cron', 'name' => 'Hourly check', 'slug' => 'hourly-check', 'cron_schedule' => '30 * * * *', 'cron_timezone' => 'UTC' ] ] ``` ## Prerequisites [Section titled “Prerequisites”](#prerequisites) Note Check-ins are project specific, so you need to set the `api_key` of the project you want to create check-ins for. A `personal_auth_token` is required to create, update or remove check-ins. You can find this token under the [authentication tab in your User Settings page](https://app.honeybadger.io/users/edit#authentication). ## Check-in options [Section titled “Check-in options”](#check-in-options) | Field name | Required | | --------------- | ---------------------------------------------------------- | | `name` | No. | | `slug` | Yes. This is the identifier used to synchronize check-ins. | | `schedule_type` | Yes. | | `report_period` | Only when `'schedule_type' => 'simple'`. | | `cron_schedule` | Only when `'schedule_type' => 'cron'`. | | `cron_timezone` | Only when `'schedule_type' => 'cron'`. | | `grace_period` | No. | You can find more details in the [Checkins API](/api/check-ins/) page. ## Synchronization [Section titled “Synchronization”](#synchronization) Once you have configured your check-ins, they need to be synchronized with Honeybadger. Usually you would do this as part of your deployment pipeline. If you are on Laravel or Lumen, you can do this by adding the `honeybadger:checkins:sync` command as an additional step to your deployment. Otherwise, you can manually create a script and run it: ```php sync($config['checkins']); ``` The output of the command will print out created, updated or removed check-ins: ```shell $ php artisan honeybadger:checkins:sync Checkins were synchronized with Honeybadger. +--------+---------------------------------------+---------------+--------------+-----------------+ | Id | Name | Schedule Type | Grace Period | Status | +--------+---------------------------------------+---------------+--------------+-----------------+ | yaI6Pr | Weekly Exports | simple | 5 minutes | ✅ Synchronized | | b3Ip54 | Hourly Notifications | simple | 5 minutes | ✅ Synchronized | | l2Ie8Q | Hourly SMS Notifications (deprecated) | simple | 5 minutes | ❌ Removed | +--------+---------------------------------------+---------------+--------------+-----------------+ ``` ### Validation [Section titled “Validation”](#validation) The synchronization process will validate the check-ins before sending them to Honeybadger. If any of the check-ins are invalid, the synchronization will fail and most probably the deployment pipeline will fail. If you want to avoid this behavior, you can ignore the result of the artisan command: ```bash php artisan honeybadger:checkins:sync || true ``` ## Troubleshooting [Section titled “Troubleshooting”](#troubleshooting) If you are receiving invalid API key errors, make sure you have set both `api_key` and `personal_auth_token` in your configuration file. If you are still receiving invalid API key errors, it is possible that you have reached your check-in limit or you are trying to create a check-in that is not supported by your plan. # Insights overview > Query automatic Laravel instrumentation alongside custom application events from PHP in Honeybadger Insights. [Insights](/guides/insights/) lets you observe what your PHP application does in production. Honeybadger records common Laravel activity automatically, including incoming requests, database queries, queued jobs, mail, notifications, Redis commands, and view renders. From there, you can add context and custom events from your own code, then use [BadgerQL](/guides/insights/badgerql/) to ask questions across the whole event stream. Any field you send is queryable as soon as it arrives, with no schema to define ahead of time. ## Start with automatic instrumentation [Section titled “Start with automatic instrumentation”](#start-with-automatic-instrumentation) Enable events in `config/honeybadger.php` and the package starts recording as soon as your app boots. [Automatic instrumentation](/lib/php/insights/automatic-instrumentation/)Configure what the package captures. [Laravel event reference](/insights/event-types/laravel/)See every Laravel event type and field. ## Add a built-in dashboard [Section titled “Add a built-in dashboard”](#add-a-built-in-dashboard) Automatic events power built-in dashboards. [Laravel](/guides/dashboards/laravel/)Request and job durations, response distributions, slowest controllers and queries ## Add application context [Section titled “Add application context”](#add-application-context) Context adds fields to the current request. Once set, every event emitted during that request carries them. Say the app is A/B testing a new checkout flow against the control. Each checkout request sets context like this: Set the variant on context ```php $honeybadger->eventContext(['checkout_variant' => $checkoutVariant]); ``` The `checkout_variant` field is now on every database event for that request. You can group by it like any other field. Database work by checkout variant ```badgerql filter event_type::str == "db.executed" and isNotNull(checkout_variant::str) | stats count() as queries, avg(duration::float) as avg_us by checkout_variant::str | sort queries desc ``` | queries | avg\_us | checkout\_variant | | ------- | ------- | ----------------- | | 26815 | 412 | new | | 11873 | 387 | control | The new variant ran more than twice as many queries with similar per-query time. Keep in mind that adding another A/B variant will extend any of the examples here without the need to change anything on the Honeybadger side. Go deeper: check for possible N+1 queries The package attaches a `requestId` to every event from the same request. To turn total database work into queries per request, group events by `requestId` first to get a per-request count, then aggregate by variant. ```badgerql filter event_type::str == "db.executed" and isNotNull(checkout_variant::str) | stats count() as queries by requestId::str, checkout_variant::str | stats count() as request_count, avg(queries) as avg_q, percentile(95, queries) as p95_q by checkout_variant | sort p95_q desc | only toHumanString(request_count) as requests, toHumanString(avg_q) as avg_queries, toHumanString(p95_q) as p95_queries, checkout_variant ``` | requests | avg\_queries | p95\_queries | checkout\_variant | | -------- | ------------ | ------------ | ----------------- | | 631 | 42.18 | 97 | new | | 638 | 18.61 | 31 | control | The new variant runs more queries per request, and the p95 is much higher than control. That pattern often points at an N+1. ## Record application events [Section titled “Record application events”](#record-application-events) Custom events record activity the framework cannot see at all. Laravel knows a checkout request ran. Only your app knows whether the payment authorized: Send a custom payment event ```php $honeybadger->event('payment.authorized', [ 'payment_provider' => $payment->provider, 'amount' => $checkout->total, 'currency' => $checkout->currency, 'authorization_id' => $payment->authorization_id, ]); ``` This query breaks down the amounts collected by variant and provider: Payments by variant and provider ```badgerql filter event_type::str == "payment.authorized" | stats count() as authorizations, sum(amount::float) as authorized_amount by checkout_variant::str, payment_provider::str | sort authorized_amount desc ``` | authorizations | authorized\_amount | checkout\_variant | payment\_provider | | -------------- | ------------------ | ----------------- | ----------------- | | 413 | 34108.00 | new | stripe | | 218 | 18722.00 | new | paypal | | 418 | 32167.00 | control | stripe | | 220 | 13639.00 | control | paypal | Go deeper: more insights, same instrumentation Conversion rate by variant ```badgerql filter event_type::str == "payment.authorized" or controller::str == "App\\Http\\Controllers\\CheckoutsController" | stats count(event_type::str == "payment.authorized") as auth_events by requestId::str, checkout_variant::str | stats count() as auths, count(auth_events > 0) as checkouts, checkouts / auths as conv_rate by checkout_variant::str | only conv_rate, checkout_variant ``` | conv\_rate | checkout\_variant | | ---------- | ----------------- | | 0.92 | new | | 0.86 | control | Revenue per payment provider per variant ```badgerql filter event_type::str == "payment.authorized" | stats sum(amount::float) as total by payment_provider::str, checkout_variant::str | sort total desc | only toHumanString(total) as revenue, payment_provider, checkout_variant ``` | revenue | payment\_provider | checkout\_variant | | ------- | ----------------- | ----------------- | | 34,108 | stripe | new | | 32,167 | stripe | control | | 18,722 | paypal | new | | 13,639 | paypal | control | Average checkout response time by variant ```badgerql filter event_type::str == "request.handled" and controller::str == "App\\Http\\Controllers\\CheckoutsController" | stats avg(duration::float) as avg_us by checkout_variant::str | only toHumanString(avg_us, "microseconds") as avg, checkout_variant ``` | avg | checkout\_variant | | ----- | ----------------- | | 142ms | new | | 78ms | control | Conversion rate over time, by variant ```badgerql filter event_type::str == "payment.authorized" or controller::str == "App\\Http\\Controllers\\CheckoutsController" | stats count(event_type::str == "payment.authorized") as auth_events, min(@ts) as request_ts by requestId::str, checkout_variant::str | stats count(auth_events > 0) / count() as conv_rate by checkout_variant::str, bin(1h, request_ts) as hour | sort hour asc ``` | conv\_rate | checkout\_variant | hour | | ---------- | ----------------- | ------------------- | | 0.93 | new | 2026-06-26 14:00:00 | | 0.86 | control | 2026-06-26 14:00:00 | | 0.92 | new | 2026-06-26 15:00:00 | | 0.86 | control | 2026-06-26 15:00:00 | | 0.91 | new | 2026-06-26 16:00:00 | | 0.87 | control | 2026-06-26 16:00:00 | The new variant holds a consistent lead over control across the rollout window. [Sending custom events](/lib/php/insights/sending-events-to-insights/)The full event API. # Automatic instrumentation > Events the Honeybadger Laravel package captures automatically for Honeybadger Insights. If you’re using Laravel or Lumen, Honeybadger provides automatic instrumentation to capture events from your apps. By default, we’ll record: * [Log events](https://laravel.com/docs/logging) * [View renders](https://laravel.com/docs/views) * [Email dispatches](https://laravel.com/docs/mail) * [Job dispatches](https://laravel.com/docs/queues) * [Notification dispatches](https://laravel.com/docs/notifications) * [Database queries](https://laravel.com/docs/queries) * [Redis commands](https://laravel.com/docs/redis) * Incoming requests See the [Laravel event reference](/insights/event-types/laravel/) for every event the package emits, with field schemas and types. You can customise this with the `events` option in your `config/honeybadger.php`: ```php 'events' => [ 'enabled' => true, 'automatic' => [ Events\DatabaseQueryExecuted::class, Events\DatabaseTransactionStarted::class, Events\DatabaseTransactionCommitted::class, Events\DatabaseTransactionRolledBack::class, Events\CacheHit::class, Events\CacheMiss::class, Events\JobQueued::class, Events\MailSending::class, Events\MailSent::class, Events\MessageLogged::class, Events\NotificationSending::class, Events\NotificationSent::class, Events\NotificationFailed::class, Events\RedisCommandExecuted::class, Events\RouteMatched::class, Events\ViewRendered::class, ], ], ``` The `events.automatic` key contains the list of the events Honeybadger tracks by default. You can disable a specific event by removing or commenting out the appropriate line. ## Managing event volume [Section titled “Managing event volume”](#managing-event-volume) If some events are noisy or you’d like to reduce quota consumption: * [Filtering events](/lib/php/insights/filtering-events/) — inspect, modify, or drop events with a callback. * [Sampling events](/lib/php/insights/sampling-events/) — send only a percentage of events. ## Sending your own events [Section titled “Sending your own events”](#sending-your-own-events) Automatic instrumentation covers the framework events the package knows about. To send your own application events, see [Sending custom events](/lib/php/insights/sending-events-to-insights/). # Capturing logs > Send application logs from PHP and Laravel applications to Honeybadger Insights. You can send your application logs to Insights either by sending them to Honeybadger from your [infrastructure](/guides/insights/integrations/log-files/) **or** if you are using Monolog, you can register Honeybadger’s `LogEventHandler` class as a handler: ```php $logger = new Monolog\Logger('my-logger'); $honeybadger = Honeybadger\Honeybadger::new([ 'api_key' => 'my-api-key' ]); $logger->pushHandler(new Honeybadger\LogEventHandler($honeybadger)); $logger->info('An info message'); $logger->info('An info message with context data', ["some-key" => "some-value"]); $logger->error('An error message'); ``` You can send an optional second argument to the `LogEventHandler` constructor to specify the minimum log level to be sent to Honeybadger. The default is `Monolog\Logger::INFO`. ```php new Honeybadger\LogEventHandler($honeybadger, Monolog\Logger::DEBUG); ``` This will send all log messages to Insights, where they will be displayed in the [Insights](https://www.honeybadger.io/tour/logging-observability) section of your dashboard. ## Using Laravel or Lumen [Section titled “Using Laravel or Lumen”](#using-laravel-or-lumen) If you are using Laravel or Lumen, [register a custom channel](https://laravel.com/docs/11.x/logging#creating-custom-channels-via-factories) in your `config/logging.php`, making use of the `HoneybadgerLogEventDriver`: config/logging.php ```php 'channels' => [ // ... 'honeybadger' => [ 'driver' => 'custom', 'via' => Honeybadger\HoneybadgerLaravel\HoneybadgerLogEventDriver::class, 'name' => 'honeybadger', 'level' => 'info', ], ], ``` Now you can write log messages as normal with Laravel’s log facade, and they’ll show up in Honeybadger Insights: ```php Log::channel('honeybadger')->info('An info message'); Log::channel('honeybadger')->error('An error message with context', ["some-key" => "some-value"]); ``` Add this custom channel to your default stack and voilà, all your log messages will appear in Honeybadger Insights: config/logging.php ```php 'channels' => [ 'stack' => [ 'driver' => 'stack', 'channels' => ['single', 'honeybadger'], 'ignore_exceptions' => false, ], // ... ], ``` # Filtering events > Ignore or modify events before they're sent from your PHP application to Honeybadger Insights. You can ignore events programmatically using the `beforeEvent` callback. This callback is called before an event is sent to Honeybadger. If the callback returns `false`, the event will not be sent. For example, you can ignore events based on the event type: ```php $honeybadger->beforeEvent(function (&$event) { if ($event['event_type'] === 'user_activity' && $event['action'] === 'registration') { return false; } }); ``` Or, you may modify the event data before it is sent: ```php $honeybadger->beforeEvent(function (&$event) { $event['user_id'] = 456; }); ``` **Note**: You can register multiple `beforeEvent` callbacks. If any of them return `false`, the event will not be sent. ## Sampling events [Section titled “Sampling events”](#sampling-events) If you’d rather reduce event volume across the board instead of ignoring specific events, see [Sampling events](/lib/php/insights/sampling-events/). # Sampling events > Send a percentage of events from your PHP application to Honeybadger Insights to manage quota consumption. If you find that you’d like to report fewer events in order to minimize your quota consumption, you can update your configuration in `config/honeybadger.php` to conditionally send a certain percentage of events: ```php 'events' => [ 'enabled' => true, 'sample_rate' => 10 ] ``` This will send 10% of events not associated with a request, and all events for 10% of requests. To ignore specific events instead of sampling across the board, see [Filtering events](/lib/php/insights/filtering-events/). # Sending custom events > Send custom events from PHP applications to Honeybadger Insights for monitoring and analysis. You can send your own application events to [Honeybadger Insights](/guides/insights/) with Honeybadger’s PHP (v2.19+) and Laravel (v4.1+) packages. (For the events the Laravel package captures on its own, see [Automatic instrumentation](/lib/php/insights/automatic-instrumentation/); to forward application logs, see [Capturing logs](/lib/php/insights/capturing-logs/).) Start by configuring Honeybadger and enabling events: ```php $honeybadger = Honeybadger\Honeybadger::new([ 'api_key' => 'my-api-key', 'events' => [ 'enabled' => true ] ]); ``` Then you can send events using the `$honeybadger->event` method: ```php $honeybadger->event('user_activity', [ 'action' => 'registration', 'user_id' => 123 ]) ``` The first argument is the type of the event (`event_type`) and the second argument is an object containing any additional data you want to include. `$honeybadger->event` can also be called with a single argument as an object containing the data for the event: ```php $honeybadger->event([ 'event_type' => 'user_activity', 'action' => 'registration', 'user_id' => 123 ]) ``` A timestamp field (`ts`) will be automatically added to the event data if it is not provided, regardless of the method used to send the event. These events may be found using the following BadgerQL query: ```badgerql fields @ts, @preview | filter event_type::str == "user_activity" | filter action::str == "registration" | sort @ts ``` ## Managing event volume [Section titled “Managing event volume”](#managing-event-volume) If some events are noisy or you’d like to reduce quota consumption: * [Filtering events](/lib/php/insights/filtering-events/) — inspect, modify, or drop events with a callback. * [Sampling events](/lib/php/insights/sampling-events/) — send only a percentage of events. # Laravel integration guide > Honeybadger monitors your Laravel applications for errors and exceptions so that you can fix them wicked fast. **Typical installation time:** 5 minutes Hi there! You’ve found Honeybadger’s guide to **Laravel error and exception tracking**. Once installed, Honeybadger will automatically report errors wherever they may happen: * During a web request * In a scheduled command * In a background task * When a process crashes ## Installation [Section titled “Installation”](#installation) First, install the [honeybadger-laravel](https://github.com/honeybadger-io/honeybadger-laravel) package via composer: ```bash composer require honeybadger-io/honeybadger-laravel ``` ### Laravel version support [Section titled “Laravel version support”](#laravel-version-support) Install the version of our package based on the version of Laravel and PHP you are using. | Laravel | PHP version | Honeybadger Laravel version | | ------- | ----------- | ----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | | 12.x | 8.2+ | [5.x (current)](https://github.com/honeybadger-io/honeybadger-laravel/releases) | | 11.x | 8.2+ | [5.x (current)](https://github.com/honeybadger-io/honeybadger-laravel/releases) | | 10.x | 8.1+ | [5.x (current)](https://github.com/honeybadger-io/honeybadger-laravel/releases); [4.7.1](https://github.com/honeybadger-io/honeybadger-laravel/releases?q=v4.\&expanded=true) if PHP ≤8.1 | | 9.x | 8.0 – 8.2 | [3.13.x](https://github.com/honeybadger-io/honeybadger-laravel/releases/tag/v3.18.2) | | 8.x | 7.3 – 8.1 | [3.2.x](https://github.com/honeybadger-io/honeybadger-laravel/releases/tag/v3.18.2) | | 7.x | 7.2.5 – 8.0 | [3.x](https://github.com/honeybadger-io/honeybadger-laravel/releases/tag/v3.18.2) | | 6.x | 7.2.5 – 8.0 | [2.1](https://github.com/honeybadger-io/honeybadger-laravel/releases/tag/v2.1.0) | | 5.x | 7.0 – 7.3 | [1.x](https://github.com/honeybadger-io/honeybadger-laravel/releases/tag/v1.7.3) | *** Note This package uses Laravel’s [package discovery](https://laravel.com/docs/12.x/packages#package-discovery) to register the service provider and facade to the framework. If you are using an older version of Laravel or do not use package discovery, you may need to [manually register those components](/lib/php/integration/laravel-advanced/). *** Next, add Honeybadger reporting to Laravel 11 and later by adding the following to `bootstrap/app.php` (): bootstrap/app.php ```php ->withExceptions(function (Exceptions $exceptions) { $exceptions->report(static function (Throwable $e) { if (app()->bound('honeybadger')) { app('honeybadger')->notify($e, app('request')); } }); }) ``` In Laravel 8.5 to 10, the default handler comes with a [`register()` method](https://laravel.com/docs/10.x/errors#reporting-exceptions); you should add the Honeybadger client within the `reportable()` callback. app/Exceptions/Handler.php ```php public function register() { $this->reportable(function (Throwable $e) { if (app()->bound('honeybadger')) { app('honeybadger')->notify($e, app('request')); } }); } ``` On earlier versions of Laravel, add the client within the `report($exception)` method: ```php public function report(Throwable $exception) { if (app()->bound('honeybadger') && $this->shouldReport($exception)) { app('honeybadger')->notify($exception, app('request')); } parent::report($exception); } ``` Finally, run the `honeybadger:install` artisan command. ```bash php artisan honeybadger:install [Your project API key] ``` If you are using our EU stack, add the `--endpoint` and the `--appEndpoint` flags to the `honeybadger:install` command: ```bash php artisan honeybadger:install [Your project API key] --endpoint=https://eu-api.honeybadger.io --appEndpoint=https://eu-app.honeybadger.io ``` The `honeybadger:install` command does three things: 1. Adds `HONEYBADGER_API_KEY` to `.env` and `.env.example` 2. If you added the `--endpoint` and `--appEndpoint` flags, it also adds `HONEBADGER_ENDPONT` and `HONEYBADGER_APP_ENDPOINT` to `.env` and `.env.example`. 3. Creates Honeybadger’s `config/honeybadger.php` configuration file 4. Sends a test notification to your Honeybadger project If everything is set up correctly, you should now have an error report in Honeybadger! Note The default config for Laravel won’t report errors to Honeybadger on `local` and `testing` environments. You can change that with the [`report_data` option](/lib/php/errors/reducing-noise/#disabling-error-reporting). ## Identifying users and controller/action [Section titled “Identifying users and controller/action”](#identifying-users-and-controlleraction) Honeybadger automatically captures details about the current logged-in user, as well as the controller and method name. No extra configuration needed. We only capture the user ID, so no sensitive information is transmitted. When an error occurs, you’ll see an **Affected Users** section on your dashboard, where we’ll list the user IDs and how many times they encountered the error. ## Adding context [Section titled “Adding context”](#adding-context) [Context](/lib/php/errors/customizing-error-reports/) can be added by either the provided Facade or by resolving from the service container. ### Facade [Section titled “Facade”](#facade) ```php Honeybadger::context('key', $value); ``` ### DI resolution [Section titled “DI resolution”](#di-resolution) ```php use Honeybadger\Honeybadger; public function __construct(Honeybadger $honeybadger) { $honeybadger->context('key', $value); } ``` ### Helper resolution [Section titled “Helper resolution”](#helper-resolution) ```php use Honeybadger\Honeybadger; public function __construct() { app('honeybadger')->context('key', $value); app(Honeybadger::class)->context('key', $value) } ``` ## Check-Ins [Section titled “Check-Ins”](#check-ins) `honeybadger-laravel` integrates with [Honeybadger’s Check-In feature](https://www.honeybadger.io/check-ins) to help you know when your scheduled tasks and background jobs go missing or silently fail. To get started, create a new check-in in the Check-Ins tab of your project dashboard. You’ll be given a check-in URL that looks like this: . Take note of the check-in ID; it’s the last part of the check-in URL. In this example, it’s **Jiy63Xw**. Alternatively, you can setup your [check-ins entirely within your configuration file](/lib/php/guides/configuring-checkins/). If you follow this method, you don’t need the check-in ID anymore and instead you can use the check-in slug. #### Run a one-off check-in [Section titled “Run a one-off check-in”](#run-a-one-off-check-in) To run a one-off check-in, use the `honeybadger:checkin` command with your check-in ID. This will let Honeybadger know that your app is alive. ```bash php artisan honeybadger:checkin Jiy63Xw ``` Or if you have configured your check-ins in your configuration file: ```bash php artisan honeybadger:checkin "my-checkin" ``` #### Scheduled command [Section titled “Scheduled command”](#scheduled-command) You can schedule the check-in command to run at an interval. This method is great for ensuring your application is up and running. app/Console/Kernel.php ```php protected function schedule(Schedule $schedule) { $schedule->command('honeybadger:checkin Jiy63Xw')->everyFiveMinutes(); // or using the check-in slug $schedule->command('honeybadger:checkin "my-checkin"')->everyFiveMinutes(); } ``` #### After a scheduled command [Section titled “After a scheduled command”](#after-a-scheduled-command) You can use the `thenPingHoneybadger($checkInId)` macro to check-in after certain scheduled commands are run. This method is great for making sure specific scheduled commands are running on time. app/Console/Kernel.php ```php protected function schedule(Schedule $schedule) { $schedule->command(SendEmails::class)->daily() ->thenPingHoneybadger('Jiy63Xw'); // or using the check-in slug ->thenPingHoneybadger('my-checkin'); } ``` In this example, if `SendEmails` fails to run for some reason, Honeybadger will notify you. You can also specify the environments where the check-in is allowed to run: app/Console/Kernel.php ```php protected function schedule(Schedule $schedule) { $schedule->command(SendEmails::class)->daily() ->thenPingHoneybadger('Jiy63Xw', 'production'); // or using the check-in slug ->thenPingHoneybadger('my-checkin', 'production'); $schedule->command(CheckStatus::class)->daily() ->thenPingHoneybadger('Jiy63Xw', ['production', 'staging']); // or using the check-in slug ->thenPingHoneybadger('my-checkin', ['production', 'staging']); } ``` #### After a successful scheduled command [Section titled “After a successful scheduled command”](#after-a-successful-scheduled-command) You can use the `pingHoneybadgerOnSuccess($checkInId)` macro to ensure that a certain command was run and completed successfully. This method is great for making sure specific scheduled commands are running on time **only if it was successful**. Like the `thenPingHoneybadger` method, you can also restrict it to specific environments. app/Console/Kernel.php ```php protected function schedule(Schedule $schedule) { $schedule->command(SendEmails::class)->daily() ->pingHoneybadgerOnSuccess('Jiy63Xw', 'production'); // or using the check-in slug ->pingHoneybadgerOnSuccess('my-checkin', 'production'); } ``` ## Using Honeybadger as a logger [Section titled “Using Honeybadger as a logger”](#using-honeybadger-as-a-logger) Note If you want to send your logs to Honeybadger, consider sending them to Insights instead. You can [learn more here](/guides/insights/) and enable the integration by following the instructions [here](/lib/php/insights/capturing-logs/). If you prefer, you can also use Honeybadger as a log channel in your Laravel app. To do this, you’ll need to [register a custom channel](https://laravel.com/docs/11.x/logging#creating-custom-channels-via-factories) in your `config/logging.php`, making use of the `HoneybadgerLogDriver`: config/logging.php ```php 'channels' => [ // ... 'honeybadger' => [ 'driver' => 'custom', 'via' => Honeybadger\HoneybadgerLaravel\HoneybadgerLogDriver::class, 'name' => 'honeybadger', 'level' => 'error', ], ], ``` Now you can write log messages as normal with Laravel’s log facade, and they’ll show up on your Honeybadger dashboard. ```php Log::channel('honeybadger')->error('An error message'); Log::channel('honeybadger')->error('An error message with context', ["some-key" => "some-value"]); Log::channel('honeybadger')->error($exception); ``` If you include an `exception` context item in your error messages, we’ll automatically format them for easy viewing: ```php $e = new \Exception('Something happened'); Log::channel('honeybadger')->error('An error message', ['exception' => $e]); ``` You can also add the custom channel to your default stack so you can automatically have exceptions logged to Honeybadger as well: config/logging.php ```php 'channels' => [ 'stack' => [ 'driver' => 'stack', 'channels' => ['single', 'honeybadger'], 'ignore_exceptions' => false, ], // ... ], ``` # Manual Laravel integration > Learn how to manually integrate Honeybadger with older Laravel versions or when package discovery is disabled. The [`honeybadger-laravel` package](https://github.com/honeybadger-io/honeybadger-laravel) uses Laravel’s [package discovery](https://laravel.com/docs/5.6/packages#package-discovery) to register the service provider and facade to the framework. If you are using an older version of Laravel or do not use package discovery see below. ### Step 1: Register the provider with the framework [Section titled “Step 1: Register the provider with the framework”](#step-1-register-the-provider-with-the-framework) config/app.php ```php 'providers' => [ /* * Package Service Providers... */ \Honeybadger\HoneybadgerLaravel\HoneybadgerServiceProvider::class, ] ``` ### Step 2: Register the facade with the framework [Section titled “Step 2: Register the facade with the framework”](#step-2-register-the-facade-with-the-framework) config/app.php ```php 'aliases' => [ 'Honeybadger' => \Honeybadger\HoneybadgerLaravel\Facades\Honeybadger::class, ] ``` # Lumen integration guide > Honeybadger monitors your Lumen applications for errors and exceptions so that you can fix them wicked fast. **Typical installation time:** 5 minutes Hi there! You’ve found Honeybadger’s guide to **Lumen error and exception tracking**. Once installed, Honeybadger will automatically report errors wherever they may happen: * During a web request * In a scheduled command * In a background task * When a process crashes ## Installation [Section titled “Installation”](#installation) First, install the [honeybadger-laravel](https://github.com/honeybadger-io/honeybadger-laravel) package via composer: ```bash composer require honeybadger-io/honeybadger-laravel ``` …and add the following line to `bootstrap/app.php` under the “Register Service Providers” section: ```php $app->register(\Honeybadger\HoneybadgerLaravel\HoneybadgerServiceProvider::class); ``` Next, add Honeybadger reporting to `app/Exceptions/Handler.php`: ```php public function report(Exception $exception) { if (app()->bound('honeybadger') && $this->shouldReport($exception)) { app('honeybadger')->notify($exception, app('request')); } parent::report($exception); } ``` Finally, run the `honeybadger:install` artisan command: ```bash php artisan honeybadger:install [Your project API key] ``` The `honeybadger:install` command does three things: 1. Adds `HONEYBADGER_API_KEY` to `.env` and `.env.example` 2. Creates Honeybadger’s `config/honeybadger.php` configuration file 3. Sends a test notification to your Honeybadger project If everything is set up correctly, you should now have an error report in Honeybadger! Note The default config for Lumen won’t report errors to Honeybadger on `local` and `testing` environments. You can change that with the [`report_data` option](/lib/php/errors/reducing-noise/). ## Identifying users [Section titled “Identifying users”](#identifying-users) Honeybadger automatically captures details about the current logged-in user, as well as the controller and method name. No extra configuration needed. We only capture the user ID, so no sensitive information is transmitted. When an error occurs, you’ll see an **Affected Users** section on your dashboard, where we’ll list the user IDs and how many times they encountered the error. ## Adding context [Section titled “Adding context”](#adding-context) [Context](/lib/php/errors/customizing-error-reports/) can be added by either the provided Facade or by resolving from the service container. ### Facade [Section titled “Facade”](#facade) ```php Honeybadger::context('key', $value); ``` ### DI resolution [Section titled “DI resolution”](#di-resolution) ```php use Honeybadger\Honeybadger; public function __construct(Honeybadger $honeybadger) { $honeybadger->context('key', $value); } ``` ### Helper resolution [Section titled “Helper resolution”](#helper-resolution) ```php use Honeybadger\Honeybadger; public function __construct() { app('honeybadger')->context('key', $value); app(Honeybadger::class)->context('key', $value) } ``` ## Using Honeybadger as a logger [Section titled “Using Honeybadger as a logger”](#using-honeybadger-as-a-logger) Note If you want to send your logs to Honeybadger, consider sending them to Insights instead. You can [learn more here](/guides/insights/) and enable the integration by following the instructions [here](/lib/php/insights/capturing-logs/). If you prefer, you can also use Honeybadger as a log channel in your Lumen app. To do this, you’ll need to [register a custom channel](https://laravel.com/docs/logging#creating-custom-channels-via-factories) in your `config/logging.php`, making use of the `HoneybadgerLogDriver`. If you don’t have a `config/logging.php` file, you can create one by copying the contents of the one [embedded in Lumen](https://github.com/laravel/lumen-framework/blob/8.x/config/logging.php). Once you’ve done that, you can add a custom channel called “honeybadger”: config/logging.php ```php 'channels' => [ // ... 'honeybadger' => [ 'driver' => 'custom', 'via' => Honeybadger\HoneybadgerLaravel\HoneybadgerLogDriver::class, 'name' => 'honeybadger' ], ], ``` Now you can write log messages as normal with Lumen’s log facade, and they’ll show up on your Honeybadger dashboard. ```php Log::channel('honeybadger')->info('An info message'); Log::channel('honeybadger')->('An info message with context data', ["some-key" => "some-value"]); Log::channel('honeybadger')->error('An error message'); ``` If you include an `exception` context item in your error messages, we’ll automatically format them for easy viewing: ```php $e = new \Exception('Something happened'); Log::channel('honeybadger')->error('An error message', ['exception' => $e]); ``` You can also add the custom channel to your default stack so you can automatically have exceptions logged to Honeybadger as well: config/logging.php ```php 'channels' => [ 'stack' => [ 'driver' => 'stack', 'channels' => ['single', 'honeybadger'], 'ignore_exceptions' => false, ], // ... ], ``` # PHP integration guide > Honeybadger monitors your PHP applications for errors and exceptions so that you can fix them wicked fast. **Typical installation time:** 3 minutes Hi there! You’ve found Honeybadger’s guide to **PHP exception and error tracking**. Note: if you use **Laravel**, go check out the **[Laravel Integration Guide](/lib/php/integration/laravel/)**. If not, then read on! This guide will teach you how to install and configure the default **Honeybadger for PHP** client and use it to manually [report errors to Honeybadger](/lib/php/errors/reporting-errors/). ## Installation [Section titled “Installation”](#installation) First, install the [honeybadger-php](https://github.com/honeybadger-io/honeybadger-php) package via composer: ```bash composer require honeybadger-io/honeybadger-php ``` Then, configure the Honeybadger client in your application: ```php $honeybadger = Honeybadger\Honeybadger::new([ 'api_key' => 'PROJECT_API_KEY' ]); ``` Honeybadger can report exceptions in several ways. To test that the Honeybadger client is working, try sending a custom notification: ```php $honeybadger->customNotification([ 'title' => 'Special Error', 'message' => 'Special Error: a special error has occurred', ]); ``` To catch exceptions in your code and report them to Honeybadger: ```php try { throw new Exception('Whoops!'); } catch (Exception $e) { // You can optionally include your own // \Symfony\Component\HttpFoundation\Request::class request. $honeybadger->notify($e, $app->request()); } ``` ## Adding context [Section titled “Adding context”](#adding-context) In Honeybadger, **context** is a custom array of data that’s displayed with your error reports. You can add context from anywhere in your app, and it will be included automatically when reporting errors. For example, you could include the ID of the currently logged-in user: ```php $honeybadger->context('user_id', $this->Auth->user('id')); ``` See [Customizing Error Reports](/lib/php/errors/customizing-error-reports/) for more info. ## Handling service exceptions [Section titled “Handling service exceptions”](#handling-service-exceptions) When the client is unable to send a report to Honeybadger’s service, it will throw an instance of `\Honeybadger\Exceptions\ServiceException`. To prevent this from crashing your app and hiding the original error, you can set the `service_exception_handler` option to a closure where you can handle the exception yourself: ```php $honeybadger = Honeybadger\Honeybadger::new([ 'api_key' => 'PROJECT_API_KEY', 'service_exception_handler' => function (ServiceException $e) { $logger->error($e); }, ]); ``` ## Using Honeybadger as a logger [Section titled “Using Honeybadger as a logger”](#using-honeybadger-as-a-logger) Note If you want to send your logs to Honeybadger, consider sending them to Insights instead. You can [learn more here](/guides/insights/) and enable the integration by following the instructions [here](/lib/php/insights/capturing-logs/). If you’re using the PHP logging library [Monolog](https://github.com/Seldaek/monolog) in your app, you can also choose to use Honeybadger as a log handler, by using the `LogHandler` class. Then write log messages as normal with Monolog, and they’ll show up on your Honeybadger dashboard. ```php $logger = new Monolog\Logger('my-logger'); $honeybadger = Honeybadger\Honeybadger::new([ 'api_key' => 'my-api-key' ]); $logger->pushHandler(new Honeybadger\LogHandler($honeybadger)); $logger->info('An info message'); $logger->info('An info message with context data', ["some-key" => "some-value"]); $logger->error('An error message'); ``` If you include an `exception` context item in your error messages, we’ll automatically format them for easy viewing: ```php $e = new \Exception('Something happened'); $logger->error('An error message', ['exception' => $e]); ``` # WordPress integration guide > Honeybadger monitors your WordPress sites for errors and exceptions so that you can fix them quickly. **Typical installation time:** 5 minutes Hi there! You’ve found Honeybadger’s guide to **WordPress error and exception tracking**. Once installed, Honeybadger will automatically report errors wherever they may happen, both in the front-end (JavaScript) and back-end (PHP) of your WordPress site. ## Installation [Section titled “Installation”](#installation) First, install the [Honeybadger Application Monitoring](https://wordpress.org/plugins/honeybadger-application-monitoring) plugin via the WordPress plugin repository: 1. In your WordPress admin panel, go to **Plugins** > **Add New**. 2. Search for “Honeybadger Application Monitoring”. 3. Click **Install Now** next to the Honeybadger plugin. 4. After installation, click **Activate**. Alternatively, you can install the plugin manually: 1. Download the plugin from the [WordPress plugin repository](https://wordpress.org/plugins/honeybadger-application-monitoring). 2. Upload the plugin files to the `/wp-content/plugins/honeybadger-application-monitoring` directory. 3. Activate the plugin through the **Plugins** page in WordPress. ## Configuration [Section titled “Configuration”](#configuration) After activating the plugin, you need to configure it with your Honeybadger API key(s): 1. In your WordPress admin panel, go to **Settings** > **Honeybadger**. 2. Grab your API key(s) from your Honeybadger project settings. It is recommended that you have two separate projects, one for PHP and another for JavaScript error tracking. 3. Enter your Honeybadger API key(s) in the **PHP API Key** and **JS API Key** fields. 4. Ensure that **PHP error reporting enabled** is checked if you want to track PHP errors, as well as **JS error reporting enabled** if you want to track JavaScript errors. 5. (Optional) You can also configure the **Environment** and **Version** settings to better track your errors. 6. Click **Save Changes**. ## Testing the integration [Section titled “Testing the integration”](#testing-the-integration) To ensure everything is set up correctly, you can trigger a test error: 1. In your WordPress admin panel, go to **Settings** > **Honeybadger**. 2. Check the **Send test notification from PHP** or **Send test notification from JS** checkboxes. 3. Click **Save Changes**. If everything is set up correctly, you should now have an error (or two if you checked both checkboxes) reported in Honeybadger! Note Make sure to uncheck the test notification checkboxes after testing to avoid unnecessary test errors in your Honeybadger dashboard. # Configuration > Configuration options for Honeybadger PHP and Laravel packages. There are several ways to configure Honeybadger. See [Default Configuration](#default-configuration) for all the options that are available. ## Creating a new client [Section titled “Creating a new client”](#creating-a-new-client) In any PHP app, you can configure a new Honeybadger client directly via its constructor function: ```php $honeybadger = Honeybadger\Honeybadger::new([ 'api_key' => 'PROJECT_API_KEY' ]); ``` Using Honeybadger this way is good for creating custom integrations or adding Honeybadger to frameworks which don’t have an official integration yet. ## Laravel/Lumen [Section titled “Laravel/Lumen”](#laravellumen) In [Laravel](/lib/php/integration/laravel/) and [Lumen](/lib/php/integration/lumen/) apps, you should add your configuration to `config/honeybadger.php` instead. In addition to the [default configuration](#default-configuration) below, you can also define the [`middleware`](https://github.com/honeybadger-io/honeybadger-laravel/blob/master/config/honeybadger.php) option to enable or disable middleware that are automatically registered by the package. For example, the [`AssignRequestId`](https://github.com/honeybadger-io/honeybadger-laravel/blob/master/src/Middleware/AssignRequestId.php) middleware is registered by default, which assigns a unique request ID to each request. If you already have a way to assign request IDs in your app, you can disable this middleware. ## Default configuration [Section titled “Default configuration”](#default-configuration) The default configuration options are shown below: ```php [ // Honeybadger API Key 'api_key' => null, // Personal authentication token (needed to synchronize checkins from this configuration file) 'personal_auth_token' => null, // The application environment 'environment_name' => 'production', // To disable exception reporting, set this to false (or an expression that returns false). 'report_data' => ! in_array(env('APP_ENV'), ['local', 'testing']), 'environment' => [ // Environment keys to filter before the payload sent to Honeybadger (see Environment Whitelist) 'filter' => [], // Additional environment keys to include (see Environment Whitelist) 'include' => [], ], 'request' => [ // Request keys to filter before the payload sent to Honeybadger 'filter' => [ 'password', 'password_confirmation' ], ], // Application version 'version' => '', // System hostname 'hostname' => gethostname(), // Project root (/var/www) 'project_root' => '', 'handlers' => [ // Enable global exception handler 'exception' => true, // Enable global error handler 'error' => true, // Enable global shutdown handler 'shutdown' => true, ], // Configure the underlying Guzzle client used 'client' => [ // Request timeout in seconds (default: 15s) 'timeout' => 15, // Request proxy settings 'proxy' => [ // Use this proxy with 'http' (tcp://username:password@localhost:8125) 'http' => '', // Use this proxy with 'https' (tcp://username:password@localhost:8125) 'https' => '', ], ], // Specify a custom endpoint 'endpoint' => 'https://api.honeybadger.io', // Exclude exceptions from being reported 'excluded_exceptions' => [], // Enable reporting deprecation warnings. 'capture_deprecations' => false, // Specify how failures to reach Honeybadger should be handled 'service_exception_handler' => function (\Honeybadger\Exceptions\ServiceException $e) { throw $e; }, // Enable breadcrumbs 'breadcrumbs' => [ 'enabled' => true, ], // Define your checkins here and synchronize them to Honeybadger 'checkins' => [], // Configure Insights events reporting 'events' => [ 'enabled' => false, 'bulk_threshold' => BulkEventDispatcher::BULK_THRESHOLD, 'dispatch_interval_seconds' => BulkEventDispatcher::DISPATCH_INTERVAL_SECONDS, 'sample_rate' => 100 // Percentage of events to send ], ] ``` ## Environment whitelist [Section titled “Environment whitelist”](#environment-whitelist) All keys beginning with `HTTP_` are reported by default, as well as the following whitelisted keys: ```plaintext 'PHP_SELF' 'argv' 'argc' 'GATEWAY_INTERFACE' 'SERVER_ADDR' 'SERVER_NAME' 'SERVER_SOFTWARE' 'SERVER_PROTOCOL' 'REQUEST_METHOD' 'REQUEST_TIME' 'REQUEST_TIME_FLOAT' 'QUERY_STRING' 'DOCUMENT_ROOT' 'HTTPS' 'REMOTE_ADDR' 'REMOTE_HOST' 'REMOTE_PORT' 'REMOTE_USER' 'REDIRECT_REMOTE_USER' 'SCRIPT_FILENAME' 'SERVER_ADMIN' 'SERVER_PORT' 'SERVER_SIGNATURE' 'PATH_TRANSLATED' 'SCRIPT_NAME' 'REQUEST_URI' 'PHP_AUTH_DIGEST' 'PHP_AUTH_USER' 'PHP_AUTH_PW' 'AUTH_TYPE' 'PATH_INFO' 'ORIG_PATH_INFO' 'APP_ENV' ``` ## Exceptions [Section titled “Exceptions”](#exceptions) If there is an error contacting Honeybadger a `\Honeybadger\Exceptions\ServiceException::class` will be thrown with a relevant exception message. # Supported versions > Supported PHP versions for Honeybadger packages. ## honeybadger-php [Section titled “honeybadger-php”](#honeybadger-php) The [honeybadger-php](https://github.com/honeybadger-io/honeybadger-php) package supports **PHP 7.3+**. Use the [latest release](https://github.com/honeybadger-io/honeybadger-php/releases?q=\&expanded=true) for current support. ## honeybadger-laravel [Section titled “honeybadger-laravel”](#honeybadger-laravel) For supported Laravel and PHP version combinations and which Honeybadger Laravel package version to install, see the [Laravel version support](/lib/php/integration/laravel/#laravel-version-support) table in the [Laravel integration guide](/lib/php/integration/laravel/). # Frequently asked questions > Common questions about Honeybadger for PHP. Don’t see your question here? See [Getting Support](/lib/php/#getting-support) for next steps. ### How do I ignore certain errors? [Section titled “How do I ignore certain errors?”](#how-do-i-ignore-certain-errors) See [Reducing Noise](/lib/php/errors/reducing-noise/). ### How do I remove sensitive params or other data from error reports? [Section titled “How do I remove sensitive params or other data from error reports?”](#how-do-i-remove-sensitive-params-or-other-data-from-error-reports) See [Filtering Sensitive Data](/lib/php/errors/filtering-sensitive-data/). # Troubleshooting > Common issues and workarounds for Honeybadger PHP packages. Common issues/workarounds for [`honeybadger-php`](https://github.com/honeybadger-io/honeybadger-php) and [`honeybadger-laravel`](https://github.com/honeybadger-io/honeybadger-laravel) are documented here. If you don’t find a solution to your problem here or in our [support documentation](/lib/php/#getting-support), email and we’ll assist you! ## Before you start troubleshooting [Section titled “Before you start troubleshooting”](#before-you-start-troubleshooting) 1. Make sure you are on the latest version of [honeybadger-php](https://packagist.org/packages/honeybadger-io/honeybadger-php) and/or [honeybadger-laravel](https://packagist.org/packages/honeybadger-io/honeybadger-laravel). ### All errors are not reported [Section titled “All errors are not reported”](#all-errors-are-not-reported) If *no* errors are reported (even [manually via `$honeybadger->notify()`](/lib/php/errors/reporting-errors/)): 1. [Is the `api_key` config option configured?](/lib/php/reference/configuration/) 2. [Is `report_data` set to `false`?](/lib/php/errors/reducing-noise/) ### Some errors are not reported [Section titled “Some errors are not reported”](#some-errors-are-not-reported) 1. [Is the error ignored via config?](/lib/php/errors/reducing-noise/) ### Function call arguments aren’t shown in the backtrace [Section titled “Function call arguments aren’t shown in the backtrace”](#function-call-arguments-arent-shown-in-the-backtrace) 1. [Is `zend.exception_ignore_args` set to “Off”?](/lib/php/errors/capturing-function-call-arguments/) # Honeybadger for Python > Honeybadger monitors your Python applications for errors and performance bottlenecks so that you can fix them wicked fast. Hi there! You’ve found Honeybadger’s guide to Python error tracking, performance monitoring, and observability. Once installed, Honeybadger will automatically report errors and telemetry in your Python application. ## How you should read the docs [Section titled “How you should read the docs”](#how-you-should-read-the-docs) * If you’re installing Honeybadger in your application for the first time, start with our **Integrations Guides** for **[Django](/lib/python/integrations/django/)**, **[Flask](/lib/python/integrations/flask/)**, and **[other frameworks](/lib/python/integrations/other/)**. * The **How-To Guides** (in the left-hand navigation menu) are general guides on how to do things with the library, and should apply to all types of applications. * There is a wealth of additional knowledge about Honeybadger in the **Package Reference** and **Support** sections. ## Getting support [Section titled “Getting support”](#getting-support) If you’re having trouble working with the package (such as you aren’t receiving error reports when you should be): 1. Read [Frequently asked questions](/lib/python/support/faq/) 2. Upgrade to the latest package version if possible (you can find a list of bugfixes and other changes in the [CHANGELOG](https://github.com/honeybadger-io/honeybadger-python/blob/master/CHANGELOG.md)) 3. Run through our [Troubleshooting guide](/lib/python/support/troubleshooting/) 4. If you believe you’ve found a bug, [submit an issue on GitHub](https://github.com/honeybadger-io/honeybadger-python/issues/) For all other problems, contact support for help: # Adding context to errors > Learn how to add custom metadata to your Honeybadger error reports in Python. Honeybadger can display additional custom key/value metadata — or “context” — with each error report. Context is what you’re looking for if: * You want to record the current user’s id or email address at the time of an exception * You need to send raw POST data for use in debugging * You have any other metadata you’d like to send with an exception There are two ways to add context to errors in your code: [global](#global-context) and [local](#local-context). While you can add any key/value data to context, a few keys [have a special meaning in Honeybadger](#special-context-keys). ## Global context [Section titled “Global context”](#global-context) `honeybadger.set_context` allows you to send additional information to the Honeybadger API to assist in debugging. This method sets global context data and is additive - every time you call it, it adds to the existing set unless you call `reset_context`, documented below. ```python from honeybadger import honeybadger honeybadger.set_context(my_data='my_value') ``` Context data is thread-local, meaning each thread maintains its own separate context. `honeybadger.reset_context` clears the global context dictionary. ```python from honeybadger import honeybadger honeybadger.reset_context() ``` ## Local context [Section titled “Local context”](#local-context) What if you don’t want to set global context data? You can use Python context managers to set case-specific contextual information. ```python # from a Django view from honeybadger import honeybadger def my_view(request): with honeybadger.context(user_email=request.POST.get('user_email', None)): form = UserForm(request.POST) # ... ``` ## Special context keys [Section titled “Special context keys”](#special-context-keys) While you can add any key/value data to context, a few keys have special meaning in Honeybadger: | Option | Description | | ------------ | -------------------------------------------------------------------------------------------- | | `_tags` | Any value passed in the `_tags` key will be processed as tags for the error. | | `user_id` | The user ID used by Honeybadger to aggregate user data across occurrences on the error page. | | `user_email` | Same as `user_id`, but for email addresses. | ## Automatic context [Section titled “Automatic context”](#automatic-context) When using Django, the middleware automatically adds user information to error context: * `user_id` - from `request.user.id` * `username` - from `request.user.get_username()` This happens automatically for authenticated users when an error occurs. ## Limits [Section titled “Limits”](#limits) Honeybadger’s servers enforce the following limits to ensure the service operates smoothly for everyone: * Nested objects have a max depth of 20 * Context values have a max size of 64Kb When an error notification includes context data that exceed these limits, the context data will be truncated on the server, and the notification will still be processed. # Customizing error grouping > Learn how to customize how Honeybadger groups similar errors together. Honeybadger groups similar exceptions together using rules which we’ve found to work the best in most cases. The default information we use to group errors is: 1. The file name, method name, and line number of the error’s location 2. The class name of the error 3. The component/controller name We use this information to construct a “fingerprint” of the exception. Exceptions with the same fingerprint are treated as the same error in Honeybadger. You can customize the grouping for each exception by changing the error class name, component, or stack trace—or by sending a custom fingerprint. The `fingerprint` parameter can be used to override the fingerprint for an exception reported with the `honeybadger.notify` method. The fingerprint value will be converted to a string if it isn’t already: ```python from honeybadger import honeybadger honeybadger.notify(exception, fingerprint="a unique string") ``` All errors with the fingerprint “a unique string” will be grouped together in Honeybadger. For more information about the `honeybadger.notify` method, see [Reporting Errors](/lib/python/errors/reporting-errors/). # Environments > Learn how to configure environments in Honeybadger for Python. Honeybadger groups errors by the environment they belong to. The default environment is “production”, but you can set it to different values such as “staging” or “development” depending on where your app is running. You can set the environment by calling the `honeybadger.configure` method: ```python from honeybadger import honeybadger honeybadger.configure(api_key='redacted', environment='development') ``` You can also set the environment using the `HONEYBADGER_ENVIRONMENT` environment variable: ```bash export HONEYBADGER_ENVIRONMENT="staging" ``` ## Development environments [Section titled “Development environments”](#development-environments) Some environments should usually not report errors at all, such as when you are developing on your local machine or running your test suite (locally or in CI). The *honeybadger* package has an internal list of environment names which it considers development environments: ```text development dev test ``` Honeybadger **does not** report errors in these environments. To always send data regardless of the environment, you can set the `force_report_data` to `True`: ```python from honeybadger import honeybadger honeybadger.configure( api_key='redacted', environment='development', force_report_data=True ) ``` If you have development environments that aren’t part of the default list, you can set the `development_environments` configuration option to meet your needs: ```python from honeybadger import honeybadger honeybadger.configure( api_key='redacted', environment='staging', development_environments=['development', 'dev', 'test', 'staging'] ) ``` This will ensure that errors are not sent in the specified environments. ## Framework defaults [Section titled “Framework defaults”](#framework-defaults) When using Django, if `DEBUG = True` is set in your Django settings, Honeybadger will automatically set the environment to “development”. This can be overridden by explicitly setting the environment in your Honeybadger configuration or using the `HONEYBADGER_ENVIRONMENT` environment variable. For more configuration options, see [Configuration](/lib/python/reference/configuration/). # Filtering sensitive data > Learn how to filter sensitive data from error reports sent to Honeybadger. You have complete control over the data that Honeybadger reports when an error occurs. Before data is sent to Honeybadger, it is passed through a filter to remove sensitive fields and do other processing on the data. The default configuration is equivalent to: ```python from honeybadger import honeybadger honeybadger.configure( params_filters=[ "password", "password_confirmation", "credit_card", "CSRF_COOKIE", ] ) ``` ## How it works [Section titled “How it works”](#how-it-works) The `params_filters` configuration applies to: * **Request parameters** (GET/POST data) * **Session data** * **Cookies** * **CGI environment variables** * **Local variables** (when `report_local_variables` is enabled) Any field matching a filter key will have its value replaced with `"[FILTERED]"`. Filtering works recursively on nested dictionaries. For example: ```python # Before filtering data = { "username": "alice", "password": "secret123", "user_data": { "credit_card": "1234-5678-9012-3456" } } # After filtering data = { "username": "alice", "password": "[FILTERED]", "user_data": { "credit_card": "[FILTERED]" } } ``` ## Filtering with before\_notify [Section titled “Filtering with before\_notify”](#filtering-with-before_notify) For more control, you can use a `before_notify` handler to inspect and modify the notice before it’s sent. This gives you access to request params, session data, CGI variables, and more: ```python from honeybadger import honeybadger def filter_notice(notice): # Remove a specific key from request params if "api_token" in notice.params: del notice.params["api_token"] # Redact session data notice.session = { k: "[FILTERED]" if k in ("auth_token", "csrf") else v for k, v in notice.session.items() } return notice honeybadger.configure(before_notify=filter_notice) ``` See [Configuration](/lib/python/reference/configuration/#notice-properties) for a full list of available notice properties. # Reducing noise > Learn how to reduce noise and ignore specific errors in Honeybadger. Sometimes there are errors that you would rather not send to Honeybadger because they are not actionable or are handled internally. ## Ignoring errors by class name [Section titled “Ignoring errors by class name”](#ignoring-errors-by-class-name) By default Honeybadger will be notified when any error occurs. To override this configuration in order not to send out errors to Honeybadger, set `excluded_exceptions` in `honeybadger.configure`. The `excluded_exceptions` configuration accepts a list of exception class names (as strings) to exclude: ```python from honeybadger import honeybadger honeybadger.configure(excluded_exceptions=["ZeroDivisionError", "ValueError"]) ``` Exceptions are skipped when the exception’s class name is found in the `excluded_exceptions` list. ## Dynamic ignoring errors with before\_notify [Section titled “Dynamic ignoring errors with before\_notify”](#dynamic-ignoring-errors-with-before_notify) For more complex scenarios, you can use a `before_notify` handler to conditionally ignore errors: ```python from honeybadger import honeybadger def filter_errors(notice): # Skip connection errors during maintenance windows if notice.error_class == 'ConnectionError' and is_maintenance_mode(): return False return notice honeybadger.configure(before_notify=filter_errors) ``` Returning `False` from the handler will skip the notification entirely. For more information about configuring `before_notify` and other options, see [Configuration](/lib/python/reference/configuration/#filtering-and-enriching-errors). # Reporting errors > Learn how to report errors to Honeybadger from your Python application. Use `honeybadger.notify()` to send errors to Honeybadger: ```python from honeybadger import honeybadger try: # Buggy code goes here except Exception as exception: honeybadger.notify(exception) ``` ## Reporting errors without an exception [Section titled “Reporting errors without an exception”](#reporting-errors-without-an-exception) You can report any type of error to Honeybadger, not just exceptions. The simplest form is calling `honeybadger.notify` with a custom class and message: ```python from honeybadger import honeybadger honeybadger.notify( error_class='ValueError', error_message='Something bad happened!' ) # Or send a simple string message honeybadger.notify("Something went wrong!") ``` ## Passing additional options to `honeybadger.notify` [Section titled “Passing additional options to honeybadger.notify”](#passing-additional-options-to-honeybadgernotify) In some cases you will want to override the defaults or add additional information to your error reports. To do so, you can pass more arguments to `honeybadger.notify`. For example, you could add tags to a notification: ```python from honeybadger import honeybadger honeybadger.notify(exception, tags=["my_custom_tag", "another_tag"]) ``` These are all the available arguments you can pass to `honeybadger.notify`: | Parameter | Type | Required | Description | | --------------- | ----------- | -------- | --------------------------------------------------------- | | `exception` | `Exception` | \* | An instance of an exception | | `error_class` | `str` | \*\* | A string representation of a class name | | `error_message` | `str` | \*\* | An error message | | `fingerprint` | `str` | No | A unique identifier used to group related errors together | | `context` | `dict` | No | A dictionary containing additional context information | | `tags` | `list[str]` | No | A list of tags to associate with the error | \* Either provide an `exception` object, OR both `error_class` and `error_message`. \*\* Required when not providing an `exception` object. The `honeybadger.notify()` method returns a UUID string that uniquely identifies the error notification. # Tagging errors > Learn how to use tags to organize and filter errors in Honeybadger. Each error in Honeybadger has tags. Tags can be used to filter results when searching and can even apply to integrations so that only errors with a combination of certain tags trigger an email or a Slack message, for example. Tags can be used to create custom workflows, such as: * Find all errors tagged “badgers” and resolve them. * Tag critical errors as “critical” and configure PagerDuty to alert you only when a critical error happens. * If you have errors which aren’t actionable (but you still want to know about them), you could tag them with “low\_priority” and exclude those errors when automatically creating issues via the GitHub integration. * Tag all errors that happen in an area of your app with the name of the team that is responsible for them, then notify their Slack channel for only those errors. These are just examples: you can use tags however you want! While you can always add tags to existing errors through the Honeybadger UI, they are most useful when you add them programmatically as the exceptions happen. There are two ways to add tags to errors from your Python app: ## Tagging errors in global context [Section titled “Tagging errors in global context”](#tagging-errors-in-global-context) Every exception which is reported within the current context will have the specified tags added. Use the `_tags` argument to set the tags: ```python from honeybadger import honeybadger # Using a comma-separated string honeybadger.set_context(_tags="critical, badgers") # Or using a list of strings honeybadger.set_context(_tags=["critical", "badgers"]) ``` ## Tagging errors in `honeybadger.notify` [Section titled “Tagging errors in honeybadger.notify”](#tagging-errors-in-honeybadgernotify) The tags will be added for just the current error being reported: ```python from honeybadger import honeybadger # Using a comma-separated string honeybadger.notify(exception, tags="critical, badgers") # Or using a list of strings honeybadger.notify(exception, tags=["critical", "badgers"]) ``` ## Tag processing [Section titled “Tag processing”](#tag-processing) Tags are processed as follows: * Comma-separated strings are split into individual tags * Whitespace is automatically trimmed from each tag * Tags from context and explicit tags are merged and deduplicated * Empty tags are ignored # Tracking deployments > Learn how to track deployments in Honeybadger for your Python application. Honeybadger has an API to keep track of project deployments. Whenever you deploy, all errors for that environment will be resolved automatically. You can choose to enable or disable the auto-resolve feature from your Honeybadger project settings page. ## Deploying with GitHub Actions [Section titled “Deploying with GitHub Actions”](#deploying-with-github-actions) If your CI/CD pipeline is hosted with GitHub Actions, you can use the [Honeybadger Deploy Action](https://github.com/marketplace/actions/honeybadger-deploy-action) to notify our API about deployments. ## Deploying with `curl` [Section titled “Deploying with curl”](#deploying-with-curl) ```sh HONEYBADGER_ENV="production" \ HONEYBADGER_REVISION="$(git rev-parse HEAD)" \ HONEYBADGER_REPOSITORY="$(git config --get remote.origin.url)" \ HONEYBADGER_API_KEY="Your project API key" \ && curl -g "https://api.honeybadger.io/v1/deploys?deploy[environment]=$HONEYBADGER_ENV&deploy[local_username]=$USER&deploy[revision]=$HONEYBADGER_REVISION&deploy[repository]=$HONEYBADGER_REPOSITORY&api_key=$HONEYBADGER_API_KEY" ``` If you are using our EU stack, you should use `eu-api.honeybadger.io` instead of `api.honeybadger.io` for the domain name. # Insights overview > Query automatic Django, Flask, ASGI, and Celery instrumentation alongside custom application events from Python in Honeybadger Insights. [Insights](/guides/insights/) lets you observe what your Python application does in production. Honeybadger records common Python activity automatically, including Django and Flask requests, ORM queries, ASGI traffic, and Celery tasks. From there, you can add context and custom events from your own code, then use [BadgerQL](/guides/insights/badgerql/) to ask questions across the whole event stream. Any field you send is queryable as soon as it arrives, with no schema to define ahead of time. ## Start with automatic instrumentation [Section titled “Start with automatic instrumentation”](#start-with-automatic-instrumentation) Set `insights_enabled=True` in your config and the package starts recording events as soon as your app boots. [Automatic instrumentation](/lib/python/insights/automatic-instrumentation/)Configure what the package captures. [Python event reference](/insights/event-types/python/)See every Python event type and field. ## Add a built-in dashboard [Section titled “Add a built-in dashboard”](#add-a-built-in-dashboard) Automatic events power built-in dashboards. [Celery](/guides/dashboards/celery/)Task counts by status, average durations, failures and retries [Django](/guides/dashboards/django/)Request durations, response status counts, slowest views and queries [Flask](/guides/dashboards/flask/)Request durations, response codes, and slowest views and queries by blueprint ## Add application context [Section titled “Add application context”](#add-application-context) Context adds fields to the current thread. Once set, every event emitted from that thread carries them. Say the app is A/B testing a new checkout flow against the control. Each checkout request sets context like this: Set the variant on context ```python honeybadger.set_event_context(checkout_variant=checkout_variant) ``` The `checkout_variant` field is now on every database event for that request. You can group by it like any other field. Database work by checkout variant ```badgerql filter event_type::str == "db.query" and isNotNull(checkout_variant::str) | stats count() as queries, avg(duration::float) as avg_ms by checkout_variant::str | sort queries desc ``` | queries | avg\_ms | checkout\_variant | | ------- | ------- | ----------------- | | 26815 | 2.48 | new | | 11873 | 2.21 | control | The new variant ran more than twice as many queries with similar per-query time. Keep in mind that adding another A/B variant will extend any of the examples here without the need to change anything on the Honeybadger side. Go deeper: check for possible N+1 queries The package attaches a `request_id` to every event from the same request. To turn total database work into queries per request, group events by `request_id` first to get a per-request count, then aggregate by variant. ```badgerql filter event_type::str == "db.query" and isNotNull(checkout_variant::str) | stats count() as queries by request_id::str, checkout_variant::str | stats count() as request_count, avg(queries) as avg_q, percentile(95, queries) as p95_q by checkout_variant | sort p95_q desc | only toHumanString(request_count) as requests, toHumanString(avg_q) as avg_queries, toHumanString(p95_q) as p95_queries, checkout_variant ``` | requests | avg\_queries | p95\_queries | checkout\_variant | | -------- | ------------ | ------------ | ----------------- | | 631 | 42.18 | 97 | new | | 638 | 18.61 | 31 | control | The new variant runs more queries per request, and the p95 is much higher than control. That pattern often points at an N+1. [Event context](/lib/python/insights/event-context/)Context lifecycle, temporary scopes, and precedence. ## Record application events [Section titled “Record application events”](#record-application-events) Custom events record activity the framework cannot see at all. Django knows a checkout request ran. Only your app knows whether the payment authorized: Send a custom payment event ```python honeybadger.event("payment.authorized", { "payment_provider": payment.provider, "amount": checkout.total, "currency": checkout.currency, "authorization_id": payment.authorization_id, }) ``` This query breaks down the amounts collected by variant and provider: Payments by variant and provider ```badgerql filter event_type::str == "payment.authorized" | stats count() as authorizations, sum(amount::float) as authorized_amount by checkout_variant::str, payment_provider::str | sort authorized_amount desc ``` | authorizations | authorized\_amount | checkout\_variant | payment\_provider | | -------------- | ------------------ | ----------------- | ----------------- | | 413 | 34108.00 | new | stripe | | 218 | 18722.00 | new | paypal | | 418 | 32167.00 | control | stripe | | 220 | 13639.00 | control | paypal | Go deeper: more insights, same instrumentation Conversion rate by variant ```badgerql filter event_type::str == "payment.authorized" or view::str == "checkout_create" | stats count(event_type::str == "payment.authorized") as auth_events by request_id::str, checkout_variant::str | stats count() as auths, count(auth_events > 0) as checkouts, checkouts / auths as conv_rate by checkout_variant::str | only conv_rate, checkout_variant ``` | conv\_rate | checkout\_variant | | ---------- | ----------------- | | 0.92 | new | | 0.86 | control | Revenue per payment provider per variant ```badgerql filter event_type::str == "payment.authorized" | stats sum(amount::float) as total by payment_provider::str, checkout_variant::str | sort total desc | only toHumanString(total) as revenue, payment_provider, checkout_variant ``` | revenue | payment\_provider | checkout\_variant | | ------- | ----------------- | ----------------- | | 34,108 | stripe | new | | 32,167 | stripe | control | | 18,722 | paypal | new | | 13,639 | paypal | control | Average checkout response time by variant ```badgerql filter event_type::str == "django.request" and view::str == "checkout_create" | stats avg(duration::float) as avg_ms by checkout_variant::str | only toHumanString(avg_ms, "milliseconds") as avg, checkout_variant ``` | avg | checkout\_variant | | ----- | ----------------- | | 142ms | new | | 78ms | control | Conversion rate over time, by variant ```badgerql filter event_type::str == "payment.authorized" or view::str == "checkout_create" | stats count(event_type::str == "payment.authorized") as auth_events, min(@ts) as request_ts by request_id::str, checkout_variant::str | stats count(auth_events > 0) / count() as conv_rate by checkout_variant::str, bin(1h, request_ts) as hour | sort hour asc ``` | conv\_rate | checkout\_variant | hour | | ---------- | ----------------- | ------------------- | | 0.93 | new | 2026-06-26 14:00:00 | | 0.86 | control | 2026-06-26 14:00:00 | | 0.92 | new | 2026-06-26 15:00:00 | | 0.86 | control | 2026-06-26 15:00:00 | | 0.91 | new | 2026-06-26 16:00:00 | | 0.87 | control | 2026-06-26 16:00:00 | The new variant holds a consistent lead over control across the rollout window. [Sending custom events](/lib/python/insights/sending-custom-events/)The full honeybadger.event API. # Automatic instrumentation > Events the Honeybadger Python package captures automatically from Django, Flask, Celery, and more for Honeybadger Insights. Honeybadger Insights allows you to automatically track various events in your application. To enable Insights automatic instrumentation, add the following to your configuration: ```python from honeybadger import honeybadger honeybadger.configure(insights_enabled=True) ``` ## Supported libraries [Section titled “Supported libraries”](#supported-libraries) *After integration with our middleware or extensions*, Honeybadger will automatically instrument the following libraries: * **Django** requests & database queries * **Flask** requests & database queries * **ASGI** requests * **Celery** tasks * **Oban** workers & maintenance loops See the [Python event reference](/insights/event-types/python/) for every event the package emits, with field schemas and types. You can configure the instrumentation for specific libraries / components by passing a dictionary to a specialized `insights_config` parameter. By default, all keyword dict params are run through our `params_filters`. ### Django [Section titled “Django”](#django) Django instrumentation captures these event types: * `django.request` * `db.query` Database events are configured in [their own section](#database), but are emitted automatically by the Django instrumentation. You can configure the Django instrumentation by passing a dictionary to `insights_config`: ```python honeybadger.configure( insights_config={ "django": { # Disable instrumentation for Django, defaults to False "disabled": True, # include GET/POST params in events, defaults to False "include_params": True, } } ) ``` ### Flask [Section titled “Flask”](#flask) Flask instrumentation captures these event types: * `flask.request` * `db.query` Database events are configured in [their own section](#database), but are emitted automatically by the Flask instrumentation. You can configure the Flask instrumentation by passing a dictionary to `insights_config`: ```python honeybadger.configure( insights_config={ "flask": { # Disable instrumentation for Flask, defaults to False "disabled": True, # Include GET/POST params in events, defaults to False "include_params": True, } } ) ``` ### ASGI [Section titled “ASGI”](#asgi) ASGI instrumentation captures these event types: * `asgi.request` You can configure the ASGI instrumentation by passing a dictionary to `insights_config`: ```python honeybadger.configure( insights_config={ "asgi": { # Disable instrumentation for ASGI, defaults to False "disabled": True, # Include query params in events, defaults to False "include_params": True, } } ) ``` ### Celery [Section titled “Celery”](#celery) Celery instrumentation captures these event types: * `celery.task_finished` You can configure the Celery instrumentation by passing a dictionary to `insights_config`: ```python import re from honeybadger import honeybadger honeybadger.configure( insights_config={ "celery": { # Disable instrumentation for Celery, defaults to False "disabled": True, # Include task args/kwargs, defaults to False "include_args": True, # List of task names or regexes to exclude, defaults to [] "exclude_tasks": [ "tasks.cleanup", re.compile("^internal_"), ], } } ) ``` ### Oban [Section titled “Oban”](#oban) [Oban](https://github.com/oban-bg/oban-py) is the Python port of the Elixir background job library. The Oban integration must be initialized explicitly (see the [Oban integration guide](/lib/python/integrations/other/#oban)) before it will emit events. Oban instrumentation captures these event types: * `oban.job_finished` * `oban.leader_exception` * `oban.stager_exception` * `oban.lifeline_exception` * `oban.pruner_exception` * `oban.refresher_exception` * `oban.scheduler_exception` * `oban.producer_exception` The `oban.job_finished` event is emitted on `oban.job.stop` and `oban.job.exception` telemetry from Oban. The `oban.*_exception` events are emitted when a corresponding maintenance loop raises. You can configure the Oban instrumentation by passing a dictionary to `insights_config`: ```python import re from honeybadger import honeybadger honeybadger.configure( insights_config={ "oban": { # Disable instrumentation for Oban, defaults to False "disabled": True, # Include job.args / job.meta in events, defaults to False "include_args": True, # List of worker names or regexes to exclude, defaults to [] "exclude_workers": [ "myapp.NoisyWorker", re.compile("^internal_"), ], } } ) ``` `exclude_workers` patterns match against the worker’s fully-qualified class name. String patterns are exact-match; compiled regex patterns use `.search()`. `exclude_workers` filters Insights events only — error reporting is unaffected. Honeybadger event context set before enqueuing a job is automatically propagated through `job.meta` and restored when the job runs, preserving request IDs and other context across async boundaries. ### Database [Section titled “Database”](#database) Honeybadger can capture database queries for supported libraries like Django ORM and SQLAlchemy. The event types captured include: * `db.query` These events are emitted as a side effect of other instrumentation, such as Django or Flask, so you don’t need to enable them separately. You can configure the database instrumentation by passing a dictionary to `insights_config`: ```python import re from honeybadger import honeybadger from honeybadger.config import default_excluded_queries honeybadger.configure( insights_config={ "db": { # Disable instrumentation for DB, defaults to False "disabled": True, # Include SQL params in events, defaults to False "include_params": True, # List of queries to exclude (strings or regexes), defaults to # common system queries "exclude_queries": [ "django_admin_log", # Matches any query containing this string re.compile(r".*auth_permission.*"), # Regex pattern ], # To add to the default excluded queries, import and use the default_excluded_queries function "exclude_queries": default_excluded_queries() + [ re.compile(r".*my_custom_table.*"), "my_system_query", ], } } ) ``` ## Sending your own events [Section titled “Sending your own events”](#sending-your-own-events) Automatic instrumentation covers the libraries the package knows about. To send your own application events, see [Sending custom events](/lib/python/insights/sending-custom-events/). ## Sending logs from your infrastructure [Section titled “Sending logs from your infrastructure”](#sending-logs-from-your-infrastructure) Honeybadger isn’t just for errors and application data! You can use our [syslog](/guides/insights/integrations/systemd/), [Vector](/guides/insights/integrations/log-files/), or [PaaS integrations](/guides/insights/#adding-data-from-other-sources) to send additional data from your infrastructure to [Honeybadger Insights](/guides/insights/), where you can query, visualize, and analyze all of your production data in one place. # Event context > Learn how to add custom metadata to events sent to Honeybadger Insights. You can add custom metadata to the events sent to Honeybadger Insights by using the `honeybadger.set_event_context` function. This metadata will be included in each event call within the current thread. Caution This will add the metadata to all events sent, so be careful not to include too much data. Try to keep it to simple key/value pairs. ```python from honeybadger import honeybadger honeybadger.set_event_context( user_id=user.id, session_id=session.id ) ``` ## Context lifecycle [Section titled “Context lifecycle”](#context-lifecycle) Event context is automatically cleared at the beginning of each web request in supported frameworks ([Django](/lib/python/integrations/django/), [Flask](/lib/python/integrations/flask/)). You can also manually clear it: ```python honeybadger.reset_event_context() ``` ## Temporary context [Section titled “Temporary context”](#temporary-context) For temporary context that should only apply to specific operations, use the context manager: ```python with honeybadger.event_context(operation="batch_import"): # Context is only set within this block honeybadger.event("import.started") process_batch() honeybadger.event("import.completed") # Context is automatically restored when exiting the block ``` ## Precedence [Section titled “Precedence”](#precedence) If both event context and event data contain the same key, the event data takes precedence: ```python honeybadger.set_event_context(service="api") honeybadger.event("order.created", service="checkout") # service="checkout" is used ``` # Filtering events > Learn how to filter or customize events sent to Honeybadger Insights. You can filter out or customize events sent to Honeybadger Insights by using the `before_event` configuration parameter. ```python from honeybadger import honeybadger def filter_event(event): # Skip health check requests if event.get('path') == '/health': return False # Redact sensitive data from custom events if event.get('event_type') == 'user.signup' and 'email' in event: event['email'] = '[REDACTED]' return event honeybadger.configure(before_event=filter_event) ``` This function will be called for every event before it is sent to Honeybadger. For more information about configuring `before_event` and other options, see [Configuration](/lib/python/reference/configuration/#filtering-and-enriching-events). # Sampling events > Learn how to sample events to reduce the volume sent to Honeybadger Insights. You can enable event sampling to reduce the number of events sent to Honeybadger. This is especially useful if you are hitting your daily event quota limit: ```python from honeybadger import honeybadger honeybadger.configure(events_sample_rate=50) # Sample 50% of events ``` The `events_sample_rate` option accepts a whole percentage value between 0 and 100, where 0 means no events will be sent and 100 means all events will be sent. The default is no sampling (100%). Events are sampled by hashing the `request_id` if available in the event payload, otherwise a unique UUID is generated for that event. This deterministic approach ensures that related events from the same request are consistently sampled together. ## Per-event sampling [Section titled “Per-event sampling”](#per-event-sampling) Note The `_hb` metadata is automatically removed from events before they are sent to Honeybadger. The sample rate is applied to all events sent to Honeybadger Insights, including automatic instrumentation events. You can also set the sample rate per event by adding the `_hb` metadata with a `sample_rate` key: ```python honeybadger.event("user_created", { "user_id": user.id, "_hb": {"sample_rate": 100} }) ``` The event sample rate can also be set within the `honeybadger.set_event_context` function. This can be handy if you want to set an overall sample rate for a thread or ensure that specific instrumented events get sent: ```python # Set a higher sampling rate for this entire thread honeybadger.set_event_context(_hb={"sample_rate": 100}) # Now all events from this thread, including automatic instrumentation, # will use the 100% sample rate ``` Remember that event context is thread-local and applies to all events sent from the same thread after the `set_event_context` call, until it’s changed or the thread terminates. ## Sample rate precedence [Section titled “Sample rate precedence”](#sample-rate-precedence) Sample rates are determined in the following order (highest to lowest priority): 1. **Event data** - `_hb` metadata passed directly to the event 2. **Event context** - `_hb` metadata set via `set_event_context()` 3. **Global configuration** - `events_sample_rate` config option When setting sample rates below the global setting, be aware that this affects how events with the same `request_id` are sampled. Since sampling is deterministic based on the `request_id` hash, all events sharing the same `request_id` will either all be sampled or all be skipped together. This ensures consistency across related events. # Sending custom events > Send custom events from Python applications to Honeybadger Insights for monitoring and analysis. Use `honeybadger.event` method to send custom events to [Honeybadger Insights](/guides/insights/). This allows you to track and monitor important events in your application. (For the events the package captures on its own, see [Automatic instrumentation](/lib/python/insights/automatic-instrumentation/).) ```python from honeybadger import honeybadger # Send a simple event honeybadger.event('user.signup', {'email': 'user@example.com'}) # Send an event with additional metadata honeybadger.event( 'order.completed', { 'order_id': '123', 'total': 49.99, 'items': ['item1', 'item2'] } ) # Or pass everything as a dictionary honeybadger.event({ 'event_type': 'order.completed', 'order_id': '123', 'total': 49.99, 'items': ['item1', 'item2'] }) ``` The `event` method can be called in two ways: * With two parameters: `event_type` (string) and `data` (dictionary) * With one parameter: a dictionary containing `event_type` and any additional data We recommend `event_type` for grouping your events. A `ts` timestamp is automatically added to events if not present, using the current UTC time in ISO 8601 format. For more information about configuring Insights and events, see [Insights Configuration](/lib/python/reference/configuration/#insights-configuration). # Django integration guide > Set up Django error tracking, performance monitoring, and observability with Honeybadger in 5 minutes. **Typical installation time:** 5 minutes Hi there! You’ve found Honeybadger’s guide to **Django error tracking and performance monitoring**. Once installed, Honeybadger will automatically report errors and performance insights from your Django application. ## Installing the package [Section titled “Installing the package”](#installing-the-package) Install the `honeybadger` Python package with pip (or add it to your `requirements.txt`): ```bash pip install honeybadger ``` In your Django application, add the Honeybadger Django middleware to *the top* of your `MIDDLEWARE` config variable in `settings.py`: ```python MIDDLEWARE = [ 'honeybadger.contrib.DjangoHoneybadgerMiddleware', # ... your other middleware ] ``` It’s important that the Honeybadger middleware is at the top, so that it wraps the entire request process, including all other middleware. Add a new `HONEYBADGER` config variable to your `settings.py`: ```python HONEYBADGER = { 'API_KEY': 'PROJECT_API_KEY', 'INSIGHTS_ENABLED': True } ``` Tip You can also configure Honeybadger with environment variables: ```sh export HONEYBADGER_API_KEY="PROJECT_API_KEY" export HONEYBADGER_INSIGHTS_ENABLED=True ``` If you use this method, you can omit the `HONEYBADGER` configuration from `settings.py`. See the [Configuration reference](/lib/python/reference/configuration/) for additional info. ## Testing your installation [Section titled “Testing your installation”](#testing-your-installation) Note Honeybadger does not report errors in `development` and `test` environments by default. To enable reporting in development environments, temporarily add `'FORCE_REPORT_DATA': True` to your Honeybadger config. To test that Honeybadger is working, you can create a simple test exception: ```python from honeybadger import honeybadger try: raise Exception("Honeybadger test exception") except Exception as e: honeybadger.notify(e) ``` If the installation is working correctly, this error should appear in your Honeybadger dashboard. ## How it works [Section titled “How it works”](#how-it-works) The `DjangoHoneybadgerMiddleware` integrates with Django’s request/response cycle to automatically capture errors and performance data. When an exception occurs, it automatically adds the following information to the error report: * **URL**: The full URL the request was sent to * **Component**: The Django app name (if available) * **Action**: The view function name * **Params**: GET or POST parameters (filtered for sensitive data) * **Session**: Session data (filtered for sensitive data) * **CGI data**: Request headers and environment variables (filtered for sensitive data) * **Context**: Username and user ID when `request.user` is authenticated ### Performance monitoring [Section titled “Performance monitoring”](#performance-monitoring) When [Insights is enabled](/lib/python/insights/automatic-instrumentation/), the middleware automatically tracks: * **Request performance**: Response times, status codes, and view information * **Database queries**: Query duration and SQL statements (with configurable filtering) * **Request correlation**: Generates or captures request IDs for tracing across systems ## Sending logs from your infrastructure [Section titled “Sending logs from your infrastructure”](#sending-logs-from-your-infrastructure) Honeybadger isn’t just for errors and application data! You can use our [syslog](/guides/insights/integrations/systemd/), [Vector](/guides/insights/integrations/log-files/), or [PaaS integrations](/guides/insights/#adding-data-from-other-sources) to send additional data from your infrastructure to [Honeybadger Insights](/guides/insights/), where you can query, visualize, and analyze all of your production data in one place. # Flask integration guide > Set up Flask error tracking, performance monitoring, and observability with Honeybadger in 5 minutes. **Typical installation time:** 5 minutes Hi there! You’ve found Honeybadger’s guide to **Flask error tracking and performance monitoring**. Once installed, Honeybadger will automatically report errors and performance insights from your Flask application. ## Installing the package [Section titled “Installing the package”](#installing-the-package) Install the `honeybadger` Python package with pip (or add it to your `requirements.txt`): ```bash pip install honeybadger ``` Flask also requires the `blinker` library for automatic error reporting: ```bash pip install blinker ``` In your Flask application, initialize the Honeybadger extension: ```python from flask import Flask from honeybadger.contrib import FlaskHoneybadger app = Flask(__name__) app.config['HONEYBADGER_ENVIRONMENT'] = 'production' app.config['HONEYBADGER_API_KEY'] = 'PROJECT_API_KEY' app.config['HONEYBADGER_INSIGHTS_ENABLED'] = True FlaskHoneybadger(app, report_exceptions=True, reset_context_after_request=True) ``` Tip `FlaskHoneybadger` checks Flask’s configuration object and automatically configures Honeybadger using [12-factor style config options](/lib/python/reference/configuration/#twelve-factor-configuration). You can also configure Honeybadger with environment variables: ```sh export HONEYBADGER_ENVIRONMENT="production" export HONEYBADGER_API_KEY="PROJECT_API_KEY" export HONEYBADGER_INSIGHTS_ENABLED=True ``` If you use this method, you can omit the `app.config` settings. Environment variables take precedence over Flask configuration settings when both are present. See the [Configuration reference](/lib/python/reference/configuration/) for additional info. ## Testing your installation [Section titled “Testing your installation”](#testing-your-installation) Note Honeybadger does not report errors in `development` and `test` environments by default. To enable reporting in development environments, temporarily add `app.config['HONEYBADGER_FORCE_REPORT_DATA'] = True` to your Flask config. To test that Honeybadger is working, you can create a simple test exception: ```python from honeybadger import honeybadger try: raise Exception("Honeybadger test exception") except Exception as e: honeybadger.notify(e) ``` If the installation is working correctly, this error should appear in your Honeybadger dashboard. ## How it works [Section titled “How it works”](#how-it-works) The `FlaskHoneybadger` extension uses Flask’s signals (via [Blinker](https://github.com/pallets-eco/blinker)) to detect and report exceptions. When an exception occurs, it automatically adds the following information to the error report: * **URL**: The URL the request was sent to * **Component**: The module that the view is defined in (or class name for class-based views) * **Action**: The name of the function called (prefixed with blueprint name if applicable) * **Params**: Query parameters and form data (filtered for sensitive data) * **Session**: Session data * **CGI data**: Request headers and method (filtered for sensitive data) ### Component naming conventions [Section titled “Component naming conventions”](#component-naming-conventions) The following conventions are used for component names: * View functions: `#` * Class-based views: `#` * Blueprints: `#.` ### Additional configuration options [Section titled “Additional configuration options”](#additional-configuration-options) When initializing `FlaskHoneybadger`, you can pass additional options: | Name | Type | Default | Description | | ----------------------------- | ------ | ------- | -------------------------------------------------------------------------------- | | `report_exceptions` | `bool` | `False` | Automatically report exceptions raised in views (including those from `abort()`) | | `reset_context_after_request` | `bool` | `False` | Reset [Honeybadger context](/lib/python/errors/context/) after each request | ## Sending logs from your infrastructure [Section titled “Sending logs from your infrastructure”](#sending-logs-from-your-infrastructure) Honeybadger isn’t just for errors and application data! You can use our [syslog](/guides/insights/integrations/systemd/), [Vector](/guides/insights/integrations/log-files/), or [PaaS integrations](/guides/insights/#adding-data-from-other-sources) to send additional data from your infrastructure to [Honeybadger Insights](/guides/insights/), where you can query, visualize, and analyze all of your production data in one place. # Python integration guide > Set up Python error tracking, performance monitoring, and observability with Honeybadger in 5 minutes. **Typical installation time:** 5 minutes Hi there! You’ve found Honeybadger’s guide to **Python error tracking and performance monitoring**. Once installed, Honeybadger will automatically report errors and performance insights from your application. ## Installing the package [Section titled “Installing the package”](#installing-the-package) Install the `honeybadger` Python package with pip (or add it to your `requirements.txt`): ```bash pip install honeybadger ``` See the [framework-specific sections](#supported-frameworks) on this page for how to configure Honeybadger for your application. For other frameworks (tornado, web2py, etc.) or plain Python scripts, simply import honeybadger and configure it with your API key. Honeybadger uses a global exception hook to automatically report uncaught exceptions: ```python from honeybadger import honeybadger honeybadger.configure( api_key='PROJECT_API_KEY', insights_enabled=True ) raise Exception("This will get reported!") ``` Tip You can also configure Honeybadger with environment variables: ```sh export HONEYBADGER_API_KEY="PROJECT_API_KEY" export HONEYBADGER_INSIGHTS_ENABLED=True ``` If you use this method, you can omit explicit configuration in your application code. Environment variables take precedence over programmatic configuration when both are present. See the [Configuration reference](/lib/python/reference/configuration/) for additional info. ## Testing your installation [Section titled “Testing your installation”](#testing-your-installation) Note Honeybadger does not report errors in `development` and `test` environments by default. To enable reporting in development environments, temporarily add `force_report_data=True` to your Honeybadger config. To test that Honeybadger is working, you can create a simple test exception: ```python from honeybadger import honeybadger try: raise Exception("Honeybadger test exception") except Exception as e: honeybadger.notify(e) ``` If the installation is working correctly, this error should appear in your Honeybadger dashboard. ## Supported frameworks [Section titled “Supported frameworks”](#supported-frameworks) ### Django [Section titled “Django”](#django) See the [Django integration guide](/lib/python/integrations/django/). ### Flask [Section titled “Flask”](#flask) See the [Flask integration guide](/lib/python/integrations/flask/). ### AWS Lambda [Section titled “AWS Lambda”](#aws-lambda) AWS Lambda environments are auto-detected by Honeybadger with no additional configuration. Here’s an example lambda function with Honeybadger: ```python from honeybadger import honeybadger honeybadger.configure( api_key='PROJECT_API_KEY', insights_enabled=True ) def lambda_handler(event, context): """ A buggy lambda function that tries to perform a zero division """ a = 1 b = 0 return (a/b) # This will be reported ``` ### Celery [Section titled “Celery”](#celery) A Celery extension is available for initializing and configuring Honeybadger: `honeybadger.contrib.celery.CeleryHoneybadger`. The extension adds the following information to reported exceptions: * **component**: The module that the task is defined at. * **action**: The name of the task. * **params**: The arguments and keyword arguments passed to the task. * **context**: A dictionary containing the following: * **task\_id**: The id of the current task. * **retries**: The number of retries that have been attempted. * **max\_retries**: The maximum number of retries that will be attempted. #### Example [Section titled “Example”](#example) ```python from celery import Celery from honeybadger.contrib import CeleryHoneybadger app = Celery(__name__) app.conf.update( HONEYBADGER_API_KEY='PROJECT_API_KEY', HONEYBADGER_ENVIRONMENT='production', HONEYBADGER_INSIGHTS_ENABLED=True ) CeleryHoneybadger(app, report_exceptions=True) ``` ### Oban [Section titled “Oban”](#oban) Honeybadger integrates with [Oban](https://github.com/oban-bg/oban-py) (the Python port of the Elixir background job library) to report unhandled worker exceptions and emit per-job telemetry to Honeybadger Insights. Requires Python 3.12+ and `oban>=0.6.2`. ```python from oban import Oban from honeybadger import honeybadger from honeybadger.contrib.oban import ObanHoneybadger honeybadger.configure( api_key='PROJECT_API_KEY', insights_enabled=True ) ObanHoneybadger(report_exceptions=True).init() async with Oban(pool=pool, queues={"default": 10}) as oban: ... ``` Setting `report_exceptions=True` installs an `executor.wrap_result` extension that calls `honeybadger.notify` whenever a worker raises. The following information is added to reported exceptions: * **component**: The module the worker is defined in. * **action**: The fully-qualified worker name. * **params**: A dictionary containing the job’s `args` and `meta` (filtered). * **context**: A dictionary containing `job_id`, `queue`, `attempt`, `max_attempts`, and `tags`. When `insights_enabled=True`, the integration also emits `oban.job_finished` events and `oban._exception` events for maintenance-loop failures to Honeybadger Insights. See the [Oban Insights configuration](/lib/python/insights/automatic-instrumentation/#oban) for details. Honeybadger event context set before enqueuing a job is automatically propagated through `job.meta` so the Insights timeline can link the enqueuing request to the worker’s execution. Only one `ObanHoneybadger` instance may be active per process. Call `tearDown()` to fully reverse all wiring (useful in tests or for application shutdown hooks). ### FastAPI [Section titled “FastAPI”](#fastapi) [FastAPI](https://fastapi.tiangolo.com/) is based on Starlette, an ASGI application. You use Honeybadger’s ASGI middleware on these types of applications. ```python from fastapi import FastAPI from honeybadger import contrib app = FastAPI() app.add_middleware(contrib.ASGIHoneybadger) ``` You can pass additional configuration parameters as keyword arguments: ```python from fastapi import FastAPI from honeybadger import honeybadger, contrib honeybadger.configure( api_key="PROJECT_API_KEY", insights_enabled=True ) app = FastAPI() app.add_middleware(contrib.ASGIHoneybadger, params_filters=["sensitive_data"]) ``` #### FastAPI advanced usage [Section titled “FastAPI advanced usage”](#fastapi-advanced-usage) Consuming the request body in an ASGI application’s middleware is [problematic and discouraged](https://github.com/encode/starlette/issues/495#issuecomment-494008175). This is the reason why request body data won’t be sent to the web UI. FastAPI allows overriding the logic used by the `Request` and `APIRoute` classes, by [using custom `APIRoute` classes](https://fastapi.tiangolo.com/advanced/custom-request-and-route/). This gives more control over the request body, and makes it possible to send request body data along with honeybadger notifications. A custom API Route is available at [`honeybadger.contrib.fastapi`](https://github.com/honeybadger-io/honeybadger-python/blob/master/honeybadger/contrib/fastapi.py): ```python from fastapi import FastAPI, APIRouter from honeybadger import honeybadger from honeybadger.contrib.fastapi import HoneybadgerRoute honeybadger.configure( api_key="PROJECT_API_KEY", insights_enabled=True ) app = FastAPI() app.router.route_class = HoneybadgerRoute router = APIRouter(route_class=HoneybadgerRoute) ``` ### Starlette [Section titled “Starlette”](#starlette) You can configure Honeybadger to work with [Starlette](https://www.starlette.io/) just like in any other ASGI framework. ```python from starlette.applications import Starlette from honeybadger import contrib app = Starlette() app.add_middleware(contrib.ASGIHoneybadger) ``` ### Other ASGI applications [Section titled “Other ASGI applications”](#other-asgi-applications) A generic [ASGI](https://asgi.readthedocs.io/en/latest/) middleware plugin is available for initializing and configuring Honeybadger: [`honeybadger.contrib.asgi`](https://github.com/honeybadger-io/honeybadger-python/blob/master/honeybadger/contrib/asgi.py). The general pattern for ASGI applications is wrapping your application with the middleware: ```python from honeybadger import contrib asgi_application = someASGIApplication() asgi_application = contrib.ASGIHoneybadger(asgi_application) ``` You can pass configuration parameters (or *additional* configuration parameters) as keyword arguments at plugin’s initialization: ```python from honeybadger import contrib asgi_application = someASGIApplication() asgi_application = contrib.ASGIHoneybadger( asgi_application, api_key="PROJECT_API_KEY", insights_enabled=True, params_filters=["sensible_data"] ) ``` Or you may want to initialize Honeybadger before your application, and then just register the plugin/middleware: ```python from honeybadger import honeybadger, contrib honeybadger.configure( api_key='PROJECT_API_KEY', insights_enabled=True ) # You can track errors happening before your plugin initialization some_possibly_failing_function() asgi_application = someASGIApplication() asgi_application = contrib.ASGIHoneybadger(asgi_application) ``` ## Sending logs from your infrastructure [Section titled “Sending logs from your infrastructure”](#sending-logs-from-your-infrastructure) Honeybadger isn’t just for errors and application data! You can use our [syslog](/guides/insights/integrations/systemd/), [Vector](/guides/insights/integrations/log-files/), or [PaaS integrations](/guides/insights/#adding-data-from-other-sources) to send additional data from your infrastructure to [Honeybadger Insights](/guides/insights/), where you can query, visualize, and analyze all of your production data in one place. # Configuration > Configuration options for the Honeybadger Python library. You can set configuration options for the Honeybadger client by calling the `honeybadger.configure` method. This can be called in one of your application files such as `settings.py` or `wsgi.py`, or in a custom middleware. ```python from honeybadger import honeybadger honeybadger.configure( api_key="PROJECT_API_KEY", environment="production", project_root="/path/to/your/project/root", excluded_exceptions=["SomeIgnoredException"], ) ``` See [Configuration Options](#configuration-options) for a list of available options. ## Twelve-factor configuration [Section titled “Twelve-factor configuration”](#twelve-factor-configuration) Most of Honeybadger’s configuration options can also be set via environment variables with the `HONEYBADGER_` prefix ([12-factor style](https://12factor.net)). For example, the `api_key` option can be set via the `HONEYBADGER_API_KEY` environment variable: ```bash export HONEYBADGER_API_KEY="PROJECT_API_KEY" export HONEYBADGER_ENVIRONMENT="production" ``` ## Filtering and enriching errors [Section titled “Filtering and enriching errors”](#filtering-and-enriching-errors) The `before_notify` handler allows you to filter or modify error notifications before they’re sent to Honeybadger: ```python def custom_before_notify(notice): # Skip notifications for specific error types if notice.error_class == 'MyCustomError': return False # Skip this notification # Add custom context notice.context['custom_data'] = 'example' # Redact sensitive request params if 'secret' in notice.params: del notice.params['secret'] # Return the notice to send it return notice honeybadger.configure(before_notify=custom_before_notify) ``` Return `False` from the handler to skip the notification. Return the notice object to send it. ### Notice properties [Section titled “Notice properties”](#notice-properties) The following properties are available on the `notice` object passed to `before_notify`. All properties support both reading and writing unless noted otherwise. | Property | Type | Description | | ----------------- | ------ | ---------------------------------------------- | | `error_class` | `str` | The exception class name (e.g. `"ValueError"`) | | `error_message` | `str` | The error message | | `backtrace` | `list` | The parsed backtrace | | `fingerprint` | `str` | Custom fingerprint for error grouping | | `context` | `dict` | The context dict | | `tags` | `list` | Tags applied to the error | | `params` | `dict` | Request parameters | | `session` | `dict` | Session data from the request | | `cgi_data` | `dict` | CGI variables such as HTTP headers | | `url` | `str` | The URL at which the error occurred | | `component` | `str` | The component (e.g. controller name) | | `action` | `str` | The action that was called | | `causes` | `list` | Exception cause chain | | `local_variables` | `dict` | Local variables from the first backtrace frame | | `id` | `str` | The unique ID of this notice (read only) | In AWS Lambda, the Lambda event is available at `notice.params["event"]`. For example, to filter the request body from an API Gateway event: ```python def filter_lambda_body(notice): event = notice.params.get("event", {}) if "body" in event: event["body"] = "[FILTERED]" return notice honeybadger.configure(before_notify=filter_lambda_body) ``` ## Filtering and enriching events [Section titled “Filtering and enriching events”](#filtering-and-enriching-events) The `before_event` handler allows you to filter or modify performance events before they’re sent to Honeybadger: ```python def custom_before_event(event): # Skip events from health check endpoints if event.get('path') == '/health': return False # Skip this event # Add custom metadata for slow requests if event.get('duration', 0) > 1000: # Over 1 second event['slow_request'] = True # Return the event to send it return event honeybadger.configure(before_event=custom_before_event) ``` Return `False` from the handler to skip the event. Return the event object to send it. ## Configuration options [Section titled “Configuration options”](#configuration-options) The following options are available to you: | Name | Type | Default | | ------------------------------------ | ---------- | --------------------------------------------------------------------- | | `api_key` | `str` | `""` | | `project_root` | `str` | The current working directory | | `environment`[1](#user-content-fn-1) | `str` | `"production"` | | `development_environments` | `list` | `['development', 'dev', 'test']` | | `hostname` | `str` | The hostname of the current server. | | `endpoint` | `str` | `"https://api.honeybadger.io"` | | `params_filters` | `list` | `['password', 'password_confirmation', 'credit_card', 'CSRF_COOKIE']` | | `force_report_data` | `bool` | `False` | | `excluded_exceptions` | `list` | `[]` | | `force_sync` | `bool` | `False` | | `report_local_variables` | `bool` | `False` | | `insights_enabled` | `bool` | `False` | | `insights_config` | `dict` | `{}` (see [Insights Configuration](#insights-configuration)) | | `events_sample_rate` | `int` | `100` (0-100, percentage of events to send) | | `events_batch_size` | `int` | `1000` | | `events_max_queue_size` | `int` | `10000` | | `events_timeout` | `float` | `5.0` | | `events_max_batch_retries` | `int` | `3` | | `events_throttle_wait` | `float` | `60.0` | | `before_notify` | `callable` | `lambda notice: notice` | | `before_event` | `callable` | `lambda event: event` | ## Insights configuration [Section titled “Insights configuration”](#insights-configuration) The `insights_config` option accepts a dictionary with configuration for Honeybadger’s automatic instrumentation: ```python from honeybadger import honeybadger honeybadger.configure( insights_enabled=True, insights_config={ "django": {"include_params": True}, "db": {"disabled": True}, "celery": {"exclude_tasks": ["cleanup_task"]} } ) ``` Each instrumented framework has its own set of options: | Framework | Name | Type | Default | Description | | :--------- | :---------------- | :------------------- | :------------------------------------ | :---------------------------------------------- | | **django** | | | | | | | `disabled` | `bool` | `False` | Disable Django instrumentation | | | `include_params` | `bool` | `False` | Include GET/POST parameters in request events | | **flask** | | | | | | | `disabled` | `bool` | `False` | Disable Flask instrumentation | | | `include_params` | `bool` | `False` | Include GET/POST parameters in request events | | **asgi** | | | | | | | `disabled` | `bool` | `False` | Disable ASGI instrumentation | | | `include_params` | `bool` | `False` | Include query parameters in request events | | **celery** | | | | | | | `disabled` | `bool` | `False` | Disable Celery instrumentation | | | `include_args` | `bool` | `False` | Include task arguments/kwargs in events | | | `exclude_tasks` | `list[str or regex]` | `[]` | List of task names or regex patterns to exclude | | **db** | | | | | | | `disabled` | `bool` | `False` | Disable database instrumentation | | | `include_params` | `bool` | `False` | Include SQL parameters in query events | | | `exclude_queries` | `list[str or regex]` | System queries[2](#user-content-fn-2) | List of queries to exclude | ## Footnotes [Section titled “Footnotes”](#footnote-label) 1. Honeybadger will try to infer the correct environment when possible. For example, in the case of the Django integration, if Django settings are set to `DEBUG = True`, the environment will default to `development`. [↩](#user-content-fnref-1) 2. Default excluded queries include Django migrations, auth tables, and common system queries. Import `default_excluded_queries` from `honeybadger.config` to see the full list. [↩](#user-content-fnref-2) # Supported versions > Supported Python and framework versions for the Honeybadger library. The support tables below are for the latest version of the Honeybadger package, which aims to support all maintained (non-EOL) versions of Python and supported frameworks. If you’re using an older version of Python or your framework, you may need to install an older version of the package. | Library | Supported Version | | ------- | ----------------- | | Python | >= 3.8 | | Django | >= 4.2.20 | | Flask | >= 1.1.4 | # Frequently asked questions > Frequently asked questions about the Honeybadger Python library. ## Why aren’t my errors being reported? [Section titled “Why aren’t my errors being reported?”](#why-arent-my-errors-being-reported) The most common reason for errors not being reported is that the app is in a development environment. See the [Environments](/lib/python/errors/environments/#development-environments) chapter in the **Error Tracking** guide for more information. The second most common reason is that the error being reported is covered by the [excluded\_exceptions list](/lib/python/errors/reducing-noise/). If neither of these is the issue, check out the [Troubleshooting guide](/lib/python/support/troubleshooting/#all-errors-are-not-reported). ## Why aren’t I getting notifications? [Section titled “Why aren’t I getting notifications?”](#why-arent-i-getting-notifications) By default we only send notifications the first time an exception happens, and when it re-occurs after being marked resolved. If an exception happens 100 times, but was never resolved you’ll only get 1 email about it. # Troubleshooting > Common issues and solutions for the Honeybadger Python library. Common issues and workarounds for [honeybadger-python](https://github.com/honeybadger-io/honeybadger-python) are documented here. If you don’t find a solution to your problem here or in our support documentation, email and we’ll assist you! ## Before you start troubleshooting [Section titled “Before you start troubleshooting”](#before-you-start-troubleshooting) 1. Make sure you are on the latest version of [honeybadger-python](https://pypi.org/project/honeybadger/). ## All errors are not reported [Section titled “All errors are not reported”](#all-errors-are-not-reported) If *no* errors are reported (even [manually via `honeybadger.notify`](/lib/python/errors/reporting-errors/)): 1. [Is the `api_key` config option configured?](/lib/python/reference/configuration/) 2. [Are you in a development environment?](/lib/python/errors/environments/#development-environments) ## Some errors are not reported [Section titled “Some errors are not reported”](#some-errors-are-not-reported) 1. [Is the error ignored via config?](/lib/python/errors/reducing-noise/) # Honeybadger for Ruby > Ruby exception tracking with the honeybadger Ruby gem. Hi there! You’ve found Honeybadger’s docs on **Ruby exception tracking**. In this guide we’re going to discuss the **honeybadger Ruby gem** and how to use it to track exceptions in your Ruby applications. If you’re new to Honeybadger, we recommend taking a moment to read through. This guide is also your reference for how to use the gem in the future, so **bookmark it**. For a refresher on working with exceptions in Ruby, check out the [Honeybadger guide to Ruby exceptions](https://www.exceptionalcreatures.com/guides/what-are-ruby-exceptions.html). ## Getting started [Section titled “Getting started”](#getting-started) Getting started is easy! First, see our [installation and configuration guide](/lib/ruby/getting-started/introduction/) for instructions on adding Honeybadger to your app in less than 3 minutes. Next steps: * Learn about getting the most out of Honeybadger for your platform or framework with one of our **Integration guides**: [Rails](/lib/ruby/integration-guides/rails-exception-tracking/), [Sinatra](/lib/ruby/integration-guides/sinatra-exception-tracking/), [Rack](/lib/ruby/integration-guides/rack-exception-tracking/), [Heroku](/lib/ruby/integration-guides/heroku-exception-tracking/), [AWS Lambda](/lib/ruby/integration-guides/aws-lambda-exception-tracking/), or [other Ruby apps](/lib/ruby/integration-guides/ruby-exception-tracking/). * See the **Gem Reference section** for details about the [gem’s configuration](/lib/ruby/gem-reference/configuration/), [public method API](https://www.rubydoc.info/gems/honeybadger), and [CLI](/lib/ruby/gem-reference/cli/) (Command Line Interface). * Finally, you may also be interested in **other areas of our documentation**, such as our [REST API guide](/api/) or [general product guides](/). ## Getting support [Section titled “Getting support”](#getting-support) If you’re having trouble working with the gem (such as you aren’t receiving error reports when you should be): 1. Read [Frequently asked questions](/lib/ruby/support/faq/) 2. Upgrade to the latest gem version if possible (you can find a list of bugfixes and other changes in the [CHANGELOG](https://github.com/honeybadger-io/honeybadger-ruby/blob/master/CHANGELOG.md)) 3. Run through our [Troubleshooting guide](/lib/ruby/support/troubleshooting/) For all other problems, contact support for help: **If your issue is gem-related**, here are a few items you can send us which will make it easier to spot the problem: * Run `bundle exec honeybadger test --file=honeybadger_test.txt` from the server having the problem and attach the generated honeybadger\_test.txt file * Run `bundle exec rake middleware` from the server having the problem and attach the output as plaintext * Attach your config/honeybadger.yml file * Attach your Gemfile.lock file # Adding context to errors > Add context to Ruby error reports with custom data to improve debugging and error resolution. Sometimes, default exception data just isn’t enough. If you have extra data that will help you in debugging, send it as part of an error’s context. Context is what you’re looking for if: * You want to record the current user’s id or email address at the time of an exception * You need to send raw POST data for use in debugging * You have any other metadata you’d like to send with an exception Honeybadger supports two types of context: global and local. ## Global context [Section titled “Global context”](#global-context) Global context is automatically reported with any exception which occurs after the context has been created: ```ruby Honeybadger.context({ my_data: 'my value' }) ``` A few other methods are also available when working with context: ```ruby # Clear the global context: Honeybadger.context.clear! # Fetch the global context: Honeybadger.get_context ``` Global context is stored in a [thread-local variable](https://ruby-doc.org/core-3.0.1/Thread.html#class-Thread-label-Thread+variables+and+scope), which means each thread has its own global context. ## Local context [Section titled “Local context”](#local-context) Local context is similar to global context but it is only reported with exceptions that occur within a specific block of code where the local context is set. This is useful when you want to add context data for a specific operation or a set of operations, but you don’t want that context to leak into other parts of your application. You can set local context by passing a block to the `Honeybadger.context` method: ```ruby Honeybadger.context({ local_data: 'local value' }) do # This block of code has access to the local context. # If an exception occurs here, the local context will be reported with the exception. end ``` The local context is automatically cleared after the block is executed, even if an exception is raised within the block. This ensures that the local context does not leak into other parts of your application. To fetch the local context, you can call `Honeybadger.get_context`: ```ruby # Set global context Honeybadger.context({ global_data: 'global value' }) # Fetch and print global context puts Honeybadger.get_context # Expected output: { global_data: 'global value' } # Set local context within a block Honeybadger.context({ local_data: 'local value' }) do # Fetch and print context within the block puts Honeybadger.get_context # Expected output: { global_data: 'global value', local_data: 'local value' } end # Fetch and print context outside the block puts Honeybadger.get_context # Expected output: { global_data: 'global value' } ``` Calling `Honeybadger.get_context` within a block will return a merged hash of the global and local context. If there are conflicts, the local context will take precedence. Remember, local context is also stored in a thread-local variable, which means each thread has its own local context. ## Context in `Honeybadger.notify` [Section titled “Context in Honeybadger.notify”](#context-in-honeybadgernotify) You can also add context to a manual error report using the `:context` option, like this: ```ruby Honeybadger.notify(exception, context: { my_data: 'my local value' }) ``` Local context always overrides any global values when the error is reported. ## Special context values [Section titled “Special context values”](#special-context-values) While you can add any key/value data to context, a few keys have special meaning in Honeybadger: | Option | Description | | ------------- | -------------------------------------------------------------------------------------------------------- | | `:_action` | This will set the `action` attribute of your error data if not already set. | | `:_component` | This will set the `component` attribute of your error data if not already set. | | `:user_id` | The `String` user ID used by Honeybadger to aggregate user data across occurrences on the error page. | | `:user_email` | Same as `:user_id`, but for email addresses | | `:tags` | A `String` comma-separated list of tags. When present, tags will be applied to errors with this context. | Using the `:_action` and `:_component` keys are useful when you are manually reporting errors via `Honeybadger.notify` or `Rails.error.report`. ## Defining context on objects [Section titled “Defining context on objects”](#defining-context-on-objects) Context must either be a `Hash`, or it must define the method `#to_honeybadger_context` to return a `Hash`. For example, to pass a `User` instance to `Honeybadger.context`: ```ruby class User < ApplicationRecord def to_honeybadger_context { user_id: id, user_email: email } end end user = User.last Honeybadger.context(user) ``` When the `#to_honeybadger_context` method is defined on an `Exception` class, the context will be automatically added when the exception is reported: ```ruby class CustomError < StandardError def to_honeybadger_context { tags: 'custom' } end end raise CustomError, 'This error will be reported with context' ``` ## Limits [Section titled “Limits”](#limits) Honeybadger uses the following limits to ensure the service operates smoothly for everyone: * Nested objects have a max depth of 20 * Context values have a max size of 64Kb When an error notification includes context data that exceed these limits, the context data will be truncated, and the notification will still be processed. # Breadcrumbs > Add breadcrumbs to Ruby error reports to track events and user actions leading up to errors. Breadcrumbs are a useful debugging tool that give you the ability to record contextual data as an event called a `breadcrumb`. When your Project reports an Error (Notice), we send along the breadcrumbs recorded during the execution (request, job, task, etc…). [Context](/lib/ruby/errors/adding-context-to-errors/) is another way to store extra data to help with debugging. Context is still a great way to attach global data to an error, however, there are scenarios where Breadcrumbs might be a better choice: * You want to record metadata that contains duplicate keys * You want to group related data * You care about when an event happened in relation to an error ## Automatic Rails breadcrumbs [Section titled “Automatic Rails breadcrumbs”](#automatic-rails-breadcrumbs) Rails provides a robust [Active Support Instrumentation](https://guides.rubyonrails.org/active_support_instrumentation.html) implementation that allows us to automatically add insights into your errors. The instrumentation breadcrumbs are very configurable. You can modify a copy of the default config if you want to change the default behavior. Here’s how you might remove all ActiveRecord breadcrumb events: ```ruby notifications = Honeybadger::Breadcrumbs::ActiveSupport.default_notifications notifications.delete("sql.active_record") Honeybadger.configure do |config| config.breadcrumbs.active_support_notifications = notifications end ``` Note Active Record SQL logging is on by default. Seeing what SQL statements have been executed leading up to an error can often give helpful context during debugging. We attempt to strip out any bound params or columns before storing queries, however, if you are executing any raw SQL commands or not using prepared statements, there might be a chance that sensitive data could get into the breadcrumb metadata. If you want to keep the ActiveRecord breadcrumbs but remove the SQL metadtata, you could update the config like this: ```ruby notifications = Honeybadger::Breadcrumbs::ActiveSupport.default_notifications notifications["sql.active_record"][:select_keys].delete_if {|k| k == :sql} Honeybadger.configure do |config| config.breadcrumbs.active_support_notifications = notifications end ``` You can set an empty hash to remove ActiveSupport notifications all together: ```ruby Honeybadger.configure do |config| config.breadcrumbs.active_support_notifications = {} end ``` The key for each instrumentation hash is the hook id used for subscribing to the ActiveSupport notification. For example ```ruby { "process_action.action_controller" => { message: "Action Controller Action Process", select_keys: [:controller, :action, :format, :method, :path, :status, :view_runtime, :db_runtime], category: "request", } } ``` will subscribe to the `process_action.action_controller` instrumentation notification and produce a breadcrumb with the specified `message` and `category` and restrict [the keys](https://guides.rubyonrails.org/active_support_instrumentation.html#process-action-action-controller) passed into the metadata to the set supplied by `select_keys`. Here are all the options you can pass into an instrumentation hash: | Option name | Description | | | --------------- | ----------------------------------------------------------------------------------------------------------------------------------------- | ------ | | `:message` | A `String` message that describes the event or you can dynamically build the message by passing a `Proc` that accepts the event metadata. | | | `:category` | A `String` key used to group specific types of events | | | `:select_keys` | An (*optional*) `Array` of keys that filters what data we select from the instrumentation data | `Proc` | | `:exclude_when` | A (*optional*) `Proc` that accepts the data payload. A truthy return value will exclude this event from the payload | `Proc` | | `:transform` | A (*optional*) `Proc` that accepts the data payload. The return value will replace the current data hash | | Check out the [config](https://github.com/honeybadger-io/honeybadger-ruby/blob/master/lib/honeybadger/breadcrumbs/active_support.rb). to see what we instrument by default. Note Some of these configuration options have `Procs` so you will need to configure `breadcrumbs.active_support_notifications` in the Ruby configuration only. ## Custom breadcrumbs [Section titled “Custom breadcrumbs”](#custom-breadcrumbs) You can also add your own custom breadcrumb events: ```ruby Honeybadger.add_breadcrumb("Email Sent", metadata: { user: user.id, message: message }) ``` The first argument (`message`) is the only required data. In the UI, `message` is front and center in your breadcrumbs list, so we prefer a more terse description accompanied by rich metadata. Here are the options allowed while adding breadcrumbs: | Option name | Description | | ----------- | ----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | | `:metadata` | A (*optional*) `Hash` that contains any contextual data to help debugging. We only accept a single-level hash with simple primitives as values (Strings, Numbers, Booleans & Symbols) | | `:category` | An (*optional*) `String` key used to group specific types of events. We primarily use this key to display a corresponding icon, however, you can use it for your own categorization if you like | ## Logging breadcrumbs [Section titled “Logging breadcrumbs”](#logging-breadcrumbs) All log messages, by default, sent to the `::Logger` class are converted into breadcrumbs. Breadcrumbs from logging can be disabled within the config: ```yaml --- breadcrumbs: logging: enabled: false ``` ## Categories [Section titled “Categories”](#categories) A Breadcrumb category is a top level property. It’s main purpose is to allow for display differences (icons & styling) in the UI. You may give a breadcrumb any category you wish. Unknown categories will default to the ‘custom’ styling. Here are the current categories and a brief description of how you might categorize certain activity: | Category | Description | | -------- | ------------------------------------------- | | custom | Any other kind of breadcrumb | | error | A thrown error | | query | Access or Updates to any data or file store | | job | Queueing or Working via a job system | | request | Outbound / inbound requests | | render | Any output or serialization via templates | | log | Any messages logged | | notice | A Honeybadger Notice | ## Disabling breadcrumbs [Section titled “Disabling breadcrumbs”](#disabling-breadcrumbs) As of version `4.6.0`, Breadcrumbs are enabled by default. You can disable breadcrumbs via the `breadcrumbs.enabled` configuration option (in YAML): ```yaml --- breadcrumbs: enabled: false ``` or in the Ruby config: ```ruby Honeybadger.configure do |config| config.breadcrumbs.enabled = false end ``` ## Limits [Section titled “Limits”](#limits) Honeybadger uses the following limits to ensure the service operates smoothly for everyone: * We only store & transmit 40 breadcrumb events. The current implementation only keeps the 40 latest breadcrumb events. * Metadata can only hold scalar values (no nested hashes or arrays) * String values have a max size of 64Kb # Collecting user feedback > Collect user feedback when errors occur in Ruby applications to get context directly from affected users. The Honeybadger gem has a few special tags that it looks for whenever you render an error page in a Rack-based application. These can be used to display extra information about the error, or to ask the user for information about how they triggered the error. ## Installing the middleware [Section titled “Installing the middleware”](#installing-the-middleware) Honeybadger installs the middleware automatically in Rails projects. For all other applications, the middleware must be installed manually: ```ruby use Honeybadger::Rack::UserInformer use Honeybadger::Rack::UserFeedback ``` ## Displaying the error ID [Section titled “Displaying the error ID”](#displaying-the-error-id) When an error is sent to Honeybadger, our API returns a unique UUID for the occurrence within your project. This UUID can be automatically displayed for reference on error pages. To include the error id, simply place this magic HTML comment on your error page (normally `public/500.html` in Rails): ```html ``` By default, we will replace this tag with: ```plaintext Honeybadger Error {{error_id}} ``` Where `{{error_id}}` is the UUID. You can customize this output by overriding the `user_informer.info` option in your honeybadger.yml file (you can also enabled/disable the middleware): config/honeybadger.yml ```yaml user_informer: enabled: true info: "Error ID: {{error_id}}" ``` You can use that UUID to load the error at the site by going to [https://app.honeybadger.io/notice/some-uuid-goes-here](https://app.honeybadger.io/notice/). ## Displaying a feedback form [Section titled “Displaying a feedback form”](#displaying-a-feedback-form) When an error is sent to Honeybadger, an HTML form can be generated so users can fill out relevant information that led up to that error. Feedback responses are displayed inline in the comments section on the fault detail page. To include a user feedback form on your error page, simply add this magic HTML comment (normally `public/500.html` in Rails): ```html ``` You can change the text displayed in the form via the Rails internationalization system. Here’s an example: config/locales/en.yml ```yaml en: honeybadger: feedback: heading: "Care to help us fix this?" explanation: "Any information you can provide will help us fix the problem." submit: "Send" thanks: "Thanks for the feedback!" labels: name: "Your name" email: "Your email address" comment: "Comment (required)" ``` The feedback form can be enabled and disabled using the `feedback.enabled` config option (defaults to `true`): config/honeybadger.yml ```yaml feedback: enabled: true ``` # Customizing error grouping > Customize how errors are grouped in Ruby applications to better organize and prioritize error reports. Honeybadger groups similar exceptions together using rules which we’ve found to work the best in most cases. The default information we use to group errors is: 1. The file name, method name, and line number of the error’s location 2. The class name of the error 3. The component/controller name We use this information to construct a “fingerprint” of the exception. Exceptions with the same fingerprint are treated as the same error in Honeybadger. You can customize the grouping for each exception by changing the error class name, component, or stack trace—or by sending a custom fingerprint. There are two ways you can customize the fingerprint: globally (for all exceptions that are reported from your app), and locally (when calling `Honeybadger.notify`). ## Customizing the grouping for all exceptions [Section titled “Customizing the grouping for all exceptions”](#customizing-the-grouping-for-all-exceptions) The `Honeybadger.before_notify` callback in conjunction with the `Notice#fingerprint` method allows you to change the fingerprint of a notice to properly group the same notices. ```ruby Honeybadger.configure do |config| config.before_notify do |notice| notice.fingerprint = [notice.error_class, notice.component, notice.backtrace.join(',')].join(':') end end ``` The `notice` parameter gives you access to useful details about the exception, such as the `url` where it occurred and the `parsed_backtrace`, an array of hashes representing each line in its backtrace. For a full list of available properties, see the [API reference](https://www.rubydoc.info/gems/honeybadger/Honeybadger/Notice). ## Customizing the grouping for `Honeybadger.notify` [Section titled “Customizing the grouping for Honeybadger.notify”](#customizing-the-grouping-for-honeybadgernotify) The `:fingerprint` option can be used to override the fingerprint for an exception reported with `Honeybadger.notify`: ```ruby Honeybadger.notify(exception, fingerprint: 'a unique string') ``` # Customizing object display > Customize how objects are displayed in Ruby error reports to improve readability and protect sensitive data. By default, Honeybadger supports displaying the following core Ruby objects (uncoincidentally, these objects are also supported by JSON): ```plaintext Hash Array Set Numeric TrueClass FalseClas NilClass String ``` When an object of a different class is sent as data to Honeybadger (via context, request data, local variables, etc.), it’s first converted to a string using the `String()` function. For instance, given a `User` object which defines the `#to_s` method to return the user’s email address: ```ruby class User < ApplicationRecord def to_s email end end user = User.create(email: "user@example.com") Honeybadger.context({ user: user }) ``` …Honeybadger will display the context as: ```json { "user": "user@example.com" } ``` If this value is undesirable (since there’s no way to know the class of the object), the `#to_honeybadger` method can be defined to customize the value that is reported to Honeybadger: ```ruby class User < ApplicationRecord def to_s email end def to_honeybadger "#" end end ``` …now the context will display as: ```json { "user": "#" } ``` Note that while by default the contents of `#inspect` are filtered to prevent leaking sensitive attributes, attributes are **not** filtered when returning `#inspect` from `#to_honeybadger`, so it’s always best to explicitly interpolate the attributes that you want to display unless you know that the inspected output will never contain sensitive information. # Environments > Configure environment-specific error tracking settings for Ruby applications across development, staging, and production. In Honeybadger, errors are grouped by the environment they belong to. You don’t have to set an environment, but it can be useful if you’re running different versions of your app: for instance, you may have a “production” and a “staging” environment. Our integrations typically set the environment automatically if your framework has an environment (such as `Rails.env`). To set the environment manually, set the `env` configuration option: ```yaml --- api_key: "your-api-key" env: "production" ``` Another option for configuring the environment that gets reported to Honyebadger is to set the `HONEYBADGER_ENV` environment variable. If this variable is set, its value will override the `RAILS_ENV` variable. ## Development environments [Section titled “Development environments”](#development-environments) Some environments should usually not report errors at all, such as when you are developing on your local machine or running your test suite (locally or in CI). The *honeybadger* gem has an internal list of environment names which it considers development environments: ```plaintext development test cucumber ``` Honeybadger **does not** report errors in these environments unless you explicitly enable data reporting: ```yaml --- api_key: "your-api-key" report_data: true ``` # Filtering sensitive data > Filter sensitive data from Ruby error reports to protect user privacy and comply with security requirements. You have complete control over the data that Honeybadger reports when an error occurs. You can [filter specific attributes](#filtering-specific-attributes) or [disable the reporting](#disable-data-completely) of entire sections of data. ## Filtering specific attributes [Section titled “Filtering specific attributes”](#filtering-specific-attributes) By default, we filter the `password` and `password_confirmation`, as well as any params specified in Rails’ [`filter_parameters`](https://guides.rubyonrails.org/action_controller_overview.html#parameters-filtering). You can configure the gem to filter additional data from the params, session, environment and cookies hashes. To do so, use the `request.filter_keys` setting. When you add an attribute name to `request.filter_keys`, that attribute will be removed from any exceptions before they are reported to us. Here’s an example honeybadger.yml: ```yaml request: filter_keys: - password - password_confirmation - credit_card_number ``` The configuration above will filter out `params[:credit_card_number]`, `session[:credit_card_number]`, `cookies[:credit_card_number]`, and `Rails.env["credit_card_number"]`, as well as the password and password\_confirmation attributes. Regular expressions (regex) are also allowed. The configuration below will filter out any keys that are named anything matching `/credit_card/i`. ```yaml request: filter_keys: - !ruby/regexp "/credit_card/i" ``` ## Disable data completely [Section titled “Disable data completely”](#disable-data-completely) You can turn off reporting of params, session and environment data entirely. Here are the configuration options to do it: ```yaml request: disable_session: true # Don't report session data disable_params: true # Don't report request params disable_environment: true # Don't report anything from Rack ENV disable_url: true # Don't report the request URL ``` # Ignoring errors > Ignore specific errors in Ruby applications to reduce noise and focus on actionable error reports. Sometimes there are errors that you would rather not send to Honeybadger because they are not actionable or are handled internally. The *honeybadger* gem has multiple ways to ignore errors, depending on the situation: * [Ignore by class](#ignore-by-class) * [Ignore by browser](#ignore-by-browser) * [Ignore by environment](#ignore-by-environment) * [Ignore programmatically](#ignore-programmatically) ## Ignore by class [Section titled “Ignore by class”](#ignore-by-class) Some exceptions aren’t very useful and are best ignored. By default, we ignore the following: ```ruby ActionController::RoutingError AbstractController::ActionNotFound ActionController::MethodNotAllowed ActionController::UnknownHttpMethod ActionController::NotImplemented ActionController::UnknownFormat ActionController::InvalidAuthenticityToken ActionController::InvalidCrossOriginRequest ActionDispatch::ParamsParser::ParseError ActionController::BadRequest ActionController::ParameterMissing ActiveRecord::RecordNotFound ActionController::UnknownAction Rack::QueryParser::ParameterTypeError Rack::QueryParser::InvalidParameterError CGI::Session::CookieStore::TamperedWithCookie Mongoid::Errors::DocumentNotFound Sinatra::NotFound ``` To ignore additional errors, use the `exceptions.ignore` configuration option. The gem will ignore any exceptions matching the string, regex or class that you add to `exceptions.ignore`. ```yaml exceptions: ignore: - "MyError" - !ruby/regexp "/Ignored$/" - !ruby/class "IgnoredError" ``` Subclasses of ignored classes will also be ignored, while strings and regexps are compared with the error class name only. To override the default ignored exceptions, use the `exceptions.ignore_only` option instead: ```yaml exceptions: ignore_only: - "MyError" ``` In this case *only* the MyError class will be ignored, and all the classes that were ignored by default will no longer be ignored. ## Ignore by browser [Section titled “Ignore by browser”](#ignore-by-browser) To ignore certain user agents, use the `exceptions.ignored_user_agents` config option. You can specify strings or regular expressions: ```yaml exceptions: ignored_user_agents: - "Exact User Agent" - !ruby/regexp "/Bing/i" ``` ## Ignore by environment [Section titled “Ignore by environment”](#ignore-by-environment) Honeybadger ignores errors in development and test environments by default. You can enable or disable error reporting for a specific environment by using the `[environment name].report_data` configuration option: ```yaml staging: report_data: false ``` You may alternatively set `HONEYBADGER_REPORT_DATA=false` in your app’s ENV. We ask that you not enable error reporting for your test environment. It doesn’t do anyone any good. :) ## Ignore programmatically [Section titled “Ignore programmatically”](#ignore-programmatically) To ignore errors with some custom logic, you can use the `before_notify` callback. This method lets you add a callback that will be run every time an exception is about to be reported to Honeybadger. If your callback calls the `notice.halt!` method, the exception won’t be reported: ```ruby # Here's how you might ignore exceptions based on their error message: Honeybadger.configure do |config| config.before_notify do |notice| notice.halt! if notice.error_message =~ /sensitive data/ end end ``` You can access any attribute on the `notice` argument by using the `[]` syntax. ```ruby Honeybadger.configure do |config| config.before_notify do |notice| notice.halt! if notice.exception.class < MyError && notice.params[:name] =~ "bob" && notice.context[:current_user_id] != 1 end end ``` # Reporting errors > Report errors from Ruby applications to Honeybadger with automatic notifications and custom error handling. Use `Honeybadger.notify(exception)` to send any exception to Honeybadger. For example, to notify Honeybadger of a rescued exception without re-raising: controller.rb ```ruby begin fail 'oops' rescue => exception Honeybadger.notify(exception) end ``` ## Reporting errors without an exception [Section titled “Reporting errors without an exception”](#reporting-errors-without-an-exception) You can report any type of error to Honeybadger, not just exceptions. The simplest form is calling `Honeybadger.notify` with an error message: ```ruby Honeybadger.notify("Something is wrong here") ``` The error’s class name will default to “Notice”, and a backtrace will be generated for you from the location in your code where `Honeybadger.notify` was called. ## Passing additional options to `Honeybadger.notify` [Section titled “Passing additional options to Honeybadger.notify”](#passing-additional-options-to-honeybadgernotify) In some cases you will want to override the defaults or add additional information to your error reports. To do so, you can pass a second options `Hash` to `Honeybadger.notify`. For example, building on the example in [Reporting errors without an exception](#reporting-errors-without-an-exception), you could override the default class name: ```ruby Honeybadger.notify("Something is wrong here", error_class: "MyError") ``` These are all the available options you can pass to `Honeybadger.notify`: | Option name | Description | Default value | | ---------------- | -------------------------------------------------------------- | ------------- | | `:error_message` | The `String` error message. | `nil` | | `:error_class` | The `String` class name of the error. | `"Notice"` | | `:backtrace` | The `Array` backtrace of the error. | `caller` | | `:fingerprint` | The `String` grouping fingerprint of the exception. | `nil` | | `:force` | Always report the exception when `true`, even when ignored. | `false` | | `:sync` | Send data synchronously (skips the worker) when `true`. | `false` | | `:tags` | The `String` comma-separated list of tags. | `nil` | | `:context` | The `Hash` context to associate with the exception. | `nil` | | `:controller` | The `String` controller name (such as a Rails controller). | `nil` | | `:component` | The `String` component name (such as a Rails controller name). | `nil` | | `:action` | The `String` action name (such as a Rails controller action). | `nil` | | `:parameters` | The `Hash` HTTP request paramaters. | `nil` | | `:session` | The `Hash` HTTP request session. | `nil` | | `:url` | The `String` HTTP request URL. | `nil` | ## Getting the current backtrace [Section titled “Getting the current backtrace”](#getting-the-current-backtrace) There are two ways to get the current backtrace in Ruby: 1. `Thread.current.backtrace` returns the entire backtrace up to and including the current method. 2. `caller` returns the backtrace up to but NOT including the current method. Either method can be passed to `Honeybadger.notify` using the `backtrace` option. Honeybadger sends the exception backtrace by default, or `caller` if there is no exception object available. # Tagging errors > Add tags to Ruby error reports to categorize and filter errors for better organization and analysis. Each error in Honeybadger has tags. Tags can be used to filter results when searching and can even apply to integrations so that only errors with a combination of certain tags trigger an email or a Slack message, for example. Tags can be used to create custom workflows, such as: * Find all errors tagged “badgers” and resolve them. * Tag critical errors as “critical” and configure PagerDuty to alert you only when a critical error happens. * If you have errors which aren’t actionable (but you still want to know about them), you could tag them with “low\_priority” and exclude those errors when automatically creating issues via the GitHub integration. * Tag all errors that happen in an area of your app with the name of the team that is responsible for them, then notify their Slack channel for only those errors. These are just examples: you can use tags however you want! While you can always add tags to existing errors through the Honeybadger UI, they are most useful when you add them programmatically as the exceptions happen. There are two ways to add tags to errors from your Ruby app: ## Tagging errors in global context [Section titled “Tagging errors in global context”](#tagging-errors-in-global-context) Every exception which is reported within the current context will have the specified tags added. Use the `tags` key to set the tags: ```ruby # Using a comma-separated string Honeybadger.context({ tags: 'critical, badgers' }) # Or using an array of strings Honeybadger.context({ tags: ['critical', 'badgers'] }) ``` ## Tagging errors in `Honeybadger.notify` [Section titled “Tagging errors in Honeybadger.notify”](#tagging-errors-in-honeybadgernotify) The tags will be added for just the current error being reported: ```ruby # Using a comma-separated string Honeybadger.notify(exception, tags: 'critical, badgers' ) # Or using an array of strings Honeybadger.notify(exception, tags: ['critical', 'badgers'] ) ``` ## Tag processing [Section titled “Tag processing”](#tag-processing) Tags are processed as follows: * Comma-separated strings are split into individual tags * Whitespace is automatically trimmed from each tag * Tags from context and explicit tags are merged and deduplicated * Empty tags are ignored # Tracking deployments > Track deployments from Ruby applications to correlate errors with releases and identify problematic code changes. Honeybadger has an API to keep track of project deployments. Whenever you deploy, all errors for that environment will be resolved automatically. You can choose to enable or disable the auto-resolve feature from your Honeybadger project settings page. ## Deploying with GitHub Actions [Section titled “Deploying with GitHub Actions”](#deploying-with-github-actions) If your CI/CD pipeline is hosted with GitHub Actions, you can use the [Honeybadger Deploy Action](https://github.com/marketplace/actions/honeybadger-deploy-action) to notify our API about deployments. ## Deployment tracking via command line [Section titled “Deployment tracking via command line”](#deployment-tracking-via-command-line) We provide a CLI command to send deployment notifications manually. Try the following command for the available options: ```sh bundle exec honeybadger help deploy ``` Here’s an example of using the CLI to send a deployment notification: ```sh bundle exec honeybadger deploy \ --repository https://github.com/myorganization/myrepo \ --revision $(cat REVISION) \ --environment production \ --user $(whoami) ``` ## Heroku deployment tracking [Section titled “Heroku deployment tracking”](#heroku-deployment-tracking) Deploy tracking via Heroku is implemented using Heroku’s [app webhooks](https://devcenter.heroku.com/articles/app-webhooks). To set up the webhook, run the following CLI command from your project root: ```sh bundle exec honeybadger heroku install_deploy_notification ``` If the honeybadger CLI command fails for whatever reason, you can add the deploy hook manually by running: ```sh heroku webhooks:add -i api:release -l notify -u "https://api.honeybadger.io/v1/deploys/heroku?repository=git@github.com/username/projectname&environment=production&api_key=asdf" --app app-name ``` If you are using our EU stack, you should use `eu-api.honeybadger.io` instead of `api.honeybadger.io` in the webhook URL. For more about manual use of Heroku deploy tracking, see the [Heroku Deployments](/guides/heroku/#heroku-deployment-tracking) guide. You should replace the `repository`, `api_key`, and `app` options with your own values. You may also want to change the environment (set to production by default). ## Kamal deployment tracking [Section titled “Kamal deployment tracking”](#kamal-deployment-tracking) You can use Kamal’s post-deploy hook to send a deployment notification to Honeybadger. Add the following snippet to `.kamal/hooks/post-deploy`: ```bash bundle exec honeybadger deploy \ --repository https://github.com/your_org/your_repo \ --revision $KAMAL_VERSION \ --environment production \ --user $KAMAL_PERFORMER ``` ## Capistrano deployment tracking [Section titled “Capistrano deployment tracking”](#capistrano-deployment-tracking) In order to track deployments using Capistrano, simply require Honeybadger’s Capistrano task in your `Capfile` file: ```ruby require "capistrano/honeybadger" ``` If you ran the `honeybadger install` command in a project that was previously configured with Capistrano, we already added this for you. Adding options to your *config/deploy.rb* file allows you to customize how the deploy task is executed. The syntax for setting them looks like this: ```ruby set :honeybadger_env, "preprod" ``` You can use any of the following options when configuring capistrano. | Option | | | ----------------------------- | -------------------------------------------------------------------------------------------------------------------------------------------------- | | `honeybadger_user` | Honeybadger will report the name of the local user who is deploying (using `whoami` or equivalent). Use this option to to report a different user. | | `honeybadger_env` | Honeybadger reports the environment supplied by capistrano by default. Use this option to change the reported environment. | | `honeybadger_api_key` | Honeybadger uses your configured API key by default. Use this option to override. | | `honeybadger_async_notify` | Run deploy notification task asynchronously using `nohup`. True or False. Defaults to false. | | `honeybadger_server` | The api endpoint that receives the deployment notification. | | `honeybadger` | The name of the honeybadger executable. Default: “honeybadger” | | `honeybadger_skip_rails_load` | Skip loading the Rails environment during deploy notification. | ## Ruby deployment tracking [Section titled “Ruby deployment tracking”](#ruby-deployment-tracking) You can also track a deployment from the *honeybadger* Ruby gem with `Honeybadger.track_deployment`: ```ruby Honeybadger.track_deployment( environment: Rails.env, revision: `git rev-parse HEAD`.strip, local_username: `whoami`.strip, repository: "git@github.com:user/example.git" ) ``` # Honeybadger CLI reference > Command-line interface reference for Honeybadger's Ruby gem with deployment tracking and testing commands. The Honeybadger CLI provides a Command Line Interface for various Honeybadger-related programs and utilities. All features are available through the `honeybadger` command and can be used independently of Bundler/Rails. When using the *honeybadger* gem with Bundler, run `bundle exec honeybadger`. To use outside of bundler, install the Honeybadger gem with `gem install honeybadger` and then run `honeybadger`. ## Commands [Section titled “Commands”](#commands) The following commands are available through the `honeybadger` CLI: | Command | Description | | --------------------- | -------------------------------------------------------------------------------- | | `honeybadger deploy` | Notify Honeybadger of deployment | | `honeybadger exec` | Execute a command. If the exit status is not 0, report the result to Honeybadger | | `honeybadger help` | Describe available commands or one specific command | | `honeybadger heroku` | Manage Honeybadger on Heroku | | `honeybadger install` | Install Honeybadger into a new project | | `honeybadger notify` | Notify Honeybadger of an error | | `honeybadger test` | Send a test notification from Honeybadger | For additional info about each command, run `honeybadger help`. ## Configuration [Section titled “Configuration”](#configuration) The `honeybadger` command optionally reads configuration from the following locations. Each location in the list takes precedence over the previous location: 1. \~/honeybadger.yml 2. ./config/honeybadger.yml 3. ./honeybadger.yml 4. Rails/Ruby configuration (only when called from a Rails app root) 5. Environment variables 6. Command-line flags (i.e. `--api-key`) The following configuration options are used by the CLI when applicable: `api_key`, `env`. See [Configuration Options](/lib/ruby/gem-reference/configuration/#configuration-options) All other options must be passed as command-line flags. ### Rails initialization [Section titled “Rails initialization”](#rails-initialization) When run from the root of a Rails project, the `honeybadger` command will load the Rails environment so that any framework/programmatic configuration is picked up. # Configuration > Complete configuration reference for Honeybadger's Ruby gem with all available options and settings. There are a few ways to configure the Honeybadger gem. You can use a YAML config file. You can use environment variables. You can use Ruby. Or you can use a combination of the three. We put together a short video highligting a few of the most common configuration options: [![Advanced Honeybadger Gem Usage](https://embed-ssl.wistia.com/deliveries/5fccf29d2b27d0f7ec62b5b39e2f5d9cd1f6f5b7.jpg?image_play_button=true\&image_play_button_color=7b796ae0\&image_crop_resized=150x84)](https://honeybadger.wistia.com/medias/vv9qq9x39d) ## YAML configuration file [Section titled “YAML configuration file”](#yaml-configuration-file) By default, Honeybadger looks for a `honeybadger.yml` configuration file in the root of your project, and then `config/honeybadger.yml` (in that order). Here’s what the simplest config file looks like: ```yaml --- api_key: "PROJECT_API_KEY" ``` ### Nested options [Section titled “Nested options”](#nested-options) Some configuration options are written in YAML as nested hashes. For example, here’s what the `logging.path` and `request.filter_keys` options look like in YAML: ```yaml --- logging: path: "/path/to/honeybadger.log" request: filter_keys: - "credit_card" ``` ### Environments [Section titled “Environments”](#environments) Environment-specific options can be set by name-spacing the options beneath the environment name. For example: ```yaml --- api_key: "PROJECT_API_KEY" production: logging: path: "/path/to/honeybadger.log" level: "WARN" ``` ### ERB and Regex [Section titled “ERB and Regex”](#erb-and-regex) The configuration file is rendered using ERB. That means you can set configuration options programmatically. You can also include regular expressions. Here’s what that looks like: ```yaml --- api_key: "PROJECT_API_KEY" request: filter_keys: - !ruby/regexp "/credit_card/i" ``` ## Configuring with environment variables (12-factor style) [Section titled “Configuring with environment variables (12-factor style)”](#configuring-with-environment-variables-12-factor-style) All configuration options can also be read from environment variables (ENV). To do this, uppercase the option name, replace all non-alphanumeric characters with underscores, and prefix with `HONEYBADGER_`. For example, `logging.path` becomes `HONEYBADGER_LOGGING_PATH`: ```plaintext export HONEYBADGER_LOGGING_PATH=/path/to/honeybadger.log ``` ENV options override other options read from framework or `honeybadger.yml` sources, so both can be used together. For example, if the `HONEYBADGER_ENV` environment variable is present, it will override the `env` configuration option and `RAILS_ENV` environment variable. ## Configuration via Ruby (programmatic) [Section titled “Configuration via Ruby (programmatic)”](#configuration-via-ruby-programmatic) To configure Honeybadger from Ruby, use `Honeybadger.configure`: ```ruby # i.e. config/initializers/honeybadger.rb Honeybadger.configure do |config| config.api_key = "PROJECT_API_KEY" config.exceptions.ignore += [CustomError] end ``` Note that configuration via Ruby means that until your configuration code is run, Honeybadger will use its default configuration (or the YAML file or environment variables), so for the best experience, this should be as early as possible after startup. There are also a few special features which can only be configured via Ruby: ### Changing notice data [Section titled “Changing notice data”](#changing-notice-data) Use `before_notify` callbacks to modify [notice data](https://www.rubydoc.info/gems/honeybadger/Honeybadger/Notice) before it’s sent to Honeybadger: ```ruby Honeybadger.configure do |config| config.before_notify do |notice| # Use your own error grouping notice.fingerprint = App.exception_fingerprint(notice) # Ignore notices with sensitive data notice.halt! if notice.error_message =~ /sensitive data/ # Avoid using all your quota for non-production errors by allowing # only 10 errors to be sent per minute notice.halt! if !Rails.env.production? && Redis.current.incr(key = "honeybadger_errors:#{(Time.now - Time.now.sec).to_i}") > 10 Redis.current.expire(key, 120) end end ``` `before_notify` can be called multiple times to add multiple callbacks. ### Changing event data [Section titled “Changing event data”](#changing-event-data) Use `before_event` callbacks to modify [event data](https://www.rubydoc.info/gems/honeybadger/Honeybadger/Event) before it’s sent to Honeybadger: ```ruby Honeybadger.configure do |config| config.before_event do |event| # DB-backed job backends can generate a lot of noisy queries if event.event_type == "sql.active_record" && event[:query]&.match?(/good_job|solid_queue/) event.halt! end # Truncate long queries if event.event_type == "sql.active_record" && event[:query].present? event[:query] = event[:query].first(256) end # Set some data for each event if environment = ENV["HONEYBADGER_ENV"] || Rails.env event[:environment] = environment end # See https://api.rubyonrails.org/classes/ActiveSupport/CurrentAttributes.html for more info about using Current event[:user] = { id: Current.user.id, email: Current.user.email } if Current.user # Avoid using all your quota for non-production events by allowing # only 10 events to be sent per minute event.halt! if !Rails.env.production? && Redis.current.incr(key = "honeybadger_event:#{(Time.now - Time.now.sec).to_i}") > 10 Redis.current.expire(key, 120) end end ``` `before_event` can be called multiple times to add multiple callbacks. ### Using a custom `logger` [Section titled “Using a custom logger”](#using-a-custom-logger) While you can configure the default logger using the provided options, it’s also possible to replace the logger entirely: ```ruby Honeybadger.configure do |config| config.logger = MyLogger.new('/path/to/honeybadger.log') end ``` ### Using a custom `backend` [Section titled “Using a custom backend”](#using-a-custom-backend) This option allows you to change the backend which handles all reported data. This is an advanced option—you’ll need to [read the code](https://github.com/honeybadger-io/honeybadger-ruby/tree/master/lib/honeybadger/backend) to use it: ```ruby Honeybadger.configure do |config| config.backend = CustomBackend.new end ``` ## Configuration options [Section titled “Configuration options”](#configuration-options) You can use any of the options below in your config file, or in the environment. | Option | Type | Description | | --------------------------------------------------- | ------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | | `api_key` | String | The API key for your Honeybadger project. *Default: `nil`* | | `env` | String | The environment the app is running in. In Rails this defaults to `Rails.env`. *Default: `nil`* | | `report_data` | Boolean | Enable/disable reporting of data. Defaults to false for “test”, “development”, and “cucumber” environments. *Default: `true`* | | `root` | String | The project’s absolute root path. *Default: `Dir.pwd`* | | `revision` | String | The project’s git revision. *Default: revision detected from git* | | `hostname` | String | The hostname of the current box. *Default: `Socket.gethostname`* | | `backend` | String | An alternate backend to use for reporting data. *Default: `nil`* | | `debug` | Boolean | Enables verbose debug logging. *Default: `false`* | | `send_data_at_exit` | Boolean | Prevent the Ruby program from exiting until all queued notices have been delivered to Honeybadger. (This can take a while in some cases; see `max_queue_size`.) *Default: `true`* | | `max_queue_size` | Integer | Maximum number of notices to queue for delivery at one time; new notices will be dropped if this number is exceeded. *Default: `100`* | | `config_path` | String | The path of the honeybadger config file. Can only be set via the `$HONEYBADGER_CONFIG_PATH` environment variable | | `development_environments` | Array | Environments which will not report data by default (use report*data to enable/disable explicitly). \_Default: `["development", "test", "cucumber"]`* | | `plugins` | Array | An optional list of plugins to load. Default is to load all plugins. *Default: `[]`* | | `skipped_plugins` | Array | An optional list of plugins to skip. *Default: `[]`* | |   | | | | **INSIGHTS AND EVENTS** | | | | `insights.enabled` | Boolean | Enable automatic Insights instrumentation. *Default: `true` (version >= 6)* | | `insights.registry_flush_interval` | Integer | Number of seconds to flush the aggregated metrics registry. Set a higher number for greater resolution but use more data. *Default: `60`* | | `insights.console.enabled` | Boolean | Enable Insights instrumentation in a Rails console. *Default: `false`* | | `events.max_queue_size` | Integer | Number of events before the event queue will start dropping events. *Default: `100000`* | | `events.batch_size` | Integer | Number of events to batch that will trigger the gem to send. *Default: `1000`* | | `events.timeout` | Integer | Number of milliseconds before the event queue will send events regardless of size. *Default: `30000`* | | `events.attach_hostname` | Boolean | Attach server hostname to every event sent by the gem. *Default: `true`* | | `events.attach_environment` | Boolean | Attach the configured environment name to every event sent by the gem (including metrics). *Default: `true`* | | `events.ignore` | Array | An list of rules to match against events to be ignored. See [Ignoring Events](/lib/ruby/insights/filtering-events/) for more information. | | `events.ignore_only` | Array | A list of events to ignore (overrides the default ignored events). *Default: `nil`* | | `events.sample_rate` | Integer | Percentage of events to send. See [Sampling Events](/lib/ruby/insights/sampling-events/) for more information. | |   | | | | **LOGGING** | | | | `logging.path` | String | The path (absolute, or relative from config.root) to the log file. Defaults to the rails logger or STDOUT. To log to standard out, use ‘STDOUT’. *Default: `nil`* | | `logging.level` | String | The log level. Does nothing unless `logging.path` is also set. *Default: `INFO`* | | `logging.tty_level` | String | Level to log when attached to a terminal (anything < `logging.level` will always be ignored). *Default: `DEBUG`* | | `logging.debug` | Boolean | Override debug logging for the logging subsystem. *Default: `nil`* | |   | | | | **HTTP CONNECTION** | | | | `connection.secure` | Boolean | Use SSL when sending data. *Default: `true`* | | `connection.host` | String | The host to use when sending data. *Default: `api.honeybadger.io`* | | `connection.port` | Integer | The port to use when sending data. *Default: `443`* | | `connection.http_open_timeout` | Integer | The HTTP open timeout when connecting to the server. *Default: `2`* | | `connection.http_read_timeout` | Integer | The HTTP read timeout when connecting to the server. *Default: `5`* | | `connection.proxy_host` | String | The proxy host to use when sending data. *Default: `nil`* | | `connection.proxy_port` | Integer | The proxy port to use when sending data. *Default: `nil`* | | `connection.proxy_user` | String | The proxy user to use when sending data. *Default: `nil`* | | `connection.proxy_pass` | String | The proxy password to use when sending data. *Default: `nil`* | | `connection.ui_host` | String | The host to use when viewing data. *Default: `app.honeybadger.io`* | | `connection.ssl_ca_bundle_path` | String | Use this CA bundle when establishing secure connections. *Default: `nil`* | | `connection.system_ssl_cert_chain` | Boolean | Use the system’s SSL certificate chain (if available). *Default: `false`* | |   | | | | **REQUEST DATA FILTERING** | | | | `request.filter_keys` | Array | A list of keys to filter when sending request data. In Rails, this also includes existing params filters. *Default: `['password', 'password_confirmation']`* | | `request.disable_session` | Boolean | Prevent session from being sent with request data. *Default: `false`* | | `request.disable_params` | Boolean | Prevent params from being sent with request data. *Default: `false`* | | `request.disable_environment` | Boolean | Prevent Rack environment from being sent with request data. *Default: `false`* | | `request.disable_url` | Boolean | Prevent url from being sent with request data (Rack environment may still contain it in some cases). *Default: `false`* | |   | | | | **USER INFORMER** | | | | `user_informer.enabled` | Boolean | Enable the UserInformer middleware. The user informer displays information about a Honeybadger error to your end-users when you display a 500 error page. This typically includes the error id which can be used to reference the error inside your Honeybadger account. [Learn More](/lib/ruby/errors/collecting-user-feedback/) *Default: `true`* | | `user_informer.info` | String | Replacement string for HTML comment in templates. *Default: `'Honeybadger Error {{error_id}}'`* | |   | | | | **USER FEEDBACK** | | | | `feedback.enabled` | Boolean | Enable the UserFeedback middleware. Feedback displays a comment form to your-end user when they encounter an error. When the user creates a comment, it is added to the error in Honeybadger, and a notification is sent. [Learn More](/lib/ruby/errors/collecting-user-feedback/) *Default: `true`* | |   | | | | **EXCEPTION REPORTING** | | | | `exceptions.enabled` | Boolean | Enable error reporting functionality. *Default: `true`* | | `exceptions.ignore` | Array | A list of exception class names to ignore (appends to defaults). *Default: `['ActionController::RoutingError', 'AbstractController::ActionNotFound', 'ActionController::MethodNotAllowed', 'ActionController::UnknownHttpMethod', 'ActionController::NotImplemented', 'ActionController::UnknownFormat', 'ActionController::InvalidAuthenticityToken', 'ActionController::InvalidCrossOriginRequest', 'ActionDispatch::ParamsParser::ParseError', 'ActionController::BadRequest', 'ActionController::ParameterMissing', 'ActiveRecord::RecordNotFound', 'ActionController::UnknownAction', 'CGI::Session::CookieStore::TamperedWithCookie', 'Mongoid::Errors::DocumentNotFound', 'Sinatra::NotFound']`* | | `exceptions.ignore_only` | Array | A list of exception class names to ignore (overrides defaults). *Default: `[]`* | | `exceptions.ignored_user_agents` | Array | A list of user agents to ignore. *Default: `[]`* | | `exceptions.rescue_rake` | Boolean | Enable rescuing exceptions in rake tasks. *Default: `true` when run in background; `false` when run in terminal.* | | `exceptions.notify_at_exit` | Boolean | Report unhandled exception when Ruby crashes (at*exit). \_Default: `true`.* | | `exceptions.source_radius` | Integer | The number of lines before and after the source when reporting snippets. *Default: `2`* | | `exceptions.local_variables` | Boolean | Enable sending local variables. Requires the [binding\_of\_caller gem](https://rubygems.org/gems/binding_of_caller). *Default: `false`* | | `exceptions.unwrap` | Boolean | Reports #original*exception or #cause one level up from rescued exception when available. \_Default: `false`* | |   | | | | **BREADCRUMBS** | | | | `breadcrumbs.enabled` | Boolean | Enable breadcrumb functionality. *Default: `true`* | | `breadcrumbs.active_support_notifications` | Hash | Configuration for automatic Active Support Instrumentation events. *Default: `Breadcrumbs::ActiveSupport.default_notifications`* | | `breadcrumbs.logging.enabled` | Boolean | Enable/Disable automatic breadcrumbs from log messages. *Default: `true`* | | **ACTIVE JOB** | | | | `active_job.attempt_threshold` | Integer | The number of attempts before notifications will be sent. *Default: `0`* | | `active_job.insights.enabled` | Boolean | Enable automatic Insights instrumentation for this plugin. *Default: `true`* | | `active_job.insights.events` | Boolean | Enable sending Active Job events to Insights. *Default: `true`* | | `active_job.insights.metrics` | Boolean | Enable sending Active Job metrics to Insights. *Default: `false`* | | **SIDEKIQ** | | | | `sidekiq.attempt_threshold` | Integer | The number of attempts before notifications will be sent. *Default: `0`* | | `sidekiq.use_component` | Boolean | Automatically set the component to the class of the job. Helps with grouping. *Default: `true`* | | `sidekiq.insights.enabled` | Boolean | Enable automatic Insights instrumentation for Sidekiq. *Default: `true`* | | `sidekiq.insights.collection_interval` | Integer | The frequency, in seconds, in which Sidekiq metrics are sampled. *Default: `60`* | | `sidekiq.insights.cluster_collection` | Boolean | Enable cluster wide metric collection. If you are using Sidekiq Enterprise, this is configured automatically. *Default: `true`* | | `sidekiq.insights.events` | Boolean | Enable sending Sidekiq events to Insights. *Default: `true`* | | `sidekiq.insights.metrics` | Boolean | Enable sending Sidekiq metrics to Insights. *Default: `false`* | | **SOLID\_QUEUE** | | | | `solid_queue.insights.enabled` | Boolean | Enable automatic Insights instrumentation for SolidQueue. *Default: `true`* | | `solid_queue.insights.collection_interval` | Integer | The frequency, in seconds, in which SolidQueue metrics are sampled. *Default: `60`* | | `solid_queue.insights.cluster_collection` | Boolean | Enable cluster wide metric collection. *Default: `true`* | | `solid_queue.insights.events` | Boolean | Enable sending SolidQueue events to Insights. *Default: `true`* | | `solid_queue.insights.metrics` | Boolean | Enable sending SolidQueue metrics to Insights. *Default: `false`* | | **DELAYED JOB** | | | | `delayed_job.attempt_threshold` | Integer | The number of attempts before notifications will be sent. *Default: `0`* | | **SHORYUKEN** | | | | `shoryuken.attempt_threshold` | Integer | The number of attempts before notifications will be sent. *Default: `0`* | | **FAKTORY** | | | | `faktory.attempt_threshold` | Integer | The number of attempts before notifications will be sent. *Default: `0`* | | **RESQUE** | | | | `resque.resque_retry.send_exceptions_when_retrying` | Boolean | Send exceptions when retrying a job. *Default: `true`* | | **SINATRA** | | | | `sinatra.enabled` | Boolean | Enable Sinatra auto-initialization. *Default: `true`* | | **RAILS** | | | | `rails.subscriber_ignore_sources` | Array | `source`s (strings or regexes) that should be ignored when using the Rails error reporter. *Default: `[]`* | | `rails.insights.enabled` | Boolean | Enable automatic Insights instrumentation for Rails. *Default: `true`* | | `rails.insights.events` | Boolean | Enable sending Rails events to Insights. *Default: `true`* | | `rails.insights.metrics` | Boolean | Enable sending Rails metrics to Insights. *Default: `false`* | | **Autotuner** | | | | `autotuner.insights.enabled` | Boolean | Enable automatic Insights data collection for Autotuner. *Default: `true`* | | `autotuner.insights.events` | Boolean | Enable sending Autotuner events to Insights. *Default: `true`* | | `autotuner.insights.metrics` | Boolean | Enable sending Autotuner metrics to Insights. *Default: `false`* | | **Karafka** | | | | `karafka.insights.enabled` | Boolean | Enable automatic Insights instrumentation for Karafka. *Default: `true`* | | `karafka.insights.events` | Boolean | Enable sending Karafka events to Insights. *Default: `true`* | | `karafka.insights.metrics` | Boolean | Enable sending Karafka metrics to Insights. *Default: `false`* | | **Net::HTTP** | | | | `net_http.insights.enabled` | Boolean | Enable automatic Insights instrumentation for `Net::HTTP`. *Default: `true`* | | `net_http.insights.full_url` | Boolean | Log the request URL instead of just the domain. *Default: `false`* | | `net_http.insights.events` | Boolean | Enable sending Net::HTTP events to Insights. *Default: `true`* | | `net_http.insights.metrics` | Boolean | Enable sending Net::HTTP metrics to Insights. *Default: `false`* | | **PUMA** | | | | `puma.insights.enabled` | Boolean | Enable automatic Insights instrumentation for Puma. *Default: `true`* | | `puma.insights.events` | Boolean | Enable sending Puma events to Insights. *Default: `true`* | | `puma.insights.metrics` | Boolean | Enable sending Puma metrics to Insights. *Default: `false`* | | `puma.insights.collection_interval` | Integer | The frequency, in seconds, in which Puma stats are sampled. *Default: `1`* | | **ACTIVE AGENT** | | | | `active_agent.insights.enabled` | Boolean | Enable automatic Insights instrumentation for Active Agent. *Default: `true`* | | **FLIPPER** | | | | `flipper.insights.enabled` | Boolean | Enable automatic Insights instrumentation for Flipper. *Default: `true`* | # Integration guide > Learn how to integrate Honeybadger's Ruby gem with custom frameworks and applications. This guide will teach you how to integrate your gem, framework, or other Ruby project with the [*honeybadger* Ruby gem](https://github.com/honeybadger-io/honeybadger-ruby). ## Who is this guide for? [Section titled “Who is this guide for?”](#who-is-this-guide-for) This guide is for anyone who is interested in extending the capability of the Honeybadger gem in order to share their integration with the Honeybadger community. In addition to covering *how* to create your integration, you’ll learn two ways to package and distribute it: 1. Submit a pull-request (PR) to the official Honeybadger gem 2. Publish your integration as a new gem that you maintain ## What can I build? [Section titled “What can I build?”](#what-can-i-build) Honeybadger’s plugin system integrates with popular gems (and even Ruby itself) in order to report exceptions with rich contextual information. Here are some examples of plugins which have been created so far: * [Report exceptions in Sidekiq jobs](https://github.com/honeybadger-io/honeybadger-ruby/blob/master/lib/honeybadger/plugins/sidekiq.rb), including the job parameters and configuration data * [Automatically associate errors with users](https://github.com/honeybadger-io/honeybadger-ruby/blob/master/lib/honeybadger/plugins/warden.rb) for any application which uses a Warden-based authentication system (such as Devise) * Hook into Ruby’s exception system in order to [report Local Variables for all Ruby exceptions](https://github.com/honeybadger-io/honeybadger-ruby/blob/master/lib/honeybadger/plugins/local_variables.rb) ## Getting started [Section titled “Getting started”](#getting-started) The Honeybadger gem has a [plugin system](https://github.com/honeybadger-io/honeybadger-ruby/blob/master/lib/honeybadger/plugin.rb) which allows you to step into our initialization process. From there, you can use the full power of Ruby to integrate with Honeybadger in interesting ways. Honeybadger’s plugin API is simple—there are only a few methods you need to learn. To give you an idea of what this looks like, let’s build a simple plugin. ## Building your plugin [Section titled “Building your plugin”](#building-your-plugin) Imagine you’re using a framework which provides the following API for handling exceptions: ```ruby MyFramework.on_exception do |exception| # Exception handling code (report the exception, log it, etc.) end ``` This is a fairly common pattern; for instance, [SuckerPunch has a similar API](https://github.com/honeybadger-io/honeybadger-ruby/blob/master/lib/honeybadger/plugins/sucker_punch.rb#L10). Here’s a Honeybadger plugin which checks to see if `MyFramework` is available. If it is, it installs an exception handler which reports all exceptions to Honeybadger: ```ruby require 'honeybadger/plugin' require 'honeybadger/ruby' module Honeybadger module Plugins # Register your plugin with an optional name. If the name (such as # "my_framework") is not provided, Honeybadger will try to infer the name # from the current file. Plugin.register 'my_framework' do requirement do # Check to see if the thing you're integrating with is loaded. Return true # if it is, or false if it isn't. An exception in this block is equivalent # to returning false. Multiple requirement blocks are supported. defined?(MyFramework) end execution do # Write your integration. This code will be executed only if all requirement # blocks return true. An exception in this block will disable the plugin. # Multiple execution blocks are supported. MyFramework.on_exception do |exception| Honeybadger.notify(exception) end end end end end ``` There are three steps which Honeybadger performs when loading your plugin: 1. `Honeybadger::Plugin.register` registers the plugin with Honeybadger. 2. When initializing an application, Honeybadger will attempt to load your plugin, executing every `requirement` block you gave it. 3. If all `requirement` blocks returned `true`, then Honeybadger executes each `execution` block in turn. ### A simple Sidekiq plugin [Section titled “A simple Sidekiq plugin”](#a-simple-sidekiq-plugin) [Sidekiq](https://sidekiq.org/) is a good example of a framework which integrates nicely with Honeybadger, providing a lot of rich contextual data with each exception. *Note: Keep in mind that [we already support Sidekiq natively](https://github.com/honeybadger-io/honeybadger-ruby/blob/master/lib/honeybadger/plugins/sidekiq.rb), so don’t try to actually run this example in a Honeybadger project, or you may get multiple exception reports. :)* lib/honeybadger/plugins/sidekiq.rb ```ruby require 'honeybadger/plugin' require 'honeybadger/ruby' module Honeybadger module Plugins # It's best practice to create your own Honeybadger::Plugins::YourFramework # namespace, if you need to create additional classes to use when executing # your plugin. module Sidekiq class Middleware def call(worker, msg, queue) Honeybadger.context.clear! yield end end Plugin.register do requirement { defined?(::Sidekiq) } execution do ::Sidekiq.configure_server do |sidekiq| sidekiq.server_middleware do |chain| chain.prepend Middleware end sidekiq.error_handlers << lambda {|ex, params| job = params[:job] Honeybadger.notify(ex, parameters: params, component: job['wrapped'] || job['class'] ) } end end end end end end ``` ## Sharing your plugin [Section titled “Sharing your plugin”](#sharing-your-plugin) Once you’ve built your plugin, it’s time to share it with other ‘badgers like you, for fame and glory (or at least a high-five). There are two good ways to share a plugin: 1. Submit a PR to the Honeybadger gem 2. Publish your own Ruby gem, such as “honeybadger-plugins-sidekiq” We’d love to help you decide which of these is the best way to go. We’re very open to including a wide variety of plugins in the official Honeybadger gem, so that everyone can enjoy them by default. Head over to GitHub and [tell us about your plugin by creating a new issue](https://github.com/honeybadger-io/honeybadger-ruby/issues/new). Here’s an example issue (this is just how I’d write it—you don’t need to include a link to your plugin if you haven’t finished it yet, or it isn’t on GitHub). > Hey ‘badgers! > > I use Sidekiq a lot in my daily work, and since there is no existing Honeybadger integration, I decided to make one. Would you be interested in including Sidekiq as a default plugin? > > Here’s a link to Sidekiq: > > > > Here’s a link to my plugin: > > > > Thanks! We’ll get back to you as soon as possible. If we decide that your plugin is something that would benefit everyone, we’ll ask you to submit a PR (if you aren’t sure how to do this, don’t worry—read on for instructions, and feel free to ask us for help! If we decided against a PR for some reason, you can publish your plugin as a gem, which is another great way to share it with the community. ### Submitting a PR [Section titled “Submitting a PR”](#submitting-a-pr) To submit a PR, you’ll need a few things: 1. A [GitHub account](https://github.com/) 2. [Git](https://help.github.com/articles/set-up-git/) and a [supported Ruby version](../supported-versions/) installed on your computer 3. A fork of the [honeybadger gem](https://github.com/honeybadger-io/honeybadger-ruby) repository After creating a fork (go to the [honeybadger-ruby repository](https://github.com/honeybadger-io/honeybadger-ruby) and use the **Fork** button, top-right of the page), run the following commands to set up your local copy of the gem: ```sh git clone https://github.com/your-username/honeybadger-ruby.git cd honeybadger-ruby bundle install ``` To make sure everything is set up correctly, try running the unit tests: ```plaintext bundle exec rake spec:units ``` You should see something like this: ```plaintext All examples were filtered out; ignoring {:focus=>true} Randomized with seed 14664 ................................................................................................................................................................................................................................................................................................................................................................................................................................................................................................................................ Finished in 0.97639 seconds (files took 0.57739 seconds to load) 512 examples, 0 failures ``` Assuming the tests ran, you should be ready to add your plugin code. 1. Create a file in [*lib/honeybadger/plugins/*](https://github.com/honeybadger-io/honeybadger-ruby/tree/master/lib/honeybadger/plugins). The file name should use [snake\_case](https://en.wikipedia.org/wiki/Snake_case), and have a Ruby (`.rb`) file extension. If your plugin integrates with “MyFramework”, then the file path should be *lib/honeybadger/plugins/my\_framework.rb*. 2. Add your plugin code to the file you created. 3. A good PR should include tests. We use [RSpec](http://rspec.info/) for our test suite. For an example of a simple RSpec plugin test, [check out the tests for the SuckerPunch plugin](https://github.com/honeybadger-io/honeybadger-ruby/blob/master/spec/unit/honeybadger/plugins/sucker_punch_spec.rb). Use `bundle exec rake spec:units` to run the tests while developing your plugin. After adding some tests and/or verifying that your plugin doesn’t cause issues with Honeybadger, you’re ready to submit your plugin: 1. Add an entry to [CHANGELOG.md](https://github.com/honeybadger-io/honeybadger-ruby/blob/master/CHANGELOG.md): ```plaintext ## [Unreleased] ### Added - Added a plugin for MyFramework ``` See [Keep a Changelog](http://keepachangelog.com/) for more info on the format of the changelog. 2. Commit your changes: ```sh git add . git commit --message "Add a MyFramework plugin." ``` 3. Push your changes: ```sh git push origin master ``` Now that your fork has the changes you want to add, create a pull request to the [honeybadger-io/honeybadger-ruby repository](https://github.com/honeybadger-io/honeybadger-ruby/pulls) on GitHub. If you’re not sure how to create a pull request, [check out GitHub’s guide](https://help.github.com/articles/creating-a-pull-request-from-a-fork/), and feel free to ask us for help! ### Publishing your own gem [Section titled “Publishing your own gem”](#publishing-your-own-gem) Before publishing your own gem, read through [the official RubyGems guide](https://guides.rubygems.org/publishing/). Here are some basic steps to create a gem and publish it to [RubyGems.org](https://rubygems.org/). If you get stuck, feel free to ask us for help! *Fun fact: did you know that Ruby Central uses Honeybadger to monitor RubyGems.org for exceptions?* #### Creating the gem [Section titled “Creating the gem”](#creating-the-gem) Bundler has a handy tool that will create a simple gem for you. 1. Make sure you have the `bundler` gem installed: ```sh gem install bundler ``` 2. Create a new gem using the `bundle gem` command. You should name your gem “honeybadger-plugins-\[name of your plugin]”. For example, if your plugin integrates with MyFramework, name your project: “honeybadger-my\_framework”: ```sh bundle gem honeybadger-plugins-my_framework ``` Follow the prompts to add tests (we use RSpec), create a license (we like MIT), and add a code of conduct for your gem. 3. Once your gem is created, check out the directory structure, and read the README: ```sh cd honeybadger-my_framework ls -l cat README.md ``` 4. Lastly, run the `bundle install` command: ```sh bundle install ``` It will fail the first time, asking you to edit the *honeybadger-plugins-my\_framework.gemspec* file. Make the requested edits and then re-run `bundle install` until it completes successfully. *Note: If you added a test framework, run the new test suite with `bundle exec rake`.* #### Adding your code [Section titled “Adding your code”](#adding-your-code) 1. Add your plugin code to *lib/honeybadger/plugins/my\_framework.rb*, which should have been created by the `bundle gem` command. 2. If you chose to add a test framework when creating your gem, add some tests. 3. After you verify that your plugin works, commit your changes: ```sh git add . git commit --message "Add a MyFramework plugin." ``` #### Pushing to RubyGems.org [Section titled “Pushing to RubyGems.org”](#pushing-to-rubygemsorg) To publish your first version (0.1.0) to [RubyGems.org](https://rubygems.org/): ```sh gem build honeybadger-plugins-my_framework.gemspec gem push honeybadger-plugins-my_framework-0.1.0.gem ``` You can view your new gem at the following URL: # Supported versions > View supported Ruby and Rails versions and compatibility requirements for Honeybadger's Ruby gem. The support tables below are for the latest version of the Honeybadger gem, which aims to support all maintained (non-EOL) versions of Ruby and supported frameworks. If you’re using an older version of Ruby or your framework, you may need to install an older version of the gem. ## Supported Ruby versions [Section titled “Supported Ruby versions”](#supported-ruby-versions) | Ruby Interpreter | Supported Version | | ---------------- | ----------------- | | MRI | >= 2.7.0 | | JRuby | >= 9.2 | ## Supported web frameworks [Section titled “Supported web frameworks”](#supported-web-frameworks) | Framework | Version | Native? | | ------------------------------------------------------------------- | -------- | ---------- | | [Rails](/lib/ruby/integration-guides/rails-exception-tracking/) | >= 5.2 | yes | | [Sinatra](/lib/ruby/integration-guides/sinatra-exception-tracking/) | >= 1.2.1 | yes | | [Rack](/lib/ruby/integration-guides/rack-exception-tracking/) | >= 1.0 | middleware | Rails and Sinatra are supported natively (install/configure the gem and you’re done). For vanilla Rack apps, we provide a collection of middleware that must be installed manually. To use Rails 2.x, you’ll need to use an earlier version of the Honeybadger gem. [Go to version 1.x of the gem docs](https://github.com/honeybadger-io/honeybadger-ruby/blob/1.16-stable/docs/index.md). ## Supported job queues [Section titled “Supported job queues”](#supported-job-queues) | Library | Version | Native? | | ------------ | ------- | ------- | | Active Job | any | yes | | Delayed Job | any | yes | | Resque | any | yes | | Sidekiq | any | yes | | Shoryuken | any | yes | | Sucker Punch | any | yes | For other job queues, you can manually call [`Honeybadger.notify`](https://docs.honeybadger.io/lib/ruby/errors/reporting-errors/) in your error handler. For instance, if you’re using GoodJob: ```ruby config.good_job.on_thread_error = do |ex| Honeybadger.notify(ex) end ``` ## Other integrations [Section titled “Other integrations”](#other-integrations) | Library | Version | Native? | Description | | ------------- | ------- | ------- | -------------------------------------------------------------- | | Devise/Warden | any | yes | Exceptions are automatically associated with the current user. | | Thor | any | yes | Exceptions in commands are automatically reported. | You can also [integrate Honeybadger into any Ruby script](/lib/ruby/integration-guides/ruby-exception-tracking/) using `Honeybadger.notify`. See the [API reference](https://www.rubydoc.info/gems/honeybadger/Honeybadger/Agent) for a full list of methods available. # Honeybadger on the command line > Use Honeybadger's command-line tools for Ruby applications to test your integration, track deployments, and more. The *honeybadger* gem includes a Command Line Interface (CLI) that can be used for a variety of activities from installing Honeybadger in a new project to reporting failed cron jobs. For a full overview of the CLI and the commands it provides, see the [CLI reference](/lib/ruby/gem-reference/cli/). In this chapter we’re going to discuss some of the interesting ways to use the CLI in your Ruby project. ## Cron/command line monitoring [Section titled “Cron/command line monitoring”](#croncommand-line-monitoring) `honeybadger exec` can be used from the command line/terminal to monitor failed commands. To use it, prefix any normal command with `honeybadger exec` (much like `bundle exec`): ```sh honeybadger exec my-command --my-flag ``` If the command executes successfully, honeybadger exits with code 0. It prints any output from the command by default. To use with cron’s automatic email feature, use the `--quiet` flag, which will suppress all standard output from the origin command unless the command fails *and* the Honeybadger notification fails, in which case it will dump the output so that cron can send a backup email notification. To learn more, run `honeybadger help exec`. ## Notify from the command line [Section titled “Notify from the command line”](#notify-from-the-command-line) To send a Honeybadger notification from the command line/terminal, use `honeybadger notify`: ```sh honeybadger notify --message "This is an error from the command line" ``` To learn more, run `honeybadger help notify`. # Introduction > Get started with Honeybadger's Ruby gem for error tracking and application monitoring in Ruby and Rails applications. In this chapter we’re going to cover [the basics of installing the *honeybadger* gem](#installing-the-gem) and [how configuration works](#how-configuration-works). For full instructions and best practices for your framework or platform, see the **Integration guides**. ## Installing the gem [Section titled “Installing the gem”](#installing-the-gem) The first step is to add the honeybadger gem to your Gemfile: ```ruby gem 'honeybadger' ``` Tell bundler to install: ```bash bundle install ``` Next, you'll set the API key for this project. ```bash bundle exec honeybadger install [Your project API key] ``` This will do three things: 1. Generate a `honeybadger.yml` file. If you don't like config files, you can place your API key in the `$HONEYBADGER_API_KEY` environment variable. 2. If Capistrano is installed, we'll add a require statement to *Capfile*. 3. Send a test exception to your Honeybadger project. ## How configuration works [Section titled “How configuration works”](#how-configuration-works) Honeybadger’s configuration consists of named options. Some are top level options such as `api_key`, while others have nested namespaces (separated with a dot) such as `exceptions.ignore`. The only *required* option is `api_key`. There are three ways to configure options for the Honeybadger gem: 1. *honeybadger.yml* configuration file 2. Environment variables 3. Programmatically using `Honeybadger.configure` By default we use the *honeybadger.yml* file, so that’s what most of the examples will use in this guide, but the method you use is a matter of preference. Here’s an example *honeybadger.yml* file: ```yaml --- api_key: "PROJECT_API_KEY" ``` See the [Configuration reference](/lib/ruby/gem-reference/configuration/) for additional info. # Multiple projects > Configure multiple Honeybadger projects in Ruby applications for multi-tenant or complex architectures. To send errors to another Honeybadger project, configure an additional agent: ```ruby OtherBadger = Honeybadger::Agent.new OtherBadger.configure do |config| config.api_key = "PROJECT_API_KEY" end begin # Failing code rescue => exception OtherBadger.notify(exception) end ``` Agents do not use the global *honeybadger.yml* or environment variable configuration and must be configured manually after they are instantiated. # Performing check-ins > Perform check-ins from Ruby applications to monitor rake tasks and cron jobs with Honeybadger. [Honeybadger supports check-ins](/guides/check-ins/), which allow you to monitor things like cron jobs and other services. To perform a check-in, call `Honeybadger.check_in` with the ID of the check-in in your Honeybadger project. For example: ```ruby Honeybadger.check_in('1MqIo1') ``` ## Checking in from a Rake task [Section titled “Checking in from a Rake task”](#checking-in-from-a-rake-task) Here’s an example of checking in from a rake task: ```ruby task :my_task do # your code Honeybadger.check_in('1MqIo1') end ``` Now your task will check in when it’s executed periodically by cron, Heroku Scheduler, etc. If it ever stops checking in, Honeybadger will notify you. # Plain ruby mode > Use Honeybadger's Ruby gem in plain Ruby applications without Rails or other frameworks. In the Rails world it’s pretty much expected that when you install a gem it’s going to automatically integrate with your application. For instance, many gems provide their own [Railtie](http://edgeapi.rubyonrails.org/classes/Rails/Railtie.html) to run their own code when Rails initializes. The honeybadger gem fully embraces this approach by automatically detecting and integrating with as many 3rd-party gems as possible when it’s required: ```ruby require 'honeybadger' ``` Some Rubyists prefer to roll their own integrations, however. They may want to avoid 3rd-party [Monkey patching](https://en.wikipedia.org/wiki/Monkey_patch), while others aren’t using any of the libraries we integrate with and would rather report errors themselves using `Honeybadger.notify`, avoiding unnecessary initialization at runtime. To use Honeybadger without the integrations, simply `require 'honeybadger/ruby'` instead of the normal `require 'honeybadger'`. You will need to configure the gem from Ruby using `Honeybadger.configure` as *honeybadger.yml* and environment variable initialization are also skipped: ```ruby require 'honeybadger/ruby' Honeybadger.configure do |config| config.api_key = "PROJECT_API_KEY" end at_exit do # Wait for asynchronous error notifications before shutting down. Honeybadger.stop end begin # Failing code rescue => exception Honeybadger.notify(exception) end ``` See the [API Reference](https://www.rubydoc.info/gems/honeybadger) for additional methods you can use to integrate Honeybadger with your Ruby project manually. # Tests and Honeybadger > Test Honeybadger's Ruby gem integration with your application using the included test backend. It is possible to test Honeybadger’s integration with your application using the included test backend. The test backend replaces the default server backend with a stub that records error notices rather than sending them, allowing all but the HTTP notification itself to be verified. Alternatively, you could use something like [WebMock](https://github.com/bblimke/webmock) to perform a similar test using the “server” backend. ## Configuring the test backend [Section titled “Configuring the test backend”](#configuring-the-test-backend) To use the test backend, set the `backend` configuration option to “test” in honeybadger.yml for your test environment only: ```yaml api_key: "PROJECT_API_KEY" test: backend: test ``` You can also use the *HONEYBADGER\_BACKEND* environment variable to configure the test backend. Note that you must also configure your API key for the test to succeed. ## Writing the integration test [Section titled “Writing the integration test”](#writing-the-integration-test) The test backend can be used in any testing framework to test any code which reports an error with `Honeybadger.notify`. A common scenario is to test the Rails-integration which reports exceptions in a Rails controller automatically. The following example uses RSpec to test error notification in a Rails controller. First, create the controller: app/controllers/honeybadger\_test\_controller.rb ```ruby class HoneybadgerTestController < ApplicationController ERROR = RuntimeError.new("testing reporting an error to Honeybadger") def index raise ERROR end end ``` Next, create a route. For security, it’s a good idea to enable the route only in the test environment: config/routes.rb ```ruby # ... get '/test/honeybadger' => 'honeybadger_test#index' if Rails.env.test? ``` Finally, create the integration test: spec/features/honeybadger\_spec.rb ```ruby require 'rails_helper' describe "error notification" do it "notifies Honeybadger" do expect { # Code to test goes here: expect { visit '/test/honeybadger' }.to raise_error(HoneybadgerTestController::ERROR) # Important: `Honeybadger.flush` ensures that asynchronous notifications # are delivered before the test's remaining expectations are verified. Honeybadger.flush }.to change(Honeybadger::Backend::Test.notifications[:notices], :size).by(1) expect(Honeybadger::Backend::Test.notifications[:notices].first.error_message).to eq('testing reporting an error to Honeybadger') end end ``` # Insights overview > Query automatic Ruby instrumentation, framework events, and custom application events in Honeybadger Insights. [Insights](/guides/insights/) lets you observe what your Ruby application does in production. Honeybadger records common Ruby activity automatically, including requests, database queries, background jobs, cache calls, and runtime metrics. From there, you can add context and custom events from your own code, then use [BadgerQL](/guides/insights/badgerql/) to ask questions across the whole event stream. Any field you send is queryable as soon as it arrives, with no schema to define ahead of time. ## Start with automatic instrumentation [Section titled “Start with automatic instrumentation”](#start-with-automatic-instrumentation) Insights is on by default in v6.0+. The gem starts recording events as soon as your app boots. [Automatic instrumentation](/lib/ruby/insights/automatic-instrumentation/)Configure what the gem captures. We capture a wide range of events automatically. [Ruby event reference](/insights/event-types/ruby/)See every Ruby event type and field. ## Add a built-in dashboard [Section titled “Add a built-in dashboard”](#add-a-built-in-dashboard) Automatic events power built-in dashboards, no setup necessary. [Rails](/guides/dashboards/rails/)Slow requests, queries, and partials; cache hit rates by controller [Sidekiq](/guides/dashboards/sidekiq/)Job counts, durations, and failure rates by worker [Active Job](/guides/dashboards/active-job/)Job counts, durations, and failure rates by job class [Autotuner](/guides/dashboards/autotuner/)Heap growth, GC counts, and memory tuning suggestions [Puma](/guides/dashboards/puma/)Request backlog, running threads, and pool capacity over time Pre-aggregated alternatives for apps that have [metrics enabled](/lib/ruby/insights/collecting-and-reporting-metrics/): [Rails Metrics](/guides/dashboards/rails-metrics/)Pre-aggregated throughput, controller durations, and DB/view timings [Sidekiq Metrics](/guides/dashboards/sidekiq-metrics/)Pre-aggregated job durations, queue depth, latency, and capacity [Active Job Metrics](/guides/dashboards/active-job-metrics/)Pre-aggregated job throughput, durations, and stats by job class [Karafka](/guides/dashboards/karafka/)Consumer lag, processing durations, and broker errors by topic [Net::HTTP Metrics](/guides/dashboards/net-http-metrics/)Outbound HTTP throughput, durations, and status codes by host [Solid Queue Metrics](/guides/dashboards/solid-queue-metrics/)Job statuses, active workers and dispatchers, and queue depths ## Add application context [Section titled “Add application context”](#add-application-context) Adding event context attaches fields to the current thread. Once set, every event emitted from that thread includes them. Lets say our app is A/B testing a new checkout flow. We could record the A/B variant simply with event context: Set the variant on context ```ruby Honeybadger.event_context({ checkout_variant: }) ``` The `checkout_variant` field is now on every ActiveRecord event for that request. You can group by it like any other field. ActiveRecord work by checkout variant ```badgerql filter event_type::str == "sql.active_record" and isNotNull(checkout_variant::str) | stats count() as queries, avg(duration::float) as avg_ms by checkout_variant::str | sort queries desc ``` | queries | avg\_ms | checkout\_variant | | ------- | ------- | ----------------- | | 26815 | 1.93 | new | | 11873 | 1.71 | control | The new variant ran more than twice as many queries with similar per-query time. Keep in mind that adding another A/B variant will extend any of the examples here without the need to change anything on the Honeybadger side. Go deeper: check for possible N+1 queries The gem attaches a `request_id` to every event from the same request. To turn total ActiveRecord work into queries per request, group events by `request_id` first to get a per-request count, then aggregate by variant. ```badgerql filter event_type::str == "sql.active_record" and isNotNull(checkout_variant::str) | stats count() as queries by request_id::str, checkout_variant::str | stats count() as request_count, avg(queries) as avg_q, percentile(95, queries) as p95_q by checkout_variant | sort p95_q desc | only toHumanString(request_count) as requests, toHumanString(avg_q) as avg_queries, toHumanString(p95_q) as p95_queries, checkout_variant ``` | requests | avg\_queries | p95\_queries | checkout\_variant | | -------- | ------------ | ------------ | ----------------- | | 631 | 42.18 | 97 | new | | 638 | 18.61 | 31 | control | The new variant runs more queries per request, and the p95 is much higher than control. That pattern often points at an N+1. [Event context](/lib/ruby/insights/event-context/)Block-scoped context, cross-thread propagation, and clearing. ## Record application events [Section titled “Record application events”](#record-application-events) Custom events record activity the framework cannot see at all. Rails knows a checkout request ran. Only your app knows whether the payment authorized: Send a custom payment event ```ruby Honeybadger.event("payment.authorized", { payment_provider: payment.provider, amount: checkout.total, currency: checkout.currency, authorization_id: payment.authorization_id }) ``` This query breaks down the amounts collected by variant and provider: Payments by variant and provider ```badgerql filter event_type::str == "payment.authorized" | stats count() as authorizations, sum(amount::float) as authorized_amount by checkout_variant::str, payment_provider::str | sort authorized_amount desc ``` | authorizations | authorized\_amount | checkout\_variant | payment\_provider | | -------------- | ------------------ | ----------------- | ----------------- | | 413 | 34108.00 | new | stripe | | 218 | 18722.00 | new | paypal | | 418 | 32167.00 | control | stripe | | 220 | 13639.00 | control | paypal | Go deeper: more insights, same instrumentation Conversion rate by variant ```badgerql filter event_type::str == "payment.authorized" or controller::str == "CheckoutsController" | stats count(event_type::str == "payment.authorized") as auth_events by request_id::str, checkout_variant::str | stats count() as auths, count(auth_events > 0) as checkouts, checkouts / auths as conv_rate by checkout_variant::str | only conv_rate, checkout_variant ``` | conv\_rate | checkout\_variant | | ---------- | ----------------- | | 0.92 | new | | 0.86 | control | Revenue per payment provider per variant ```badgerql filter event_type::str == "payment.authorized" | stats sum(amount::float) as total by payment_provider::str, checkout_variant::str | sort total desc | only toHumanString(total) as revenue, payment_provider, checkout_variant ``` | revenue | payment\_provider | checkout\_variant | | ------- | ----------------- | ----------------- | | 34,108 | stripe | new | | 32,167 | stripe | control | | 18,722 | paypal | new | | 13,639 | paypal | control | Average checkout response time by variant ```badgerql filter event_type::str == "process_action.action_controller" and controller::str == "CheckoutsController" | stats avg(duration::float) as avg_ms by checkout_variant::str | only toHumanString(avg_ms, "milliseconds") as avg, checkout_variant ``` | avg | checkout\_variant | | ----- | ----------------- | | 488ms | new | | 198ms | control | Conversion rate over time, by variant ```badgerql filter event_type::str == "payment.authorized" or controller::str == "CheckoutsController" | stats count(event_type::str == "payment.authorized") as auth_events, min(@ts) as request_ts by request_id::str, checkout_variant::str | stats count(auth_events > 0) / count() as conv_rate by checkout_variant::str, bin(1h, request_ts) as hour | sort hour asc ``` | conv\_rate | checkout\_variant | hour | | ---------- | ----------------- | ------------------- | | 0.93 | new | 2026-06-26 14:00:00 | | 0.86 | control | 2026-06-26 14:00:00 | | 0.92 | new | 2026-06-26 15:00:00 | | 0.86 | control | 2026-06-26 15:00:00 | | 0.91 | new | 2026-06-26 16:00:00 | | 0.87 | control | 2026-06-26 16:00:00 | The new variant holds a consistent lead over control across the rollout window. [Sending custom events](/lib/ruby/insights/sending-events-to-insights/)The full Honeybadger.event API, naming conventions, and delivery. # Automatic instrumentation > Events the Honeybadger Ruby gem captures automatically from Rails, background jobs, and more for Honeybadger Insights. [Honeybadger Insights](/guides/insights/) captures events from your Ruby application, including web requests, database queries, background jobs, and cache operations, and makes them available for querying, visualization, and [dashboards](/guides/dashboards/). In a Rails app, this gives you performance monitoring and observability out of the box without additional instrumentation libraries. In Honeybadger Ruby gem v6.0+, Insights is enabled by default. If you’re using an older gem version (v5.11+), you’ll need to enable it manually in your `honeybadger.yml` configuration file: ```yaml insights: enabled: true ``` ## Event captures [Section titled “Event captures”](#event-captures) Automatic instrumentation sends events from Rails, ActiveJob, Sidekiq, SolidQueue, Karafka, Net::HTTP, Puma, and more to Honeybadger, where they will be displayed in the [Insights](/guides/insights/) section of your project. See the [Ruby event reference](/insights/event-types/ruby/) for every event the gem emits, with field schemas and types. To find these events, filter by `event_type::str`. Here’s an example BadgerQL query that you can use: ```badgerql fields @ts, @preview | filter event_type::str == "perform.sidekiq" | sort @ts ``` ## Customizing Insights for a specific plugin [Section titled “Customizing Insights for a specific plugin”](#customizing-insights-for-a-specific-plugin) When Insights is active, all plugins are enabled if the required library is present. For example, if Sidekiq is present in your app, the Sidekiq plugin will be loaded. You can disable automatic Insights instrumentation for a specific plugin by adding a configuration like this: ```yaml sidekiq: insights: enabled: false ``` This will only affect Insights-related data capture and not the error notification portion of the plugin. Some plugins allow for an easy way to choose if you want to capture events, metrics, or both for a particular plugin. The following configuration options are available: ```yaml rails: insights: events: true metrics: false karafka: insights: events: true metrics: false sidekiq: insights: events: true metrics: false net_http: insights: events: true metrics: false solid_queue: insights: events: true metrics: false puma: insights: events: true metrics: false autotuner: insights: events: true metrics: false ``` Event options are all true by default. It is recommened to turn off events for plugins that may be producing more data than you actually need. Metric data collection is false by default since most metrics can be calculated from events. By default, the `net_http` plugin logs the domain name of any request as part of the event payload. You can enabling logging of the full URL by setting the following configuration: ```plaintext net_http: insights: full_url: true ``` ## Managing event volume [Section titled “Managing event volume”](#managing-event-volume) If some events are noisy or you’d like to reduce quota consumption: * [Filtering events](/lib/ruby/insights/filtering-events/) — ignore specific event types, or inspect and halt events with a callback. * [Sampling events](/lib/ruby/insights/sampling-events/) — send only a percentage of events. ## Sending your own events [Section titled “Sending your own events”](#sending-your-own-events) Automatic instrumentation covers the libraries the gem knows about. To send your own application events, see [Sending custom events](/lib/ruby/insights/sending-events-to-insights/). ## Metrics [Section titled “Metrics”](#metrics) The Honeybadger Ruby gem does more than just send events when they occur in your app. You can also enable metric collection. Check out [Collecting and Reporting Metrics](/lib/ruby/insights/collecting-and-reporting-metrics/) for more information. ## Sending Rails logs to Insights [Section titled “Sending Rails logs to Insights”](#sending-rails-logs-to-insights) If you are already using the Rails logger to track events in your application, you can send those events to Insights by [using a structured logging gem](/guides/insights/integrations/ruby-and-rails). # Collecting and reporting metrics > Collect and report custom metrics from Ruby applications to Honeybadger for performance monitoring. Honeybadger’s Ruby gem (v5.11+) can be used to collect metrics and send them to [Insights](https://docs.honeybadger.io/guides/insights/). ## Enabling Insights [Section titled “Enabling Insights”](#enabling-insights) To enable collecting of metrics, you’ll first need to enable Insights in your `honeybadger.yml` configuration file: ```yaml insights: enabled: true ``` ### Enable metrics collection [Section titled “Enable metrics collection”](#enable-metrics-collection) You can enable the metrics collection of each plugin by adding the relevant configuration to your `honeybadger.yml` file: ```yaml rails: insights: metrics: true karafka: insights: metrics: true sidekiq: insights: metrics: true net_http: insights: metrics: true solid_queue: insights: metrics: true puma: insights: metrics: true autotuner: insights: metrics: true ``` Enabling this will collect metric data for the libraries below and display it in the [Insights](/guides/insights/) section of your project. Each metric is emitted as a [`metric.hb`](/insights/event-types/ruby/metric.hb/) event with a `metric_source` identifying the plugin and a `metric_name` identifying the metric. `rails`12 | Kind | Metric name | | --------------- | ----------------------------------------------- | | [gauge](#gauge) | `duration.sql.active_record` | | [gauge](#gauge) | `duration.process_action.action_controller` | | [gauge](#gauge) | `db_runtime.process_action.action_controller` | | [gauge](#gauge) | `view_runtime.process_action.action_controller` | | [gauge](#gauge) | `duration.cache_read.active_support` | | [gauge](#gauge) | `duration.cache_fetch_hit.active_support` | | [gauge](#gauge) | `duration.cache_write.active_support` | | [gauge](#gauge) | `duration.cache_exist?.active_support` | | [gauge](#gauge) | `duration.render_partial.action_view` | | [gauge](#gauge) | `duration.render_template.action_view` | | [gauge](#gauge) | `duration.render_collection.action_view` | | [gauge](#gauge) | `duration.perform.active_job` | `sidekiq`13 | Kind | Metric name | | --------------- | ------------------ | | [gauge](#gauge) | `active_workers` | | [gauge](#gauge) | `active_processes` | | [gauge](#gauge) | `jobs_processed` | | [gauge](#gauge) | `jobs_failed` | | [gauge](#gauge) | `jobs_scheduled` | | [gauge](#gauge) | `jobs_enqueued` | | [gauge](#gauge) | `jobs_dead` | | [gauge](#gauge) | `jobs_retry` | | [gauge](#gauge) | `queue_latency` | | [gauge](#gauge) | `queue_depth` | | [gauge](#gauge) | `queue_busy` | | [gauge](#gauge) | `capacity` | | [gauge](#gauge) | `utilization` | `solid_queue`8 | Kind | Metric name | | --------------- | -------------------- | | [gauge](#gauge) | `jobs_in_progress` | | [gauge](#gauge) | `jobs_blocked` | | [gauge](#gauge) | `jobs_failed` | | [gauge](#gauge) | `jobs_scheduled` | | [gauge](#gauge) | `jobs_processed` | | [gauge](#gauge) | `active_workers` | | [gauge](#gauge) | `active_dispatchers` | | [gauge](#gauge) | `queue_depth` | `autotuner`5 | Kind | Metric name | | --------------- | --------------------- | | [gauge](#gauge) | `diff.minor_gc_count` | | [gauge](#gauge) | `diff.major_gc_count` | | [gauge](#gauge) | `diff.time` | | [gauge](#gauge) | `request_time` | | [gauge](#gauge) | `heap_pages` | `puma`5 | Kind | Metric name | | --------------- | ---------------- | | [gauge](#gauge) | `pool_capacity` | | [gauge](#gauge) | `max_threads` | | [gauge](#gauge) | `requests_count` | | [gauge](#gauge) | `backlog` | | [gauge](#gauge) | `running` | `net_http`1 | Kind | Metric name | | --------------- | ------------------ | | [gauge](#gauge) | `duration.request` | `karafka`29 | Kind | Metric name | | ----------------------- | ------------------------------ | | [counter](#counter) | `messages_consumed` | | [counter](#counter) | `messages_consumed_bytes` | | [counter](#counter) | `consume_attempts` | | [counter](#counter) | `consume_errors` | | [counter](#counter) | `receive_errors` | | [counter](#counter) | `connection_connects` | | [counter](#counter) | `connection_disconnects` | | [gauge](#gauge) | `network_latency_avg` | | [gauge](#gauge) | `network_latency_p95` | | [gauge](#gauge) | `network_latency_p99` | | [gauge](#gauge) | `consumer_lags` | | [gauge](#gauge) | `consumer_lags_delta` | | [gauge](#gauge) | `consumer_aggregated_lag` | | [counter](#counter) | `error_occurred` | | [histogram](#histogram) | `listener_polling_time_taken` | | [histogram](#histogram) | `listener_polling_messages` | | [counter](#counter) | `consumer_messages` | | [counter](#counter) | `consumer_batches` | | [gauge](#gauge) | `consumer_offset` | | [histogram](#histogram) | `consumer_consumed_time_taken` | | [histogram](#histogram) | `consumer_batch_size` | | [histogram](#histogram) | `consumer_processing_lag` | | [histogram](#histogram) | `consumer_consumption_lag` | | [counter](#counter) | `consumer_revoked` | | [counter](#counter) | `consumer_shutdown` | | [counter](#counter) | `consumer_tick` | | [gauge](#gauge) | `worker_total_threads` | | [histogram](#histogram) | `worker_processing` | | [histogram](#histogram) | `worker_enqueued_jobs` | These metrics may be found using the following BadgerQL query: ```badgerql fields @ts, @preview | filter event_type::str == "metric.hb" | filter metric_source::str == "sidekiq" | filter metric_name::str == "active_workers" | sort @ts ``` ### Customizing Insights for a specific plugin [Section titled “Customizing Insights for a specific plugin”](#customizing-insights-for-a-specific-plugin) When Insights is active, all plugins are enabled if the required library is present. For example, if Sidekiq is present in your app, the Sidekiq plugin will be loaded. You can disable automatic Insights instrumentation for a specific plugin by adding a configuration like this: ```yaml sidekiq: insights: enabled: false ``` This will only affect Insights-related data capture and not the error notification portion of the plugin. Some plugins allow for an easy way to choose if you want to capture events, metrics, or both for a particular plugin. The following configuration options are available: ```yaml rails: insights: events: true metrics: false karafka: insights: events: true metrics: false sidekiq: insights: events: true metrics: false net_http: insights: events: true metrics: false solid_queue: insights: events: true metrics: false puma: insights: events: true metrics: false autotuner: insights: events: true metrics: false ``` Event options are all true by default. It is recommened to turn off events for plugins that may be producing more data than you actually need. Metric data collection is false by default since most metrics can be calculated from events. ### Customizing cluster metrics collection [Section titled “Customizing cluster metrics collection”](#customizing-cluster-metrics-collection) For certain stats, collection is limited by a polling interval. Honeybadger will periodically collect stats. This can be tailored per plugin through a configuration parameter: ```yaml sidekiq: insights: collection_interval: 5 solid_queue: insights: collection_interval: 5 puma: insights: collection_interval: 1 ``` By reducing or increasing the frequency the gem collect stats will all you to fine tune the accuracy of your stats and the resources used to do so. Some metrics collection methods collect data based on the entire cluster of an application. In these cases, you would only need to collect data from a single instance of the Honeybadger gem. This helps save on unecessary load as well as data usage. Plugins collect data by default, but can be customized through configuration. ```yaml sidekiq: insights: cluster_collection: false solid_queue: insights: cluster_collection: false ``` You can use this configuration paramter to control which instances you want collecting cluster based data. If you are using Sidekiq Enterprise, we automatically detect the leader instance and will enable cluster collection on that instance and disable it on others without any additional configuration. ## Data aggregation [Section titled “Data aggregation”](#data-aggregation) When you collect metrics using the Honeybadger gem, the gem will aggregate the data and report the results to Insights every 60 seconds. This allows you to collect data as much and as quickly as you want, while making efficient use of your daily data quota. If you want to tweak the resolution of the timing, you can configure it in the `honeybadger.yml` config file. ```yaml insights: registry_flush_interval: 120 ``` The above configuration will adjust the metric registry so that it reports every 2 minutes and help save on data usage. ## Manually collecting your own metrics [Section titled “Manually collecting your own metrics”](#manually-collecting-your-own-metrics) The Honeybadger gem provides a API for defining and collecting your own metrics to feed into Insights. ### Types of metrics [Section titled “Types of metrics”](#types-of-metrics) #### Gauge [Section titled “Gauge”](#gauge) A gauge tracks a specific value at a point in time. During aggregation, the metric will record the values: `max`, `min`, `avg`, and `latest`. ```ruby Honeybadger.gauge('data_size', ->{ file.byte_size }) ``` #### Timer [Section titled “Timer”](#timer) Timers are similar to gauges in that they track a specific value in time. However, the `time` methods provides a convenient way to measure duration across your ruby operations. ```ruby Honeybadger.time('process_application', ->{ application.process }) ``` #### Counter [Section titled “Counter”](#counter) Counters are simple numbers that you can increment or decrement by any value you wish. ```ruby Honeybadger.increment_counter('add_to_basket', { item_id: item.id }) ``` #### Histogram [Section titled “Histogram”](#histogram) Histograms allows you to collate data values into predefined bins. The default bins are `[0.005, 0.01, 0.025, 0.05, 0.1, 0.25, 0.5, 1, 2.5, 5, 10]`. You can define your own set by passing a `bins` attribute to the metric. You may pass a callable lambda, which will be timed and the duration recorded. Or you may also pass a `duration` keyword argument if you have the value at hand. ```ruby Honeybadger.histogram('execute_request', ->{ request.execute }) # or Honeybadger.histogram('execute_request', duration: duration) ``` #### Helper module [Section titled “Helper module”](#helper-module) You can also include the helper module `Honeybadger::InstrumentationHelper` into any of your classes. The module provdes shortened forms to create the same metrics as metioned above, as well as other helper methods to customize your metrics. Here is an example of how we can rewrite the example metrics above, while adding more custom attributes: ```ruby class MyMetrics include Honeybadger::InstrumentationHelper attr_reader :region def initialize(region) @region = region end def example metric_source 'custom_metrics' metric_attributes { region: region } gauge 'data_size', ->{ file.byte_size } time 'process_application', ->{ application.process } increment_counter 'add_to_basket', { item_id: item.id } histogram 'execute_request', ->{ request.execute } end end ``` Aside from a less verbose API, there are two available helper methods that will aid in organizing your metrics. The `metric_source` method accepts the name of where your metrics are coming from. This can be the name of a library, or the class you are calling from. The `metric_attributes` method accepts a hash that will be passed to all metrics that follow. Then you can find these metrics by using the following BadgerQL query: ```badgerql fields @ts, @preview | filter event_type::str == "metric.hb" | filter metric_source::str == "custom_metrics" | filter region::str == "some-region" | sort @ts ``` ## Ignoring metrics [Section titled “Ignoring metrics”](#ignoring-metrics) You can use the `before_event` callback to inspect or modify metric data, as well as calling `halt!` to prevent the metric from being sent to Honeybadger: ```ruby Honeybadger.configure do |config| config.before_event do |event| if event.event_type == "metric.hb" && event[:metric_name] == "jobs_processed" event.halt! end end end ``` `before_event` can be called multiple times to add multiple callbacks. Similarly, you may also ignore metric events by configuring your `honeybadger.yml` config file by specifying a hash object: ```yaml events: ignore: - event_type: "metric.hb" metric_name: "jobs_processed" ``` ## Puma [Section titled “Puma”](#puma) Puma has it’s own plugin system and requires a small change to your `puma.rb`. The Honeybadger gem comes with Puma plugin and can be enabled by adding the following to your `puma.rb`: ```ruby plugin :honeybadger ``` ## Autotuner [Section titled “Autotuner”](#autotuner) To enable Autotuner, follow the directions in the [README.md](https://github.com/Shopify/autotuner) file. You can skip the parts about setting `Autotuner.reporter` and `Autotuner.metrics_reporter` as the Honeybadger gem will configure this for you. ## More automatic instrumentation [Section titled “More automatic instrumentation”](#more-automatic-instrumentation) The Honeybadger Ruby gem provides more instrumentation than just metrics. When you enable Insights, you also enable automatic event logging. Check out [Automatic instrumentation](/lib/ruby/insights/automatic-instrumentation/) for more information. # Event context > Add custom metadata to the events sent from your Ruby application to Honeybadger Insights. You can add custom metadata to the events sent to Honeybadger Insights by using the `Honeybadger.event_context` method. This metadata will be included in each event sent within the same thread. Caution This will add the metadata to all events sent, so be careful not to include too much data. Try to keep it to simple key/value pairs. For example, you can add user ID information to all events (via a Rails controller): ```ruby class ApplicationController < ActionController::Base before_action :set_honeybadger_context private def set_honeybadger_context if current_user Honeybadger.event_context(user_id: current_user.id, user_email: current_user.email) end end end ``` Event context is not automatically propagated to other threads. If you want to add context to events in a different thread, you can use the `Honeybadger.get_event_context` method to get the current context and pass it to the `Honeybadger.event` method: ```ruby class MyJob < ApplicationJob def perform(user_id) # Get context from the main thread context = Honeybadger.get_event_context Thread.new do # Set the context in the new thread Honeybadger.event_context(context) # Do some work here Honeybadger.event("background_work", { user_id: user_id, status: "completed" }) end end end ``` ## Block-scoped context [Section titled “Block-scoped context”](#block-scoped-context) You can also set event context for a specific block of code using a block form: ```ruby Honeybadger.event_context(user_id: 123) do # All events within this block will include the user_id context Honeybadger.event("user_action", { action: "login" }) Honeybadger.event("user_action", { action: "logout" }) end # Context is automatically cleared after the block ``` ## Clearing event context [Section titled “Clearing event context”](#clearing-event-context) You can clear the current event context at any time: ```ruby Honeybadger.event_context.clear! ``` # Filtering events > Ignore unwanted events before they're sent from your Ruby application to Honeybadger Insights. For some applications, certain default events may be unecessary or excessively data heavy. To specify events to ignore, use the `events.ignore` configuration option. Here you can specify a list of event types for the gem to ignore. They can be either a string or a regex. ```yaml events: ignore: - "enqueue.sidekiq" - !ruby/regexp "/.*.active_storage/" ``` You may also ignore events based on event data by specifying a hash object. ```yaml events: ignore: - event_type: "chatty_events" custom_data: "ignore_me" ``` This will ignore events that have been created with the matching `event_type` and key(symbol)/value: ```ruby Honeybadger.event('chatty_events', custom_data: 'ignore_me') # will not be sent to Insights ``` You can also use the `before_event` callback to inspect or modify event data, as well as calling `halt!` to prevent the event from being sent to Honeybadger: config/initializers/honeybadger.rb ```ruby Honeybadger.configure do |config| config.before_event do |event| # Ignore health check requests if event.event_type == "process_action.action_controller" && event[:controller] == "Rails::HealthController" event.halt! end # DB-backed job backends can generate a lot of useless queries if event.event_type == "sql.active_record" && event[:query].match?(/good_job|solid_queue/) event.halt! end end end ``` `before_event` can be called multiple times to add multiple callbacks. ## Default ignored events [Section titled “Default ignored events”](#default-ignored-events) The gem comes configured to ignore a few events that can be chatty and not useful: * `sql.active_record` events with queries that contain only “BEGIN” or “COMMIT”. * `sql.active_record` events for database backed background processing gems (SolidQueue and GoodJob). * `process_action.action_controller` events for `Rails::HealthController` actions. ## Sampling events [Section titled “Sampling events”](#sampling-events) If you’d rather reduce event volume across the board instead of ignoring specific events, see [Sampling events](/lib/ruby/insights/sampling-events/). # Sampling events > Send a percentage of events from your Ruby application to Honeybadger Insights to manage quota consumption. If you find that you’d like to report fewer events in order to minimize your quota consumption, you can conditionally send a certain percentage of events: config/honeybadger.yml ```yaml insights: sample_rate: 10 ``` This will send 10% of events not associated with a request, and all events for 10% of requests. To ignore specific events instead of sampling across the board, see [Filtering events](/lib/ruby/insights/filtering-events/). # Sending custom events > Send custom events from Ruby applications to Honeybadger Insights for monitoring and analysis. You can send your own application events to [Honeybadger Insights](/guides/insights/) using the `Honeybadger.event` method. (For the events the gem captures on its own — web requests, database queries, background jobs, and more — see [Automatic instrumentation](/lib/ruby/insights/automatic-instrumentation/).) ```ruby Honeybadger.event('user_activity', { action: 'registration', user_id: 123 }) ``` The first argument is the type of the event (`event_type`) and the second argument is an object containing any additional data you want to include. Payloads can include nested hashes and arrays, and are sanitized the same way error context is. `Honeybadger.event` can also be called with a single argument as an object containing the data for the event: ```ruby Honeybadger.event({ event_type: 'user_activity', action: 'registration', user_id: 123 }) ``` ## Naming events [Section titled “Naming events”](#naming-events) The `event_type` is how you’ll filter for these events in every query, so stable, descriptive names pay off. Dot-namespaced names group related events and read naturally in queries: `payment.completed`, `payment.refunded`, `export.finished`. The gem’s own events follow the same convention (`sql.active_record`, `perform.sidekiq`). ## Fields added automatically [Section titled “Fields added automatically”](#fields-added-automatically) The gem adds a few fields to every event before sending: | Field | Type | Description | | ------------- | ------------------ | -------------------------------------------------------------------------------------------------------------------------------------------- | | `ts` | string\ | Event timestamp (ISO 8601, UTC). Added unless you provide your own. | | `request_id` | string | Rails request ID, when the event is sent during a web request. Correlates your events with the gem’s automatic events from the same request. | | `hostname` | string | Server hostname. Disable with the `events.attach_hostname` [configuration option](/lib/ruby/gem-reference/configuration/). | | `environment` | string | Deploy environment. Disable with the `events.attach_environment` [configuration option](/lib/ruby/gem-reference/configuration/). | Fields set via [Event context](/lib/ruby/insights/event-context/) — user IDs, tenant IDs, and other per-request metadata — are also merged into every event. ## Delivery [Section titled “Delivery”](#delivery) `Honeybadger.event` doesn’t block: events are queued in memory and sent in batches — when 1,000 events accumulate or every 30 seconds, whichever comes first. The queue holds up to 100,000 events; batch size, timeout, and queue limits are [configurable](/lib/ruby/gem-reference/configuration/). When the process exits, the gem sends any remaining queued events (`send_data_at_exit`, on by default). For cases where you need delivery before continuing — a short-lived script that must not exit early, or work that follows immediately — `Honeybadger.flush` sends everything queued: ```ruby Honeybadger.flush do records.each { |r| Honeybadger.event("import.row_processed", id: r.id) } end ``` ## Finding your events [Section titled “Finding your events”](#finding-your-events) Filter by the `event_type` you chose: ```badgerql fields @ts, @preview | filter event_type::str == "user_activity" | filter action::str == "registration" | sort @ts ``` See the [BadgerQL guide](/guides/insights/badgerql/) for aggregations, grouping, and the rest of the query language. ## Managing event volume [Section titled “Managing event volume”](#managing-event-volume) If some events are noisy or you’d like to reduce quota consumption: * [Filtering events](/lib/ruby/insights/filtering-events/) — ignore specific event types, or inspect and halt events with a callback. * [Sampling events](/lib/ruby/insights/sampling-events/) — send only a percentage of events. # Tracking Ruby errors on AWS Lambda > Honeybadger monitors your Ruby AWS Lambda functions for errors and exceptions so that you can fix them wicked fast. **Typical installation time:** 1 minute Hi there! You’ve found Honeybadger’s guide to **Ruby Exception and error tracking on AWS Lambda and Serverless**. Once installed, Honeybadger will report exceptions wherever they may happen. If you’re new to Honeybadger, read our [Getting Started guide](/lib/ruby/) to become familiar with our Ruby gem. For a refresher on working with exceptions in Ruby, check out the [Honeybadger guide to Ruby exceptions](https://www.exceptionalcreatures.com/guides/what-are-ruby-exceptions/). ## Installation [Section titled “Installation”](#installation) The first step is to add the honeybadger gem to your Gemfile: ```ruby gem 'honeybadger' ``` Tell bundler to install: ```bash bundle install --deployment --without development,test ``` Depending on your deployment method, vendoring might be required to ensure your dependencies are included. We think the [serverless framework](https://serverless.com/framework/docs/providers/aws/examples/hello-world/ruby/) is a cool way to manage your lambda functions. It may help to use a Ruby version manager (something like [asdf](https://github.com/asdf-vm/asdf-ruby) or [rvm](https://rvm.io/)) to ensure you are building against your selected lambda Ruby runtime. You can view a list of lambda runtime versions [here](https://docs.aws.amazon.com/lambda/latest/dg/lambda-runtimes.html). You can configure Honeybadger in your Lambda by adding your API key via the `HONEYBADGER_API_KEY` environment variable. ## Capturing exceptions [Section titled “Capturing exceptions”](#capturing-exceptions) To automatically capture exceptions from your Lambda handler, register your handlers with the `hb_wrap_handler` method. Any unhandled exceptions raised within the specified methods will be automatically reported to Honeybadger. ```ruby require 'honeybadger' hb_wrap_handler :my_handler1, :my_handler2 def my_handler1(event:, context:) # ... end def my_handler2(event:, context:) # ... end ``` For class methods, you’ll need to first extend our `LambdaExtensions` module: ```ruby class MyLambdaApp extend ::Honeybadger::Plugins::LambdaExtension hb_wrap_handler :my_handler def self.my_handler(event:, context:) # ... end end ``` # Hanami integration guide > Honeybadger monitors your Hanami applications for errors and exceptions so that you can fix them wicked fast. **Typical installation time:** 4 minutes Hi there! You’ve found Honeybadger’s guide to **Hanami exception and error tracking**. Once installed, Honeybadger will automatically report exceptions wherever they may happen: * During a web request * In a background job * In a Rake task * When a process crashes (`at_exit`) If you’re new to Honeybadger, read our [Getting Started guide](/lib/ruby/index.html) to become familiar with our Ruby gem. For a refresher on working with exceptions in Ruby, check out the [Honeybadger guide to Ruby exceptions](https://www.exceptionalcreatures.com/guides/what-are-ruby-exceptions.html). ## Installation [Section titled “Installation”](#installation) The first step is to add the honeybadger gem to your Gemfile: ```ruby gem 'honeybadger' ``` Tell bundler to install: ```bash bundle install ``` Next, you'll set the API key for this project. ```bash bundle exec honeybadger install [Your project API key] ``` This will do three things: 1. Generate a `honeybadger.yml` file. If you don't like config files, you can place your API key in the `$HONEYBADGER_API_KEY` environment variable. 2. If Capistrano is installed, we'll add a require statement to *Capfile*. 3. Send a test exception to your Honeybadger project. Finally, require the honeybadger gem in your `config.ru`, before you run your Hanami app. config.ru ```ruby require "hanami/boot" require "honeybadger" run Hanami.app ``` If you’re on a Hanami **v1** app, you’ll need to add the Rack middleware manually: config.ru ```ruby require './config/environment' require 'honeybadger' # These two are optional (explained below), but for them # to work, they must be placed *before* the ErrorNotifier. use Honeybadger::Rack::UserInformer use Honeybadger::Rack::UserFeedback use Honeybadger::Rack::ErrorNotifier run Hanami.app ``` That’s it. Honeybadger will now automatically catch exceptions in your app. ## Identifying users [Section titled “Identifying users”](#identifying-users) If you’re using the *devise* or the *warden* gems for user authentication, then we already associate errors with the current user. For other authentication systems (or to customize the user values), use `Honeybadger.context` to associate the current user: ```ruby Honeybadger.context({ user_id: current_user.id, user_email: current_user.email }) ``` ## Collecting user feedback [Section titled “Collecting user feedback”](#collecting-user-feedback) The Honeybadger gem has a few special tags that it looks for whenever you render an error page in a Rack-based application. These can be used to display extra information about the error, or to ask the user for information about how they triggered the error. Honeybadger automatically installs the middleware for these in your Hanami project. ### Displaying the error ID [Section titled “Displaying the error ID”](#displaying-the-error-id) When an error is sent to Honeybadger, our API returns a unique UUID for the occurrence within your project. This UUID can be automatically displayed for reference on error pages. To include the error id, simply place this magic HTML comment on your error page (normally `public/500.html` in Rails): ```html ``` By default, we will replace this tag with: ```plaintext Honeybadger Error {{error_id}} ``` Where `{{error_id}}` is the UUID. You can customize this output by overriding the `user_informer.info` option in your honeybadger.yml file (you can also enabled/disable the middleware): config/honeybadger.yml ```yaml user_informer: enabled: true info: "Error ID: {{error_id}}" ``` You can use that UUID to load the error at the site by going to [https://app.honeybadger.io/notice/some-uuid-goes-here](https://app.honeybadger.io/notice/). ### Displaying a feedback form [Section titled “Displaying a feedback form”](#displaying-a-feedback-form) When an error is sent to Honeybadger, an HTML form can be generated so users can fill out relevant information that led up to that error. Feedback responses are displayed inline in the comments section on the fault detail page. To include a user feedback form on your error page, simply add this magic HTML comment (normally `public/500.html` in Rails): ```html ``` You can change the text displayed in the form via the Rails internationalization system. Here’s an example: config/locales/en.yml ```yaml en: honeybadger: feedback: heading: "Care to help us fix this?" explanation: "Any information you can provide will help us fix the problem." submit: "Send" thanks: "Thanks for the feedback!" labels: name: "Your name" email: "Your email address" comment: "Comment (required)" ``` The feedback form can be enabled and disabled using the `feedback.enabled` config option (defaults to `true`): config/honeybadger.yml ```yaml feedback: enabled: true ``` # Heroku integration guide > Honeybadger monitors your Heroku Ruby applications for errors and exceptions so that you can fix them wicked fast. **Typical installation time:** 1 minute Hi there! You’ve found Honeybadger’s guide to **Ruby exception and error tracking on Heroku**. Once installed, Honeybadger will automatically report exceptions wherever they may happen: * During a web request * In a background job * In a rake task * When a process crashes (`at_exit`) If you’re new to Honeybadger, read our [Getting Started guide](/lib/ruby/) to become familiar with our Ruby gem. For a refresher on working with exceptions in Ruby, check out the [Honeybadger guide to Ruby exceptions](https://www.exceptionalcreatures.com/guides/what-are-ruby-exceptions/). ## Installation [Section titled “Installation”](#installation) The first step is to add the honeybadger gem to your Gemfile: ```ruby gem 'honeybadger' ``` Tell bundler to install: ```bash bundle install ``` You can configure Honeybadger on your dynos like so: *Note: This last step isn’t necessary if you’re using our [Heroku add-on](https://elements.heroku.com/addons/honeybadger), as it adds our API key to your Heroku config automatically.* ```bash bundle exec honeybadger heroku install [YOUR API KEY HERE] ``` This will automatically add a `HONEYBADGER_API_KEY` environment variable to your remote Heroku config and configure deploy notifications. ### Tracking deployments [Section titled “Tracking deployments”](#tracking-deployments) To learn more about tracking deployments, see the [Tracking deployments](/lib/ruby/errors/tracking-deployments/) section of the [Getting Started guide](/lib/ruby/). Deploy tracking via Heroku is implemented using Heroku’s [app webhooks](https://devcenter.heroku.com/articles/app-webhooks). If you ran the [Installation](#installation) command already, then you should already have deployment tracking installed. Otherwise, to install the addon and configure it for Honeybadger, run the following CLI command from your project root: ```sh bundle exec honeybadger heroku install_deploy_notification ``` If the honeybadger CLI command fails for whatever reason, you can add the deploy hook manually by running: ```sh heroku webhooks:add -i api:release -l notify -u "https://api.honeybadger.io/v1/deploys/heroku?repository=git@github.com/username/projectname&environment=production&api_key=asdf" --app app-name ``` You should replace the `repository`, `api_key`, and `app` options with your own values. You may also want to change the environment (set to production by default). For more about manual use of Heroku deploy tracking, see the [Heroku Deployments](/guides/heroku/#heroku-deployment-tracking) guide. # Rack integration guide > Honeybadger monitors your Ruby/Rack applications for errors and exceptions so that you can fix them wicked fast. **Typical installation time:** 4 minutes Hi there! You’ve found Honeybadger’s guide to **Rack exception and error tracking**. Once installed, Honeybadger will automatically report exceptions wherever they may happen: * During a web request * In a background job * In a rake task * When a process crashes (`at_exit`) If you’re new to Honeybadger, read our [Getting Started guide](/lib/ruby/index.html) to become familiar with our Ruby gem. For a refresher on working with exceptions in Ruby, check out the [Honeybadger guide to Ruby exceptions](https://www.exceptionalcreatures.com/guides/what-are-ruby-exceptions.html). ## Installation [Section titled “Installation”](#installation) The first step is to add the honeybadger gem to your Gemfile: ```ruby gem 'honeybadger' ``` Tell bundler to install: ```bash bundle install ``` Next, you'll set the API key for this project. ```bash bundle exec honeybadger install [Your project API key] ``` This will do three things: 1. Generate a `honeybadger.yml` file. If you don't like config files, you can place your API key in the `$HONEYBADGER_API_KEY` environment variable. 2. If Capistrano is installed, we'll add a require statement to *Capfile*. 3. Send a test exception to your Honeybadger project. Now it’s time to set up your Rack app. Start by requiring the *honeybadger* gem **after** any other gems you’re using: ```ruby require 'rack' # ... require 'honeybadger' ``` Then add the middleware to your app. Make sure Honeybadger’s middleware is the first middleware you define so that it can catch exceptions in your other middleware: ```ruby use Honeybadger::Rack::ErrorNotifier # ... ``` ### Example app [Section titled “Example app”](#example-app) ```ruby require 'rack' # Load the gem require 'honeybadger' # Write your app app = Rack::Builder.app do run lambda { |env| raise "Rack down" } end # These middleware are optional, but for them to work, # they must be placed *before* the ErrorNotifier middleware use Honeybadger::Rack::UserFeedback use Honeybadger::Rack::UserInformer # Use Honeybadger's Rack middleware use Honeybadger::Rack::ErrorNotifier # Use your other middleware here run app ``` ## Identifying users [Section titled “Identifying users”](#identifying-users) If you’re using the *devise* or the *warden* gems for user authentication, then we already associate errors with the current user. For other authentication systems (or to customize the user values), use `Honeybadger.context` to associate the current user: ```ruby Honeybadger.context({ user_id: current_user.id, user_email: current_user.email }) ``` ## Collecting user feedback [Section titled “Collecting user feedback”](#collecting-user-feedback) The Honeybadger gem has a few special tags that it looks for whenever you render an error page in a Rack-based application. These can be used to display extra information about the error, or to ask the user for information about how they triggered the error. You can enable them by adding the middleware to your application: ```ruby use Honeybadger::Rack::UserInformer use Honeybadger::Rack::UserFeedback # ^^^ These middleware must be placed *before* the ErrorNotifier use Honeybadger::Rack::ErrorNotifier ``` ### Displaying the error ID [Section titled “Displaying the error ID”](#displaying-the-error-id) When an error is sent to Honeybadger, our API returns a unique UUID for the occurrence within your project. This UUID can be automatically displayed for reference on error pages. To include the error id, simply place this magic HTML comment on your error page (normally `public/500.html` in Rails): ```html ``` By default, we will replace this tag with: ```plaintext Honeybadger Error {{error_id}} ``` Where `{{error_id}}` is the UUID. You can customize this output by overriding the `user_informer.info` option in your honeybadger.yml file (you can also enabled/disable the middleware): config/honeybadger.yml ```yaml user_informer: enabled: true info: "Error ID: {{error_id}}" ``` You can use that UUID to load the error at the site by going to [https://app.honeybadger.io/notice/some-uuid-goes-here](https://app.honeybadger.io/notice/). ### Displaying a feedback form [Section titled “Displaying a feedback form”](#displaying-a-feedback-form) When an error is sent to Honeybadger, an HTML form can be generated so users can fill out relevant information that led up to that error. Feedback responses are displayed inline in the comments section on the fault detail page. To include a user feedback form on your error page, simply add this magic HTML comment (normally `public/500.html` in Rails): ```html ``` You can change the text displayed in the form via the Rails internationalization system. Here’s an example: config/locales/en.yml ```yaml en: honeybadger: feedback: heading: "Care to help us fix this?" explanation: "Any information you can provide will help us fix the problem." submit: "Send" thanks: "Thanks for the feedback!" labels: name: "Your name" email: "Your email address" comment: "Comment (required)" ``` The feedback form can be enabled and disabled using the `feedback.enabled` config option (defaults to `true`): config/honeybadger.yml ```yaml feedback: enabled: true ``` # Rails integration guide > Honeybadger monitors your Ruby on Rails applications for errors and exceptions so that you can fix them wicked fast. **Typical installation time:** 2 minutes Hi there! You’ve found Honeybadger’s guide to **Ruby on Rails exception and error tracking**. Once installed, Honeybadger will automatically report exceptions wherever they may happen: * During a web request * In a background job * In a rake task * When a process crashes (`at_exit`) If you’re new to Honeybadger, read our [Getting Started guide](/lib/ruby/index.html) to become familiar with our Ruby gem. For a refresher on working with exceptions in Ruby, check out the [Honeybadger guide to Ruby exceptions](https://www.exceptionalcreatures.com/guides/what-are-ruby-exceptions.html). ## Installation [Section titled “Installation”](#installation) [![Using the Honeybadger gem with Rails](https://embed-ssl.wistia.com/deliveries/e1e2133b8f1bec224c57f6677f6bdb11691b3822.jpg?image_play_button=true\&image_play_button_color=7b796ae0\&image_crop_resized=150x84)](https://honeybadger.wistia.com/medias/l3cmyucx8f) The first step is to add the honeybadger gem to your Gemfile: ```ruby gem 'honeybadger' ``` Tell bundler to install: ```bash bundle install ``` Next, you'll set the API key for this project. ```bash bundle exec honeybadger install [Your project API key] ``` This will do three things: 1. Generate a `config/honeybadger.yml` file. If you don't like config files, you can place your API key in the `$HONEYBADGER_API_KEY` environment variable. 2. If Capistrano is installed, we'll add a require statement to *Capfile*. 3. Send a test exception to your Honeybadger project. Assuming the test completed successfully: **you’re done!** ## Identifying users [Section titled “Identifying users”](#identifying-users) If you’re using the *devise* or the *warden* gems for user authentication, then we already associate errors with the current user. For other authentication systems (or to customize the user values), add the following `before_action` to your `ApplicationController`: ```ruby before_action do Honeybadger.context({ user_id: current_user.id, user_email: current_user.email }) end ``` ## Collecting user feedback [Section titled “Collecting user feedback”](#collecting-user-feedback) The Honeybadger gem has a few special tags that it looks for whenever you render an error page. These can be used to display extra information about the error, or to ask the user for information about how they triggered the error. ### Displaying the error ID [Section titled “Displaying the error ID”](#displaying-the-error-id) When an error is sent to Honeybadger, our API returns a unique UUID for the occurrence within your project. This UUID can be automatically displayed for reference on error pages. To include the error id, simply place this magic HTML comment on your error page (normally `public/500.html` in Rails): ```html ``` By default, we will replace this tag with: ```plaintext Honeybadger Error {{error_id}} ``` Where `{{error_id}}` is the UUID. You can customize this output by overriding the `user_informer.info` option in your honeybadger.yml file (you can also enabled/disable the middleware): config/honeybadger.yml ```yaml user_informer: enabled: true info: "Error ID: {{error_id}}" ``` You can use that UUID to load the error at the site by going to [https://app.honeybadger.io/notice/some-uuid-goes-here](https://app.honeybadger.io/notice/). ### Displaying a feedback form [Section titled “Displaying a feedback form”](#displaying-a-feedback-form) When an error is sent to Honeybadger, an HTML form can be generated so users can fill out relevant information that led up to that error. Feedback responses are displayed inline in the comments section on the fault detail page. To include a user feedback form on your error page, simply add this magic HTML comment (normally `public/500.html` in Rails): ```html ``` You can change the text displayed in the form via the Rails internationalization system. Here’s an example: config/locales/en.yml ```yaml en: honeybadger: feedback: heading: "Care to help us fix this?" explanation: "Any information you can provide will help us fix the problem." submit: "Send" thanks: "Thanks for the feedback!" labels: name: "Your name" email: "Your email address" comment: "Comment (required)" ``` The feedback form can be enabled and disabled using the `feedback.enabled` config option (defaults to `true`): config/honeybadger.yml ```yaml feedback: enabled: true ``` ## The Rails error reporter [Section titled “The Rails error reporter”](#the-rails-error-reporter) On Rails 7 and above, Honeybadger supports the new [error reporter](https://guides.rubyonrails.org/error_reporting.html) included in Rails. This means you can use `Rails.error.handle` as described in the Rails docs, and errors will be reported as normal, in line with your Honeybadger configuration. `Rails.error.record` is, however, not supported, since the Honeybadger native error handlers for each integration provide much richer context for your errors than Rails’ default. On Rails 7.1 and above, each error report can include a `source` parameter. You can use the Honeybadger config option `rails.subscriber_ignore_sources` to automatically ignore errors from certain sources: ```ruby Honeybadger.configure do |config| config.rails.subscriber_ignore_sources += [/some_source/] end ``` ## Content Security Policy reports [Section titled “Content Security Policy reports”](#content-security-policy-reports) You can use [Content Security Policy](https://developer.mozilla.org/en-US/docs/Web/HTTP/CSP) headers to help mitigate XSS attacks, and Rails has a [DSL](https://guides.rubyonrails.org/security.html#content-security-policy) that you can use to configure those headers in your application. When a policy includes a `report-uri` or `report-to` directive, reports about blocked resources can be sent to a URL: ```ruby Rails.application.config.content_security_policy do |policy| policy.default_src :self, :https ... policy.report_uri -> { "https://api.honeybadger.io/v1/browser/csp?api_key=HB_API_KEY_GOES_HERE&report_only=true&env=#{Rails.env}&context[user_id]=#{respond_to?(:current_user) ? current_user&.id : nil}" } end ``` Every parameter in the URL is optional, aside from the `api_key` parameter. If you don’t need the value to be generated at request time (as in this example, to report the current user’s id), then you can provide a simple string as the argument to `report_uri`. If you set the `report_only` parameter to true, then our UI will label reports as “CSP Report”; otherwise, they will be labeled as “CSP Error”. CSP Reports and Errors show up with the rest of your app’s errors in the Honeybadger UI. For this reason, and since CSP reports can be very numerous, we recommend you create a separate Honeybadger project specifically for CSP reports. ## If you use `config.exceptions_app` [Section titled “If you use config.exceptions\_app”](#if-you-use-configexceptions_app) If you use [the `config.exceptions_app` Rails setting](https://guides.rubyonrails.org/configuring.html#rails-general-configuration) to display a custom error page, you may need some extra config for the correct controller and action name to be displayed in Honeybadger. The following snippet assumes that the name of your custom controller is “errors” (e.g. `ErrorsController`): ```ruby Honeybadger.configure do |config| config.before_notify do |notice| # Change "errors" to match your custom controller name. break if notice.component != "errors" # Look up original route path and override controller/action # in Honeybadger. params = Rails.application.routes.recognize_path(notice.url) notice.component = params[:controller] notice.action = params[:action] end end ``` ## JavaScript source maps with esbuild and Sprockets [Section titled “JavaScript source maps with esbuild and Sprockets”](#javascript-source-maps-with-esbuild-and-sprockets) If you’re using esbuild with Sprockets, you can generate source maps for your JavaScript assets and upload them to Honeybadger. This will allow Honeybadger to display the original source code for your minified JavaScript files. Here’s a [Rake Task](https://railsinspire.com/samples/18) that uploads source maps to Honeybadger via the `assets:precompile` step. # Ruby integration guide > Honeybadger monitors your Ruby applications for errors and exceptions so that you can fix them wicked fast. **Typical installation time:** 3 minutes Hi there! You’ve found Honeybadger’s guide to **Ruby exception and error tracking**. Once installed, Honeybadger will automatically report exceptions wherever they may happen: * During a web request * In a background job * In a rake task * When a process crashes (`at_exit`) If you’re new to Honeybadger, read our [Getting Started guide](/lib/ruby/) to become familiar with our Ruby gem. For a refresher on working with exceptions in Ruby, check out the [Honeybadger guide to Ruby exceptions](https://www.exceptionalcreatures.com/guides/what-are-ruby-exceptions.html). ## Installation [Section titled “Installation”](#installation) The first step is to add the honeybadger gem to your Gemfile: ```ruby gem 'honeybadger' ``` Tell bundler to install: ```bash bundle install ``` Next, you'll set the API key for this project. ```bash bundle exec honeybadger install [Your project API key] ``` This will do three things: 1. Generate a `honeybadger.yml` file. If you don't like config files, you can place your API key in the `$HONEYBADGER_API_KEY` environment variable. 2. If Capistrano is installed, we'll add a require statement to *Capfile*. 3. Send a test exception to your Honeybadger project. Next, require the *honeybadger* gem **after** any other gems you’re using: ```ruby # ... require 'honeybadger' ``` Honeybadger will detect any supported 3rd-party gems you’re using such as Sidekiq, Rake, etc. and integrate with them automatically. To notify Honeybadger of an exception you’ve rescued, use `Honeybadger.notify`: ```ruby begin fail 'oops' rescue => exception Honeybadger.notify(exception) end ``` For additional ways to use `Honeybadger.notify`, check out the [Reporting errors](/lib/ruby/errors/reporting-errors/) chapter of our [Getting started guide](/lib/ruby/). For Rack-based web applications, see the [Rack integration guide](/lib/ruby/integration-guides/rack-exception-tracking/) for instructions on how to automatically report exceptions in web requests. # Sinatra integration guide > Honeybadger monitors your Sinatra applications for errors and exceptions so that you can fix them wicked fast. **Typical installation time:** 3 minutes Hi there! You’ve found Honeybadger’s guide to **Sinatra exception and error tracking**. Once installed, Honeybadger will automatically report exceptions wherever they may happen: * During a web request * In a background job * In a Rake task * When a process crashes (`at_exit`) If you’re new to Honeybadger, read our [Getting Started guide](/lib/ruby/index.html) to become familiar with our Ruby gem. For a refresher on working with exceptions in Ruby, check out the [Honeybadger guide to Ruby exceptions](https://www.exceptionalcreatures.com/guides/what-are-ruby-exceptions.html). ## Installation [Section titled “Installation”](#installation) [![Using the Honeybadger gem with Sinatra](https://embed-ssl.wistia.com/deliveries/7c9b6e6831f2288874f24d10eec88116e9f378eb.jpg?image_play_button=true\&image_play_button_color=7b796ae0\&image_crop_resized=150x84)](https://honeybadger.wistia.com/medias/b2wr5n9fcv) The first step is to add the honeybadger gem to your Gemfile: ```ruby gem 'honeybadger' ``` Tell bundler to install: ```bash bundle install ``` Next, you'll set the API key for this project. ```bash bundle exec honeybadger install [Your project API key] ``` This will do three things: 1. Generate a `honeybadger.yml` file. If you don't like config files, you can place your API key in the `$HONEYBADGER_API_KEY` environment variable. 2. If Capistrano is installed, we'll add a require statement to *Capfile*. 3. Send a test exception to your Honeybadger project. Finally, require the honeybadger gem in your app *after* requiring the sinatra gem: ```ruby # Always require Sinatra first. require 'sinatra' # Then require honeybadger. require 'honeybadger' # Define your application code *after* Sinatra *and* honeybadger: get '/' do raise "Sinatra has left the building" end ``` ## Identifying users [Section titled “Identifying users”](#identifying-users) If you’re using the *devise* or the *warden* gems for user authentication, then we already associate errors with the current user. For other authentication systems (or to customize the user values), use `Honeybadger.context` to associate the current user: ```ruby Honeybadger.context({ user_id: current_user.id, user_email: current_user.email }) ``` ## Collecting user feedback [Section titled “Collecting user feedback”](#collecting-user-feedback) The Honeybadger gem has a few special tags that it looks for whenever you render an error page in a Rack-based application. These can be used to display extra information about the error, or to ask the user for information about how they triggered the error. Honeybadger automatically installs the middleware for these in your Sinatra project. ### Displaying the error ID [Section titled “Displaying the error ID”](#displaying-the-error-id) When an error is sent to Honeybadger, our API returns a unique UUID for the occurrence within your project. This UUID can be automatically displayed for reference on error pages. To include the error id, simply place this magic HTML comment on your error page (normally `public/500.html` in Rails): ```html ``` By default, we will replace this tag with: ```plaintext Honeybadger Error {{error_id}} ``` Where `{{error_id}}` is the UUID. You can customize this output by overriding the `user_informer.info` option in your honeybadger.yml file (you can also enabled/disable the middleware): config/honeybadger.yml ```yaml user_informer: enabled: true info: "Error ID: {{error_id}}" ``` You can use that UUID to load the error at the site by going to [https://app.honeybadger.io/notice/some-uuid-goes-here](https://app.honeybadger.io/notice/). ### Displaying a feedback form [Section titled “Displaying a feedback form”](#displaying-a-feedback-form) When an error is sent to Honeybadger, an HTML form can be generated so users can fill out relevant information that led up to that error. Feedback responses are displayed inline in the comments section on the fault detail page. To include a user feedback form on your error page, simply add this magic HTML comment (normally `public/500.html` in Rails): ```html ``` You can change the text displayed in the form via the Rails internationalization system. Here’s an example: config/locales/en.yml ```yaml en: honeybadger: feedback: heading: "Care to help us fix this?" explanation: "Any information you can provide will help us fix the problem." submit: "Send" thanks: "Thanks for the feedback!" labels: name: "Your name" email: "Your email address" comment: "Comment (required)" ``` The feedback form can be enabled and disabled using the `feedback.enabled` config option (defaults to `true`): config/honeybadger.yml ```yaml feedback: enabled: true ``` ## Content Security Policy reports [Section titled “Content Security Policy reports”](#content-security-policy-reports) You can use [Content Security Policy](https://developer.mozilla.org/en-US/docs/Web/HTTP/CSP) headers to help mitigate XSS attacks, and the [SecureHeaders](https://rubygems.org/gems/secure_headers) gem makes it easy to emit those headers from your Sinatra application. When a policy includes a `report-uri` or `report-to` directive, reports about blocked resources can be sent to a URL: ```ruby require 'rubygems' require 'sinatra' require 'secure_headers' use SecureHeaders::Middleware SecureHeaders::Configuration.default do |config| ... report_uri: "https://api.honeybadger.io/v1/browser/csp?api_key=HB_API_KEY_GOES_HERE&report_only=true&env=#{ENV['RACK_ENV']}" end ``` Every parameter in the URL is optional, aside from the `api_key` parameter. If you don’t need the value to be generated at request time (as in this example, to report the current user’s id), then you can provide a simple string as the argument to `report_uri`. If you set the `report_only` parameter to true, then our UI will label reports as “CSP Report”; otherwise, they will be labeled as “CSP Error”. CSP Reports and Errors show up with the rest of your app’s errors in the Honeybadger UI. For this reason, and since CSP reports can be very numerous, we recommend you create a separate Honeybadger project specifically for CSP reports. # Architecture deep-dive > Learn about Honeybadger's Ruby gem architecture, threading model, and how error reporting works internally. This guide explains the architecture of the [*honeybadger* Ruby gem](https://github.com/honeybadger-io/honeybadger-ruby), and how it interacts with your application. ## Who is this guide for? [Section titled “Who is this guide for?”](#who-is-this-guide-for) This guide is for anyone interested in learning about how our gem works internally or is attempting to debug/rule out a gem-related issue. ## The major components of the gem [Section titled “The major components of the gem”](#the-major-components-of-the-gem) The `honeybadger` gem has the following components: * `Notice` — Represents a single exception/error report * `Backend` — Responsible for reporting a `Notice` to the honeybadger.io API * `Queue` — A first-in-first-out (FIFO) queue which drops items after reaching a maximum size * `Worker` — A single-threaded worker that is responsible for processing `Notice` items in the `Queue` and notifying the `Backend` * `Initializer` — An integration with a detected framework (such as Rails) * `Plugin` — An isolated integration with a Ruby or 3rd party gem feature * `Config` — The user [configuration](/lib/ruby/gem-reference/configuration/) for the gem * `Agent` — An instance of the gem composed of a `Config` and a `Worker` (multiple `Agents` are supported, but are uncommon) * `Honeybadger` — The global singleton `Agent` ## What happens when your app boots [Section titled “What happens when your app boots”](#what-happens-when-your-app-boots) The gem has two modes of booting: 1. **Normal mode**: loads `Initializers`, `Config`, and `Plugins` automatically (this is what we’ll be discussing here) 2. [Plain Ruby Mode](/lib/ruby/getting-started/plain-ruby-mode/): Skips automatically loading `Initializers`, `Config`, and `Plugins` If your app is configured to `require 'honeybadger'` (the default when you install our gem), then it boots in **Normal Mode**. Here is the order of events in a Rails app: 1. When `'honeybadger'` is required, we immediately: 2. Detect your framework (Rails, Sinatra, etc.) and load the respective `Initializer` 3. Load our Rake `Initializer` if Rake is present in your application 4. Install our global `at_exit` handler 5. As Rails initializes, our Rack middleware are inserted in the Rails middleware stack via the `honeybadger.install_middleware` initializer (see our [Railtie](https://github.com/honeybadger-io/honeybadger-ruby/blob/master/lib/honeybadger/init/rails.rb)) 6. Rails finishes initializing 7. Honeybadger reads `Config` from supported sources 8. Honeybadger loads `Plugins` 9. Rails finishes booting ## The life cycle of an exception [Section titled “The life cycle of an exception”](#the-life-cycle-of-an-exception) The *honeybadger* gem integrates with popular frameworks and libraries to automatically report exceptions when they occur. Examples of where this can happen: * Rails and Sinatra requests * Background jobs (ActiveJob, Sidekiq, Resque, etc.) * Rake tasks * Ruby crashes (via our global `at_exit` handler) Here is the order of events when an unhandled exception occurs in one of these scenarios: 1. The exception is reported to the global singleton `Agent` using [`Honeybadger.notify`](https://www.rubydoc.info/gems/honeybadger/Honeybadger/Agent#notify-instance_method) 2. A `Notice` is built from the exception and any other data passed to `Honeybadger.notify`, `Honeybadger.context`, `Honeybadger.add_breadcrumb`, etc. 3. Configured [`before_notify` callbacks](/lib/ruby/gem-reference/configuration/#changing-notice-data) are executed, passing the `Notice` to each callback (which may modify it) 4. If the `Notice` is ignored via `Config`, `before_notify` callbacks, etc., then it’s immediately dropped. Otherwise, it’s pushed to the `Worker`. 5. The `Worker` processes each `Notice` in the order that it was added to its `Queue`. The `Queue` holds up to 100 `Notices` by default (this number is configurable via the [`max_queue_size` option](/lib/ruby/gem-reference/configuration/#configuration-options)). If the number of `Notices` in the `Queue` equals the `max_queue_size`, new `Notices` are dropped until the number is reduced. 6. When the `Worker` processes a notice, it removes it from the `Queue`, passes it to the `Backend`, and waits for a response from the honeybadger.io API: 1. `429`, `503` (throttled): Applies an exponential throttle of `1.05`. When a throttle is added, the `Worker` will briefly pause between processing each `Notice` in the `Queue`. Additional throttles are added until the server stops throttling the client. Each new throttle multiplies the previous throttle by `1.05`; for example, three `429` responses would result in a \~0.158-second pause (`((1.05*1.05*1.05)-1)`—we subtract 1 to account for the initial throttle). 2. `402`, `403` (payment required/invalid API key): Suspends the `Worker` for 1 hour. During this time, all `Notices` are dropped. 3. `201` (success): if throttled, one throttle per `201` response is removed until the `Worker` is back to processing the `Queue` in real-time. ## What happens when your app shuts down [Section titled “What happens when your app shuts down”](#what-happens-when-your-app-shuts-down) Honeybadger performs the following via our global `at_exit` handler: 1. If there is an exception that is crashing the Ruby process, it’s reported to `Honeybadger.notify`, which calls the backend synchronously (it skips the `Worker`) 2. The `Worker` shuts down. By default, it will wait to process remaining exceptions in the `Queue`. [See `send_data_at_exit` and `max_queue_size`](/lib/ruby/gem-reference/configuration/#configuration-options) # Frequently asked questions > Find answers to frequently asked questions about Honeybadger's Ruby gem for error tracking and application monitoring. ## Why aren’t my errors being reported? [Section titled “Why aren’t my errors being reported?”](#why-arent-my-errors-being-reported) The most common reason for errors not being reported is that the gem is in a development environment. See the [Environments](/lib/ruby/errors/environments/#development-environments) chapter in the **Getting Started** guide for more information. The second most common reason is that the error being reported is on the [default ignored exceptions list](/lib/ruby/errors/ignoring-errors/#ignore-by-class). We also don’t capture errors in a Ruby console (IRB, pry, etc..) by default, even in production. If neither of these is the issue, check out the [Troubleshooting guide](/lib/ruby/support/troubleshooting/#my-errors-arent-being-reported). ## Why aren’t I getting notifications? [Section titled “Why aren’t I getting notifications?”](#why-arent-i-getting-notifications) By default we only send notifications the first time an exception happens, and when it re-occurs after being marked resolved. If an exception happens 100 times, but was never resolved you’ll only get 1 email about it. ## Can I use Honeybadger outside of Rails, such as in my gem? [Section titled “Can I use Honeybadger outside of Rails, such as in my gem?”](#can-i-use-honeybadger-outside-of-rails-such-as-in-my-gem) Yes! All our gem needs to report errors is a supported Ruby version; there are no other hard dependencies. We detect and integrate with optional dependencies such as Rails by default, but if you want complete control of the initialization process you can use [Plain Ruby Mode](/lib/ruby/getting-started/plain-ruby-mode/). See the [API Reference](https://www.rubydoc.info/gems/honeybadger/Honeybadger/Agent) for all the methods you can use to report errors from anywhere in Ruby. ## After enabling Insights, I see a lot of extra console output during my builds. How can I silence this? [Section titled “After enabling Insights, I see a lot of extra console output during my builds. How can I silence this?”](#after-enabling-insights-i-see-a-lot-of-extra-console-output-during-my-builds-how-can-i-silence-this) If you enabled Insights via your `config/honeybadger.yml` file, you may see extra output in your console during builds (such as asset compile in Docker). This is because the Honeybadger Insights agent is running as configured. You can temporarily disable Insights during your builds by setting the `HONEYBADGER_INSIGHTS_ENABLED` environment variable to `false`. ```bash HONEYBADGER_INSIGHTS_ENABLED=false bundle exec rake assets:precompile ``` Alternatively, instead of configuring Insights in your `config/honeybadger.yml` file, you can enable it via the `HONEYBADGER_INSIGHTS_ENABLED` environment variable in your proudction environment. This way, Insights will only be enabled in production. # Troubleshooting > Troubleshoot common issues with Honeybadger's Ruby gem and resolve integration problems. Common issues/workarounds are documented here. If you don’t find a solution to your problem here or in our [support documentation](../../#getting-support), email and we’ll assist you! ## Upgrade the gem [Section titled “Upgrade the gem”](#upgrade-the-gem) Before digging deeper into this guide, **make sure you are on the latest minor release of the honeybadger gem** (i.e. 3.x.x). There’s a chance you’ve found a bug which has already been fixed! ## Send a test exception [Section titled “Send a test exception”](#send-a-test-exception) You can send a test exception using the `honeybadger` command line utility: ```bash honeybadger test ``` ## How to enable verbose logging [Section titled “How to enable verbose logging”](#how-to-enable-verbose-logging) Troubleshooting any of these issues will be much easier if you can see what’s going on with Honeybadger when your app starts. To enable verbose debug logging, run your app with the `HONEYBADGER_DEBUG=true` environment variable or add the following to your *honeybadger.yml* file: ```yaml debug: true ``` By default Honeybadger will log to the default Rails logger or STDOUT outside of Rails. When debugging it can be helpful to have a dedicated log file for Honeybadger. To enable one, set the `HONEYBADGER_LOGGING_PATH=log/honeybadger.log` environment variable or add the following to your *honeybadger.yml* file: ```yaml logging: path: "log/honeybadger.log" ``` ## Common issues [Section titled “Common issues”](#common-issues) ### My errors aren’t being reported [Section titled “My errors aren’t being reported”](#my-errors-arent-being-reported) Error reporting may be disabled for several reasons: #### Honeybadger is not configured [Section titled “Honeybadger is not configured”](#honeybadger-is-not-configured) Honeybadger requires at minimum the `api_key` option to be set. If Honeybadger is unable to start due to invalid configuration, you should see something like the following in your logs: ```plaintext ** [Honeybadger] Unable to start Honeybadger -- api_key is missing or invalid. level=2 pid=18195 ``` #### Honeybadger is in a development environment [Section titled “Honeybadger is in a development environment”](#honeybadger-is-in-a-development-environment) Errors are ignored by default in the “test”, “development”, and “cucumber” environments. To explicitly enable Honeybadger in a development environment, set the `HONEYBADGER_REPORT_DATA=true` environment variable or add the following configuration to *honeybadger.yml* file (change “development” to the name of the environment you want to enable): ```yaml development: report_data: true ``` #### The error is ignored by default [Section titled “The error is ignored by default”](#the-error-is-ignored-by-default) Honeybadger ignores [this list of exceptions](https://github.com/honeybadger-io/honeybadger-ruby/blob/master/lib/honeybadger/config/defaults.rb#L7) by default. #### The error was rescued without re-raising [Section titled “The error was rescued without re-raising”](#the-error-was-rescued-without-re-raising) Honeybadger will automatically report exceptions in many frameworks including Rails, Sinatra, Sidekiq, Rake, etc. For exceptions to reported automatically they must be raised; check for any `rescue` statements in your app where exceptions may be potentially silenced. In Rails, this includes any use of `rescue_from` which does not re-raise the exception. Errors which are handled in a `rescue` block without re-raising must be reported to Honeybadger manually: ```ruby begin fail 'This error will be handled internally.' rescue => e Honeybadger.notify(e) end ``` #### The configuration is being overridden [Section titled “The configuration is being overridden”](#the-configuration-is-being-overridden) Check to make sure that you aren’t overriding the *honeybadger.yml* configuration file via Ruby configuration using `Honeybadger.configure`, or using an environment variable (`HONEYBADGER_API_KEY`, for instance). For example, the Honeybadger Heroku addon sets the `HONEYBADGER_API_KEY` config option automatically, so you must remove the addon (or the config option) if you switch to a Honeybadger project with a different API key. #### A rake task is running in a local terminal [Section titled “A rake task is running in a local terminal”](#a-rake-task-is-running-in-a-local-terminal) By default, the Honeybadger rake integration reports errors that happen when running *outside* of a terminal, such as in a cron job or scheduled task. The integration does *not* report errors which happen when running rake manually from a terminal (i.e., if you SSH into a production server to run the task). [To report exceptions all the time, set the `exceptions.rescue_rake` config option to `true`](/lib/ruby/gem-reference/configuration/#configuration-options). #### The `better_errors` gem is installed [Section titled “The better\_errors gem is installed”](#the-better_errors-gem-is-installed) The [`better_errors` gem](https://github.com/charliesome/better_errors) conflicts with the Honeybadger gem when in development mode. To be able to report errors from development you must first temporarily disable/remove the `better_errors` gem. Better Errors should not affect production because it should never be enabled in production. ### I’m not receiving notifications [Section titled “I’m not receiving notifications”](#im-not-receiving-notifications) Likewise, if the error is reported but your aren’t being notified: #### The error was reported already and is unresolved [Section titled “The error was reported already and is unresolved”](#the-error-was-reported-already-and-is-unresolved) By default we only send notifications the first time an exception happens, and when it re-occurs after being marked resolved. If an exception happens 100 times, but was never resolved you’ll only get 1 email about it. ### `SignalException` or `SystemExit` is reported when a process or rake task exits [Section titled “SignalException or SystemExit is reported when a process or rake task exits”](#signalexception-or-systemexit-is-reported-when-a-process-or-rake-task-exits) The Honeybadger gem currently [ignores signal exceptions](https://github.com/honeybadger-io/honeybadger-ruby/blob/v4.2.1/lib/honeybadger/singleton.rb#L91) in our `at_exit` callback, which is installed by default whenever Honeybadger is loaded. We do not ignore these exceptions anywhere else, such as in Rake tasks. If you would like to ignore them globally, you can add the following configuration to `honeybadger.yml`: ```yaml exceptions: ignore: - !ruby/class "SystemExit" - !ruby/class "SignalException" ``` * Related: [#306](https://github.com/honeybadger-io/honeybadger-ruby/issues/306) ## Sidekiq/Resque/ActiveJob/etc. [Section titled “Sidekiq/Resque/ActiveJob/etc.”](#sidekiqresqueactivejobetc) * See [Common Issues](#common-issues) ### If the error is ignored by default [Section titled “If the error is ignored by default”](#if-the-error-is-ignored-by-default) Honeybadger ignores [this list of exceptions](https://github.com/honeybadger-io/honeybadger-ruby/blob/master/lib/honeybadger/config/defaults.rb#L7) by default. It may be surprising that `ActiveRecord::RecordNotFound` is on that list; that’s because in a Rails controller that error class is treated as a 404 not-found and handled internally (and thus we shouldn’t report it). Support for Sidekiq and friends was added later and inherited the default. We would like to provide alternate defaults for job processors in the future, but for now you can provide your own list of ignored class names if you want to change this behavior: ```plaintext HONEYBADGER_EXCEPTIONS_IGNORE_ONLY=Error,ClassNames,Here bundle exec sidekiq ``` ## Command line utility [Section titled “Command line utility”](#command-line-utility) If you get an error while running the `honeybadger` command line utility: 1. Try prefixing the command with `bundle exec`…even if you normally rely on bin-stubs to do this for you 2. Check `honeybadger help` if you’re having trouble with the syntax for a specific command. 3. Try enabling [verbose logging](#how-to-enable-verbose-logging) to get more info 4. Ask Us! We’re always here to help. Just copy the terminal output and email it to us at ## Wrong controller/action name is reported in Rails [Section titled “Wrong controller/action name is reported in Rails”](#wrong-controlleraction-name-is-reported-in-rails) If you’re using `config.exceptions_app`, you may need some extra config to report the correct controller and action to Honeybadger. See the [Rails integration guide](/lib/ruby/integration-guides/rails-exception-tracking/#if-you-use-configexceptions_app). * Related: [#250](https://github.com/honeybadger-io/honeybadger-ruby/issues/250#issuecomment-379780492) ## My issue isn’t here [Section titled “My issue isn’t here”](#my-issue-isnt-here) For a deep-dive into how the [*honeybadger* gem](https://github.com/honeybadger-io/honeybadger-ruby/) works, check out the [Architecture Guide](/lib/ruby/support/architecture/). If you’re stuck, shoot us an: # Honeybadger CLI > Use the Honeybadger CLI for command-line access to check-ins, deployments, metrics collection, and data queries. The [Honeybadger CLI](https://github.com/honeybadger-io/cli) gives you command-line access to the Honeybadger API for check-ins, deployments, metrics collection, and data queries. If you’ve been using our [MCP server](/resources/mcp/) to integrate Honeybadger with AI agents, the CLI offers a similar feature set for direct terminal use. ## Installation [Section titled “Installation”](#installation) The quickest way to install is via Homebrew: ```shell brew install honeybadger-io/tap/honeybadger ``` You can also download binaries directly from the [GitHub releases page](https://github.com/honeybadger-io/cli/releases) or install with Go: ```shell go install github.com/honeybadger-io/cli/cmd/hb@latest ``` This installs the `hb` command. ## Authentication [Section titled “Authentication”](#authentication) The CLI uses two types of credentials depending on which commands you’re running: * **Project API key** — For Reporting API commands (`deploy`, `agent`). Find your key in your [project settings](https://app.honeybadger.io/). * **Personal auth token** — For Data API commands (everything else). Find your token under the “Authentication” tab in your [user settings](https://app.honeybadger.io/users/edit#authentication). You can provide credentials via environment variables, a configuration file, or command-line flags: ### Environment Variables [Section titled “Environment Variables”](#environment-variables) ```shell export HONEYBADGER_API_KEY=your-project-api-key # For Reporting API export HONEYBADGER_AUTH_TOKEN=your-personal-token # For Data API export HONEYBADGER_PROJECT_ID=12345 # Optional, default project ID for Data API export HONEYBADGER_ENDPOINT=https://eu-api.honeybadger.io # Optional, for EU region ``` ### Configuration File [Section titled “Configuration File”](#configuration-file) Create a file at `~/.honeybadger-cli.yaml`: ```yaml api_key: your-project-api-key auth_token: your-personal-auth-token project_id: 12345 endpoint: https://api.honeybadger.io ``` ### Command-line Flags [Section titled “Command-line Flags”](#command-line-flags) * `--api-key` — Project API key (for Reporting API) * `--auth-token` — Personal auth token (for Data API) * `--project-id` — Default project ID for Data API commands * `--endpoint` — API endpoint (default: `https://api.honeybadger.io`) * `--config` — Path to configuration file *** ## Reporting API Commands [Section titled “Reporting API Commands”](#reporting-api-commands) These commands use your project API key (`--api-key` or `HONEYBADGER_API_KEY`). ### agent [Section titled “agent”](#agent) Start a metrics reporting agent that collects system metrics and reports them to [Honeybadger Insights](/guides/insights/). ```shell hb agent --api-key PROJECT_API_KEY ``` Or with an environment variable: ```shell export HONEYBADGER_API_KEY=PROJECT_API_KEY hb agent ``` **Metrics collected:** * **CPU** — Usage percentages and load averages * **Memory** — Total, used, free, and available memory * **Disk** — Usage for all mounted filesystems **Optional flags:** * `-i, --interval` — Reporting interval in seconds (default: `60`) * `-t, --tag` — Tag in `key=value` format (repeatable) **Tagging metrics:** Add custom tags to annotate metrics with environment, role, or other metadata: ```shell hb agent --tag environment=production --tag role=web-1 ``` Tags appear as top-level fields on every metric event, so you can filter and group by them in [Insights](/guides/insights/) queries. You can also use `--tag host=custom-name` to override the default hostname. Tags can also be set in the configuration file: ```yaml agent: tags: environment: production role: web-1 ``` CLI flags take precedence over configuration file tags. Tag keys cannot collide with built-in metric field names (such as `event_type` or `used_percent`), with the exception of `host`. See [Host metrics](/guides/insights/integrations/host-metrics/) for query examples and alternative collection methods. ### deploy [Section titled “deploy”](#deploy) Report a deployment to Honeybadger. ```shell hb deploy --environment production --repository github.com/org/repo --revision abc123 --user johndoe ``` **Required flags:** * `-e, --environment` — Environment being deployed to (e.g., `production`) **Optional flags:** * `-r, --repository` — Repository being deployed * `-v, --revision` — Revision or commit SHA being deployed * `-u, --user` — Local username of the person deploying ### run [Section titled “run”](#run) Run a command and report its status to Honeybadger’s [check-in API](/api/reporting-check-ins/). This wraps your command, captures its output and execution time, and reports the results. ```shell hb run --id XyZZy -- /usr/local/bin/backup.sh ``` Or using a slug (requires API key): ```shell hb run --slug daily-backup --api-key PROJECT_API_KEY -- pg_dump -U postgres mydb > backup.sql ``` The command will: * Execute your command and stream its output in real-time * Capture stdout, stderr, duration, and exit code * Report success or error status to Honeybadger * Exit with the same exit code as your command **Required flags (one of):** * `-i, --id` — Check-in ID to report * `-s, --slug` — Check-in slug to report (requires API key) Shell operators such as `>` are interpreted by your shell before `hb` runs, so redirection works as usual. If you need more complex shell features, wrap them in a shell script and invoke that script with `hb run`. ### check-in [Section titled “check-in”](#check-in) Report a simple check-in to Honeybadger without running a command. Use this when you want to signal that a task completed successfully from your own scripts. ```shell hb check-in --id XyZZy ``` Or using a slug (requires API key): ```shell hb check-in --slug daily-backup --api-key PROJECT_API_KEY ``` **Required flags (one of):** * `-i, --id` — Check-in ID to report * `-s, --slug` — Check-in slug to report (requires API key) See [Check-ins](/guides/check-ins/) for more information on setting up check-ins in Honeybadger. *** ## Data API Commands [Section titled “Data API Commands”](#data-api-commands) These commands use your personal auth token (`--auth-token` or `HONEYBADGER_AUTH_TOKEN`). Most also require a project ID (`--project-id` or `HONEYBADGER_PROJECT_ID`). | Command | Description | | -------------------------------------------- | ---------------------------------------- | | [accounts](/resources/cli/accounts/) | Manage accounts, users, and invitations | | [alarms](/resources/cli/alarms/) | Manage Insights alarms | | [check-ins](/resources/cli/check-ins/) | Manage check-ins for cron job monitoring | | [comments](/resources/cli/comments/) | Manage comments on faults | | [dashboards](/resources/cli/dashboards/) | Manage Insights dashboards | | [deployments](/resources/cli/deployments/) | View and manage deployment history | | [environments](/resources/cli/environments/) | Manage project environments | | [faults](/resources/cli/faults/) | View and manage faults (errors) | | [insights](/resources/cli/insights/) | Execute BadgerQL queries | | [projects](/resources/cli/projects/) | Manage projects and view reports | | [statuspages](/resources/cli/statuspages/) | Manage status pages | | [streams](/resources/cli/streams/) | List Insights data streams | | [teams](/resources/cli/teams/) | Manage teams and memberships | | [uptime](/resources/cli/uptime/) | Manage uptime monitoring | *** ## Output Formats [Section titled “Output Formats”](#output-formats) Most commands support the `-o, --output` flag: * `table` — Human-readable table format (default for list commands) * `json` — JSON output for scripting and automation * `text` — Plain text output (default for get commands) ## JSON Input [Section titled “JSON Input”](#json-input) Commands that accept `--cli-input-json` can receive input as: * Inline JSON: `--cli-input-json '{"key": "value"}'` * File path: `--cli-input-json file:///path/to/file.json` ## Additional resources [Section titled “Additional resources”](#additional-resources) * [Honeybadger CLI on GitHub](https://github.com/honeybadger-io/cli) — Source code and issue tracker * [Honeybadger MCP server](/resources/mcp/) — Integrate Honeybadger with AI assistants * [Honeybadger API documentation](/api/) — REST API reference # Accounts CLI reference > Manage Honeybadger accounts, users, and invitations from the command line. The `accounts` command lets you manage Honeybadger accounts, users, and invitations. ## List accounts [Section titled “List accounts”](#list-accounts) ```shell hb accounts list hb accounts list --output json ``` **Optional flags:** * `-o, --output` — Output format: `table` or `json` (default: `table`) ## Get account details [Section titled “Get account details”](#get-account-details) ```shell hb accounts get --id 12345 ``` **Required flags:** * `--id` — Account ID **Optional flags:** * `-o, --output` — Output format: `text` or `json` (default: `text`) *** ## Managing users [Section titled “Managing users”](#managing-users) ### List users for an account [Section titled “List users for an account”](#list-users-for-an-account) ```shell hb accounts users list --account-id 12345 ``` **Required flags:** * `--account-id` — Account ID **Optional flags:** * `-o, --output` — Output format: `table` or `json` (default: `table`) ### Get a specific user [Section titled “Get a specific user”](#get-a-specific-user) ```shell hb accounts users get --account-id 12345 --user-id 67890 ``` **Required flags:** * `--account-id` — Account ID * `--user-id` — User ID **Optional flags:** * `-o, --output` — Output format: `text` or `json` (default: `text`) ### Update a user’s role [Section titled “Update a user’s role”](#update-a-users-role) ```shell hb accounts users update --account-id 12345 --user-id 67890 --role Admin ``` **Required flags:** * `--account-id` — Account ID * `--user-id` — User ID * `--role` — New role: `Member`, `Billing`, `Admin`, or `Owner` **Optional flags:** * `-o, --output` — Output format: `text` or `json` (default: `text`) ### Remove a user from an account [Section titled “Remove a user from an account”](#remove-a-user-from-an-account) ```shell hb accounts users remove --account-id 12345 --user-id 67890 ``` **Required flags:** * `--account-id` — Account ID * `--user-id` — User ID *** ## Managing invitations [Section titled “Managing invitations”](#managing-invitations) ### List invitations [Section titled “List invitations”](#list-invitations) ```shell hb accounts invitations list --account-id 12345 ``` **Required flags:** * `--account-id` — Account ID **Optional flags:** * `-o, --output` — Output format: `table` or `json` (default: `table`) ### Get an invitation [Section titled “Get an invitation”](#get-an-invitation) ```shell hb accounts invitations get --account-id 12345 --invitation-id 11111 ``` **Required flags:** * `--account-id` — Account ID * `--invitation-id` — Invitation ID **Optional flags:** * `-o, --output` — Output format: `text` or `json` (default: `text`) ### Create an invitation [Section titled “Create an invitation”](#create-an-invitation) ```shell hb accounts invitations create --account-id 12345 --cli-input-json '{ "email": "user@example.com", "role": "Member", "team_ids": [111, 222] }' ``` **Required flags:** * `--account-id` — Account ID * `--cli-input-json` — JSON payload (inline string or `file://path`) **JSON fields:** * `email` — Email address to invite * `role` — Role for the new user: `Member`, `Billing`, `Admin`, or `Owner` * `team_ids` — Optional array of team IDs to add the user to **Optional flags:** * `-o, --output` — Output format: `text` or `json` (default: `text`) ### Update an invitation [Section titled “Update an invitation”](#update-an-invitation) ```shell hb accounts invitations update --account-id 12345 --invitation-id 11111 --cli-input-json '{"role": "Admin"}' ``` **Required flags:** * `--account-id` — Account ID * `--invitation-id` — Invitation ID * `--cli-input-json` — JSON payload with fields to update **Optional flags:** * `-o, --output` — Output format: `text` or `json` (default: `text`) ### Delete an invitation [Section titled “Delete an invitation”](#delete-an-invitation) ```shell hb accounts invitations delete --account-id 12345 --invitation-id 11111 ``` **Required flags:** * `--account-id` — Account ID * `--invitation-id` — Invitation ID # Alarms CLI reference > Manage Honeybadger Insights alarms and view their trigger history from the command line. The `alarms` command lets you view and manage [Insights alarms](/guides/insights/alarms/) for your projects. All alarms commands require `--project-id` (or `HONEYBADGER_PROJECT_ID`). ## List alarms [Section titled “List alarms”](#list-alarms) ```shell hb alarms list --project-id 12345 ``` **Required flags:** * `--project-id` — Project ID **Optional flags:** * `-o, --output` — Output format: `table` or `json` (default: `table`) ## Get alarm details [Section titled “Get alarm details”](#get-alarm-details) ```shell hb alarms get --project-id 12345 --id abc123 ``` **Required flags:** * `--project-id` — Project ID * `--id` — Alarm ID **Optional flags:** * `-o, --output` — Output format: `text` or `json` (default: `text`) ## Create an alarm [Section titled “Create an alarm”](#create-an-alarm) ```shell hb alarms create --project-id 12345 --cli-input-json '{ "alarm": { "name": "High Error Rate", "description": "Alert when errors spike", "query": "filter event_type::str == \"notice\"", "evaluation_period": "5m", "lookback_lag": "1m", "trigger_config": { "type": "alert_result_count", "config": { "operator": "gt", "value": 10 } } } }' ``` Or from a file: ```shell hb alarms create --project-id 12345 --cli-input-json file://alarm.json ``` **Required flags:** * `--project-id` — Project ID * `--cli-input-json` — JSON payload (inline string or `file://path`) **Optional flags:** * `-o, --output` — Output format: `text` or `json` (default: `text`) **JSON fields:** * `name` — Alarm name * `description` — Optional description, included in alarm notifications * `query` — [BadgerQL](/guides/insights/badgerql/) query whose results are evaluated * `stream_ids` — Optional list of [stream IDs](/api/streams/) to query. Omit it and the alarm queries every stream on the project. See [Scoping an alarm to specific streams](#scoping-an-alarm-to-specific-streams) below. * `evaluation_period` — How often the alarm is evaluated, and the window it looks back over (e.g., `5m`, `1h`, `1d`) * `lookback_lag` — Delay before each evaluation, so late-arriving data is counted (e.g., `1m`) * `trigger_config` — When the alarm triggers **Trigger config:** The only trigger type is `alert_result_count`, which compares the number of results the query returns against a threshold: ```json { "type": "alert_result_count", "config": { "operator": "gt", "value": 10 } } ``` Operators are `gt` (greater than), `gte`, `lt` (less than), `lte`, `eq`, and `neq`. ## Scoping an alarm to specific streams [Section titled “Scoping an alarm to specific streams”](#scoping-an-alarm-to-specific-streams) An alarm queries every stream on the project unless you pass `stream_ids`. To narrow it, get the IDs first: ```shell hb streams list --project-id 12345 ``` Then pass them in the payload: ```json { "stream_ids": ["pEFgoATf7kNq"] } ``` Use the opaque IDs from the `ID` column — not the slugs (`default`, `internal`) shown under `SLUG`. Unrecognized IDs are dropped without complaint, so a wrong one silently leaves the alarm watching fewer streams than you intended. If *every* ID you pass is unrecognized, nothing survives and the API rejects the alarm with a `422`. That rejection means the IDs weren’t recognized, not that the field is mandatory — passing a slug like `"default"` is the usual cause. Omitting `stream_ids` entirely is always valid. ## Update an alarm [Section titled “Update an alarm”](#update-an-alarm) ```shell hb alarms update --project-id 12345 --id abc123 --cli-input-json '{ "alarm": { "name": "Updated Alarm Name", "query": "filter event_type::str == \"notice\"", "evaluation_period": "10m", "lookback_lag": "1m", "trigger_config": { "type": "alert_result_count", "config": { "operator": "gt", "value": 25 } } } }' ``` **Required flags:** * `--project-id` — Project ID * `--id` — Alarm ID * `--cli-input-json` — JSON payload (inline string or `file://path`) ## Delete an alarm [Section titled “Delete an alarm”](#delete-an-alarm) ```shell hb alarms delete --project-id 12345 --id abc123 ``` This action cannot be undone. **Required flags:** * `--project-id` — Project ID * `--id` — Alarm ID ## View trigger history [Section titled “View trigger history”](#view-trigger-history) List the times an alarm has changed state. ```shell hb alarms history --project-id 12345 --id abc123 ``` **Required flags:** * `--project-id` — Project ID * `--id` — Alarm ID **Optional flags:** * `--page` — Page number for pagination * `-o, --output` — Output format: `table` or `json` (default: `table`) # Check-ins CLI reference > Manage Honeybadger check-ins for cron job and scheduled task monitoring. The `check-ins` command lets you manage check-ins for monitoring cron jobs and scheduled tasks. All check-ins commands require `--project-id`. Note To *report* a check-in, use the [`hb check-in`](/resources/cli/#check-in) command (Reporting API). The `check-ins` command is for viewing and managing existing check-ins. ## List check-ins [Section titled “List check-ins”](#list-check-ins) ```shell hb check-ins list --project-id 12345 ``` **Required flags:** * `--project-id` — Project ID **Optional flags:** * `-o, --output` — Output format: `table` or `json` (default: `table`) ## Get check-in details [Section titled “Get check-in details”](#get-check-in-details) ```shell hb check-ins get --project-id 12345 --id 67890 ``` **Required flags:** * `--project-id` — Project ID * `--id` — Check-in ID **Optional flags:** * `-o, --output` — Output format: `text` or `json` (default: `text`) ## Create a check-in [Section titled “Create a check-in”](#create-a-check-in) ### Simple schedule [Section titled “Simple schedule”](#simple-schedule) For jobs that run at regular intervals: ```shell hb check-ins create --project-id 12345 --cli-input-json '{ "name": "Daily backup", "slug": "daily-backup", "schedule_type": "simple", "report_period": "1440", "grace_period": "5" }' ``` ### Cron schedule [Section titled “Cron schedule”](#cron-schedule) For jobs with cron expressions: ```shell hb check-ins create --project-id 12345 --cli-input-json '{ "name": "Hourly job", "slug": "hourly-job", "schedule_type": "cron", "cron_schedule": "0 * * * *", "cron_timezone": "America/New_York", "grace_period": "5" }' ``` **Required flags:** * `--project-id` — Project ID * `--cli-input-json` — JSON payload (inline string or `file://path`) **JSON fields:** * `name` — Display name for the check-in * `slug` — URL-safe identifier used in the check-in URL * `schedule_type` — Either `simple` or `cron` * `report_period` — For simple schedules: expected interval in minutes * `grace_period` — Minutes to wait before alerting * `cron_schedule` — For cron schedules: cron expression * `cron_timezone` — For cron schedules: timezone (e.g., `America/New_York`) **Optional flags:** * `-o, --output` — Output format: `text` or `json` (default: `text`) ## Update a check-in [Section titled “Update a check-in”](#update-a-check-in) ```shell hb check-ins update --project-id 12345 --id 67890 --cli-input-json '{"name": "Updated name"}' ``` **Required flags:** * `--project-id` — Project ID * `--id` — Check-in ID * `--cli-input-json` — JSON payload with fields to update **Optional flags:** * `-o, --output` — Output format: `text` or `json` (default: `text`) ## Delete a check-in [Section titled “Delete a check-in”](#delete-a-check-in) ```shell hb check-ins delete --project-id 12345 --id 67890 ``` **Required flags:** * `--project-id` — Project ID * `--id` — Check-in ID # Comments CLI reference > Manage comments on Honeybadger faults from the command line. The `comments` command lets you manage comments on faults. All comments commands require both `--project-id` and `--fault-id`. ## List comments [Section titled “List comments”](#list-comments) ```shell hb comments list --project-id 12345 --fault-id 67890 ``` **Required flags:** * `--project-id` — Project ID * `--fault-id` — Fault ID **Optional flags:** * `-o, --output` — Output format: `table` or `json` (default: `table`) ## Get a comment [Section titled “Get a comment”](#get-a-comment) ```shell hb comments get --project-id 12345 --fault-id 67890 --id 11111 ``` **Required flags:** * `--project-id` — Project ID * `--fault-id` — Fault ID * `--id` — Comment ID **Optional flags:** * `-o, --output` — Output format: `text` or `json` (default: `text`) ## Create a comment [Section titled “Create a comment”](#create-a-comment) ```shell hb comments create --project-id 12345 --fault-id 67890 --body "This is a comment" ``` **Required flags:** * `--project-id` — Project ID * `--fault-id` — Fault ID * `--body` — Comment text **Optional flags:** * `-o, --output` — Output format: `text` or `json` (default: `text`) ## Update a comment [Section titled “Update a comment”](#update-a-comment) ```shell hb comments update --project-id 12345 --fault-id 67890 --id 11111 --body "Updated comment" ``` **Required flags:** * `--project-id` — Project ID * `--fault-id` — Fault ID * `--id` — Comment ID * `--body` — New comment text **Optional flags:** * `-o, --output` — Output format: `text` or `json` (default: `text`) ## Delete a comment [Section titled “Delete a comment”](#delete-a-comment) ```shell hb comments delete --project-id 12345 --fault-id 67890 --id 11111 ``` **Required flags:** * `--project-id` — Project ID * `--fault-id` — Fault ID * `--id` — Comment ID # Dashboards CLI reference > Manage Honeybadger Insights dashboards and their widgets from the command line. The `dashboards` command lets you view and manage [Insights dashboards](/guides/insights/#working-with-dashboards) for your projects. All dashboards commands require `--project-id` (or `HONEYBADGER_PROJECT_ID`). ## List dashboards [Section titled “List dashboards”](#list-dashboards) ```shell hb dashboards list --project-id 12345 ``` **Required flags:** * `--project-id` — Project ID **Optional flags:** * `-o, --output` — Output format: `table` or `json` (default: `table`) ## Get dashboard details [Section titled “Get dashboard details”](#get-dashboard-details) ```shell hb dashboards get --project-id 12345 --id abc123 ``` The default `text` output summarizes the dashboard and lists its widgets. Use `--output json` to get the full widget definitions — that’s the form `hb dashboards update --cli-input-json` expects. **Required flags:** * `--project-id` — Project ID * `--id` — Dashboard ID **Optional flags:** * `-o, --output` — Output format: `text` or `json` (default: `text`) ## Create a dashboard [Section titled “Create a dashboard”](#create-a-dashboard) ```shell hb dashboards create --project-id 12345 --cli-input-json '{ "dashboard": { "title": "Request Health", "default_ts": "P1D", "widgets": [ { "type": "insights_vis", "grid": { "x": 0, "y": 0, "w": 6, "h": 4 }, "presentation": { "title": "Errors Over Time" }, "config": { "streams": ["default"], "query": "filter event_type::str == \"notice\" | stats count() as count by bin(1h)", "vis": { "view": "line" } } } ] } }' ``` Or from a file: ```shell hb dashboards create --project-id 12345 --cli-input-json file://dashboard.json ``` **Required flags:** * `--project-id` — Project ID * `--cli-input-json` — JSON payload (inline string or `file://path`) **Optional flags:** * `-o, --output` — Output format: `text` or `json` (default: `text`) **JSON fields:** * `title` — Dashboard title * `default_ts` — Default time range for the dashboard (e.g., `P1D` for one day) * `widgets` — List of widget definitions **Widget fields:** * `type` — Widget type: `insights_vis`, `alarms`, `errors`, `deployments`, `checkins`, or `uptime` * `grid` — Position and size on a 12-column grid: `x`, `y`, `w`, `h`. Widgets must not overlap. * `presentation` — Display options, including the widget `title` * `config` — Widget configuration. The fields it accepts depend on the widget `type`. * `id` — Widget ID. Omit it on create and the server assigns one. An `insights_vis` widget — the primary building block, which renders a BadgerQL query as a chart or table — takes these `config` fields: * `streams` — Streams to query: `default`, `internal`, or both (defaults to `["default"]`) * `query` — The [BadgerQL](/guides/insights/badgerql/) query producing the widget’s data * `vis` — How to render the result: `{"view": ..., "chart_config": {...}}` The other widget types take their own fields, mostly a `limit` plus type-specific options. See the [dashboards API reference](/api/dashboards/) for more on widget structure. Dashboard structure is validated on save, and unknown keys anywhere in the dashboard, widget, or config objects are rejected. The payload is accepted either wrapped in a `{"dashboard": {...}}` envelope or as a bare dashboard object, so output from `hb dashboards get --output json` can be edited and passed straight back. ## Update a dashboard [Section titled “Update a dashboard”](#update-a-dashboard) Update **replaces** the dashboard rather than patching it, so send the complete widget list — any widget you omit is dropped. Both `title` and `widgets` are required; a payload carrying only one of them is refused rather than sent. The reliable workflow is to fetch the current state, edit it, and send it back: ```shell hb dashboards get --project-id 12345 --id abc123 --output json > dashboard.json # edit dashboard.json hb dashboards update --project-id 12345 --id abc123 --cli-input-json file://dashboard.json ``` Keep each existing widget’s `id` in the payload so it’s updated in place instead of being replaced by a newly assigned one. To remove every widget, pass `"widgets": []` explicitly. **Required flags:** * `--project-id` — Project ID * `--id` — Dashboard ID * `--cli-input-json` — JSON payload (inline string or `file://path`) ## Delete a dashboard [Section titled “Delete a dashboard”](#delete-a-dashboard) ```shell hb dashboards delete --project-id 12345 --id abc123 ``` This action cannot be undone. **Required flags:** * `--project-id` — Project ID * `--id` — Dashboard ID # Deployments CLI reference > View and manage Honeybadger deployment history from the command line. The `deployments` command lets you view and manage deployment history for your projects. All deployments commands require `--project-id`. Note To *report* a new deployment, use the [`hb deploy`](/resources/cli/#deploy) command (Reporting API). The `deployments` command is for viewing and managing existing deployment records. ## List deployments [Section titled “List deployments”](#list-deployments) ```shell hb deployments list --project-id 12345 ``` ### With filters [Section titled “With filters”](#with-filters) ```shell # Filter by environment hb deployments list --project-id 12345 --environment production # Filter by user hb deployments list --project-id 12345 --local-user johndoe # Filter by time range (Unix timestamps) hb deployments list --project-id 12345 --created-after 1704067200 --created-before 1706745600 # Limit results hb deployments list --project-id 12345 --limit 10 ``` **Required flags:** * `--project-id` — Project ID **Optional flags:** * `-e, --environment` — Filter by environment name * `--local-user` — Filter by deploying user * `--created-after` — Unix timestamp for start of range * `--created-before` — Unix timestamp for end of range * `--limit` — Maximum results (default: 25, max: 25) * `-o, --output` — Output format: `table` or `json` (default: `table`) ## Get deployment details [Section titled “Get deployment details”](#get-deployment-details) ```shell hb deployments get --project-id 12345 --id 67890 ``` **Required flags:** * `--project-id` — Project ID * `--id` — Deployment ID **Optional flags:** * `-o, --output` — Output format: `text` or `json` (default: `text`) ## Delete a deployment [Section titled “Delete a deployment”](#delete-a-deployment) ```shell hb deployments delete --project-id 12345 --id 67890 ``` **Required flags:** * `--project-id` — Project ID * `--id` — Deployment ID # Environments CLI reference > Manage Honeybadger project environments from the command line. The `environments` command lets you manage environments for your projects. All environments commands require `--project-id`. ## List environments [Section titled “List environments”](#list-environments) ```shell hb environments list --project-id 12345 ``` **Required flags:** * `--project-id` — Project ID **Optional flags:** * `-o, --output` — Output format: `table` or `json` (default: `table`) ## Get environment details [Section titled “Get environment details”](#get-environment-details) ```shell hb environments get --project-id 12345 --id 67890 ``` **Required flags:** * `--project-id` — Project ID * `--id` — Environment ID **Optional flags:** * `-o, --output` — Output format: `text` or `json` (default: `text`) ## Create an environment [Section titled “Create an environment”](#create-an-environment) ```shell hb environments create --project-id 12345 --cli-input-json '{ "name": "staging", "notifications": true }' ``` **Required flags:** * `--project-id` — Project ID * `--cli-input-json` — JSON payload (inline string or `file://path`) **JSON fields:** * `name` — Environment name * `notifications` — Whether to send notifications for this environment **Optional flags:** * `-o, --output` — Output format: `text` or `json` (default: `text`) ## Update an environment [Section titled “Update an environment”](#update-an-environment) ```shell hb environments update --project-id 12345 --id 67890 --cli-input-json '{"notifications": false}' ``` **Required flags:** * `--project-id` — Project ID * `--id` — Environment ID * `--cli-input-json` — JSON payload with fields to update **Optional flags:** * `-o, --output` — Output format: `text` or `json` (default: `text`) ## Delete an environment [Section titled “Delete an environment”](#delete-an-environment) ```shell hb environments delete --project-id 12345 --id 67890 ``` **Required flags:** * `--project-id` — Project ID * `--id` — Environment ID # Faults CLI reference > View and manage Honeybadger faults (errors) from the command line. The `faults` command lets you view and manage faults (errors) in your projects. All faults commands require `--project-id`. ## List faults [Section titled “List faults”](#list-faults) ```shell hb faults list --project-id 12345 ``` ### With search and ordering [Section titled “With search and ordering”](#with-search-and-ordering) ```shell # Search for specific error classes hb faults list --project-id 12345 --query "class:RuntimeError" # Sort by frequency instead of recency hb faults list --project-id 12345 --order frequent # Limit results hb faults list --project-id 12345 --limit 10 ``` **Required flags:** * `--project-id` — Project ID **Optional flags:** * `-q, --query` — Search query string * `--order` — Sort order: `recent` or `frequent` (default: `recent`) * `--limit` — Maximum results (default: 25, max: 25) * `-o, --output` — Output format: `table` or `json` (default: `table`) ## Get fault details [Section titled “Get fault details”](#get-fault-details) ```shell hb faults get --project-id 12345 --id 67890 ``` **Required flags:** * `--project-id` — Project ID * `--id` — Fault ID **Optional flags:** * `-o, --output` — Output format: `text` or `json` (default: `text`) ## List notices for a fault [Section titled “List notices for a fault”](#list-notices-for-a-fault) View individual error occurrences for a fault: ```shell hb faults notices --project-id 12345 --id 67890 hb faults notices --project-id 12345 --id 67890 --limit 10 ``` **Required flags:** * `--project-id` — Project ID * `--id` — Fault ID **Optional flags:** * `--limit` — Maximum results (default: 25, max: 25) * `-o, --output` — Output format: `table` or `json` (default: `table`) ## Get fault counts [Section titled “Get fault counts”](#get-fault-counts) Get aggregated fault counts for a project: ```shell hb faults counts --project-id 12345 ``` **Required flags:** * `--project-id` — Project ID **Optional flags:** * `-o, --output` — Output format: `text` or `json` (default: `text`) ## List affected users [Section titled “List affected users”](#list-affected-users) View users affected by a specific fault: ```shell hb faults affected-users --project-id 12345 --id 67890 # Search for a specific user hb faults affected-users --project-id 12345 --id 67890 --query "user@example.com" ``` **Required flags:** * `--project-id` — Project ID * `--id` — Fault ID **Optional flags:** * `-q, --query` — Search query to filter users * `-o, --output` — Output format: `table` or `json` (default: `table`) # Insights CLI reference > Execute BadgerQL queries against your Honeybadger Insights data from the command line. The `insights` command lets you execute BadgerQL queries against your Honeybadger Insights data. ## Query Insights data [Section titled “Query Insights data”](#query-insights-data) ```shell hb insights query --project-id 12345 --query "fields @ts, @preview | sort @ts" ``` ### With timezone [Section titled “With timezone”](#with-timezone) ```shell hb insights query --project-id 12345 \ --query "fields @ts, @preview | sort @ts" \ --timezone "America/New_York" ``` ### Restricted to specific streams [Section titled “Restricted to specific streams”](#restricted-to-specific-streams) ```shell hb insights query --project-id 12345 \ --query "fields @ts, @preview | sort @ts" \ --stream-ids abc123,def456 ``` ### With timestamp filter [Section titled “With timestamp filter”](#with-timestamp-filter) ```shell hb insights query --project-id 12345 \ --query "fields @ts, @preview | sort @ts" \ --ts "2024-01-15T00:00:00Z" ``` ### Output as JSON [Section titled “Output as JSON”](#output-as-json) ```shell hb insights query --project-id 12345 \ --query "fields @ts, @preview" \ --output json ``` **Required flags:** * `--project-id` — Project ID * `-q, --query` — BadgerQL query to execute **Optional flags:** * `--ts` — Timestamp in RFC3339 format * `--timezone` — Timezone for results (e.g., `America/New_York`) * `--stream-ids` — Comma-separated stream IDs to restrict the query to (see [`hb streams list`](/resources/cli/streams/)) * `-o, --output` — Output format: `table` or `json` (default: `table`) ## Example queries [Section titled “Example queries”](#example-queries) ### Recent errors [Section titled “Recent errors”](#recent-errors) ```shell hb insights query --project-id 12345 \ --query "filter @type = 'error' | fields @ts, error.class, error.message | sort @ts desc | limit 10" ``` ### Count by error class [Section titled “Count by error class”](#count-by-error-class) ```shell hb insights query --project-id 12345 \ --query "filter @type = 'error' | stats count() by error.class" ``` ### Host metrics [Section titled “Host metrics”](#host-metrics) ```shell hb insights query --project-id 12345 \ --query "filter @type = 'metric' | fields @ts, cpu.usage, memory.used | sort @ts desc" ``` See the [Insights documentation](/guides/insights/) and [BadgerQL reference](/guides/insights/badgerql/) for more query examples. # Projects CLI reference > Manage Honeybadger projects from the command line. The `projects` command lets you manage Honeybadger projects and view reports. ## List projects [Section titled “List projects”](#list-projects) ```shell hb projects list # Filter by account hb projects list --account-id 12345 ``` **Optional flags:** * `--account-id` — Filter projects by account ID * `-o, --output` — Output format: `table` or `json` (default: `table`) ## Get project details [Section titled “Get project details”](#get-project-details) ```shell hb projects get --id 12345 ``` **Required flags:** * `--id` — Project ID **Optional flags:** * `-o, --output` — Output format: `text` or `json` (default: `text`) ## Create a project [Section titled “Create a project”](#create-a-project) ```shell hb projects create --account-id 12345 --cli-input-json '{ "project": { "name": "My Project", "language": "ruby", "resolve_errors_on_deploy": true } }' # Or from a file hb projects create --account-id 12345 --cli-input-json file://project.json ``` **Required flags:** * `--account-id` — Account ID to create the project in * `--cli-input-json` — JSON payload (inline string or `file://path`) **JSON fields:** * `name` — Project name * `language` — Programming language * `resolve_errors_on_deploy` — Auto-resolve errors on deploy * `disable_public_links` — Disable public error links * `user_url` — URL template for user links (e.g., `https://myapp.com/users/[user_id]`) * `source_url` — URL template for source links (e.g., `https://github.com/org/repo/blob/main/[filename]#L[line]`) * `purge_days` — Days to retain data * `user_search_field` — Field to use for user search **Optional flags:** * `-o, --output` — Output format: `text` or `json` (default: `text`) ## Update a project [Section titled “Update a project”](#update-a-project) ```shell hb projects update --id 12345 --cli-input-json '{"project": {"name": "New Name"}}' ``` **Required flags:** * `--id` — Project ID * `--cli-input-json` — JSON payload with fields to update **Optional flags:** * `-o, --output` — Output format: `text` or `json` (default: `text`) ## Delete a project [Section titled “Delete a project”](#delete-a-project) ```shell hb projects delete --id 12345 ``` **Required flags:** * `--id` — Project ID *** ## Get occurrence counts [Section titled “Get occurrence counts”](#get-occurrence-counts) View error occurrence counts across projects: ```shell # All projects hb projects occurrences --period day --environment production # Specific project hb projects occurrences --id 12345 --period hour ``` **Optional flags:** * `--id` — Project ID (omit for all projects) * `--period` — Time period: `hour`, `day`, `week`, or `month` (default: `day`) * `--environment` — Filter by environment * `-o, --output` — Output format: `table` or `json` (default: `table`) ## Get integrations [Section titled “Get integrations”](#get-integrations) List integrations configured for a project: ```shell hb projects integrations --id 12345 ``` **Required flags:** * `--id` — Project ID **Optional flags:** * `-o, --output` — Output format: `table` or `json` (default: `table`) ## Get reports [Section titled “Get reports”](#get-reports) Generate reports for a project: ```shell hb projects reports --id 12345 --type notices_per_day \ --start 2024-01-01T00:00:00Z \ --stop 2024-01-31T23:59:59Z ``` **Required flags:** * `--id` — Project ID * `--type` — Report type: * `notices_by_class` — Errors grouped by class * `notices_by_location` — Errors grouped by location * `notices_by_user` — Errors grouped by user * `notices_per_day` — Error count over time **Optional flags:** * `--start` — Start time in RFC3339 format * `--stop` — Stop time in RFC3339 format * `--environment` — Filter by environment * `-o, --output` — Output format: `table` or `json` (default: `table`) # Status pages CLI reference > Manage Honeybadger status pages from the command line. The `statuspages` command lets you manage status pages for your accounts. All statuspages commands require `--account-id`. ## List status pages [Section titled “List status pages”](#list-status-pages) ```shell hb statuspages list --account-id 12345 ``` **Required flags:** * `--account-id` — Account ID **Optional flags:** * `-o, --output` — Output format: `table` or `json` (default: `table`) ## Get status page details [Section titled “Get status page details”](#get-status-page-details) ```shell hb statuspages get --account-id 12345 --id 67890 ``` **Required flags:** * `--account-id` — Account ID * `--id` — Status page ID **Optional flags:** * `-o, --output` — Output format: `text` or `json` (default: `text`) ## Create a status page [Section titled “Create a status page”](#create-a-status-page) ```shell hb statuspages create --account-id 12345 --cli-input-json '{ "name": "My Status Page", "domain": "status.example.com", "sites": [111, 222], "check_ins": [333], "hide_branding": false }' ``` **Required flags:** * `--account-id` — Account ID * `--cli-input-json` — JSON payload (inline string or `file://path`) **JSON fields:** * `name` — Status page name * `domain` — Custom domain for the status page * `sites` — Array of uptime site IDs to include * `check_ins` — Array of check-in IDs to include * `hide_branding` — Whether to hide Honeybadger branding **Optional flags:** * `-o, --output` — Output format: `text` or `json` (default: `text`) ## Update a status page [Section titled “Update a status page”](#update-a-status-page) ```shell hb statuspages update --account-id 12345 --id 67890 --cli-input-json '{"name": "Updated Name"}' ``` **Required flags:** * `--account-id` — Account ID * `--id` — Status page ID * `--cli-input-json` — JSON payload with fields to update **Optional flags:** * `-o, --output` — Output format: `text` or `json` (default: `text`) ## Delete a status page [Section titled “Delete a status page”](#delete-a-status-page) ```shell hb statuspages delete --account-id 12345 --id 67890 ``` **Required flags:** * `--account-id` — Account ID * `--id` — Status page ID # Streams CLI reference > List Honeybadger Insights data streams and their IDs from the command line. The `streams` command lists the [Insights streams](/guides/insights/#streams) for a project. Stream IDs are what you use to scope an [Insights query](/resources/cli/insights/) to specific streams (`hb insights query --stream-ids`) and to point an [alarm](/resources/cli/alarms/) at the right data. `stream_ids` is optional on an alarm — omit it and the alarm queries every stream on the project. ## List streams [Section titled “List streams”](#list-streams) ```shell hb streams list --project-id 12345 ``` The table output lists each stream’s ID, name, slug, whether it’s the internal stream, and when it was created. **Required flags:** * `--project-id` — Project ID **Optional flags:** * `-o, --output` — Output format: `table` or `json` (default: `table`) # Teams CLI reference > Manage Honeybadger teams and team memberships from the command line. The `teams` command lets you manage teams and team memberships. ## List teams [Section titled “List teams”](#list-teams) ```shell hb teams list --account-id 12345 ``` **Required flags:** * `--account-id` — Account ID **Optional flags:** * `-o, --output` — Output format: `table` or `json` (default: `table`) ## Get team details [Section titled “Get team details”](#get-team-details) ```shell hb teams get --id 67890 ``` **Required flags:** * `--id` — Team ID **Optional flags:** * `-o, --output` — Output format: `text` or `json` (default: `text`) ## Create a team [Section titled “Create a team”](#create-a-team) ```shell hb teams create --account-id 12345 --name "Backend Team" ``` **Required flags:** * `--account-id` — Account ID * `--name` — Team name **Optional flags:** * `-o, --output` — Output format: `text` or `json` (default: `text`) ## Update a team [Section titled “Update a team”](#update-a-team) ```shell hb teams update --id 67890 --name "New Team Name" ``` **Required flags:** * `--id` — Team ID * `--name` — New team name **Optional flags:** * `-o, --output` — Output format: `text` or `json` (default: `text`) ## Delete a team [Section titled “Delete a team”](#delete-a-team) ```shell hb teams delete --id 67890 ``` **Required flags:** * `--id` — Team ID *** ## Managing team members [Section titled “Managing team members”](#managing-team-members) ### List members [Section titled “List members”](#list-members) ```shell hb teams members list --team-id 67890 ``` **Required flags:** * `--team-id` — Team ID **Optional flags:** * `-o, --output` — Output format: `table` or `json` (default: `table`) ### Update member permissions [Section titled “Update member permissions”](#update-member-permissions) ```shell hb teams members update --team-id 67890 --member-id 11111 --admin true ``` **Required flags:** * `--team-id` — Team ID * `--member-id` — Member ID * `--admin` — Set admin status (`true` or `false`) **Optional flags:** * `-o, --output` — Output format: `text` or `json` (default: `text`) ### Remove a member [Section titled “Remove a member”](#remove-a-member) ```shell hb teams members remove --team-id 67890 --member-id 11111 ``` **Required flags:** * `--team-id` — Team ID * `--member-id` — Member ID *** ## Managing team invitations [Section titled “Managing team invitations”](#managing-team-invitations) ### List invitations [Section titled “List invitations”](#list-invitations) ```shell hb teams invitations list --team-id 67890 ``` **Required flags:** * `--team-id` — Team ID **Optional flags:** * `-o, --output` — Output format: `table` or `json` (default: `table`) ### Get an invitation [Section titled “Get an invitation”](#get-an-invitation) ```shell hb teams invitations get --team-id 67890 --invitation-id 22222 ``` **Required flags:** * `--team-id` — Team ID * `--invitation-id` — Invitation ID **Optional flags:** * `-o, --output` — Output format: `text` or `json` (default: `text`) ### Create an invitation [Section titled “Create an invitation”](#create-an-invitation) ```shell hb teams invitations create --team-id 67890 --cli-input-json '{ "email": "user@example.com", "admin": false, "message": "Welcome to the team!" }' ``` **Required flags:** * `--team-id` — Team ID * `--cli-input-json` — JSON payload (inline string or `file://path`) **JSON fields:** * `email` — Email address to invite * `admin` — Whether the user should be a team admin * `message` — Optional welcome message **Optional flags:** * `-o, --output` — Output format: `text` or `json` (default: `text`) ### Update an invitation [Section titled “Update an invitation”](#update-an-invitation) ```shell hb teams invitations update --team-id 67890 --invitation-id 22222 --cli-input-json '{"admin": true}' ``` **Required flags:** * `--team-id` — Team ID * `--invitation-id` — Invitation ID * `--cli-input-json` — JSON payload with fields to update **Optional flags:** * `-o, --output` — Output format: `text` or `json` (default: `text`) ### Delete an invitation [Section titled “Delete an invitation”](#delete-an-invitation) ```shell hb teams invitations delete --team-id 67890 --invitation-id 22222 ``` **Required flags:** * `--team-id` — Team ID * `--invitation-id` — Invitation ID # Uptime CLI reference > Manage Honeybadger uptime monitoring from the command line. The `uptime` command lets you manage uptime monitoring checks and view outages. All uptime commands require `--project-id`. ## Managing uptime sites [Section titled “Managing uptime sites”](#managing-uptime-sites) ### List sites [Section titled “List sites”](#list-sites) ```shell hb uptime sites list --project-id 12345 ``` **Required flags:** * `--project-id` — Project ID **Optional flags:** * `-o, --output` — Output format: `table` or `json` (default: `table`) ### Get site details [Section titled “Get site details”](#get-site-details) ```shell hb uptime sites get --project-id 12345 --site-id 67890 ``` **Required flags:** * `--project-id` — Project ID * `--site-id` — Site ID **Optional flags:** * `-o, --output` — Output format: `text` or `json` (default: `text`) ### Create a site [Section titled “Create a site”](#create-a-site) ```shell hb uptime sites create --project-id 12345 --cli-input-json '{ "name": "Production API", "url": "https://api.example.com/health", "frequency": 1, "match_type": "success", "validate_ssl": true, "locations": ["us-east", "eu-west"] }' ``` **Required flags:** * `--project-id` — Project ID * `--cli-input-json` — JSON payload (inline string or `file://path`) **JSON fields:** * `name` — Site name * `url` — URL to check * `frequency` — Check frequency in minutes: `1`, `5`, or `15` * `match_type` — How to validate response: * `success` — Any 2xx response * `exact` — Response must exactly match expected string * `include` — Response must contain expected string * `exclude` — Response must not contain expected string * `locations` — Array of check locations * `validate_ssl` — Whether to validate SSL certificates **Optional flags:** * `-o, --output` — Output format: `text` or `json` (default: `text`) ### Update a site [Section titled “Update a site”](#update-a-site) ```shell hb uptime sites update --project-id 12345 --site-id 67890 --cli-input-json '{"frequency": 5}' ``` **Required flags:** * `--project-id` — Project ID * `--site-id` — Site ID * `--cli-input-json` — JSON payload with fields to update **Optional flags:** * `-o, --output` — Output format: `text` or `json` (default: `text`) ### Delete a site [Section titled “Delete a site”](#delete-a-site) ```shell hb uptime sites delete --project-id 12345 --site-id 67890 ``` **Required flags:** * `--project-id` — Project ID * `--site-id` — Site ID *** ## View outages [Section titled “View outages”](#view-outages) List outages for a site: ```shell hb uptime outages --project-id 12345 --site-id 67890 ``` ### With time filters [Section titled “With time filters”](#with-time-filters) ```shell hb uptime outages --project-id 12345 --site-id 67890 \ --created-after 1704067200 \ --created-before 1706745600 \ --limit 10 ``` **Required flags:** * `--project-id` — Project ID * `--site-id` — Site ID **Optional flags:** * `--created-after` — Unix timestamp for start of range * `--created-before` — Unix timestamp for end of range * `--limit` — Maximum results (default: 25, max: 25) * `-o, --output` — Output format: `table` or `json` (default: `table`) *** ## View check history [Section titled “View check history”](#view-check-history) List recent uptime checks for a site: ```shell hb uptime checks --project-id 12345 --site-id 67890 --limit 25 ``` **Required flags:** * `--project-id` — Project ID * `--site-id` — Site ID **Optional flags:** * `--created-after` — Unix timestamp for start of range * `--created-before` — Unix timestamp for end of range * `--limit` — Maximum results (default: 25, max: 25) * `-o, --output` — Output format: `table` or `json` (default: `table`) # Data residency > Control where your application data is stored with Honeybadger's data residency options for EU and US regions. Data residency refers to the physical location where your organization’s data is stored and processed. It’s a way to ensure that data like customer information, application logs, and business data remain within the geographical borders of a specific country or region. Honeybadger offers two regions (US and EU) so that your organization can choose where your data is stored and processed. ## United States [Section titled “United States”](#united-states) Honeybadger stores your data in the US by default (Amazon’s us-east-1 region). Unless you specifically signed up for our [EU region](#european-union), this is where your data is located. If you access Honeybadger via one of the following subdomains, you’re in our US region: * app.honeybadger.io * api.honeybadger.io ## European Union [Section titled “European Union”](#european-union) You can optionally [sign up for an account in our EU region](https://eu-app.honeybadger.io/users/sign_up?plan=team), which we operate on dedicated infrastructure in Amazon’s eu-central-1 region in Frankfurt, Germany. Honeybadger EU accounts are purchased separately, allowing you to choose different tiers depending on your needs. The pricing and features we offer are otherwise the same across both regions. If you access Honeybadger via one of the following subdomains, you’re in our EU region: * eu-app.honeybadger.io * eu-api.honeybadger.io # Working with LLMs > Learn how to integrate large language models (LLMs) with Honeybadger's error tracking and monitoring tools for faster debugging and troubleshooting. Large language models (LLMs) can help you troubleshoot your applications and fix issues faster. When integrated with Honeybadger’s error tracking and application monitoring tools, they become even more effective at helping you squash bugs and keep your systems running smoothly. ## Honeybadger Model Context Protocol (MCP) server [Section titled “Honeybadger Model Context Protocol (MCP) server”](#honeybadger-model-context-protocol-mcp-server) The [Honeybadger MCP server](/resources/mcp/) provides structured access to Honeybadger’s API through the Model Context Protocol, allowing AI assistants to interact with your Honeybadger projects and monitoring data. Connect to the hosted server in minutes, or run your own. See the [MCP server documentation](/resources/mcp/) for the quick start, authorization details, and example workflows. ## Documentation for LLMs [Section titled “Documentation for LLMs”](#documentation-for-llms) We publish machine-readable content for LLMs: our documentation in [llms.txt](https://llmstxt.org/) format, plus task-focused instructions for AI agents. Everything is generated automatically from our documentation and codebase. ### Available formats [Section titled “Available formats”](#available-formats) * [/llms.txt](/llms.txt) - Index page with links to full and abridged documentation, plus specialized subsets * [/llms-full.txt](/llms-full.txt) - Complete documentation in text format * [/llms-small.txt](/llms-small.txt) - Abridged documentation with non-essential content removed The abridged version (`llms-small.txt`) is optimized for token efficiency while preserving essential technical information. ### Specialized documentation subsets [Section titled “Specialized documentation subsets”](#specialized-documentation-subsets) We also provide focused documentation subsets for specific use cases: * The Honeybadger Data (REST) API and reporting APIs * Honeybadger Insights and BadgerQL (for generating queries, augment with [agent instructions](/resources/llms/instructions/) for better results) * Honeybadger’s user interface and product features * Individual documentation sets for each client library (Ruby, JavaScript, Python, PHP, Elixir, etc.) Visit [/llms.txt](/llms.txt) for the complete list with links to download. ### Instructions for AI agents [Section titled “Instructions for AI agents”](#instructions-for-ai-agents) The documentation subsets above are our docs reformatted for reading. We also publish [agent instructions](/resources/llms/instructions/): task-focused documents that teach an agent how to write BadgerQL, query Insights, configure charts and dashboards, manage alarms, and search errors. They focus on the mistakes language models tend to make. The two complement each other: documentation gives an agent product knowledge, and instructions help it avoid common mistakes. ### Using llms.txt files [Section titled “Using llms.txt files”](#using-llmstxt-files) These files are designed to be consumed by LLMs either: 1. **Directly:** Some LLM tools can fetch and process llms.txt files automatically 2. **As context:** Copy and paste relevant sections into your AI assistant 3. **Via automation:** Build tools that fetch and inject documentation into LLM prompts ## Responding to alerts in Slack and GitHub [Section titled “Responding to alerts in Slack and GitHub”](#responding-to-alerts-in-slack-and-github) Honeybadger includes full backtraces in [Slack error notifications](/guides/integrations/slack/) to provide the context that AI coding assistants need for effective debugging. The backtrace appears as formatted code in Slack, allowing you to copy and paste it to AI debugging assistants like Cursor, Windsurf, or Copilot. If you use Cursor’s [Background Agents](https://docs.cursor.com/background-agent), you can install their [Slack integration](https://docs.cursor.com/slack) to ask Cursor to fix the error directly from Slack: ![Slack notification showing a Honeybadger error and integration with AI debugging tools for quick issue resolution.](/_astro/slack_notification.DW_wrxfK_ZaozXc.webp) We include similar information when [creating issues for errors in GitHub](/guides/integrations/github/) and other issue trackers, which should help you—for example—[assign bugfixes to GitHub Copilot](https://github.blog/ai-and-ml/github-copilot/assigning-and-completing-issues-with-coding-agent-in-github-copilot/). See our [integration docs](https://docs.honeybadger.io/guides/integrations/) to learn more about our third-party integrations. ## Natural language tools in Honeybadger [Section titled “Natural language tools in Honeybadger”](#natural-language-tools-in-honeybadger) Honeybadger includes a few tools that let you describe what you want in plain English. [Natural language search](/guides/errors/search/#natural-language-search)Find errors by describing the filters you want, such as unresolved production errors from the last 24 hours. [Natural language queries](/guides/insights/#natural-language-queries)Explore event data in Insights. Describe the data you want to see, and Honeybadger will build the BadgerQL query for you. ## Going further [Section titled “Going further”](#going-further) As we continue to develop LLM integrations, we’re exploring ways to make automated monitoring and debugging more intelligent. Some ideas we’re excited about: * Root cause analysis and bug fixes **Do you have ideas for how LLMs could improve your Honeybadger experience?** We’d love to hear from you! Drop us a line at [support@honeybadger.io](mailto:support@honeybadger.io?subject=HB+LLMs). ## Additional resources [Section titled “Additional resources”](#additional-resources) * [Honeybadger MCP server](/resources/mcp/) * [Honeybadger API documentation](/api/) # Instructions for AI agents > Machine-generated reference documents that teach LLMs and AI agents how to query, visualize, and manage Honeybadger data. These are reference documents written for LLMs and AI agents rather than people. They teach an agent how to work with Honeybadger correctly: writing BadgerQL, configuring visualizations and dashboards, managing alarms, and searching errors. If you are building on Honeybadger with an AI assistant, coding agent, or your own tooling, fetch the relevant instructions and include them as context. The [Honeybadger MCP server](/resources/mcp/) serves this same content to connected agents. ## Available instructions [Section titled “Available instructions”](#available-instructions) | Name | Covers | Size | | ------------------------------------------------------ | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | -------------- | | [badgerql](/resources/llms/instructions/badgerql/) | The BadgerQL language: grammar, type hints, built-in fields, statements, expression functions, and the rules for writing correct queries. | \~9,067 tokens | | [queries](/resources/llms/instructions/queries/) | Fundamentals for querying Honeybadger Insights: streams, time ranges, event-class filtering, and verifying field names exist before aggregating. | \~1,666 tokens | | [charts](/resources/llms/instructions/charts/) | Visualization views for Insights query results and the chart\_config fields each view accepts. | \~1,644 tokens | | [dashboards](/resources/llms/instructions/dashboards/) | Insights dashboard structure: the dashboard object, widget types and their configs, grid layout, and the vis object. | \~1,479 tokens | | [alarms](/resources/llms/instructions/alarms/) | Insights alarms: alarm fields, trigger\_config, states, evaluation timing, and query guidelines. | \~1,056 tokens | | [errors](/resources/llms/instructions/errors/) | The Honeybadger error model (faults and notices), lifecycle states, and the error search query language. | \~2,729 tokens | | [checkins](/resources/llms/instructions/checkins/) | Check-in monitoring for scheduled processes: fields and schedule types, plan gating, lifecycle states, the report endpoint and payloads, and check-in events in Insights. | \~1,886 tokens | ## Fetching them [Section titled “Fetching them”](#fetching-them) Each document is available in three forms: * **Raw text** at `/resources/llms/instructions/.txt`. This is the document byte-for-byte, with no page formatting. Use this form when injecting instructions into an agent’s context. * **A readable page** at `/resources/llms/instructions//` (linked from the table above), with a markdown version at `/resources/llms/instructions/.md` like every page on this site. * **A machine-readable catalog** at [/resources/llms/instructions/index.json](/resources/llms/instructions/index.json), listing every document with its description, approximate token count, SHA-256 digest, and URL. Tools can read the catalog to discover what’s available without hardcoding the list, and use the digest to skip re-downloading unchanged content. # Alarms for AI agents > Insights alarms: alarm fields, trigger_config, states, evaluation timing, and query guidelines. This page is written for AI agents It is generated from the Honeybadger codebase and published as part of our [instructions for AI agents](/resources/llms/instructions/). Agents and tools should fetch the raw version at [`/resources/llms/instructions/alarms.txt`](/resources/llms/instructions/alarms.txt); the machine-readable catalog is at [`/resources/llms/instructions/index.json`](/resources/llms/instructions/index.json). For the human documentation on this topic, see [the guides](/guides/insights/alarms/). Alarms monitor an Insights query and send notifications when a trigger condition is met. Companion reading: alarm queries are BadgerQL (see the BadgerQL reference), and the **queries** instructions’ event-class filtering and field-grounding rules apply. Their time-range (`ts`) rules do NOT — an alarm has no `ts`; the time window is the `evaluation_period`. ## Alarm fields * `name`: string, required * `query`: BadgerQL query, required — see Query guidelines below * `evaluation_period`: how often the alarm is evaluated (`5m`, `1h`, `1d`). Minimum `1m`, must be more granular than a week * `lookback_lag`: delay before each evaluation so late-arriving data is counted (`1m`, or `0s` for none) * `trigger_config`: object defining when the alarm triggers (see below) * `description`: string, optional * `stream_ids`: array of stream ids the query runs against, optional — defaults to all of the project’s streams. Stream ids are listed at `GET /v2/projects/{project_id}/streams`; unknown ids are silently dropped. Honeybadger-generated event types (`notice`, `deploy`, `uptime_check`, …) live on the internal stream. ## Trigger config ### Structure ```json { "type": "alert_result_count", "config": { "operator": "gt", "value": 100 } } ``` ### Types * `alert_result_count` — triggers based on the count of events matching the query ### Config fields * `operator`: string, required — comparison operator * `value`: integer, required — threshold to compare against (>= 0) ### Operators * `gt` — greater than * `gte` — greater than or equal * `lt` — less than * `lte` — less than or equal * `eq` — equal * `neq` — not equal ### Examples Trigger when error count exceeds 50: ```json {"type": "alert_result_count", "config": {"operator": "gt", "value": 50}} ``` Trigger when count drops below a threshold: ```json {"type": "alert_result_count", "config": {"operator": "lt", "value": 10}} ``` Trigger when exactly zero events (missing heartbeat): ```json {"type": "alert_result_count", "config": {"operator": "eq", "value": 0}} ``` Trigger when any events exist: ```json {"type": "alert_result_count", "config": {"operator": "neq", "value": 0}} ``` ## Alarm states * `initial` — created but not yet evaluated * `ok` — query result does not meet the trigger condition * `alarm` — query result meets the trigger condition (alarm is triggered) An alarm with a non-null `error` field means the query failed to execute; check the `error` field for details. ## Evaluation timing The alarm evaluates at each `evaluation_period` boundary, looking back over the `evaluation_period` duration (offset by `lookback_lag` if set). ## Query guidelines The alarm system automatically wraps the query to count results per evaluation period. The query should filter and/or aggregate events; the system handles the final counting. Good queries: ```plaintext filter event_type::str == "notice" filter status::int >= 500 filter event_type::str == "request.handled" and duration::int > 5000 ``` Queries with `stats` also work (the system counts the result rows): ```plaintext filter event_type::str == "notice" | stats count() as count by fault_id::int ``` ## Common patterns Error spike detection: ```plaintext name: "Error Spike" query: filter event_type::str == "notice" evaluation_period: 5m lookback_lag: 1m trigger_config: {"type": "alert_result_count", "config": {"operator": "gt", "value": 100}} ``` Slow requests: ```plaintext name: "Slow Requests" query: filter event_type::str == "request.handled" and duration::int > 5000 evaluation_period: 5m lookback_lag: 1m trigger_config: {"type": "alert_result_count", "config": {"operator": "gt", "value": 10}} ``` Missing heartbeat (no events in period): ```plaintext name: "Missing Heartbeat" query: filter event_type::str == "heartbeat" evaluation_period: 10m lookback_lag: 0m trigger_config: {"type": "alert_result_count", "config": {"operator": "eq", "value": 0}} ``` Server errors (any 5xx): ```plaintext name: "Server Errors" query: filter event_type::str == "request.handled" and status::int >= 500 evaluation_period: 5m lookback_lag: 1m trigger_config: {"type": "alert_result_count", "config": {"operator": "gt", "value": 0}} ``` # BadgerQL for AI agents > The BadgerQL language: grammar, type hints, built-in fields, statements, expression functions, and the rules for writing correct queries. This page is written for AI agents It is generated from the Honeybadger codebase and published as part of our [instructions for AI agents](/resources/llms/instructions/). Agents and tools should fetch the raw version at [`/resources/llms/instructions/badgerql.txt`](/resources/llms/instructions/badgerql.txt); the machine-readable catalog is at [`/resources/llms/instructions/index.json`](/resources/llms/instructions/index.json). For the human documentation on this topic, see [the guides](/guides/insights/badgerql/). BadgerQL is a pipe-based query language for events stored in Honeybadger Insights. Functions are joined with `|`; each function consumes the events the previous one produced. **Schema awareness.** A caller may include event-trait schemas in the user message describing what fields exist on the events and their types. When schemas are provided, draw field names and `::type` hints from them — do not guess. When schemas are not provided, prefer discovery (`fields @preview | limit 1 by event_type::str` to inspect a sample of each event type) over guessing field types from names. ## BadgerQL Grammar ### Query Structure A query is one or more functions combined with the pipe operator `|`: ```plaintext fields status_code::int, controller::str | filter status_code > 400 | stats count() as count by controller | sort count desc | limit 10 ``` Every function after the first must be preceded by `|`. In multi-line queries, the `|` starts each new function line. Each function consumes the events produced by the previous one. ### Type Hinting Each field’s data is stored in a separate bucket per type. The `::type` hint tells BadgerQL which bucket to look in — it is not a conversion, it is a lookup directive. ```plaintext fields status_code::int | filter email::str like "%example.com%" | stats avg(duration::float) by controller::str ``` Available type hints: | Hint | Bucket | | --------- | ------- | | `::int` | integer | | `::float` | float | | `::str` | string | | `::bool` | boolean | Rules of thumb: * **Hint once.** Subsequent uses of the same field remember the hint. `filter status::int > 400 | stats count() as count by status` works. * **Wrong hint = empty results.** If a field is stored as a float and you hint `::int`, the lookup misses and you get empty results or a type error. * **Don’t infer from output.** Check `@preview` to see how a field is actually stored before hinting. #### Nested fields Use dot notation: `site.name::str`, `user.id::int`. #### Array fields Use `[*]` to reference all elements: `tags[*]::str`. **This is always an array, even when aliased** — `tags[*]::str as tag` makes `tag` an array alias, not a scalar. To work with individual elements as scalars (so plain `==`, `<`, etc. work), use `| expand field[*]::type as alias` which unrolls the array into one event per element. To filter on a property of array elements without unrolling, wrap the predicate in `any()` or `all()`: `filter any(tags[*]::str == "fun")`. Use a positional index `[N]` (0-based) to extract a single element: `a[0]::int` is the first element, `a[1]::int` is the second. Positional access works in `fields` clauses; use the hinted type on each reference. #### Aliases Use `as` to rename. Wrap aliases with spaces in backticks: ```plaintext stats unique(user::str) as `Affected Users` by fault_id::int ``` **Pick aliases by intent, not by input.** * When projecting a field unchanged, keep its name: `sum(bytes::int) as bytes`. * When an aggregate has an obvious output, use the function name: `stats count() as count`, `stats avg(latency::float) as avg`. * When the same function appears multiple times with different parameters, name by the **distinguishing parameter** — not by the input value. For example, `bin(1h) as hourly` / `bin(1d) as daily`, or `percentile(50, x) as p50` / `percentile(99, x) as p99`. * Never bake input literals into the alias. `latency_2025_01_01` and `count_when_status_400` are anti-patterns; use `daily_latency` and `errors` instead. ## Built-in Fields Built-in fields are prefixed with `@`. They are always available without a type hint. | Field | Type | Description | | ----------------- | ------------ | ------------------------------------------ | | `@id` | string | The id of the event | | `@ts` | datetime | The timestamp of the event | | `@received_ts` | datetime | The timestamp when we received the event | | `@stream.id` | string | The id of the stream | | `@stream.name` | string | The name of the stream | | `@size` | integer | The size (in bytes) of the event | | `@query.start_at` | datetime | Start of the `@ts` range being queried | | `@query.end_at` | datetime | End of the `@ts` range being queried | | `@fill` | boolean | Whether or not result has filled in values | | `@preview` | json\_object | A preview of the query results | ## Statements The base pipeline functions. Each consumes the events produced by the previous function and produces events for the next one. ### fields ```plaintext fields expr [as alias][, ...]* ``` Add computed or renamed fields to each event. The expression can be any field reference or expression function. `fields` does **not** drop unmentioned fields. Use `only` to restrict the output set. **Don’t project fields speculatively.** Only add a field that the final result outputs or that a later clause consumes. A field referenced by a downstream `filter`/`stats` is hinted at that reference directly — you don’t need a leading `fields` to “set it up”. A `fields` clause whose projections a later `stats` drops is dead: `fields @ts, query::str | filter query::str == "x" | stats count()` should just be `filter query::str == "x" | stats count()`. **Pipeline statements are not valid inside `fields`.** Do not write `fields parse(x, /regex/) as y`, `fields expand(...)`, `fields fill(...)`, etc. — those are statements run at the pipeline level (`| parse x /regex/`, `| expand ...`, `| fill ...`). The expression position inside `fields` is for expression functions only. ```badgerql fields a as b fields duration::int / 1000 as duration_sec fields concat(first_name::str, " ", last_name::str) as full_name ``` ### filter ```plaintext filter boolean_expr [and|or ...]* ``` Drop events that don’t match the condition. Filters can sit before or after `stats`. **After a `stats`, reference the aggregate aliases — not the original hinted fields.** ```badgerql filter status_code::int >= 400 filter controller::str == "UsersController" and action::str == "show" filter email::str match /.*@example\.com/ ``` ### stats ```plaintext stats agg_expr[, ...]* [by [expr][, ...]*] ``` Group and aggregate. Every expression in the `agg_expr` list must use an aggregate function (`count`, `sum`, `avg`, `min`, `max`, `unique`, `percentile`, `first`, `last`, `apdex`, …). **Always alias aggregates.** Without `as`, the column is named after the function call expression — awkward to reference downstream. **`stats` rewrites the fieldset — drop any `fields` it doesn’t consume.** A `fields` projection upstream of a `stats` is dead unless the `stats` references it (inside an aggregate or in `by`). When building or modifying a query, remove orphaned projections: `fields @preview | stats count() by controller::str` is just `stats count() by controller::str` — the `fields @preview` is a no-op. **After `stats`, the original hinted fields are gone** — only `by` keys and aggregate aliases survive. Subsequent `filter` or `stats` must use those aliases. **This includes `@ts`**: never write `| stats ... | sort @ts desc`, `@ts` is out of scope after the aggregation. To sort the output rows of a `stats`, sort by a `by` key or by an aggregate alias. **`sort` BEFORE `stats` is only justified when an aggregate function reads input order — i.e. `first(...)` / `last(...)`.** Otherwise it’s wasted CPU (`count`, `avg`, `sum`, `min`, `max`, `unique`, `percentile`, … don’t care about input order). “Recent” wording in the user’s request maps to two different shapes: * *Pick the latest value per group* → sort BEFORE: `sort @ts desc | stats first(X::type) as X by Y::type`. * *Order the output rows by recency* → carry `@ts` through, sort AFTER on the alias: `stats max(@ts) as last_seen, ... by Y::type | sort last_seen desc`. * “(count|summarize|show totals for) all events” → `stats count() as count` * “(count|summarize|group) events by group” → `stats count() as count by group::type` * “(show|give me|summarize) average X and event count by group” → `stats avg(field::int) as avg, count() as count by group::type` * “(chart|trend|show) event count over time” → `stats count() as count by bin(1h) as hour` * “(show|count|group) only the top N values of X” → `stats count() as count by top(N, field::type)` * “(show|carry|attach) field X while grouping related events” → `stats first(field::type) as field by session_id::str` * “(get|show|find) the most recent X per Y — latest value per group” → `sort @ts desc | stats first(X::type) as X by Y::type` * “(show|list|rank) groups (most-recent|latest|recently active) first — sort output by recency” → `stats max(@ts) as last_seen, ... by Y::type | sort last_seen desc` ```badgerql stats count() as count stats count() as count by status_code::int stats avg(duration::int) as avg, count() as count by controller::str, action::str stats percentile(95, duration::int) as p95 by bin(1h) ``` ### expand ```plaintext expand array_field [as alias][, ...] ``` Unroll an array field into one event per element. The unrolled value takes a new alias and behaves like a scalar field downstream. **Use `expand` when you need to filter, aggregate, or project per element.** Use `any()` / `all()` when you only need a boolean test on the array without changing event cardinality. Multiple arrays in one `expand` zip them by index (parallel arrays, not a cartesian product). After expand, the alias is a scalar — you filter and aggregate it like any normal field. * “(split|expand|unroll) array X into one row per item” → `expand X[*]::type as alias` * “(split|expand|unroll) array X and then filter or aggregate each item” → `expand X[*]::type as alias | filter alias > N | stats sum(alias) as total` * “(split|expand|unroll) arrays X and Y together by position” → `expand X[*]::type as x, Y[*]::type as y` ```badgerql expand tags[*]::str as tag expand nums[*]::int as num | filter num > 50 expand events[*].url::str as url ``` ### fill ```plaintext fill field_expression [as alias] [asc|desc|up|down] [from ...] [to ...] [step ...] [across field [bounded | including [...]]]* [with field[ = expression][, ...]*] ``` Insert synthetic result rows for missing values in a numeric or temporal sequence. **Reach for this when a user wants to zero-fill a time series, include empty hourly/daily bins, complete a numeric range, or carry a value forward across gaps.** Don’t refuse the request — `fill` exists for exactly this. When the fill field comes from `bin()` or `bucket()`, a bare `fill field` infers the grid from that function. `bin(1h)` supplies a 1-hour step; `bucket(x, 100)` supplies a 100-wide step; bounded `bucket(x, min, max, n)` supplies from/to/step. Explicit `from`/`to`/`step` always override inferred values. **`across ` fills the cross product with another grouping dimension** — every (fill value, across value) cell exists in the result. Use for stacked charts, heatmaps, and per-category series that need explicit zeros. `across field bounded` limits each category to its own observed fill-field range; `across field including ["a", "b"]` pins values into the domain even when absent from the data. A null dimension value is a category of its own in the cross product. Counting aggregates (`count`, `sum`, `unique` and their `*If` forms) default to 0 on filled cells; everything else defaults to null; `with field = value` overrides. Cross-fill does not support fill direction (`up`/`down`) or carry-forward `with field`; use explicit `with field = value` defaults instead. The `@fill` field marks inserted rows so generated values can be distinguished from real results. * “(fill|zero-fill|include) empty time buckets in a time series” → `stats count() as count by bin(1h) as date | fill date` * “(fill|zero-fill|include) empty buckets in a histogram” → `stats count() as count by bucket(field::int, 0, 1000, 20) as b | fill b` * “(chart|show) per-category time series with explicit zeros for missing category/time cells” → `stats count() as count by bin(1h) as t, category::str | fill t across category` * “(fill|complete) every category and time cell, pinning categories even when absent” → `stats count() as count by bin(1h) as t, op::str | fill t across op including ["create", "delete"]` * “(fill|complete) each category only within its own active period” → `stats count() as count by bin(1h) as t, sensor::str | fill t across sensor bounded` * “(fill|complete|add) every number from A to B with a default value” → `fields field::type, number::int | fill number from A to B with field = "default"` * “(fill|carry forward|forward-fill) X across missing numbers from A to B” → `fields field::type, number::int | fill number up from A to B with field` * “(fill|complete|extend) missing numbers up to N” → `fields field::type, number::int | fill number to N` ```badgerql fill bin fill bin step 1h fill number to 100 fill number from 0 to 5 with controller = "unknown" fill number up from 1 to 5 with controller ``` ### limit ```plaintext limit integer [by expr[, ...]*] ``` Cap the number of returned events. **Always pair with `sort`** — `limit` without a sort is non-deterministic. With a `by` clause, `limit` caps events per group. **The `by` clause accepts boolean expressions, not just fields**, so you can cap per (group, predicate-bucket) instead of writing two separate filtered queries. * “(show|give me|list) the top N events after sorting by X” → `sort field::type desc | limit N` * “(show|keep|limit to) N events per group” → `limit N by group::type` * “(show|keep|limit to) N events per group and condition bucket” → `limit N by group::type, field::int > threshold` ```badgerql limit 25 limit 5 by controller::str ``` ### only ```plaintext only expr [as alias][, ...]* ``` Restrict and order the final output columns. **Drops every column not listed** (unlike `fields`, which keeps the rest). Use to keep responses small and focused. ```badgerql only @ts, controller, status_code, duration ``` ### parse ```plaintext parse expr /regex/ ``` Extract fields from a string using named capture groups. **`parse` is a statement, not an expression function** — write it at the pipeline level (`| parse field /regex/`), never inside `fields` or `filter`. There is no `parse(field, /regex/)` expression form; SQL’s `regexp_extract` and similar do not exist. **Regex is RE2 syntax**, not PCRE. **`parse` is the BadgerQL pattern for pattern-based string extraction.** BadgerQL has `substring(string, start, length)` for fixed-position slicing, but no `indexOf`, `lastIndexOf`, `instr`, or `substr` — any “first word”, “everything before X”, “Nth field of a delimited string” intent that needs to *find* a position is solved with a regex capture, not string-position math. Each named capture becomes a new field on the event, accessible by its capture name. Non-matching captures yield `null`. * “(extract|pull|get) value from text X using regex” → `parse field::str /regex/` * “(parse|extract|pull) named field from X with regex” → `parse X::str /(?...)/` * “(show|give me|get) the captured value from X” → `parse X::str /(?regex)/ | fields name` * “(split|break up|extract) text X into named fields” → `parse field::str /(?...)(?...)/` * “(show|give me|get) the first word from X” → `parse X::str /^(?\w+)/` * “(show|give me|get) everything before the period in X” → `parse X::str /^(?[^.]*)\./` ```badgerql parse controller::str /(?\w+)Controller/ ``` ### sort ```plaintext sort expr [desc|asc][, ...]* ``` Order events. **Direction defaults to descending** — `sort field` is equivalent to `sort field desc`. Use `asc` explicitly for ascending order. Pair with `limit` to take the top N. * “(sort|order) events by X largest first” → `sort field::type` * “(sort|order) events by X smallest first” → `sort field::type asc` * “(sort|order) events by X and then Y” → `sort field_a::type asc, field_b::type desc` * “(show|give me|list) the top N events sorted by X” → `sort field::type desc | limit N` ```badgerql sort count sort created_at asc sort count desc, name asc ``` ### unique ```plaintext unique field[, ...] ``` **`unique` is a pipeline statement** that deduplicates events by one or more fields — distinct from the `unique()` aggregate, which counts distinct values. Use the statement form when the user wants distinct combinations of fields preserved as event-shaped rows. Don’t reconstruct it with `stats unique(concat(toString(a), ",", b))` — the statement form preserves the original event shape. **`unique` deduplicates but does not project.** To show the distinct values themselves, project the field first: `fields X::type | unique X`. `unique X::type` alone dedupes the events but leaves X out of the output. * “(show|keep|list) the distinct values of X” → `fields field::type | unique field` * “(show|keep|list) the distinct combinations of X and Y” → `fields field_a::type, field_b::type | unique field_a, field_b` ```badgerql fields controller::str | unique controller fields controller::str, action::str | unique controller, action ``` ## Expression Functions: Quick Reference Common functions you can use inside `fields`, `filter`, and `stats` expressions. Each entry shows its signature; notes call out the traps LLMs trained on SQL tend to hit. * **t between t and t -> boolean** — Use infix form, not function-call form. Both bounds are inclusive. * “(find|show|filter to) events where X is between A and B” → `filter field::int between A and B` * “(find|show|filter to) events that happened between START and END” → `filter @ts between START and END` * **isNotNull(t) -> boolean** — Function-call form, not infix. SQL’s `field is not null` is not valid BadgerQL. * “(find|show|filter to) events where X is present” → `filter isNotNull(field::type)` * **isNull(t) -> boolean** — Function-call form, not infix. SQL’s `field is null` is not valid BadgerQL. * “(find|show|filter to) events where X is missing or null” → `filter isNull(field::type)` * **any(boolean) -> boolean** — Wraps an array predicate. SQL-trained models often write `field[*]::type == value` directly — that’s a type error because `field[*]::type` is an array. Always wrap the predicate. Returns false on empty arrays. * “(find|show|filter to) events where any item in X equals Y” → `filter any(X[*]::type == Y)` * “(find|show|filter to) events where any item in X is one of A or B” → `filter any(X[*]::type in [A, B])` * “(find|show|filter to) events where any number in X is greater than N” → `filter any(X[*]::int > N)` * “(find|show|filter to) events where any object in X has field equal to Y” → `filter any(X[*].field::type == Y)` * “(show|list|keep) X values from events where any X equals Y” → `fields X[*]::type as X | filter any(X == Y) | only X` * **all(boolean) -> boolean** — Like `any()` but requires every element to match. Same wrapping rule applies. Returns true on empty arrays (vacuous truth). * “(find|show|filter to) events where every item in X equals Y” → `filter all(X[*]::type == Y)` * “(find|show|filter to) events where every number in X is between A and B” → `filter all(X[*]::int between A and B)` * “(find|show|filter to) events where every object in X has field equal to Y” → `filter all(X[*].field::type == Y)` * **t in t\[] -> boolean** — Right-hand side must be a literal array. Subqueries are not supported. The array element type must match the field type. * “(find|show|filter to) events where X is one of A, B, or C” → `filter field::type in [A, B, C]` * “(hide|exclude|drop) events where X is A or B” → `filter field::type not in [A, B]` * **either(t, …t) -> t** — Returns the first non-null value. Args must share a type; wrap with conversion functions to unify. SQL’s `coalesce` is accepted too. * “(use|show|pick) the first present value from X, Y, or Z” → `either(a::type, b::type, c::type)` * “(use|show|pick) the first present numeric value and make it an integer” → `either(toInt(str::str), int::int, toInt(float::float))` * **string like string -> boolean** — SQL-style wildcards inside a quoted string: `%` matches any characters, `_` matches one. Case-sensitive — use `ilike` for case-insensitive. For regex matching, use `match`. * “(find|show|filter to) events where X contains pattern” → `filter field::str like "%pattern%"` * “(find|show|filter to) events where X starts with prefix” → `filter field::str like "prefix%"` * **string match regex -> boolean** — Right-hand side is a regex literal between forward slashes, not a quoted string. Uses RE2 syntax. For SQL-style wildcards, use `like` instead. * “(find|show|filter to) events where X matches regex” → `filter field::str match /regex/` * “(find|show|filter to) events where X matches option1 or option2” → `filter field::str match /(option1|option2)/` * **if(condition, then, else)** — Three-arg function, not a Python/JS ternary. For multi-branch logic use `cond` instead of nested `if`s. * “(show|make|add) one value when a condition matches and another when it does not” → `if(cond, then_value, else_value)` * “(label|bucket|mark) events as high or low based on X” → `if(field::int > N, "high", "low")` * **cond(boolean, t, boolean, t, …, t) -> t** — Multi-branch conditional: pairs of (test, value) followed by a single default value. Replaces SQL `CASE WHEN ... THEN ... ELSE ... END`. * “(label|bucket|group) events across multiple conditions with a default” → `cond(test1, value1, test2, value2, default)` * “(label|bucket|group) X into high, medium, or low ranges” → `cond(x > 100, "high", x > 50, "medium", "low")` * **round(number, literal integer) -> float** — Optional second argument is the number of decimal places (default 0). `round(x)` rounds to the nearest integer; `round(x, 2)` rounds to two decimals. `floor` and `ceil` take the same optional precision argument. * “(round) X to the nearest integer” → `round(x::float)` * “(round) X to N decimal places” → `round(x::float, N)` * **bucket(value, width) or bucket(value, min, max, n)** — BadgerQL’s numeric histogram primitive — `bin()` buckets time, `bucket()` buckets numbers. Width form uses a fixed width anchored at zero. Bounded form divides a fixed range into N bucket slots and clips out-of-range values to null. `bucket()` assigns events to bucket keys; add `fill` to show empty buckets. All parameters are literals — there is no auto-ranged histogram function. * “(show|chart|give me) a histogram of X in buckets of width W” → `stats count() as count by bucket(field::int, W) as b | fill b | sort b asc` * “(show|chart|give me) a histogram of X from MIN to MAX in N buckets” → `stats count() as count by bucket(field::int, MIN, MAX, N) as b | fill b | sort b asc` * **toInt(any) -> integer** — Convert any expression to an integer. Use when you need a string-to-integer coercion. The reverse — turning an integer into a string for display — is `toString()`, not `toInt()`. * “(turn|convert|cast) X into an integer” → `toInt(field::str)` * “(use|show|pick) the first present value from mixed numeric fields as an integer” → `either(toInt(str::str), int::int, toInt(float::float))` * **toString(any) -> string** — Required when interpolating non-string values into `concat()`. SQL’s `CAST(x AS VARCHAR)` is not valid BadgerQL. * “(turn|convert|cast) X into text for display” → `toString(field::type)` * “(build|make|show) text that includes numeric X” → `concat("prefix-", toString(field::int))` * **toHour(datetime) -> integer** — Returns the 24-hour number (0-23) from a datetime. Use for “by hour of day” grouping. Do not reach for `formatDate("%H", @ts)` (returns a string) or `bin(1h)` (returns time buckets, not hour-of-day). * “(show|count|group) events by hour of day” → `stats count() as count by toHour(@ts) as hour` * **formatDate(format, date)** — Argument order is format first, datetime second. The reverse is wrong but common in SQL-trained models. Date argument defaults to `@ts` if omitted. * “(show|format|display) the event timestamp as YYYY-MM-DD text” → `formatDate("%Y-%m-%d", @ts)` * “(show|format|display) event timestamps as YYYY-MM-DD text” → `formatDate("%Y-%m-%d")` * **bin(interval, datetime = `@ts`) -> datetime** — BadgerQL’s time-bucketing function. Use a fixed interval for a specific bucket size, or no args to let BadgerQL auto-size from the query’s time window. Datetime is inferred from `@ts` by default. SQL’s `date_trunc`, ClickHouse’s `toStartOfInterval`, and `time_bucket` do not exist here. * “(chart|trend|show) event volume over time with automatic buckets” → `stats count() as count by bin() as bin` * “(chart|trend|show) event volume over time in 1 hour buckets” → `stats count() as count by bin(1h) as hour` * **urlPath(string) -> string** — Extracts the path from a URL string. Use for “give me the path from this URL” — don’t reach for `parse` with a regex. * **urlDomain(string) -> string** — Extracts the hostname/domain from a URL string. Use for “give me the domain from this URL” — don’t reach for `parse` with a regex. * **json(string, path)** — Extract a scalar value from a JSON string using a JSONPath expression. Use when a field is JSON text and you need a value inside it. Returns null for non-scalar paths (arrays, objects). * “(get|pull|show) a value inside JSON text field X” → `json(field::str, "$.path.to.value")` * **concat(string, string…) -> string** — All arguments must be strings. Wrap non-strings in `toString(...)` first. * “(join|combine|merge) text fields X and Y” → `concat(a::str, "-", b::str)` * “(build|make|show) text that includes numeric X” → `concat("prefix-", toString(field::int))` * **substring(string, start, length)** — Fixed-position string slicing. Positions are 1-indexed (`substring(s, 1, 3)` returns the first three characters). For pattern-based extraction where you need to *find* a position, use the `parse` statement with a regex instead. * “(take|get|extract) the first N characters of X” → `fields substring(field::str, 1, N) as prefix` * “(take|get|extract) N characters starting at position P” → `fields substring(field::str, P, N)` * **replace(string, match, replacement)** — Replace every occurrence of a substring (string match arg) or pattern (regex `/.../` match arg) with another string. Returns the rewritten string; project it under whatever alias makes sense. * “(replace|swap|change) every X with Y in field” → `fields replace(field::str, "X", "Y") as field` * “(strip|remove|drop) a regex pattern from field” → `fields replace(field::str, /pattern/, "") as field` * **toHumanString(num, type)** — Format a number as a human-readable string with unit handling. Don’t build the human format manually with `concat`/`toString`/division — this function handles unit-suffix logic for you. * “(show|format|display) byte count X as a readable size” → `toHumanString(field::int, "bytes")` * “(show|format|display) millisecond duration X as readable time” → `toHumanString(field::int, "milliseconds")` * “(show|format|display) microsecond duration X as readable time” → `toHumanString(field::int, "microseconds")` * “(show|format|display) large number X with a short suffix” → `toHumanString(field::float, "short")` * **count(string) -> integer** — Three forms: no-arg counts events, with a field counts non-null occurrences, with a predicate counts events where it’s true. Use the predicate form instead of SQL’s `sum(case when ... then 1 else 0 end)` pattern. * “(count|show me) all events” → `count()` * “(count|show me) events where X is present” → `count(field::type)` * “(count|show me) events where X is greater than N” → `count(field::int > N)` * **percentile(percent, value)** — There is no `p95(x)` or `p99(x)` shorthand. The percent goes first (0-100), the value second (must be numeric — `::str` is a type error). Result is approximated. * “(show|give me|find) the Nth percentile of X” → `stats percentile(N, field::int) as pN` * **unique(t) -> integer** — This is the count-distinct aggregate. SQL’s `count(distinct ...)` is not valid BadgerQL — use this instead. * “(count|show me) how many unique X values there are” → `stats unique(field::type) as count` * “(count|show me) unique X values per group” → `stats unique(field::type) as count by group::type` * **min(t) -> t** * **max(t) -> t** * **sum(number) -> number** — Argument must be numeric. `::str` is a type error — re-hint the field as numeric. * “(sum|total|add up) X across events” → `stats sum(field::int) as total` * **avg(number) -> number** — Argument must be numeric. `::str` is a type error — pick `::int` or `::float` for the argument regardless of how the field name reads. * “(average|show average|give me average) X across events” → `stats avg(field::int) as avg` * “(average|show average|give me average) X per group” → `stats avg(field::float) as avg by group::type` * **first(t) -> t** — Returns whichever value happened to be encountered first. Skips nulls — useful for projecting fields across event types when grouping by a shared key. Order is non-deterministic without a prior `sort`. * **last(t) -> t** — Returns whichever value happened to be encountered last. Same null-skipping and ordering semantics as `first`. * **apdex(responseTime, threshold)** — Threshold is in the same units as the response-time argument. If the field is microseconds, the threshold is microseconds. Mismatched units are a frequent foot-gun. * “(show|calculate|get) apdex for duration X with a 200ms target when X is in microseconds” → `stats apdex(duration::int, 200000) as score` * “(show|calculate|get) apdex for duration X with a 200ms target when X is in milliseconds” → `stats apdex(duration::int, 200) as score` * **pickMax(value, selector)** — Replaces SQL’s `argMax` / sort-and-limit-1 patterns. `pickMax(value, @ts)` returns the value from the most recent event in each group. * “(show|get|find) the most recent X per group” → `stats pickMax(X::type, @ts) as X by group::type` * “(show|get|find) the X with the largest Y per group” → `stats pickMax(X::type, Y::int) as X by group::type` * **countIf(predicate)** — Canonical conditional count. Part of the `*If` family (`sumIf`, `avgIf`, `minIf`, `maxIf`, `uniqueIf`, …) — use these instead of SQL’s `sum(case when ... then 1 else 0 end)` or `FILTER (WHERE ...)` patterns. * “(count|show me) events where X is greater than N” → `stats countIf(field::int > N) as count` * **sumIf(value, predicate)** — Conditional sum: value first, predicate second. Use instead of SQL’s `sum(case when pred then x else 0 end)`. * “(sum|total|add up) X for events where Y matches” → `stats sumIf(field::int, other::type == value) as total` * **avgIf(value, predicate)** — Conditional average: value first, predicate second. Events where the predicate is false are excluded entirely; they do not count as zeroes. * **rate(aggregate\[, interval])** — Bin-aware rates. Divides an aggregate by the surrounding `bin()` width, so the result stays a true per-second (or per-interval) rate when the bin size changes. Use instead of dividing by a hand-written constant like `count() / 60`. * “(chart|show|trend) requests or events per second over time” → `stats rate(count()) as rps by bin(1m) as t` * “(chart|show|trend) bytes or throughput per second over time” → `stats rate(sum(bytes::int)) as bps by bin(1m) as t` * “(chart|show|trend) events per minute over time” → `stats rate(count(), 1m) as rpm by bin(1h) as t` * **top(literal integer, t, any = null) -> t\[] | t** — Context-aware — pick the position by intent. Plain equality `field == top(N, field)` is not valid. * “(show|count|list) the top N values of X” → `stats count() as count by top(N, X)` * “(keep|show|filter to) events where X is in the top N values” → `filter X in top(N, X)` * “(show|list|give me) X from events where X is in the top N values” → `filter X in top(N, X) | fields X` * “(hide|exclude|drop) events where X is in the top N values” → `filter X not in top(N, X)` * “(show|list|give me) the top N X values for each group” → `stats top(N, X) by group` * “(show|list|give me) the top N X values as a list” → `stats top(N, X)` * “(show|list|give me) the top N X values ranked by Y” → `stats count() as count by top(N, X, max(Y))` * “(chart|trend|graph) the top N X values over time” → `filter X in top(N, X) | stats count() as count by bin(1h), X` ## Expression Functions: Other Traps * `ilike` — Case-insensitive form of `like`. Same SQL wildcards (`%`, `_`). * `uniqueIf` — Conditional count-distinct: value first, predicate second. SQL’s `count(distinct ...) filter (where ...)` is not valid BadgerQL. * `percentileIf` — Conditional percentile with the same leading arguments as `percentile`: percent first (0-100), value second, predicate last. * `apdexIf` — Apdex over a filtered slice. The predicate gates the denominator too, so the score only reflects matching events. Threshold units must match the response-time argument, same as `apdex`. ## Rules ### Pipeline shape * **Every function after the first is preceded by `|`.** In multi-line queries the `|` opens the next line. * **Aggregate functions are aliased.** Write `stats count() as count`, not `stats count()`. The unaliased column name is literally `count()`, which downstream `sort` / `filter` cannot reference cleanly. * **`limit` follows a `sort`.** A `limit` without `sort` returns a non-deterministic subset. * **Negate operators inline, not by wrapping.** Use `not between`, `not in`, `not like`, `not match` — never `not (x between ...)` or `not (x in [...])`. The parser does not accept a parenthesized negation of these operators. ### Types and fields * **Type hints are storage-bucket lookups.** Use `::int` for whole numbers, `::float` for decimals, `::str` for strings, `::bool` for booleans. A wrong hint returns empty results. * **Every field reference needs a hint on first use.** A bare `field` (no `::type`) in `fields`, `filter`, or `stats` is a “missing type hint” error. Hint each new field once when it first appears: `fields user_id::str`, then later `filter user_id == "x"` works because the hint is remembered. * **Hint once per field per query.** Subsequent uses of the same field reuse the hint. * **The hint must appear on the field reference, not on an enclosing function.** Conversion and aggregate functions (`toInt`, `toFloat`, `toString`, `count`, `sum`, …) do **not** supply a hint to the field they wrap. Write `toInt(b::str)`, not `toInt(b)`. * **After `stats`, reference aliases.** The hinted source fields are consumed by the aggregation. Downstream `filter` and `stats` must reference the aliases produced by the upstream `stats`. ### Discovery before analysis * **Inventory event types first** with `stats count() as count by event_type::str`. * **Inspect fields with one call**: `fields @preview | limit 1 by event_type::str`. Pick type hints from what `@preview` actually shows. * **Don’t probe for fields with `filter isNotNull(field::str)`.** Run `@preview` instead. ### Aggregation hygiene * **`bin()` defaults to auto-sized buckets.** Pass an explicit interval like `bin(1h)` when you want a predictable bucket size. * **Cap high-cardinality groups** with `top(N, field)` in the `by` clause, or with `| sort ... | limit N` after the `stats`. * **`first()` and `last()` skip nulls.** Use them to project a field that lives on one event type from a group keyed by a shared id (cross-event correlation). ### Output * **End queries with `sort` + `limit`** unless they are naturally bounded (e.g. time-bucketed). * **Use `only` to drop columns** you don’t need in the result. * **Project the fields the user named.** `filter`, `limit`, and `unique` do **not** add fields to the output — an event keeps only internal metadata (`@ts`, `@id`, …) unless a `fields` or `only` clause names the fields. Whenever the request mentions a field by name or by role, add a leading `fields` clause naming it, even if a later `filter`/`limit`/`unique` also references it. Example: “show the `num` of rows where num is negative” is `fields num::int | filter num < 0`, not `filter num::int < 0` alone. * **Answer with a query, not a question.** Write a best-effort BadgerQL query using the field names as given in the request. Never respond by asking for clarification or for field names — take the names the request supplies at face value. # Charts for AI agents > Visualization views for Insights query results and the chart_config fields each view accepts. This page is written for AI agents It is generated from the Honeybadger codebase and published as part of our [instructions for AI agents](/resources/llms/instructions/). Agents and tools should fetch the raw version at [`/resources/llms/instructions/charts.txt`](/resources/llms/instructions/charts.txt); the machine-readable catalog is at [`/resources/llms/instructions/index.json`](/resources/llms/instructions/index.json). For the human documentation on this topic, see [the guides](/guides/insights/). Each visualization view accepts an optional `chart_config` object — the key is named `chart_config` for every view, including views that aren’t strictly charts (`table`, `billboard`). Keys must match the schema for the chosen view below. Values reference the *output aliases* produced by the query — an aggregate aliased `count` is referenced as `"count"`, not `count()`. How the fields are packaged depends on the surface: dashboard widgets nest them in an object, query URLs flatten them into parameters. See the dashboards and queries instructions respectively — this reference only defines the fields themselves. ## table Raw result rows and columns. No config. ## billboard Big-number stat tiles: one tile per result row (or one per result field when `groupType` is `fields`). * `titleField`: string — Alias shown as the tile title * `valueField`: string — Alias shown as the big number; required when `groupType` is `events` * `titleURLField`: string — Alias containing a URL; makes the tile title a link * `subtitleField`: string — Alias shown below the value * `statusField`: string — Alias whose value drives the tile’s status indicator * `groupType`: string (fields|events) — `events` (default): one tile per result row using `valueField`; `fields`: one tile per result field ## bar Bar chart of a value per category. * `categoryField`: string, REQUIRED — Alias for the category axis; one bar per distinct value * `valueField`: string, REQUIRED — Alias for bar height * `valueFieldUnit`: string — Unit used to format values: `percent`, `microseconds`, or `milliseconds` * `labelField`: string — Alias rendered as a label on each bar * `groupType`: string (fields|events) — `events` (default): series come from `groupField`; `fields`: every result field except `categoryField` becomes its own series * `groupField`: string — Alias whose distinct values split bars into series (with `groupType` `events`) * `horizontal`: boolean — Render bars horizontally * `stacked`: boolean — Stack series instead of grouping side by side * `groups`: object — Per-series display options keyed by series name, e.g. `{"web": {"color": "#4A90D9"}}`. Advanced — usually omit ## line One or more series plotted over an x axis, usually time. * `xField`: string — Alias for the x axis, typically a time bin such as `bin(1h)` * `yField`: string — Alias plotted as the series value; required when `groupType` is `events` * `zField`: string — Alias whose distinct values split results into one series each * `colorField`: string — Alias whose values supply explicit series colors * `xFieldUnit`: string — Unit used to format x values: `percent`, `microseconds`, or `milliseconds` * `yFieldUnit`: string — Unit used to format y values: `percent`, `microseconds`, or `milliseconds` * `groupType`: string (fields|events) — `events` (default): one series from `yField`, split by `zField` if set; `fields`: every result field except `xField` becomes its own series * `yAxisLabel`: string — Left y-axis label (accepted but not currently applied by the renderer) * `yAxisMin`: number — Left y-axis minimum (accepted but not currently applied by the renderer) * `yAxisMax`: number — Left y-axis maximum (accepted but not currently applied by the renderer) * `rightYAxisFormat`: string — Right y-axis format (accepted but not currently applied by the renderer) * `rightYAxisLabel`: string — Right y-axis label (accepted but not currently applied by the renderer) * `rightYAxisMin`: number — Right y-axis minimum (accepted but not currently applied by the renderer) * `rightYAxisMax`: number — Right y-axis maximum (accepted but not currently applied by the renderer) * `groups`: object — Per-series display options keyed by series name, e.g. `{"web": {"color": "#4A90D9"}}`; entries may also set `axis` (`left`|`right`) to plot a series on the right y axis. Advanced — usually omit ## area Like line, with the area under each series filled; series can be stacked. * `xField`: string — Alias for the x axis, typically a time bin such as `bin(1h)` * `yField`: string — Alias plotted as the series value; required when `groupType` is `events` * `zField`: string — Alias whose distinct values split results into one series each * `groupType`: string (fields|events) — `events` (default): one series from `yField`, split by `zField` if set; `fields`: every result field except `xField` becomes its own series * `stacked`: boolean — Stack series instead of overlaying them * `groups`: object — Per-series display options keyed by series name, e.g. `{"web": {"color": "#4A90D9"}}`. Advanced — usually omit ## histogram Distribution of values across buckets. * `xField`: string, REQUIRED — Alias for the x axis * `yField`: string, REQUIRED — Alias for the y axis * `zField`: string — Alias whose distinct values split results into one series each * `xFieldUnit`: string — Unit used to format x values: `percent`, `microseconds`, or `milliseconds` * `yFieldUnit`: string — Unit used to format y values: `percent`, `microseconds`, or `milliseconds` * `groups`: object — Per-series display options keyed by series name, e.g. `{"web": {"color": "#4A90D9"}}`. Advanced — usually omit ## scatter Individual points plotted on two axes. * `xField`: string, REQUIRED — Alias for the x axis * `yField`: string, REQUIRED — Alias for the y axis * `groupField`: string — Alias whose distinct values color the points * `scaleField`: string — Alias that scales point size * `groups`: object — Per-series display options keyed by series name, e.g. `{"web": {"color": "#4A90D9"}}`. Advanced — usually omit ## heatmap Grid of cells colored by intensity. The query must sort by the x and y fields (`| sort x, y`) to render correctly. * `xField`: string, REQUIRED — Alias for the x axis, typically a time bin such as `bin(1h)` * `yField`: string, REQUIRED — Alias for the y axis * `zField`: string, REQUIRED — Alias for cell value/intensity * `yFieldUnit`: string — Unit used to format y values: `percent`, `microseconds`, or `milliseconds` * `steps`: integer, minimum 1 — Number of color steps (default 5) * `groups`: object — Per-series display options keyed by series name, e.g. `{"web": {"color": "#4A90D9"}}`. Advanced — usually omit ## pie Proportional slices; one slice per result row. * `nameField`: string, REQUIRED — Alias for slice labels * `valueField`: string, REQUIRED — Alias for slice sizes * `groups`: object — Per-slice display options keyed by slice name, e.g. `{"web": {"color": "#4A90D9"}}`. Advanced — usually omit # Check-ins for AI agents > Check-in monitoring for scheduled processes: fields and schedule types, plan gating, lifecycle states, the report endpoint and payloads, and check-in events in Insights. This page is written for AI agents It is generated from the Honeybadger codebase and published as part of our [instructions for AI agents](/resources/llms/instructions/). Agents and tools should fetch the raw version at [`/resources/llms/instructions/checkins.txt`](/resources/llms/instructions/checkins.txt); the machine-readable catalog is at [`/resources/llms/instructions/index.json`](/resources/llms/instructions/index.json). For the human documentation on this topic, see [the guides](/guides/check-ins/). Check-ins monitor scheduled and recurring processes (cron jobs, queue workers, backups). The process reports to Honeybadger on each run, and Honeybadger alerts when an expected report doesn’t arrive on time. Check-ins are inbound (the process calls Honeybadger); uptime monitoring is the outbound counterpart (Honeybadger probes a URL). A silent process is exactly what check-ins catch — a cron job that stops running produces no error to track. ## Check-in fields * `name`: string, optional (max 255 characters, unique per project). Display falls back to the check-in ID when blank * `slug`: string, optional — lowercase letters, digits, hyphens, underscores; unique per project. Enables the slug report URL (see Reporting). **Immutable after creation** — updates silently ignore it * `schedule_type`: `simple` or `cron`, defaults to `simple` when omitted. **Immutable after creation** — switching schedule types means deleting and recreating the check-in, which discards the check-in’s report history and resets monitoring. Verify the existing check-in and confirm the change is intended before recreating * `report_period`: required for `simple` — how often a report is expected, as `" "` where unit is `minute`, `hour`, `day`, `week`, or `month` (`"5 minutes"`, `"1 day"`). Zero periods are invalid * `cron_schedule`: required for `cron` — a standard cron expression (`"30 * * * *"`) describing when the job runs * `cron_timezone`: optional for `cron`, defaults to `UTC`. Takes Rails/ActiveSupport zone names (`"Eastern Time (US & Canada)"`, `"London"`, `"UTC"`) — **IANA identifiers like `"America/New_York"` are rejected** with a “not included in the list” validation error * `grace_period`: optional, same format as `report_period` — extra time allowed after the expected report before the check-in is considered missing. Use it for jobs with variable runtime: a job that runs hourly but can take 20 minutes gets `report_period: "1 hour"`, `grace_period: "20 minutes"` ## Plan limits * **The `cron` schedule type and report payloads both require the Business plan** — they share one entitlement, not two. On Basic and Team plans: creating or updating a `cron` check-in fails with an upgrade error, and any payload (standard *or* custom fields) is discarded on report (the report itself still counts, and missing detection still works). Simple check-ins and missing alerts are available on all plans * A `simple` period only approximates a regular cadence — it cannot represent an irregular cron schedule (weekdays only, specific times, uneven intervals). It’s a lossy fallback, not an equivalent: surface the cron option and its Business requirement rather than silently swapping in a simple period when a user’s schedule is really a cron * Plans also cap the number of check-ins per account ## Lifecycle and states * `pending` — created (or schedule changed) but not yet reported. **A pending check-in never alerts** — monitoring arms on the first report. After creating a check-in, the process must report once before missing detection begins * `reporting` — reporting on schedule. The next expected report is calculated from the last report: for `simple`, last report + `report_period`; for `cron`, the next cron occurrence after the last report (plus `grace_period`) * `missing` — the expected report (plus `grace_period`) didn’t arrive. A notification is sent for each missed period, incrementing the missed count. When a missing check-in reports again, it returns to `reporting` and a recovery notification is sent * `paused` — monitoring is suspended for a duration; missing detection resumes when the pause window ends Changing `report_period` or `cron_schedule` resets the check-in to `pending` — it re-arms on the next report. A missing check-in stops notifying after 60 consecutive misses, or when its last report is more than 6 months old. ## Reporting Each check-in has a report URL containing its ID: ```plaintext https://api.honeybadger.io/v1/check_in/XyZZy ``` Accounts in the EU region report to `eu-api.honeybadger.io` instead. * `GET` reports a simple ping; `POST` reports a ping plus an optional payload (see below). `HEAD` also works. No authentication is required — the ID *is* the credential, so treat the report URL like a secret: anyone who has it can submit fake reports and suppress missing alerts * IDs are **case-sensitive**, in URLs and everywhere else * If the check-in has a slug, an alternate URL uses the project API key and slug instead of the ID — useful to avoid embedding generated IDs in code and config: ```plaintext https://api.honeybadger.io/v1/check_in// ``` * A report can also be sent by email to `@report.hbchk.in` (no subject or body required; the ID is case-sensitive) The typical integration appends a report to the scheduled command so it only fires on success: ```plaintext @hourly /usr/bin/do_something && curl https://api.honeybadger.io/v1/check_in/XyZZy ``` ### Report payloads A `POST` report (with a `Content-Type: application/json` header) may include a JSON payload with the run’s results (plan-gated — see Plan limits): ```json { "check_in": { "status": "success", "duration": 1234, "stdout": "backup completed", "stderr": "", "exit_code": 0 } } ``` * `status`: `"success"` or `"error"` * `duration`: integer, milliseconds * `stdout` / `stderr`: captured output strings * `exit_code`: integer These five are the standard fields (the UI renders them specially). The payload is not restricted to them — any additional custom fields are accepted, stored, and queryable in Insights as `payload.`. The payload is informational and queryable only — it does not drive monitoring state. Any report sets the check-in to `reporting`, including one with `"status": "error"`; a payload status never triggers a missing alert. Only the *absence* of an expected report does. Keep payloads under 20KB. ## Check-ins in Insights Check-in activity is emitted as events with `event_type` `"check_in"` on the project’s **internal** stream (the stream must be selected for these queries to return anything). Events carry `check_in_id`, `state`, and the report `payload` fields when present. Note which activity emits an event: * `reporting` — emitted on each recorded report (deduplicated to at most one per \~30 seconds), even when the check-in was already reporting * `missing` — emitted for every missed period, even when already missing (this is what drives the per-miss notifications) * `paused` — emitted when the check-in is paused * Creation, and a schedule change that resets the check-in to `pending`, emit **no** event ```plaintext filter event_type::str == "check_in" and state::str == "missing" | stats count() as count by check_in_id::str ``` This counts *historical* `missing` events per check-in, not check-ins that are currently missing — a check-in that recovered still has its past `missing` events. For current state, list or fetch the check-ins directly rather than querying events. Payload fields are queryable under `payload` (`payload.status::str`, `payload.duration::int`, `payload.exit_code::int`) — history of run durations, failure exit codes, and output is all queryable. Custom payload fields are queryable the same way (`payload.`). Payloads exist only for Business accounts (see Plan limits); on other plans they’re discarded, so `payload.*` fields are simply absent — empty results mean no stored payload, not that the job reported no data. # Dashboards for AI agents > Insights dashboard structure: the dashboard object, widget types and their configs, grid layout, and the vis object. This page is written for AI agents It is generated from the Honeybadger codebase and published as part of our [instructions for AI agents](/resources/llms/instructions/). Agents and tools should fetch the raw version at [`/resources/llms/instructions/dashboards.txt`](/resources/llms/instructions/dashboards.txt); the machine-readable catalog is at [`/resources/llms/instructions/index.json`](/resources/llms/instructions/index.json). For the human documentation on this topic, see [the guides](/guides/dashboards/). A dashboard is a collection of widgets displayed on a project’s Insights page. Companion reading: widget queries are BadgerQL (see the BadgerQL reference), the **queries** instructions cover query fundamentals and `${...}` parameters, and the **charts** instructions cover `chart_config` fields. ## Dashboard object * `title`: string, required (max 255 characters) * `default_ts`: string, optional — default time range as an ISO 8601 duration (`PT3H`, `P1D`) or keyword (`today`, `yesterday`, `week`, `month`) * `widgets`: array of widget objects, required ## Widget object * `type`: string, required — one of the widget types below * `id`: string — omit when creating a widget; the server assigns one. A widget without an `id` is treated as new. Preserve existing `id`s when updating a dashboard so widget state and history are retained * `grid`: object — layout position `{x, y, w, h}` (see Grid layout) * `presentation`: object — `{title, subtitle}` display strings (max 255 characters each) * `config`: object — type-specific configuration ## Widget types and purposes * `insights_vis` — renders a BadgerQL query as a chart or table; the primary building block * `errors` — list of the project’s errors, optionally filtered by a search query (syntax: see the **errors** instructions) * `alarms` — current status of the project’s Insights alarms * `deployments` — recent deploy history * `checkins` — check-in statuses * `uptime` — uptime monitor statuses ## Config fields by widget type Valid widget `type` values: `insights_vis`, `alarms`, `errors`, `deployments`, `checkins`, `uptime`. ### `insights_vis` * `streams`: array of default|internal — Streams to query (defaults to \[“default”]) * `query`: any — BadgerQL query producing the widget’s data * `vis`: any — How to render the result: `{view, chart_config}` ### `alarms` * `limit`: integer, minimum 1 — Max alarms shown * `filter_state`: string (all|triggered|ok) — Show all alarms or only those in one state ### `errors` * `limit`: integer, minimum 1 — Max errors shown * `query`: string — Error search query string to filter the list * `sort`: string (last\_seen\_desc|last\_seen\_asc|times\_desc|times\_asc) — Sort order ### `deployments` * `limit`: integer, minimum 1 — Max deploys shown * `override_time`: boolean — Use `ts` instead of the dashboard’s time range * `ts`: string — Time range used when `override_time` is true ### `checkins` * `limit`: integer, minimum 1 — Max check-ins shown * `sort_order`: string (state\_name|name|last\_reported) — Sort by state, name, or last report time ### `uptime` * `limit`: integer, minimum 1 — Max uptime monitors shown ## Timepicker tokens (`errors` widgets) An `errors` widget’s `config.query` is error search syntax, not BadgerQL, so it cannot use `@query.start_at` / `@query.end_at`. Instead, two tokens expand to the dashboard timepicker’s range: * `@ts` — the start of the range * `@ts.end` — the end of the range Both expand to a quoted timestamp, so use them as the value of a date key: `created.after:@ts`, `created.before:@ts.end`. ```json {"type": "errors", "config": {"query": "-is:resolved created.after:@ts created.before:@ts.end"}} ``` When the selected range is open-ended — a relative duration like `PT3H`, or a keyword like `today` — its end is simply “now”, so the entire term containing `@ts.end` is dropped rather than emitting a redundant upper bound. `created.after:@ts created.before:@ts.end` becomes `created.after:"3 hours ago"`. This means one query works for both bounded and open-ended ranges; there is no need to maintain separate widgets. Widgets whose query contains either token re-run when the timepicker changes. ## The vis object (`insights_vis` widgets) `config.vis` controls how the query result renders: * `view`: string, required — one of `table`, `billboard`, `line`, `area`, `bar`, `histogram`, `scatter`, `heatmap`, `pie` * `chart_config`: object, optional — view-specific options. For the fields each view accepts, see the **charts** instructions; do not invent fields Example widget: ```json { "type": "insights_vis", "presentation": {"title": "Errors Over Time"}, "grid": {"x": 0, "y": 0, "w": 6, "h": 4}, "config": { "query": "filter event_type::str == \"notice\" | stats count() as count by bin(1h)", "vis": {"view": "line"} } } ``` ## Grid layout Dashboards use a 12-column grid: * `x` — column offset (0–11) * `y` — row offset (0 = top) * `w` — width in columns (1–12) * `h` — height in row units Widgets must not overlap. A widget’s `y` must be >= the `y + h` of any widget above it in the same columns. Side-by-side widgets in the same row share the same `y`; the next row starts at `y + h` of the tallest widget in the current row. Plan the full layout before assigning positions — overlapping or misaligned widgets render incorrectly. Example two-column layout: ```plaintext Row 0: Widget A: {x:0, y:0, w:6, h:4} Widget B: {x:6, y:0, w:6, h:4} Row 4: Widget C: {x:0, y:4, w:12, h:4} Row 8: Widget D: {x:0, y:8, w:6, h:3} Widget E: {x:6, y:8, w:6, h:3} ``` ## Validation Dashboard structure IS validated on save: unknown keys anywhere in the dashboard, widget, config, or chart\_config objects are rejected. Widget queries are NOT validated when a dashboard is saved — a widget with a broken query silently renders empty or shows an error. Verify each query returns the expected data before saving it into a dashboard. Widget queries may use query parameters — `${name}` or `${name:-default}` (syntax: see the **queries** instructions). Parameter values come from the dashboard URL’s query parameters and apply dashboard-wide, so every widget referencing `${env}` resolves to the same value. Give each parameter the same inline default everywhere it appears; a parameter that lacks both a URL value and a default blocks that widget from running. # Errors for AI agents > The Honeybadger error model (faults and notices), lifecycle states, and the error search query language. This page is written for AI agents It is generated from the Honeybadger codebase and published as part of our [instructions for AI agents](/resources/llms/instructions/). Agents and tools should fetch the raw version at [`/resources/llms/instructions/errors.txt`](/resources/llms/instructions/errors.txt); the machine-readable catalog is at [`/resources/llms/instructions/index.json`](/resources/llms/instructions/index.json). For the human documentation on this topic, see [the guides](/guides/errors/). ## The error model Honeybadger groups error occurrences by fingerprint: a *fault* is one unique error within a project, and each occurrence of it is a *notice*. A fault carries the error class, message, component/action, environment, tags, and an optional assignee; its notices carry the occurrence details (backtrace, request, params, context, session, hostname, revision). Occurrences are also emitted as `notice` events on the project’s internal Insights stream, so error data is queryable with BadgerQL too (see the queries instructions — Streams). ## Lifecycle and states * **Unresolved** — the default state; the error is open. * **Resolved** — marked fixed. If the error occurs again it automatically REOPENS (resolved is cleared) and a notification is sent — resolving is not permanent suppression. By default a deploy also auto-resolves every open error in its environment (`resolve_errors_on_deploy`, on by default, per-project) — which is why `created.after:"last deploy"` is the idiomatic “new errors” triage window. * **Ignored** — new occurrences are DISCARDED (not recorded as notices) and never notify, until unignored. The fault and its existing history remain. * **Paused** — notifications are snoozed for a duration (hour/day/week) or until the error occurs N more times (10/100/1000). Occurrences ARE still recorded — pausing silences the noise without losing data. * **Pending resolution** — marked to resolve automatically at the next deploy. Processed on every deploy regardless of the auto-resolve setting — the per-fault alternative when project-wide auto-resolve is off. * **Assigned** — a user (by email) owns the fault. Recording can also be paused outright until a set time — occurrences are discarded during the pause, and the first occurrence after it expires notifies. This is separate from the notification pause above and has no search filter. ## Search The same search string is accepted everywhere errors are filtered: the error list UI, the `errors` dashboard widget’s `query` field, and the Data API’s `q` parameter on the faults endpoints. ### Syntax * Combine filters with spaces; different keys must all match (AND). * REPEATING a key ORs its values: `class:NoMethodError class:TypeError` matches either. This is the only way to express OR — there is no `OR` operator. * Repeating a negated key excludes every listed value: `-environment:staging -environment:development` excludes both. * Bare terms (no `key:`) full-text search the error class and message, ANDed with the other filters: `stripe class:PaymentError`. * Negate a filter with a leading `-`: `-is:resolved`. Not every key is negatable — see the reference. * Quote values containing spaces: `message:"undefined method"`. * `component#action` is shorthand for `component:X action:Y`: `users_controller#show`. ### Values and wildcards * `*` in a value is a case-insensitive wildcard matching any run of characters. The value must match the whole field, so bracket the term to search for a substring: `context.user.email:*@example.com` matches addresses ending with it, `request.url:*checkout*` matches anywhere in the URL, and `class:Foo*` matches classes starting with it. * `key:*` alone is a presence check — any non-empty value: `context.user_id:*` finds errors with a user attached. * `-key:*` is its exact complement, an absence check — the value is missing or empty: `-context.user_id:*` finds errors with no user attached. * Array elements are addressed by index in the key path (`params.job.args.0.job_id:123`), or matched anywhere in the array with a wildcard value (`params.job.args:*Foo*`). ### Filter reference * `class` — Filter by class. Example: `class:value` (negatable with `-`) * `component` — Filter by component. Example: `component:value` (negatable with `-`) * `action` — Filter by action. Example: `action:value` (negatable with `-`) * `environment` — Filter by environment. Example: `environment:value` (negatable with `-`) * `is:assigned` — Errors that are assigned. Example: `is:assigned` (negatable with `-`) * `is:ignored` — Errors that are ignored. Example: `is:ignored` (negatable with `-`) * `is:resolved` — Errors that are resolved. Example: `is:resolved` (negatable with `-`) * `is:paused` — Errors that are paused. Example: `is:paused` (negatable with `-`) * `is:pending_resolution` — Errors that are pending\_resolution. Example: `is:pending_resolution` (negatable with `-`) * `has:ticket` — Errors that have ticket. Example: `has:ticket` (negatable with `-`) * `has:tickets` — Errors that have tickets. Example: `has:tickets` (negatable with `-`) * `has:comment` — Errors that have comment. Example: `has:comment` (negatable with `-`) * `has:comments` — Errors that have comments. Example: `has:comments` (negatable with `-`) * `tag` — Filter by tag. Example: `tag:"foo"` (negatable with `-`) * `assignee` — Filter by assignee email; also accepts assignee:anybody, assignee:nobody, assignee:me (resolved server-side to the current user’s email). Example: `assignee:user@example.com` * `created` — Lucene-style range on first-seen date; a single value (created:“August 4”) covers the whole period it names. Example: `created:[NOW-1DAY TO NOW]` (negatable with `-`) * `created.before` — First seen before a date. Example: `created.before:"24 hours ago"` (negatable with `-`) * `created.after` — First seen after a date. Example: `created.after:"last deploy"` (negatable with `-`) * `last_occurred.before` — Last occurred before a date. Example: `last_occurred.before:"1 hour ago"` * `last_occurred.after` — Last occurred after a date. Example: `last_occurred.after:"1 week ago"` * `occurred` — Lucene-style range on any occurrence date; a single value (occurred:“August 4”) covers the whole period it names. Example: `occurred:[NOW-1DAY TO NOW]` (negatable with `-`) * `message` — Filter notices by error message text. Example: `message:"undefined method"` (negatable with `-`) * `file` — Filter notices by file path. Example: `file:app/models/user.rb` (negatable with `-`) * `hostname` — Filter notices by hostname. Example: `hostname:web-1` (negatable with `-`) * `revision` — Filter notices by revision sha. Example: `revision:abc123` (negatable with `-`) * `request.*` — Filter notices by request fields (url, referer, user\_agent, etc.). Example: `request.url:example.com` (negatable with `-`) * `params.*` — Filter notices by request params. Example: `params.user_id:42` (negatable with `-`) * `context.*` — Filter notices by context fields. Example: `context.tenant:foo` (negatable with `-`) * `session.*` — Filter notices by session fields. Example: `session.id:abc` (negatable with `-`) ### Semantics and traps * The default error list excludes resolved and ignored faults. A search for “what’s broken” should include `-is:resolved -is:ignored`; drop them only when resolved or ignored errors are explicitly wanted. * Use `is:` and `has:` values exactly as enumerated in the reference (`is:resolved`, `is:ignored`, `is:assigned`, `is:paused`, `is:pending_resolution`, `has:ticket`, `has:comment`). Do not invent other values. * Never invent filter keys. An unrecognized filter does NOT error — the whole token silently becomes a full-text search over class and message, which usually matches nothing. The wildcard prefixes (`request.*`, `params.*`, `context.*`, `session.*`) accept any subkey, but only use subkeys known to exist in the project’s data. * `assignee:` takes an email address. `assignee:me` resolves server-side to the current user; `assignee:anybody` and `assignee:nobody` match presence/absence of an assignee. A bare name (`assignee:bob`) is never valid. * Use class names as given; do not normalize casing (a search for `redis` is `class:redis`, not `class:Redis`). * User identity lives in the error context — `context.user_id` and `context.user_email` by convention (the tracked field is configurable per project). “Errors affecting user X” → `context.user_email:x@example.com`; “errors that affected any user” → `context.user_id:*`. * There is NO sort token — `sort:count` does not exist. Sorting is a separate UI/API parameter (`order`: `recent`, `frequent`), never part of the search string. ### Time filters * For relative periods, use the `.after:` forms: `last_occurred.after:"24 hours ago"` (most recent occurrence), `created.after:"1 week ago"` (first seen — new errors), `occurred.after:"24 hours ago"` (any occurrence in the window). * For errors that have NOT happened recently, use `last_occurred.before:` — “errors that haven’t occurred in a month” → `last_occurred.before:"1 month ago"` (the most recent occurrence is older than a month). Do not reach for a negated `.after:` — `last_occurred.*` is not negatable, and the unrecognized token silently degrades to a full-text search. * Date values are parsed as natural language: `"24 hours ago"`, `"today"`, `"july 1"`, `"now"`, and ISO timestamps. The special value `"last deploy"` works only on the `.before:`/`.after:` forms, not on `created:`/`occurred:`. Ambiguous numeric dates are day-first (`01/02/2026` is 1 February). * A date that names no year means the most recent one already past, since a search is about what has happened: asked in August 2026, `"july 1"` is 2026-07-01, `"december 25"` is 2025-12-25, and `"monday"` is the Monday just gone. Name the year when you mean a different one. * `created.after:"last deploy"` matches faults first seen since the latest deploy; combined with an `environment:` filter, “last deploy” resolves to that environment’s latest deploy. * Do not add upper bounds that are always true: `.before:NOW` or `[X TO NOW]` is redundant for one-sided “since X” ranges — use `.after:` instead. Use the bracketed Lucene range form (`created:[NOW-7DAY TO NOW-1DAY]`) only when both bounds are meaningful. * A bound given as a bare date covers that whole day: the lower bound starts at `00:00:00` and the upper bound runs through `23:59:59`, so `created:[2026-06-28 TO 2026-06-29]` spans both days end to end. Name a time (`2026-06-28 14:30 UTC`) when you need something narrower. * Either end of a bracketed range may be `*` to leave it unbounded — `created:[2026-06-28 TO *]` is everything since that date. Prefer `created.after:` for one-sided ranges. * Quotes around a bound are ignored (`created:["2026-06-28" TO "2026-06-29"]` is the range above), but a bound that contains a space needs the whole range quoted instead: `created:"[2026-06-28 14:30 UTC TO NOW]"`. * A single value in place of a range covers the whole of the period it names, so “errors on August 4” is `occurred:"August 4"` — the same day `occurred:[2026-08-04 TO 2026-08-04]` spans. Naming a time narrows it to that minute: `occurred:"August 4 20:05"` covers `20:05:00`–`20:05:59`. Widen it the same way — `occurred:2026-06` is that month and `occurred:2026` that year. Quote any value containing a space. # Queries for AI agents > Fundamentals for querying Honeybadger Insights: streams, time ranges, event-class filtering, and verifying field names exist before aggregating. This page is written for AI agents It is generated from the Honeybadger codebase and published as part of our [instructions for AI agents](/resources/llms/instructions/). Agents and tools should fetch the raw version at [`/resources/llms/instructions/queries.txt`](/resources/llms/instructions/queries.txt); the machine-readable catalog is at [`/resources/llms/instructions/index.json`](/resources/llms/instructions/index.json). For the human documentation on this topic, see [the guides](/guides/insights/). Fundamentals for writing BadgerQL queries against Honeybadger Insights — what to establish before aggregating, and the traps that silently produce wrong results. For the language itself (syntax, functions, types), see the BadgerQL reference. ## Streams Events live in streams, and every project has two: `default` (events your applications send) and `internal` (events Honeybadger generates about the project — errors, deploys, uptime checks, check-ins). Which streams a query searches is a request-level selection like `ts`, NOT a query clause — an event class that lives on an unselected stream returns nothing, which looks identical to the events not existing. Honeybadger-generated event types (`notice`, `deploy`, `uptime_check`, …) require the internal stream. `@stream.id` and `@stream.name` identify each result event’s stream. Streams are selected by id via the `stream_ids` request parameter; when omitted, all of the project’s streams are searched. A project’s streams and their ids are listed at `GET /v2/projects/{project_id}/streams`. Selection is per-project: ids not belonging to the queried project — unknown or from another project — are silently dropped, so a cross-project query partially succeeds and looks complete. Streams are provisioned asynchronously: a just-created project’s stream list may be empty or partial for a short time — retry before concluding streams are missing. ## Time range The time range (`ts`) is a *separate* parameter from the query — BadgerQL queries do NOT filter on time in their body. `ts` accepts three forms: * Rolling windows, as an ISO-8601 duration: “last 15 minutes” → `PT15M`, “last hour” → `PT1H`, “last 24 hours” → `PT24H`, “last 7 days” → `P7D`, “last 30 days” → `P30D` * Calendar windows, as a keyword: `today`, `yesterday`, `week` (this week so far), `month` (this month so far) * Absolute ranges, as slash-separated ISO-8601 timestamps: `2026-01-22T00:00:00/2026-01-29T00:00:00` Calendar windows and absolute ranges are interpreted in the `timezone` parameter — an IANA name (`America/Chicago`) or a UTC offset in seconds, defaulting to UTC. Rolling durations are timezone-independent. When the user’s question is calendar-shaped (“today”, “since Monday”), set `timezone` to their timezone or the window boundaries will be UTC’s, not theirs. `timezone` also changes outputs, not just the window: datetime values in results (`@ts`, `now()`) are returned in that timezone, and `bin()` buckets align to its boundaries — `bin(1d)` splits days at that timezone’s midnight, so daily counts differ between timezones. When comparing timestamps across queries or against other systems, use one consistent `timezone` (or leave everything UTC). Anything that scopes a query to a time window belongs in `ts`, never in the query body — even when phrased as a filter (“events from today”, “where the time is in the last hour”). The only time-related clause that belongs in a query body is `bin(...)` for time-grouped aggregates — that’s binning, not filtering. Never write in a query body: * `filter @ts > now() - PT1H` — use `ts: "PT1H"` instead * `filter @ts between formatDate(...) and ...` — set `ts` and let the platform handle the window * `formatDate(...)`, `nowMinus(...)`, `dateAdd(...)`, string-concatenated ISO timestamps — these are NOT BadgerQL functions; don’t invent them * Any `@ts`-based filter that mirrors a requested time range — `ts` already covers it ## Filter by event class When a query targets a class of events (“sql queries”, “errors”, “deploys”, “cache reads”), include an explicit `filter event_type::str == ""` clause. Without it, aggregates run across every event type in the selected streams and silently return wrong numbers. Use exact `event_type` values that are grounded — named in the request, observed in prior results, or discovered. Do not guess: a plausible-looking value that doesn’t exist matches nothing. When unsure, inventory the data first: ```plaintext fields @preview | limit 1 by event_type::str ``` ## Query parameters Query text may contain parameters: `${name}`, or `${name:-default}` with an inline default. Values are resolved from URL query parameters of the same name (`?hostname=web-1`), falling back to the inline default; a parameter with no URL value and no default leaves the query unable to run until a value is supplied. Up to 20 distinct parameters per query. ```plaintext filter hostname::str == "${hostname:-web-1}" and environment::str == "${env}" ``` Parameters are resolved by the app UI before the query executes. A query submitted directly to the API with an unresolved `${...}` is NOT substituted — it’s sent literally and will not match; substitute values yourself before submitting. ## Query URLs A query, its time range, and its visualization serialize into a shareable URL at `/projects/{project_id}/insights/query`: * `query`, `ts`, `timezone`, and `view` are query parameters * Chart config fields (see the charts instructions) are ALSO flat query parameters — every parameter other than the reserved ones is read as a chart config field. There is no `chart_config` parameter; do not JSON-encode the config object into the URL * Query-parameter values (`${name}` in the query text) are ALSO supplied as URL parameters of the same name: `?env=staging` ```plaintext ?query=filter+status%3A%3Aint+%3E%3D+500%0A%7C+stats+count()+as+count+by+bin(1h)&view=line&xField=bin(1h)&ts=P7D ``` ## Field names: no invention Only reference fields that are known to exist: 1. Fields observed in the data (via discovery queries), OR 2. Top-level meta fields documented in the BadgerQL reference (`@ts`, `@id`, `@preview`, `@stream.id`, etc.), OR 3. Fields named as literal identifiers in the request (`duration`, `response.status_code`). A natural-language concept (“response time”, “error code”) is NOT a grounded field name — it must be resolved through (1) or (2) first. Do NOT invent fields based on intuition (e.g. `scheduled_time`, `actual_time`, `response_time`, `error_code`). If a request implies fields you can’t ground, inspect a sample first: ```plaintext fields @preview | limit 5 ``` ## Result limits and retention Results are capped at 1,000 rows regardless of the `limit` you write. Aggregate (`stats ... by ...`) instead of enumerating raw events — a raw dump that “looks complete” at 1,000 rows usually isn’t. Event retention is plan-dependent and can be as short as 7 days. A `ts` window longer than the retention period silently returns only what’s retained — an apparent drop-off at the retention boundary is data purge, not a real change in the metric. # Honeybadger MCP server > Connect AI assistants to your Honeybadger projects and monitoring data with the Honeybadger MCP server, hosted or self-hosted. The Honeybadger MCP server provides structured access to Honeybadger’s API through the Model Context Protocol, allowing AI assistants to interact with your Honeybadger projects and monitoring data. The Model Context Protocol (MCP) is a standard that enables LLMs to interact with external services. Instead of manually copying error details or switching between tools, your AI assistant can fetch Honeybadger data, analyze patterns, and help investigate production issues within your existing workflow. ## What can you do with the MCP server? [Section titled “What can you do with the MCP server?”](#what-can-you-do-with-the-mcp-server) Once connected, your AI assistant gains the following capabilities: * **Project management**: List, create, update, and delete projects, and get detailed project reports. * **Error investigation**: Search and filter errors, view occurrences and stack traces, see affected users, and analyze error patterns. * **Insights**: Run BadgerQL queries against your event data. * **Dashboards**: List, create, update, and delete Insights dashboards. * **Alarms**: List, create, update, and delete Insights alarms, and review alarm history. We’re actively developing additional tools for account and team management, uptime monitoring, and other platform features. For a live list of the hosted server’s tools, visit [mcp.honeybadger.io](https://mcp.honeybadger.io/). Tool parameters are documented in the [GitHub README](https://github.com/honeybadger-io/honeybadger-mcp-server?tab=readme-ov-file#tools). ## Connect to the hosted server [Section titled “Connect to the hosted server”](#connect-to-the-hosted-server) Add the endpoint to your client. The first time it connects, complete the authorization flow in your browser. You don’t need to run the server locally or manually manage API tokens. ```plaintext https://mcp.honeybadger.io/mcp ``` EU region If your account is in our [EU region](/resources/data-residency/), use `https://eu-mcp.honeybadger.io/mcp` instead. Each endpoint only accepts accounts from its own region. ### Claude Code [Section titled “Claude Code”](#claude-code) Run this command to configure [Claude Code](https://www.anthropic.com/claude-code): ```bash claude mcp add --transport http honeybadger "https://mcp.honeybadger.io/mcp" ``` ### Cursor, Windsurf, and Claude Desktop [Section titled “Cursor, Windsurf, and Claude Desktop”](#cursor-windsurf-and-claude-desktop) Put this config in `~/.cursor/mcp.json` for [Cursor](https://docs.cursor.com/context/model-context-protocol), or `~/.codeium/windsurf/mcp_config.json` for [Windsurf](https://docs.windsurf.com/windsurf/cascade/mcp). See Anthropic’s [MCP quickstart guide](https://modelcontextprotocol.io/quickstart/user) for how to locate your `claude_desktop_config.json` for Claude Desktop: ```json { "mcpServers": { "honeybadger": { "url": "https://mcp.honeybadger.io/mcp" } } } ``` ### VS Code [Section titled “VS Code”](#vs-code) Run this command: ```bash code --add-mcp '{"name":"honeybadger","type":"http","url":"https://mcp.honeybadger.io/mcp"}' ``` See [Use MCP servers in VS Code](https://code.visualstudio.com/docs/copilot/chat/mcp-servers) for more info. ## Authorize and manage access [Section titled “Authorize and manage access”](#authorize-and-manage-access) The first time your client connects, you’ll be prompted to authorize the connection in your browser. You choose which account to grant access to and whether the connection can read and write or only read. The resulting access is always a subset of your own: the connection can never see or change anything you can’t. ![The Connect with Honeybadger MCP authorization screen, with selectors for the account to grant access to and the access level](/_astro/mcp-authorize.CzLnCfmV_1N6Xik.webp)![The Connect with Honeybadger MCP authorization screen, with selectors for the account to grant access to and the access level](/_astro/mcp-authorize-dark.DXrsLIjL_ZOySBy.webp) The access level you choose determines which tools your agent can use. With read-only access, write tools such as `create_project`, `update_project`, and `delete_project` are filtered out of the tool list entirely. Connections use short-lived tokens that refresh automatically in the background, so you only authorize each client once. If a client repeatedly asks you to re-authorize, it doesn’t support refresh tokens; use a client that does, or check for an update. To revoke a connection later, visit [API Access in your user settings](https://app.honeybadger.io/users/edit#api-access). Account admins can also revoke any member’s connections from the account’s API Access page. Revocation takes effect immediately. ## Try these workflows [Section titled “Try these workflows”](#try-these-workflows) Here are some things you might ask your AI assistant to help with. Always review its work closely; LLMs can make mistakes. ### Investigate an error [Section titled “Investigate an error”](#investigate-an-error) > Fix this error: \[link to error] Your assistant can look up the project and error details, open the source file from the stack trace, and fix the bug. You could also ask it to explain the error or help troubleshoot it. ### Review your projects [Section titled “Review your projects”](#review-your-projects) > What’s happening with my Honeybadger projects? Your assistant can list your projects, show recent error activity, and filter faults by time and environment to provide a quick overview or help you triage. ### Create an Insights chart [Section titled “Create an Insights chart”](#create-an-insights-chart) > Create an interactive chart that shows error occurrences for my “\[project name]” Honeybadger project over time. Your assistant can fetch time-series data from your project and generate an interactive chart showing error trends. ## Running your own server [Section titled “Running your own server”](#running-your-own-server) You can also run the server yourself with Docker instead of using the hosted endpoint. Self-hosted servers authenticate with your personal auth token, found under the “Authentication” tab in your [Honeybadger user settings](https://app.honeybadger.io/users/edit#authentication): ```json { "mcpServers": { "honeybadger": { "command": "docker", "args": [ "run", "-i", "--rm", "-e", "HONEYBADGER_PERSONAL_AUTH_TOKEN", "ghcr.io/honeybadger-io/honeybadger-mcp-server" ], "env": { "HONEYBADGER_PERSONAL_AUTH_TOKEN": "your personal auth token" } } } } ``` Client-specific setup, configuration options, and how to build from source are covered in the [GitHub README](https://github.com/honeybadger-io/honeybadger-mcp-server#installation). ### Configure access [Section titled “Configure access”](#configure-access) Self-hosted servers default to read-only access. Set `HONEYBADGER_READ_ONLY=false` to expose write tools. Use caution, as this allows destructive operations such as deleting projects. ### Connect a self-hosted server to the EU region [Section titled “Connect a self-hosted server to the EU region”](#connect-a-self-hosted-server-to-the-eu-region) Set `HONEYBADGER_API_URL` to `https://eu-app.honeybadger.io` in the config’s `env` block (for Docker, also add a matching `-e HONEYBADGER_API_URL` entry to the `args` list so Docker passes it through) and use a personal auth token from your [EU user settings](https://eu-app.honeybadger.io/users/edit#authentication). A US token won’t authenticate against the EU region, and vice versa. If you work across both regions, add both servers with distinct names (for example `honeybadger-us` and `honeybadger-eu`). ## How the server instructs your agent [Section titled “How the server instructs your agent”](#how-the-server-instructs-your-agent) The MCP server makes the same [Honeybadger instructions](/resources/llms/instructions/) linked from `llms.txt` available to your agent automatically, including references for BadgerQL, Insights queries, charts, dashboards, alarms, and error search. You don’t need to copy these instructions into your prompt or tell your agent to fetch them. Your agent fetches the instructions it needs through the server’s `get_reference` tool, typically once per session. You may notice this as a quick reference lookup before the first query or dashboard call. In long sessions, an agent may compact or summarize its history to stay within its context window, which can drop previously fetched instructions. When that happens, the agent may fetch them again, so a repeated reference lookup mid-session is normal. ## Additional resources [Section titled “Additional resources”](#additional-resources) * [Honeybadger MCP server](https://mcp.honeybadger.io/) * [Honeybadger MCP server GitHub repository](https://github.com/honeybadger-io/honeybadger-mcp-server) * [Model Context Protocol](https://modelcontextprotocol.io/) * [Working with LLMs](/resources/llms/) # Quotas > Learn how Honeybadger quotas work and optimize your error tracking budget across monthly and annual plans. The amount you pay for Honeybadger revolves mainly around how much error traffic your projects report to our API. Read on to find out how quotas work and how to maximize the value you get from Honeybadger. ## Error reporting [Section titled “Error reporting”](#error-reporting) ### Understanding quotas [Section titled “Understanding quotas”](#understanding-quotas) Your account has a limit on the number of error notifications that it will process per month. This quota varies based on the subscription plan you have chosen for your account, and reporting occurrences of an error to our API consumes your quota. For example, suppose your app sends ten notifications to our API when a user encounters the same bug ten times. In that case, your remaining quota will be reduced by ten. Whether you pay annually or monthly, quotas reset at the beginning of the calendar month (UTC). If your usage reaches 80% of your quota for the month, and if your projects are consuming the quota faster than the month is elapsing, we will send you notifications about your quota potentially running out. In other words, if you use up 80% of your quota by the 15th of the month, we’ll give you a heads-up about that, but if you hit 80% usage on the 27th (87% of a 31-day month), we won’t. We’ll send you another warning if/when you pass 90% (assuming you don’t upgrade first) and again at 100%. ### Exceeding your quota [Section titled “Exceeding your quota”](#exceeding-your-quota) If you hit 100% quota in a month, we will limit your projects to processing only one error notification per minute per project for the rest of the month. Any hits to our API after that one per minute per project will be ignored and won’t count against your quota. You can resume standard processing at any time by upgrading your plan to the next tier, and you can avoid getting limited by upgrading before reaching the 100% threshold. Should you upgrade, your bill will be prorated for the new subscription amount based on your billing anniversary. We also prorate downgrades. If you need to upgrade near the end of the month, you can downgrade after the beginning of the month (assuming your error volume won’t be as high in the coming month), and you’ll only be billed a little extra on your next invoice. As mentioned, we allow your account to exceed 100% of quota usage. However, we have a hard shutoff at 125% of quota consumption. If you hit that amount, your projects will not process any additional error notifications until you upgrade or until the 1st of the month rolls around. You can avoid the limits altogether by enabling overage billing, which allows you to go over your quota and be billed separately for that overage on the next invoice. Overage billing can work well if your error traffic puts you just over the limit for your plan, but if you are consistently going well past your quota, it will likely be cheaper for you to upgrade to the next tier. Overage charges can get very expensive, so we recommend being careful when enabling that option. ### Quota forgiveness [Section titled “Quota forgiveness”](#quota-forgiveness) Quotas work well when your error traffic is somewhat consistent, but sometimes, an unexpected spike in error traffic can consume your quota quickly. Having a production database go down, deploying buggy code to a staging environment, or other rarely-experienced scenarios can leave you early in the month without any quota remaining. If this happens to you, please feel free to [contact us](mailto:support@honeybadger.io) to get back in action once you’ve conquered the black swan event. Assuming this kind of thing isn’t happening to you regularly 😉, we’ll be happy to remove your account limits for the rest of the month. ### Limiting your quota usage [Section titled “Limiting your quota usage”](#limiting-your-quota-usage) An ounce of prevention is worth a pound of cure, right? You can help keep your Honeybadger costs down and avoid prematurely consuming your quota by using one or more of the following tips: * Use the Throttle field on the Advanced tab of the project settings page to limit how much error traffic is processed. Setting the throttle to 1 will limit that project to accepting only 1 API request per minute. * Use a hook in your code to prevent errors you don’t care about from being sent to our API. Examples of how to do this can be found in our client documentation — e.g., for [Ruby](/lib/ruby/errors/ignoring-errors/#ignore-programmatically) and [JavaScript](/lib/javascript/errors/reducing-noise/#ignoring-errors). This method is handy for ignoring errors raised by browser extensions. * Mark an error as ignored in our UI. Any future notifications will be discarded entirely, and won’t count against your quota. ## Insights [Section titled “Insights”](#insights) ### Daily data limit [Section titled “Daily data limit”](#daily-data-limit) Insights usage is measured by the amount of data you send to the [API endpoint](/api/reporting-events) each day (starting at midnight UTC). Since event and log data can be bursty, we do not immediately limit your traffic once you have reached your quota for the day. Instead, if you consistently go over your quota, you will be prompted to upgrade your subscription. If you do not upgrade or reduce the amount of data you send, then a hard limit will be applied to your account to enforce the Insights quota. ## Viewing your quota usage [Section titled “Viewing your quota usage”](#viewing-your-quota-usage) For a high level overview, visit the [Errors Stats page](https://app.honeybadger.io/projects/stats) and the [Insights Stats Page](https://app.honeybadger.io/projects/stats/insights) in the application to see your quota usage. For a more detailed view, you can use BadgerQL to query your Insights data usage. Here’s an example query that will show you the amount of data you’ve sent to the Insights for a project (be sure to deselect the [Internal Stream](/guides/insights/#streams) so you only see the data you are sending): ```badgerql stats sum(@size) as size by event_type::str | sort size | only toHumanString(size, "bytes"), event_type ``` ![Quota consumption query results](/_astro/quota-consumption.O4Ts2sZL_23HCT7.webp) You can then drill down and see the specific events that are consuming the most data. ```badgerql filter event_type::str == "sql.active_record" | stats count() as count by query::str | sort count ``` With this information, you may also want to set up an [Insights Alarm](/guides/insights/alarms/) to notify you when you’re generating more events than expected. For more information on how to use BadgerQL, check out our [BadgerQL documentation](/guides/insights/badgerql/). # Referral program > Earn monitoring credits by referring new customers to Honeybadger. Our customer referral program rewards you for spreading the word about Honeybadger. When someone you refer becomes a Honeybadger customer, you receive up to 20% of their payments as credit towards your bill. ## How to join [Section titled “How to join”](#how-to-join) Getting started with the referral program is simple: 1. Navigate to **Settings & billing** → **Referrals** in your [Honeybadger account](/guides/accounts/) 2. Accept the referral program terms 3. Share your unique referral link with colleagues, clients, or anyone who needs application monitoring ## How it works [Section titled “How it works”](#how-it-works) When you refer a new customer: * You earn 20% of their payments as monthly/annual invoice credits, up to your total invoice amount * Credits are automatically applied to your next bill * Credits don’t roll over—use them each period or lose them * Credits continue as long as both accounts remain active See the [referral program terms](https://www.honeybadger.io/terms/referral-agreement/) for full details. ## Earning potential [Section titled “Earning potential”](#earning-potential) The more you refer, the more you can save. Here are some examples: * **Small team ($90/month)**: Earn up to $18/month in credits * **Growing company ($200/month)**: Earn up to $40/month in credits * **Enterprise account ($900/month)**: Earn up to $180/month in credits Since Honeybadger team accounts [start at $26/month](https://www.honeybadger.io/plans/), one workplace referral could cover your personal account indefinitely. ## Tax information [Section titled “Tax information”](#tax-information) U.S. customers expecting to earn $600 or more in annual referral credits will need to provide tax information as required by law. You can provide this information by \[sending us a W-9 form]\(mailto:support\@honeybadger.io?subject=W-9 tax info for referral program\&body=Hi, please send me a secure link to provide my tax info.%0D%0A%0D%0AAccount ID:). We will issue a 1099 form at the end of the year for tax reporting purposes. If you reach the annual threshold before providing your tax information, referral credits will be paused until we receive it. # Security > Keep your error data safe. Please see [this page](https://www.honeybadger.io/security/) for more info about our policies and procedures related to security, as well our compliance information. ## Authenticating requests from Honeybadger [Section titled “Authenticating requests from Honeybadger”](#authenticating-requests-from-honeybadger) Requests sent from Honeybadger servers for *source maps*, *web hooks*, and *uptime checks* include the header `Honeybadger-Token` which is a secret token derived from your api key. The Honeybadger token may be used to authenticate the request (note that this token will change if you reset your project API key): ```plaintext Honeybadger-Token: your-token ``` You can find your token on the API Key tab in project settings. If your endpoint requires an `Authorization` header instead, the [Webhook integration](/guides/integrations/webhook/#3-set-a-bearer-token-optional) can send one. Set a bearer token on the integration and we’ll send it alongside the `Honeybadger-Token` header: ```plaintext Authorization: Bearer your-token ``` ## Firewalls [Section titled “Firewalls”](#firewalls) To use Honeybadger behind a firewall, you’ll need to configure your firewall to allow connections to our servers. Here’s the list: ### For exception monitoring [Section titled “For exception monitoring”](#for-exception-monitoring) Whitelist the following IPs for outgoing traffic: * 34.196.34.99 * 34.195.239.200 * 34.193.240.253 * 34.225.218.213 * 52.5.3.101 ### For webhooks, sourcemaps, and uptime monitoring [Section titled “For webhooks, sourcemaps, and uptime monitoring”](#for-webhooks-sourcemaps-and-uptime-monitoring) We use a dynamic range of IPs for outbound requests to your servers. Please use the Honeybadger-Token header, described above, to authenticate requests coming from our servers. ## Reporting issues [Section titled “Reporting issues”](#reporting-issues) If you’ve noticed a possible security issue, please let us know at . Please note that we do not pay bounties for vulnerability reports. ## Hall of fame [Section titled “Hall of fame”](#hall-of-fame) We’d like to thank the following people for helping us keep Honeybadger secure: * Manish Bhattacharya * Jayson Zabate * Aditya Agrawal * Evan Ricafort * Osanda Malith Jayathissa * Madhu Akula * Abdul Wasay * Shivam Kumar Agarwal * Sumit Sahoo * Adam Enger * Sajibe Kanti * Md. Nur A Alam Dipu * Pethuraj M * Tinu Tomy * Hariharan.S * Anil Tom * Pranshu Tiwari * Ranjeet Kumar Singh * Vikas Srivastava * Pankaj Kumar Thakur * Pratik Vinod Yadav * Mrunal Chawda * Bharat * Gaurav Solanki * Mahendra Purbia * Aditya Soni * Kunal Mhaske * Suresh Kumar * Agrah Jain * Ome Mishra * Dhanu Maalaian * Bilal Abdul Muqeet * Shaikh Sameer